Cover
About this book
Computing is entering its parallel age.
For more than thirty years, from the first microprocessors to the middle of the 2000s, most programs became faster without being changed. Each new generation of processor ran at a higher clock rate, and the same code finished sooner. Around 2005 that stopped. A faster clock made a chip too hot to cool, so clock rates settled at a few gigahertz, and chip designers spent each new generation’s extra transistors on more processors instead of faster ones. Since then, a program becomes faster mainly when it is written to do many things at once.
The GPU is the clearest example of that change. A CPU has a few large cores, each designed to finish one sequence of instructions as quickly as possible. A GPU has thousands of small arithmetic units and keeps tens of thousands of threads ready to run, and it is designed to finish a great many independent pieces of work in the same time. GPUs were first built to color the pixels of a screen, a task made of millions of independent pieces. The same design now runs scientific simulations, trains and serves machine-learning models, and processes images and signals.
Programming a GPU well does not depend on a large body of special knowledge. A small number of ideas explain most of what makes a GPU program fast or slow: how threads are grouped and scheduled, how data moves through the levels of memory, and how much arithmetic a program performs for each byte it reads. This book builds those ideas from the beginning, and then uses them to write and measure real programs.
The Hardware Gap
A CUDA library call can hide the hardware behind it. A matrix multiply runs at 3% of peak when threads in a warp read columns instead of rows. A reduction can silently drop half of its data when threads diverge across a __syncthreads(). A host allocation that is pageable instead of pinned doubles transfer latency. None of these failures print an error. They produce a slow benchmark or a subtly wrong result.
This book covers the hardware model, the CUDA C++ programming model, and the C++ and Rust ecosystem around them, so those failures are diagnosable instead of mysterious.
What You Will Build
Every chapter builds toward one project: a complete GPU image-processing pipeline - read an image, convert it to grayscale, apply a separable Gaussian blur, run a Sobel edge detector, and write the result - implemented three times:
- in CUDA C++ with hand-written, fully commented kernels;
- with the Thrust/CUB/cuBLAS library ecosystem;
- in pure Rust with NVIDIA’s experimental CUDA-Oxide compiler, which turns idiomatic Rust into PTX.
You will build the same kind of pipeline a camera vendor would ship: pinned-memory transfers, streamed double buffering, an occupancy-tuned kernel configuration, and reproducible benchmarks. When you have finished, you will be able to look at any CUDA kernel - including the ones inside the libraries you already use - and explain, line by line, what it does and why it is fast.
Who This Book Is For
You should read this book if:
- You can write C++ or Rust, but every GPU program you have written so far was a library call you did not fully understand.
- You have launched a kernel, seen it produce garbage, and had no idea whether the bug was in your index arithmetic, your memory layout, or your synchronization.
- You suspect that most GPU tutorials skip the hardware model and want to understand the primitives - the warp, the streaming multiprocessor, the memory hierarchy - before touching a single CUDA API.
- You write Rust and want to know what CUDA-Oxide changes, and what it does not.
- You do not own a GPU and want to learn on the free compute that the cloud gives away (see the next section).
- You ship software whose performance budget is measured in microseconds and whose correctness budget is zero.
You do not need prior GPU experience. You need to be willing to sit with the hardware model. This book does not hand-wave the memory hierarchy. Every term is defined when it first appears; every primitive - every type, every built-in variable, every API call - is described before it is used. Where the book refers to a number (register counts, memory bandwidths, transaction sizes), it gives you the reasoning behind it, not just the number.
You Do Not Need to Own a GPU
Every line of code in this book runs on any NVIDIA GPU with CUDA 12.x - including the free ones. If you do not own a GPU, the cloud has you covered, and most providers give away enough free compute to finish this entire book:
- Google Colab - free T4 GPUs in browser notebooks, zero setup; the fastest way to run your first kernel.
- Kaggle Notebooks - free GPU hours (roughly 30 per week, refreshed weekly), data-science friendly.
- Google Cloud - a new-account trial credit (about USD 300 at the time of writing) covers serious L4 and A100 sessions.
- Microsoft Azure - a new-account credit (about USD 200) for NC/ND-series GPU virtual machines.
- AWS - GPU instances (g4dn, g5, p4); the free tier is CPU-only, but the Activate and Educate programmes grant credits to startups and students.
- Paperspace / Gradient - GPU notebooks and cloud workstations with free and low-cost tiers.
- Lambda, RunPod, Vast.ai - cheap on-demand GPUs (RTX 4090 up to H100) when you outgrow the free tiers.
- NVIDIA LaunchPad - free, time-boxed hands-on labs on real NVIDIA hardware.
- Modal - serverless GPU code with recurring free compute credits (about USD 30 per month at the time of writing).
Credit amounts and session limits change frequently; check the current terms before you sign up. The repository README contains a fuller comparison table to help you choose.
The Structure
The book is organized into six parts:
Part I - Foundations of GPU Computing (Chapters 1-3) covers the mathematics of parallelism, the GPU hardware model, and the CUDA programming model. Read this part carefully; every later chapter assumes the primitives defined here.
Part II - Writing CUDA C++ Kernels (Chapters 4-6) covers memory management, synchronization, atomics, and asynchronous execution with streams and events.
Part III - Optimization & Advanced Patterns (Chapters 7-9) covers memory optimization, the canonical parallel algorithms (reduction, scan, histogram), and a complete, step-by-step optimization of matrix multiplication.
Part IV - Modern C++ & The CUDA Ecosystem (Chapters 10-12) covers RAII wrappers, templates and modern C++ idioms, the Thrust/CUB/cuBLAS libraries, and runtime compilation with NVRTC.
Part V - Rust, CUDA-Oxide & Safe GPU Programming (Chapters 13-15) covers Rust host code driving CUDA kernels, NVIDIA’s experimental CUDA-Oxide compiler for writing kernels in pure Rust, and the image-processing capstone.
Part VI - The Engineering Mindset (Chapter 25) covers profiling with Nsight Compute, debugging with Compute Sanitizer, and reproducible performance engineering.
A Note on the Coding Standards
This project has a constitution. You will find it as CODING_STANDARDS.md in the repository root. It is not a suggestion. Every code block in this book follows it:
- Every primitive is explained before it is used.
- No magic numbers - if it is not
0,1,-1, or a power of two required by the CUDA API, it gets a named constant. - Every kernel is commented line by line.
- Every CUDA API call that can fail is checked.
- Every
__syncthreads()and every atomic carries a comment stating which data it protects and why.
A Note on Hardware and Honesty
The examples in this book target the CUDA 12.x toolkit and are written against the compute capability of modern NVIDIA GPUs (Ada and Hopper architectures, compute capability 8.x and 9.0). You do not need to own this hardware: the section “You Do Not Need to Own a GPU” lists the cloud options, and the free tiers alone are enough for everything in this book. Where a feature is architecture-specific, the book says so explicitly.
This book is also direct about the tooling. NVIDIA’s CUDA-Oxide is an experimental, alpha-stage compiler; its API is evolving and its syntax may change. The chapters that cover it describe the project as it exists today, with code written in the style of its documented examples. Treat those chapters as a map of the territory, not a surveyor’s certificate.
If you find a bug in the book - in the prose or in the code - open an issue or submit a pull request. This is a living document. The GPU does not stop changing, and neither should the book.
Chapter 1 starts from the mathematics and builds the programming model from the hardware up. No GPU knowledge is assumed; the requirements are the C++ or Rust listed above and a machine that can run CUDA 12.x examples.
- Arpan Pathak
About the cover
The cover is the inside of a hive. The queen bee gives a single order, c[i] = a[i] + b[i], and 32 worker bees carry it out together, each on its own honeycomb cell. That is the picture this book keeps coming back to.
- The queen is the host program on the CPU. She does no filling herself. She decides the work and launches it.
- The order is a kernel: one piece of code, written once.
- The workers are GPU threads. Each runs the same order on a different cell.
- The 32 workers in formation are one warp, the group of 32 threads that a GPU steps through each instruction together.
- The empty cell belongs to the worker who wandered off on a branch of its own. When threads in a warp take different branches, the warp has to wait for the stragglers. Chapter 5 calls this divergence.
- The crab is the Rust crew. From Part V onward, the kernels are written in Rust with cuda-oxide.
Each chapter opens with a member of the cast at work on the chapter’s subject.
| Chapter | Character | Scene |
|---|---|---|
| 1 | Tally the ant | a column of ants crossing a meadow all at once, then crossing a one-ant bridge in single file: the serial part of the work |
| 2 | Comb the worker bee | a guide beside a cut-away hive whose comb frames are SMs, with workers standing on them in formations that move as one: warps |
| 3 | The Queen | holds up a launch, <<<4, 256>>>, beside 4 comb frames of worker bees: 1 order, carried out by every thread of every block |
| 4 | Ferry the pelican | carries crates of bytes on a raft from the host memory bank to the device memory bank: pinned data crosses in 1 trip |
| 5 | Whistle the meerkat | keeps watch at a gate that stays down until every bee has arrived: a barrier |
| 6 | The otter twins | float down 2 rivers side by side, each carrying work: 2 streams at the same time |
| 7 | Inch the caterpillar | walks with each segment over the next numbered cell: neighboring threads read neighboring addresses |
| 8 | Stash the squirrel | beside a pyramid of 8, 4, 2 and 1 acorns, each standing for the 2 below it: the tree of a reduction |
| 9 | Shell the tortoise | carries a shell laid with square tiles past stacks marked A and B: load a tile once, use it many times |
| 13 | Pinch the crab | one claw for a[i], one for b[i], the sum dropped into c[i]; two spare crabs doze past the end of the row |
The plates are drawn by tools/art.py.
Chapter 1: The Mathematics of Parallelism
A parallel program divides one computation among several processors that run at the same time. How much sooner such a program finishes than a sequential one can be estimated before any code is written. The estimate needs 3 things: how long each operation takes, how much of the computation can be divided, and how many bytes each operation reads from memory.
For several decades, programs became faster without any effort from the people who wrote them. Each generation of microprocessors ran at a higher clock rate than the one before, and the same sequential program finished sooner on the newer chip. That trend ended in the mid-2000s. A higher clock rate requires more power, and the power drawn by a chip becomes heat that must be removed from it; at clock rates of a few gigahertz, the heat reached the limit of what a chip package and its cooling could carry away. Since then, chip designers have spent the additional transistors of each generation on more processors per chip, and a program becomes faster on a newer chip only if it divides its work among those processors. A GPU contains thousands of simple arithmetic units and depends entirely on parallel programs to keep them busy.
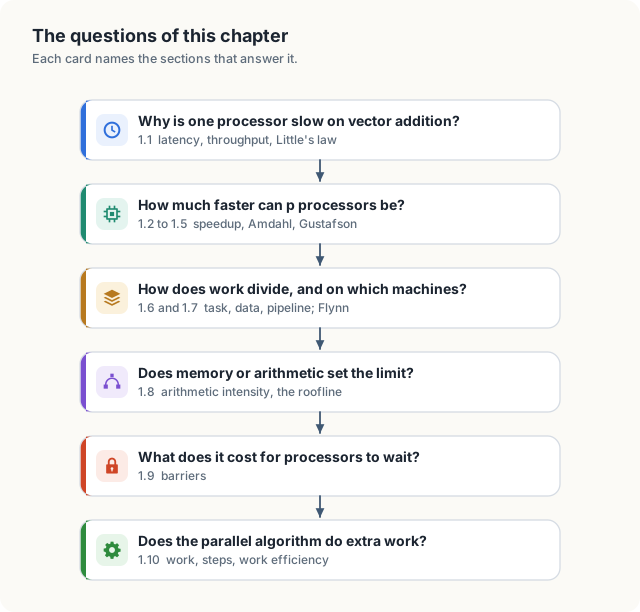
This chapter develops the quantitative tools that we use throughout the book to reason about the performance of such programs. They do not depend on any particular machine. A processor here is any unit that executes instructions: a core of a CPU, or one of the threads of a GPU that section 1.1.5 introduces. We begin with the time that individual operations take and the way in which overlapping them hides that time (section 1.1). We then ask how much faster a program can become on more processors, and find that the answer depends on the part of it that cannot be divided (sections 1.2 to 1.5). Sections 1.6 and 1.7 classify the ways in which work divides and the machines that execute it. Section 1.8 introduces the model that decides whether memory or arithmetic limits a computation, which later chapters use to judge every kernel. Sections 1.9 and 1.10 account for the costs that parallel execution adds: waiting at barriers, and performing more operations than a sequential program would.
This chapter covers
- cycles, latency and throughput, and how they differ
- concurrency, and Little’s law, which relates it to latency and throughput
- dependencies, and why independent operations can overlap
- speedup and efficiency
- Amdahl’s law for a fixed computation, and Gustafson’s law for a growing one
- Amdahl’s law when only part of a program moves to a GPU, and the copies it needs
- strong and weak scaling
- task, data and pipeline parallelism, and Flynn’s classes of machines
- arithmetic intensity and the roofline model
- the cost of a barrier
- work, steps, and why a parallel algorithm that does extra work can be slower
The running example: vector addition
Most examples in this chapter use one computation, chosen because it is the simplest
computation that a parallel machine can speed up. 2 arrays of numbers, a and b, each hold
N entries, and a third array c receives their sum, entry by entry:
c[i] = a[i] + b[i] for every i from 0 to N - 1
For N = 4:
| i | a[i] | b[i] | c[i] |
|---|---|---|---|
| 0 | 0.0 | 0.0 | 0.0 |
| 1 | 1.0 | 2.0 | 3.0 |
| 2 | 2.0 | 4.0 | 6.0 |
| 3 | 3.0 | 6.0 | 9.0 |
Each entry c[i] is computed from a[i] and b[i] alone; no entry of c needs another
entry of c. Computations with this property are called independent. They give the
same result in any order, and they can therefore run at the same time on different
processors. Almost everything a GPU does well rests on this property, and much of the
difficulty of parallel programming, which later chapters address, arises in computations
that lack it.
1.1 Latency, throughput, and concurrency
A sequential program on a modern processor spends most of its time waiting for data, and very little of it computing. This section measures that waiting, and shows how a machine can hide it by keeping many operations under way at once. The argument introduces 3 quantities, latency, throughput and concurrency, and one law that connects them. The same law gives the number of threads a GPU must hold, which section 1.1.5 works out for an H100.
1.1.1 Cycles
A processor performs its work in steps timed by a clock, and one tick of the clock is a cycle. At a clock rate of 1 GHz there are 109 cycles per second, so a cycle lasts 1 nanosecond; at 2 GHz it lasts half a nanosecond. We count time in cycles because the number of cycles an operation takes changes much less from one machine to another than its duration in nanoseconds. A processor whose clock runs twice as fast completes each cycle in half the time, but an addition still occupies roughly the same number of cycles on it.
1.1.2 Latency
The latency of an operation is the time from the moment it starts to the moment its result can be used. The 2 operations of vector addition have very different latencies.
| Operation | Latency |
|---|---|
| add 2 numbers that are already in the processor | about 4 cycles |
| read one number from main memory | about 500 cycles |
The difference of more than 100 times comes from distance and from the kind of storage. An addition works on values held in registers inside the processor, a short distance from the arithmetic unit, and passes them through a few layers of logic. A read from main memory leaves the processor, crosses the chip to a memory controller, waits in a queue behind other requests, and travels over wires to separate memory chips. There a row of storage cells is opened and read, and the value returns by the same route. Each of these steps is fast by itself, but there are many of them, and the slowest, reading the storage cells, has hardly become faster in decades.
Why is a read from main memory so slow? Main memory is built from DRAM, dynamic random-access memory. A DRAM chip stores each bit as a small electrical charge in a capacitor, and connects thousands of these capacitors to each long wire, called a bit line, that leads to a detector called a sense amplifier. To read a bit, the chip first raises a row line that connects every cell of one row to its bit line. The small charge of the cell then spreads over the much larger bit line and shifts its voltage by a tiny amount, and the sense amplifier must wait until that shift is large enough to tell a 1 from a 0. Both steps take tens of nanoseconds, which is tens to hundreds of cycles of a processor that runs at 1 to 2 GHz. The process could be made faster with larger capacitors that hold more charge. DRAM makers have done the opposite: they have shrunk the capacitors in each generation to fit more bits on a chip. As a result, the capacity and the bandwidth of DRAM have grown by large factors over the decades, while its latency has changed little. Chapter 2 describes how DRAM delivers many bytes from each opened row, which is the property that GPUs exploit.
NOTE: The latencies in this chapter, and the 40 TFLOP/s machine of section 1.8, are round figures chosen to keep the arithmetic easy. They have the right order of magnitude, and Chapter 2 replaces them with measured values for real GPUs.
Suppose one processor computes the 4 rows of the example, one row after another, and issues the reads of a row only after it has finished the previous row.
Worked example: one processor, 4 rows
- The processor requests
a[0]andb[0]. The 2 reads travel together, so both values arrive 500 cycles later. - It adds them: 4 cycles.
- It sends
c[0]toward memory. A processor does not wait for a write to complete, so it moves straight on to the next row. - Rows 1, 2 and 3 repeat the same steps.
Each row takes 504 cycles, the 4 rows take 2,016 cycles, and the adder is busy for 16 of them.
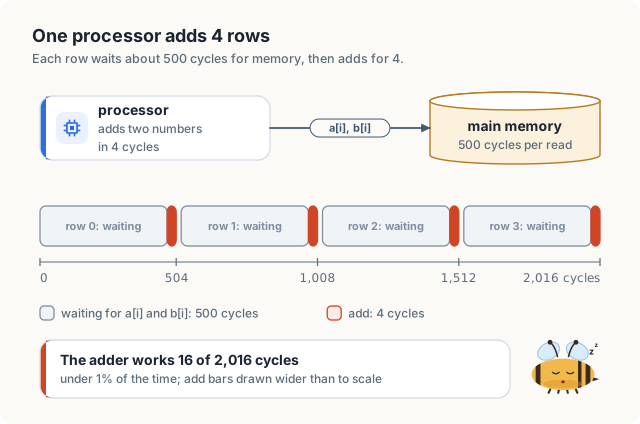
It may seem that a faster adder would shorten this run. It would not: the adder accounts for 16 of the 2,016 cycles, and an infinitely fast adder could save at most those 16. The run is long because the processor waits for each read before it asks for the next one, so the reads take place one after another and their latencies add up. The latency of a memory read is a property of the hardware, and the program cannot shorten it. What the program can change is how many reads it has under way at the same time, which is the subject of the next 3 sections.
The processor in figure 1.2 spends more than 99% of the run waiting for memory.
1.1.3 Throughput
The throughput of a system is the rate at which it completes operations: the number of operations it completes during an interval of time, divided by the length of the interval. Latency is a property of one operation, and throughput is a property of a stream of operations, so the 2 answer different questions. Latency tells us how long one result takes to arrive. Throughput tells us how many results arrive per unit of time once a steady stream of operations is under way.
A related quantity is bandwidth: the maximum amount of data that a connection or an electronic system, such as a memory system, can transfer in a given amount of time. Bandwidth is a capacity of the hardware. Throughput is the rate that a stream of operations actually achieves, and it can be anything up to that capacity. A memory system with a bandwidth of 1 TB/s that receives one read at a time achieves a small fraction of it, as the processor of figure 1.2 does. Section 1.8 uses the bandwidth of a GPU’s memory.
If a system worked on only one operation at a time, its throughput would follow from its latency: with reads that take 10 cycles, it would complete one read every 10 cycles. Many systems instead accept a new operation before the earlier ones have finished, and their throughput can then be much higher than one operation per latency. Memory systems work this way. A memory is divided into many independent parts, called channels and banks, and each part can work on a different read at the same time; Chapter 2 describes these parts in a GPU.
Consider a simplified memory system in which every read takes 10 cycles, and which accepts a new read every 2 cycles. Figure 1.3 shows 8 reads sent to it, one every 2 cycles.
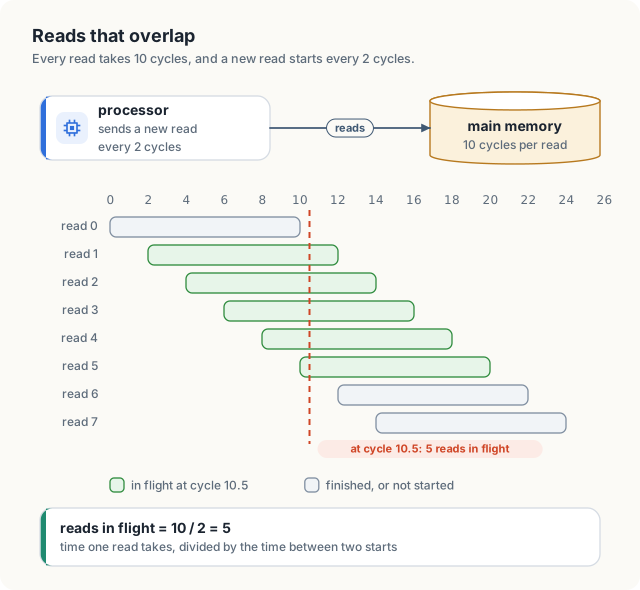
| Read | Starts at cycle | Completes at cycle |
|---|---|---|
| 0 | 0 | 10 |
| 1 | 2 | 12 |
| 2 | 4 | 14 |
| 3 | 6 | 16 |
From cycle 10 onwards a read completes every 2 cycles, so the throughput is 0.5 reads per cycle. Each individual read still takes 10 cycles. Starting reads in quick succession did not make any of them faster; it made them overlap. Most optimizations in this book work the same way: they raise throughput by overlapping operations, and leave the latency of each operation as it was.
1.1.4 Concurrency and Little’s law
The reads that have started and not yet completed are said to be in flight, and their number is the concurrency of the system. The dashed line in figure 1.3, at cycle 10.5, crosses reads 1 to 5, so 5 reads are in flight at that moment. A line drawn at any later cycle, until the stream of reads ends, also crosses 5.
The number 5 is not an accident of the drawing. Each read stays in flight for 10 cycles, and while it does, a new read starts every 2 cycles, so 10 / 2 = 5 reads start during its lifetime. When it completes, those 5 are the reads still in flight.
We write \(L\) for the latency (10 cycles here), \(X\) for the throughput (0.5 reads per cycle) and \(C\) for the concurrency (5 reads). The same argument holds for any system that runs at a steady rate:
\[ C = X \times L \qquad\text{or equivalently}\qquad X = \frac{C}{L} \]
This relation is Little’s law. John Little proved it in 1961 for queues of every kind: the average number of customers in a shop equals the rate at which they arrive multiplied by the average time each one stays. For the reads of figure 1.3, \(0.5 \times 10 = 5\), the number we counted.
The second form, \(X = C / L\), is the one that matters for performance. When the latency is fixed by the hardware, the only way to raise the throughput is to raise the concurrency: twice as many reads in flight complete twice as many reads per cycle. The law also works in the other direction. A memory system that can deliver a certain throughput only delivers it if the program keeps \(X \times L\) reads in flight; with fewer, the throughput falls in proportion, however high the bandwidth printed on the data sheet.
A latency that cannot be shortened can still be hidden, by keeping enough operations in flight.
A memory read takes 400 cycles, and the memory accepts a new read every 4 cycles. How many reads must be in flight to keep it busy?
The throughput is \(X = 1/4\) read per cycle and the latency \(L = 400\) cycles, so \(C = 400 / 4 = 100\) reads.
1.1.5 Where the concurrency comes from
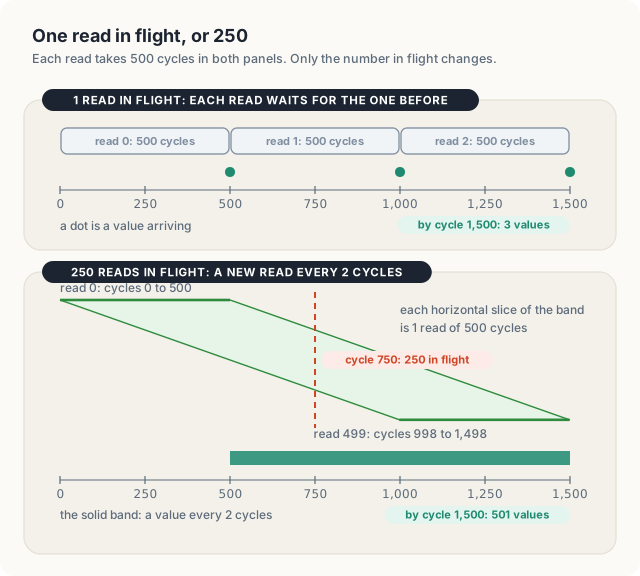
We now return to main memory, with its 500-cycle reads, and suppose that it accepts a new read every 2 cycles. To keep it busy, Little’s law asks for
\[ C = X \times L = 0.5 \times 500 = 250 \]
reads in flight at all times. The processor of figure 1.2 has at most 2 in flight. It receives 2 values every 500 cycles from a memory that could have delivered 250 in the same time (figure 1.4).
The 250 reads must come from the computation, and its structure decides how many it can offer. An operation depends on another when it needs that operation’s result. In one row of vector addition, the add depends on both reads and the write depends on the add. A sequence of operations in which each depends on the one before is a dependency chain, and no 2 operations of the same chain can overlap. One row is a short chain, so it can offer at most its 2 reads at once.
The rows, however, are independent. The reads of row 7 do not need anything from row 6, so a program can issue the reads of 125 rows before the first of them returns. A GPU does this with threads. A thread is a sequence of instructions with its own registers, the small storage slots inside a processor that each hold one value. A GPU runs thousands of threads and gives each a few rows. While some threads wait for their values, others already have theirs and keep the arithmetic units busy (animation 1).
The animation uses small numbers so that every cycle is visible. A group needs 8 cycles for one round, a read and an add, and the unit finishes an add every 2 cycles. Little’s law gives the number of groups that keeps it busy: \(C = 8 \times \tfrac{1}{2} = 4\). A GPU applies the same arithmetic with latencies of hundreds of cycles, which is why it holds thousands of threads at once.
The same law, applied to bytes, gives the scale of a real GPU. Little’s law holds for any unit of work, so the number of bytes that must be in flight is the bandwidth multiplied by the latency.
Worked example: how many threads an H100 needs for vector addition
- The H100’s memory delivers \(X\) = 3.35 TB/s (section 1.8).
- A read from its memory takes about 500 cycles (section 2.6). At its clock rate of 1.98 GHz (section 2.2), 500 cycles last 500 / (1.98 × 10⁹) s = 253 ns.
- Bytes in flight: \(C = X \times L\) = 3.35 × 10¹² B/s × 253 × 10-9 s = 848,000 bytes, about 0.85 MB.
- One row of vector addition reads
a[i]andb[i], 8 bytes. A thread that works on one row at a time has 8 bytes in flight, so the memory stays busy only with 848,000 / 8 = 106,000 threads waiting at every moment.
An H100 can hold 132 SMs × 2,048 threads = 270,336 threads at once (section 2.9). Vector addition needs about 40% of them in flight just to keep the memory busy. A kernel that holds fewer threads, or gives each thread a long dependency chain, runs below the memory’s bandwidth however simple its arithmetic. A CPU core keeps only a few reads outstanding and relies on its caches to make most reads short. The number of threads a GPU holds follows from Little’s law and the latency of DRAM.
Why not reduce the latency instead? A CPU and a GPU read from the same kind of DRAM, with the same latency of hundreds of cycles. They differ in what they spend chip area on. A CPU core is designed to make one thread fast. It spends much of its area and power on large caches that turn many slow memory reads into fast ones, and on control logic that predicts branches and reorders instructions so that one thread rarely waits. This approach is called latency-oriented design. A GPU is designed to make many threads fast in total. It spends the same area on more arithmetic units and more memory channels, lets each operation take a long time, and relies on other threads to fill the wait. This approach is called throughput-oriented design. The choice follows from cost. Doubling the throughput of an arithmetic unit takes a second unit, about twice the area and power. Halving its latency requires faster circuits, which cost disproportionately more area and power. Per unit of area and power, throughput costs less than latency, provided the program supplies the threads. A GPU therefore performs poorly on a program with one thread or a few, and a CPU performs poorly on a program with many; most applications that use a GPU run their sequential parts on the CPU and their data-parallel parts on the GPU. Section 2.1.1 compares the 2 designs in hardware.
1.2 Speedup and efficiency
Section 1.1 made one processor faster by overlapping its reads. The other way to finish sooner is to share the work among several processors. This section defines the 2 measures of the result. We write \(p\) for the number of processors, \(T_1\) for the running time on one processor and \(T_p\) for the running time on \(p\).
Consider a program with 3 phases that run in order: it reads its input for 20 microseconds (µs), computes for 100 µs and writes its result for 10 µs, so \(T_1 = 130\) µs. Suppose that the compute phase can be shared evenly among any number of processors, but that the read and the write pass through a single channel and cannot be shared.
Worked example: the program on 1, 2, 4 and 8 processors
| \(p\) | Compute (µs) | Read + write (µs) | \(T_p\) (µs) | Saved by the last doubling (µs) |
|---|---|---|---|---|
| 1 | 100 | 30 | 130 | |
| 2 | 50 | 30 | 80 | 50 |
| 4 | 25 | 30 | 55 | 25 |
| 8 | 12.5 | 30 | 42.5 | 12.5 |
Every doubling of the processors saves half as much time as the doubling before it, because only the compute phase shrinks. 2 ratios describe the result. The speedup compares the running times:
\[ S(p) = \frac{T_1}{T_p} \]
On 2 processors \(S(2) = 130 / 80 = 1.63\). The efficiency divides the speedup by the number of processors, and so measures how much of the added capacity turned into speed:
\[ E(p) = \frac{S(p)}{p} \]
| \(p\) | \(T_p\) (µs) | Speedup \(S\) | Efficiency \(E\) |
|---|---|---|---|
| 1 | 130 | 1.00 | 1.00 |
| 2 | 80 | 1.63 | 0.81 |
| 4 | 55 | 2.36 | 0.59 |
| 8 | 42.5 | 3.06 | 0.38 |
At 8 processors the efficiency has fallen to 0.38. During the 30 µs of reading and writing, 7 of the 8 processors have nothing to do, and those 30 µs are a larger share of each shorter run. At 8 processors, 62% of the processor time paid for is idle.
The speedup is normally no greater than \(p\), and the efficiency no greater than 1. The exception, superlinear speedup, appears when each processor’s share of the data becomes small enough to fit in its cache, a small fast memory beside the processor. Each processor then runs faster than the single processor did, and the combined speedup can exceed \(p\). The extra speed comes from the cache, so the program loses it once its data no longer fits.
TIP: Report the efficiency with the speedup. A speedup of 10 sounds good until it turns out to need 64 processors, an efficiency of 0.16.
A speedup is only as meaningful as its baseline, the run it divides by. \(T_1\) should be the time of the best sequential program for the task. The parallel program run on 1 processor is a weaker baseline, because it still carries the work of dividing the data and combining the results, so it makes \(T_1\) larger and the speedup look better. The same rule applies between machines. A GPU program compared with 1 CPU core running plain loops shows a larger speedup than the same program compared with every core of the CPU using its vector instructions (section 1.7). Only the second comparison tells the reader whether the GPU is worth using.
1.3 Amdahl’s law
The table of section 1.2 showed the speedup leveling off as processors were added. This section explains why, and gives the limit a formula. In 1967 Gene Amdahl, the chief architect of IBM’s System/360, used a short argument to show that machines with many processors would gain less than their designers hoped. Part of every program, he observed, can only be executed by one processor at a time, and that part limits what the rest of the machine can achieve. His argument fits in the table of section 1.2, extended to many more processors.
The serial part of a program is the part that only one processor can execute at a time; the parallel part is the part that can be shared. In our program the read and the write, 30 µs, are serial, and the compute phase, 100 µs, is parallel.
Worked example: more and more processors
| \(p\) | Parallel part (µs) | Serial part (µs) | \(T_p\) (µs) | Speedup |
|---|---|---|---|---|
| 1 | 100 | 30 | 130 | 1.00 |
| 8 | 12.5 | 30 | 42.5 | 3.06 |
| 100 | 1 | 30 | 31 | 4.19 |
| 1,000 | 0.1 | 30 | 30.1 | 4.32 |
| unlimited | approaches 0 | 30 | approaches 30 | approaches 4.33 |
However many processors share the parallel part, the 30 serial microseconds remain. The program can never run in less than 30 µs, and so never more than 130 / 30 = 4.33 times faster than on one processor.
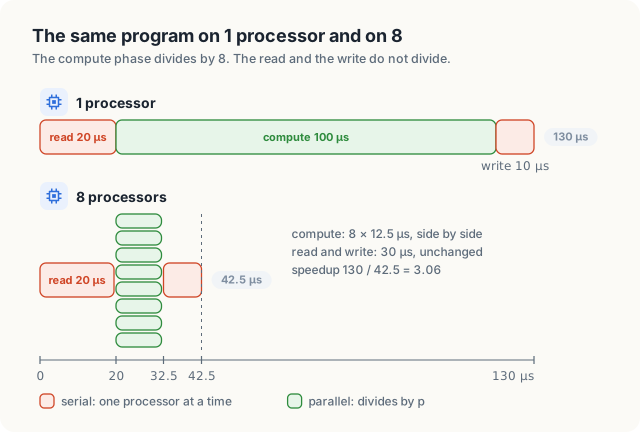
To state the result for any program, let \(f\) be the serial fraction: the share of the one-processor time that is serial. For our program \(f = 30 / 130 = 0.23\), and the parallel share is \(1 - f = 0.77\). On \(p\) processors the serial part keeps its length and the parallel part is divided by \(p\):
\[ T_p = f \cdot T_1 + \frac{(1 - f) \cdot T_1}{p} \]
For \(p = 8\) this is \(30 + 100 / 8 = 42.5\) µs, as in the table. As \(p\) grows, the second term vanishes and \(T_p\) approaches \(f \cdot T_1\). The speedup therefore approaches
\[ S_{\max} = \frac{T_1}{f \cdot T_1} = \frac{1}{f} \]
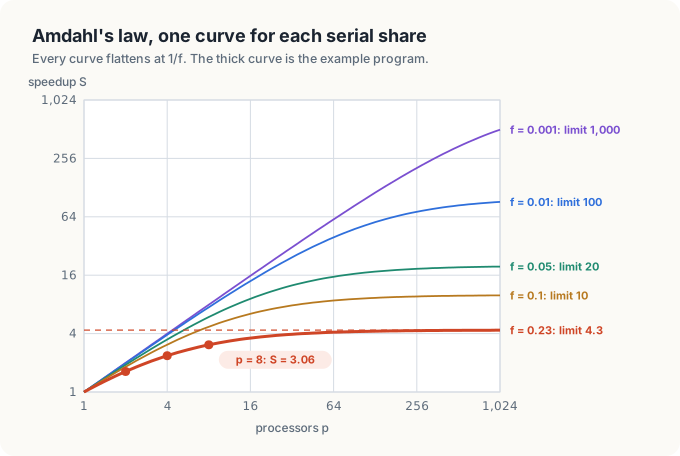
which is Amdahl’s law. For our program, \(1 / 0.23 = 4.3\). Dividing \(T_1\) by \(T_p\) gives the speedup on a particular number of processors:
\[ S(p) = \frac{1}{f + \dfrac{1 - f}{p}} \]
A program with serial fraction \(f\) can never run more than \(1/f\) times faster, however many processors it is given.
1.3.1 How small the serial fraction must be
The limit rises steeply as the serial fraction falls. The table also gives the number of processors at which a program reaches half of its limit.
| Serial fraction \(f\) | Limit \(1/f\) | Processors for half the limit |
|---|---|---|
| 0.25 | 4 | 3 |
| 0.10 | 10 | 9 |
| 0.05 | 20 | 19 |
| 0.01 | 100 | 99 |
| 0.001 | 1,000 | 999 |
The last column follows from the formula for \(T_p\). The speedup is half of its limit when the shared parallel part has shrunk to the size of the serial part, \((1 - f)/p = f\), that is at \(p = 1/f - 1\). Beyond that point each additional processor divides an ever smaller remainder. A GPU runs thousands of threads, and a program can only make use of them if its serial fraction is a small fraction of a percent (figure 1.6). A program that spends 1% of its time in serial code cannot run more than 100 times faster, on a GPU with 100 threads or with 100,000.
Animation 2 follows the example along its curve, then lengthens the read, which raises \(f\) and lowers the limit.
A program spends 5% of its one-processor time in a serial part. What is the highest speedup any number of processors can give it?
\(f = 0.05\), so the limit is \(1 / 0.05 = 20\).
1.3.2 Where the serial part comes from
The serial part of a real program is rarely a single phase that is easy to point to. It includes starting the program and loading its input, combining the processors’ partial results at the end, and every step that has to wait for the one before it. It is often larger than its author expects, and measuring it is the first step in deciding how many processors a program can use. The serial parts of an application frequently make up most of its source code while taking a small share of its running time. Such code usually stays on the CPU, which runs one thread quickly, and the parallel programming effort goes into the small amount of code where the time is spent.
Amdahl’s formula is also optimistic in one respect: it assumes that the parallel part divides for free. In practice, handing out work and collecting results take time, and that time grows with the number of processors, so measured speedup curves bend over earlier than the formula predicts. Section 1.9 calculates one such cost.
1.3.3 When the parallel part has a speedup of its own
The formula for \(T_p\) assumes that \(p\) processors divide the parallel part exactly \(p\) ways. A GPU program is measured differently. The serial part stays on the CPU, the parallel part moves to the GPU, and the GPU runs that part some number of times faster. We call that number \(s\). It depends on the GPU and on the part, and it is not a count of processors. Putting \(s\) in place of \(p\) gives the speedup of the whole program:
\[ S = \frac{1}{f + \dfrac{1 - f}{s}} \]
Worked example: 1 serial second and 99 parallel seconds
A program runs for 100 s on 1 CPU core: 1 s of serial work and 99 s of parallel work, so \(f = 0.01\).
- The GPU runs the parallel part 100 times faster, in 99 / 100 = 0.99 s. The program takes 1 + 0.99 = 1.99 s, a speedup of 100 / 1.99 = 50.
- The parallel part is memory-bound, and the GPU runs it only 10 times faster, in 9.9 s. The program takes 1 + 9.9 = 10.9 s, a speedup of 9.2.
- The parallel part again runs 100 times faster, but its input must first be copied into the GPU’s memory and its output copied back, which takes 2 s. The program takes 1 + 0.99 + 2 = 3.99 s, a speedup of 25.
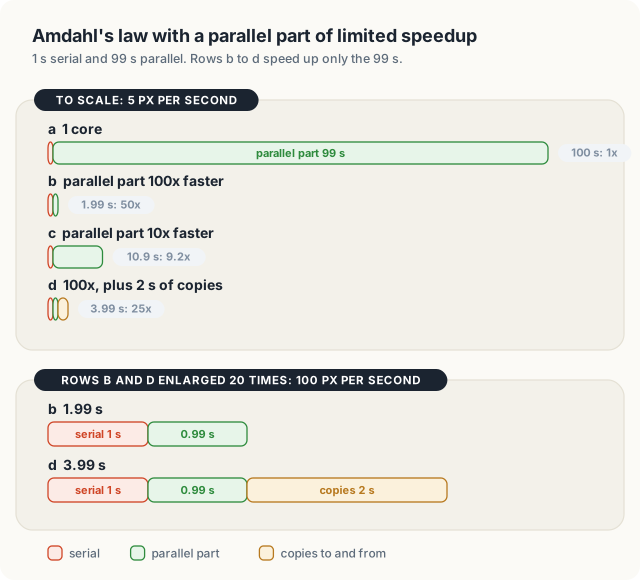
In case 1 the parallel part became 100 times faster and the program only 50 times. The serial second was 1% of the original run and is half of the new one (row b of figure 1.7). The table of section 1.3.1 predicts this: with \(f = 0.01\), the speedup reaches half of its limit of 100 when the parallel part shrinks to the size of the serial part, at \(s = 99\).
The factor of 10 in case 2 has a specific cause. A memory-bound part runs at the rate at which its memory delivers bytes (section 1.8), so moving it to a GPU makes it faster by about the ratio of the 2 memory bandwidths, whatever the GPU’s arithmetic units could do. A desktop CPU with 2 channels of DDR5-5600 memory moves 2 × 8 bytes × 5.6 × 10⁹ per second = 89.6 GB/s. A GeForce RTX 4090 moves 1,008 GB/s, about 11 times as much. A straightforward port of a memory-bound program to a GPU therefore often stops near a speedup of 10. Chapters 7 to 9 go beyond it by reusing each byte from on-chip memory once it has arrived, which reduces the number of bytes the part must fetch from DRAM.
The copies of case 3 exist only because the work moved, and they behave like serial time: the GPU’s speed does not shorten them. With \(t\) for the copy time as a fraction of the original run, here 2 / 100 = 0.02:
\[ S = \frac{1}{f + \dfrac{1 - f}{s} + t} = \frac{1}{0.01 + 0.0099 + 0.02} = 25 \]
| Symbol | Meaning | In the example |
|---|---|---|
| \(f\) | serial fraction of the 1-core run | 0.01 |
| \(s\) | speedup of the parallel part alone | 100 in cases 1 and 3, 10 in case 2 |
| \(t\) | copy time as a fraction of the 1-core run | 0.02 in case 3 |
| \(S\) | speedup of the whole program | 50, 9.2 and 25 |
Chapter 4 measures what copies cost and shows that a GPU sharing the CPU’s memory, as on a Jetson board, can skip them. Chapter 6 runs copies at the same time as computation, which removes most of \(t\) from the formula.
A GPU speeds up only the part it runs. The serial part and the copies keep their length, and they set the limit.
The parallel part of a program is 90% of its 1-core time, and a GPU runs it 20 times faster. What is the speedup of the program, and what is its limit for a GPU of unlimited speed?
\(S = 1 / (0.1 + 0.9 / 20) = 1 / 0.145 = 6.9\). As \(s\) grows the second term vanishes, and the limit is \(1 / 0.1 = 10\).
1.4 Gustafson’s law
Amdahl’s law was derived for a computation of fixed size. This section shows that the conclusion changes when the size of the computation grows with the machine, as it usually does in practice. For 2 decades Amdahl’s law was read as a verdict against large parallel machines. In 1988 John Gustafson and his colleagues at Sandia National Laboratories ran 3 scientific programs on a machine with 1,024 processors. They measured speedups of 1,021, 1,020 and 1,016, for programs whose serial fractions were 0.4 to 0.8 percent. By Amdahl’s formula, a serial fraction of 0.4 percent allows a speedup of about 200 on 1,024 processors. The measured speedups were 5 times higher, and the arithmetic of both results was correct.
The difference lay in the question being asked. Amdahl asked how much faster a fixed computation runs on more processors. Gustafson’s group did what users of large machines usually do: they enlarged the problem to fill the machine, and asked how much more work could be done in the same time. A larger machine renders a larger image, trains on a larger batch or simulates a finer grid. In such programs the serial part, typically the setup and the input and output, grows slowly or not at all, while the parallel part grows with the data.
Worked example: a computation that grows with the machine
A program runs for 10 seconds on 4 processors: 1 second in a serial part, then 9 seconds in which all 4 processors compute.
- On one processor, the serial second still takes 1 second.
- The 9 parallel seconds kept 4 processors busy, which is 4 × 9 = 36 processor-seconds of work. One processor needs 36 seconds for it.
- So \(T_1 = 37\) s and \(T_4 = 10\) s, a speedup of 3.7.
On 8 processors, with twice the data, the run again takes 1 + 9 = 10 seconds, and one processor would need 1 + 8 × 9 = 73. The speedup is 7.3.
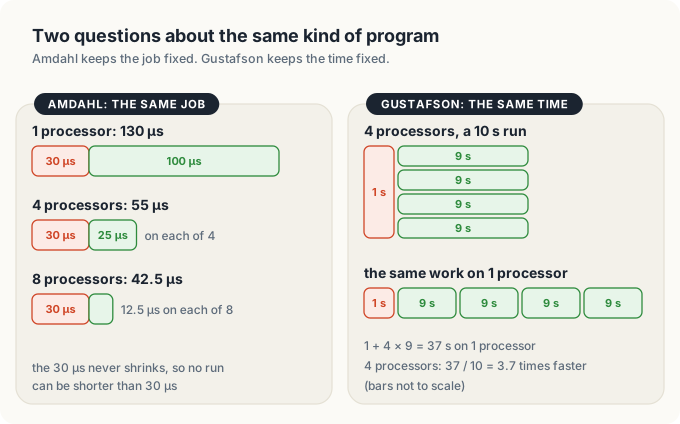
Let \(s\) be the serial fraction measured on the parallel run, here 1 second out of 10, so \(s = 0.1\). The worked example generalizes to
\[ S(p) = s + p \cdot (1 - s) \]
which is Gustafson’s law. For the example, \(0.1 + 4 \times 0.9 = 3.7\). For the Sandia programs, with \(s = 0.004\) and \(p = 1{,}024\), it gives 1,020, the speedup they measured.
The 2 laws do not contradict each other. They measure the serial fraction against different running times, and answer different questions.
| Amdahl | Gustafson | |
|---|---|---|
| Question | how much faster does the same computation run? | how much more computation fits in the same time? |
| Serial fraction measured on | the one-processor run, \(f\) | the parallel run, \(s\) |
| As processors are added | the computation stays the same | the computation grows |
| Speedup | approaches \(1/f\) | grows in proportion to \(p\) |
In the worked example the serial second is a tenth of the parallel run but only a thirty-seventh of the one-processor run. Its share of the one-processor run keeps falling as the problem grows. A video frame of fixed size that must be ready in 16 milliseconds is governed by Amdahl’s law; a training batch that grows with the machine is governed by Gustafson’s.
1.5 Strong and weak scaling
The 2 laws correspond to the 2 standard ways of measuring a parallel program. Strong scaling keeps the total problem fixed and adds processors; the running time should fall, and Amdahl’s law predicts where it stops falling. Weak scaling keeps the problem per processor fixed, so the total grows with the processors; the running time should stay the same, as Gustafson’s law describes.
| Measurement | Problem size | Good result |
|---|---|---|
| strong scaling | fixed | time falls as processors are added |
| weak scaling | grows with the processors | time stays the same |
Weak scaling exposes overheads directly. Suppose that one processor handles 1,000 elements in 1 ms, and that 16 processors are given 16,000 elements, still 1,000 each. A run of 1 ms is perfect scaling. A run of 1.25 ms means that 0.25 ms went to distributing work, exchanging data and waiting, costs that grow with the number of processors.
TIP: When you report a speedup, say whether it comes from strong or weak scaling. The 2 have different limits, so a speedup without that information cannot be checked.
1.6 How a computation divides
Both laws assume that the parallel part can be divided, but they say nothing about how. The way in which a computation divides decides which machines can run it well, and 3 patterns cover most programs.
Task parallelism runs different computations at the same time: one processor decodes the next video frame while another filters the current one. Programs rarely have more than a handful of separate tasks, so task parallelism occupies a few processors, not thousands. Chapter 6 uses it to overlap data transfers with computation.
Data parallelism runs the same computation on different parts of the data at the same time. Vector addition is data parallel: every row runs the same instructions, and each processor takes some of the rows. The number of parts grows with the data, which is what a machine with thousands of processors needs. Data parallelism is also easier to reason about than task parallelism, because every processor executes the same code, and a programmer can understand the whole computation by understanding one part of it. GPUs are built for data parallelism, and most of this book uses it.
Pipeline parallelism splits the work on each item into stages, such as load, compute and store, and lets different items occupy different stages at the same time, like an assembly line. Figure 1.9 shows 4 items passing through 3 stages.
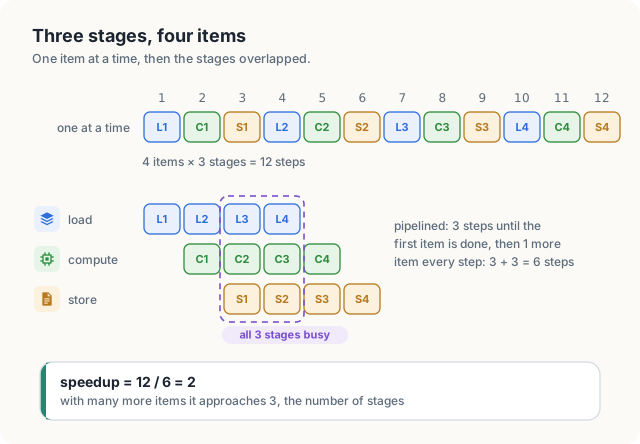
One item at a time, each item needs 3 steps and the 4 need 12. In the pipeline, the first item still needs 3 steps to pass through every stage. From then on one item leaves at every step, so the remaining 3 items need only 3 more: 6 steps in all, a speedup of 2. In general \(N\) items through \(S\) stages take \(S \cdot N\) steps one at a time and \(S + N - 1\) in a pipeline, a speedup of
\[ \frac{S \cdot N}{S + N - 1} \]
For figure 1.9, \(3 \times 4 / 6 = 2\). As \(N\) grows the speedup approaches \(S\), the number of stages. A short batch spends most of its time filling and emptying the pipeline, which is why pipelines pay off on long streams. The same arithmetic reappears in Chapter 6, where the stages are a copy to the GPU, a kernel and a copy back.
1.7 Flynn’s taxonomy
The patterns of section 1.6 describe programs. This section classifies the machines that run them, by the way in which their processors receive instructions. In 1966 Michael Flynn sorted computers by 2 counts: the number of instruction streams a machine follows at once, and the number of data streams those instructions work on. With one or many of each there are 4 classes. Figure 1.10 shows one computation, adding 8 pairs of numbers, on each kind of machine.
- SISD, single instruction stream, single data stream: an ordinary core. Each add instruction adds one pair, so 8 pairs take 8 instructions in sequence.
- SIMD, single instruction stream, multiple data streams: a core with vector registers that hold several numbers side by side. One add instruction adds all 8 pairs. AVX on x86 processors and NEON on Arm processors are SIMD instruction sets.
- MIMD, multiple instruction streams, multiple data streams: several cores, each running its own program on its own data. Every multi-core CPU is a MIMD machine.
- MISD, multiple instruction streams, single data stream, is rare. Some fault-tolerant systems run the same data through different programs and compare the results.
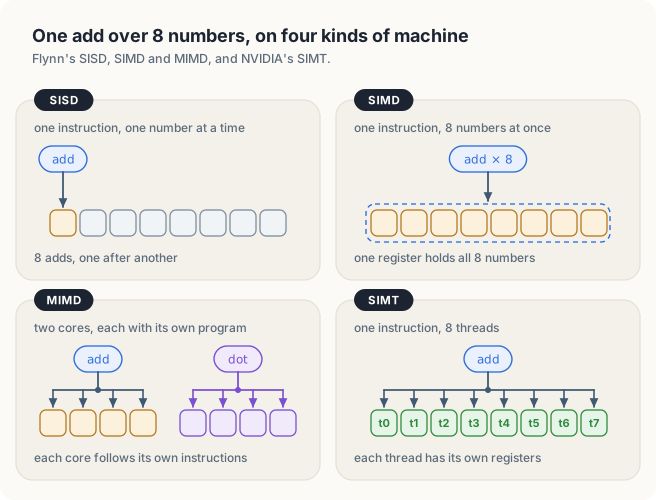
A GPU fits none of the 4 exactly. NVIDIA calls its design SIMT, for single instruction, multiple threads. As in SIMD, one instruction is issued to a whole group of threads, so the cost of fetching and decoding the instruction is shared among them; this sharing is what lets a GPU devote most of its area to arithmetic units. Unlike SIMD, every thread has its own registers, so the programmer writes an ordinary sequential program for one thread and the hardware runs it for many. A SIMD programmer must arrange the data into vector registers by hand; a SIMT programmer does not.
The difference becomes visible at a branch. When some threads of a group take the if
side and others the else side, the group cannot do both at once. It runs one side while
the threads of the other side wait, and then runs the other side. The program remains
correct, but the group spends time on both sides. Chapter 2 shows how the hardware forms
these groups and what such a split costs.
1.8 Arithmetic intensity and the roofline
The previous sections asked how many processors a program can use. This section asks a different question: given a machine, which of its resources limits a computation. An NVIDIA H100 can perform 67 trillion additions of 32-bit numbers per second. Given 2 long arrays to add, element by element, it performs about 0.28 trillion, less than half of one percent of its peak. The GPU is working correctly: its arithmetic units spend almost all of their time waiting for numbers to arrive from memory, as the processor of section 1.1 did. Both observations follow from one ratio, which compares the arithmetic a computation performs with the bytes it moves.
1.8.1 Arithmetic intensity
A computation on arrays does 2 kinds of work: it moves bytes between main memory and the processor, and it performs arithmetic on them. One addition or multiplication of 2 floating-point numbers is one FLOP, for floating-point operation. The arithmetic intensity of a computation is the number of FLOPs it performs for each byte it moves:
\[ I = \frac{\text{FLOPs performed}}{\text{bytes moved}} \]
Worked example: 2 intensities counted by hand
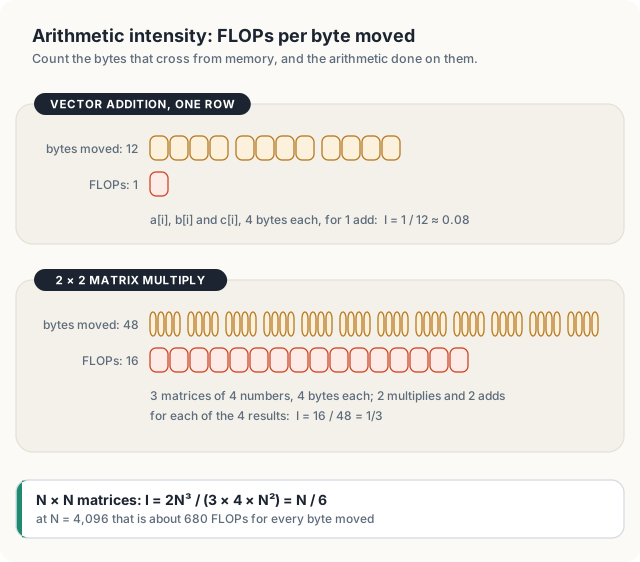
Vector addition, one row. The processor reads a[i] and b[i], 4 bytes each, and
writes c[i], 4 bytes: 12 bytes moved for 1 addition. \(I = 1/12 \approx 0.08\) FLOP
per byte.
A 2 × 2 matrix product \(C = A \times B\). Each entry of \(C\) is a row of \(A\) multiplied by a column of \(B\):
C[0][0] = A[0][0] × B[0][0] + A[0][1] × B[1][0]
Each of the 4 entries takes 2 multiplications and 2 additions, counting the addition to the initial zero: 16 FLOPs. The 3 matrices hold 12 numbers of 4 bytes, 48 bytes. \(I = 16/48 = 1/3\) FLOP per byte.
The matrix product already does 4 times as much arithmetic per byte, and the ratio grows with the size of the matrices, because each number takes part in many products. For 2 \(N \times N\) matrices the same count gives \(2N^3\) FLOPs on \(3N^2\) numbers of 4 bytes:
\[ I = \frac{2N^3}{3N^2 \times 4} = \frac{N}{6}\ \text{FLOP per byte} \]
For \(N = 2\) this is the \(1/3\) we counted. For \(N = 4{,}096\) it is about 680 (figure 1.11). The number of times a byte is used after it arrives is its reuse. Vector addition uses every byte once, and a large matrix product uses each one thousands of times. The count above assumes that each number is fetched from memory only once, which a program achieves only if it keeps the numbers close to the processor between uses; whether it does is the subject of Chapter 9.
1.8.2 The ridge point
A machine has 2 speed limits. Its arithmetic units perform at most \(P_{\text{peak}}\) FLOPs per second, and its memory delivers at most \(B\) bytes per second, a figure called the memory bandwidth. A computation with intensity \(I\) performs \(I\) FLOPs per byte, so memory alone lets it reach \(I \times B\) FLOPs per second. It runs at whichever limit is lower:
\[ P = \min(P_{\text{peak}},\ I \times B) \]
Worked example: 3 computations on a machine with 40 TFLOP/s and 1 TB/s
| Computation | \(I\) (FLOP/byte) | Memory allows \(I \times B\) | Arithmetic allows | Runs at |
|---|---|---|---|---|
| vector addition | 0.08 | 0.08 TFLOP/s | 40 TFLOP/s | 0.08 TFLOP/s |
| matrix product, \(N = 64\) | 10.7 | 10.7 TFLOP/s | 40 TFLOP/s | 10.7 TFLOP/s |
| matrix product, \(N = 4{,}096\) | 683 | 683 TFLOP/s | 40 TFLOP/s | 40 TFLOP/s |
For the first 2 computations memory sets the speed. Such a computation is memory-bound, and faster arithmetic units would not help it. For the third, arithmetic sets the speed; it is compute-bound, and more memory bandwidth would not help. The 2 limits are equal at the intensity
\[ I_{\text{ridge}} = \frac{P_{\text{peak}}}{B} = \frac{40}{1} = 40\ \text{FLOP per byte} \]
called the ridge point of the machine. The ridge point has a direct reading: it is the number of FLOPs the machine can perform in the time its memory delivers 1 byte. A computation that performs fewer FLOPs than that per byte leaves the arithmetic units idle part of the time. Drawn on logarithmic axes, the limit \(P\) rises along a slope and then runs flat, like a roof. Samuel Williams, Andrew Waterman and David Patterson introduced the picture in 2009 and named it the roofline (figure 1.12).
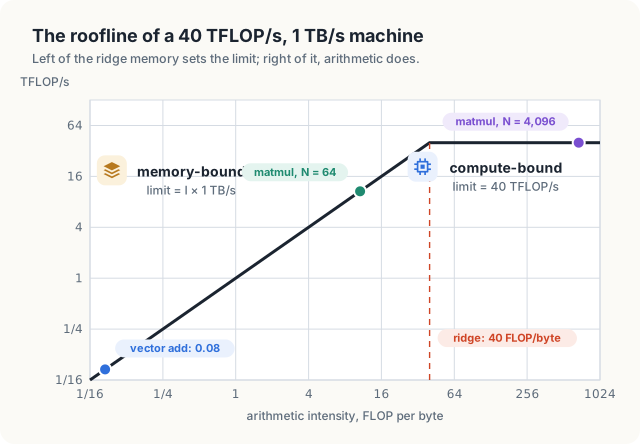
The H100 delivers 3.35 TB/s from its memory, so its ridge is at 67 / 3.35 = 20 FLOP per byte. Vector addition, at 1/12, sits far down the slope, and \(\tfrac{1}{12} \times 3.35 = 0.28\) TFLOP/s is the speed quoted at the start of this section. Section 2.1 repeats the calculation for the Jetson board used in this book.
The roofline is an upper bound, and a program can sit well below it. The most common reason is the one of section 1.1. The memory delivers \(B\) bytes per second only if enough reads are in flight to satisfy Little’s law; a program that offers too few independent reads reaches a fraction of \(B\), and therefore a fraction of its roof. A measured point far below the roof means that the program has too few reads in flight, or moves more bytes than the count of section 1.8.1 assumed.
A machine performs 20 TFLOP/s and its memory delivers 0.5 TB/s. Where is its ridge point, and is a computation with an intensity of 10 FLOP per byte memory-bound on it?
The ridge is at \(20 / 0.5 = 40\) FLOP per byte. An intensity of 10 lies below it, so the computation is memory-bound and runs at \(10 \times 0.5 = 5\) TFLOP/s.
A computation moves to the right on the roofline when each byte it loads is used more often. In the inner loop of a straightforward matrix product, each step reads 2 numbers, 8 bytes, for 2 FLOPs, an intensity of 0.25. If a 16 × 16 block of the result is kept in registers, every number read is used 16 times and the intensity rises to about 4. The technique is called tiling, and Chapter 9 builds it step by step (animation 3). Vector addition offers nothing to reuse, so it can only become faster by moving its bytes more efficiently, the subject of section 2.7 and Chapter 7.
1.8.3 CPU-bound, memory-bound, and I/O-bound programs
The same words describe whole programs once a third resource is added: input and output (I/O), such as a disk or a network. Whichever resource stays busy while the others wait gives the program its name. A CPU-bound program, also called compute-bound, keeps the processor busy. A memory-bound program keeps the memory system busy while the processor waits for bytes. An I/O-bound program keeps a disk or network link busy while the processor waits for data.
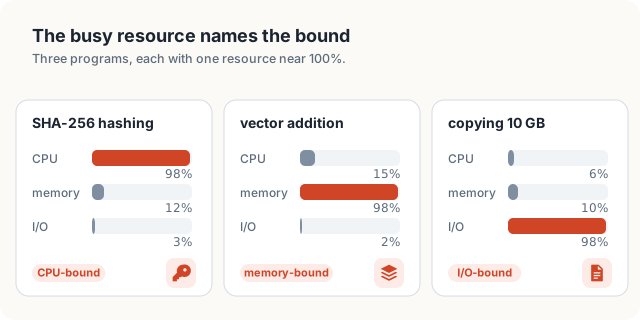
An experiment confirms the bound: make one resource twice as fast and measure again.
| Resource made twice as fast | Running time halves? | The program is |
|---|---|---|
| processor | yes | CPU-bound |
| memory bandwidth | yes | memory-bound |
| disk or network | yes | I/O-bound |
| number of processors | no | limited by its serial part (section 1.3) |
A video encoder that spends 98% of its time computing and 2% reading frames is CPU-bound: a faster disk changes nothing, and a processor twice as fast nearly halves its running time. The bound of a program is the first thing to establish before optimizing it, because an optimization aimed at a resource that is not the bound cannot help. Chapter 7 treats memory-bound GPU programs, Chapter 9 compute-bound ones and Chapter 6 programs that wait for data transfers. Chapter 25 shows how a profiler measures the bound instead of guessing it.
1.9 The cost of synchronization
The laws of sections 1.3 and 1.4 treat the parallel part as if each processor worked alone from start to finish. Real parallel computations must also coordinate. Many of them end by combining the results of their processors, for example by adding partial sums, and the results cannot be combined until every processor has finished. The usual mechanism is a barrier: a point in the program at which each processor stops until all the others have reached it. Chapter 5 shows how barriers are built; this section calculates what they cost.
If 4 processors each perform 1,000 cycles of work and then spend 100 cycles at a barrier, each works for 1,000 of every 1,100 cycles, an efficiency of 0.91. Work is rarely divided that evenly.
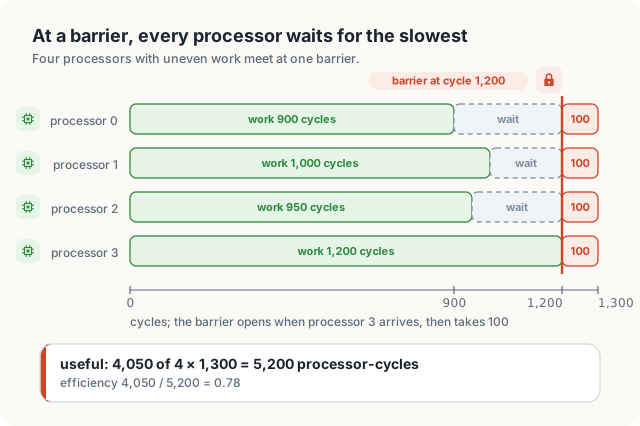
Worked example: uneven work at a barrier
- The processors have 900, 1,000, 950 and 1,200 cycles of work.
- The barrier opens at cycle 1,200, when processor 3 arrives; the other 3 stand idle until then.
- Useful work: 900 + 1,000 + 950 + 1,200 = 4,050 processor-cycles.
- Time paid for: 4 processors × (1,200 + 100) cycles = 5,200 processor-cycles.
- Efficiency: 4,050 / 5,200 = 0.78.
A barrier makes every processor finish at the pace of the slowest. The amount of work each processor receives often depends on the input data, for example on the number of non-zero entries in its part of a sparse matrix, so the same program can scale well on one input and poorly on another. A barrier also has a cost that the figure does not show. A value written by one processor does not become visible to the others instantly. A barrier has to wait until all such writes are visible, which is part of why it takes 100 cycles and not 1.
The idle time and the barrier itself behave like serial time, since adding processors shortens neither. Under strong scaling each processor’s share of the work shrinks while the barrier stays the same, so the barrier takes a growing share of each run and Amdahl’s limit falls.
Fast parallel programs meet as rarely as they can: each processor writes its own partial result, and the results are combined once, at the end.
Chapter 8 applies this to the sum of \(N\) numbers and reduces the number of barriers from about \(\log_2 N\) to a small constant.
1.10 Work, steps and work efficiency
The laws of this chapter compare a parallel program with a sequential one as if both performed the same operations. That assumption often fails. Many parallel algorithms perform more operations than the best sequential algorithm, and for large inputs the extra operations can make them slower than the program they replace. This section measures a parallel algorithm by 2 counts that expose the problem, and derives bounds on its running time from them.
Section 1.1.5 showed that the operations of a dependency chain cannot overlap. The 2 counts turn that observation into numbers. The work \(W\) of an algorithm is the number of operations it performs. Its steps \(D\), also called its depth or span, is the number of operations in its longest dependency chain. Chapter 8 uses the same 2 counts for sums. In this section we count time in units of 1 operation, and assume that every operation takes 1 unit.
Worked example: 3 computations on the entries of c
The running example produced \(c\) = 0, 3, 6, 9.
- Vector addition itself: 4 additions, and none needs the result of another. \(W = 4\), \(D = 1\).
- The sum of \(c\), from left to right: 0 + 3 = 3, then 3 + 6 = 9, then 9 + 9 = 18. Each addition needs the one before. \(W = 3\), \(D = 3\).
- The same sum in pairs: 0 + 3 = 3 and 6 + 9 = 15 are independent, then 3 + 15 = 18. \(W = 3\), \(D = 2\).
On \(p\) processors, at most \(p\) operations complete in each unit of time, so the run takes at least \(W / p\) units. It also takes at least \(D\) units, because the operations of the longest chain run one after another however many processors are free. Both limits hold at once:
\[ T_p \ge \max\left(\frac{W}{p},\ D\right) \]
In 1974 Richard Brent showed that the operations can always be scheduled so that the run is not much longer than this bound:
\[ T_p \le \frac{W}{p} + D \]
For the sum in pairs on 2 processors, the bounds give \(\max(1.5,\ 2) = 2\) and \(1.5 + 2 = 3.5\) units. The run takes 2: both first additions in the first unit, the last addition in the second.
The ratio \(W / D\) is the parallelism of the algorithm: the average number of operations available per unit of time. Up to about \(W / D\) processors, the \(W / p\) term dominates and each added processor shortens the run. Beyond it, \(D\) dominates and added processors wait. Vector addition of \(N\) entries has parallelism \(N / 1 = N\). A chain has parallelism 1, which is why exercise 8 finds no gain from more processors. A sum in pairs of \(2^{20}\) = 1,048,576 values has \(W\) = 1,048,575 and \(D = 20\), a parallelism of about 52,000.
| Symbol | Meaning | In the example |
|---|---|---|
| \(W\) | work: operations performed | 3 for the sum of \(c\) |
| \(D\) | steps: operations on the longest chain | 3 left to right, 2 in pairs |
| \(p\) | processors | 2 |
| \(W / D\) | parallelism | 1 left to right, 1.5 in pairs |
A parallel algorithm is work-efficient when its work is within a constant factor of the work of the best sequential algorithm for the same task. Many parallel algorithms buy fewer steps with more work, and the bounds show what that costs.
A scan, or running sum, replaces each entry by the sum of all entries up to it. The scan of \(c\) = 0, 3, 6, 9 is 0, 3, 9, 18. A scan appears to be inherently sequential, since each output needs the one before it, yet it can be computed in parallel by algorithms that perform extra additions. A sequential scan of \(N\) values performs \(N - 1\) additions, each needing the one before: \(W = D = N - 1\). 2 parallel scans appear in Chapter 8.
- The shifted scan (section 8.7.2) runs rounds at offsets 1, 2, 4, up to \(N / 2\). In the round at offset \(d\), every entry from position \(d\) on adds the entry \(d\) places to its left. On \(c\), offset 1 gives 0, 3, 9, 15 with 3 additions, and offset 2 gives 0, 3, 9, 18 with 2 more: \(W = 5\), \(D = 2\). In general \(W = N \log_2 N - (N - 1)\) and \(D = \log_2 N\).
- The tree scan, due to Guy Blelloch, adds pairs up a tree and then passes the partial sums back down it. It has \(W = 2(N - 1)\) and \(D = 2 \log_2 N\).
Worked example: 3 scans of 1,024 values
With \(N = 1{,}024 = 2^{10}\), the shifted scan performs 1,024 × 10 − 1,023 = 9,217 additions, 9 times the sequential 1,023. The table gives the lower bound \(\max(W / p, D)\) in units of 1 addition.
| Scan | \(W\) | \(D\) | \(p = 4\) | \(p = 32\) | \(p = 1{,}024\) |
|---|---|---|---|---|---|
| sequential | 1,023 | 1,023 | 1,023 | 1,023 | 1,023 |
| tree | 2,046 | 20 | 511.5 | 63.9 | 20 |
| shifted | 9,217 | 10 | 2,304 | 288 | 10 |
On 4 processors the shifted scan needs at least 2,304 units, more than twice the sequential scan. Its extra work needs more than 9,217 / 1,023 = 9.01 processors before it can even break even, and the ratio grows with \(N\): for a scan of \(2^{20}\) values it is about 19. The tree scan breaks even at 2 processors whatever the size. On 1,024 processors the order reverses: each scan has processors to spare for its work, the steps decide, and the shifted scan’s 10 beat the tree scan’s 20 (figure 1.15).
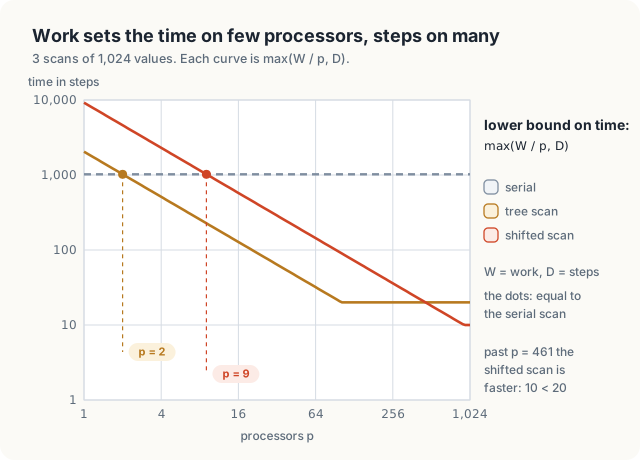
Neither scan is better in general; the choice depends on how many processors the scan actually has. A warp of 32 GPU threads executes every step of the shifted scan together, whether a thread adds or not, so its extra work costs no time there, and section 8.7.2 uses the shifted scan inside a warp for that reason. Across a whole block, each step usually ends at a barrier. \(D\) then counts barriers too, and section 1.9 gives the price of each.
Work decides the running time on few processors, and steps decide it on many. Count both before choosing a parallel algorithm.
An algorithm has \(W = 10^6\) and \(D = 10^3\). Between which times does it run on 100 processors, and on 10,000?
On 100 processors, \(\max(10^4, 10^3) = 10{,}000\) units at least and \(10^4 + 10^3 = 11{,}000\) at most. On 10,000 processors, \(\max(100, 1{,}000) = 1{,}000\) and \(100 + 1{,}000 = 1{,}100\). The parallelism is \(10^6 / 10^3 = 1{,}000\), so the processors beyond about 1,000 wait.
Summary
- Latency is the time one operation takes; throughput is the number of operations completed per unit of time. Little’s law, \(C = X \times L\), gives the concurrency needed to reach a throughput when the latency is fixed.
- Operations in a dependency chain cannot overlap. Independent operations can, and they supply the concurrency that hides memory latency. A CPU is designed to shorten latency, a GPU to hide it.
- Speedup is \(T_1 / T_p\) and efficiency is \(S / p\). Measure every speedup against the best sequential program.
- Amdahl’s law: a fixed computation with serial fraction \(f\) runs at most \(1/f\) times faster on any number of processors.
- A GPU runs the parallel part \(s\) times faster, and copies take a fraction \(t\) of the original run. The program’s speedup is \(1 / (f + (1 - f)/s + t)\).
- Gustafson’s law: a computation that grows with the machine has a speedup of \(s + p(1 - s)\).
- Strong scaling fixes the total problem; weak scaling fixes the problem per processor.
- Computations divide by task, by data, or into pipeline stages. GPUs are built for data parallelism.
- Flynn’s taxonomy classifies machines as SISD, SIMD, MISD or MIMD. A GPU uses SIMT: one instruction issued to a group of threads that each have their own registers.
- Arithmetic intensity, FLOPs per byte, compared with the machine’s ridge point, shows whether memory or arithmetic limits a computation. The roofline is reached only with enough reads in flight.
- A barrier costs the wait for the slowest processor plus the barrier itself.
- Work \(W\) counts operations and steps \(D\) the longest chain; \(\max(W/p, D) \le T_p \le W/p + D\). A work-efficient parallel algorithm does no more than a constant factor of the sequential work.
Chapter 2 opens up the GPU: how its processors are organized, how it keeps hundreds of memory reads in flight, and where the ridge point of the Jetson board used in this book lies.
Exercises
- A memory read has a latency of 600 cycles, and the memory accepts a new read every 3 cycles. How many reads must be in flight to reach its highest throughput?
- A program takes 10.0 s on one processor, 5.5 s on 2 and 4.0 s on 4. Compute the speedup and efficiency for each number of processors.
- A program spends 10 µs reading its input, 100 µs computing and 10 µs writing its output, and only the computing can be shared. Compute the serial fraction and Amdahl’s limit.
- The same program grows its problem with the number of processors, so that the serial fraction of the parallel run falls to 0.001. Estimate the speedup on 1,000 processors.
- Using Amdahl’s formula, what speedup would the Sandia programs of section 1.4, with a serial fraction of 0.8 percent, reach on 1,024 processors? What does Gustafson’s law give?
- An \(N \times N\) matrix product has an intensity of \(N/6\) FLOP per byte. For which \(N\) does it reach a ridge point of 40 FLOP per byte?
- A program downloads 10 GB over a network at 2 GB/s and compresses it on the CPU at 20 GB/s. Estimate the fraction of the time the CPU is busy and name the bound. Which change shortens the run more: a CPU twice as fast, or a network twice as fast?
- Explain why a program whose operations form one long dependency chain gains nothing from more processors.
- Name the class of each machine: one ordinary core; one vector instruction that adds 8 pairs; 4 cores, each running its own program; one instruction issued to many threads. Which of these is not one of Flynn’s classes?
- In figure 1.14, the work of processor 3 falls from 1,200 to 1,000 cycles. Compute the efficiency.
- A program spends 5% of its 1-core time in a serial part, and a GPU runs the rest 40 times faster. Compute the speedup with no copies, and with copies that take 3% of the 1-core time.
- Count \(W\) and \(D\) for the shifted scan and the tree scan of 8 values. On how many processors does each first match the sequential scan’s 7 units?
- A report compares a GPU kernel with the same parallel code run on 1 CPU thread. Explain why the speedup it quotes is larger than the speedup over the best sequential program.
- A memory system has a bandwidth of 1 TB/s and a read latency of 500 ns. Each read returns 32 bytes. How many reads must be in flight for a program to reach the bandwidth, and what fraction of it does a program reach with 1,000 reads in flight?
Sources and further reading
- Gene M. Amdahl, “Validity of the Single Processor Approach to Achieving Large-Scale Computing Capabilities,” AFIPS Conference Proceedings 30, 1967.
- John L. Gustafson, “Reevaluating Amdahl’s Law,” Communications of the ACM 31(5), 1988.
- John L. Gustafson, Gary R. Montry and Robert E. Benner, “Development of Parallel Methods for a 1024-Processor Hypercube,” SIAM Journal on Scientific and Statistical Computing 9(4), 1988.
- John D. C. Little, “A Proof for the Queuing Formula: L = λW,” Operations Research 9(3), 1961.
- Michael J. Flynn, “Very High-Speed Computing Systems,” Proceedings of the IEEE 54(12), 1966.
- Samuel Williams, Andrew Waterman and David Patterson, “Roofline: An Insightful Visual Performance Model for Multicore Architectures,” Communications of the ACM 52(4), 2009.
- NVIDIA, H100 Tensor Core GPU datasheet, for the 67 TFLOP/s and 3.35 TB/s of the SXM part.
- NVIDIA, GeForce RTX 4090 specifications, for the 1,008 GB/s of section 1.3.3.
- Richard P. Brent, “The Parallel Evaluation of General Arithmetic Expressions,” Journal of the ACM 21(2), 1974.
- Guy E. Blelloch, “Programming Parallel Algorithms,” Communications of the ACM 39(3), 1996, for work and depth as a way to compare parallel algorithms.
Chapter 2: GPU Hardware from First Principles
A graphics processing unit, or GPU, is a processor built for data parallelism: it runs the same instructions on a very large number of data elements at the same time. Chapter 1 showed that a processor reading from main memory waits hundreds of cycles for every value, and that the wait can be hidden only by keeping many independent operations in flight. A GPU is designed around that observation. Its parts, and the rules that decide how fast a program runs on them, are the subject of this chapter.
This chapter covers
- kernels, threads, blocks and grids: how work is handed to a GPU
- the parts of a GPU, from the whole chip down to a single thread
- the streaming multiprocessor (SM) and its schedulers
- the warp, a group of 32 threads that carry out each instruction together, and what happens when its threads take different sides of a branch
- how a block is divided into warps
- the memory hierarchy, from registers to the CPU’s memory
- coalescing: why neighboring threads should read neighboring addresses
- shared-memory banks and bank conflicts
- occupancy, and how switching between warps hides memory latency
2.1 The GPU at a glance
2.1.1 How a CPU and a GPU deal with memory latency
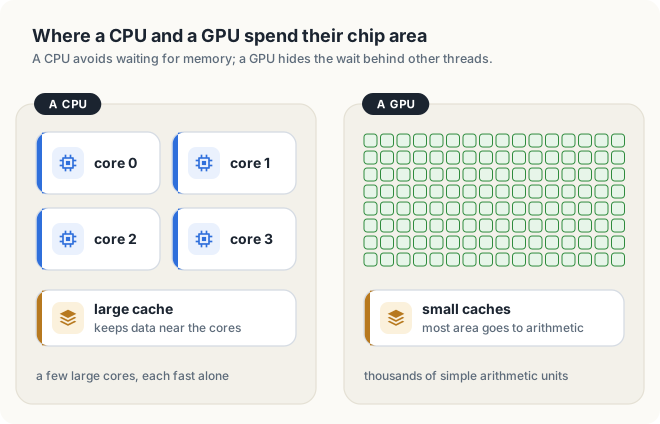
A CPU and a GPU handle the long wait for memory in opposite ways (figure 2.1).
A CPU core runs 1 sequence of instructions as fast as possible, and spends much of its chip area on avoiding waits. Large caches, small fast memories near a core that keep copies of recently used data, answer most reads without a trip to main memory. Prediction logic starts likely next instructions early. A desktop CPU has 4 to 32 such cores.
A GPU accepts that a read from main memory takes hundreds of cycles. It spends its area on thousands of simple arithmetic units and on room for tens of thousands of threads. A thread, as in Chapter 1, is 1 sequence of instructions with its own working values. While some threads wait for memory, others compute. In Chapter 1’s terms, a CPU core is built for low latency and a GPU for high throughput.
2.1.2 Kernels, threads, blocks and grids
A few terms describe how a program hands work to a GPU (figure 2.2).
- A kernel is a function that runs on the GPU.
- A launch starts a kernel from a program on the CPU. The GPU then runs many copies of the kernel at once.
- Each copy is 1 thread. A thread keeps its working values in registers, small storage slots inside a processor that each hold 1 value. Each thread also receives its own number, its index, and uses it to pick its share of the work.
- Threads are grouped into blocks of equal size. Threads of 1 block run on the same part of the GPU, so they can share fast memory and wait for each other.
- All blocks of 1 launch form the grid.
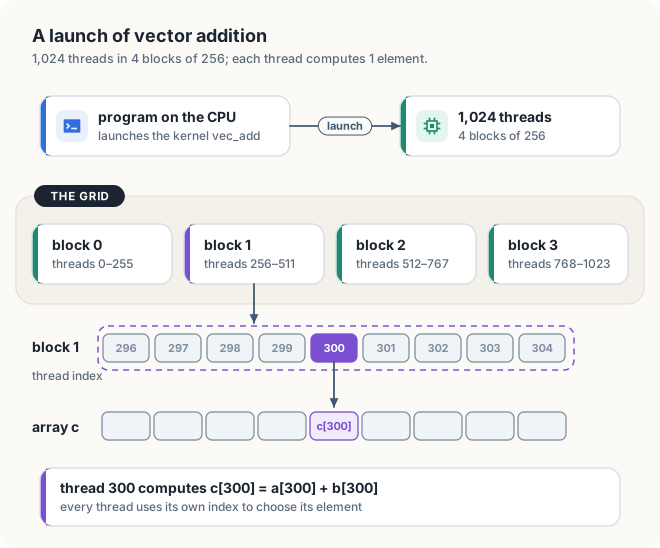
c[300].For vector addition with N = 1,024, every element needs 1 thread, so the launch needs 1,024 threads. A block holds 256 of them, so the grid needs 1,024 ÷ 256 = 4 blocks.
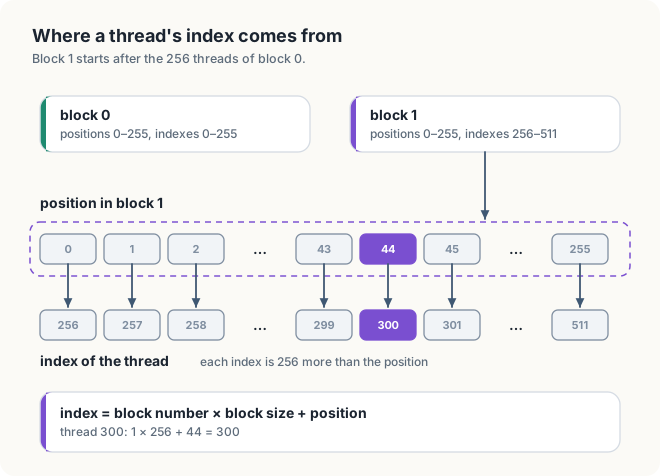
A thread finds its element through its index. Inside its block, each thread has a position, numbered from 0. Block 0 has positions 0 to 255, and so does block 1, so a position alone cannot tell a thread which element is its own. The blocks before a thread’s block hold 256 threads each, and its index counts them first:
\[ \text{index} = \text{block number} \times \text{block size} + \text{position} \]
Thread 300 is at position 44 of block 1, and 1 × 256 + 44 = 300 (figure 2.3). Going the other
way, 300 ÷ 256 = 1 with remainder 44 gives back its block and its position. Each thread
computes c[index], so the 1,024 threads cover the 1,024 elements once each, and no 2
threads write the same element.
Chapter 3 shows how a kernel reads its block number and position in code, and how blocks and grids can also be laid out in 2 or 3 dimensions, which suits images and volumes. The rest of this chapter describes where blocks and threads run.
2.1.3 From the chip to one thread
A GPU is built in levels, each made of copies of the next (figure 2.4).
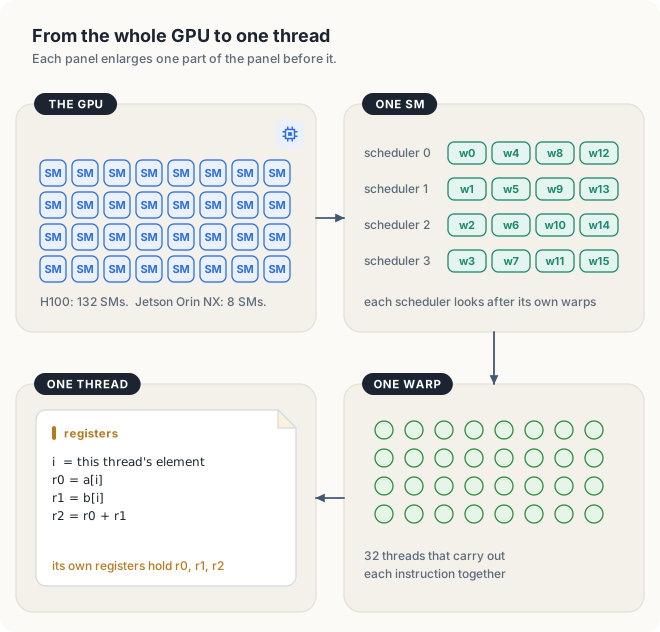
- Most of a GPU chip is a set of identical units called streaming multiprocessors, or SMs: 8 on a Jetson Orin NX, 132 on an H100 (section 2.1.4). Each block of a launch runs on 1 SM.
- An SM holds threads of several blocks at once. It has 4 schedulers, units that choose in every cycle which instruction runs next (section 2.2).
- An SM runs threads in groups of 32 called warps. The 32 threads of a warp carry out each instruction together (section 2.3).
- Each thread has its own registers for its working values.
2.1.4 GPUs in numbers
GPUs are built in very different sizes, from boards for robots to cards for data centers, and they share the design of this chapter. The table compares 7 of them. The compute capability, CC in the table, is NVIDIA’s version number for each generation of the design (section 2.11).
| GPU | Kind | CC | SMs | Memory | Bandwidth | FP32 peak |
|---|---|---|---|---|---|---|
| Jetson Orin NX 16 GB | embedded | 8.7 | 8 | 16 GB, shared | 102 GB/s | 2.4 TFLOP/s |
| Jetson AGX Thor | embedded | 11.0 | 20 | 128 GB, shared | 273 GB/s | 8.1 TFLOP/s |
| DGX Spark (GB10) | desktop AI | 12.1 | 48 | 128 GB, shared | 273 GB/s | ~31 TFLOP/s |
| GeForce RTX 4090 | desktop card | 8.9 | 128 | 24 GB | 1,008 GB/s | 82.6 TFLOP/s |
| GeForce RTX 5090 | desktop card | 12.0 | 170 | 32 GB | 1,792 GB/s | 104.8 TFLOP/s |
| A100 SXM 80 GB | data center | 8.0 | 108 | 80 GB | 2,039 GB/s | 19.5 TFLOP/s |
| H100 SXM | data center | 9.0 | 132 | 80 GB | 3,350 GB/s | 67 TFLOP/s |
CC is the compute capability, and “shared” marks memory that the GPU shares with the CPU.
The figures are NVIDIA’s published specifications, with peak arithmetic at the highest
clock rate. The SM counts of the Thor and the DGX Spark follow from their published numbers
of arithmetic units, 2,560 and 6,144, at 128 units per SM. The Orin NX figures were also
read from a board with cudaGetDeviceProperties, a CUDA function that Chapter 3
introduces.
The memory column shows 2 kinds of system. The Jetson modules and the DGX Spark are integrated: the CPU and the GPU share one set of memory chips. The graphics cards and data-center GPUs are discrete: the GPU has memory chips of its own, beside it on the card, and data moves to it from the CPU’s memory over a link (Chapter 4).
2.1.5 The ridge point of each GPU
Chapter 1 defined the ridge point of a machine as its peak arithmetic divided by its memory bandwidth: the arithmetic intensity at which a computation stops being limited by memory. For the H100,
\[ \frac{67 \times 10^{12}\ \text{FLOP/s}}{3.35 \times 10^{12}\ \text{B/s}} = 20\ \text{FLOP per byte} \]
Dividing FLOPs per second by bytes per second leaves FLOPs per byte. The result has a direct meaning: in the time an H100’s memory delivers 1 byte, its arithmetic units can perform 20 FLOPs. A kernel that performs fewer than 20 FLOPs on each byte it reads leaves those units waiting for data. The same division for the other GPUs of the table gives very different values.
| GPU | Ridge point (FLOP per byte) |
|---|---|
| A100 SXM 80 GB | 19.5 / 2.039 ≈ 10 |
| H100 SXM | 67 / 3.35 = 20 |
| Jetson Orin NX 16 GB | 2.4 / 0.102 ≈ 24 |
| Jetson AGX Thor | 8.1 / 0.273 ≈ 30 |
| GeForce RTX 5090 | 104.8 / 1.792 ≈ 58 |
| GeForce RTX 4090 | 82.6 / 1.008 ≈ 82 |
| DGX Spark (GB10) | 31 / 0.273 ≈ 114 |
The data-center GPUs have the lowest ridge points, because their memory, stacked beside the GPU chip, delivers several terabytes per second. The graphics cards and the DGX Spark have far more arithmetic for each byte of bandwidth, so a kernel needs more reuse to reach their peak. A kernel that is compute-bound on an A100 can be memory-bound on an RTX 4090.
Vector addition, at 1/12 of a FLOP per byte, is memory-bound on every GPU in the table.
2.2 The streaming multiprocessor
Every thread of a launch runs on an SM. Figure 2.5 shows the parts of 1 SM of an H100.
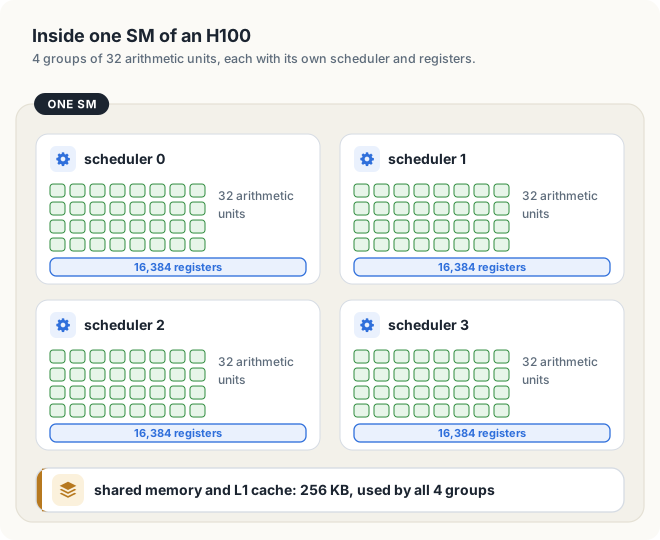
- Arithmetic units. 4 groups of 32 units for 32-bit floating-point numbers, 128 per SM, often called CUDA cores. A group has 32 units because a warp has 32 lanes (section 2.3): 1 instruction keeps a whole group busy. Each unit performs 1 fused multiply-add per cycle: it computes \(a \times b + c\) in 1 step, which counts as 2 FLOPs.
- Schedulers. Each group has 1 scheduler. In every cycle a scheduler picks 1 warp whose next instruction is ready and sends that instruction to its 32 units.
- Registers. 65,536 registers of 4 bytes each, 65,536 × 4 = 262,144 bytes or 256 KB, split into 4 parts of 65,536 ÷ 4 = 16,384, 1 per group. Each thread on the SM gets its own registers from this file. Section 2.9 shows how the registers a thread needs limit the number of threads that fit.
- Shared memory and L1 cache. 1 pool of 256 KB serves 2 purposes. Shared memory is memory that all threads of a block can read and write, so threads of a block exchange data through it. The L1 cache keeps copies of data the SM has read from main memory. On an H100, up to 228 KB of the pool can serve as shared memory.
- Other units. Units for integer arithmetic; special function units, which compute
fast approximations of
sin,cos,expand square roots; and tensor cores, which multiply small matrices in 1 operation (Chapter 11).
Peak arithmetic follows from these parts. Each unit completes 1 fused multiply-add, 2 FLOPs, per cycle, and the clock rate counts cycles per second, so peak FLOPs per second = 2 × number of units × clock rate. For an H100, 2 × 132 SMs × 128 units × 1.98 GHz = 67 TFLOP/s. For an RTX 4090, 2 × 128 × 128 × 2.52 GHz = 82.6 TFLOP/s.
NOTE: SMs of other generations differ in detail. An A100 SM has 64 units for 32-bit floating-point numbers, not 128. The number of threads and blocks an SM can hold, and its shared memory, depend on the compute capability; section 2.9 lists them.
2.3 The warp
2.3.1 One instruction, 32 lanes
A warp is a group of 32 threads that an SM schedules as 1 unit. A scheduler issues 1 instruction to a warp, and all 32 threads carry it out in the same cycle, each on values in its own registers. The 32 positions in a warp are its lanes: lane 0 holds the warp’s first thread, lane 1 the next, and so on.
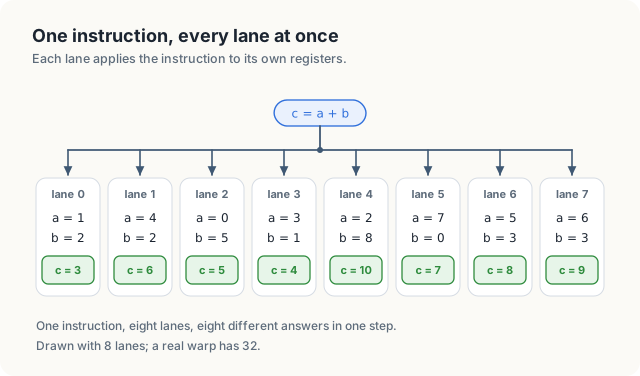
Figure 2.6 draws 8 lanes instead of 32, to keep the values readable. A single instruction,
c = a + b, gives 8 different results, because each lane holds its own a and b. Chapter
1 called this design SIMT (section 1.7).
Grouping threads saves chip area. Fetching and decoding an instruction costs the same for 1 thread as for 32, so a warp shares that cost among 32 threads and leaves more area for arithmetic units.
2.3.2 Why 32
NVIDIA GPUs have used warps of 32 threads since the first CUDA GPUs. The size balances 3 effects:
- A wider warp shares each instruction’s cost among more threads.
- 32 threads reading 4 bytes each read 128 bytes, the size of 1 cache line. Section 2.7 shows why this match helps.
- A wider warp loses more when its threads need to do different things (section 2.3.3).
2.3.3 Divergence
All lanes of a warp carry out the same instruction. An if can send some threads of a warp
one way and the rest the other way, and a warp cannot run both sides at once. It runs them
in turn (figure 2.7).
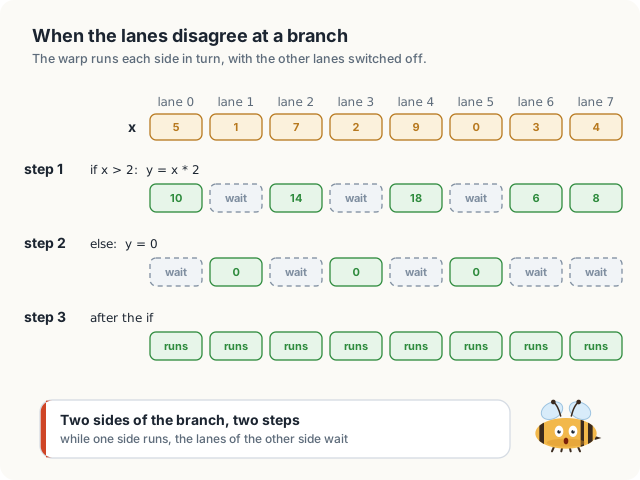
In figure 2.7 the condition x > 2 holds in 5 lanes and fails in 3.
- Step 1 runs the
ifside. 5 lanes computey = x * 2; the other 3 are switched off. - Step 2 runs the
elseside. 3 lanes computey = 0; the other 5 are switched off. - Step 3 comes after the branch, and all 8 lanes run together again.
A branch on which lanes of a warp disagree is called divergence. Results stay correct, but both sides cost time: when each side is long, a diverging warp takes about twice as long. Chapter 5 shows how to measure divergence and how to arrange data so lanes tend to agree.
2.4 Blocks, grids, and warps
A launch asks for a grid of blocks with an equal number of threads each, for example 256. Hardware turns each block into warps in 2 steps.
Step 1: each block goes to 1 SM, whole. All threads of a block stay on 1 SM from start to finish, so they can share that SM’s shared memory and wait for each other at a barrier (Chapter 5). An SM can hold several blocks at once when it has room; section 2.9 counts how many.
Step 2: each block is cut into warps of 32 consecutive threads. Threads 0 to 31 form warp 0, threads 32 to 63 form warp 1, and so on (figure 2.8). A program never creates warps itself; warps are how an SM runs a block.
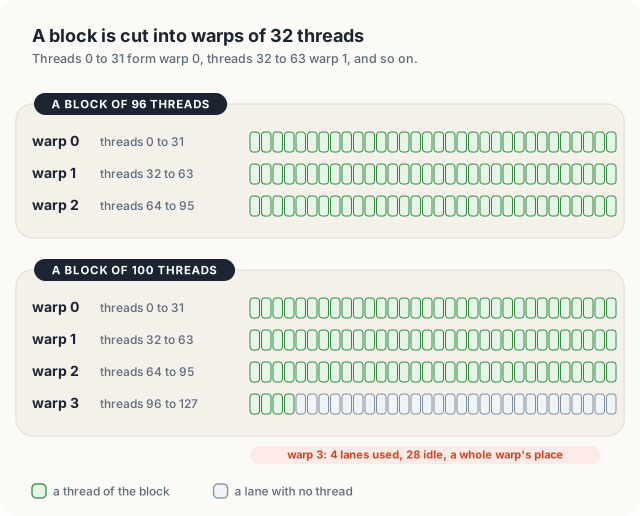
A block of 100 threads needs 4 warps: 3 full warps hold 96 threads, and the 4 threads left over need a 4th warp. In general a block needs its size ÷ 32 warps, rounded up. The 4th warp’s other 28 lanes do no work, yet the warp still takes a full warp’s place on the SM. Block sizes are therefore almost always multiples of 32, such as 128 or 256.
A block can also be 2-dimensional, for example 16 × 16 threads covering a tile of an image. Its threads are numbered row by row before the block is cut, so its first 2 rows of 16 form warp 0. Chapter 3 shows the numbering.
| Block | Warp | |
|---|---|---|
| chosen by | the program, at launch | the hardware |
| size | up to 1,024 threads | always 32 threads |
| its threads can | share memory and wait for each other | carry out each instruction together |
2.5 The memory hierarchy
A thread can keep data in several kinds of memory. Memory closer to the arithmetic units is faster and smaller. Together, these levels form the memory hierarchy (figure 2.9).
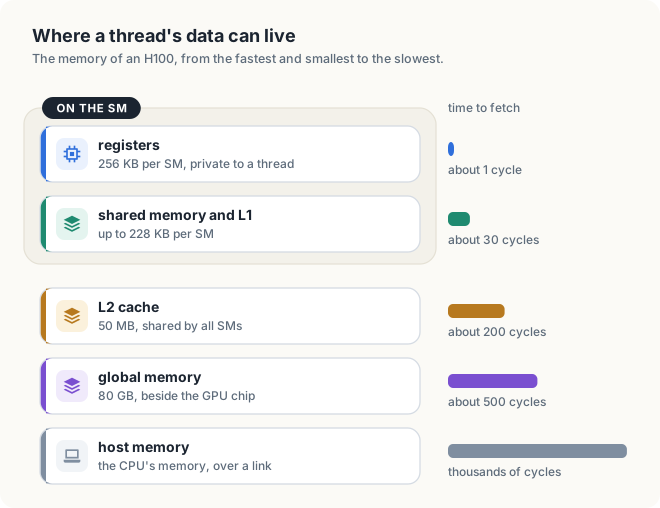
Registers belong to 1 thread. A thread’s local variables live in registers when they fit, and an instruction reads a register at no extra cost. An SM’s 65,536 registers are shared out among all its threads, so a thread needing many registers leaves room for fewer threads (section 2.9). When a thread needs more registers than it gets, the compiler moves some values out to slow memory, a spill; Chapter 7 shows how to detect one.
Shared memory belongs to 1 block and sits on the SM. Any thread of a block can read what another thread of it wrote, so threads of a block cooperate through shared memory. A read takes 20 to 30 cycles, about 20 times less than a read from main memory. A program decides what goes into shared memory and when; Chapters 7 to 9 rely on it.
L1 cache uses the same on-chip memory as shared memory, but hardware manages it: data read from main memory stays there in case it is read again soon. Caches store data in fixed-size pieces called lines, 128 bytes each on these GPUs.
L2 cache is 1 cache shared by all SMs, 50 MB on an H100, with reads of about 200 cycles. Every SM goes through it, so blocks on different SMs see each other’s writes there (Chapter 5).
Global memory is a GPU’s main memory: 80 GB on an H100, in memory chips beside the GPU chip. Every array a program allocates for the GPU lives there (Chapter 4). Its bandwidth is very high, but a single read takes about 500 cycles, and most optimization work aims to read it less often.
Host memory is the CPU’s memory; CUDA calls the CPU the host. A request for host memory leaves the GPU and crosses a link to the CPU, so it is the slowest level. Chapter 4 covers moving data across that link efficiently.
2 read-only paths complete the hierarchy. Constant memory is fast when every thread of a warp reads the same value, such as a kernel’s parameters. Texture memory is designed for reading 2-dimensional images. Chapter 7 covers both.
NOTE: On integrated systems, such as Jetson modules and DGX Spark, CPU and GPU share 1 set of memory chips, so global memory and host memory are the same hardware. The hierarchy still holds: a read from those chips takes hundreds of cycles, while registers and shared memory sit on the SM.
2.6 The latency table
The table gives each level’s read time. Values are typical for a recent GPU and rounded; Chapter 7 measures real ones.
| Where the data is | Time to read it | Location |
|---|---|---|
| register | about 1 cycle | inside the SM |
| shared memory | 20 to 30 cycles | inside the SM |
| L1 cache | about 30 cycles | inside the SM |
| L2 cache | about 200 cycles | elsewhere on the chip |
| global memory | 400 to 800 cycles | in separate memory chips |
| host memory | thousands of cycles, plus the transfer | across a link to the CPU |
Read time grows with distance. A signal needs time to travel, and data further from the arithmetic units passes through more circuits on its way. Leaving the SM is the largest step: a read from global memory costs about 20 times a read from shared memory.
Worked example: reading 1 value 20 times
A kernel needs the same value 20 times.
- Reading it from global memory each time costs 20 × 500 = 10,000 cycles.
- Reading it once from global memory into shared memory, then 20 times from shared memory, costs 500 + 20 × 25 = 1,000 cycles.
The second way is 10 times cheaper. Chapter 9 builds a matrix multiplication on this trade.
2.7 Coalescing: how a warp reads memory
1 instruction drives all 32 lanes of a warp (section 2.3). When that instruction reads global memory, a warp asks for 32 values at once, 1 per lane. How fast they arrive depends on where those 32 values lie in memory.
2.7.1 Sectors
Global memory does not deliver single values. It delivers 32-byte pieces called sectors; 4 sectors make 1 cache line of 128 bytes. A line of 128 bytes holds 128 ÷ 4 = 32 floats, 1 for each lane of a warp. Fetching a sector costs the same however many of its bytes a warp uses, so a warp’s read costs about 1 fetch per sector it touches.
2.7.2 Worked by hand
Figure 2.10 shrinks everything by a factor of 4: a warp of 8 lanes, each reading 1 float of
4 bytes, and sectors of 8 floats.
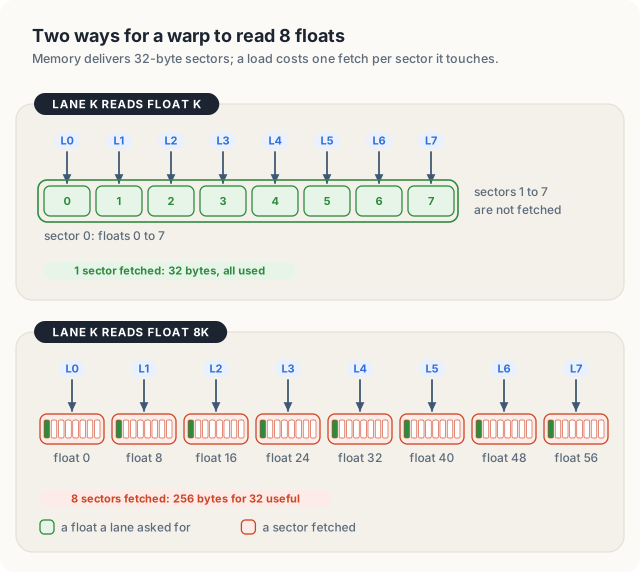
- Lane k reads float k. Floats 0 to 7 lie side by side in sector 0. Memory fetches 1 sector, 32 bytes, and every byte is used.
- Lane k reads float 8k. Floats 0, 8, 16 and so on up to 56 each lie in a different sector. Memory fetches 8 sectors, 256 bytes, to deliver the same 32 useful bytes: 8 times the traffic for the same result.
A real warp behaves the same way with larger numbers. 32 lanes reading 32 consecutive floats need 128 bytes, 4 sectors. Floats 32 apart are 32 × 4 = 128 bytes apart, a whole line, so 32 lanes reading every 32nd float touch 32 different sectors and fetch 32 × 32 = 1,024 bytes for 32 × 4 = 128 useful ones.
2.7.3 The rule
A read whose addresses fall into as few sectors as possible is coalesced; a read whose addresses spread out is uncoalesced. Hardware does not rearrange a warp’s requests: it fetches every sector any lane needs.
Neighboring threads should read neighboring addresses.
Most kernels are memory-bound (Chapter 1), and for them this rule alone can change running time several times over. Chapter 7 measures the difference.
2.8 Shared-memory banks
Shared memory sits on the SM and has to answer all 32 lanes of a warp at once. It is built from 32 separate memory arrays called banks, and each bank delivers 1 word of 4 bytes per cycle. Working side by side, 32 banks deliver 32 words in 1 cycle: 1 word for each lane.
Words are spread over the banks in turn, the way cards are dealt to 32 players. Word 0 goes to bank 0, word 1 to bank 1, and so on to word 31 in bank 31; word 32 starts the next round in bank 0. A word’s bank is therefore the remainder when its number is divided by 32:
\[ \text{bank} = \text{word number} \bmod 32 \]
Word 70, for example, is 2 full rounds of 32 plus 6, so it lies in bank 6.
A warp’s read takes 1 cycle when no bank is asked for more than 1 word. When 2 lanes ask 1 bank for different words, the bank delivers them in turn. A read that has to wait for a bank in this way has a bank conflict.
Figure 2.11 uses 8 banks and 8 lanes, so a word’s bank is its number modulo 8. Words are drawn in rows of 8, so each column is 1 bank.
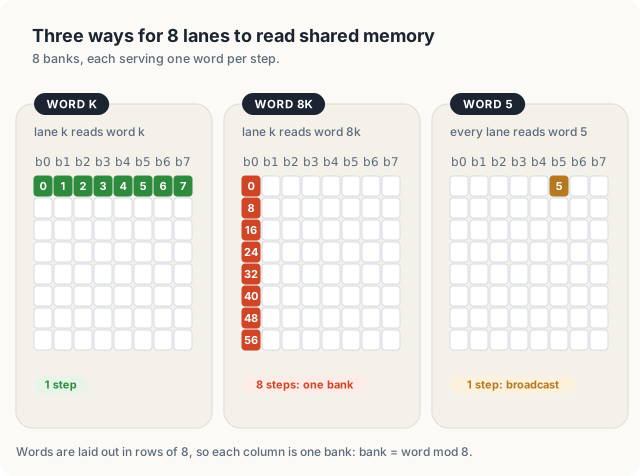
- Lane k reads word k. Words 0 to 7 lie in banks 0 to 7, 1 each: 1 step.
- Lane k reads word 8k. Words 0, 8, 16 and so on all lie in bank 0, which serves them 1 at a time: 8 steps for 1 read.
- Every lane reads word 5. Many lanes ask 1 bank for the same word. The bank reads it once and hands it to every lane, a broadcast: 1 step.
With 32 banks, the worst case is 32 lanes asking 1 bank for 32 different words: 32 steps. In general, a warp’s read takes as many steps as its busiest bank has different words to deliver.
The middle case appears whenever threads read down a column of a 32 × 32 table of floats in shared memory. Element (row r, column c) is word 32r + c, and (32r + c) mod 32 = c: the row drops out, so every element of column c lies in bank c. Chapter 7 shows the usual fix. With 1 unused word added to each row, element (r, c) becomes word 33r + c, whose bank is (r + c) mod 32. That bank differs from row to row, so the column spreads across all 32 banks.
A warp reads a shared-memory table of floats with 32 columns, each lane reading one element of the same column. How many steps does the read take, and why?
32 steps. Rows of 32 floats are 32 words long, so every element of a column has the same word number modulo 32 and lies in the same bank. The bank delivers the 32 different words one at a time.
2.9 Occupancy
2.9.1 Why an SM holds many warps
Threads an SM holds at a given moment are its resident threads, and their warps its resident warps. When 1 warp reads global memory and must wait about 500 cycles, the scheduler switches, at no cost, to another resident warp that is ready. More resident warps mean better odds that 1 of them is ready.
An SM’s occupancy is its number of resident warps divided by the most it can hold. An H100 SM holds up to 2,048 threads, which is 2,048 ÷ 32 = 64 warps, so 32 resident warps give an occupancy of 32 ÷ 64 = 50%.
2.9.2 What limits occupancy
4 resources limit how many threads an SM holds, and whichever runs out first sets the occupancy: registers, resident threads, resident blocks and shared memory. Every compute capability below has 65,536 registers per SM; the other 3 limits vary.
| Compute capability | Examples | Resident threads (warps) | Resident blocks | Shared memory |
|---|---|---|---|---|
| 8.0 | A100 | 2,048 (64) | 32 | up to 164 KB |
| 8.6 | GeForce RTX 30 series | 1,536 (48) | 16 | up to 100 KB |
| 8.7 | Jetson Orin | 1,536 (48) | 16 | up to 164 KB |
| 8.9 | GeForce RTX 40 series | 1,536 (48) | 24 | up to 100 KB |
| 9.0 | H100 | 2,048 (64) | 32 | up to 228 KB |
| 10.0 | B200 | 2,048 (64) | 32 | up to 228 KB |
| 12.x | GeForce RTX 50 series, DGX Spark | 1,536 (48) | 32 | up to 100 KB |
Values come from NVIDIA’s CUDA C++ Programming Guide and its tuning guide for each architecture.
Worked example: the register budget, blocks of 256 threads on an H100 SM
A compiler decides how many registers each thread of a kernel needs; Chapter 9 shows how to see that number and how to cap it.
| Registers per thread | Registers per block | Blocks that fit | Resident threads | Occupancy |
|---|---|---|---|---|
| 32 | 256 × 32 = 8,192 | 65,536 / 8,192 = 8 | 2,048 | 100% |
| 64 | 16,384 | 4 | 1,024 | 50% |
| 128 | 32,768 | 2 | 512 | 25% |
Each row divides the SM’s 65,536 registers by 1 block’s need: the register file has enough for 8, 4 or 2 blocks. The thread limit allows 2,048 / 256 = 8 blocks and the block limit 32, and this kernel uses no shared memory, so registers set the limit in every row.
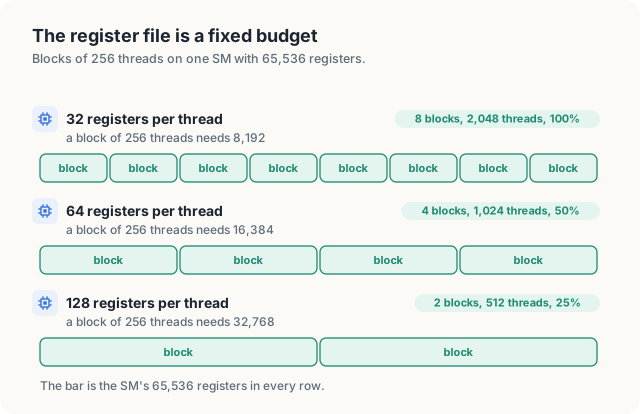
As a formula, with \(T_B\) threads per block and \(R_T\) registers per thread, the number of blocks that fit on an SM is the smallest of
\[ \left\lfloor \frac{65{,}536}{T_B \cdot R_T} \right\rfloor,\quad \left\lfloor \frac{\text{thread limit}}{T_B} \right\rfloor,\quad \text{block limit},\quad \left\lfloor \frac{\text{shared memory per SM}}{\text{shared memory per block}} \right\rfloor \]
where \(\lfloor\ \rfloor\) means rounding down, since part of a block cannot be resident. Occupancy is then that number of blocks times \(T_B\), divided by the thread limit. Chapter 25 shows the CUDA function that computes it.
2.9.3 More is not always better
High occupancy helps a kernel that often waits for memory, because more warps give the scheduler more chances to find 1 that is ready. High occupancy is not a goal in itself.
- A kernel whose data already sits in registers rarely waits, and can run at full speed with few warps.
- Forcing a kernel to use fewer registers, so more warps fit, can make the compiler spill values to slow memory, adding the very memory traffic the extra warps were meant to hide.
- A kernel keeping a large tile of data in shared memory may run fewer blocks per SM on purpose, because each block then does more work per byte it reads.
The aim is enough ready warps to keep the schedulers busy, not the largest possible number.
2.10 The SM in action: time slicing
Figure 2.13 follows 1 scheduler with 4 warps. To keep the picture small, a read from memory takes 8 cycles instead of about 500.
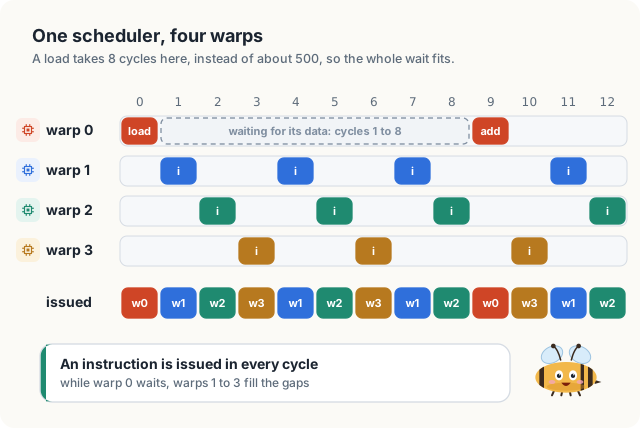
- In cycle 0, warp 0 issues a read. Its data arrives at the end of cycle 8.
- In cycles 1 to 8, the scheduler issues instructions from warps 1, 2 and 3, whichever is ready. No cycle stays empty.
- In cycle 9, warp 0 has its data and issues the add that needed it.
No code in a program makes this happen. A scheduler picks among its resident warps in every cycle, and switching costs nothing, because each warp’s registers stay where they are. A program’s part is to provide enough warps (occupancy) and enough independent work in each warp.
Little’s law (Chapter 1, section 1.1.4) gives the number of warps needed. A scheduler issuing 1 instruction per cycle against a latency of 500 cycles needs about 500 independent instructions in flight to stay busy. No SM holds 500 warps per scheduler, and none needs to: a warp usually has several independent instructions between reads, and can have several reads in flight at once. In practice, a few dozen warps per SM cover the wait.
2.11 Architecture generations
The design described in this chapter has been stable across NVIDIA GPUs for more than a decade, while the sizes have changed. Each generation is identified by a compute capability, a version number of the form major.minor.
| Compute capability | Architecture | Examples |
|---|---|---|
| 7.x | Volta, Turing | V100, GeForce RTX 20 series |
| 8.0, 8.6, 8.7 | Ampere | A100 (8.0), GeForce RTX 30 series (8.6), Jetson Orin (8.7) |
| 8.9 | Ada Lovelace | GeForce RTX 40 series |
| 9.0 | Hopper | H100 |
| 10.0, 11.0, 12.0, 12.1 | Blackwell | B200 (10.0), Jetson AGX Thor (11.0), GeForce RTX 50 series (12.0), DGX Spark (12.1) |
Each generation changes the number of SMs, the size of shared memory, the tensor cores and
many of the limits of section 2.9. A performance figure is only meaningful together with the
compute capability on which it was measured. The deviceQuery sample that ships with CUDA
prints the limits of the GPU it runs on; Chapter 25 shows how to read its output.
Common mistakes
- Treating higher occupancy as always faster. Spilled registers or smaller shared-memory tiles can make a kernel at 50% occupancy faster than one at 100%. Measure.
- Forgetting the warp. A kernel is written for one thread, but the hardware runs warps. Divergence, coalescing and bank conflicts all depend on what the 32 lanes of a warp do together.
- Reading a shared-memory table by column. A column of a 32 × 32 table of floats lies in one bank, so reading it takes 32 times as long as reading a row. Padding each row by one element fixes it (Chapter 7).
- Quoting one GPU’s numbers for another. Check the compute capability and the limits of the GPU the program actually runs on.
Summary
- A kernel is a function that runs on the GPU. A launch runs it as many threads, organized in blocks; the blocks of a launch form the grid.
- A GPU is a set of SMs. Each block runs on one SM, and the SM runs its threads in warps of 32 that carry out each instruction together.
- When the lanes of a warp disagree at a branch, the 2 sides run one after the other: divergence.
- A block is divided into warps of 32 consecutive threads, so block sizes should be multiples of 32.
- The memory hierarchy runs from registers (about 1 cycle) through shared memory (about 30), the L2 cache (about 200) and global memory (about 500) to host memory.
- Global memory delivers 32-byte sectors, so neighboring threads should read neighboring addresses: coalescing.
- Shared memory has 32 banks; lanes that ask one bank for different words must wait for each other.
- Occupancy is the share of an SM’s warp places that are filled. Registers usually limit it. Enough warps let the scheduler hide memory latency; more than enough brings nothing.
Chapter 3 turns from the hardware to the code: how a kernel is written, how a grid of blocks is described, and how each thread finds its own piece of work.
Exercises
- A kernel uses 64 registers per thread. How many threads can one SM hold before its 65,536 registers run out?
- The same kernel uses 128 registers per thread. What share of an H100 SM’s 2,048 thread places can be filled?
- On the Orin NX an SM holds at most 1,536 threads and 16 blocks. A kernel uses 32 registers per thread and blocks of 256 threads. How many blocks fit on one SM, and which limit sets the number?
- A warp reads 32 consecutive
ints of 4 bytes each. How many 32-byte sectors does it touch? How many if the lanes read every 32ndint, and how many bytes are fetched in each case? - Why must all the threads of a block run on the same SM? What 2 features does this make possible?
- How many steps does a shared-memory read take when all 32 lanes read the same 4-byte word? And when they read words 128 bytes apart?
- A warp runs
if (i % 2 == 0) { A } else { B }, whereiis the thread’s index and A and B each take 10 cycles. How long does the branch take, and how long would it take if every lane took the same side? - A launch of vector addition with N = 1,000,000 uses blocks of 256 threads. How many blocks does the grid need, and how many threads of the last block have no element to compute?
Sources and further reading
- NVIDIA, CUDA C++ Programming Guide, “Hardware Implementation” and “Compute Capabilities”: https://docs.nvidia.com/cuda/cuda-c-programming-guide/
- NVIDIA, H100 Tensor Core GPU Architecture whitepaper, and the H100 data sheet, for the H100 figures in this chapter.
- NVIDIA, Jetson Orin NX Series and Jetson Thor Series module data sheets, the DGX Spark hardware overview (https://docs.nvidia.com/dgx/dgx-spark/hardware.html), and the GeForce RTX 4090 and 5090 specifications, for the other figures of section 2.1.4.
- NVIDIA, Ampere, Ada and Blackwell tuning guides, for the limits per SM in section 2.9: https://docs.nvidia.com/cuda/blackwell-tuning-guide/
- David B. Kirk, Wen-mei W. Hwu and Izzat El Hajj, Programming Massively Parallel Processors: A Hands-on Approach, 4th ed., Morgan Kaufmann, 2022.
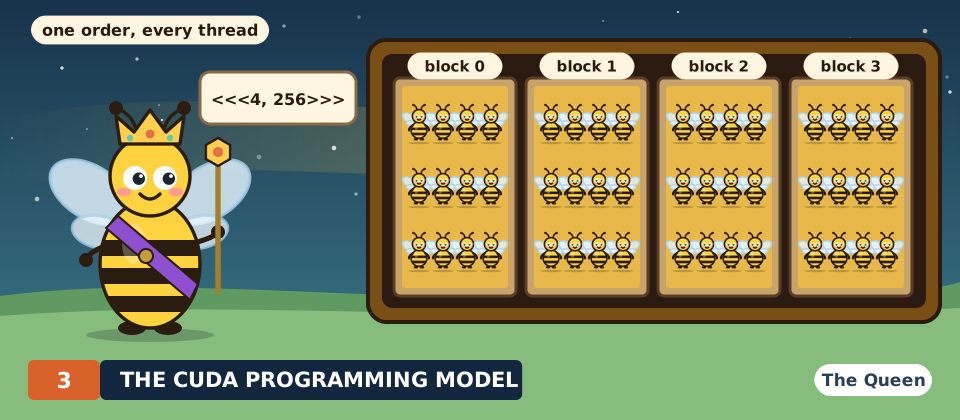
Chapter 3: The CUDA Programming Model
CUDA is NVIDIA’s platform for running general-purpose programs on its GPUs. Its programming model is C++ with a small number of additions: a way to mark a function as a kernel, a syntax to launch it as a grid of blocks, built-in variables that tell each thread who it is, and library functions that move data between the CPU’s memory and the GPU’s. Chapter 2 described the hardware that runs these programs. This chapter writes the first complete program, vector addition, and runs it.
Every program in the chapter appears twice: in CUDA C++, and in Rust with cuda-oxide, NVIDIA’s compiler that turns Rust functions into GPU kernels. The two versions take the same steps, so each idea is seen from both sides. Part V of the book uses cuda-oxide throughout.
This chapter covers
- host and device: the 2 processors and 2 memories of a CUDA program
- the function qualifiers
__global__,__device__and__host__ - launching a kernel as a grid of blocks, in 1, 2 or 3 dimensions
- the built-in variables
threadIdx,blockIdx,blockDimandgridDim - the global index formula, and rounding a grid up with a guard
- the first complete program: vector addition, with its real output
- allocating and copying memory with
cudaMallocandcudaMemcpy - why a launch is asynchronous, and how to check for errors
- how
nvcccompiles a.cufile, and howcargo oxidebuilds the Rust version
The complete code of the chapter is in
code/ch03_vector_add/
for C++ and in
code/oxide/ch03_basics/
for Rust.
3.1 Host and device
A CUDA program runs on 2 processors. CUDA calls the CPU and its memory the host, and
the GPU and its memory the device (figure 3.1). The program’s main function runs on
the host. Kernels run on the device.
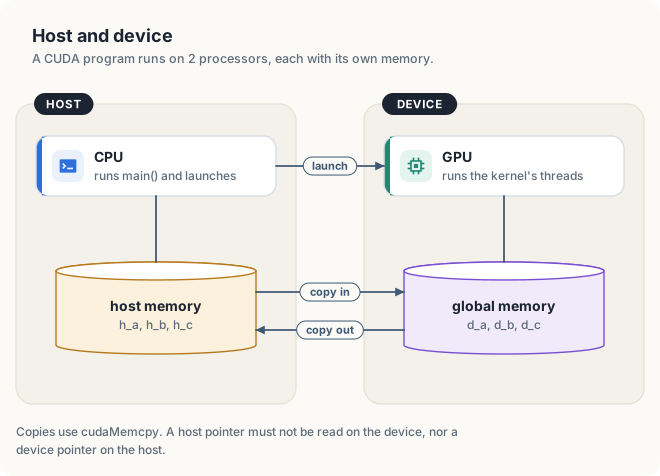
Each side has its own address space: the set of memory addresses its code can use. An
address on 1 side means nothing on the other. A pointer is a variable that holds an
address, so a pointer to device memory, a device pointer, must not be read on the host,
and a host pointer must not be read on the device. Data crosses between the 2 memories
only when the program copies it. This book names host arrays h_a, h_b, and device
arrays d_a, d_b, so the side each pointer belongs to is always visible.
The separation follows the hardware. On a discrete GPU, such as an RTX 4090 or an H100, global memory is a separate set of chips on the GPU’s card, and every copy crosses a link between the card and the CPU (Chapter 2, section 2.1.4).
NOTE: On integrated systems such as Jetson modules and DGX Spark, host and device share 1 set of memory chips. The programs in this chapter still allocate device memory and copy data explicitly, so they run unchanged on every NVIDIA GPU. In Chapter 4, we show how integrated systems can avoid the copies.
3.2 Function qualifiers
A C++ compiler needs to know which functions to compile for the CPU and which for the GPU. CUDA marks them with a function qualifier, a keyword written before the function’s return type.
| Qualifier | Runs on | Called from | Typical use |
|---|---|---|---|
__global__ | device | host | a kernel |
__device__ | device | device code | a helper called by a kernel |
__host__ | host | host code | an ordinary function; the default |
A __global__ function is a kernel. It must return void, because thousands of threads
run it at once and there is no single caller to receive a return value; a kernel delivers
its results by writing to memory. The 2 qualifiers __host__ __device__ together compile
1 function for both sides, which suits small helpers such as a function that clamps a value
to a range (Chapter 10).
In Rust with cuda-oxide, an attribute plays the part of the qualifier. #[kernel] marks a
kernel and #[device] a helper that runs on the GPU, and both live in a module marked
#[cuda_module], which cuda-oxide compiles for the GPU.
#![allow(unused)]
fn main() {
#[cuda_module]
mod kernels {
    #[device]
    fn square(x: f32) -> f32 { x * x }               // helper, GPU only

    #[kernel]
    pub fn squares(input: &[f32], mut out: DisjointSlice<f32>) {
        // ... each thread computes 1 element, using square() ...
    }
}
}
__device__ float square(float x) { return x * x; } // helper, GPU only
__global__ void squares(float* out, const float* in, int n) // kernel, launched from the host
{
// ... each thread computes 1 element, using square() ...
}
3.3 Launching a kernel: grids and blocks
3.3.1 A 1-dimensional launch
A launch names the kernel, then the shape of the work between triple angle brackets, then the kernel’s arguments:
#![allow(unused)]
fn main() {
let add = module.prepare_add_vectors(LaunchConfig1D::new(blocks, BLOCK, 0))?;
module.add_vectors(&stream, &add, &a_dev, &b_dev, &mut c_dev)?;
}
addVectors<<<blocks, threadsPerBlock>>>(d_a, d_b, d_c, n);
The part between <<< and >>> is the execution configuration. Its first number is
the number of blocks in the grid, and its second the number of threads in each block. The
launch kernel<<<3, 8>>> therefore starts 3 × 8 = 24 threads (figure 3.2).
In Rust, a launch takes 2 calls: prepare_ checks the configuration against what the kernel
declares, and the second call runs it. LaunchConfig1D::new(blocks, threads, 0) holds the
same 2 numbers as <<<blocks, threads>>>; its last argument, 0 here, is the shared memory
each block asks for (Chapter 7).
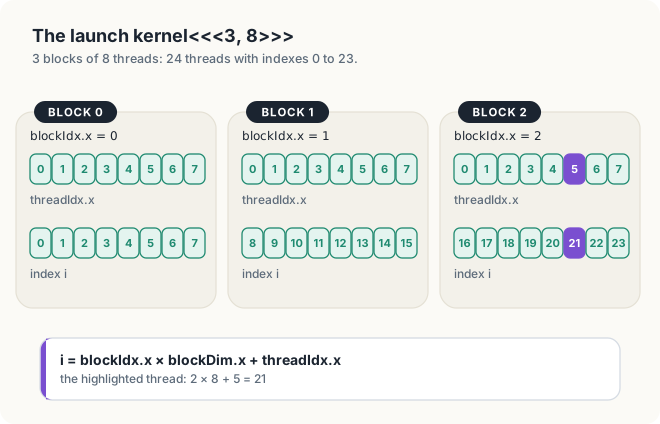
kernel<<<3, 8>>>: 3 blocks of 8 threads, with each thread's position in its block and its index.A launch states how much work there is and how it is grouped. It does not state an order. The GPU decides which SM runs which block, and when, so blocks may run in any order and must not depend on each other. In Section 3.6, we show a real run in which block 1 printed before block 0.
3.3.2 2 and 3 dimensions
Many kinds of data have 2 or 3 dimensions: an image has rows and columns, and a medical
scan or a simulated volume has layers as well. CUDA lets a grid and its blocks have the same
shape. Both numbers of the execution configuration can be a dim3, a small type with 3
fields, x, y and z; a field that is not given is 1.
fn main() -> Result<(), Box<dyn std::error::Error>> {
    // ...
    let threads_per_block = (4, 4); // 4 x 4 = 16 threads per block
    let blocks = (2, 2); // 2 x 2 = 4 blocks
    let config = LaunchConfig2D::new(blocks, threads_per_block, 0);

    let pixels = module.prepare_pixel_numbers(config)?;
    module.pixel_numbers(&stream, &pixels, RowWidth::new(&mut image, 8))?;
    // ...
}
dim3 threadsPerBlock(4, 4); // 4 × 4 = 16 threads per block, z = 1
dim3 blocks(2, 2); // 2 × 2 = 4 blocks
kernel<<<blocks, threadsPerBlock>>>(...);
The 4 blocks of 4 × 4 threads cover an image of 8 × 8 pixels, 1 thread per pixel (figure 3.3). Each thread computes its column and row with the same formula as in 1 dimension, once for x and once for y.
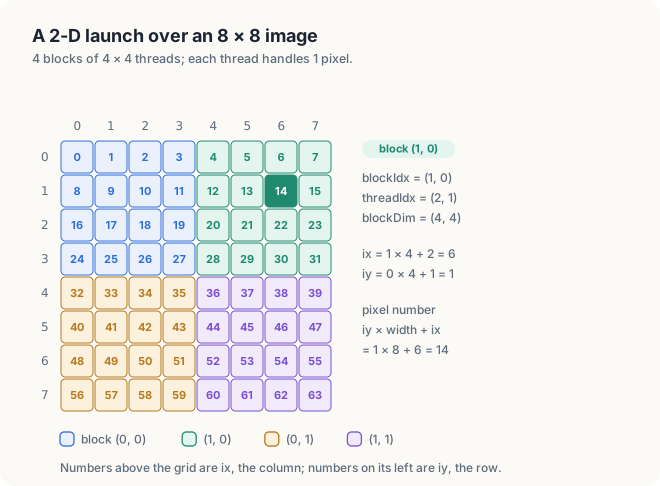
A block can have depth too. Figure 3.4 shows a block of dim3(4, 4, 2): 2 layers of 4 × 4
threads. The hardware numbers a block’s threads with x changing fastest, then y, then z, and
cuts that numbering into warps of 32 (Chapter 2, section 2.4). A row of 4 threads therefore
counts 4, and a layer of 16 counts 16, so the thread at (2, 1, 1) is number
2 + 4 × 1 + 16 × 1 = 22. This block holds 4 × 4 × 2 = 32 threads, exactly 1 warp.
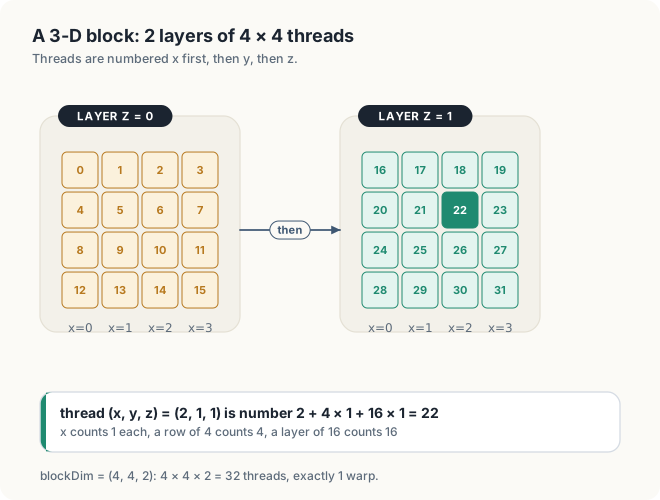
Stacked, the layers form a cube (figure 3.5). A block of dim3(4, 4, 4) holds 64 threads,
2 warps. One layer holds 16 threads, half a warp, so warp 0 is layers z = 0 and 1, and warp 1
is layers z = 2 and 3. The thread at (2, 0, 3), on top of the back layer, is number
2 + 4 × 0 + 16 × 3 = 50, and 50 ÷ 32 = 1 remainder 18 places it in warp 1, lane 18.
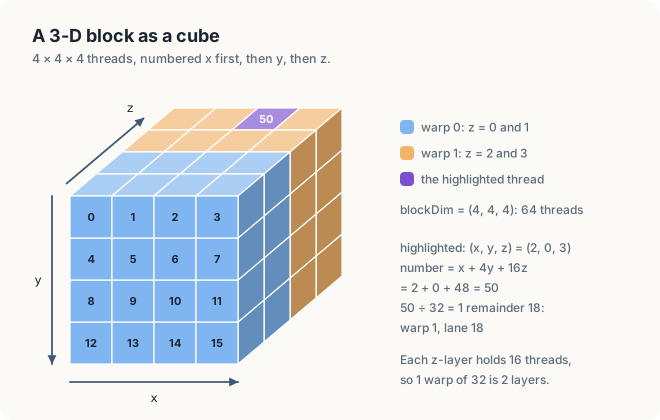
3.3.3 Launch limits
A launch must stay within limits that NVIDIA documents for every current GPU.
| Quantity | Limit | Where the number comes from |
|---|---|---|
| threads per block | 1,024 | 32 warps; NVIDIA’s limit, which keeps a whole block small enough for 1 SM (Chapter 2, section 2.4) |
| block size in x, in y | 1,024 each | no axis can exceed the block total |
| block size in z | 64 | NVIDIA’s documented limit |
| blocks in a grid, in x | 231 − 1 | the largest positive 32-bit signed integer |
| blocks in a grid, in y and in z | 65,535 | the largest 16-bit unsigned integer |
A launch that breaks a limit does not run. The launch itself reports no error; the program
learns of the failure from cudaGetLastError, as section 3.8 explains.
3.4 Built-in variables
Inside a kernel, 4 variables describe the launch and the thread’s place in it. Every thread can read them, and no program declares them.
| C++ | Rust (cuda-oxide) | Meaning |
|---|---|---|
threadIdx.x | thread::threadIdx_x() | the thread’s position in its block |
blockIdx.x | thread::blockIdx_x() | the block’s position in the grid |
blockDim.x | thread::blockDim_x() | the number of threads in a block |
gridDim.x | thread::gridDim_x() | the number of blocks in the grid |
Each has .y and .z forms as well (threadIdx_y() and so on in Rust). In C++,
threadIdx and blockIdx have type uint3 and blockDim and gridDim type dim3; both
hold 3 unsigned integers.
threadIdx is the position of Chapter 2, section 2.1.2, and blockIdx is the block number.
3.5 The global index formula
In Chapter 2, we found a thread’s index by counting the threads of the blocks before it, then adding its position. In CUDA’s names:
mod kernels {
    // ...
    pub fn who_am_i() {
        let block = thread::blockIdx_x();
        let position = thread::threadIdx_x();
        let index = block * thread::blockDim_x() + position;
        // ...
    }
    // ...
}
const int i = blockIdx.x * blockDim.x + threadIdx.x;
blockIdx.x * blockDim.x counts the threads of all earlier blocks: block 2 of a launch with
8 threads per block starts after 2 × 8 = 16 threads. Adding threadIdx.x, the position in
the block, gives the index. In figure 3.2, thread 5 of block 2 has index 2 × 8 + 5 = 21.
Worked example: the launch kernel<<<4, 256>>>
| Thread | blockIdx.x | threadIdx.x | Index |
|---|---|---|---|
| first thread of block 0 | 0 | 0 | 0 × 256 + 0 = 0 |
| thread 137 of block 2 | 2 | 137 | 2 × 256 + 137 = 649 |
| last thread of block 3 | 3 | 255 | 3 × 256 + 255 = 1,023 |
Block 2 covers indexes 512 to 767. Its warp 0 holds positions 0 to 31, indexes 512 to 543: 32 consecutive indexes.
For a 2-dimensional launch the same formula is applied to each axis, and the pixel’s place in memory follows from its row and column (figure 3.3):
mod kernels {
    // ...
    pub fn pixel_numbers(mut image: DisjointSlice<u32, Runtime2DIndex>) {
        // ...
        // Column ix and row iy, as in 1 dimension; rows are stored 1 after another.
        let ix = thread::blockIdx_x() * thread::blockDim_x() + thread::threadIdx_x();
        let iy = thread::blockIdx_y() * thread::blockDim_y() + thread::threadIdx_y();
        let pixel = iy * width + ix;
        // ...
    }
}
const int ix = blockIdx.x * blockDim.x + threadIdx.x; // column
const int iy = blockIdx.y * blockDim.y + threadIdx.y; // row
const int pixel = iy * width + ix; // rows are stored 1 after another
An image stored row after row puts a row’s pixels at consecutive addresses. Neighboring
threads of a warp have consecutive threadIdx.x, so they read consecutive pixels of 1 row:
the coalesced pattern of Chapter 2, section 2.7.
3.5.1 Rounding the grid up
A grid must have a whole number of blocks, but the number of elements need not be a multiple of the block size. For n = 1,000 elements and 256 threads per block, 3 blocks cover only 768 elements, and 4 blocks start 1,024 threads. A program launches 4 blocks and lets the 24 extra threads do nothing (figure 3.6).
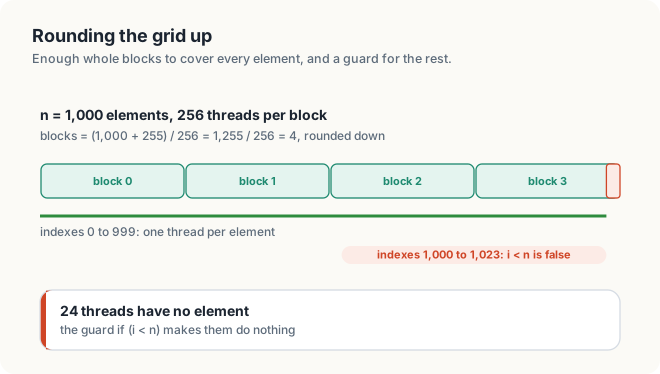
if (i < n) stops the last 24 threads.C++ integer division rounds down: 1,000 / 256 = 3. Adding 255, 1 less than the block size, before dividing makes any remainder reach the next multiple: (1,000 + 255) / 256 = 1,255 / 256 = 4. In general,
fn main() -> Result<(), Box<dyn std::error::Error>> {
    // ...
    let blocks = (N as u32).div_ceil(BLOCK);
    // ...
}
const int blocks = (n + threadsPerBlock - 1) / threadsPerBlock;
gives the smallest number of blocks that covers n. When n is already a multiple, the added 255 does not reach the next multiple, and no extra block is launched. Every kernel then needs a guard, a test that stops threads whose index is past the end of the data:
mod kernels {
    // ...
    pub fn add_vectors(a: &[f32], b: &[f32], mut c: DisjointSlice<f32>) {
        // ...
        if let Some(out) = c.get_mut(idx) {
            *out = a[i] + b[i];
        }
    }
    // ...
}
if (i < n) { c[i] = a[i] + b[i]; }
Without the guard, threads 1,000 to 1,023 would read and write outside the arrays. The guard costs 1 comparison per thread, and only the last block contains threads that fail it.
A program adds 1,000,000 elements with 256 threads per block. How many blocks does it launch, and how many threads are stopped by the guard?
(1,000,000 + 255) / 256 = 3,907 blocks, which is 3,907 × 256 = 1,000,192 threads. The guard stops 1,000,192 − 1,000,000 = 192 of them, all in the last block.
3.6 The first program: vector addition
The program adds 2 arrays of 1,048,576 floats on the GPU, copies the result back, and checks every element.
3.6.1 The kernel
Listing 3.2 The kernel, in Rust. code/oxide/ch03_basics/src/main.rs
mod kernels {
    // ...
    #[kernel]
    #[launch_contract(domain = 1, block = (256, 1, 1))]
    pub fn add_vectors(a: &[f32], b: &[f32], mut c: DisjointSlice<f32>) {
        let idx = thread::index_1d();
        let i = idx.get();
        if let Some(out) = c.get_mut(idx) {
            *out = a[i] + b[i];
        }
    }
    // ...
}
Listing 3.1 The kernel, in C++. code/ch03_vector_add/vector_add.cu
__global__ void addVectors(const float* a, const float* b, float* c, int n)
{
    int i = blockIdx.x * blockDim.x + threadIdx.x;
    if (i < n) {
        c[i] = a[i] + b[i];
    }
}
In C++, each thread computes its index, checks it against n, and adds 1 pair of elements.
The Rust kernel does the same with 2 helpers. thread::index_1d() computes the same index,
blockIdx.x × blockDim.x + threadIdx.x. DisjointSlice is an output array in which each
thread can reach only its own element: c.get_mut(idx) returns that element, or None when
the index is past the end. The guard is therefore part of the type, and a kernel that forgot
it would not compile. #[launch_contract(domain = 1, block = (256, 1, 1))] states that the
kernel expects 1-dimensional blocks of 256 threads; the host checks every launch against it.
In both versions, each thread writes a different element of c, so no 2 threads ever write
to the same address, and the threads need no coordination.
3.6.2 Memory on both sides
Listing 3.4 Host and device arrays, in Rust.
fn main() -> Result<(), Box<dyn std::error::Error>> {
    // ...
    // Vector addition: a[i] = i, b[i] = 2i, so c[i] should be 3i.
    let a: Vec<f32> = (0..N).map(|i| i as f32).collect();
    let b: Vec<f32> = (0..N).map(|i| 2.0 * i as f32).collect();

    let a_dev = DeviceBuffer::from_host(&stream, &a)?;
    let b_dev = DeviceBuffer::from_host(&stream, &b)?;
    let mut c_dev = DeviceBuffer::<f32>::zeroed(&stream, N)?;
    // ...
}
Listing 3.3 Host and device arrays, in C++.
int main()
{
    const int n = 1 << 20;
    const size_t bytes = n * sizeof(float);

    std::vector<float> h_a(n), h_b(n), h_c(n);
    for (int i = 0; i < n; ++i) {
        h_a[i] = i;
        h_b[i] = 2.0f * i;
    }

    float *d_a, *d_b, *d_c;
    check(cudaMalloc(&d_a, bytes));
    check(cudaMalloc(&d_b, bytes));
    check(cudaMalloc(&d_c, bytes));

    check(cudaMemcpy(d_a, h_a.data(), bytes, cudaMemcpyHostToDevice));
    check(cudaMemcpy(d_b, h_b.data(), bytes, cudaMemcpyHostToDevice));
    // ...
}
1 << 20 shifts 1 left by 20 bits, which is 220 = 1,048,576. Each array holds
1,048,576 floats of 4 bytes, so bytes is 4,194,304, 4 MiB.
In C++, cudaMalloc allocates that many bytes of global memory and stores the new device
pointer in its first argument, which is why it receives the pointer’s address, &d_a.
cudaMemcpy then copies each input from host to device.
In Rust, DeviceBuffer::from_host allocates device memory and copies a host array into it
in a single call, and DeviceBuffer::zeroed allocates the output, filled with zeros. A
DeviceBuffer frees its memory when it goes out of scope, so the Rust program has no
equivalent of cudaFree.
3.6.3 Launch and wait
Listing 3.6 Launch, in Rust.
fn main() -> Result<(), Box<dyn std::error::Error>> {
    // ...
    let blocks = (N as u32).div_ceil(BLOCK);
    let add = module.prepare_add_vectors(LaunchConfig1D::new(blocks, BLOCK, 0))?;

    module.add_vectors(&stream, &add, &a_dev, &b_dev, &mut c_dev)?;
    let c = c_dev.to_host_vec(&stream)?;
    // ...
}
Listing 3.5 Launch, in C++.
int main()
{
    // ...
    const int threads = 256;
    const int blocks = (n + threads - 1) / threads;

    addVectors<<<blocks, threads>>>(d_a, d_b, d_c, n);
    check(cudaGetLastError());
    check(cudaDeviceSynchronize());
    // ...
}
The block size of 256 is 8 full warps, and small enough that several blocks fit on 1 SM
(Chapter 2, section 2.9); sizes from 128 to 512 are common. With n = 1,048,576, the grid has
1,048,576 / 256 = 4,096 blocks, and no thread fails the guard. Rust’s div_ceil divides and
rounds up, the same as (n + threads - 1) / threads in C++.
C++ waits for the kernel with cudaDeviceSynchronize. In Rust, to_host_vec copies the
result back into a new Vec, and the copy waits for the kernel first.
3.6.4 Building and running
$ nvcc -arch=native vector_add.cu -o vector_add
$ ./vector_add
n = 1048576, 4096 blocks of 256 threads
c[0] = 0, c[1] = 3, c[1048575] = 3145725
max error = 0
$ cargo oxide run
...
n = 1048576, 4096 blocks of 256 threads
c[0] = 0, c[1] = 3, c[1048575] = 3145725
max error = 0
Both outputs come from runs on a Jetson Orin NX with CUDA 12.6; any NVIDIA GPU prints the same
numbers. The inputs were a[i] = i and b[i] = 2i, so c[i] should be 3i: c[1048575]
is 3 × 1,048,575 = 3,145,725, and the maximum error over all 1,048,576 elements is 0.
3.6.5 Which thread runs first?
A second, tiny kernel makes the index formula visible. Every thread of a launch of 2 blocks of 4 threads prints its block, its position and its index.
Listing 3.8 The same kernel, in Rust.
mod kernels {
    // ...
    #[kernel]
    #[launch_contract(domain = 1, block = (4, 1, 1))]
    pub fn who_am_i() {
        let block = thread::blockIdx_x();
        let position = thread::threadIdx_x();
        let index = block * thread::blockDim_x() + position;

        gpu_printf!("block {}, position {} -> index {}\n", block, position, index);
    }
    // ...
}
Listing 3.7 Every thread prints who it is, in C++. code/ch03_vector_add/whoami.cu
__global__ void whoAmI()
{
    const int index = blockIdx.x * blockDim.x + threadIdx.x;
    printf("block %d, position %d -> index %d\n", blockIdx.x, threadIdx.x, index);
}

int main()
{
    whoAmI<<<2, 4>>>();           // 2 blocks of 4 threads: indexes 0 to 7
    cudaDeviceSynchronize();      // wait, so the printed lines reach the screen
    return 0;
}
$ ./whoami
block 1, position 0 -> index 4
block 1, position 1 -> index 5
block 1, position 2 -> index 6
block 1, position 3 -> index 7
block 0, position 0 -> index 0
block 0, position 1 -> index 1
block 0, position 2 -> index 2
block 0, position 3 -> index 3
The Rust program printed the same 8 lines in the same order. Each index is the block number × 4 + the position, as section 3.5 says. On these runs block 1 printed before block 0. Another GPU, or another run, may print them in a different order: the order of blocks is not defined, and a correct kernel never depends on it.
3.6.6 The complete programs
Listing 3.10 The complete Rust program.
//! Chapter 3 in Rust: every thread prints who it is, vector addition, and a 2-dimensional
//! launch that numbers the pixels of an 8 x 8 image.
//!
//!     cargo oxide run

use cuda_core::{CudaContext, DeviceBuffer, LaunchConfig1D, LaunchConfig2D};
use cuda_device::thread::Runtime2DIndex;
use cuda_device::{DisjointSlice, cuda_module, gpu_printf, kernel, launch_contract, thread};
use cuda_host::RowWidth;

const N: usize = 1 << 20;
const BLOCK: u32 = 256;

#[cuda_module]
mod kernels {
    use super::*;

    #[kernel]
    #[launch_contract(domain = 1, block = (4, 1, 1))]
    pub fn who_am_i() {
        let block = thread::blockIdx_x();
        let position = thread::threadIdx_x();
        let index = block * thread::blockDim_x() + position;

        gpu_printf!("block {}, position {} -> index {}\n", block, position, index);
    }

    #[kernel]
    #[launch_contract(domain = 1, block = (256, 1, 1))]
    pub fn add_vectors(a: &[f32], b: &[f32], mut c: DisjointSlice<f32>) {
        let idx = thread::index_1d();
        let i = idx.get();
        if let Some(out) = c.get_mut(idx) {
            *out = a[i] + b[i];
        }
    }

    #[kernel]
    #[launch_contract(domain = 2, block = (4, 4, 1))]
    pub fn pixel_numbers(mut image: DisjointSlice<u32, Runtime2DIndex>) {
        let width = image.row_width();

        // Column ix and row iy, as in 1 dimension; rows are stored 1 after another.
        let ix = thread::blockIdx_x() * thread::blockDim_x() + thread::threadIdx_x();
        let iy = thread::blockIdx_y() * thread::blockDim_y() + thread::threadIdx_y();
        let pixel = iy * width + ix;

        if let Some(idx) = thread::index_2d_runtime(&image)
            && let Some(out) = image.get_mut(idx)
        {
            *out = pixel;
        }
    }
}

fn main() -> Result<(), Box<dyn std::error::Error>> {
    let ctx = CudaContext::new(0)?;
    let stream = ctx.default_stream();
    // SAFETY: the loaded code was compiled from the `kernels` module above.
    let module = unsafe { kernels::load(&ctx)? };

    // 2 blocks of 4 threads, each printing its block, position and index.
    let who = module.prepare_who_am_i(LaunchConfig1D::new(2, 4, 0))?;
    module.who_am_i(&stream, &who)?;
    stream.synchronize()?;

    // Vector addition: a[i] = i, b[i] = 2i, so c[i] should be 3i.
    let a: Vec<f32> = (0..N).map(|i| i as f32).collect();
    let b: Vec<f32> = (0..N).map(|i| 2.0 * i as f32).collect();

    let a_dev = DeviceBuffer::from_host(&stream, &a)?;
    let b_dev = DeviceBuffer::from_host(&stream, &b)?;
    let mut c_dev = DeviceBuffer::<f32>::zeroed(&stream, N)?;

    let blocks = (N as u32).div_ceil(BLOCK);
    let add = module.prepare_add_vectors(LaunchConfig1D::new(blocks, BLOCK, 0))?;

    module.add_vectors(&stream, &add, &a_dev, &b_dev, &mut c_dev)?;
    let c = c_dev.to_host_vec(&stream)?;

    let max_err = (0..N).map(|i| (c[i] as f64 - 3.0 * i as f64).abs()).fold(0.0, f64::max);

    println!("n = {N}, {blocks} blocks of {BLOCK} threads");
    println!("c[0] = {}, c[1] = {}, c[{}] = {}", c[0], c[1], N - 1, c[N - 1]);
    println!("max error = {max_err}");

    // A 2-dimensional launch over an 8 x 8 image: each thread stores its pixel's number.
    let mut image = DeviceBuffer::<u32>::zeroed(&stream, 8 * 8)?;

    let threads_per_block = (4, 4); // 4 x 4 = 16 threads per block
    let blocks = (2, 2); // 2 x 2 = 4 blocks
    let config = LaunchConfig2D::new(blocks, threads_per_block, 0);

    let pixels = module.prepare_pixel_numbers(config)?;
    module.pixel_numbers(&stream, &pixels, RowWidth::new(&mut image, 8))?;

    let numbers = image.to_host_vec(&stream)?;
    let any_wrong = numbers.iter().enumerate().any(|(p, &number)| number != p as u32);
    if any_wrong {
        return Err("a thread computed the wrong pixel number".into());
    }

    Ok(())
}
Listing 3.9 The complete vector_add.cu.
// Chapter 3: vector addition, c = a + b, on the GPU.
// Build: nvcc -arch=native vector_add.cu -o vector_add

#include <cmath>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cuda_runtime.h>

// Stops the program if a CUDA call failed (section 3.8).
void check(cudaError_t err)
{
    if (err != cudaSuccess) {
        std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
        std::exit(1);
    }
}

__global__ void addVectors(const float* a, const float* b, float* c, int n)
{
    int i = blockIdx.x * blockDim.x + threadIdx.x;
    if (i < n) {
        c[i] = a[i] + b[i];
    }
}

int main()
{
    const int n = 1 << 20;
    const size_t bytes = n * sizeof(float);

    std::vector<float> h_a(n), h_b(n), h_c(n);
    for (int i = 0; i < n; ++i) {
        h_a[i] = i;
        h_b[i] = 2.0f * i;
    }

    float *d_a, *d_b, *d_c;
    check(cudaMalloc(&d_a, bytes));
    check(cudaMalloc(&d_b, bytes));
    check(cudaMalloc(&d_c, bytes));

    check(cudaMemcpy(d_a, h_a.data(), bytes, cudaMemcpyHostToDevice));
    check(cudaMemcpy(d_b, h_b.data(), bytes, cudaMemcpyHostToDevice));

    const int threads = 256;
    const int blocks = (n + threads - 1) / threads;

    addVectors<<<blocks, threads>>>(d_a, d_b, d_c, n);
    check(cudaGetLastError());
    check(cudaDeviceSynchronize());

    check(cudaMemcpy(h_c.data(), d_c, bytes, cudaMemcpyDeviceToHost));

    double maxErr = 0;
    for (int i = 0; i < n; ++i) {
        maxErr = std::fmax(maxErr, std::fabs(h_c[i] - 3.0 * i));
    }

    std::printf("n = %d, %d blocks of %d threads\n", n, blocks, threads);
    std::printf("c[0] = %.0f, c[1] = %.0f, c[%d] = %.0f\n", h_c[0], h_c[1], n - 1, h_c[n - 1]);
    std::printf("max error = %g\n", maxErr);

    check(cudaFree(d_a));
    check(cudaFree(d_b));
    check(cudaFree(d_c));
}
3.7 The memory functions
| Function | What it does |
|---|---|
cudaMalloc(&p, bytes) | allocates bytes of global memory and stores the device pointer in p |
cudaFree(p) | frees memory allocated by cudaMalloc |
cudaMemcpy(dst, src, bytes, kind) | copies bytes; kind is cudaMemcpyHostToDevice, cudaMemcpyDeviceToHost or cudaMemcpyDeviceToDevice; waits for earlier device work, and in most cases returns when the copy is complete (Chapter 4 gives the exceptions) |
cudaDeviceSynchronize() | waits until all work launched so far on the device has finished |
cudaGetLastError() | returns, and clears, the last error recorded by the runtime |
cudaGetErrorString(err) | returns a readable description of an error code |
cudaMalloc writes its result through a pointer to the caller’s pointer, as C functions do,
and returns an error code instead of the pointer. cudaMemcpy needs the direction because a
host address and a device address are both plain numbers, and the same number can be valid
on both sides.
3.8 Errors and asynchronous launches
Every CUDA runtime function returns a value of type cudaError_t: cudaSuccess, which is
0, or a code that names what went wrong. Errors arrive in two ways.
- Immediately. A call with a bad argument, such as a copy from a null pointer, returns an error code at once.
- Later. A launch returns before its kernel runs. The host carries on while the GPU
works (figure 3.7), so an error inside the kernel, such as a read outside an array,
cannot be reported by the launch. It is reported by the next call that waits for the
kernel, such as
cudaDeviceSynchronize.
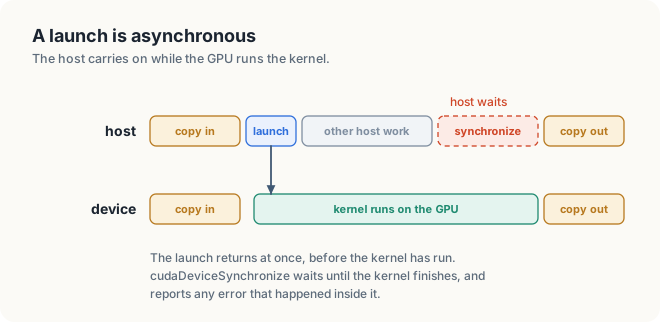
cudaDeviceSynchronize.The program in section 3.6 checks both kinds. Right after the launch, cudaGetLastError
reports whether the launch was accepted, for example whether a block of more than 1,024
threads was requested. cudaDeviceSynchronize then waits for the kernel and reports any
error that happened while it ran.
Every CUDA call in the C++ program goes through check, which prints the error’s
description and stops the program. In Rust, every call returns a Result, and the ?
operator passes an error up to main, which reports it. An unchecked error does not stop
anything: the program goes on with wrong data and prints wrong results.
A kernel reads outside its array. Which call in listing 3.5 reports the error?
cudaDeviceSynchronize. The launch was valid, so cudaGetLastError right after it returns
cudaSuccess; the bad read happens while the kernel runs, and the wait reports it.
3.9 Compiling with nvcc
A .cu file holds code for 2 processors. nvcc, NVIDIA’s compiler driver, splits it in 2
(figure 3.8).
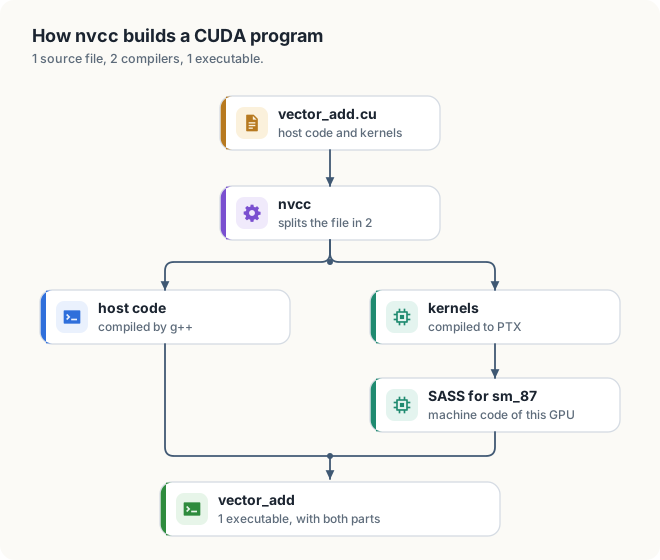
- The host code goes to the host’s ordinary C++ compiler, such as
g++. Each launch<<<...>>>becomes a call into the CUDA runtime library. - The kernels are compiled first to PTX, an instruction set that NVIDIA keeps stable
across GPU generations, then to SASS, the machine code of 1 particular GPU. SASS is
specific to a compute capability;
sm_87names compute capability 8.7.
The -arch option chooses the GPU to compile for:
$ nvcc -arch=native vector_add.cu -o vector_add    # the GPU in this machine
$ nvcc -arch=sm_90  vector_add.cu -o vector_add    # an H100
An executable compiled with -arch=sm_90 also carries PTX for compute capability 9.0, and a
newer GPU’s driver can compile that PTX for itself when the program starts. This book never
shows PTX or SASS: the kernels are read in C++ and in Rust.
The Rust version is built with cargo oxide run. cuda-oxide compiles the #[cuda_module]
for the GPU, rustc compiles the host code, and both end up in 1 executable, as with nvcc.
Common mistakes
- Reading a device pointer on the host.
d_c[0]inmainreads an address that means nothing to the CPU. Copy the data back first. - Forgetting the guard. A rounded-up grid has threads past the end of the data. Without
if (i < n)they read and write outside the arrays. - Reading results before the kernel has finished. A launch returns at once. Synchronize,
or copy with
cudaMemcpy, which waits for earlier work, before reading the output. - Assuming an order of blocks. Blocks run in any order (section 3.6.6), and a kernel’s result must not depend on it.
- Using
intfor byte counts. Sizes in bytes can exceed 231 − 1; usesize_t.
Summary
- The host is the CPU and its memory; the device is the GPU and its memory. Each has
its own address space, and data moves between them with
cudaMemcpy. __global__marks a kernel, which runs on the device and is launched from the host.__device__marks a helper that runs on the device.kernel<<<blocks, threadsPerBlock>>>launches a grid of blocks. Grids and blocks can have 1, 2 or 3 dimensions, and blocks run in no fixed order.- A thread’s index is
blockIdx.x * blockDim.x + threadIdx.x. (n + threadsPerBlock - 1) / threadsPerBlockrounds the grid up, andif (i < n)stops the extra threads.- A launch is asynchronous. Check
cudaGetLastErrorafter it and the result ofcudaDeviceSynchronize, and check every other CUDA call. nvcccompiles host code with the host’s compiler and kernels to PTX and SASS.- In Rust with cuda-oxide,
#[kernel]marks a kernel,thread::index_1d()gives the index,DisjointSlicebuilds the guard into the type, andDeviceBufferallocates, copies and frees device memory.
Chapter 4 looks closely at the copies between host and device: how fast they are, and how pinned and unified memory make them faster or remove them.
Exercises
- A launch
kernel<<<5, 64>>>starts how many threads? What is the index of thread 10 of block 3? - Write the 2-dimensional index formulas for an image of
width × heightpixels, and show that the 32 threads of a warp in a block of 32 × 8 threads read 32 consecutive pixels. - For n = 1,000,000 and 512 threads per block, how many blocks are launched, and how many threads fail the guard?
- A block has
blockDim = (8, 4, 2). How many threads does it hold, how many warps, and what is the number of the thread at (3, 2, 1)? - Why must a
__global__function returnvoid? What would a return value mean for 1,000,000 threads? - Change
whoami.cuto launch 4 blocks of 2 threads. Predict the indexes before running it, then run it 3 times. Does the order of the lines change? - Remove the guard from the kernel of listing 3.1 and run it with n = 1,000. What happens? Use a machine where a crash does no harm.
- In the Rust kernel of listing 3.2, try to write
c[i] = a[i] + b[i]directly instead of going throughc.get_mut(idx). What does the compiler say, and why?
Sources and further reading
- NVIDIA, CUDA C++ Programming Guide, “Programming Model” and “Programming Interface”: https://docs.nvidia.com/cuda/cuda-c-programming-guide/
- NVIDIA, CUDA C++ Best Practices Guide: https://docs.nvidia.com/cuda/cuda-c-best-practices-guide/
- NVIDIA, NVCC documentation, for
-archand the compilation flow: https://docs.nvidia.com/cuda/cuda-compiler-driver-nvcc/ - David B. Kirk, Wen-mei W. Hwu and Izzat El Hajj, Programming Massively Parallel Processors, 4th ed., chapters 2 and 3.
Chapter 4: Memory Management & Data Movement
In Chapter 3, we used cudaMemcpy to transfer data between host memory and device memory,
and we treated each transfer as a single function call. In this chapter, we look at how a
transfer is carried out and how long it takes. The time matters because on many systems a
transfer takes longer than the kernel that uses the data. For example, a kernel that reads
1 GB from the memory of an H100 at 3.35 TB/s finishes in about 0.3 ms, whereas copying the same
1 GB to the H100 over PCIe 5.0 takes about 20 ms. Making such a kernel faster has little effect
on the running time of the whole program unless the transfers are also made faster or avoided.
We first describe the path that data takes between the CPU and the GPU, which differs between discrete and integrated GPUs. We then explain why CUDA distinguishes pageable from pinned host memory, build a simple model of the cost of a transfer, and compare the model with measurements. The chapter ends with two kinds of memory that reduce or remove explicit transfers: unified memory and zero-copy memory. The measurements are made by 2 small programs, one in C++ and one in Rust, which run on any NVIDIA GPU.
This chapter covers
- discrete and integrated systems, and the path of a transfer in each
- PCIe lanes, NVLink-C2C, and transfer times on 7 systems
- virtual memory, pages, and the reason copy engines require pinned memory
- the cost of a transfer: a fixed latency plus the size divided by the bandwidth
- measuring transfers, and the cost of small transfers
- unified memory, whose pages move on first use
- zero-copy memory, which a kernel accesses in place
- choosing a kind of memory, and overlapping transfers with kernels
The code of the chapter is in
code/ch04_memory/
for C++ and in
code/oxide/ch04_transfers/
for Rust.
4.1 The transfer path
4.1.1 Discrete and integrated systems
The path of a transfer depends on how the GPU is attached to the CPU. Figure 4.1 shows the 2 arrangements in use today.
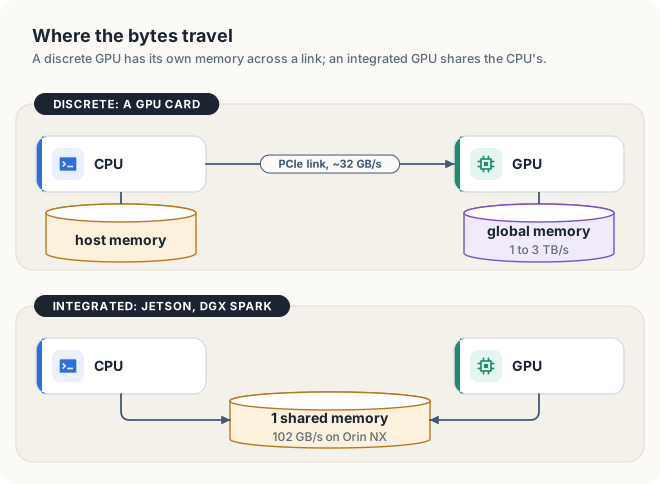
A GPU is said to be discrete if it sits on its own card or module with its own memory chips, as an RTX 4090, an A100 or an H100 does. Data moves between the CPU’s memory and the GPU’s memory over a link, which is a connection between the 2 chips. A GPU is said to be integrated if it has no memory of its own and uses the CPU’s memory chips, as the GPUs of the Jetson boards and of the DGX Spark do.
The two designs make different trade-offs. The memory of a discrete GPU serves the GPU alone and is very fast; an H100 reads its own memory at 3.35 TB/s. However, the link that fills this memory is much slower, so data is fast to use once it has arrived and slow to arrive. An integrated GPU has no link to cross, but its memory is slower and is shared with the CPU.
4.1.2 PCIe lanes and NVLink-C2C
Most discrete GPUs are connected to the CPU through PCIe, the standard expansion bus of a computer. A pair of wires can switch only so fast before its signal becomes unreliable, so PCIe increases bandwidth by running several connections side by side. Each connection is called a lane and consists of 2 wire pairs, 1 for each direction, so that a lane sends and receives at the same time (figure 4.2). The notation “PCIe 4.0 × 16” means 16 lanes of generation 4.0, and the bandwidth of the link is the number of lanes multiplied by the rate of 1 lane.
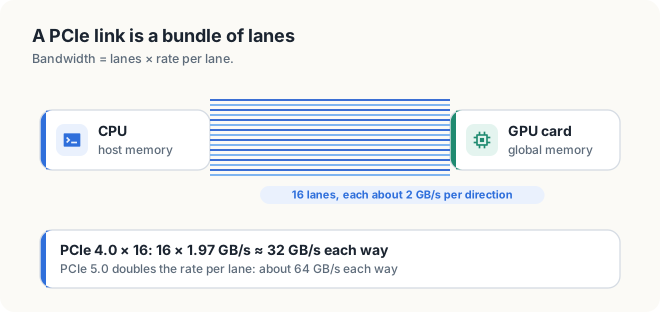
A lane of PCIe 4.0 carries 1.97 GB/s in each direction, so 16 lanes carry 16 × 1.97 ≈ 32 GB/s. PCIe 5.0 doubles the rate of each lane, to about 64 GB/s for 16 lanes. Programs reach about 80% of these figures in practice. The link carries data in packets, and the header of each packet, which holds an address and error checks, occupies the link without being part of the program’s data.
NVIDIA’s Grace Hopper (GH200) connects its CPU and GPU with NVLink-C2C, a chip-to-chip link of 900 GB/s in total, or 450 GB/s in each direction. This is 14 times the bandwidth of PCIe 5.0.
4.1.3 Transfer times on 7 systems
The time to transfer \(N\) bytes over a path of bandwidth \(B\) is \(N / B\), since bandwidth is measured in bytes per second. The table applies this formula to 1 GB on 7 systems.
| System | Path from host memory to device memory | Bandwidth each way | Time to copy 1 GB |
|---|---|---|---|
| GeForce RTX 4090 | PCIe 4.0 × 16 | 32 GB/s | 31 ms |
| A100 SXM | PCIe 4.0 × 16 | 32 GB/s | 31 ms |
| GeForce RTX 5090 | PCIe 5.0 × 16 | 64 GB/s | 16 ms |
| H100 SXM | PCIe 5.0 × 16 | 64 GB/s | 16 ms |
| GH200 Grace Hopper | NVLink-C2C | 450 GB/s | 2.2 ms |
| Jetson AGX Thor, DGX Spark | shared memory, 273 GB/s | at most 137 GB/s | at least 7.3 ms |
| Jetson Orin NX 16 GB | shared memory, 102 GB/s | at most 51 GB/s | at least 20 ms |
On an integrated system a program does not need to copy at all, as sections 4.5 and 4.6 show. When it does copy, each byte is read from the shared memory and written back to another place in the same memory, so every byte copied causes 2 bytes of memory traffic. A copy can therefore use at most half of the memory bandwidth: 273 / 2 ≈ 137 GB/s on a Thor or a DGX Spark, and 102 / 2 = 51 GB/s on an Orin NX.
We can now return to the example of the introduction. Over PCIe 5.0 at about 50 GB/s, which is 80% of 64 GB/s, copying 1 GB to an H100 takes 1 / 50 = 0.02 s, or 20 ms. A kernel that reads the same 1 GB once from the H100’s memory at 3.35 TB/s takes 1 / 3,350 = 0.0003 s, or 0.3 ms. The copy therefore takes about 20 / 0.3 ≈ 67 times as long as the kernel.
This ratio is not specific to the H100. Each discrete GPU in the table reads its own memory 28 to 64 times as fast as PCIe can fill it: 1,008 / 32 ≈ 32 for the RTX 4090, 2,039 / 32 ≈ 64 for the A100, and 1,792 / 64 = 28 for the RTX 5090. A program that copies its data in, runs 1 short kernel and copies the result out therefore spends almost all of its time on the link. Such a program becomes faster by copying less, by keeping data on the GPU between kernels, and by overlapping copies with computation (section 4.8).
4.2 Pageable and pinned host memory
4.2.1 Virtual memory and pages
A program does not use physical memory addresses directly. The operating system gives it virtual addresses and translates each of them to a physical address through a table that it keeps for the program. The translation works in fixed-size units called pages, usually 4 KiB on Linux. Because the program sees only virtual addresses, the operating system is free to move a page to a different physical location and update the table. It does so, for example, to gather free memory into larger contiguous regions, or to write a page to disk when memory runs short. The program is not affected by such a move.
Memory allocated with malloc, new, std::vector or a Rust Vec is called pageable,
because the operating system may move its pages at any time.
4.2.2 Copy engines and pinned memory
A GPU has copy engines, which are units that move data between host memory and device memory by themselves while the CPU and the SMs do other work. A transfer performed this way is called DMA, for direct memory access; without it, a CPU core would have to load and store every byte. The driver gives a copy engine the physical addresses of the pages to read, and the engine then works through them without consulting the operating system’s tables. If a pageable page were moved during the transfer, the copy engine would read whatever now occupies the old physical address, and the device would receive the wrong bytes without any error being reported.
For this reason, CUDA copies pageable memory in 2 steps. The CPU first copies the data into a staging buffer whose pages cannot move, and a copy engine then transfers the staging buffer to the device. The driver processes the data in chunks, so the 2 steps partly overlap, but every byte still passes through the CPU once. Memory whose pages the operating system has agreed not to move is called pinned, or page-locked, memory. A transfer from pinned memory needs only the second step. Animation 1 shows both cases.
Figure 4.3 shows the same 2 paths as a still picture.
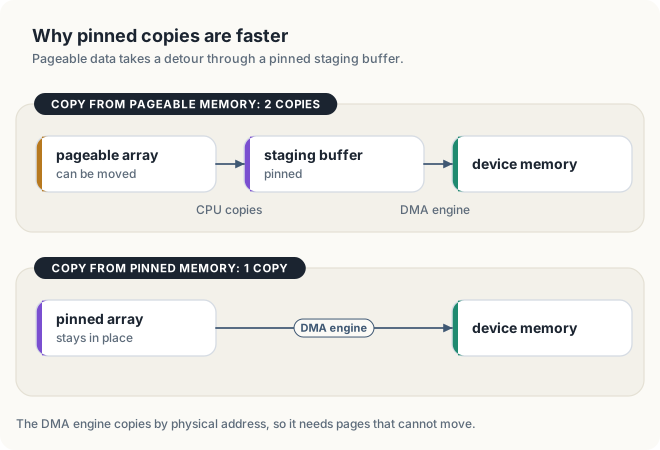
Some newer systems do not need the staging buffer. On the Jetson AGX Thor and on Grace Hopper,
the GPU translates addresses through the CPU’s own page tables, so it finds a pageable page
wherever the operating system has placed it. CUDA reports this capability as the device
attribute pageableMemoryAccessUsesHostPageTables, which is 1 on a Thor and 0 on an Orin NX.
On such a system, a copy from pageable memory runs as fast as a copy from pinned memory, as the
measurements of section 4.4 confirm.
4.2.3 Allocating pinned memory
The table lists the calls that allocate and free pinned and pageable host memory in C++ and in Rust.
| Allocate | Free | |
|---|---|---|
| C++, pinned | cudaMallocHost(&p, bytes) | cudaFreeHost(p) |
| C++, pageable | std::malloc, new, std::vector | std::free, delete, automatic |
| Rust, pinned | PinnedHostBuffer::<f32>::zeroed(&ctx, n)? | automatic, when the buffer goes out of scope |
| Rust, pageable | vec![0.0f32; n] | automatic |
Memory obtained from cudaMallocHost must be released with cudaFreeHost; calling free or
delete on it would corrupt CUDA’s records of the allocation. A Rust PinnedHostBuffer is
released correctly when it goes out of scope.
Pinned memory has a cost. Every pinned page is a page that the operating system can no longer move or write to disk, which leaves it less room to manage memory for other programs. Pinning is also slow to set up, because every page must be located and locked. Programs therefore allocate pinned buffers once and reuse them, pin only the buffers that they copy often, and leave the rest pageable. Pinned memory is also required for asynchronous copies, which Chapter 6 uses to overlap copies with kernels.
4.3 The cost of a copy
Section 4.1 treated the time of a copy as \(N / B\). With this formula, a copy of 4 KiB at 30 GB/s would take about 0.14 µs, yet section 4.4 measures 18.6 µs for such a copy. The formula leaves out a cost that every copy pays regardless of its size: the CPU’s call into the CUDA driver, the setup of the copy engine, and the notification that the copy is complete. We call this fixed cost the latency of the copy and denote it \(t_0\). The time of a copy is then
\[ T = t_0 + \frac{N}{B} \]
The formula has 2 regimes. For small copies, \(N / B\) is tiny and \(T \approx t_0\); such a copy is said to be latency-bound, and copying 4 times as many bytes takes about the same time. For large copies, \(t_0\) is negligible and \(T \approx N / B\); such a copy is said to be bandwidth-bound. The 2 terms are equal at the break-even size
\[ N^* = t_0 \times B \]
It follows from the model that a copy of \(N\) bytes achieves the fraction \(N / (N + N^{\ast})\) of the bandwidth: one half at \(N^{\ast}\), 10 / 11 ≈ 91% at 10 \(N^{\ast}\), and 1 / 11 ≈ 9% at a tenth of \(N^{\ast}\). The table gives the break-even size for 2 systems.
| System | \(t_0\) | \(B\) | Break-even size \(N^*\) |
|---|---|---|---|
| a discrete GPU on PCIe 4.0 | 10 µs | 25 GB/s | 10 × 10−6 × 25 × 109 = 250 KB |
| the Orin NX of section 4.4 | 16 µs | 30 GB/s | 16 × 10−6 × 30 × 109 = 480 KB |
The 10 µs of the first row indicates only the order of magnitude; section 4.4 measures \(t_0\) on 1 machine, and the programs of this chapter measure it on any other.
Below the break-even size, more than half of the time of a copy is fixed cost. For example, 1,000 copies of 4 KB each take about 1,000 × \(t_0\), whereas 1 copy of the same 4 MB takes about \(t_0 + 4\ \text{MB} / B\). A program that has many small pieces of data to transfer should therefore gather them into 1 buffer and copy that buffer once. This is the relation between latency and throughput from Chapter 1: a fixed latency per operation limits the throughput of operations that are issued one at a time.
4.4 Measuring copies
We now test the model with measurements. The C++ program transfers.cu measures 4 quantities
on whatever GPU it runs on, and its Rust counterpart measures the same 4.
4.4.1 Timing a copy
Listing 4.1 Timing a copy. code/oxide/ch04_transfers/src/main.rs code/ch04_memory/transfers.cu
/// Runs `copy` once to warm up, then `reps` times; returns the average in milliseconds.
fn time_copy(
    reps: u32,
    mut copy: impl FnMut() -> Result<(), DriverError>,
) -> Result<f64, DriverError> {
    copy()?;

    let start = Instant::now();
    for _ in 0..reps {
        copy()?;
    }

    Ok(start.elapsed().as_secs_f64() * 1e3 / reps as f64)
}
// Average time of `reps` copies of `bytes`, in milliseconds, after 1 warm-up copy.
double timeCopy(void* dst, const void* src, size_t bytes, cudaMemcpyKind kind, int reps)
{
check(cudaMemcpy(dst, src, bytes, kind));
double t0 = nowMs();
for (int r = 0; r < reps; ++r) {
check(cudaMemcpy(dst, src, bytes, kind));
}
return (nowMs() - t0) / reps;
}
The function timeCopy first performs 1 copy that is not timed. This warm-up copy includes
work that happens only once, such as setting up the staging buffer, and would distort the
average. The function then reads the clock, performs reps copies, reads the clock again, and
returns the average time per copy in milliseconds. The clocks used, steady_clock in C++ and
Instant in Rust, never jump when the system adjusts its time of day, which makes them suitable
for measuring intervals. Chapter 6 replaces them with CUDA events, which measure time on the GPU
itself.
The Rust function time_copy has the same structure, but it receives the copy as a closure
that returns a Result. Every copy can fail, for example when the GPU is lost, and the ?
operator passes any failure up to main instead of ignoring it.
4.4.2 Pageable and pinned copies
Listing 4.2 4 copies of 64 MiB.
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
let mut pageable = vec![0.0f32; N];
let mut pinned = PinnedHostBuffer::<f32>::zeroed(&ctx, N)?;
let mut device = DeviceBuffer::<f32>::zeroed(&stream, N)?;
let bytes = N * size_of::<f32>();
println!("copies of {} MiB", bytes >> 20);
let ms = time_copy(20, || device.copy_from_host(&stream, &pageable))?;
println!(" pageable host -> device {ms:6.2} ms {:5.1} GB/s", gb_per_s(bytes, ms));
let ms = time_copy(20, || device.copy_from_host(&stream, pinned.as_slice()))?;
println!(" pinned host -> device {ms:6.2} ms {:5.1} GB/s", gb_per_s(bytes, ms));
let ms = time_copy(20, || device.copy_to_host(&stream, &mut pageable))?;
println!(" device -> pageable host {ms:6.2} ms {:5.1} GB/s", gb_per_s(bytes, ms));
let ms = time_copy(20, || device.copy_to_pinned_host(&stream, &mut pinned))?;
println!(" device -> pinned host {ms:6.2} ms {:5.1} GB/s", gb_per_s(bytes, ms));
// ...
}// 1. Copy speed from pageable and from pinned host memory, both directions.
void copySpeeds(float* pageable, float* pinned, float* device, size_t bytes)
{
struct Case { const char* name; void* dst; const void* src; cudaMemcpyKind kind; };
const Case cases[] = {
{"pageable host -> device", device, pageable, cudaMemcpyHostToDevice},
{"pinned host -> device", device, pinned, cudaMemcpyHostToDevice},
{"device -> pageable host", pageable, device, cudaMemcpyDeviceToHost},
{"device -> pinned host", pinned, device, cudaMemcpyDeviceToHost},
};
std::printf("copies of %zu MiB\n", bytes >> 20);
for (const Case& c : cases) {
double ms = timeCopy(c.dst, c.src, bytes, c.kind, 20);
std::printf(" %s %6.2f ms %5.1f GB/s\n", c.name, ms, bytes / 1e9 / (ms / 1e3));
}
}
The function copySpeeds measures 4 copies of 64 MiB: from pageable and from pinned host
memory to the device, and from the device back to each. The C++ version lists the 4 cases in
an array of Case structures and runs 1 loop over it, printing the time and the bandwidth of
each. The size of 64 MiB is about 140 times the break-even size of 480 KB, so \(t_0\) is less
than 1% of the time of each copy, and the results measure the bandwidth alone.
In the Rust version, copy_from_host copies a host slice to the device and waits for the copy
to finish. When it is given pinned.as_slice(), the source is pinned memory, and CUDA skips
the staging buffer. copy_to_pinned_host copies from the device into a PinnedHostBuffer.
4.4.3 Copy time as a function of size
Listing 4.3 Copies from 4 KiB to 64 MiB.
fn main() -> Result<(), Error> {
// ...
println!("pinned host -> device, by size");
let mut len = 1 << 10; // 1,024 floats, 4 KiB
while len <= N {
let mut part = DeviceBuffer::<f32>::zeroed(&stream, len)?;
let src = &pinned.as_slice()[..len];
let ms = time_copy(200, || part.copy_from_host(&stream, src))?;
let size = len * size_of::<f32>();
let (kib, us) = (size >> 10, ms * 1e3);
println!(" {kib:8} KiB {us:8.1} us {:5.1} GB/s", gb_per_s(size, ms));
len *= 4;
}
// ...
}// 2. Copy time against copy size, pinned host -> device.
void sizeSweep(float* pinned, float* device)
{
std::printf("pinned host -> device, by size\n");
for (size_t bytes = 4 << 10; bytes <= (64 << 20); bytes *= 4) {
double ms = timeCopy(device, pinned, bytes, cudaMemcpyHostToDevice, 200);
std::printf(" %8zu KiB %8.1f us %5.1f GB/s\n",
bytes >> 10, ms * 1e3, bytes / 1e9 / (ms / 1e3));
}
}
The function sizeSweep copies pinned memory to the device at sizes from 4 KiB to 64 MiB, each
size 4 times the previous one. Each size is copied 200 times. The small copies take only
microseconds each, and 200 of them take long enough to be timed reliably: 200 copies of 4 KiB
take about 3.6 ms in total.
4.4.4 Results
The first 2 runs below were made on a Jetson Orin NX and the third on a Jetson AGX Thor. On a discrete GPU, the pinned figures approach the PCIe rates of section 4.1.
$ ./transfers
GPU: Orin, integrated, 2 copy engine(s)
copies of 64 MiB
pageable host -> device 11.81 ms 5.7 GB/s
pinned host -> device 3.40 ms 19.8 GB/s
device -> pageable host 8.63 ms 7.8 GB/s
device -> pinned host 4.12 ms 16.3 GB/s
pinned host -> device, by size
4 KiB 18.6 us 0.2 GB/s
16 KiB 16.9 us 1.0 GB/s
64 KiB 21.8 us 3.0 GB/s
256 KiB 25.1 us 10.4 GB/s
1024 KiB 74.0 us 14.2 GB/s
4096 KiB 278.9 us 15.0 GB/s
16384 KiB 616.5 us 27.2 GB/s
65536 KiB 2139.7 us 31.4 GB/s
$ cargo oxide run
copies of 64 MiB
pageable host -> device 11.19 ms 6.0 GB/s
pinned host -> device 4.26 ms 15.7 GB/s
device -> pageable host 9.16 ms 7.3 GB/s
device -> pinned host 3.60 ms 18.7 GB/s
pinned host -> device, by size
4 KiB 17.7 us 0.2 GB/s
16 KiB 16.8 us 1.0 GB/s
64 KiB 16.0 us 4.1 GB/s
256 KiB 22.1 us 11.9 GB/s
1024 KiB 104.1 us 10.1 GB/s
4096 KiB 331.5 us 12.7 GB/s
16384 KiB 642.3 us 26.1 GB/s
65536 KiB 2215.4 us 30.3 GB/s
$ ./transfers # on a Jetson AGX Thor
GPU: NVIDIA Thor, integrated, 2 copy engine(s)
copies of 64 MiB
pageable host -> device 0.57 ms 118.4 GB/s
pinned host -> device 0.57 ms 118.4 GB/s
device -> pageable host 0.68 ms 99.4 GB/s
device -> pinned host 0.62 ms 108.9 GB/s
pinned host -> device, by size
4 KiB 23.2 us 0.2 GB/s
16 KiB 23.2 us 0.7 GB/s
64 KiB 23.9 us 2.7 GB/s
256 KiB 28.0 us 9.4 GB/s
1024 KiB 32.1 us 32.7 GB/s
4096 KiB 55.6 us 75.5 GB/s
16384 KiB 167.0 us 100.5 GB/s
65536 KiB 573.8 us 117.0 GB/s
Pinned and pageable memory. On the Orin NX, pinned copies ran 2.1 to 3.5 times as fast as pageable ones: 19.8 / 5.7 = 3.5 and 16.3 / 7.8 = 2.1 in the C++ run (figure 4.4). The difference is the CPU’s copy into the staging buffer, which pinned copies do not need. On the Thor, both kinds of copy ran at the same speed, because its GPU reads pageable memory through the CPU’s page tables (section 4.2.2). Its largest copies reached 117 GB/s, close to the 137 GB/s limit for a copy within its 273 GB/s memory, with \(t_0\) of about 23 µs.
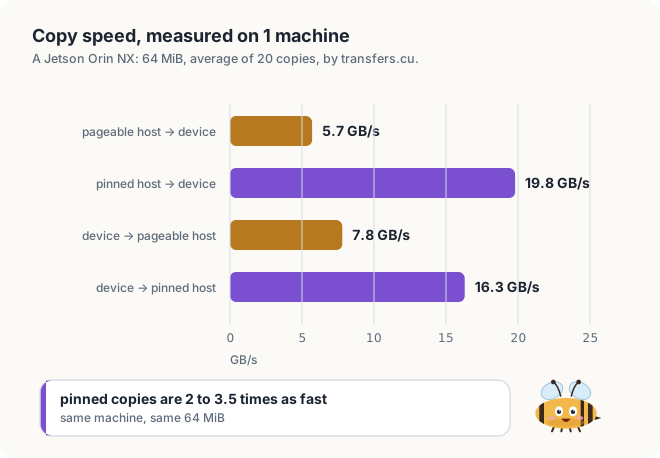
Latency and bandwidth. On the Orin NX, every copy up to 64 KiB took about 16 to 22 µs regardless of its size; this is \(t_0\). From 1 MiB upward the time grows with the size, and the largest copies reached about 30 GB/s. Figure 4.5 plots the measured points together with the model of section 4.3, using \(t_0\) = 16 µs and \(B\) = 30 GB/s.
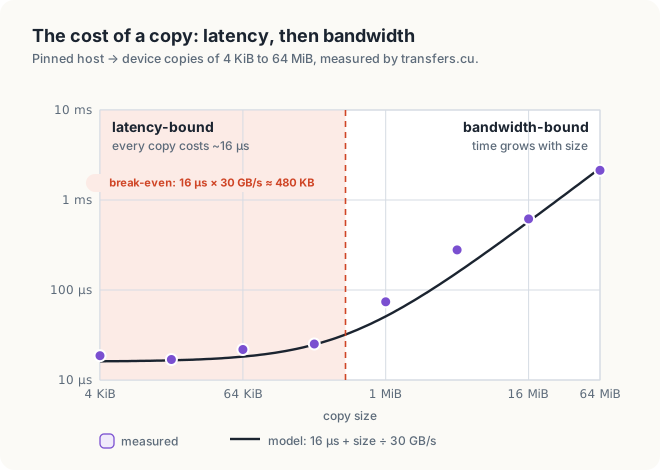
The model’s 2 parameters describe 8 measurements over a 16,384-fold range of sizes. Between 1 MiB and 4 MiB the points lie above the line, within the variation between runs.
The bandwidth of 30 GB/s is below the 51 GB/s that a copy within 102 GB/s of shared memory could reach (section 4.1.3), so on this GPU the copy engine, not the memory, sets the limit. Timings vary by up to about 30% from run to run, because the GPU changes its clock rates with load and temperature; the shape of the results does not change.
A program copies 1,000 buffers of 4 KB each to the device, 1 copy per buffer, with t0 = 16 µs and B = 30 GB/s. How long does it take, and how long would 1 copy of all 4 MB take?
1,000 copies take about 1,000 × (16 µs + 4 KB / 30 GB/s) = 1,000 × (16 + 0.13) µs ≈ 16 ms. One copy of 4 MB takes 16 µs + 4 MB / 30 GB/s ≈ 16 + 133 = 149 µs, about 100 times less.
4.5 Unified memory
Explicit copies work well for arrays, but not for data structures built from pointers. A tree copied node by node to the device still holds host addresses in every pointer, and the program would have to rewrite each of them.
Unified memory is memory that the host and the device access through the same pointer.
CUDA allocates it with cudaMallocManaged, and the program reads and writes it on either side
without calling cudaMemcpy. The pages must still reach the GPU before a kernel can use them.
On a discrete GPU, the CUDA driver moves a page the first time a kernel accesses it. The access
causes a page fault: the warp that made the access stops, the driver moves the page across
the link and records its new location, and the warp resumes (animation 2). Later accesses to
the page run at full speed.
Listing 4.4 Unified memory.
/// 3. Unified memory: 1 pointer for both sides. The host writes it first.
fn unified_memory(
module: &kernels::LoadedModule,
ctx: &Arc<CudaContext>,
stream: &Arc<CudaStream>,
) -> Result<(), Error> {
let mut ptr: sys::CUdeviceptr = 0;
let global = sys::CUmemAttach_flags_enum_CU_MEM_ATTACH_GLOBAL;
// SAFETY: cuMemAllocManaged stores the address of N new floats in `ptr`.
unsafe { sys::cuMemAllocManaged(&mut ptr, N * size_of::<f32>(), global) }.result()?;
// SAFETY: `ptr` holds N floats; the buffer frees them with cuMemFree, as CUDA requires.
let mut managed = unsafe { DeviceBuffer::<f32>::from_raw_parts(ptr, N, ctx.clone()) };
// SAFETY: managed memory is valid on the host, and no kernel uses it yet.
let host = unsafe { std::slice::from_raw_parts_mut(ptr as *mut f32, N) };
host.fill(1.0);
println!("unified memory, kernel over {} MiB", managed.num_bytes() >> 20);
let first = time_scale(module, stream, &mut managed, 1)?;
let next = time_scale(module, stream, &mut managed, 10)?;
println!(" 1st launch, after the host wrote it {first:6.2} ms");
println!(" next 10 launches, average {next:6.2} ms");
// SAFETY: time_scale waited for the kernels, so the host may read the memory again.
let value = unsafe { *(ptr as *const f32) };
println!(" host reads managed[0] = {value}");
Ok(())
}// 3. Unified memory: 1 pointer for both sides. The host writes it first.
void unifiedMemory(int n)
{
float* managed;
check(cudaMallocManaged(&managed, n * sizeof(float)));
for (int i = 0; i < n; ++i) {
managed[i] = 1.0f;
}
std::printf("unified memory, kernel over %d MiB\n", int(n * sizeof(float) >> 20));
double first = timeScale(managed, n, 1);
double next = timeScale(managed, n, 10);
std::printf(" 1st launch, after the host wrote it %6.2f ms\n", first);
std::printf(" next 10 launches, average %6.2f ms\n", next);
std::printf(" host reads managed[0] = %g\n", managed[0]);
check(cudaFree(managed));
}
The function unifiedMemory allocates 64 MiB with cudaMallocManaged and sets every element
to 1.0 on the host. It then launches a kernel that doubles every element, first once and then
10 more times, and times both. Finally, the host reads the first element. The kernel has
doubled 1.0 11 times, so the expected value is 211 = 2,048; the printed value
confirms that the host and the device worked on the same memory.
unified memory, kernel over 64 MiB
1st launch, after the host wrote it 3.51 ms
next 10 launches, average 2.26 ms
host reads managed[0] = 2048
On the Orin NX, the first launch took about 1.5 times as long as the later ones, because the driver prepares the pages for the GPU on first use. No data crosses a link, since the host and the device share the memory. On a discrete GPU, the first launch also pays for moving every page across PCIe. At about 25 GB/s, 64 MiB adds about 2.7 ms, and because page faults move the data in many small pieces, each paying a latency, the real cost is higher still.
A program can avoid the page faults by moving the pages to the device in 1 bulk transfer before the kernel needs them:
// move the pages to device 0 now
unsafe { sys::cuMemPrefetchAsync(managed, bytes, 0, stream.cu_stream()) }.result()?;cudaMemPrefetchAsync(managed, bytes, 0); // move the pages to device 0 now
Unified memory is best suited to data structures that contain many pointers, such as trees and graphs, which are difficult to copy by hand. For large arrays, explicit copies or prefetching give the program control over when the bytes move.
NOTE: The version of cuda-oxide used in this book has no wrapper for unified memory or
zero-copy memory, so the Rust code of sections 4.5 and 4.6 calls the CUDA driver functions
cuMemAllocManaged, cuMemPrefetchAsync, cuMemHostAlloc and cuMemHostGetDevicePointer
through cuda_core::sys.
4.6 Zero-copy memory
Zero-copy memory is pinned host memory that a kernel reads and writes in place, without any
copy. CUDA allocates it with cudaHostAlloc and the flag cudaHostAllocMapped, and
cudaHostGetDevicePointer returns the address through which a kernel accesses it. The memory
must be pinned for the reason given in section 4.2: the GPU accesses it by physical address. On
a discrete GPU, every load or store that a kernel makes to zero-copy memory crosses the link.
Listing 4.5 Zero-copy memory.
/// 4. Zero-copy: pinned host memory that a kernel reads and writes in place.
fn zero_copy(
module: &kernels::LoadedModule,
ctx: &Arc<CudaContext>,
stream: &Arc<CudaStream>,
device: &mut DeviceBuffer<f32>,
) -> Result<(), Error> {
let bytes = N * size_of::<f32>();
let mut host: *mut c_void = std::ptr::null_mut();
let mut ptr: sys::CUdeviceptr = 0;
let mapped_flag = sys::CU_MEMHOSTALLOC_DEVICEMAP;
// SAFETY: cuMemHostAlloc stores the address of `bytes` new pinned bytes in `host`.
unsafe { sys::cuMemHostAlloc(&mut host, bytes, mapped_flag) }.result()?;
// SAFETY: `host` is mapped memory; its address for kernels is stored in `ptr`.
unsafe { sys::cuMemHostGetDevicePointer_v2(&mut ptr, host, 0) }.result()?;
// SAFETY: `host` holds `bytes` bytes, and no kernel uses them yet.
unsafe { std::ptr::write_bytes(host.cast::<u8>(), 0, bytes) };
// SAFETY: `ptr` addresses N floats; into_raw_parts below stops the buffer freeing them.
let mut mapped = unsafe { DeviceBuffer::<f32>::from_raw_parts(ptr, N, ctx.clone()) };
time_scale(module, stream, device, 1)?; // warm up the kernel itself
println!("kernel over {} MiB, average of 10 launches", bytes >> 20);
let in_device = time_scale(module, stream, device, 10)?;
println!(" in device memory {in_device:6.2} ms");
let in_mapped = time_scale(module, stream, &mut mapped, 10)?;
println!(" in zero-copy memory {in_mapped:6.2} ms");
// Pinned host memory is freed with cuMemFreeHost, not with the buffer's cuMemFree.
let _ = mapped.into_raw_parts();
// SAFETY: time_scale waited for the kernels, so no kernel uses the memory any more.
unsafe { sys::cuMemFreeHost(host) }.result()?;
Ok(())
}// 4. Zero-copy: pinned host memory that a kernel reads and writes in place.
void zeroCopy(float* device, int n)
{
float* mapped;
float* mappedOnDevice;
check(cudaHostAlloc(&mapped, n * sizeof(float), cudaHostAllocMapped));
check(cudaHostGetDevicePointer(&mappedOnDevice, mapped, 0));
std::memset(mapped, 0, n * sizeof(float));
timeScale(device, n, 1); // warm up the kernel itself
int mib = int(n * sizeof(float) >> 20);
std::printf("kernel over %d MiB, average of 10 launches\n", mib);
std::printf(" in device memory %6.2f ms\n", timeScale(device, n, 10));
std::printf(" in zero-copy memory %6.2f ms\n", timeScale(mappedOnDevice, n, 10));
check(cudaFreeHost(mapped));
}
The function zeroCopy allocates mapped host memory, obtains the device address of that memory,
and runs the same doubling kernel 10 times on device memory and 10 times on the mapped memory.
The kernel reads 64 MiB and writes 64 MiB, which is 0.134 GB of traffic in total. On a discrete
GPU such as an RTX 4090, this traffic takes 0.134 / 1,000 = 0.13 ms in device memory at about
1 TB/s, but 0.134 / 25 = 5.4 ms in zero-copy memory across PCIe 4.0 at about 25 GB/s. Zero-copy
is therefore about 40 times slower on such a GPU, and every further launch pays the same cost
again, because no data stays on the device.
On an integrated GPU the result is different, because zero-copy memory and device memory are the same memory chips. On the Orin NX the kernel took about the same time in both:
kernel over 64 MiB, average of 10 launches
in device memory 1.70 ms
in zero-copy memory 1.72 ms
On a discrete GPU, zero-copy memory is therefore suited to small data and to data that a kernel reads only once, such as a few parameters, or a result that the host needs as soon as it is written. On an integrated GPU it can replace copies altogether. Figure 4.6 compares the 3 ways in which data reaches a kernel, according to when the bytes move.
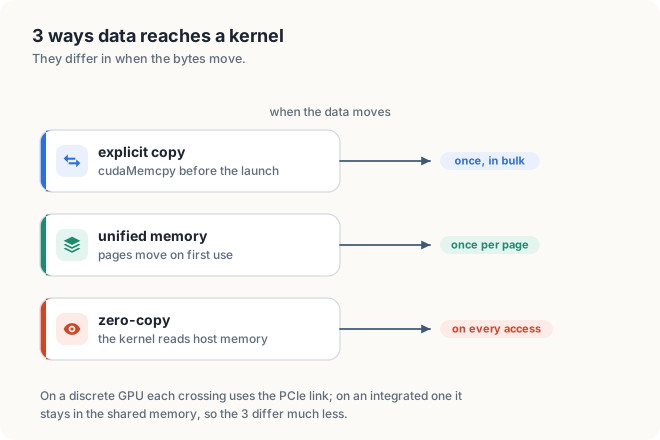
4.7 Choosing a kind of memory
The table summarizes the choice of memory for common situations.
| Situation | Choice | Reason |
|---|---|---|
| data copied once, at start-up | pageable memory and cudaMemcpy | simplest; the slower copy happens once |
| data copied again and again | pinned memory (cudaMallocHost, PinnedHostBuffer) | 1 copy instead of 2, 2 to 3.5 times as fast unless the GPU uses the CPU’s page tables |
| many small pieces of data | 1 pinned buffer, copied once | pays the copy latency \(t_0\) once instead of many times |
| pointer-heavy data structures | unified memory and cudaMemPrefetchAsync | 1 pointer on both sides; no copying by hand |
| small data, or data read once | zero-copy memory (cudaHostAllocMapped) | no copy at all |
| data on an integrated GPU | zero-copy or unified memory | host and device share the chips, so copies only duplicate data |
| data used by kernel after kernel | device memory (cudaMalloc, DeviceBuffer) | the full speed of the GPU’s memory |
A common mistake is to allocate everything with cudaMallocManaged because it is convenient,
and then to find on a discrete GPU that a large array crosses the link page by page. The kind
of memory should be chosen as part of the design of a program.
4.8 Overlapping copies with kernels
A copy engine and the SMs are separate units, so a copy and a kernel that work on different data can run at the same time. Double buffering divides the data into chunks, and while a kernel processes 1 chunk, a copy engine transfers the next (figure 4.7).
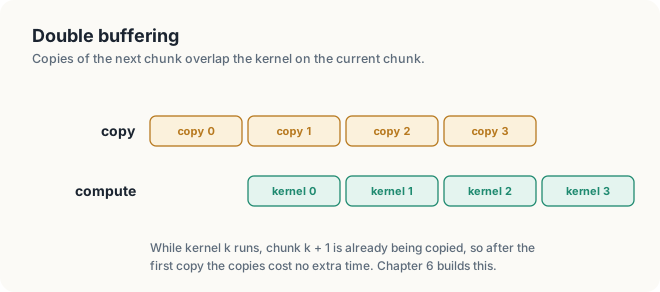
Consider 4 chunks whose copy and kernel take 1 time unit each. Performed in sequence, the work
takes 4 × 2 = 8 units; overlapped, it takes 1 + 3 + 1 = 5 units. After the first copy, the
copies add no time as long as each copy takes no longer than each kernel. A GPU with 2 copy
engines, as transfers reported for the Orin NX, can also copy results back to the host while
it copies the next inputs in. Double buffering requires pinned memory and asynchronous copies,
which Chapter 6 introduces.
4.9 The complete programs
Listing 4.6 The complete programs. code/oxide/ch04_transfers/src/main.rs code/ch04_memory/transfers.cu
//! Chapter 4 in Rust: copy speed from pageable and from pinned host memory, copy time
//! against copy size, unified memory, and zero-copy memory.
//!
//! cargo oxide run
use std::ffi::c_void;
use std::sync::Arc;
use std::time::Instant;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, DriverError, IntoResult};
use cuda_core::{LaunchConfig1D, PinnedHostBuffer, sys};
use cuda_device::{DisjointSlice, cuda_module, kernel, launch_contract, thread};
type Error = Box<dyn std::error::Error>;
const N: usize = 16 << 20; // 16,777,216 floats, 64 MiB
#[cuda_module]
mod kernels {
use super::*;
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scale(mut x: DisjointSlice<f32>) {
if let Some(v) = x.get_mut(thread::index_1d()) {
*v = 2.0 * *v;
}
}
}
/// Runs `copy` once to warm up, then `reps` times; returns the average in milliseconds.
fn time_copy(
reps: u32,
mut copy: impl FnMut() -> Result<(), DriverError>,
) -> Result<f64, DriverError> {
copy()?;
let start = Instant::now();
for _ in 0..reps {
copy()?;
}
Ok(start.elapsed().as_secs_f64() * 1e3 / reps as f64)
}
fn gb_per_s(bytes: usize, ms: f64) -> f64 {
bytes as f64 / 1e9 / (ms / 1e3)
}
/// Average time of `reps` launches of `scale` over `x`, in milliseconds.
fn time_scale(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
x: &mut DeviceBuffer<f32>,
reps: u32,
) -> Result<f64, Error> {
let blocks = x.len().div_ceil(256) as u32;
let launch = module.prepare_scale(LaunchConfig1D::new(blocks, 256, 0))?;
let start = Instant::now();
for _ in 0..reps {
module.scale(stream, &launch, x)?;
}
stream.synchronize()?;
Ok(start.elapsed().as_secs_f64() * 1e3 / reps as f64)
}
/// 3. Unified memory: 1 pointer for both sides. The host writes it first.
fn unified_memory(
module: &kernels::LoadedModule,
ctx: &Arc<CudaContext>,
stream: &Arc<CudaStream>,
) -> Result<(), Error> {
let mut ptr: sys::CUdeviceptr = 0;
let global = sys::CUmemAttach_flags_enum_CU_MEM_ATTACH_GLOBAL;
// SAFETY: cuMemAllocManaged stores the address of N new floats in `ptr`.
unsafe { sys::cuMemAllocManaged(&mut ptr, N * size_of::<f32>(), global) }.result()?;
// SAFETY: `ptr` holds N floats; the buffer frees them with cuMemFree, as CUDA requires.
let mut managed = unsafe { DeviceBuffer::<f32>::from_raw_parts(ptr, N, ctx.clone()) };
// SAFETY: managed memory is valid on the host, and no kernel uses it yet.
let host = unsafe { std::slice::from_raw_parts_mut(ptr as *mut f32, N) };
host.fill(1.0);
println!("unified memory, kernel over {} MiB", managed.num_bytes() >> 20);
let first = time_scale(module, stream, &mut managed, 1)?;
let next = time_scale(module, stream, &mut managed, 10)?;
println!(" 1st launch, after the host wrote it {first:6.2} ms");
println!(" next 10 launches, average {next:6.2} ms");
// SAFETY: time_scale waited for the kernels, so the host may read the memory again.
let value = unsafe { *(ptr as *const f32) };
println!(" host reads managed[0] = {value}");
Ok(())
}
/// 4. Zero-copy: pinned host memory that a kernel reads and writes in place.
fn zero_copy(
module: &kernels::LoadedModule,
ctx: &Arc<CudaContext>,
stream: &Arc<CudaStream>,
device: &mut DeviceBuffer<f32>,
) -> Result<(), Error> {
let bytes = N * size_of::<f32>();
let mut host: *mut c_void = std::ptr::null_mut();
let mut ptr: sys::CUdeviceptr = 0;
let mapped_flag = sys::CU_MEMHOSTALLOC_DEVICEMAP;
// SAFETY: cuMemHostAlloc stores the address of `bytes` new pinned bytes in `host`.
unsafe { sys::cuMemHostAlloc(&mut host, bytes, mapped_flag) }.result()?;
// SAFETY: `host` is mapped memory; its address for kernels is stored in `ptr`.
unsafe { sys::cuMemHostGetDevicePointer_v2(&mut ptr, host, 0) }.result()?;
// SAFETY: `host` holds `bytes` bytes, and no kernel uses them yet.
unsafe { std::ptr::write_bytes(host.cast::<u8>(), 0, bytes) };
// SAFETY: `ptr` addresses N floats; into_raw_parts below stops the buffer freeing them.
let mut mapped = unsafe { DeviceBuffer::<f32>::from_raw_parts(ptr, N, ctx.clone()) };
time_scale(module, stream, device, 1)?; // warm up the kernel itself
println!("kernel over {} MiB, average of 10 launches", bytes >> 20);
let in_device = time_scale(module, stream, device, 10)?;
println!(" in device memory {in_device:6.2} ms");
let in_mapped = time_scale(module, stream, &mut mapped, 10)?;
println!(" in zero-copy memory {in_mapped:6.2} ms");
// Pinned host memory is freed with cuMemFreeHost, not with the buffer's cuMemFree.
let _ = mapped.into_raw_parts();
// SAFETY: time_scale waited for the kernels, so no kernel uses the memory any more.
unsafe { sys::cuMemFreeHost(host) }.result()?;
Ok(())
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
let mut pageable = vec![0.0f32; N];
let mut pinned = PinnedHostBuffer::<f32>::zeroed(&ctx, N)?;
let mut device = DeviceBuffer::<f32>::zeroed(&stream, N)?;
let bytes = N * size_of::<f32>();
println!("copies of {} MiB", bytes >> 20);
let ms = time_copy(20, || device.copy_from_host(&stream, &pageable))?;
println!(" pageable host -> device {ms:6.2} ms {:5.1} GB/s", gb_per_s(bytes, ms));
let ms = time_copy(20, || device.copy_from_host(&stream, pinned.as_slice()))?;
println!(" pinned host -> device {ms:6.2} ms {:5.1} GB/s", gb_per_s(bytes, ms));
let ms = time_copy(20, || device.copy_to_host(&stream, &mut pageable))?;
println!(" device -> pageable host {ms:6.2} ms {:5.1} GB/s", gb_per_s(bytes, ms));
let ms = time_copy(20, || device.copy_to_pinned_host(&stream, &mut pinned))?;
println!(" device -> pinned host {ms:6.2} ms {:5.1} GB/s", gb_per_s(bytes, ms));
println!("pinned host -> device, by size");
let mut len = 1 << 10; // 1,024 floats, 4 KiB
while len <= N {
let mut part = DeviceBuffer::<f32>::zeroed(&stream, len)?;
let src = &pinned.as_slice()[..len];
let ms = time_copy(200, || part.copy_from_host(&stream, src))?;
let size = len * size_of::<f32>();
let (kib, us) = (size >> 10, ms * 1e3);
println!(" {kib:8} KiB {us:8.1} us {:5.1} GB/s", gb_per_s(size, ms));
len *= 4;
}
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
unified_memory(&module, &ctx, &stream)?;
zero_copy(&module, &ctx, &stream, &mut device)?;
Ok(())
}// Chapter 4: how fast data moves between host and device, measured on this GPU.
// Build: nvcc -arch=native transfers.cu -o transfers
#include <chrono>
#include <cstdio>
#include <cstdlib>
#include <cstring>
#include <cuda_runtime.h>
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// Average time of `reps` copies of `bytes`, in milliseconds, after 1 warm-up copy.
double timeCopy(void* dst, const void* src, size_t bytes, cudaMemcpyKind kind, int reps)
{
    check(cudaMemcpy(dst, src, bytes, kind));

    double t0 = nowMs();
    for (int r = 0; r < reps; ++r) {
        check(cudaMemcpy(dst, src, bytes, kind));
    }

    return (nowMs() - t0) / reps;
}
__global__ void scale(float* x, int n)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
x[i] = 2.0f * x[i];
}
}
// Average time of `reps` launches of `scale` over `x`, in milliseconds.
double timeScale(float* x, int n, int reps)
{
double t0 = nowMs();
for (int r = 0; r < reps; ++r) {
scale<<<(n + 255) / 256, 256>>>(x, n);
}
check(cudaGetLastError());
check(cudaDeviceSynchronize());
return (nowMs() - t0) / reps;
}
// 1. Copy speed from pageable and from pinned host memory, both directions.
void copySpeeds(float* pageable, float* pinned, float* device, size_t bytes)
{
    struct Case { const char* name; void* dst; const void* src; cudaMemcpyKind kind; };
    const Case cases[] = {
        {"pageable host -> device", device, pageable, cudaMemcpyHostToDevice},
        {"pinned   host -> device", device, pinned, cudaMemcpyHostToDevice},
        {"device -> pageable host", pageable, device, cudaMemcpyDeviceToHost},
        {"device -> pinned   host", pinned, device, cudaMemcpyDeviceToHost},
    };

    std::printf("copies of %zu MiB\n", bytes >> 20);
    for (const Case& c : cases) {
        double ms = timeCopy(c.dst, c.src, bytes, c.kind, 20);
        std::printf("  %s  %6.2f ms  %5.1f GB/s\n", c.name, ms, bytes / 1e9 / (ms / 1e3));
    }
}
// 2. Copy time against copy size, pinned host -> device.
void sizeSweep(float* pinned, float* device)
{
    std::printf("pinned host -> device, by size\n");

    for (size_t bytes = 4 << 10; bytes <= (64 << 20); bytes *= 4) {
        double ms = timeCopy(device, pinned, bytes, cudaMemcpyHostToDevice, 200);
        std::printf("  %8zu KiB  %8.1f us  %5.1f GB/s\n",
                    bytes >> 10, ms * 1e3, bytes / 1e9 / (ms / 1e3));
    }
}
// 3. Unified memory: 1 pointer for both sides. The host writes it first.
void unifiedMemory(int n)
{
    float* managed;
    check(cudaMallocManaged(&managed, n * sizeof(float)));

    for (int i = 0; i < n; ++i) {
        managed[i] = 1.0f;
    }

    std::printf("unified memory, kernel over %d MiB\n", int(n * sizeof(float) >> 20));
    double first = timeScale(managed, n, 1);
    double next = timeScale(managed, n, 10);
    std::printf("  1st launch, after the host wrote it  %6.2f ms\n", first);
    std::printf("  next 10 launches, average            %6.2f ms\n", next);
    std::printf("  host reads managed[0] = %g\n", managed[0]);

    check(cudaFree(managed));
}
// 4. Zero-copy: pinned host memory that a kernel reads and writes in place.
void zeroCopy(float* device, int n)
{
    float* mapped;
    float* mappedOnDevice;
    check(cudaHostAlloc(&mapped, n * sizeof(float), cudaHostAllocMapped));
    check(cudaHostGetDevicePointer(&mappedOnDevice, mapped, 0));
    std::memset(mapped, 0, n * sizeof(float));

    timeScale(device, n, 1);                  // warm up the kernel itself
    int mib = int(n * sizeof(float) >> 20);
    std::printf("kernel over %d MiB, average of 10 launches\n", mib);
    std::printf("  in device memory      %6.2f ms\n", timeScale(device, n, 10));
    std::printf("  in zero-copy memory   %6.2f ms\n", timeScale(mappedOnDevice, n, 10));

    check(cudaFreeHost(mapped));
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %s, %d copy engine(s)\n", prop.name,
prop.integrated ? "integrated" : "discrete", prop.asyncEngineCount);
const int n = 16 << 20; // 16,777,216 floats
const size_t bytes = n * sizeof(float); // 64 MiB
float* pageable = static_cast<float*>(std::malloc(bytes));
float* pinned;
float* device;
check(cudaMallocHost(&pinned, bytes));
check(cudaMalloc(&device, bytes));
std::memset(pageable, 0, bytes);
std::memset(pinned, 0, bytes);
copySpeeds(pageable, pinned, device, bytes);
sizeSweep(pinned, device);
unifiedMemory(n);
zeroCopy(device, n);
std::free(pageable);
check(cudaFreeHost(pinned));
check(cudaFree(device));
}
Common mistakes
- Copying repeatedly from pageable memory. Pin the buffers that are copied often.
- Many small copies. Each pays the fixed latency \(t_0\). Gather small pieces into 1 buffer and copy it once.
- Freeing pinned memory with
freeordelete. PaircudaMallocHostandcudaHostAllocwithcudaFreeHost, andcudaMallocwithcudaFree. - Pinning everything. Pinned pages cannot move, which leaves the operating system less memory to manage for other programs.
- Using unified memory for every array on a discrete GPU. Large arrays then move page by page, on first access. Prefetch them, or copy them explicitly.
- Using zero-copy memory on a discrete GPU for large data that kernels read repeatedly. Every access crosses the link.
- Timing the first copy. It includes work that happens only once; perform a warm-up copy first and average several copies.
Summary
- A discrete GPU has its own memory across a link: PCIe 4.0 at about 32 GB/s in each direction, PCIe 5.0 at about 64 GB/s, and NVLink-C2C at 450 GB/s. An integrated GPU shares the CPU’s memory, and a copy within that memory can use at most half of its bandwidth.
- The operating system may move pageable pages, so CUDA copies them through a pinned staging buffer. Pinned memory is transferred directly by a copy engine, 2 to 3.5 times as fast on the Orin NX. A GPU that uses the CPU’s page tables, such as the Thor’s, copies pageable memory as fast as pinned memory.
- The time of a copy is \(T = t_0 + N/B\). Below the break-even size \(t_0 B\), a copy is latency-bound, so many small copies should be combined into 1 large copy.
- Unified memory gives the host and the device 1 pointer. Its pages move on first use, or in
advance with
cudaMemPrefetchAsync. - Zero-copy memory is accessed in place. It is slow for large data on a discrete GPU and as fast as device memory on an integrated GPU.
- In Rust with cuda-oxide,
PinnedHostBufferholds pinned memory,DeviceBuffercopies to and from it, and every copy returns aResult.
In Chapter 5, we turn to threads that depend on each other’s results: barriers, atomic operations and race conditions.
Exercises
- A 4 GB dataset is copied to an H100 over PCIe 5.0 at 50 GB/s from pinned memory, and at 15 GB/s from pageable memory. How many milliseconds does pinning save?
- Run
transferson your own GPU. Fit \(t_0\) and \(B\) to your sweep, and calculate your break-even size. - Why can a copy engine not copy directly from pageable memory? Describe what could go wrong.
- A kernel reads each element of a 1 GB unified-memory array once on a discrete GPU. Where
would you call
cudaMemPrefetchAsync, and why? - A kernel reads the same 1 MB of zero-copy memory 1,000 times on a discrete GPU at 25 GB/s. How long do the reads take, and how long would they take from device memory at 1 TB/s?
- A GH200 copies 1 GB from host to device over NVLink-C2C at 450 GB/s. How long does the copy take, and how does that compare with the H100 on PCIe 5.0?
- In the Rust program, pass
&pageableinstead ofpinned.as_slice()in the second copy. What happens to the measured speed, and why?
Sources and further reading
- NVIDIA, CUDA C++ Programming Guide, “Page-Locked Host Memory”, “Mapped Memory” and “Unified Memory Programming”: https://docs.nvidia.com/cuda/cuda-c-programming-guide/
- NVIDIA, CUDA C++ Best Practices Guide, “Data Transfer Between Host and Device”: https://docs.nvidia.com/cuda/cuda-c-best-practices-guide/
- NVIDIA, CUDA for Tegra, on memory in integrated systems: https://docs.nvidia.com/cuda/cuda-for-tegra-appnote/
- NVIDIA, NVIDIA Grace Hopper Superchip Architecture whitepaper, for NVLink-C2C.
- PCI-SIG, PCI Express Base Specifications 4.0 and 5.0, for lane rates.
Chapter 5: Synchronization, Atomics & Race Conditions
In every kernel so far, we used one thread to write one element of the result array. In the
vector addition kernel, for example, thread \(i\) wrote c[i] and nothing else, so the threads
never needed to know about each other. Many useful computations lack this property. To build a
histogram of bytes, we let millions of threads add counts to only 256 bins. To compute a sum, we
let every thread contribute a part of a single result. Whenever 2 threads access one memory
location, and at least one of them writes to it, the result can depend on the order of those
accesses. The hardware does not choose that order in any predictable way, so we must impose an
order wherever our program needs one.
In this chapter, we’ll examine the two mechanisms that CUDA provides for this purpose. With a barrier, we make the threads of a block wait for each other at a chosen point in the program. With an atomic operation, we perform a read-modify-write on a memory location as one indivisible step. We’ll also examine control divergence, the slowdown that occurs when threads of one warp take different paths through a branch. We measure each effect with a C++ program and a Rust program.
This chapter covers
- race conditions, and why a kernel can complete without error and still produce a wrong result
- control divergence within a warp
__syncthreads(), the barrier for the threads of a block, and the errors caused by a missing barrier- the visibility of writes across blocks: caches, memory fences and memory orderings
- atomic operations, and the atomic types that safe Rust requires for a shared counter
- privatization of a histogram in shared memory, 6 to 28 times as fast as the direct version
- why a floating-point sum computed with atomic operations varies from run to run
The code of the chapter is in
code/ch05_sync/
for C++ and in
code/oxide/ch05_sync/
for Rust.
5.1 Race conditions
5.1.1 Lost updates
The statement counter = counter + 1 appears to be a single step, but a processor executes it as
3. It reads the value of counter from memory into a register, adds 1 to the register,
and writes the register back to memory. Since these are separate operations, another thread
can access counter between them. Figure 5.1 shows 2 threads that do so.
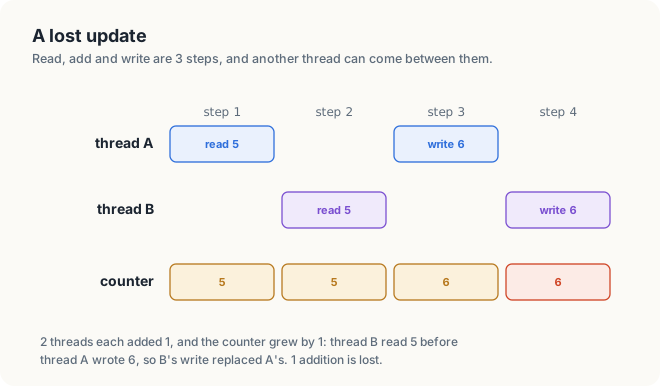
The counter initially holds 5. Thread A reads 5 in step 1, and thread B reads 5 in step 2, before A has written its result. Both threads compute 6, and both write 6. Two additions were performed, but the counter increased by only 1. The addition performed by thread A has been overwritten; we call this a lost update. The situation that makes it possible is called a race condition. A race condition, or data race, occurs when 2 or more threads access the same memory location, at least one of the accesses is a write, and nothing in the program orders the accesses. The result then depends on the relative timing of the threads.
5.1.2 Measuring a race on the GPU
Listing 5.1 produces the same race with 1,048,576 threads. The kernel is launched with 4,096
blocks of 256 threads, and every thread executes *counter = *counter + 1 on the same location.
The second kernel, countAtomic, performs the same increment with atomicAdd, which we discuss
in section 5.5.
In Rust, the plain statement counter[0] = counter[0] + 1 on a slice that all threads share
does not compile. The kernel receives the slice as a shared reference, and the compiler rejects
the write with error E0594. The Rust kernel count_racy therefore writes the same race
explicitly. It reads the counter with an atomic load and writes the incremented value back with a
separate atomic store, so another thread can store between the 2 operations, exactly as in the
plain C++ addition.
Listing 5.1 2 ways to count. code/oxide/ch05_sync/src/main.rs code/ch05_sync/sync.cu
mod kernels {
    // ...
    // A lost update on purpose. The load and the store are 2 separate operations,
    // so another thread can store between them, exactly like the plain C++ add.
    #[kernel]
    #[launch_contract(domain = 1, block = (256, 1, 1))]
    pub fn count_racy(counter: &[DeviceAtomicU32]) {
        let seen = counter[0].load(AtomicOrdering::Relaxed);

        counter[0].store(seen + 1, AtomicOrdering::Relaxed);
    }

    #[kernel]
    #[launch_contract(domain = 1, block = (256, 1, 1))]
    pub fn count(counter: &[DeviceAtomicU32]) {
        counter[0].fetch_add(1, AtomicOrdering::Relaxed);
    }
    // ...
}
// 1. Every thread adds 1 to the same counter.
__global__ void countRacy(unsigned* counter)
{
*counter = *counter + 1;
}
__global__ void countAtomic(unsigned* counter)
{
atomicAdd(counter, 1u);
}
The measurements in this chapter come from 2 integrated GPUs, a Jetson Orin NX and a Jetson AGX Thor. The output below is from the first.
$ ./sync
1,048,576 threads each add 1 to 1 counter
plain add counter = 505
atomicAdd counter = 1048576
The plain version counted 505 of the 1,048,576 additions, and the same program counted 192 on the
second GPU. Nearly every update was lost, because thousands of threads read the counter at almost
the same time and wrote back almost the same value. The count also changes from one run to the
next. Note that the kernel completed without any error. The hardware does not detect races, so a
racy kernel stores a wrong result in exactly the same way as a correct kernel stores a right one.
The atomic version counted all 1,048,576 additions. The Rust program behaves in the same way. Its load-and-store kernel counted
94 of the 1,048,576 additions, and its fetch_add kernel counted all of them.
Animation 1 shows the race with 2 threads, followed by the same 2 additions performed with
atomicAdd.
atomicAdd.5.1.3 Shared counters in safe Rust
The racy kernel cannot be written in safe Rust. Recall from Chapter 3 that a cuda-oxide kernel
receives its inputs as &[T], which it can only read, and its outputs as a DisjointSlice, which
gives each thread access to its own element only. Neither type allows every thread to write
counter[0]. Memory that many threads update must instead have an atomic type, such as
DeviceAtomicU32, whose operations are all indivisible. Listing 5.2 shows the counting kernel
written this way.
Listing 5.2 The counter. code/oxide/ch05_sync/src/main.rs code/ch05_sync/sync.cu
mod kernels {
// ...
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn count(counter: &[DeviceAtomicU32]) {
counter[0].fetch_add(1, AtomicOrdering::Relaxed);
}
// ...
}__global__ void countAtomic(unsigned* counter)
{
atomicAdd(counter, 1u);
}
The host allocates the counter as ordinary zeroed u32 memory, as listing 5.3 shows. The
function atomic_u32 then calls cast_elem to change the element type that the kernel sees to
DeviceAtomicU32. The bytes in device memory are not moved or changed.
Listing 5.3 Allocating atomic counters and launching the count.
/// `n` zeroed counters that kernels update with atomic operations.
fn atomic_u32(
stream: &Arc<CudaStream>,
n: usize,
) -> Result<DeviceBuffer<DeviceAtomicU32>, DriverError> {
Ok(DeviceBuffer::<u32>::zeroed(stream, n)?.cast_elem::<DeviceAtomicU32>())
}
fn main() -> Result<(), Box<dyn std::error::Error>> {
// ...
// 1. 1,048,576 threads each add 1 to 1 counter, with a race and with an atomic.
let grid = LaunchConfig1D::new(4096, 256, 0);
let racy = atomic_u32(&stream, 1)?;
let launch = module.prepare_count_racy(grid)?;
module.count_racy(&stream, &launch, &racy)?;
let lost = racy.cast_elem::<u32>().to_host_vec(&stream)?;
let counter = atomic_u32(&stream, 1)?;
let launch = module.prepare_count(grid)?;
module.count(&stream, &launch, &counter)?;
let result = counter.cast_elem::<u32>().to_host_vec(&stream)?;
println!("1,048,576 threads each add 1 to 1 counter");
println!(" load, store counter = {}", lost[0]);
println!(" fetch_add counter = {}", result[0]);
// ...
}void race()
{
unsigned* counter;
check(cudaMalloc(&counter, sizeof(unsigned)));
const int blocks = 4096, threads = 256;
std::printf("1,048,576 threads each add 1 to 1 counter\n");
for (int atomic = 0; atomic < 2; ++atomic) {
unsigned result;
check(cudaMemset(counter, 0, sizeof(unsigned)));
if (atomic) {
countAtomic<<<blocks, threads>>>(counter);
} else {
countRacy<<<blocks, threads>>>(counter);
}
check(cudaMemcpy(&result, counter, sizeof(unsigned), cudaMemcpyDeviceToHost));
std::printf(" %-12s counter = %u\n", atomic ? "atomicAdd" : "plain add", result);
}
check(cudaFree(counter));
}
$ cargo oxide run
1,048,576 threads each add 1 to 1 counter
fetch_add counter = 1048576
The call to fetch_add takes a memory ordering, here Relaxed, which we explain in section 5.4.
The guarantee that Rust provides is a narrow one. A data race on ordinary device memory cannot be
written without unsafe. In section 5.3, we’ll see that accesses to shared memory still require
unsafe blocks, and in those blocks the programmer is again responsible for correctness.
5.2 Control divergence
Recall from Chapter 2 that a warp issues 1 instruction at a time for all 32 of its threads. A
branch therefore needs special handling when some threads of a warp take the if path and the
others take the else path. In this case, the warp executes both paths. It first executes the
if path, with the threads that took it active and the other threads idle. It then executes the
else path with the roles reversed. After the branch, the threads continue together. Executing
more than one path within a warp is called control divergence. Its cost is proportional to the
number of paths the warp executes, not to the number of threads that take each path, as figure 5.2
illustrates.
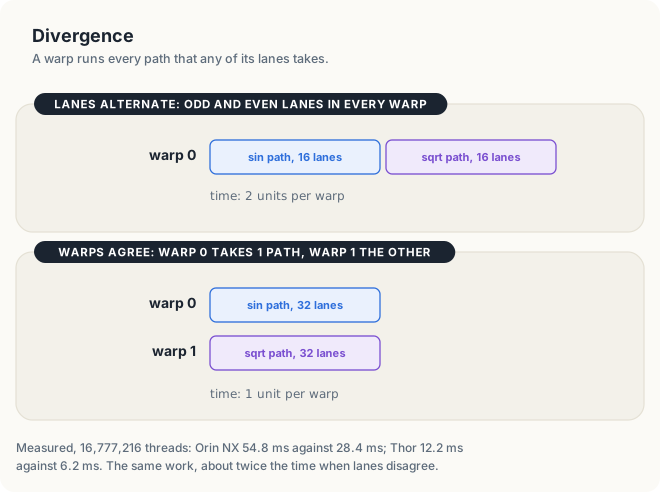
Listing 5.4 measures this cost. Every thread executes 1 of 2 loops of 64 iterations, and half the threads take each loop. The 2 runs of the kernel differ only in which threads take which loop.
Listing 5.4 A branch on alternate lanes or alternate warps.
mod kernels {
// ...
/// The loop of the odd threads: 64 steps of v = sin(v) + 1.
#[device]
fn sin_loop(mut v: f32) -> f32 {
let mut k = 0;
#[unroll]
while k < 64 {
v = v.sin() + 1.0;
k += 1;
}
v
}
/// The loop of the even threads: 64 steps of v = sqrt(v) / 2 + 1 / 4.
#[device]
fn sqrt_loop(mut v: f32) -> f32 {
let mut k = 0;
#[unroll]
while k < 64 {
v = v.sqrt() * 0.5 + 0.25;
k += 1;
}
v
}
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn branches(mut x: DisjointSlice<f32>, by_warp: bool) {
let tid = thread::threadIdx_x();
let odd = if by_warp { (tid / 32) % 2 == 1 } else { tid % 2 == 1 };
let Some(x_i) = x.get_mut(thread::index_1d()) else {
return;
};
let v = *x_i;
*x_i = if odd { sin_loop(v) } else { sqrt_loop(v) };
}
// ...
}// 4. Half the threads take each branch: alternate lanes, or alternate warps.
__global__ void branches(float* x, int n, bool byWarp)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i >= n) return;
bool odd = byWarp ? (threadIdx.x / 32) % 2 : threadIdx.x % 2;
float v = x[i];
if (odd) {
for (int k = 0; k < 64; ++k) v = sinf(v) + 1.0f;
} else {
for (int k = 0; k < 64; ++k) v = sqrtf(v) * 0.5f + 0.25f;
}
x[i] = v;
}
The variable odd decides the path. When byWarp is true, odd is computed from
threadIdx.x / 32, the number of the warp within the block. All 32 threads of a warp then compute
the same value, and each warp executes only 1 loop. When byWarp is false, odd is computed from
threadIdx.x % 2, which alternates from 1 thread to the next. Every warp then contains threads of
both kinds and must execute both loops.
branch on every other thread, 16777216 threads, average of 10 runs
whole warps agree 28.37 ms
lanes alternate 54.78 ms
The same work took 54.78 / 28.37 = 1.93 times as long when lanes alternated. On the second GPU, the ratio was 12.24 / 6.22 = 1.97. Both are close to 2, the ratio we expect from counting the paths each warp executes.
Divergence is therefore a property of warps, not of individual threads. A branch on blockIdx.x
or on threadIdx.x / 32 adds no cost, because all threads of each warp agree. The guard
if (i < n) of Chapter 3 diverges only in the warp that contains element \(n\), which is at most
1 warp in the entire grid, so its cost is negligible. Branches that depend on the data are more
likely to diverge. When the data can be arranged so that neighboring threads tend to take the same
path, the warps diverge less.
A warp executes every path that any of its threads takes, so branch on whole warps where you can.
5.3 __syncthreads(): the block barrier
5.3.1 Phases within a block
We often organize the work of a block in phases. In the first phase, we let each thread write a
value to shared memory. In the second phase, we let the threads read values that other threads
wrote. The second phase is correct only if every write of the first phase has completed. A barrier is a point in a
program that every thread of a group must reach before any thread of the group continues past it.
__syncthreads() is the barrier for the threads of 1 block. A thread that calls it waits until all
threads of its block have called it. In addition, the writes that each thread made to shared and
global memory before the barrier are visible to all threads of the block after it (figure 5.3). In
Rust, the same barrier is thread::sync_threads().
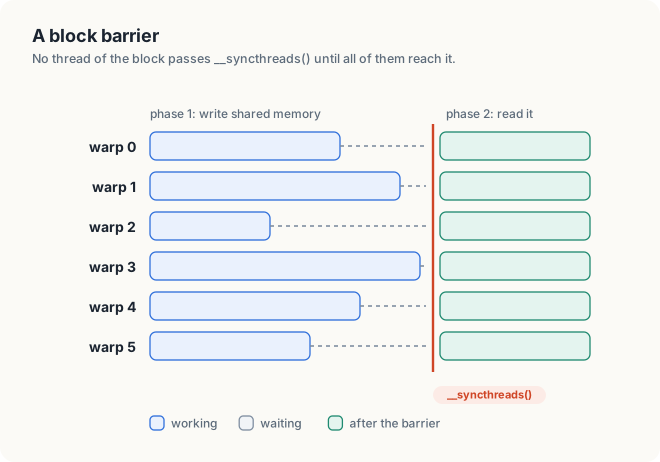
5.3.2 A block sum with and without barriers
Listing 5.5 sums the 256 values of each block in shared memory. Each thread first copies 1 value
from global memory into the shared array s. In the loop that follows, the variable stride
starts at 128. At stride 128, the first 128 threads each add s[k + 128] into s[k]. At stride
64, the first 64 threads add s[k + 64] into s[k], and so on, with the stride halved in each
iteration, until s[0] holds the sum of the block. 256 values require log2 256 = 8
levels. Figure 5.4 shows the same tree for 8 values.
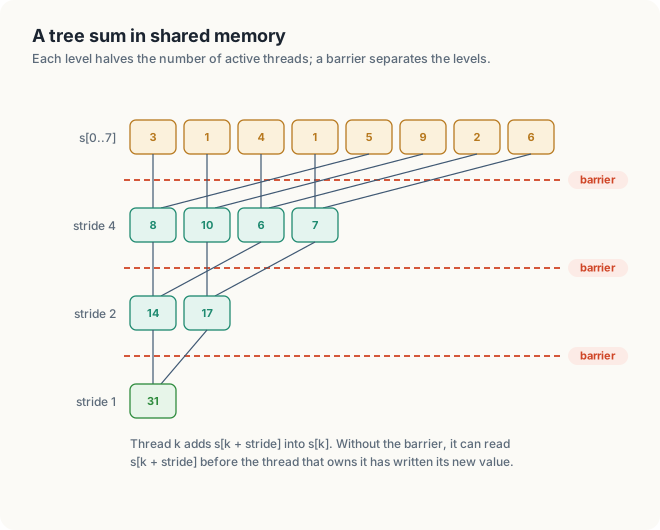
Listing 5.5 A block sum with or without barriers.
mod kernels {
// ...
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn block_sum(input: &[f32], mut out: DisjointSlice<f32>, barrier: bool) {
static mut S: SharedArray<f32, 256> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
let block = thread::blockIdx_x() as usize;
// SAFETY: each thread writes only its own element.
unsafe { S[tid] = input[block * 256 + tid] };
if barrier {
thread::sync_threads();
}
let mut stride = 128;
while stride > 0 {
if tid < stride {
// SAFETY: true only with the barriers. Thread tid alone writes S[tid] here,
// and S[tid + stride] was written before the last barrier.
unsafe { S[tid] += S[tid + stride] };
}
if barrier {
thread::sync_threads();
}
stride /= 2;
}
if tid == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *out.get_unchecked_mut(block) = S[0] };
}
}
// ...
}// 3. Each block sums its 256 values in shared memory, with or without barriers.
__global__ void blockSum(const float* in, float* out, bool barrier)
{
__shared__ float s[256];
s[threadIdx.x] = in[blockIdx.x * 256 + threadIdx.x];
if (barrier) __syncthreads();
for (int stride = 128; stride > 0; stride /= 2) {
if (threadIdx.x < stride) {
s[threadIdx.x] += s[threadIdx.x + stride];
}
if (barrier) __syncthreads();
}
if (threadIdx.x == 0) {
out[blockIdx.x] = s[0];
}
}
Each level reads values that the previous level wrote, and these values were often written by
threads in other warps. A barrier must therefore separate each level from the next. The parameter
barrier allows the program to leave the barriers out, so that we can observe the effect. Every
block sums 256 ones, so the correct result for every block is 256.
4,096 blocks each sum 256 ones; the right answer is 256
with barriers wrong sums: 0 of 4096 (block 0: 256)
without barriers wrong sums: 2450 of 4096 (block 0: 96)
Without barriers, 2,450 of the 4,096 block sums were wrong on the first GPU, and 3,057 on the second. A thread that reached the next level early read a value that its neighbor had not yet written. Some blocks still produced the correct sum, because whether a warp runs ahead of the others depends on the scheduling of the warps. Errors of this kind are difficult to find, because a test can pass on some runs and fail on others. Animation 2 shows the 8-value tree with and without barriers.
5.3.3 Rules for barriers
A barrier is correct only if every thread of the block reaches it, and reaches it the same number
of times. If __syncthreads() is placed inside a branch that some threads skip, the threads that
reach it wait for threads that never arrive, and the block hangs. In listing 5.5,
if (barrier) __syncthreads(); is allowed only because barrier has the same value in every
thread. The following code is incorrect:
if thread::threadIdx_x() % 2 == 0 {
thread::sync_threads(); // odd threads never arrive: the block hangs
}if (threadIdx.x % 2 == 0) {
__syncthreads(); // odd threads never arrive: the block hangs
}
Note also that a barrier applies to exactly 1 block. The blocks of a grid run on different SMs, and a GPU does not guarantee that all the blocks of a launch are running at the same time. There is therefore no ordinary barrier across a grid. Work that needs every block to complete a phase before any block starts the next is split into 2 kernel launches, which execute in order, or it uses atomic operations (section 5.5).
5.4 Visibility across blocks: caches, fences and orderings
A barrier orders memory accesses within a block. Between blocks, 2 further effects determine which writes of 1 thread another thread can see. First, each SM has its own L1 cache, and the L1 caches of different SMs are not kept consistent with each other. A thread on SM 0 can read a stale copy of a location that a thread on SM 1 has already changed in L2. Second, the compiler may keep a value in a register and never read it from memory again.
A memory fence orders the memory operations of 1 thread as other threads observe them.
__threadfence() guarantees that every write the thread made before the fence becomes visible to
the whole device before any write it makes after the fence. __threadfence_block() gives the
same guarantee for the threads of the block, and __threadfence_system() extends it to the host.
A fence does not make any thread wait. Its typical use is to publish data. A thread writes the
data, executes a fence, and then sets a flag, so that any thread that sees the flag also sees the
data.
cuda-oxide expresses the same ideas in its types. An atomic type names its scope, the set of
threads that must observe its operations: BlockAtomicU32 for 1 block, DeviceAtomicU32 for the
device, and SystemAtomicU32 for the device and the host. Each operation names a memory
ordering, which states what other memory accesses the operation orders:
| Ordering | Guarantee | Typical use |
|---|---|---|
Relaxed | the operation itself is atomic; nothing else is ordered | counters, histograms |
Release | writes before it are visible to a thread that acquires the value | setting a “data ready” flag |
Acquire | reads after it see what the releasing thread wrote | reading that flag |
AcqRel | both, for a read-modify-write | locks, queues |
SeqCst | 1 order of all such operations that every thread agrees on | rarely needed |
A counter needs only Relaxed, because no other memory access depends on its value. A flag that
announces that data is ready needs Release on the write and Acquire on the read.
5.5 Atomic operations
5.5.1 Atomic read-modify-write
An atomic operation is a read-modify-write that the hardware performs indivisibly. No other
thread can read or write the location between the read and the write of the operation. When 2
threads call atomicAdd on the same location, the 2 operations are performed one after the other,
in an order chosen by the hardware, and both take effect. Atomic operations do not
impose a particular order between the threads; they only guarantee that the operations do not
overlap. Atomic operations on global memory are performed in the L2 cache, which all SMs share
(figure 5.5).
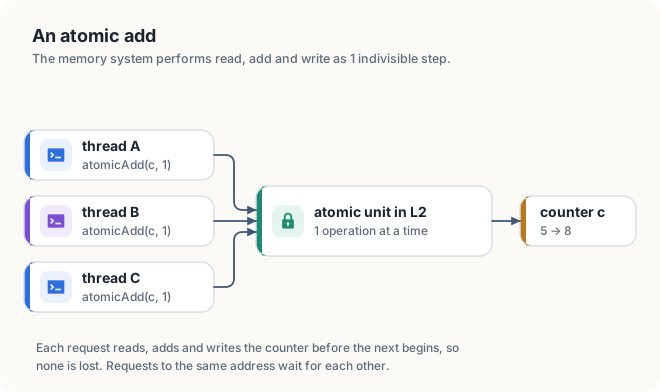
CUDA provides the following atomic functions for int, unsigned int and unsigned long long,
and atomicAdd also for float and double. Each function returns the value that the location
held before the operation.
| Function | Operation | Returns |
|---|---|---|
atomicAdd(addr, v) | *addr += v | the old value |
atomicSub(addr, v) | *addr -= v | the old value |
atomicExch(addr, v) | *addr = v | the old value |
atomicCAS(addr, cmp, v) | if *addr == cmp then *addr = v | the old value |
atomicMin(addr, v) | *addr = min(*addr, v) | the old value |
atomicMax(addr, v) | *addr = max(*addr, v) | the old value |
atomicAnd(addr, v) | *addr &= v | the old value |
atomicOr(addr, v) | *addr |= v | the old value |
atomicXor(addr, v) | *addr ^= v | the old value |
The Rust atomic types provide the same operations as methods: fetch_add, fetch_sub, swap,
compare_exchange, fetch_min, fetch_max, fetch_and, fetch_or and fetch_xor.
Atomic operations are correct, but they have a cost. Since operations on the same address are performed one at a time, many threads that update 1 location must wait for each other, and the waiting time grows with the number of threads. The next section measures this cost.
5.5.2 A histogram
A histogram counts how many times each value occurs in a data set. A byte has 256 possible
values, so a histogram of bytes has 256 counters, called bins. In the direct kernel, shown in
listing 5.6, we give each thread a set of bytes, and we let the thread add 1 to the bin of each
byte with atomicAdd.
Listing 5.6 A histogram with global bins.
mod kernels {
// ...
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn hist_global(data: &[u8], bins: &[DeviceAtomicU32]) {
let stride = (thread::gridDim_x() * thread::blockDim_x()) as usize;
let mut i = thread::index_1d().get();
while i < data.len() {
bins[data[i] as usize].fetch_add(1, AtomicOrdering::Relaxed);
i += stride;
}
}
// ...
}// 2. A histogram of bytes: 256 bins, 1 per byte value.
__global__ void histGlobal(const unsigned char* data, int n, unsigned* bins)
{
int stride = gridDim.x * blockDim.x;
for (int i = blockIdx.x * blockDim.x + threadIdx.x; i < n; i += stride) {
atomicAdd(&bins[data[i]], 1u);
}
}
The launch uses 1,024 blocks of 256 threads, 262,144 threads in total, for 67,108,864 bytes, so
each thread processes 256 bytes. The loop advances by stride, the total number of threads in the
grid. This pattern is called a grid-stride loop. In every iteration, neighboring threads read
neighboring bytes.
Every one of the 67,108,864 additions targets 1 of only 256 addresses in global memory. We can reduce this contention with privatization. We give each block its own 256 bins in shared memory, where atomic operations are fast and only the threads of that block compete for each bin. At the end, we add each block’s totals to the global bins once (figure 5.6).
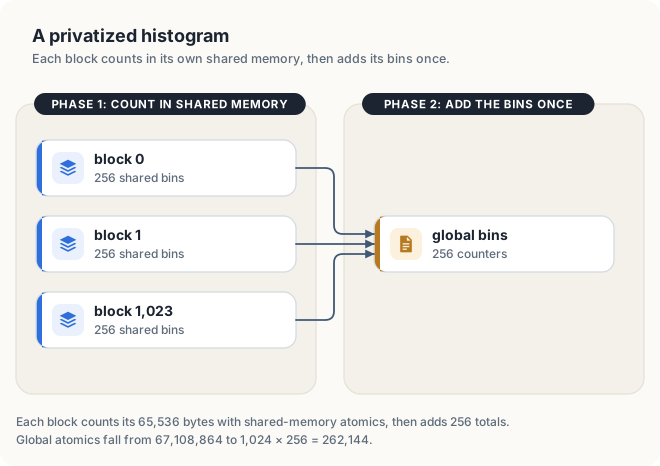
Listing 5.7 A histogram with shared bins.
mod kernels {
// ...
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn hist_shared(data: &[u8], bins: &[DeviceAtomicU32]) {
static mut LOCAL: SharedArray<u32, 256> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
// SAFETY: each thread zeroes only its own bin, before the barrier.
unsafe { LOCAL[tid] = 0 };
thread::sync_threads();
let stride = (thread::gridDim_x() * thread::blockDim_x()) as usize;
let mut i = thread::index_1d().get();
while i < data.len() {
// SAFETY: between the 2 barriers every access to LOCAL is atomic.
let bin = unsafe {
let base = (*&raw mut LOCAL).as_mut_ptr();
BlockAtomicU32::from_ptr(base.add(data[i] as usize))
};
bin.fetch_add(1, AtomicOrdering::Relaxed);
i += stride;
}
thread::sync_threads();
// SAFETY: after the barrier no thread writes LOCAL again.
let local = unsafe { LOCAL[tid] };
bins[tid].fetch_add(local, AtomicOrdering::Relaxed);
}
// ...
}__global__ void histShared(const unsigned char* data, int n, unsigned* bins)
{
__shared__ unsigned local[256];
local[threadIdx.x] = 0;
__syncthreads();
int stride = gridDim.x * blockDim.x;
for (int i = blockIdx.x * blockDim.x + threadIdx.x; i < n; i += stride) {
atomicAdd(&local[data[i]], 1u);
}
__syncthreads();
atomicAdd(&bins[threadIdx.x], local[threadIdx.x]);
}
We split the kernel into 3 phases, separated by 2 barriers. In the first phase, we let each thread
set one bin of local to 0. The first barrier ensures that every bin is 0 before any thread counts into it. In
the second phase, we let the threads count their bytes into local. The second barrier ensures that all
counting has finished before the third phase, in which thread \(k\) adds bin \(k\) to the
global bins. Since the block has 256 threads and there are 256 bins, each thread handles exactly
1 bin in the first and third phases.
The Rust versions have the same structure. In the shared version, the bins are held in a
SharedArray, and every access to it is unsafe. The compiler cannot see the barriers that make
these accesses correct, so each unsafe block carries a SAFETY comment that states the reason.
BlockAtomicU32::from_ptr treats 1 shared bin as an atomic with block scope, which is sufficient
for a counter in shared memory. We ran each kernel on 2 inputs: random bytes, which are spread
over all 256 bins, and bytes that all have the value 7, so that every addition targets the same
bin.
histogram of 64 MiB, average of 10 runs
random bytes global bins 33.40 ms total 67108864
random bytes shared bins 5.19 ms total 67108864
all 7 global bins 134.65 ms total 67108864
all 7 shared bins 4.84 ms total 67108864
$ cargo oxide run
histogram of 64 MiB, average of 10 runs
random bytes global bins 35.54 ms total 67108864
random bytes shared bins 4.05 ms total 67108864
all 7 global bins 133.65 ms total 67108864
all 7 shared bins 4.04 ms total 67108864
Every total is 67,108,864, 1 count per byte, so no update was lost. The versions differ in time (figure 5.7). With global bins, the bytes that are all 7 took 134.65 / 33.40 = 4 times as long as the random bytes, because all requests waited for the same address. The shared bins were 6 times as fast as the global bins on random bytes, and 28 times as fast on the bytes that are all 7. On the second GPU, the global version took 21 ms and 51 ms and the shared version 0.5 ms to 1.3 ms, 16 to 109 times less.
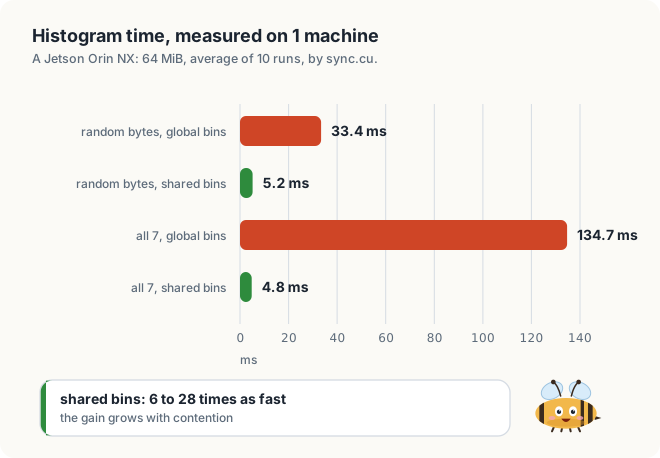
How many atomic operations on global memory does each histogram make for 64 MiB, with 1,024 blocks?
The global version makes 1 per byte: 67,108,864. The shared version makes 1 per bin per block: 1,024 × 256 = 262,144, which is 256 times fewer. Its other 67,108,864 atomic operations are on shared memory, inside each block.
5.5.3 Compare-and-swap
atomicCAS(addr, cmp, v) writes v only if the location still holds cmp, and it returns the
value it found. With this operation, we can make any update atomic. We read the old value, compute the new
value, and attempt to swap it in. If another thread changed the location
in the meantime, the swap fails, and we try again with the value that atomicCAS returned. The same operation can be used to build a lock. However, a lock makes threads wait for
each other on a machine designed to keep all of them busy, and a warp whose threads spin on 1 lock
can stop making progress. Privatization, partitioning the data, and plain atomic operations are
almost always faster.
5.6 Floating-point non-determinism
Floating-point addition rounds every result to the nearest representable number, so the result of
a sum depends on the order of the additions. A float has 24 bits of precision, and near
108 the representable numbers are 8 apart. Adding 1 to 108 therefore gives
108, so (108 + 1) − 108 = 0, while
(108 − 108) + 1 = 1.
An atomicAdd on a float performs the additions in the order in which the threads arrive, and
that order changes from run to run. Listing 5.8 sums 1,048,576 values with 1 atomic operation per
value.
Listing 5.8 A float sum by atomics.
mod kernels {
// ...
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_atomic(values: &[f32], total: &[DeviceAtomicF32]) {
let i = thread::index_1d().get();
if i < values.len() {
total[0].fetch_add(values[i], AtomicOrdering::Relaxed);
}
}
}// 5. A float sum by atomicAdd, in whatever order the threads arrive.
__global__ void sumAtomic(const float* in, int n, float* total)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
atomicAdd(total, in[i]);
}
}
sum of 1,048,576 floats by atomicAdd (exact: 7851.7077)
run 1 7849.5161
run 2 7849.4971
run 3 7849.4990
run 4 7849.5288
The 4 runs give 4 different results, and all of them are about 2.2 below the exact sum. Both
effects are caused by rounding. Near 7,850, representable float values are
2−11 ≈ 0.00049 apart, so each of the 1,048,576 additions rounds the running total, and
the small rounding errors accumulate. The runs differ from each other because the threads added
their values in a different order each time, and the rounding errors therefore differ.
For most programs this variation is acceptable. Programs that need the same bits on every run, for example to compare results across software versions or to reproduce a training run, must add in a fixed order. The tree sum of section 5.3 always adds the same pairs, so it gives the same result on every run. In Chapter 8, we develop fast sums of this kind.
5.7 Choosing a synchronization method
When the threads of a kernel share memory, the answers to 4 questions determine what the kernel needs:
| Question | If yes |
|---|---|
| Do 2 threads write the same location? | use an atomic, or give each thread its own location |
| Does a thread read what another thread of its block wrote? | put a __syncthreads() between the write and the read, reached by every thread |
| Does a thread read what another block wrote? | split the work into 2 launches, or use atomics with release and acquire |
| Must the result be the same bits on every run? | add in a fixed order, not with floating-point atomics |
Each method in the table imposes an order on 2 accesses that had none. The same reasoning can be
used to find a race. We identify the shared location, list the threads that write it and the
threads that read it, and determine what orders their accesses. If nothing does, the program
contains a race, even if every test so far has passed. The racecheck tool of Compute Sanitizer
(Chapter 25) detects unordered accesses to shared memory automatically.
5.8 The complete programs
Listing 5.9 The complete programs. code/oxide/ch05_sync/src/main.rs code/ch05_sync/sync.cu
//! Chapter 5 in Rust: an atomic counter, 2 histograms, a block sum with and without
//! barriers, a branch on alternate lanes or warps, and a float sum by atomics.
//!
//! cargo oxide run
use std::sync::Arc;
use std::time::Instant;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, DriverError, LaunchConfig1D};
use cuda_device::atomic::{AtomicOrdering, BlockAtomicU32, DeviceAtomicF32, DeviceAtomicU32};
use cuda_device::{DisjointSlice, SharedArray, cuda_module, device, kernel, launch_contract};
use cuda_device::thread;
#[cuda_module]
mod kernels {
use super::*;
// A lost update on purpose. The load and the store are 2 separate operations,
// so another thread can store between them, exactly like the plain C++ add.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn count_racy(counter: &[DeviceAtomicU32]) {
let seen = counter[0].load(AtomicOrdering::Relaxed);
counter[0].store(seen + 1, AtomicOrdering::Relaxed);
}
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn count(counter: &[DeviceAtomicU32]) {
counter[0].fetch_add(1, AtomicOrdering::Relaxed);
}
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn hist_global(data: &[u8], bins: &[DeviceAtomicU32]) {
let stride = (thread::gridDim_x() * thread::blockDim_x()) as usize;
let mut i = thread::index_1d().get();
while i < data.len() {
bins[data[i] as usize].fetch_add(1, AtomicOrdering::Relaxed);
i += stride;
}
}
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn hist_shared(data: &[u8], bins: &[DeviceAtomicU32]) {
static mut LOCAL: SharedArray<u32, 256> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
// SAFETY: each thread zeroes only its own bin, before the barrier.
unsafe { LOCAL[tid] = 0 };
thread::sync_threads();
let stride = (thread::gridDim_x() * thread::blockDim_x()) as usize;
let mut i = thread::index_1d().get();
while i < data.len() {
// SAFETY: between the 2 barriers every access to LOCAL is atomic.
let bin = unsafe {
let base = (*&raw mut LOCAL).as_mut_ptr();
BlockAtomicU32::from_ptr(base.add(data[i] as usize))
};
bin.fetch_add(1, AtomicOrdering::Relaxed);
i += stride;
}
thread::sync_threads();
// SAFETY: after the barrier no thread writes LOCAL again.
let local = unsafe { LOCAL[tid] };
bins[tid].fetch_add(local, AtomicOrdering::Relaxed);
}
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn block_sum(input: &[f32], mut out: DisjointSlice<f32>, barrier: bool) {
static mut S: SharedArray<f32, 256> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
let block = thread::blockIdx_x() as usize;
// SAFETY: each thread writes only its own element.
unsafe { S[tid] = input[block * 256 + tid] };
if barrier {
thread::sync_threads();
}
let mut stride = 128;
while stride > 0 {
if tid < stride {
// SAFETY: true only with the barriers. Thread tid alone writes S[tid] here,
// and S[tid + stride] was written before the last barrier.
unsafe { S[tid] += S[tid + stride] };
}
if barrier {
thread::sync_threads();
}
stride /= 2;
}
if tid == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *out.get_unchecked_mut(block) = S[0] };
}
}
/// The loop of the odd threads: 64 steps of v = sin(v) + 1.
#[device]
fn sin_loop(mut v: f32) -> f32 {
let mut k = 0;
#[unroll]
while k < 64 {
v = v.sin() + 1.0;
k += 1;
}
v
}
/// The loop of the even threads: 64 steps of v = sqrt(v) / 2 + 1 / 4.
#[device]
fn sqrt_loop(mut v: f32) -> f32 {
let mut k = 0;
#[unroll]
while k < 64 {
v = v.sqrt() * 0.5 + 0.25;
k += 1;
}
v
}
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn branches(mut x: DisjointSlice<f32>, by_warp: bool) {
let tid = thread::threadIdx_x();
let odd = if by_warp { (tid / 32) % 2 == 1 } else { tid % 2 == 1 };
let Some(x_i) = x.get_mut(thread::index_1d()) else {
return;
};
let v = *x_i;
*x_i = if odd { sin_loop(v) } else { sqrt_loop(v) };
}
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_atomic(values: &[f32], total: &[DeviceAtomicF32]) {
let i = thread::index_1d().get();
if i < values.len() {
total[0].fetch_add(values[i], AtomicOrdering::Relaxed);
}
}
}
/// Bytes from a small linear congruential generator, so the run needs no extra crate.
fn random_bytes(n: usize) -> Vec<u8> {
let mut state: u32 = 1;
(0..n)
.map(|_| {
state = state.wrapping_mul(1_664_525).wrapping_add(1_013_904_223);
(state >> 24) as u8
})
.collect()
}
/// `n` zeroed counters that kernels update with atomic operations.
fn atomic_u32(
stream: &Arc<CudaStream>,
n: usize,
) -> Result<DeviceBuffer<DeviceAtomicU32>, DriverError> {
Ok(DeviceBuffer::<u32>::zeroed(stream, n)?.cast_elem::<DeviceAtomicU32>())
}
fn main() -> Result<(), Box<dyn std::error::Error>> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
// 1. 1,048,576 threads each add 1 to 1 counter, with a race and with an atomic.
let grid = LaunchConfig1D::new(4096, 256, 0);
let racy = atomic_u32(&stream, 1)?;
let launch = module.prepare_count_racy(grid)?;
module.count_racy(&stream, &launch, &racy)?;
let lost = racy.cast_elem::<u32>().to_host_vec(&stream)?;
let counter = atomic_u32(&stream, 1)?;
let launch = module.prepare_count(grid)?;
module.count(&stream, &launch, &counter)?;
let result = counter.cast_elem::<u32>().to_host_vec(&stream)?;
println!("1,048,576 threads each add 1 to 1 counter");
println!(" load, store counter = {}", lost[0]);
println!(" fetch_add counter = {}", result[0]);
// 2. A histogram of 64 MiB of bytes, with global bins and with shared bins.
let n = 64 << 20;
let inputs = [("random bytes", random_bytes(n)), ("all 7", vec![7u8; n])];
let global = module.prepare_hist_global(LaunchConfig1D::new(1024, 256, 0))?;
let shared = module.prepare_hist_shared(LaunchConfig1D::new(1024, 256, 0))?;
println!("histogram of 64 MiB, average of 10 runs");
for (name, bytes) in &inputs {
let data = DeviceBuffer::from_host(&stream, bytes)?;
for kind in ["global bins", "shared bins"] {
let mut ms = 0.0;
let mut total = 0;
for run in 0..11 {
let bins = atomic_u32(&stream, 256)?;
stream.synchronize()?;
let start = Instant::now();
if kind == "global bins" {
module.hist_global(&stream, &global, &data, &bins)?;
} else {
module.hist_shared(&stream, &shared, &data, &bins)?;
}
stream.synchronize()?;
if run > 0 {
ms += start.elapsed().as_secs_f64() * 1e3;
}
let counts = bins.cast_elem::<u32>().to_host_vec(&stream)?;
total = counts.iter().map(|&c| c as u64).sum();
}
println!(" {name:<12} {kind:<13} {:7.2} ms total {total}", ms / 10.0);
}
}
// 3. 4,096 blocks each sum 256 ones in shared memory, with and without barriers.
let blocks = 4096;
let ones = DeviceBuffer::from_host(&stream, &vec![1.0f32; blocks * 256])?;
let mut sums = DeviceBuffer::<f32>::zeroed(&stream, blocks)?;
let block_sum = module.prepare_block_sum(LaunchConfig1D::new(blocks as u32, 256, 0))?;
println!("4,096 blocks each sum 256 ones; the right answer is 256");
for barrier in [true, false] {
module.block_sum(&stream, &block_sum, &ones, &mut sums, barrier)?;
let s = sums.to_host_vec(&stream)?;
let wrong = s.iter().filter(|&&sum| sum != 256.0).count();
let name = if barrier { "with barriers" } else { "without barriers" };
println!(" {name:<18} wrong sums: {wrong:4} of {blocks} (block 0: {})", s[0]);
}
// 4. Half the threads take each branch: alternate lanes, or alternate warps.
let n = 16 << 20;
let mut x = DeviceBuffer::<f32>::zeroed(&stream, n)?;
let branch = module.prepare_branches(LaunchConfig1D::new((n / 256) as u32, 256, 0))?;
println!("branch on every other thread, {n} threads, average of 10 runs");
for by_warp in [true, false] {
module.branches(&stream, &branch, &mut x, by_warp)?; // warm up
stream.synchronize()?;
let start = Instant::now();
for _ in 0..10 {
module.branches(&stream, &branch, &mut x, by_warp)?;
}
stream.synchronize()?;
let ms = start.elapsed().as_secs_f64() * 1e3 / 10.0;
let name = if by_warp { "whole warps agree" } else { "lanes alternate" };
println!(" {name:<22} {ms:6.2} ms");
}
// 5. A float sum by fetch_add, in whatever order the threads arrive.
let values: Vec<f32> = (0..1 << 20).map(|i| 1.0 / (1 + i % 1000) as f32).collect();
let exact: f64 = values.iter().map(|&v| v as f64).sum();
let values_dev = DeviceBuffer::from_host(&stream, &values)?;
let sum = module.prepare_sum_atomic(LaunchConfig1D::new(4096, 256, 0))?;
println!("sum of 1,048,576 floats by fetch_add (exact: {exact:.4})");
for run in 1..=4 {
let total = DeviceBuffer::<f32>::zeroed(&stream, 1)?.cast_elem::<DeviceAtomicF32>();
module.sum_atomic(&stream, &sum, &values_dev, &total)?;
let result = total.cast_elem::<f32>().to_host_vec(&stream)?;
println!(" run {run} {:.4}", result[0]);
}
Ok(())
}// Chapter 5: races, atomics, barriers and divergence, measured on this GPU.
// Build: nvcc -arch=native sync.cu -o sync
#include <chrono>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cuda_runtime.h>
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// 1. Every thread adds 1 to the same counter.
__global__ void countRacy(unsigned* counter)
{
    *counter = *counter + 1;
}

__global__ void countAtomic(unsigned* counter)
{
    atomicAdd(counter, 1u);
}
// 2. A histogram of bytes: 256 bins, 1 per byte value.
__global__ void histGlobal(const unsigned char* data, int n, unsigned* bins)
{
int stride = gridDim.x * blockDim.x;
for (int i = blockIdx.x * blockDim.x + threadIdx.x; i < n; i += stride) {
atomicAdd(&bins[data[i]], 1u);
}
}
__global__ void histShared(const unsigned char* data, int n, unsigned* bins)
{
__shared__ unsigned local[256];
local[threadIdx.x] = 0;
__syncthreads();
int stride = gridDim.x * blockDim.x;
for (int i = blockIdx.x * blockDim.x + threadIdx.x; i < n; i += stride) {
atomicAdd(&local[data[i]], 1u);
}
__syncthreads();
atomicAdd(&bins[threadIdx.x], local[threadIdx.x]);
}
// 3. Each block sums its 256 values in shared memory, with or without barriers.
__global__ void blockSum(const float* in, float* out, bool barrier)
{
__shared__ float s[256];
s[threadIdx.x] = in[blockIdx.x * 256 + threadIdx.x];
if (barrier) __syncthreads();
for (int stride = 128; stride > 0; stride /= 2) {
if (threadIdx.x < stride) {
s[threadIdx.x] += s[threadIdx.x + stride];
}
if (barrier) __syncthreads();
}
if (threadIdx.x == 0) {
out[blockIdx.x] = s[0];
}
}
// 4. Half the threads take each branch: alternate lanes, or alternate warps.
__global__ void branches(float* x, int n, bool byWarp)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i >= n) return;
bool odd = byWarp ? (threadIdx.x / 32) % 2 : threadIdx.x % 2;
float v = x[i];
if (odd) {
for (int k = 0; k < 64; ++k) v = sinf(v) + 1.0f;
} else {
for (int k = 0; k < 64; ++k) v = sqrtf(v) * 0.5f + 0.25f;
}
x[i] = v;
}
// 5. A float sum by atomicAdd, in whatever order the threads arrive.
__global__ void sumAtomic(const float* in, int n, float* total)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
atomicAdd(total, in[i]);
}
}
void race()
{
    unsigned* counter;
    check(cudaMalloc(&counter, sizeof(unsigned)));
    const int blocks = 4096, threads = 256;

    std::printf("1,048,576 threads each add 1 to 1 counter\n");
    for (int atomic = 0; atomic < 2; ++atomic) {
        unsigned result;
        check(cudaMemset(counter, 0, sizeof(unsigned)));

        if (atomic) {
            countAtomic<<<blocks, threads>>>(counter);
        } else {
            countRacy<<<blocks, threads>>>(counter);
        }

        check(cudaMemcpy(&result, counter, sizeof(unsigned), cudaMemcpyDeviceToHost));
        std::printf("  %-12s counter = %u\n", atomic ? "atomicAdd" : "plain add", result);
    }

    check(cudaFree(counter));
}
void histograms()
{
const int n = 64 << 20; // 64 MiB of bytes
std::vector<unsigned char> random(n), same(n, 7);
for (int i = 0; i < n; ++i) {
random[i] = std::rand() & 255;
}
unsigned char* data;
unsigned* bins;
check(cudaMalloc(&data, n));
check(cudaMalloc(&bins, 256 * sizeof(unsigned)));
std::printf("histogram of 64 MiB, average of 10 runs\n");
for (const auto* input : {&random, &same}) {
check(cudaMemcpy(data, input->data(), n, cudaMemcpyHostToDevice));
for (int shared = 0; shared < 2; ++shared) {
histGlobal<<<1024, 256>>>(data, n, bins); // warm up
check(cudaDeviceSynchronize());
double t0 = nowMs();
for (int r = 0; r < 10; ++r) {
check(cudaMemset(bins, 0, 256 * sizeof(unsigned)));
if (shared) {
histShared<<<1024, 256>>>(data, n, bins);
} else {
histGlobal<<<1024, 256>>>(data, n, bins);
}
}
check(cudaDeviceSynchronize());
double ms = (nowMs() - t0) / 10;
unsigned h[256];
check(cudaMemcpy(h, bins, sizeof(h), cudaMemcpyDeviceToHost));
unsigned long long total = 0;
for (unsigned c : h) total += c;
const char* name = input == &random ? "random bytes" : "all 7";
const char* kind = shared ? "shared bins" : "global bins";
std::printf(" %-12s %-13s %7.2f ms total %llu\n", name, kind, ms, total);
}
}
check(cudaFree(data));
check(cudaFree(bins));
}
void barriers()
{
const int blocks = 4096;
std::vector<float> ones(blocks * 256, 1.0f), sums(blocks);
float *in, *out;
check(cudaMalloc(&in, ones.size() * sizeof(float)));
check(cudaMalloc(&out, blocks * sizeof(float)));
check(cudaMemcpy(in, ones.data(), ones.size() * sizeof(float), cudaMemcpyHostToDevice));
std::printf("4,096 blocks each sum 256 ones; the right answer is 256\n");
for (int barrier = 1; barrier >= 0; --barrier) {
blockSum<<<blocks, 256>>>(in, out, barrier);
check(cudaMemcpy(sums.data(), out, blocks * sizeof(float), cudaMemcpyDeviceToHost));
int wrong = 0;
for (float s : sums) wrong += (s != 256.0f);
std::printf(" %-18s wrong sums: %4d of %d (block 0: %g)\n",
barrier ? "with barriers" : "without barriers", wrong, blocks, sums[0]);
}
check(cudaFree(in));
check(cudaFree(out));
}
void divergence()
{
const int n = 16 << 20;
float* x;
check(cudaMalloc(&x, n * sizeof(float)));
check(cudaMemset(x, 0, n * sizeof(float)));
std::printf("branch on every other thread, %d threads, average of 10 runs\n", n);
for (int byWarp = 1; byWarp >= 0; --byWarp) {
branches<<<n / 256, 256>>>(x, n, byWarp); // warm up
check(cudaDeviceSynchronize());
double t0 = nowMs();
for (int r = 0; r < 10; ++r) {
branches<<<n / 256, 256>>>(x, n, byWarp);
}
check(cudaDeviceSynchronize());
const char* name = byWarp ? "whole warps agree" : "lanes alternate";
std::printf(" %-22s %6.2f ms\n", name, (nowMs() - t0) / 10);
}
check(cudaFree(x));
}
void floatSums()
{
const int n = 1 << 20;
std::vector<float> values(n);
double exact = 0;
for (int i = 0; i < n; ++i) {
values[i] = 1.0f / (1 + i % 1000);
exact += values[i];
}
float *in, *total;
check(cudaMalloc(&in, n * sizeof(float)));
check(cudaMalloc(&total, sizeof(float)));
check(cudaMemcpy(in, values.data(), n * sizeof(float), cudaMemcpyHostToDevice));
std::printf("sum of 1,048,576 floats by atomicAdd (exact: %.4f)\n", exact);
for (int run = 1; run <= 4; ++run) {
float result;
check(cudaMemset(total, 0, sizeof(float)));
sumAtomic<<<n / 256, 256>>>(in, n, total);
check(cudaMemcpy(&result, total, sizeof(float), cudaMemcpyDeviceToHost));
std::printf(" run %d %.4f\n", run, result);
}
check(cudaFree(in));
check(cudaFree(total));
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %d SMs\n", prop.name, prop.multiProcessorCount);
race();
histograms();
barriers();
divergence();
floatSums();
}
Common mistakes
- Updating a shared counter with
+=. UseatomicAdd, or in Rust an atomic type. - A
__syncthreads()that some threads skip. Every thread of the block must reach every barrier, the same number of times, or the block hangs. - Reading another thread’s shared-memory value without a barrier. The value may not have been written yet, and the result is correct on some runs and wrong on others.
- Expecting
__syncthreads()to synchronize blocks. It applies to 1 block. Use 2 launches. - Many threads updating 1 global location. The atomic operations are serialized. Privatize the counts in shared memory and add the totals once.
- Expecting a floating-point atomic sum to repeat exactly. The order of the additions changes, so the last digits change.
- Branching on alternate threads. Branch on whole warps where the data allows it.
Summary
- A race condition consists of 2 accesses to 1 location, at least one of them a write, with nothing ordering them. 1,048,576 plain additions to 1 counter kept 505 and 192 of the additions on the 2 GPUs, and no error was reported.
- Safe Rust cannot express that race, because memory that many threads update must have an atomic type.
- A warp executes every path that its threads take. Branching on alternate lanes doubled the time of the same work.
__syncthreads()makes every thread of a block wait for the others and makes their writes visible to the block. Without it, 2,450 of 4,096 block sums were wrong.- Atomic operations make a read-modify-write indivisible, at the cost of serializing the operations on a busy address. A privatized histogram was 6 to 28 times as fast as one with global atomic operations.
- Floating-point atomic operations add in a different order on each run, so their sums differ in the last digits.
Chapter 6 moves from the threads of a kernel to streams of work on the GPU, and overlaps copies with kernels through asynchronous execution.
Exercises
- Explain why the guard
if (i < n)diverges in at most 1 warp of a grid. - Rewrite the branch
if (threadIdx.x % 2 == 0) {...} else {...}so that whole warps take each path while each path still covers half the threads. - The barrier in the hanging example of section 5.3.3 is inside an
if. Rewrite it so that every thread reaches the barrier exactly once. - A histogram has 1,024 bins instead of 256, with blocks of 256 threads. How must listing 5.7 change for the zeroing and the final addition?
- Use
atomicMaxto find the largest of 1,048,576intvalues. Why does this result, unlike the float sum, not change from run to run? - On the bytes that are all 7, why did shared bins become no slower than on random bytes, while global bins became 4 times slower?
- In Rust, try to write the racy counter with a
DisjointSlice<u32>. What prevents it?
Sources and further reading
- NVIDIA, CUDA C++ Programming Guide, “Synchronization Functions”, “Memory Fence Functions”, “Atomic Functions” and “SIMT Architecture”: https://docs.nvidia.com/cuda/cuda-c-programming-guide/
- NVIDIA, CUDA C++ Best Practices Guide, “Branching and Divergence”: https://docs.nvidia.com/cuda/cuda-c-best-practices-guide/
- NVIDIA, Compute Sanitizer, the
racechecktool: https://docs.nvidia.com/compute-sanitizer/ - NVlabs, cuda-oxide, the
cuda_device::atomicmodule, for scopes and orderings: https://github.com/NVlabs/cuda-oxide - D. Goldberg, “What Every Computer Scientist Should Know About Floating-Point Arithmetic”, ACM Computing Surveys 23(1), 1991.
Chapter 6: Streams, Events & Asynchronous Execution
A GPU contains more than one kind of execution unit. The streaming multiprocessors (SMs), described in Chapter 2, execute kernels. The copy engines, described in Chapter 4, transfer data between host memory and device memory without using the SMs. In the programs of the previous chapters, these units were used one at a time. The program copied its input to the device, launched a kernel, and copied the result back, and each operation started only after the previous one had finished. While a copy was in progress the SMs were idle, and while the kernel was running the copy engines were idle.
In this chapter, we study how a program can keep these units busy at the same time. The mechanism is asynchronous execution: a kernel launch or a copy is placed in a queue, called a stream, and the call returns before the work is done. When the data is divided into chunks and the chunks are distributed over 2 streams, a copy engine can transfer 1 chunk while the SMs process another and the second copy engine returns a third. We also use events to time work on the GPU’s own clock, and CUDA graphs to reduce the cost of launching many short kernels.
This chapter covers
- asynchronous launches and copies, and the work the host can do while the GPU runs
- streams: ordered queues of GPU work, and the overlap of work in different streams
- the default stream and the synchronization it adds between streams
- events, which time work on the GPU’s own clock
- a pipeline of chunks on 2 streams, 43% faster on a Jetson Orin NX
- why overlap gains less when the kernel dominates or the memory is shared
- CUDA graphs, which submit 1,000 launches with 1 call
The code of the chapter is in
code/ch06_streams/
for C++ and in
code/oxide/ch06_streams/
for Rust.
6.1 Serial execution of copies and kernels
The programs of this chapter process 128 MiB of floats in 3 stages. The first stage copies the input to the device, the second runs a kernel that performs some arithmetic on every element, and the third copies the result back to the host. Listing 6.1 shows the kernel. Its loop of 256 iterations has no purpose other than to make the kernel take about as long as its copies; with a much shorter kernel, overlapping the stages would make little difference.
Listing 6.1 The kernel of the chapter. code/oxide/ch06_streams/src/main.rs code/ch06_streams/streams.cu
mod kernels {
    // ...
    /// Some arithmetic per element, so that a kernel takes about as long as its copies.
    #[kernel]
    #[launch_contract(domain = 1, block = (256, 1, 1))]
    pub fn work(mut x: DisjointSlice<f32>, steps: u32) {
        if let Some(v) = x.get_mut(thread::index_1d()) {
            let mut a = *v;
            for _ in 0..steps {
                a = a * 0.999 + 0.5;
            }
            *v = a;
        }
    }
    // ...
}
// Some arithmetic per element, so that a kernel takes about as long as its copies.
__global__ void work(float* x, int n, int steps)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i >= n) return;
float v = x[i];
for (int k = 0; k < steps; ++k) {
v = fmaf(v, 0.999f, 0.5f);
}
x[i] = v;
}
When the 3 stages are timed separately on a Jetson Orin NX, they take the following times:
copy in, kernel, copy out over 128 MiB
copy in 4.29 ms
kernel 10.39 ms
copy out 4.30 ms
If the stages run one after another, the computation takes about 4.3 + 10.4 + 4.3 = 19 ms. Each unit of the GPU is busy for only part of that time: the copy engine that moves data to the device works for 4.3 ms of the 19 ms, and the SMs work for 10.4 ms. If the 3 stages could operate at the same time on different parts of the data, the total time would approach the time of the longest stage, 10.4 ms. For that, the program must be able to give the GPU new work without waiting for earlier work to finish. Asynchronous launches and streams, the subject of section 6.2, provide this ability.
6.2 Asynchronous launches and streams
6.2.1 Asynchronous kernel launches
A call is said to be synchronous if it returns only after its work is done, and asynchronous if it returns as soon as the work has been queued. Kernel launches have been asynchronous in every program since Chapter 3. The program of this chapter measures the effect directly, with a method that section 6.4 explains:
a launch of a kernel over 128 MiB
launch call returned after 0.075 ms
kernel finished after 12.451 ms
The launch call returned after 0.075 ms, whereas the kernel finished 12 ms later. Between these 2 moments the host thread was free, as figure 6.1 shows. It could prepare the next input or launch more work, and it needs to wait only when it requires a result from the GPU.
6.2.2 Streams
Work that has been queued must be held somewhere until the GPU executes it. A stream is an ordered queue of GPU operations, such as kernel launches and memory copies. The GPU executes the operations of a stream in the order in which they were queued, so operations in the same stream never overlap: a copy queued after a kernel starts only when the kernel has finished. Operations in different streams, on the other hand, have no ordering constraint between them, and the GPU may execute them at the same time (figure 6.2). Animation 1 shows a host thread placing work in a stream and the GPU executing it in order.
In C++, cudaStreamCreate(&s) creates a stream. A kernel is launched into a stream by passing
the stream as the 4th launch parameter between the angle brackets,
kernel<<<grid, block, 0, s>>>(...), and cudaMemcpyAsync(dst, src, bytes, kind, s) places a
copy in it. In Rust, ctx.new_stream()? creates a stream, and every launch and copy takes the
stream as its first argument. Note that an asynchronous copy requires pinned host memory, which
Chapter 4 introduced. The copy engine reads the host memory after the call has returned, so the
operating system must not move the pages of that memory while the copy is in progress.
6.3 The default stream and implicit synchronization
A launch or a copy that does not name a stream is placed in the default stream. In its
original form, which is still the default behavior in C++, the default stream synchronizes with
every other stream of the device. An operation in the default stream waits for all earlier work in
all streams, and work queued later in other streams waits for it. Therefore, a single launch or
cudaMemcpy without a stream can serialize a program that was designed to overlap its operations.
There are two ways to avoid this behavior:
- Name a stream in every launch and copy. The dependencies between operations are then visible in the code, at the place where the work is queued.
- Compile with
--default-stream per-thread. Each host thread then has its own default stream, which does not synchronize with the streams of other threads.
Streams created with cudaStreamCreateWithFlags(&s, cudaStreamNonBlocking) do not synchronize
with the default stream at all.
6.4 CUDA events
An event is a marker placed in a stream. When the GPU reaches the marker, it records the time on its own clock. By recording 1 event before a kernel and another after it, we can measure the execution time of the kernel on the GPU. The measurement excludes the time the host takes to launch the kernel and the time it takes to notice that the kernel has finished (figure 6.3).
Listing 6.2 An asynchronous launch, timed with events.
fn main() -> Result<(), Box<dyn std::error::Error>> {
// ...
// 1. A launch returns at once; events time the kernel on the GPU.
let stream = &streams[0];
let launch = module.prepare_work(LaunchConfig1D::new((N / 256) as u32, 256, 0))?;
let device = &mut whole[0].device;
let t0 = Instant::now();
let start = stream.record_event(Some(TIMING))?;
module.work(stream, &launch, device, STEPS)?;
let stop = stream.record_event(Some(TIMING))?;
let launched = t0.elapsed().as_secs_f64() * 1e3;
stop.synchronize()?;
let finished = t0.elapsed().as_secs_f64() * 1e3;
println!("a launch of a kernel over 128 MiB");
println!(" launch call returned after {launched:8.3} ms");
println!(" kernel finished after {finished:8.3} ms");
println!(" kernel time by events {:8.3} ms", start.elapsed_ms(&stop)?);
// ...
}// 1. A launch returns before the kernel finishes; events time the kernel on the GPU.
void asyncLaunch(float* d, int n, int steps)
{
cudaEvent_t start, stop;
check(cudaEventCreate(&start));
check(cudaEventCreate(&stop));
work<<<(n + 255) / 256, 256>>>(d, n, steps); // warm up
check(cudaDeviceSynchronize());
double t0 = nowMs();
check(cudaEventRecord(start));
work<<<(n + 255) / 256, 256>>>(d, n, steps);
check(cudaEventRecord(stop));
double launched = nowMs() - t0;
check(cudaEventSynchronize(stop));
double finished = nowMs() - t0;
float gpuMs;
check(cudaEventElapsedTime(&gpuMs, start, stop));
std::printf("a launch of a kernel over %d MiB\n", int(n * sizeof(float) >> 20));
std::printf(" launch call returned after %8.3f ms\n", launched);
std::printf(" kernel finished after %8.3f ms\n", finished);
std::printf(" kernel time by events %8.3f ms\n", gpuMs);
check(cudaEventDestroy(start));
check(cudaEventDestroy(stop));
}
The call cudaEventRecord(e) places the marker in the stream, cudaEventSynchronize(e) makes
the host wait until the GPU has passed it, and cudaEventElapsedTime(&ms, start, stop) returns
the time between 2 markers in milliseconds. The Rust version follows the same steps.
stream.record_event(Some(TIMING))? creates an event that can record time and places it in the
stream, stop.synchronize()? waits for it, and start.elapsed_ms(&stop)? returns the time
between the 2 events.
a launch of a kernel over 128 MiB
launch call returned after 0.075 ms
kernel finished after 12.451 ms
kernel time by events 11.151 ms
The host observed the kernel finish after 12.45 ms, whereas the events measured 11.15 ms. The difference of about 1.3 ms is time spent outside the kernel: the GPU starting the kernel and signaling its completion, and the host thread noticing that signal. For timing work on the GPU, events therefore give the more accurate measurement.
6.5 A double-buffered pipeline
6.5.1 Dividing the data into chunks
To allow the units of the GPU to overlap, we divide the data into chunks and give each chunk its own 3 stages. Chunk \(c\) is placed in stream \(c \bmod 2\), so consecutive chunks alternate between 2 streams. Within a stream, the stages of a chunk remain in order. Between the streams, however, the copy of 1 chunk can proceed while the kernel of the previous chunk runs (figure 6.4). Keeping 2 chunks in flight in this way is commonly called double buffering.
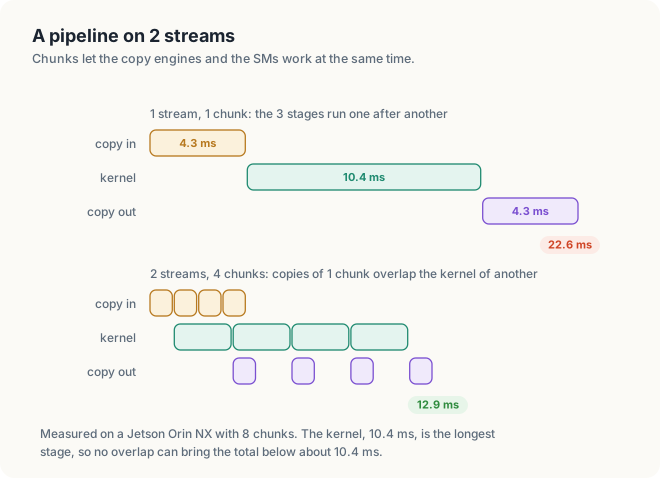
Listing 6.3 The pipeline.
/// 1 chunk of the data: its pinned host buffer and its device buffer.
struct Chunk {
host: PinnedHostBuffer<f32>,
device: DeviceBuffer<f32>,
}
/// Copy in, compute and copy out every chunk, chunk c on stream c % streams.len().
/// Returns the average of 5 runs, in milliseconds.
fn pipeline(
module: &kernels::LoadedModule,
streams: &[Arc<CudaStream>],
parts: &mut [Chunk],
) -> Result<f64, Box<dyn std::error::Error>> {
let len = parts[0].host.len();
let blocks = len.div_ceil(256) as u32;
let launch = module.prepare_work(LaunchConfig1D::new(blocks, 256, 0))?;
let start = Instant::now();
for _ in 0..5 {
for (c, part) in parts.iter_mut().enumerate() {
let stream = &streams[c % streams.len()];
// SAFETY: `part.host` is neither read, written nor dropped until every
// stream is synchronized below, after both copies have completed.
unsafe { part.device.copy_from_pinned_host_async(stream, &part.host)? };
module.work(stream, &launch, &mut part.device, STEPS)?;
unsafe { part.device.copy_to_pinned_host_async(stream, &mut part.host)? };
}
}
for stream in streams {
stream.synchronize()?;
}
Ok(start.elapsed().as_secs_f64() * 1e3 / 5.0)
}// 2. Copy in, compute, copy out: all at once on 1 stream, or in chunks on 2 streams.
void enqueue(float* host, float* d, int n, int steps, int chunks, cudaStream_t* streams)
{
int part = n / chunks;
size_t bytes = part * sizeof(float);
for (int c = 0; c < chunks; ++c) {
cudaStream_t s = streams[c % 2];
float* h = host + c * part;
float* g = d + c * part;
check(cudaMemcpyAsync(g, h, bytes, cudaMemcpyHostToDevice, s));
work<<<(part + 255) / 256, 256, 0, s>>>(g, part, steps);
check(cudaMemcpyAsync(h, g, bytes, cudaMemcpyDeviceToHost, s));
}
}
// Average time of 5 pipelines, in milliseconds.
double pipeline(float* host, float* d, int n, int steps, int chunks, cudaStream_t* streams)
{
check(cudaDeviceSynchronize());
double t0 = nowMs();
for (int r = 0; r < 5; ++r) {
enqueue(host, d, n, steps, chunks, streams);
}
check(cudaDeviceSynchronize());
return (nowMs() - t0) / 5;
}
The function enqueue only queues work. Each of the 3 calls in its loop returns immediately, so
the host queues every chunk of every stream before the first copy has finished. The function
pipeline runs the complete pipeline 5 times and divides the total time by 5. Animation 2 shows
the chunks passing through the 3 units of the GPU.
6.5.2 The pipeline in Rust
In the Rust version of Listing 6.3, each chunk owns its pinned host buffer and its device buffer. With this arrangement, the borrow checker can see which data each stream uses.
The asynchronous copies are unsafe for a reason that the borrow checker cannot see. A copy
continues after copy_from_pinned_host_async has returned, so the host buffer must remain alive
and unchanged until the GPU has finished with it. The borrow of part.host ends when the call
returns, but the GPU’s use of the buffer ends only at stream.synchronize(). The SAFETY comment
states why the program meets this requirement. No code touches the host buffers until every
stream has been synchronized.
6.5.3 Measured pipeline times
$ ./streams # on a Jetson Orin NX
copy in, kernel, copy out over 128 MiB
1 stream, 1 chunk 22.60 ms
2 streams, 8 chunks 12.93 ms
2 streams, 32 chunks 13.27 ms
$ ./streams # on a Jetson AGX Thor
copy in, kernel, copy out over 128 MiB
copy in 1.12 ms
kernel 3.05 ms
copy out 1.08 ms
1 stream, 1 chunk 5.21 ms
2 streams, 8 chunks 4.88 ms
2 streams, 32 chunks 4.51 ms
$ cargo oxide run # on a Jetson Orin NX
copy in, kernel, copy out over 128 MiB
1 stream, 1 chunk 20.07 ms
2 streams, 8 chunks 12.55 ms
On the Orin NX, 2 streams reduced the time from 22.6 ms to 12.9 ms, a reduction of 43% (figure 6.5). To judge how close this result is to the best possible, we can derive a simple bound. With \(k\) chunks, the longest stage runs from the start of the pipeline to its end. Each of the other stages contributes only the time it spends on 1 chunk: the copy of the first chunk before the first kernel can start, and the copy of the last chunk after the last kernel has finished. The total time is therefore approximately
\[ T_{\text{pipeline}} \approx T_{\text{longest}} + \frac{T_{\text{others}}}{k} \]
For 8 chunks, the bound is 10.4 + (4.3 + 4.3) / 8 ≈ 11.5 ms, which is close to the measured 12.9 ms. 32 chunks performed no better than 8. The bound for 8 chunks is already within 1 ms of the kernel’s time, and each additional chunk adds 3 more calls that the host must queue.
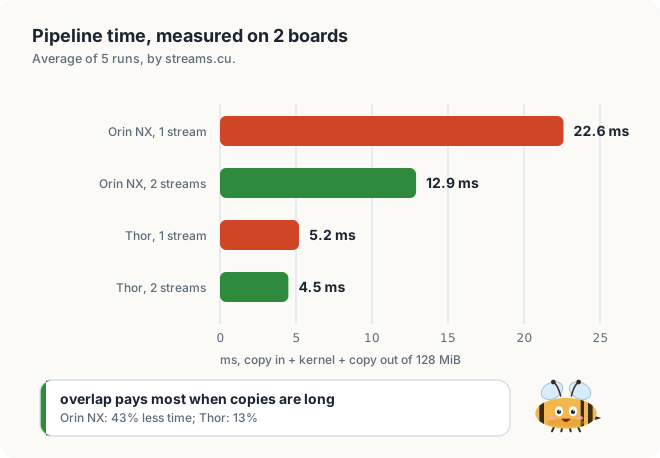
On the Thor, the gain was 13%, for two reasons. First, its kernel dominates: the kernel takes 3.05 ms, against 1.1 ms for each copy, so even perfect overlap could hide only the copies, about 2.2 ms of the 5.2 ms. Second, on an integrated GPU the copies and the kernel use the same memory, so a copy that runs during a kernel slows the kernel down. In Chapter 4, we saw a larger saving that is available on such a GPU: avoiding the copies altogether with zero-copy or unified memory.
Overlap hides the shorter stages behind the longest one; it cannot make the longest one shorter.
A pipeline has copy in 6 ms, kernel 4 ms and copy out 6 ms, on a GPU with 2 copy engines. What is the best time with 8 chunks?
The longest stage is a copy, which takes 6 ms. The bound gives 6 + (4 + 6) / 8 ≈ 7.3 ms, against 16 ms in 1 stream. When the copies dominate, they set the time, and the kernel is hidden behind them.
6.6 Stream priorities and concurrency limits
Not every pair of operations can overlap. A GPU has a fixed number of copy engines, which the
device property asyncEngineCount reports. With 2 copy engines, as on both boards used here, 1
copy to the device and 1 copy to the host can run at the same time, but 2 copies in the same
direction must take turns. Kernels in different streams can run at the same time only if the
first kernel leaves some SMs free. A kernel that fills the GPU, like the one in this chapter, runs
alone until its last blocks finish.
When operations compete for the SMs, stream priorities tell the scheduler which stream to serve first:
/// A stream for urgent work and a stream for bulk work, at the 2 ends of the range.
fn priorities(ctx: &Arc<CudaContext>) -> Result<(), DriverError> {
let range = ctx.stream_priority_range()?;
let urgent = ctx.new_stream_with_priority(range.greatest())?;
let bulk = ctx.new_stream_with_priority(range.least())?;
println!("stream priorities: urgent {}, bulk {}", urgent.priority()?, bulk.priority()?);
Ok(())
}int least, greatest;
cudaStream_t urgent, bulk;
cudaDeviceGetStreamPriorityRange(&least, &greatest);
cudaStreamCreateWithPriority(&urgent, cudaStreamNonBlocking, greatest);
cudaStreamCreateWithPriority(&bulk, cudaStreamNonBlocking, least);
The scheduler starts blocks from a high-priority stream before waiting blocks from a low-priority
stream. Latency-critical work, such as a small kernel whose result the host is waiting for, belongs
in the high-priority stream, and bulk work in the low-priority one. In Rust,
ctx.new_stream_with_priority(p)? creates such a stream, and ctx.stream_priority_range()?
returns the range of priorities.
6.7 CUDA graphs
Every kernel launch costs the host a few microseconds: the driver checks the arguments, writes a command, and submits it to the GPU. For a kernel that runs for 10 ms, this cost is negligible. For a program that launches thousands of short kernels, however, the launch cost can exceed the execution time of the kernels themselves.
A CUDA graph is a recorded set of GPU operations, such as kernels and copies, together with the
ordering between them. The program records the graph once and then launches the whole graph with a
single call, so the launch work is performed once for all of its operations. The simplest way to
record a graph is stream capture: between the calls cudaStreamBeginCapture and
cudaStreamEndCapture, operations queued in the stream are recorded instead of executed.
Listing 6.4 1,000 launches, one by one and as a graph.
/// 1,000 launches of an empty kernel: one by one, and replayed from a graph.
fn graphs(
module: &kernels::LoadedModule,
stream: &CudaStream,
) -> Result<(), Box<dyn std::error::Error>> {
let launches = 1000;
let launch = module.prepare_empty(LaunchConfig1D::new(1, 32, 0))?;
module.empty(stream, &launch)?;
stream.synchronize()?;
let t0 = Instant::now();
for _ in 0..launches {
module.empty(stream, &launch)?;
}
stream.synchronize()?;
let direct = t0.elapsed().as_secs_f64() * 1e3 / launches as f64;
let s = stream.cu_stream();
let mut graph = std::ptr::null_mut();
let mut exec = std::ptr::null_mut();
// SAFETY: `s` is a live stream, and no other thread queues work while it is captured.
unsafe { sys::cuStreamBeginCapture_v2(s, GLOBAL).result()? };
for _ in 0..launches {
module.empty(stream, &launch)?;
}
// SAFETY: `graph` and `exec` receive new handles, used only in this function.
unsafe {
sys::cuStreamEndCapture(s, &mut graph).result()?;
sys::cuGraphInstantiateWithFlags(&mut exec, graph, 0).result()?;
}
// SAFETY: `exec` is the graph instantiated above, and `s` is still live.
unsafe { sys::cuGraphLaunch(exec, s).result()? }; // warm up
stream.synchronize()?;
let t0 = Instant::now();
// SAFETY: `exec` is the graph instantiated above, and `s` is still live.
unsafe { sys::cuGraphLaunch(exec, s).result()? };
stream.synchronize()?;
let replay = t0.elapsed().as_secs_f64() * 1e3 / launches as f64;
let direct_us = direct * 1e3;
let replay_us = replay * 1e3;
println!("1,000 launches of an empty kernel, time per kernel");
println!(" launched one by one {direct_us:6.2} us");
println!(" replayed from a graph {replay_us:6.2} us");
// SAFETY: the stream is synchronized, so the GPU no longer uses either handle.
unsafe {
sys::cuGraphExecDestroy(exec).result()?;
sys::cuGraphDestroy(graph).result()?;
}
Ok(())
}// 3. 1,000 launches of an empty kernel: one by one, and replayed from a graph.
void graphs(cudaStream_t s)
{
const int launches = 1000;
empty<<<1, 32, 0, s>>>();
check(cudaStreamSynchronize(s));
double t0 = nowMs();
for (int k = 0; k < launches; ++k) {
empty<<<1, 32, 0, s>>>();
}
check(cudaStreamSynchronize(s));
double direct = (nowMs() - t0) / launches;
cudaGraph_t graph;
cudaGraphExec_t exec;
check(cudaStreamBeginCapture(s, cudaStreamCaptureModeGlobal));
for (int k = 0; k < launches; ++k) {
empty<<<1, 32, 0, s>>>();
}
check(cudaStreamEndCapture(s, &graph));
check(cudaGraphInstantiate(&exec, graph, 0));
check(cudaGraphLaunch(exec, s)); // warm up
check(cudaStreamSynchronize(s));
t0 = nowMs();
check(cudaGraphLaunch(exec, s));
check(cudaStreamSynchronize(s));
double replay = (nowMs() - t0) / launches;
std::printf("1,000 launches of an empty kernel, time per kernel\n");
std::printf(" launched one by one %6.2f us\n", direct * 1e3);
std::printf(" replayed from a graph %6.2f us\n", replay * 1e3);
check(cudaGraphExecDestroy(exec));
check(cudaGraphDestroy(graph));
}
1,000 launches of an empty kernel, time per kernel
launched one by one 3.77 us
replayed from a graph 0.93 us
An empty kernel does no work, so its time consists entirely of launch overhead. Launched 1 at a time, each empty kernel cost 3.77 µs on the Orin NX and 2.65 µs on the Thor. Replayed from a graph, it cost 0.93 µs and 0.85 µs, respectively (figure 6.6). Graphs are therefore useful in programs that run the same short sequence of operations many times, such as each step of an inference loop or each frame of a video pipeline.
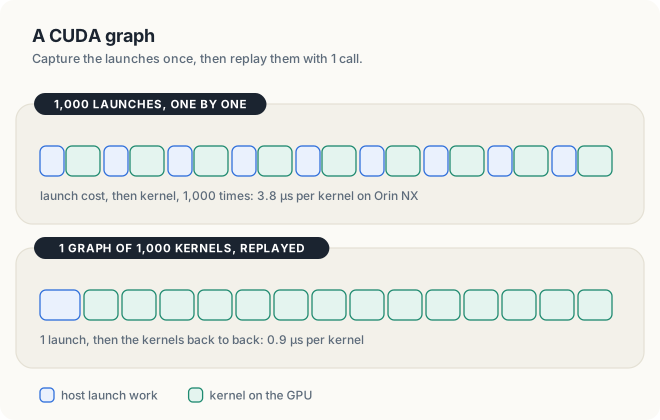
NOTE: The version of cuda-oxide used in this book has no safe API for CUDA graphs. The Rust
version therefore calls the driver functions cuStreamBeginCapture_v2, cuStreamEndCapture,
cuGraphInstantiateWithFlags and cuGraphLaunch through cuda_core::sys, in unsafe blocks.
6.8 Synchronization calls
| C++ | Rust (cuda-oxide) | The host waits for |
|---|---|---|
cudaDeviceSynchronize() | ctx.synchronize()? | all work on the device |
cudaStreamSynchronize(s) | stream.synchronize()? | all work queued in stream s |
cudaEventSynchronize(e) | event.synchronize()? | the GPU to pass event e |
cudaStreamWaitEvent(s, e) | stream.wait(&event)? | nothing: stream s waits on the GPU for event e |
cudaMemcpy(...) | buffer.copy_from_host(&stream, ...)? | the copy itself |
cudaMemcpyAsync(..., s) | unsafe { buffer.copy_from_pinned_host_async(&stream, ...)? } | nothing: the copy is queued |
The call cudaStreamWaitEvent needs a further explanation. It makes 1 stream wait for work in
another stream without stopping the host. For example, if a kernel in 1 stream must not start
until a copy in another stream has completed, the program records an event after the copy in the
first stream and makes the second stream wait for that event.
6.9 The complete programs
Listing 6.5 The complete programs. code/oxide/ch06_streams/src/main.rs code/ch06_streams/streams.cu
//! Chapter 6 in Rust: a launch timed with events, a pipeline on 2 streams, streams with
//! priorities, and a CUDA graph of 1,000 launches.
//!
//! cargo oxide run
use std::sync::Arc;
use std::time::Instant;
use cuda_core::sys::CUevent_flags_enum_CU_EVENT_DEFAULT as TIMING;
use cuda_core::sys::CUstreamCaptureMode_enum_CU_STREAM_CAPTURE_MODE_GLOBAL as GLOBAL;
use cuda_core::{
CudaContext, CudaStream, DeviceBuffer, DriverError, IntoResult, LaunchConfig1D,
PinnedHostBuffer, sys,
};
use cuda_device::{DisjointSlice, cuda_module, kernel, launch_contract, thread};
const N: usize = 32 << 20; // 33,554,432 floats, 128 MiB
const STEPS: u32 = 256;
#[cuda_module]
mod kernels {
use super::*;
/// Some arithmetic per element, so that a kernel takes about as long as its copies.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn work(mut x: DisjointSlice<f32>, steps: u32) {
if let Some(v) = x.get_mut(thread::index_1d()) {
let mut a = *v;
for _ in 0..steps {
a = a * 0.999 + 0.5;
}
*v = a;
}
}
/// A kernel that does nothing, so that its time is the cost of its launch.
#[kernel]
#[launch_contract(domain = 1, block = (32, 1, 1))]
pub fn empty() {}
}
/// 1 chunk of the data: its pinned host buffer and its device buffer.
struct Chunk {
host: PinnedHostBuffer<f32>,
device: DeviceBuffer<f32>,
}
/// The data split into `count` chunks of 1.0s.
fn chunks(
ctx: &Arc<CudaContext>,
stream: &CudaStream,
count: usize,
) -> Result<Vec<Chunk>, DriverError> {
let len = N / count;
(0..count)
.map(|_| {
let host = PinnedHostBuffer::from_slice(ctx, &vec![1.0f32; len])?;
let device = DeviceBuffer::<f32>::zeroed(stream, len)?;
Ok(Chunk { host, device })
})
.collect()
}
/// Copy in, compute and copy out every chunk, chunk c on stream c % streams.len().
/// Returns the average of 5 runs, in milliseconds.
fn pipeline(
module: &kernels::LoadedModule,
streams: &[Arc<CudaStream>],
parts: &mut [Chunk],
) -> Result<f64, Box<dyn std::error::Error>> {
let len = parts[0].host.len();
let blocks = len.div_ceil(256) as u32;
let launch = module.prepare_work(LaunchConfig1D::new(blocks, 256, 0))?;
let start = Instant::now();
for _ in 0..5 {
for (c, part) in parts.iter_mut().enumerate() {
let stream = &streams[c % streams.len()];
// SAFETY: `part.host` is neither read, written nor dropped until every
// stream is synchronized below, after both copies have completed.
unsafe { part.device.copy_from_pinned_host_async(stream, &part.host)? };
module.work(stream, &launch, &mut part.device, STEPS)?;
unsafe { part.device.copy_to_pinned_host_async(stream, &mut part.host)? };
}
}
for stream in streams {
stream.synchronize()?;
}
Ok(start.elapsed().as_secs_f64() * 1e3 / 5.0)
}
/// A stream for urgent work and a stream for bulk work, at the 2 ends of the range.
fn priorities(ctx: &Arc<CudaContext>) -> Result<(), DriverError> {
let range = ctx.stream_priority_range()?;
let urgent = ctx.new_stream_with_priority(range.greatest())?;
let bulk = ctx.new_stream_with_priority(range.least())?;
println!("stream priorities: urgent {}, bulk {}", urgent.priority()?, bulk.priority()?);
Ok(())
}
/// 1,000 launches of an empty kernel: one by one, and replayed from a graph.
fn graphs(
module: &kernels::LoadedModule,
stream: &CudaStream,
) -> Result<(), Box<dyn std::error::Error>> {
let launches = 1000;
let launch = module.prepare_empty(LaunchConfig1D::new(1, 32, 0))?;
module.empty(stream, &launch)?;
stream.synchronize()?;
let t0 = Instant::now();
for _ in 0..launches {
module.empty(stream, &launch)?;
}
stream.synchronize()?;
let direct = t0.elapsed().as_secs_f64() * 1e3 / launches as f64;
let s = stream.cu_stream();
let mut graph = std::ptr::null_mut();
let mut exec = std::ptr::null_mut();
// SAFETY: `s` is a live stream, and no other thread queues work while it is captured.
unsafe { sys::cuStreamBeginCapture_v2(s, GLOBAL).result()? };
for _ in 0..launches {
module.empty(stream, &launch)?;
}
// SAFETY: `graph` and `exec` receive new handles, used only in this function.
unsafe {
sys::cuStreamEndCapture(s, &mut graph).result()?;
sys::cuGraphInstantiateWithFlags(&mut exec, graph, 0).result()?;
}
// SAFETY: `exec` is the graph instantiated above, and `s` is still live.
unsafe { sys::cuGraphLaunch(exec, s).result()? }; // warm up
stream.synchronize()?;
let t0 = Instant::now();
// SAFETY: `exec` is the graph instantiated above, and `s` is still live.
unsafe { sys::cuGraphLaunch(exec, s).result()? };
stream.synchronize()?;
let replay = t0.elapsed().as_secs_f64() * 1e3 / launches as f64;
let direct_us = direct * 1e3;
let replay_us = replay * 1e3;
println!("1,000 launches of an empty kernel, time per kernel");
println!(" launched one by one {direct_us:6.2} us");
println!(" replayed from a graph {replay_us:6.2} us");
// SAFETY: the stream is synchronized, so the GPU no longer uses either handle.
unsafe {
sys::cuGraphExecDestroy(exec).result()?;
sys::cuGraphDestroy(graph).result()?;
}
Ok(())
}
fn main() -> Result<(), Box<dyn std::error::Error>> {
let ctx = CudaContext::new(0)?;
let streams = [ctx.new_stream()?, ctx.new_stream()?];
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let mut whole = chunks(&ctx, &streams[0], 1)?;
let mut eighths = chunks(&ctx, &streams[0], 8)?;
pipeline(&module, &streams, &mut eighths)?; // warm up: the clocks rise under load
// 1. A launch returns at once; events time the kernel on the GPU.
let stream = &streams[0];
let launch = module.prepare_work(LaunchConfig1D::new((N / 256) as u32, 256, 0))?;
let device = &mut whole[0].device;
let t0 = Instant::now();
let start = stream.record_event(Some(TIMING))?;
module.work(stream, &launch, device, STEPS)?;
let stop = stream.record_event(Some(TIMING))?;
let launched = t0.elapsed().as_secs_f64() * 1e3;
stop.synchronize()?;
let finished = t0.elapsed().as_secs_f64() * 1e3;
println!("a launch of a kernel over 128 MiB");
println!(" launch call returned after {launched:8.3} ms");
println!(" kernel finished after {finished:8.3} ms");
println!(" kernel time by events {:8.3} ms", start.elapsed_ms(&stop)?);
// 2. The same work in 1 chunk on 1 stream, and in 8 chunks on 2 streams.
println!("copy in, kernel, copy out over 128 MiB");
let one = pipeline(&module, &streams[..1], &mut whole)?;
let eight = pipeline(&module, &streams, &mut eighths)?;
println!(" 1 stream, 1 chunk {one:7.2} ms");
println!(" 2 streams, 8 chunks {eight:7.2} ms");
// 3. Streams with priorities, and a graph.
priorities(&ctx)?;
graphs(&module, stream)?;
Ok(())
}// Chapter 6: asynchronous launches, events, a pipeline on 2 streams, and a CUDA graph.
// Build: nvcc -arch=native streams.cu -o streams
#include <chrono>
#include <cstdio>
#include <cstdlib>
#include <cuda_runtime.h>
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// Some arithmetic per element, so that a kernel takes about as long as its copies.
__global__ void work(float* x, int n, int steps)
{
    int i = blockIdx.x * blockDim.x + threadIdx.x;
    if (i >= n) return;

    float v = x[i];
    for (int k = 0; k < steps; ++k) {
        v = fmaf(v, 0.999f, 0.5f);
    }
    x[i] = v;
}
__global__ void empty() {}
// 1. A launch returns before the kernel finishes; events time the kernel on the GPU.
void asyncLaunch(float* d, int n, int steps)
{
    cudaEvent_t start, stop;
    check(cudaEventCreate(&start));
    check(cudaEventCreate(&stop));

    work<<<(n + 255) / 256, 256>>>(d, n, steps);       // warm up
    check(cudaDeviceSynchronize());

    double t0 = nowMs();
    check(cudaEventRecord(start));
    work<<<(n + 255) / 256, 256>>>(d, n, steps);
    check(cudaEventRecord(stop));
    double launched = nowMs() - t0;

    check(cudaEventSynchronize(stop));
    double finished = nowMs() - t0;

    float gpuMs;
    check(cudaEventElapsedTime(&gpuMs, start, stop));

    std::printf("a launch of a kernel over %d MiB\n", int(n * sizeof(float) >> 20));
    std::printf("  launch call returned after   %8.3f ms\n", launched);
    std::printf("  kernel finished after        %8.3f ms\n", finished);
    std::printf("  kernel time by events        %8.3f ms\n", gpuMs);

    check(cudaEventDestroy(start));
    check(cudaEventDestroy(stop));
}
// 2. Copy in, compute, copy out: all at once on 1 stream, or in chunks on 2 streams.
void enqueue(float* host, float* d, int n, int steps, int chunks, cudaStream_t* streams)
{
    int part = n / chunks;
    size_t bytes = part * sizeof(float);

    for (int c = 0; c < chunks; ++c) {
        cudaStream_t s = streams[c % 2];
        float* h = host + c * part;
        float* g = d + c * part;

        check(cudaMemcpyAsync(g, h, bytes, cudaMemcpyHostToDevice, s));
        work<<<(part + 255) / 256, 256, 0, s>>>(g, part, steps);
        check(cudaMemcpyAsync(h, g, bytes, cudaMemcpyDeviceToHost, s));
    }
}

// Average time of 5 pipelines, in milliseconds.
double pipeline(float* host, float* d, int n, int steps, int chunks, cudaStream_t* streams)
{
    check(cudaDeviceSynchronize());
    double t0 = nowMs();

    for (int r = 0; r < 5; ++r) {
        enqueue(host, d, n, steps, chunks, streams);
    }

    check(cudaDeviceSynchronize());
    return (nowMs() - t0) / 5;
}
// The 3 stages of the 1-stream run, timed separately with events.
void stages(float* host, float* d, int n, int steps, cudaStream_t s)
{
cudaEvent_t e[4];
for (auto& ev : e) check(cudaEventCreate(&ev));
size_t bytes = n * sizeof(float);
check(cudaEventRecord(e[0], s));
check(cudaMemcpyAsync(d, host, bytes, cudaMemcpyHostToDevice, s));
check(cudaEventRecord(e[1], s));
work<<<(n + 255) / 256, 256, 0, s>>>(d, n, steps);
check(cudaEventRecord(e[2], s));
check(cudaMemcpyAsync(host, d, bytes, cudaMemcpyDeviceToHost, s));
check(cudaEventRecord(e[3], s));
check(cudaEventSynchronize(e[3]));
const char* names[] = {"copy in", "kernel", "copy out"};
for (int k = 0; k < 3; ++k) {
float ms;
check(cudaEventElapsedTime(&ms, e[k], e[k + 1]));
std::printf(" %-9s %7.2f ms\n", names[k], ms);
}
for (auto& ev : e) check(cudaEventDestroy(ev));
}
// 3. 1,000 launches of an empty kernel: one by one, and replayed from a graph.
void graphs(cudaStream_t s)
{
    const int launches = 1000;
    empty<<<1, 32, 0, s>>>();
    check(cudaStreamSynchronize(s));

    double t0 = nowMs();
    for (int k = 0; k < launches; ++k) {
        empty<<<1, 32, 0, s>>>();
    }
    check(cudaStreamSynchronize(s));
    double direct = (nowMs() - t0) / launches;

    cudaGraph_t graph;
    cudaGraphExec_t exec;
    check(cudaStreamBeginCapture(s, cudaStreamCaptureModeGlobal));
    for (int k = 0; k < launches; ++k) {
        empty<<<1, 32, 0, s>>>();
    }
    check(cudaStreamEndCapture(s, &graph));
    check(cudaGraphInstantiate(&exec, graph, 0));

    check(cudaGraphLaunch(exec, s));                    // warm up
    check(cudaStreamSynchronize(s));

    t0 = nowMs();
    check(cudaGraphLaunch(exec, s));
    check(cudaStreamSynchronize(s));
    double replay = (nowMs() - t0) / launches;

    std::printf("1,000 launches of an empty kernel, time per kernel\n");
    std::printf("  launched one by one   %6.2f us\n", direct * 1e3);
    std::printf("  replayed from a graph %6.2f us\n", replay * 1e3);

    check(cudaGraphExecDestroy(exec));
    check(cudaGraphDestroy(graph));
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %d copy engine(s)\n", prop.name, prop.asyncEngineCount);
const int n = 32 << 20; // 33,554,432 floats, 128 MiB
const int steps = 256;
float* host;
float* d;
check(cudaMallocHost(&host, n * sizeof(float)));
check(cudaMalloc(&d, n * sizeof(float)));
for (int i = 0; i < n; ++i) {
host[i] = 1.0f;
}
cudaStream_t streams[2];
check(cudaStreamCreate(&streams[0]));
check(cudaStreamCreate(&streams[1]));
pipeline(host, d, n, steps, 8, streams); // warm up: clocks rise under load
asyncLaunch(d, n, steps);
std::printf("copy in, kernel, copy out over 128 MiB\n");
stages(host, d, n, steps, streams[0]);
double one = pipeline(host, d, n, steps, 1, streams);
double eight = pipeline(host, d, n, steps, 8, streams);
double many = pipeline(host, d, n, steps, 32, streams);
std::printf(" 1 stream, 1 chunk %7.2f ms\n", one);
std::printf(" 2 streams, 8 chunks %7.2f ms\n", eight);
std::printf(" 2 streams, 32 chunks %7.2f ms\n", many);
graphs(streams[0]);
check(cudaStreamDestroy(streams[0]));
check(cudaStreamDestroy(streams[1]));
check(cudaFreeHost(host));
check(cudaFree(d));
}
Common mistakes
- Queuing a copy with
cudaMemcpyAsyncfrom pageable memory. The copy runs synchronously, and the overlap is lost. Use pinned memory (Chapter 4). - Launching or copying without a stream in a program that overlaps work. The default stream waits for every other stream. Name a stream in every call.
- Timing GPU work with the host clock alone. The measurement includes launch time and the time the host takes to notice completion. Use events.
- Modifying a host buffer while an asynchronous copy still reads it. Synchronize the stream, or wait for an event, first.
- Dividing the data into more and more chunks. Once the longest stage dominates, additional chunks only add launch work.
- Expecting overlap to shorten the longest stage. Overlap hides the other stages behind it.
Summary
- A launch or an asynchronous copy only queues work and returns: 0.075 ms for a kernel that ran for 12 ms.
- A stream is an ordered queue. Work in 1 stream runs in order; work in different streams may run at the same time, on the copy engines and the SMs together.
- The default stream synchronizes with every other stream, so programs that overlap work name their streams explicitly.
- Events time work on the GPU’s own clock.
- A pipeline of chunks on 2 streams reduced 22.6 ms to 12.9 ms on an Orin NX, close to the bound \(T_{\text{longest}} + T_{\text{others}} / k\). On a Thor, where the kernel dominates and the memory is shared, it saved 13%.
- In Rust, asynchronous copies are
unsafe, because the GPU uses the buffer after the borrow has ended. - A CUDA graph launches many operations with 1 call: 0.93 µs per empty kernel instead of 3.77 µs.
In Chapter 7, we return to a single kernel and study its memory accesses: coalescing, shared-memory tiling and bank conflicts, each measured.
Exercises
- A program queues copy in, kernel and copy out for 4 chunks, all in stream 0. Why does it gain nothing over 1 chunk?
- Copy in takes 8 ms, the kernel 3 ms and copy out 2 ms. What is the bound for 4 chunks on 2 streams, and which stage sets it?
- Change
streams.cuto use 1 stream with 8 chunks. Predict the time, then measure it. - Why does the gain from overlap fall on an integrated GPU such as the Thor? Name two reasons.
- Record an event after the copy in stream 0 and make stream 1 wait for it with
cudaStreamWaitEvent. What does stream 1 now wait for, and what does the host wait for? - A loop launches 5 kernels of 20 µs each, 10,000 times. Estimate the launch overhead at 4 µs per launch, and the time saved by a graph at 1 µs per kernel.
- In the Rust pipeline, move
stream.synchronize()out ofpipelineand readparts[0].hostright after the loop. Which promise in theSAFETYcomment does that break?
Sources and further reading
- NVIDIA, CUDA C++ Programming Guide, “Asynchronous Concurrent Execution”, “Streams”, “Events” and “CUDA Graphs”: https://docs.nvidia.com/cuda/cuda-c-programming-guide/
- NVIDIA, CUDA C++ Best Practices Guide, “Asynchronous and Overlapping Transfers with Computation”: https://docs.nvidia.com/cuda/cuda-c-best-practices-guide/
- M. Harris, “How to Overlap Data Transfers in CUDA C/C++”, NVIDIA Technical Blog, 2012.
- NVlabs, cuda-oxide,
cuda_core::CudaStreamandcuda_core::CudaEvent: https://github.com/NVlabs/cuda-oxide
Chapter 7: Memory Optimization Deep Dive
Most kernels perform only a few arithmetic operations for each byte they read from global memory. As we saw in Chapter 1, the speed of such a kernel is limited by the memory bandwidth of the GPU, not by its arithmetic units. For a memory-bound kernel, the number of operations it performs matters less than the number of bytes it moves and the fraction of those bytes it uses. Two kernels that compute the same result can differ 5 times in speed because one of them moves 5 times as many bytes.
In this chapter, we study the rules that determine how many bytes a kernel moves. Global memory transfers data in fixed-size pieces, so the pattern in which the threads of a warp access memory matters as much as the amount of data they access. Shared memory allows a block to rearrange data on the chip before writing it to global memory, and it has a layout rule of its own. Wider load instructions move more bytes per instruction. We measure the effect of each rule and conclude with a checklist for memory-bound kernels that later chapters use.
This chapter covers
- effective bandwidth as the measure of a memory-bound kernel
- 32-byte sectors, and the effect of the stride between neighboring threads on the bytes moved
- the grid-stride loop
- shared memory as a program-managed cache, applied to a matrix transpose
- bank conflicts, and the padding column that removes them
- vector loads with
float4 - constant and texture memory
- a checklist for memory-bound kernels
The code of the chapter is in
code/ch07_memory/
for C++ and in
code/oxide/ch07_memory/
for Rust.
7.1 Effective bandwidth
The effective bandwidth of a kernel is the number of bytes it must read and write to perform its task, divided by its running time. For example, a kernel that copies 64 MiB reads 64 MiB and writes 64 MiB, so its effective bandwidth is 128 MiB divided by its running time. Effective bandwidth counts only the bytes that the task requires, not the bytes that the hardware actually transfers. Therefore, a kernel that causes unnecessary memory traffic has a low effective bandwidth, and the measure exposes the waste.
A plain copy kernel provides the reference point. On a Jetson Orin NX, whose memory has a peak bandwidth of 102 GB/s, a copy kernel reached about 74 GB/s; on a Jetson AGX Thor, with a peak of 273 GB/s, it reached about 225 GB/s. No kernel moves its bytes faster than a copy. A memory-bound kernel whose effective bandwidth is close to that of a copy has little left to gain, whereas a kernel far below it either transfers bytes that it does not use or accesses memory in an unfavorable pattern.
There are two ways to improve a memory-bound kernel:
- Waste fewer bytes. Arrange the accesses so that every byte delivered by the memory is used.
- Fetch fewer bytes. When the same data is needed more than once, keep it on the chip, in shared memory or in registers, instead of reading it from global memory again.
Each technique in the rest of this chapter belongs to one of these 2 categories.
7.2 Memory coalescing
7.2.1 Sectors
Global memory does not deliver individual bytes. The memory system transfers data in sectors of 32 bytes, aligned to multiples of 32, and the L2 cache groups 4 sectors into a 128-byte line. When a warp executes a load instruction, the hardware collects the 32 addresses of its threads and fetches every sector that contains at least one of them. A warp’s access is said to be coalesced when its addresses fall into as few sectors as possible.
Consider a warp whose 32 threads read 32 neighboring floats. These occupy 32 × 4 = 128 bytes,
exactly 4 sectors, so the warp moves 128 bytes and uses all 128 of them. If the threads instead read
every other float, the 32 floats are spread over 256 bytes, or 8 sectors, and half of each sector is
wasted. At a distance of 8 floats, which is 32 bytes, each float lies in a sector of its own. The
warp then moves 32 sectors, 1,024 bytes, to use 128 bytes (figure 7.1).
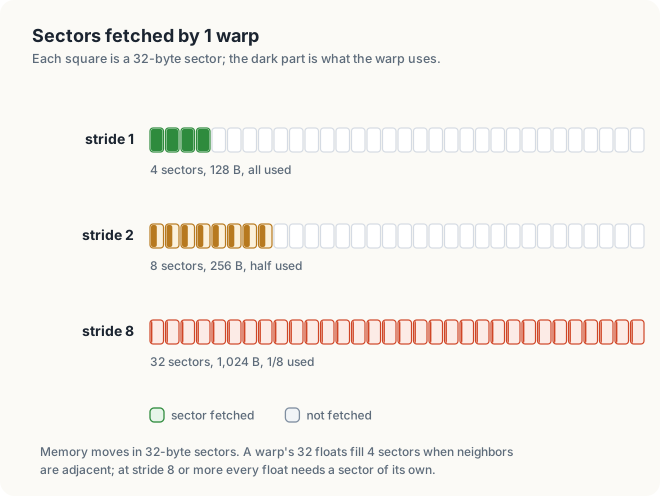
Animation 1 shows the sectors moved for each stride, with the bytes moved and the bytes used.
7.2.2 Measuring the effect of stride
The kernel in Listing 7.1 takes the stride as a parameter. Thread \(i\) reads element \(i
\times\) stride of the input and writes element \(i\) of the output. The writes therefore
remain coalesced for every stride, and only the reads change from one run to the next.
Listing 7.1 A strided read. code/oxide/ch07_memory/src/main.rs code/ch07_memory/memory.cu
mod kernels {
    // ...
    /// Thread i reads element i * stride.
    #[kernel]
    #[launch_contract(domain = 1, block = (256, 1, 1))]
    pub fn strided(input: &[f32], mut out: DisjointSlice<f32>, stride: u32) {
        let idx = thread::index_1d();
        let i = idx.get();

        if let Some(o) = out.get_mut(idx) {
            *o = input[i * stride as usize];
        }
    }
    // ...
}
// 1. Thread i reads element i * stride, so neighboring threads read `stride` floats apart.
__global__ void strided(const float* in, float* out, int n, int stride)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
out[i] = in[(size_t)i * stride];
}
}
The program launches 16,777,216 threads, so every run reads the 64 MiB that the task requires. The input array is 32 times as large, 2 GiB, so that stride 32 stays within it. The array is also far larger than the L2 cache, which is 2 MiB on the Orin NX and 32 MiB on the Thor, so no stride can be served from the cache.
$ ./memory # on a Jetson Orin NX
GPU: Orin, 8 SMs, L2 cache 2 MiB
each thread reads 1 float, neighbours `stride` floats apart
stride 1 1.973 ms 68.0 GB/s useful
stride 2 2.199 ms 61.0 GB/s useful
stride 4 3.824 ms 35.1 GB/s useful
stride 8 6.432 ms 20.9 GB/s useful
stride 16 9.333 ms 14.4 GB/s useful
stride 32 7.616 ms 17.6 GB/s useful
$ ./memory # on a Jetson AGX Thor
GPU: NVIDIA Thor, 20 SMs, L2 cache 32 MiB
each thread reads 1 float, neighbours `stride` floats apart
stride 1 0.587 ms 228.6 GB/s useful
stride 2 0.776 ms 172.9 GB/s useful
stride 4 1.283 ms 104.6 GB/s useful
stride 8 2.315 ms 58.0 GB/s useful
stride 16 4.468 ms 30.0 GB/s useful
stride 32 2.636 ms 50.9 GB/s useful
The sector model of section 7.2.1 predicts how far the useful bandwidth falls. At stride 1, each thread moves 4 bytes of read and 4 bytes of write, 8 bytes in all. From stride 8 onwards, each read costs a whole sector, so a thread moves 32 + 4 = 36 bytes for the same 8 useful bytes. That is 36 / 8 = 4.5 times the traffic, and the useful bandwidth should therefore fall to about 1/4.5 of its stride-1 value: 68 / 4.5 ≈ 15 GB/s on the Orin NX and 229 / 4.5 ≈ 51 GB/s on the Thor. These predictions are close to the measured values at strides 8 and 16 (figure 7.2).
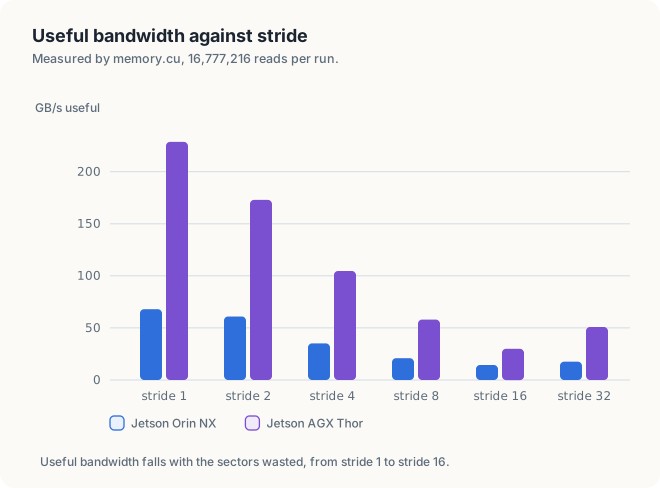
Note that stride 32 ran faster than stride 16 on both GPUs. The DRAM chips are organized in rows and banks, and some address patterns are distributed over them better than others. This effect lies below the level of the sector model, and we do not analyze it here. The stride-1 bandwidth on the Orin NX also varied between about 68 and 78 GB/s from run to run, as the GPU’s clocks changed. Neither effect changes the conclusion:
Neighboring threads should read neighboring addresses.
The global index of Chapter 3, blockIdx.x * blockDim.x + threadIdx.x, satisfies this rule by
construction, since consecutive threads receive consecutive indices. Row-major 2-D data satisfies
it when threadIdx.x moves along a row: thread \(x\) reads in[y * width + x]. If the same data
is read down a column, as in in[x * width + y], neighboring threads are width floats apart,
which is the worst case in the measurements above.
7.3 The grid-stride loop
A kernel that assigns 1 thread to each element ties the size of its launch to the size of the
data. A grid-stride loop, which we used for the histogram in Chapter 5, removes that
dependence. The program launches a grid of fixed size, and each thread processes element \(i\),
then element \(i + s\), then \(i + 2s\), and so on, where \(s\) = gridDim.x * blockDim.x is
the number of threads in the grid.
mod kernels {
// ...
/// A copy by a grid-stride loop: thread i copies elements i, i + s, i + 2s, ...
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn copy_grid_stride(input: &[f32], mut out: DisjointSlice<f32>) {
let stride = (thread::gridDim_x() * thread::blockDim_x()) as usize;
let mut i = thread::index_1d().get();
while i < out.len() {
// SAFETY: thread t writes only the elements i with i % stride == t, and no 2
// threads of the grid have the same t.
unsafe { *out.get_unchecked_mut(i) = input[i] };
i += stride;
}
}
// ...
}int stride = gridDim.x * blockDim.x;
for (int i = blockIdx.x * blockDim.x + threadIdx.x; i < n; i += stride) {
out[i] = in[i];
}
In every iteration of the loop, neighboring threads access neighboring elements, so the loop keeps the coalescing of the kernel with one thread per element. It allows a kernel to process data of any size with a grid sized to the GPU, typically a few blocks per SM. It also allows each thread to accumulate a private result over many elements before it updates shared state, as the histogram kernel of Chapter 5 did.
7.4 Shared memory tiling
7.4.1 Matrix transpose
A transpose exchanges the rows and columns of a matrix: out[x][y] = in[y][x]. When the
matrix is stored in row-major order, 1 of the 2 accesses must cross rows. If each warp reads a row
of the input, the read is coalesced, but the write goes down a column of the output, 1 float in each
of 32 rows (figure 7.3).
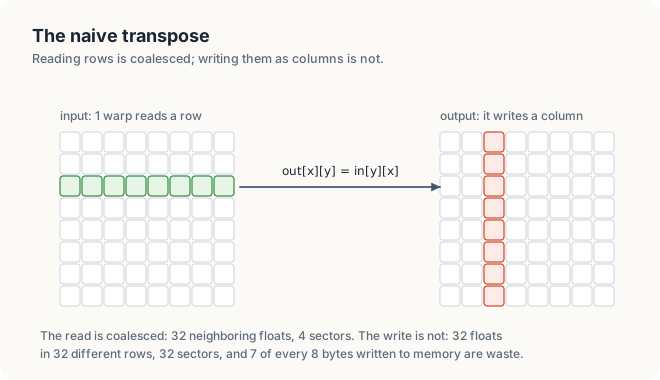
Listing 7.2 The naive transpose.
mod kernels {
// ...
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (32, 32, 1))]
pub fn transpose_naive(input: &[f32], mut out: DisjointSlice<f32, Index2D<WIDTH>>) {
let x = (thread::blockIdx_x() * 32 + thread::threadIdx_x()) as usize;
let y = (thread::blockIdx_y() * 32 + thread::threadIdx_y()) as usize;
// SAFETY: (x, y) -> x * WIDTH + y is a permutation of the matrix, so no 2 threads
// write the same element, and every index is below WIDTH * WIDTH.
unsafe { *out.get_unchecked_mut(x * WIDTH + y) = input[y * WIDTH + x] };
}
// ...
}// 3. Transposes of a width x width matrix, 1 thread per element, blocks of 32 x 32.
__global__ void transposeNaive(const float* in, float* out, int width)
{
int x = blockIdx.x * TILE + threadIdx.x;
int y = blockIdx.y * TILE + threadIdx.y;
out[x * width + y] = in[y * width + x];
}
Exchanging the 2 accesses does not help, because the read then goes down a column instead. The solution is to perform the column access in a memory that does not transfer data in sectors, and to access global memory only along rows.
7.4.2 A tiled transpose
Recall from Chapter 2 that shared memory is located on the chip and belongs to 1 block. It does not transfer data in sectors: a thread can read or write any word of it at the same cost. A block can therefore use shared memory as a cache whose contents the program chooses explicitly. For the transpose, each block of 32 × 32 threads performs 3 steps:
- It reads a 32 × 32 tile of the input row by row, with coalesced accesses, and stores the tile in shared memory in the same layout.
- It waits at a barrier, so that the whole tile is in shared memory before any thread reads it.
- It reads the tile column by column and writes each column as a row of the output tile, which is located at the mirrored position of the output matrix. These writes are also coalesced.
Global memory is accessed only along rows; the column access takes place in shared memory (figure 7.4).
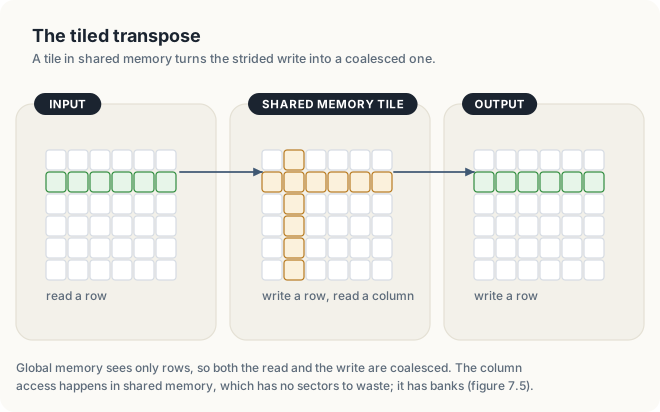
Listing 7.3 The tiled transpose.
mod kernels {
// ...
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (32, 32, 1))]
pub fn transpose_tiled(input: &[f32], mut out: DisjointSlice<f32, Index2D<WIDTH>>) {
static mut TILE: SharedArray<f32, { 32 * 33 }> = SharedArray::UNINIT;
let (tx, ty) = (thread::threadIdx_x() as usize, thread::threadIdx_y() as usize);
let bx = thread::blockIdx_x() as usize * 32;
let by = thread::blockIdx_y() as usize * 32;
// SAFETY: each thread writes only its own slot of the tile, before the barrier.
unsafe { TILE[ty * 33 + tx] = input[(by + ty) * WIDTH + bx + tx] };
thread::sync_threads();
// SAFETY: the tile is only read after the barrier. The map
// (tx, ty) -> (bx + ty) * WIDTH + by + tx is a permutation of the matrix,
// so no 2 threads write the same element.
unsafe { *out.get_unchecked_mut((bx + ty) * WIDTH + by + tx) = TILE[tx * 33 + ty] };
}
// ...
}template <int PAD>
__global__ void transposeTiled(const float* in, float* out, int width)
{
__shared__ float tile[TILE][TILE + PAD];
int x = blockIdx.x * TILE + threadIdx.x;
int y = blockIdx.y * TILE + threadIdx.y;
tile[threadIdx.y][threadIdx.x] = in[y * width + x];
__syncthreads();
x = blockIdx.y * TILE + threadIdx.x;
y = blockIdx.x * TILE + threadIdx.y;
out[y * width + x] = tile[threadIdx.x][threadIdx.y];
}
After the barrier, the kernel recomputes x and y for the output. The block’s x and y block
numbers are exchanged, because tile (bx, by) of the input becomes tile (by, bx) of the output.
PAD is a template parameter whose value is 0 or 1; section 7.5 explains the purpose of the
additional column. Animation 2 follows a 4 × 4 tile through shared memory.
7.4.3 The transposes in Rust
In Rust, both transpose kernels, Listings 7.2 and 7.3, require unsafe, for a reason that the
compiler cannot check. A DisjointSlice allows a thread to write only the element named by its own
index, which guarantees that no 2 threads write the same element. A transpose, however, writes
element x * WIDTH + y, which is the index of a different thread. The writes are still disjoint,
because the mapping from \((x, y)\) to x * WIDTH + y is a permutation, but the compiler cannot
prove this. The kernel therefore states the argument in a SAFETY comment and writes through
get_unchecked_mut.
Index2D<WIDTH> declares the output to be a 2-D grid of width WIDTH, which a launch with a 2-D
contract requires. The tile is a SharedArray<f32, { 32 * 33 }>, indexed as row * 33 + column.
This is the padded layout described in section 7.5.
7.5 Bank conflicts and column padding
Shared memory is divided into 32 banks, each of which can serve 1 32-bit word per cycle. Consecutive words are assigned to consecutive banks, so word \(w\) is located in bank \(w \bmod 32\) (Chapter 2). A warp’s 32 accesses complete in 1 cycle when they fall into 32 different banks. When several accesses fall into the same bank at different addresses, the result is a bank conflict, and that bank serves the accesses one after another.
In a tile declared as float tile[32][32], element tile[r][c] is word \(32r + c\), which is in
bank \((32r + c) \bmod 32 = c\). Reading column 0 means reading tile[0][0] to tile[31][0],
all of which are in bank 0. This is a 32-way conflict, and 1 warp’s access takes 32 cycles. If the
tile is declared with 1 additional column, as float tile[32][33], then tile[r][c] is word
\(33r + c\), in bank \((33r + c) \bmod 32 = (r + c) \bmod 32\). Column 0 now falls into banks
0, 1, 2, … 31, which are all different, and the access takes 1 cycle (figure 7.5). The additional
column is never used; its only effect is to shift each row by 1 bank.
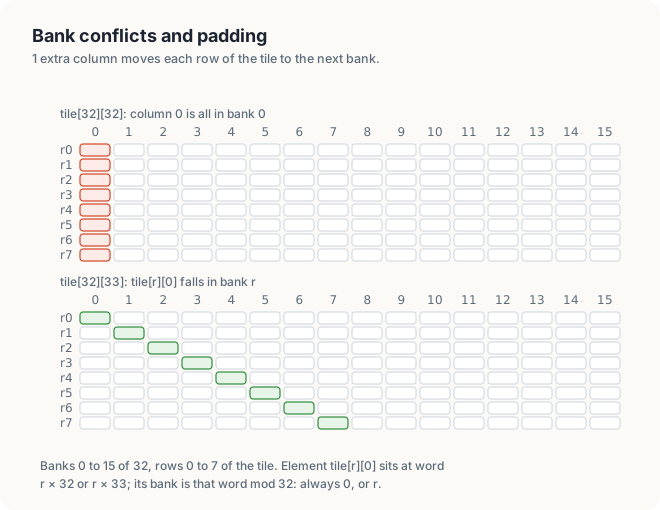
transpose of a 4096 x 4096 matrix # on a Jetson Orin NX
copy, for reference 1.71 ms 78.3 GB/s
naive 8.13 ms 16.5 GB/s
tiled 4.60 ms 29.2 GB/s
tiled and padded 3.00 ms 44.8 GB/s
tiled transpose correct: yes
transpose of a 4096 x 4096 matrix # on a Jetson AGX Thor
copy, for reference 0.58 ms 230.6 GB/s
naive 1.66 ms 80.7 GB/s
tiled 1.39 ms 96.4 GB/s
tiled and padded 0.94 ms 143.1 GB/s
tiled transpose correct: yes
$ cargo oxide run # on a Jetson Orin NX
transpose of a 4096 x 4096 matrix
naive 7.98 ms 16.8 GB/s
tiled and padded 3.26 ms 41.1 GB/s
tiled transpose correct: yes
On the Orin NX, tiling alone raised the transpose from 16.5 to 29.2 GB/s, and padding raised it to 44.8 GB/s, 2.7 times the bandwidth of the naive kernel. On the Thor, the transpose rose from 80.7 to 143.1 GB/s, 1.8 times (figure 7.6). Both results are still below the copy. A block of the tiled transpose must wait at its barrier between reading and writing, so it overlaps memory traffic less than a copy does. Chapter 9 returns to the problem of keeping more work in flight per thread.
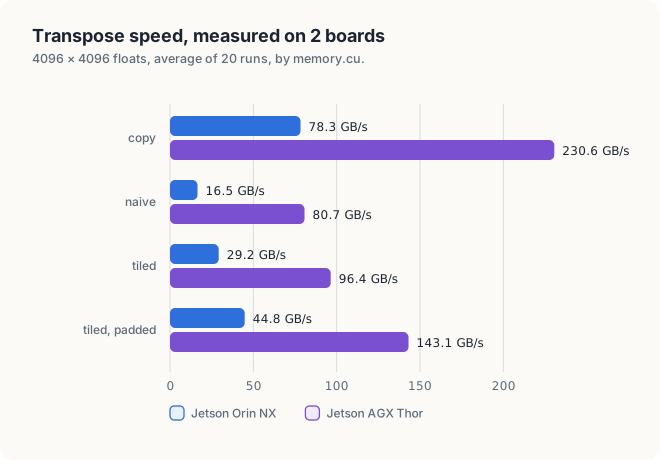
A tile is declared float tile[32][16]. Which banks does a column of it fall in, and how many cycles does reading a column take?
tile[r][c] is word \(16r + c\), in bank \((16r + c) \bmod 32\). For column 0, rows 0, 2, 4, …
fall in bank 0 and rows 1, 3, 5, … in bank 16. With 32 rows, each of the 2 banks serves 16 words: a
16-way conflict, 16 cycles. Padding to 17 columns spreads the column over all 32 banks.
7.6 Vectorized loads: float4 and alignment
A load instruction can move 4, 8 or 16 bytes per thread. float4 is a built-in type that holds 4
floats. With a float4 load, 1 instruction moves 16 bytes per thread and 512 bytes per warp, 4
times as much as a float load. The kernel therefore issues a quarter as many load and store
instructions for the same number of bytes.
Listing 7.4 A copy with 1 and with 4 floats per thread.
/// 4 floats aligned to 16 bytes, so that 1 instruction loads or stores all 4: `float4`.
#[repr(C, align(16))]
#[derive(Clone, Copy, PartialEq)]
pub struct Float4([f32; 4]);
// SAFETY: 4 plain floats, with no pointers, can be copied to and from the device.
unsafe impl DeviceCopy for Float4 {}
mod kernels {
// ...
/// A copy, 1 float per thread.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn copy1(input: &[f32], mut out: DisjointSlice<f32>) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(o) = out.get_mut(idx) {
*o = input[i];
}
}
/// A copy, 4 floats per thread.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn copy4(input: &[Float4], mut out: DisjointSlice<Float4>) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(o) = out.get_mut(idx) {
*o = input[i];
}
}
// ...
}// 2. A copy, 1 float or 4 floats per thread.
__global__ void copy1(const float* in, float* out, int n)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
out[i] = in[i];
}
}
__global__ void copy4(const float4* in, float4* out, int n4)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n4) {
out[i] = in[i];
}
}
copy of 64 MiB # Orin NX, then Thor
1 float per thread 1.83 ms 73.5 GB/s
4 floats per thread 1.53 ms 87.7 GB/s
1 float per thread 0.60 ms 225.2 GB/s
4 floats per thread 0.53 ms 251.5 GB/s
The wider loads made the copy 19% faster on the Orin NX and 12% faster on the Thor, where the copy
reached 92% of the peak of 273 GB/s. A float4 access must be aligned to 16 bytes. Memory returned
by cudaMalloc is aligned to a much larger boundary, so it is safe to cast the start of an
allocation to float4*. A pointer offset by 1, 2 or 3 floats, however, is not aligned, and the last
\(n \bmod 4\) elements of an array must be handled with a plain float loop. In Rust, the
type Float4, 4 floats with the attribute #[repr(C, align(16))], takes the place of float4.
7.7 Constant memory
Constant memory is a read-only space of 64 KB with a small cache of its own on each SM. The constant cache serves all 32 threads of a warp in 1 access when they read the same address; this is called a broadcast. When the threads read different addresses, the accesses are served 1 after another. This behavior is the opposite of global and shared memory, which perform best when the threads access different addresses.
mod kernels {
// ...
#[constant]
static COEFFS: ConstantMemory<[f32; 16]> = ConstantMemory::UNINIT; // in constant memory
/// Every thread multiplies by the same coefficient, coeffs[k].
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scale(input: &[f32], mut out: DisjointSlice<f32>, k: u32) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(o) = out.get_mut(idx) {
*o = input[i] * COEFFS.get_ref()[k as usize]; // every thread reads coeffs[k]
}
}
}
fn main() -> Result<(), Error> {
// ...
let coeffs: [f32; 16] = std::array::from_fn(|k| k as f32 * 0.5);
module.set_coeffs(&stream, &coeffs)?; // fill it by name
// ...
}__constant__ float coeffs[16]; // device side, at file scope
cudaMemcpyToSymbol(coeffs, host, 16 * sizeof(float)); // host side: fill it by name
out[i] = in[i] * coeffs[k]; // in a kernel: every thread reads coeffs[k]
Constant memory is therefore suited to parameters, coefficients and small tables that every thread of a warp reads at the same index. When each thread needs a different entry, ordinary global memory, served through the caches, is faster.
7.8 Texture and surface memory
Texture memory is a read-only path to global memory with 2 additional capabilities. Its cache is organized for 2-D neighborhoods, which suits images read in small squares, and its hardware can interpolate, returning a weighted average of neighboring pixels in 1 load. On current GPUs, the ordinary L1 and L2 caches serve most access patterns as well as the texture cache does, so the main reason to use textures today is the interpolation hardware. Surfaces are the writable counterpart of textures. For data read in rows, as in every kernel of this chapter, coalesced accesses to global memory are as fast and simpler to program.
7.9 Optimization checklist
For a memory-bound kernel, check the following items in order, and measure after each change:
- Effective bandwidth. Compute it and compare it with a copy on the same GPU. A kernel close to the copy has little left to gain.
- Coalescing. Do neighboring threads access neighboring addresses in every load and every store (section 7.2)?
- Launch shape. Does a grid-stride loop give each thread enough work (section 7.3)?
- Reuse. Is data read more than once, or read in a pattern that cannot be coalesced? Stage it in shared memory (section 7.4).
- Bank conflicts. Do the shared-memory accesses of a warp fall into different banks? If not, pad the rows of the tile (section 7.5).
- Vector loads. Can the kernel use
float4loads with correct alignment (section 7.6)? - Uniform values. Do all threads of a warp read the same small values? Use constant memory (section 7.7).
- Transfers. Do the copies that feed the kernel take longer than the kernel itself? Use pinned memory and streams first (Chapters 4 and 6).
7.10 The complete programs
Listing 7.5 The complete programs. code/oxide/ch07_memory/src/main.rs code/ch07_memory/memory.cu
//! Chapter 7 in Rust: coalescing, a grid-stride loop, a matrix transpose through shared
//! memory, copies of 1 and 4 floats per thread, and constant memory.
//!
//! cargo oxide run
use std::sync::Arc;
use std::time::Instant;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, DeviceCopy};
use cuda_core::{LaunchConfig1D, LaunchConfig2D};
use cuda_device::thread::Index2D;
use cuda_device::{ConstantMemory, DisjointSlice, SharedArray, constant, cuda_module};
use cuda_device::{kernel, launch_contract, thread};
const WIDTH: usize = 4096;
const N: usize = WIDTH * WIDTH; // 16,777,216 floats, 64 MiB
type Error = Box<dyn std::error::Error>;
/// 4 floats aligned to 16 bytes, so that 1 instruction loads or stores all 4: `float4`.
#[repr(C, align(16))]
#[derive(Clone, Copy, PartialEq)]
pub struct Float4([f32; 4]);
// SAFETY: 4 plain floats, with no pointers, can be copied to and from the device.
unsafe impl DeviceCopy for Float4 {}
#[cuda_module]
mod kernels {
use super::*;
/// Thread i reads element i * stride.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn strided(input: &[f32], mut out: DisjointSlice<f32>, stride: u32) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(o) = out.get_mut(idx) {
*o = input[i * stride as usize];
}
}
/// A copy by a grid-stride loop: thread i copies elements i, i + s, i + 2s, ...
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn copy_grid_stride(input: &[f32], mut out: DisjointSlice<f32>) {
let stride = (thread::gridDim_x() * thread::blockDim_x()) as usize;
let mut i = thread::index_1d().get();
while i < out.len() {
// SAFETY: thread t writes only the elements i with i % stride == t, and no 2
// threads of the grid have the same t.
unsafe { *out.get_unchecked_mut(i) = input[i] };
i += stride;
}
}
/// A copy, 1 float per thread.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn copy1(input: &[f32], mut out: DisjointSlice<f32>) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(o) = out.get_mut(idx) {
*o = input[i];
}
}
/// A copy, 4 floats per thread.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn copy4(input: &[Float4], mut out: DisjointSlice<Float4>) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(o) = out.get_mut(idx) {
*o = input[i];
}
}
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (32, 32, 1))]
pub fn transpose_naive(input: &[f32], mut out: DisjointSlice<f32, Index2D<WIDTH>>) {
let x = (thread::blockIdx_x() * 32 + thread::threadIdx_x()) as usize;
let y = (thread::blockIdx_y() * 32 + thread::threadIdx_y()) as usize;
// SAFETY: (x, y) -> x * WIDTH + y is a permutation of the matrix, so no 2 threads
// write the same element, and every index is below WIDTH * WIDTH.
unsafe { *out.get_unchecked_mut(x * WIDTH + y) = input[y * WIDTH + x] };
}
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (32, 32, 1))]
pub fn transpose_tiled(input: &[f32], mut out: DisjointSlice<f32, Index2D<WIDTH>>) {
static mut TILE: SharedArray<f32, { 32 * 33 }> = SharedArray::UNINIT;
let (tx, ty) = (thread::threadIdx_x() as usize, thread::threadIdx_y() as usize);
let bx = thread::blockIdx_x() as usize * 32;
let by = thread::blockIdx_y() as usize * 32;
// SAFETY: each thread writes only its own slot of the tile, before the barrier.
unsafe { TILE[ty * 33 + tx] = input[(by + ty) * WIDTH + bx + tx] };
thread::sync_threads();
// SAFETY: the tile is only read after the barrier. The map
// (tx, ty) -> (bx + ty) * WIDTH + by + tx is a permutation of the matrix,
// so no 2 threads write the same element.
unsafe { *out.get_unchecked_mut((bx + ty) * WIDTH + by + tx) = TILE[tx * 33 + ty] };
}
#[constant]
static COEFFS: ConstantMemory<[f32; 16]> = ConstantMemory::UNINIT; // in constant memory
/// Every thread multiplies by the same coefficient, coeffs[k].
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scale(input: &[f32], mut out: DisjointSlice<f32>, k: u32) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(o) = out.get_mut(idx) {
*o = input[i] * COEFFS.get_ref()[k as usize]; // every thread reads coeffs[k]
}
}
}
/// Average time of 20 runs of `launch`, in milliseconds, after 1 warm-up run.
fn time_ms(
stream: &Arc<CudaStream>,
mut launch: impl FnMut() -> Result<(), Error>,
) -> Result<f64, Error> {
launch()?;
stream.synchronize()?;
let start = Instant::now();
for _ in 0..20 {
launch()?;
}
stream.synchronize()?;
Ok(start.elapsed().as_secs_f64() * 1e3 / 20.0)
}
fn gb_per_s(bytes: usize, ms: f64) -> f64 {
bytes as f64 / 1e9 / (ms / 1e3)
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
// 1. Strided reads, from 2 GiB: room for stride 32, too big for any L2.
let big = DeviceBuffer::<f32>::zeroed(&stream, 32 * N)?;
let mut out = DeviceBuffer::<f32>::zeroed(&stream, N)?;
let launch = module.prepare_strided(LaunchConfig1D::new((N / 256) as u32, 256, 0))?;
let mut read = |stride| -> Result<(), Error> {
Ok(module.strided(&stream, &launch, &big, &mut out, stride)?)
};
time_ms(&stream, || read(1))?; // warm up the clocks
println!("each thread reads 1 float, neighbours `stride` floats apart");
for stride in [1u32, 2, 4, 8, 16, 32] {
let ms = time_ms(&stream, || read(stride))?;
let useful = gb_per_s(2 * N * 4, ms);
println!(" stride {stride:2} {ms:7.3} ms {useful:6.1} GB/s useful");
}
// 2. Transposes of a 4096 x 4096 matrix.
let values: Vec<f32> = (0..N).map(|i| (i % 1000) as f32).collect();
let input = DeviceBuffer::from_host(&stream, &values)?;
let blocks = (WIDTH / 32) as u32;
let grid = LaunchConfig2D::new((blocks, blocks), (32, 32), 0);
let naive = module.prepare_transpose_naive(grid)?;
let tiled = module.prepare_transpose_tiled(grid)?;
let ms_naive = time_ms(&stream, || {
Ok(module.transpose_naive(&stream, &naive, &input, &mut out)?)
})?;
let ms_tiled = time_ms(&stream, || {
Ok(module.transpose_tiled(&stream, &tiled, &input, &mut out)?)
})?;
let gb_naive = gb_per_s(2 * N * 4, ms_naive);
let gb_tiled = gb_per_s(2 * N * 4, ms_tiled);
println!("transpose of a {WIDTH} x {WIDTH} matrix");
println!(" naive {ms_naive:6.2} ms {gb_naive:6.1} GB/s");
println!(" tiled and padded {ms_tiled:6.2} ms {gb_tiled:6.1} GB/s");
let result = out.to_host_vec(&stream)?;
let correct = (0..WIDTH)
.all(|y| (0..WIDTH).all(|x| result[x * WIDTH + y] == values[y * WIDTH + x]));
println!("tiled transpose correct: {}", if correct { "yes" } else { "no" });
// 3. A copy of 64 MiB, 1 float and 4 floats per thread, and by a grid-stride loop.
let quads: Vec<Float4> = values
.chunks_exact(4)
.map(|c| Float4([c[0], c[1], c[2], c[3]]))
.collect();
let input4 = DeviceBuffer::from_host(&stream, &quads)?;
let mut out4 = DeviceBuffer::from_host(&stream, &vec![Float4([0.0; 4]); N / 4])?;
let one = module.prepare_copy1(LaunchConfig1D::new((N / 256) as u32, 256, 0))?;
let four = module.prepare_copy4(LaunchConfig1D::new((N / 1024) as u32, 256, 0))?;
let ms1 = time_ms(&stream, || Ok(module.copy1(&stream, &one, &input, &mut out)?))?;
let ms4 = time_ms(&stream, || Ok(module.copy4(&stream, &four, &input4, &mut out4)?))?;
let copied = out4.to_host_vec(&stream)? == quads;
let gb1 = gb_per_s(2 * N * 4, ms1);
let gb4 = gb_per_s(2 * N * 4, ms4);
println!("copy of 64 MiB");
println!(" 1 float per thread {ms1:6.2} ms {gb1:6.1} GB/s");
println!(" 4 floats per thread {ms4:6.2} ms {gb4:6.1} GB/s");
let grid = module.prepare_copy_grid_stride(LaunchConfig1D::new(64, 256, 0))?;
module.copy_grid_stride(&stream, &grid, &input, &mut out)?;
let strided = out.to_host_vec(&stream)? == values;
let copies = if copied && strided { "yes" } else { "no" };
println!("copies correct: {copies}");
// 4. A coefficient from constant memory, read by every thread.
let coeffs: [f32; 16] = std::array::from_fn(|k| k as f32 * 0.5);
module.set_coeffs(&stream, &coeffs)?; // fill it by name
let scale = module.prepare_scale(LaunchConfig1D::new((N / 256) as u32, 256, 0))?;
module.scale(&stream, &scale, &input, &mut out, 3)?;
let result = out.to_host_vec(&stream)?;
let correct = result.iter().zip(&values).all(|(r, v)| *r == v * 1.5);
let verdict = if correct { "yes" } else { "no" };
println!("constant memory correct: {verdict}");
Ok(())
}// Chapter 7: coalescing, vector loads, and a matrix transpose in shared memory, measured.
// Build: nvcc -arch=native memory.cu -o memory
#include <chrono>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cuda_runtime.h>
const int TILE = 32;
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// 1. Thread i reads element i * stride, so neighboring threads read `stride` floats apart.
__global__ void strided(const float* in, float* out, int n, int stride)
{
    int i = blockIdx.x * blockDim.x + threadIdx.x;
    if (i < n) {
        out[i] = in[(size_t)i * stride];
    }
}
__global__ void fill(float* x, size_t n)
{
size_t i = (size_t)blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
x[i] = float(i % 1000);
}
}
// 2. A copy, 1 float or 4 floats per thread.
__global__ void copy1(const float* in, float* out, int n)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
out[i] = in[i];
}
}
__global__ void copy4(const float4* in, float4* out, int n4)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n4) {
out[i] = in[i];
}
}
// 3. Transposes of a width x width matrix, 1 thread per element, blocks of 32 x 32.
__global__ void transposeNaive(const float* in, float* out, int width)
{
    int x = blockIdx.x * TILE + threadIdx.x;
    int y = blockIdx.y * TILE + threadIdx.y;
    out[x * width + y] = in[y * width + x];
}
template <int PAD>
__global__ void transposeTiled(const float* in, float* out, int width)
{
    __shared__ float tile[TILE][TILE + PAD];

    int x = blockIdx.x * TILE + threadIdx.x;
    int y = blockIdx.y * TILE + threadIdx.y;
    tile[threadIdx.y][threadIdx.x] = in[y * width + x];
    __syncthreads();

    x = blockIdx.y * TILE + threadIdx.x;
    y = blockIdx.x * TILE + threadIdx.y;
    out[y * width + x] = tile[threadIdx.x][threadIdx.y];
}
// Average time of 20 runs of `launch`, in milliseconds, after 1 warm-up run.
template <typename F>
double timeKernel(F launch)
{
launch();
check(cudaDeviceSynchronize());
double t0 = nowMs();
for (int r = 0; r < 20; ++r) {
launch();
}
check(cudaGetLastError());
check(cudaDeviceSynchronize());
return (nowMs() - t0) / 20;
}
double gbps(double bytes, double ms)
{
return bytes / 1e9 / (ms / 1e3);
}
void coalescing(const float* in, float* out)
{
const int n = 16 << 20; // 16,777,216 threads, 64 MiB each way
std::printf("each thread reads 1 float, neighbours `stride` floats apart\n");
for (int stride = 1; stride <= 32; stride *= 2) {
double ms = timeKernel([&] { strided<<<n / 256, 256>>>(in, out, n, stride); });
double useful = 2.0 * n * sizeof(float);
std::printf(" stride %2d %7.3f ms %6.1f GB/s useful\n", stride, ms,
gbps(useful, ms));
}
}
void vectors(const float* in, float* out, int n)
{
double ms1 = timeKernel([&] { copy1<<<n / 256, 256>>>(in, out, n); });
double ms4 = timeKernel([&] {
copy4<<<n / 4 / 256, 256>>>((const float4*)in, (float4*)out, n / 4);
});
std::printf("copy of %d MiB\n", int(n * sizeof(float) >> 20));
double bytes = 2.0 * n * sizeof(float);
std::printf(" 1 float per thread %6.2f ms %6.1f GB/s\n", ms1, gbps(bytes, ms1));
std::printf(" 4 floats per thread %6.2f ms %6.1f GB/s\n", ms4, gbps(bytes, ms4));
}
void transposes(const float* in, float* out, int width)
{
dim3 grid(width / TILE, width / TILE), block(TILE, TILE);
double bytes = 2.0 * width * width * sizeof(float);
int n = width * width;
double copy = timeKernel([&] { copy1<<<n / 256, 256>>>(in, out, n); });
double naive = timeKernel([&] { transposeNaive<<<grid, block>>>(in, out, width); });
double tiled = timeKernel([&] { transposeTiled<0><<<grid, block>>>(in, out, width); });
double padded = timeKernel([&] { transposeTiled<1><<<grid, block>>>(in, out, width); });
std::printf("transpose of a %d x %d matrix\n", width, width);
std::printf(" copy, for reference %6.2f ms %6.1f GB/s\n", copy, gbps(bytes, copy));
const char* names[] = {"naive", "tiled", "tiled and padded"};
double times[] = {naive, tiled, padded};
for (int k = 0; k < 3; ++k) {
double gb = gbps(bytes, times[k]);
std::printf(" %-20s %6.2f ms %6.1f GB/s\n", names[k], times[k], gb);
}
}
bool isTranspose(const float* in, float* out, int width)
{
dim3 grid(width / TILE, width / TILE), block(TILE, TILE);
transposeTiled<1><<<grid, block>>>(in, out, width);
std::vector<float> a(width * width), b(width * width);
check(cudaMemcpy(a.data(), in, a.size() * sizeof(float), cudaMemcpyDeviceToHost));
check(cudaMemcpy(b.data(), out, b.size() * sizeof(float), cudaMemcpyDeviceToHost));
for (int y = 0; y < width; ++y) {
for (int x = 0; x < width; ++x) {
if (b[x * width + y] != a[y * width + x]) return false;
}
}
return true;
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %d SMs, L2 cache %d MiB\n",
prop.name, prop.multiProcessorCount, prop.l2CacheSize >> 20);
const int width = 4096;
const int n = width * width; // 16,777,216 floats, 64 MiB
const size_t inLen = (size_t)32 * n; // 2 GiB: room for stride 32, beyond any L2
float *in, *out;
check(cudaMalloc(&in, inLen * sizeof(float)));
check(cudaMalloc(&out, n * sizeof(float)));
fill<<<(inLen + 255) / 256, 256>>>(in, inLen);
for (int k = 0; k < 10; ++k) { // warm up: clocks rise under sustained load
timeKernel([&] { copy1<<<n / 256, 256>>>(in, out, n); });
}
coalescing(in, out);
vectors(in, out, n);
transposes(in, out, width);
bool correct = isTranspose(in, out, width);
std::printf("tiled transpose correct: %s\n", correct ? "yes" : "no");
check(cudaFree(in));
check(cudaFree(out));
}
Common mistakes
- Indexing 2-D data with
threadIdx.xdown a column. Neighboring threads are thenwidthfloats apart. LetthreadIdx.xmove along rows. - Measuring a small array. When the data fits in the L2 cache, the measurement reflects the cache, not the memory: the Thor reported 432 GB/s, above the 273 GB/s peak of its memory, for a 16 MiB test.
- Timing before the clocks have risen. Run the kernel for a fraction of a second before timing it.
- A 32 × 32 shared tile read by columns. Pad it to 32 × 33.
- A missing barrier between filling a tile and reading it. We measured the consequences in Chapter 5.
- Casting an unaligned pointer to
float4*. Only offsets that are multiples of 4 floats are safe. - Constant memory indexed differently by each thread. The accesses are serialized.
Summary
- Effective bandwidth, the bytes a task requires divided by its running time, compared with a plain copy, shows how much a memory-bound kernel has left to gain.
- Global memory transfers 32-byte sectors. When neighboring threads access neighboring addresses, every byte is used; at a stride of 8 floats or more, a warp moves 8 times the bytes it needs, and the measured useful bandwidth fell 3 to 5 times.
- A tile in shared memory allows a transpose to read and write global memory only along rows; a barrier separates filling the tile from reading it.
- Shared memory has 32 banks. One additional column in a 32 × 32 tile removes the 32-way conflict of a column read. Tiling and padding made the transpose 2.7 times as fast on the Orin NX.
float4loads moved the same bytes with a quarter of the instructions and were 12 to 19% faster.- In Rust, a write to another thread’s index requires
unsafeand a stated permutation argument.
Chapter 8 combines these techniques in reductions, scans and histograms that run close to the speed of a copy.
Exercises
- A warp reads
floats at stride 3. How many 32-byte sectors does it fetch, and what fraction of the bytes is used? - A kernel reads 1 GB and writes 1 GB in 25 ms on a GPU whose copy reaches 90 GB/s. What is its effective bandwidth, and how far is it from the copy?
- Run
memoryon your GPU. Use the sector model to predict the useful bandwidth at stride 8 from your stride-1 result, and compare. - Rewrite
transposeNaiveso that it reads down columns and writes rows. Is it faster or slower than the original, and why? - A tile is
double tile[32][32]. Adoubletakes 2 banks. Which padding removes the conflict of a column read? - Change
copy4to handle anyn, including the last \(n \bmod 4\) elements. - In the Rust
transpose_tiled, whichSAFETYclaim would break if the tile were filled after the barrier instead of before?
Sources and further reading
- NVIDIA, CUDA C++ Best Practices Guide, “Coalesced Access to Global Memory”, “Shared Memory” and “Effective Bandwidth Calculation”: https://docs.nvidia.com/cuda/cuda-c-best-practices-guide/
- NVIDIA, CUDA C++ Programming Guide, “Device Memory Accesses”: https://docs.nvidia.com/cuda/cuda-c-programming-guide/
- M. Harris, “An Efficient Matrix Transpose in CUDA C/C++”, NVIDIA Technical Blog, 2013.
- D. Kirk and W. Hwu, Programming Massively Parallel Processors, 4th ed., Morgan Kaufmann, 2022, chapters on memory and tiling.
Chapter 8: Reduction, Scan & Histogram
Many computations end by combining a large number of values into a small result: the total of an array, its largest element, the running total at every position, or the number of elements that fall into each of several bins. These are the reduction, scan and histogram patterns. In Chapter 5 we wrote a tree sum in shared memory and a histogram with atomic counters, and we used them to study barriers and atomic operations. Both kernels produced correct results, but both ran far below the bandwidth of the memory that supplied their data.
In this chapter, we develop a sum, a scan and a histogram that run close to the memory bandwidth of the GPU. We use the tools of Chapter 7: effective bandwidth as the measure of a kernel, the grid-stride loop, and wide loads. The sum is developed in 4 stages, and each stage removes one source of overhead. The scan reuses the same building blocks in a different arrangement. The histogram returns to the kernel of Chapter 5, and its measurements show that its speed was limited by its loads rather than by contention between atomic operations. Every kernel is given in CUDA C++ and in Rust.
This chapter covers
- reductions, and the difference between the work of a computation and its number of steps
- the accuracy of a float sum computed sequentially and computed as a tree
- a tree sum in shared memory, thread coarsening, and warp shuffles, each measured
- inclusive and exclusive scans within a warp, within a block, and across many blocks
- a histogram that reads 16 bytes per load
- results that are identical from run to run
The code of the chapter is in
code/ch08_reduction/
for C++ and in
code/oxide/ch08_reduce/
for Rust. The measurements in this chapter come from 2 integrated GPUs: a Jetson Orin NX (8 SMs,
102 GB/s) and a Jetson AGX Thor (20 SMs, 273 GB/s).
8.1 Background
8.1.1 Reduction operators
A reduction derives a single value from \(n\) values by repeatedly applying a binary operator. A sum uses \(+\), a maximum uses \(\max\), and a count of the elements that satisfy a condition uses \(+\) over values of 0 and 1. A sequential program computes a reduction by walking the array from one end to the other and combining each element with the result so far.
A parallel program must combine the values in a different order. It adds them in pairs, then adds the pairs, and so on. The result is unchanged only if the operator is associative, that is, if \((a + b) + c = a + (b + c)\) for any 3 values. Integer addition, maximum and minimum are associative. Floating-point addition is associative only approximately, because every addition rounds its result and a different grouping rounds at different places (Chapter 5, section 5.6). A float sum computed in pairs is therefore a slightly different sum from the sequential one. As we will see in section 8.2, it is usually the more accurate of the 2.
8.1.2 Work and steps
Two quantities describe the cost of a parallel computation. The work of a computation is the number of operations it performs. Its steps, also called its depth, is the length of the longest chain of operations in which each operation needs the result of the one before. Given enough threads, the work determines the energy that the computation consumes, and the number of steps determines its time.
Consider the 8 values 3, 1, 4, 1, 5, 9, 2, 6. Added sequentially, they produce the running sums 3, 4, 8, 9, 14, 23, 25, 31. Each addition needs the previous running sum, so the computation performs 7 additions in 7 steps. Added in pairs, the values become 4, 5, 14, 8; these become 9 and 22; and these become 31. The 4 additions of the first level are independent of each other, and so are the 2 additions of the second level. The tree therefore performs the same 7 additions in 3 steps (figure 8.1).
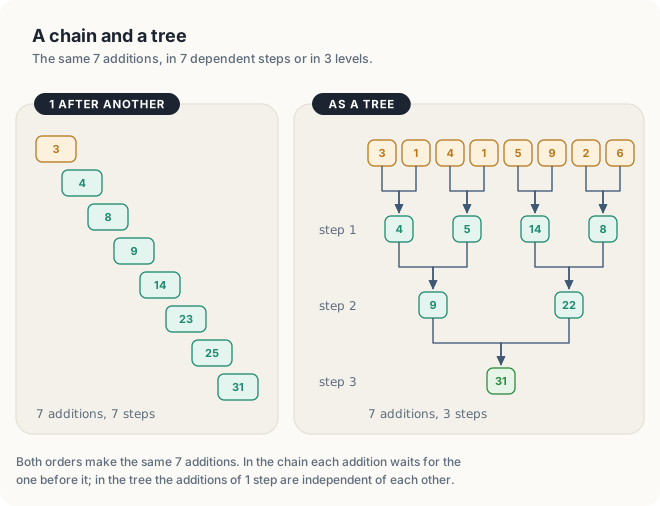
In general, both orders perform \(n - 1\) additions. Each level of the tree halves the number of values, so a tree over \(n\) values has \(\log_2 n\) levels, while the sequential chain has \(n - 1\) steps. For the \(n\) = 67,108,864 values summed in this chapter, the chain is 67,108,863 steps long and the tree 26 steps, because \(2^{26}\) = 67,108,864.
8.1.3 The bandwidth limit of a sum
A sum performs 1 addition for every 4-byte float that it reads, so its arithmetic intensity is 0.25 FLOP per byte. The ridge points of Chapter 2 lie between 10 and 114 FLOP per byte. A sum is therefore memory-bound on every GPU of that table, by a factor of 40 or more, and the shortest time in which it can run is the time the memory needs to deliver the array once: the size of the array divided by the memory bandwidth.
| GPU | Bandwidth | 256 MiB read once |
|---|---|---|
| Jetson Orin NX 16 GB | 102 GB/s | 2.63 ms |
| Jetson AGX Thor | 273 GB/s | 0.98 ms |
| DGX Spark (GB10) | 273 GB/s | 0.98 ms |
| GeForce RTX 4090 | 1,008 GB/s | 0.27 ms |
| GeForce RTX 5090 | 1,792 GB/s | 0.15 ms |
| A100 SXM 80 GB | 2,039 GB/s | 0.13 ms |
| H100 SXM | 3,350 GB/s | 0.08 ms |
For example, 256 MiB is 268,435,456 bytes, and at 102 GB/s the array takes 268,435,456 / (102 × 109) s = 2.63 ms to read. As in Chapter 7, we judge each kernel of this chapter by the bytes it must read and write, divided by its time, and compare the result with the bandwidth in the table.
8.2 Accuracy of a sequential float sum
The test data of the chapter is 67,108,864 floats spread evenly between 0 and 1, generated on the
host. Their exact sum, computed in double precision, is 33,557,630.3. When the same values are
added sequentially into a float on the CPU, the result is 16,777,216.0, half of the correct
answer.
The reason lies in the precision of a float, which holds 24 significant bits. Below 224 = 16,777,216, consecutive floats are at most 1 apart. Between 224 and 225, they are 2 apart, so a float in that range can hold only even numbers. When a value below 1 is added to 16,777,216, the exact result is closer to 16,777,216 than to 16,777,218, and rounding returns 16,777,216. Once the running sum reaches 224, which happens about halfway through the array, no further addition changes it (figure 8.2).
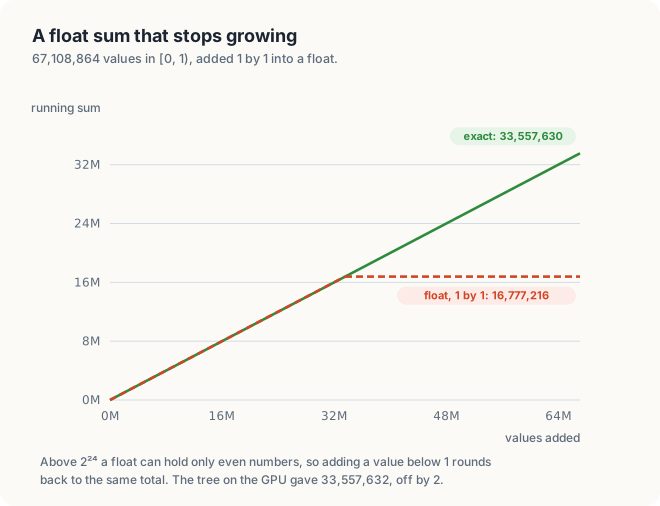
A reduction tree does not have this problem. In the GPU sums of this chapter, each thread first adds 256 values into a register, which produces a total near 128. From then on, totals of similar size are added to each other, so no addition combines a very large number with a very small one. The GPU sums of section 8.6 produced 33,557,632.0. Near 33.5 million, consecutive floats are 4 apart, and 33,557,632 is the float nearest to the exact 33,557,630.3. It is the most accurate result that a float can hold.
A long float sum computed sequentially loses the small values. A tree adds values of similar size and keeps them.
8.3 A tree in shared memory
The first GPU sum is the tree of Chapter 5, section 5.3. Each block of 256 threads loads 256 values into shared memory. At strides 128, 64, …, 1, the lower half of the active threads adds the values of the upper half into its own slots. The halving requires a block size that is a power of 2, so that every level splits evenly; 128, 256 and 512 are the usual choices. A barrier separates the levels, because each level reads values that other threads wrote in the level before.
Listing 8.1 A tree sum per block, 1 element per thread. code/oxide/ch08_reduce/src/main.rs code/ch08_reduction/reduce.cu
mod kernels {
    // ...
    /// 1. A tree in shared memory, 1 element per thread.
    #[kernel]
    #[launch_contract(domain = 1, block = (256, 1, 1))]
    pub fn sum_tree(input: &[f32], mut partial: DisjointSlice<f32>) {
        static mut S: SharedArray<f32, 256> = SharedArray::UNINIT;
        let t = thread::threadIdx_x() as usize;
        let i = thread::index_1d().get();

        let value = if i < input.len() { input[i] } else { 0.0 };
        // SAFETY: each thread writes only its own slot, before the first barrier.
        unsafe { S[t] = value };

        let mut step: usize = 0;
        #[unroll]
        while step < 8 {
            let stride = (BLOCK as usize / 2) >> step; // 128, 64, ... 1
            thread::sync_threads();
            if t < stride {
                // SAFETY: between 2 barriers thread t alone writes slot t, and it reads
                // slot t + stride, which no thread writes at this stride.
                unsafe { S[t] += S[t + stride] };
            }
            step += 1;
        }

        if t == 0 {
            // SAFETY: only thread 0 of each block writes, at its own block number.
            unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = S[0] };
        }
    }
    // ...
}
// 1. A tree in shared memory, 1 element per thread.
__global__ void sumTree(const float* in, float* partial, int n)
{
__shared__ float s[BLOCK];
int i = blockIdx.x * BLOCK + threadIdx.x;
s[threadIdx.x] = i < n ? in[i] : 0.0f;
for (int stride = BLOCK / 2; stride > 0; stride /= 2) {
__syncthreads();
if (threadIdx.x < stride) {
s[threadIdx.x] += s[threadIdx.x + stride];
}
}
if (threadIdx.x == 0) {
partial[blockIdx.x] = s[0];
}
}
Each block writes 1 partial sum, the total of its own values, to partial[blockIdx.x].
Because blocks cannot wait for each other inside a kernel (Chapter 5, section 5.4), the partial
sums are added by a second launch of 1 block of 256 threads. For 67,108,864 values, the first
launch writes 262,144 partial sums.
sum of 67108864 floats (256 MiB), average of 20 runs # on a Jetson Orin NX
tree, 1 per thread 10.36 ms 25.9 GB/s sum 33557628.0
The kernel reached 25.9 GB/s, a quarter of the first GPU’s 102 GB/s; on the second GPU it reached 88.3 GB/s, a third of 273 GB/s. The cause is the ratio of loads to barriers. We let each thread load 1 float and then takes part in 8 levels separated by 8 barriers. In the last levels, almost all of the threads of a block wait for a few others: at stride 1, 1 thread adds and 255 threads wait. While its threads are busy with the tree, a block issues no loads, so the memory is idle for much of the time.
8.4 Thread coarsening
Thread coarsening assigns many elements to each thread instead of 1. Each thread first sums its elements in a register, and the block’s tree then combines the 256 register sums once, at the end. The elements are assigned by the grid-stride loop of Chapter 7, section 7.3: thread \(i\) of a grid of \(s\) threads reads elements \(i\), \(i + s\), \(i + 2s\), and so on.
The program launches 1,024 blocks of 256 threads, so \(s\) = 262,144 threads, and each thread adds 67,108,864 / 262,144 = 256 elements (figure 8.3). 1,024 blocks are several times as many as either GPU can hold at once, so no SM runs out of work. They are also few enough that the second launch adds only 1,024 partial sums.
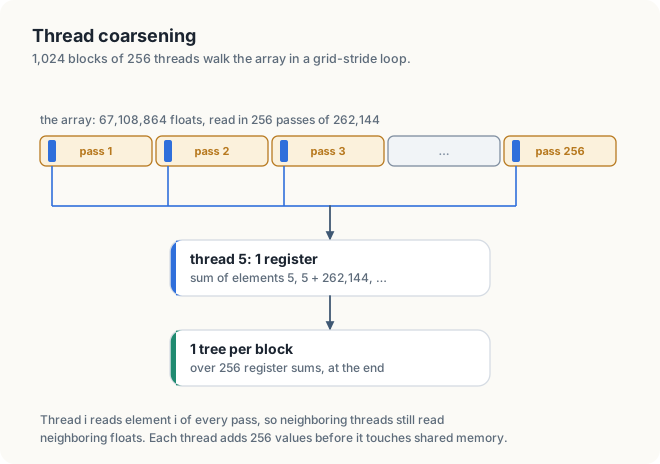
Listing 8.2 The coarsened sum.
mod kernels {
// ...
/// 2. Each thread first sums many elements in a register, then 1 tree per block.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_coarse(input: &[f32], mut partial: DisjointSlice<f32>) {
static mut S: SharedArray<f32, 256> = SharedArray::UNINIT;
let t = thread::threadIdx_x() as usize;
let grid = (thread::gridDim_x() * BLOCK) as usize;
let mut sum = 0.0;
let mut i = thread::index_1d().get();
while i < input.len() {
sum += input[i];
i += grid;
}
// SAFETY: each thread writes only its own slot, before the first barrier.
unsafe { S[t] = sum };
let mut step: usize = 0;
#[unroll]
while step < 8 {
let stride = (BLOCK as usize / 2) >> step; // 128, 64, ... 1
thread::sync_threads();
if t < stride {
// SAFETY: between 2 barriers thread t alone writes slot t, and it reads
// slot t + stride, which no thread writes at this stride.
unsafe { S[t] += S[t + stride] };
}
step += 1;
}
if t == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = S[0] };
}
}
// ...
}// 2. Each thread first sums many elements in a register, then 1 tree per block.
__global__ void sumCoarse(const float* in, float* partial, int n)
{
__shared__ float s[BLOCK];
float sum = 0.0f;
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n; i += gridDim.x * BLOCK) {
sum += in[i];
}
s[threadIdx.x] = sum;
for (int stride = BLOCK / 2; stride > 0; stride /= 2) {
__syncthreads();
if (threadIdx.x < stride) {
s[threadIdx.x] += s[threadIdx.x + stride];
}
}
if (threadIdx.x == 0) {
partial[blockIdx.x] = s[0];
}
}
In every pass of the loop, neighboring threads read neighboring floats, so the loads of each warp are coalesced. The loads of different passes do not depend on each other, so a thread can have several of them in flight while the memory serves them.
coarsened 4.19 ms 64.1 GB/s sum 33557632.0 # Orin NX
coarsened 1.32 ms 203.0 GB/s sum 33557632.0 # Thor
With 256 loads per tree instead of 1, the same kernel structure ran 2.5 times as fast on the first GPU and 2.3 times as fast on the second. The tree still costs 8 barriers per block, but a block now pays that cost once for 65,536 values instead of once for 256 values.
8.5 Warp shuffles
8.5.1 Shuffle instructions
A lane is the position of a thread within its warp, from 0 to 31; for a 1-D block it is
threadIdx.x % 32. A warp shuffle is an instruction with which the lanes of a warp read each
other’s registers, without shared memory and without a barrier. In
__shfl_down_sync(mask, v, d), every lane supplies its value v, and lane \(k\) receives the
value of lane \(k + d\). A lane for which \(k + d\) is above 31 receives its own value. The
mask names the lanes that take part, 0xffffffff for all 32, and each of these lanes must
execute the call. In Rust the same instruction is warp::shuffle_down_f32(v, d).
A warp is reduced with 5 shuffles. At offset 16, lanes 0 to 15 add the values of lanes 16 to 31. At offset 8, lanes 0 to 7 add the values of lanes 8 to 15, and so on down to offset 1, after which lane 0 holds the sum of all 32 values (figure 8.4). The other lanes hold partial sums that the program does not use. The number 5 is \(\log_2 32\), the depth of a tree over 32 values.
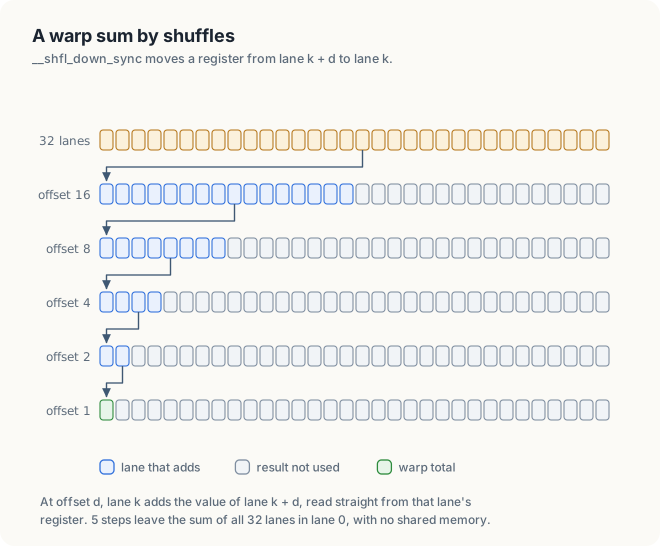
8.5.2 A block reduction with warp shuffles
A block of 256 threads consists of 8 warps. Each warp reduces its 32 values by shuffles, and lane 0 of each warp writes the warp’s total into 1 of 8 slots in shared memory. A single barrier makes the 8 totals visible to all threads, and warp 0 then reduces them by shuffles (figure 8.5). The tree of section 8.3 needed 8 barriers for the same 256 values; this version needs 1.
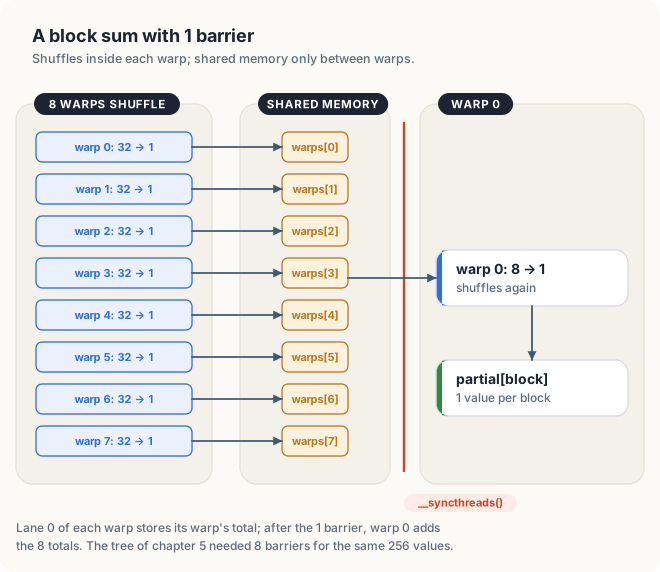
Listing 8.3 Warp sum, block sum, and the shuffle kernel.
mod kernels {
// ...
#[device]
fn warp_sum(mut v: f32) -> f32 {
for offset in [16, 8, 4, 2, 1] {
v += warp::shuffle_down_f32(v, offset);
}
v
}
// ...
}
mod kernels {
// ...
/// Each thread sums many elements, each warp shuffles, 1 barrier per block.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_shuffle(input: &[f32], mut partial: DisjointSlice<f32>) {
static mut WARPS: SharedArray<f32, 8> = SharedArray::UNINIT;
let stride = (thread::gridDim_x() * BLOCK) as usize;
let lane = warp::lane_id() as usize;
let warp = thread::threadIdx_x() as usize / 32;
let mut sum = 0.0;
let mut i = thread::index_1d().get();
while i < input.len() {
sum += input[i];
i += stride;
}
sum = warp_sum(sum);
if lane == 0 {
// SAFETY: lane 0 of each warp writes its own slot, before the barrier.
unsafe { WARPS[warp] = sum };
}
thread::sync_threads();
if warp == 0 {
// SAFETY: after the barrier the slots are only read.
sum = warp_sum(if lane < 8 { unsafe { WARPS[lane] } } else { 0.0 });
if lane == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = sum };
}
}
}
// ...
}// 3. Shuffles within each warp, and 1 barrier per block.
__device__ float warpSum(float v)
{
for (int offset = 16; offset > 0; offset /= 2) {
v += __shfl_down_sync(0xffffffff, v, offset);
}
return v; // the warp's total, in lane 0
}
__device__ float blockSum(float v)
{
__shared__ float warps[BLOCK / 32];
int lane = threadIdx.x % 32;
int warp = threadIdx.x / 32;
v = warpSum(v);
if (lane == 0) {
warps[warp] = v;
}
__syncthreads();
if (warp == 0) {
v = warpSum(lane < BLOCK / 32 ? warps[lane] : 0.0f);
}
return v; // the block's total, in thread 0
}
__global__ void sumShuffle(const float* in, float* partial, int n)
{
float sum = 0.0f;
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n; i += gridDim.x * BLOCK) {
sum += in[i];
}
sum = blockSum(sum);
if (threadIdx.x == 0) {
partial[blockIdx.x] = sum;
}
}
In blockSum, lanes 8 to 31 of warp 0 contribute 0, the identity value of addition, so the second
call of warpSum adds exactly the 8 warp totals. Only warp 0 makes this second call, and all 32 of
its lanes make it, as the mask requires.
The Rust kernel has the same structure. The attribute #[device] marks warp_sum as a function
that runs on the GPU and is called from kernels. Thread 0 of each block writes the block’s partial
sum at an index that is not the thread’s own. The write therefore uses get_unchecked_mut, with a
SAFETY comment, as the transpose of Chapter 7 did.
shuffles 4.17 ms 64.4 GB/s sum 33557632.0 # Orin NX
shuffles 1.31 ms 203.6 GB/s sum 33557632.0 # Thor
The shuffles made almost no difference: 64.4 GB/s against 64.1 GB/s on the first GPU, and 203.6 GB/s against 203.0 GB/s on the second. After coarsening, a block runs its tree once per 65,536 values, so the 8 barriers had become a small part of its time, and removing 7 of them saved little. Shuffles are worthwhile where the combining step is frequent: in many short reductions, such as 1 per row of a matrix, and in the scans of section 8.7, which perform a shuffle-based scan in every block.
8.6 Vector loads and reproducible results
8.6.1 Vector loads with float4
The last stage replaces each float load with a float4 load, the 16-byte load of Chapter 7,
section 7.6. Each thread now adds 4 floats per load instruction, and the loop runs a quarter as
many iterations.
Listing 8.4 The shuffle sum with 16-byte loads.
mod kernels {
// ...
/// The sum of `v` over the 256 threads of a block, returned to thread 0.
#[device]
fn block_sum(v: f32) -> f32 {
static mut WARPS: SharedArray<f32, 8> = SharedArray::UNINIT;
let lane = warp::lane_id() as usize;
let warp = thread::threadIdx_x() as usize / 32;
let v = warp_sum(v);
if lane == 0 {
// SAFETY: lane 0 of each warp writes its own slot, before the barrier.
unsafe { WARPS[warp] = v };
}
thread::sync_threads();
// SAFETY: after the barrier the slots are only read.
let w = if lane < 8 { unsafe { WARPS[lane] } } else { 0.0 };
if warp == 0 { warp_sum(w) } else { 0.0 }
}
// ...
}
mod kernels {
// ...
/// 4. The shuffle sum, loading 4 floats per instruction.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_shuffle4(input: &[f32], mut partial: DisjointSlice<f32>) {
let quads = vector::as_vectors::<F32x4>(input).unwrap_or(&[]);
let grid = (thread::gridDim_x() * BLOCK) as usize;
let mut sum = 0.0;
let mut i = thread::index_1d().get();
while i < quads.len() {
let [x, y, z, w] = quads[i].to_array();
sum += x + y + z + w;
i += grid;
}
let sum = block_sum(sum);
if thread::threadIdx_x() == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = sum };
}
}
// ...
}// 4. The same, loading 4 floats per instruction; n4 is the number of float4s.
__global__ void sumShuffle4(const float4* in, float* partial, int n4)
{
float sum = 0.0f;
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n4; i += gridDim.x * BLOCK) {
float4 v = in[i];
sum += v.x + v.y + v.z + v.w;
}
sum = blockSum(sum);
if (threadIdx.x == 0) {
partial[blockIdx.x] = sum;
}
}
Listing 8.5 times the 4 stages. Each run consists of 2 launches: the stage itself, and 1 block of
sumShuffle over its partial sums.
Listing 8.5 Timing the 4 stages.
/// Prints a stage's time and bandwidth over `n` floats, and the sum it left in `total`.
fn report(
stream: &Arc<CudaStream>,
name: &str,
ms: f64,
n: usize,
total: &DeviceBuffer<f32>,
) -> Result<(), Error> {
let sum = total.to_host_vec(stream)?[0];
let gb = (n * 4) as f64 / 1e9 / (ms / 1e3);
println!(" {name:22} {ms:6.2} ms {gb:6.1} GB/s sum {sum:.1}");
Ok(())
}
/// Times the 4 stages of the sum. A run is the stage, then 1 block over its partial sums.
fn sums(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
input: &DeviceBuffer<f32>,
) -> Result<(), Error> {
let n = input.len();
let mut leaves = DeviceBuffer::<f32>::zeroed(stream, n / BLOCK as usize)?;
let mut partial = DeviceBuffer::<f32>::zeroed(stream, GRID as usize)?;
let mut total = DeviceBuffer::<f32>::zeroed(stream, 1)?;
let full = LaunchConfig1D::new(GRID, BLOCK, 0);
let tree = module.prepare_sum_tree(LaunchConfig1D::new(n as u32 / BLOCK, BLOCK, 0))?;
let coarse = module.prepare_sum_coarse(full)?;
let shuffle = module.prepare_sum_shuffle(full)?;
let shuffle4 = module.prepare_sum_shuffle4(full)?;
let last = module.prepare_sum_shuffle(LaunchConfig1D::new(1, BLOCK, 0))?;
println!("sum of {n} floats, the 4 stages, average of 20 runs");
let ms = time_ms(stream, || {
module.sum_tree(stream, &tree, input, &mut leaves)?;
Ok(module.sum_shuffle(stream, &last, &leaves, &mut total)?)
})?;
report(stream, "tree, 1 per thread", ms, n, &total)?;
let ms = time_ms(stream, || {
module.sum_coarse(stream, &coarse, input, &mut partial)?;
Ok(module.sum_shuffle(stream, &last, &partial, &mut total)?)
})?;
report(stream, "coarsened", ms, n, &total)?;
let ms = time_ms(stream, || {
module.sum_shuffle(stream, &shuffle, input, &mut partial)?;
Ok(module.sum_shuffle(stream, &last, &partial, &mut total)?)
})?;
report(stream, "shuffles", ms, n, &total)?;
let ms = time_ms(stream, || {
module.sum_shuffle4(stream, &shuffle4, input, &mut partial)?;
Ok(module.sum_shuffle(stream, &last, &partial, &mut total)?)
})?;
report(stream, "shuffles, F32x4", ms, n, &total)
}void sums(const float* in, float* partial, float* total, int n)
{
double bytes = n * sizeof(float);
std::printf("sum of %d floats (%d MiB), average of 20 runs\n", n, int(bytes) >> 20);
auto finish = [&](int blocks) { sumShuffle<<<1, BLOCK>>>(partial, total, blocks); };
auto report = [&](const char* name, double ms) {
float t;
check(cudaMemcpy(&t, total, sizeof(float), cudaMemcpyDeviceToHost));
double gb = bytes / ms / 1e6;
std::printf(" %-22s %6.2f ms %6.1f GB/s sum %.1f\n", name, ms, gb, t);
};
report("tree, 1 per thread", timeKernel([&] {
sumTree<<<n / BLOCK, BLOCK>>>(in, partial, n);
finish(n / BLOCK);
}));
report("coarsened", timeKernel([&] {
sumCoarse<<<GRID, BLOCK>>>(in, partial, n);
finish(GRID);
}));
report("shuffles", timeKernel([&] {
sumShuffle<<<GRID, BLOCK>>>(in, partial, n);
finish(GRID);
}));
report("shuffles, float4", timeKernel([&] {
sumShuffle4<<<GRID, BLOCK>>>((const float4*)in, partial, n / 4);
finish(GRID);
}));
}
$ ./reduce # on a Jetson Orin NX
GPU: Orin, 8 SMs, L2 cache 2 MiB
sum of 67108864 floats (256 MiB), average of 20 runs
tree, 1 per thread 10.36 ms 25.9 GB/s sum 33557628.0
coarsened 4.19 ms 64.1 GB/s sum 33557632.0
shuffles 4.17 ms 64.4 GB/s sum 33557632.0
shuffles, float4 2.99 ms 89.7 GB/s sum 33557628.0
exact sum (double) 33557630.3
CPU, float, 1 by 1 16777216.0
GPU, shuffles, 5 runs 33557632.0 33557632.0 33557632.0 33557632.0 33557632.0
$ ./reduce # on a Jetson AGX Thor
GPU: NVIDIA Thor, 20 SMs, L2 cache 32 MiB
sum of 67108864 floats (256 MiB), average of 20 runs
tree, 1 per thread 3.04 ms 88.3 GB/s sum 33557628.0
coarsened 1.32 ms 203.0 GB/s sum 33557632.0
shuffles 1.32 ms 203.6 GB/s sum 33557632.0
shuffles, float4 1.02 ms 264.2 GB/s sum 33557628.0
$ cargo oxide run # on a Jetson Orin NX, then a Thor
sum of 67108864 floats, average of 20 runs
shuffles 4.13 ms 65.0 GB/s sum 33557632.0
shuffles 1.33 ms 201.2 GB/s sum 33557632.0
With float4 loads, the sum read its 256 MiB at 89.7 GB/s on the first GPU, 88% of its rated
102 GB/s, and at 264.2 GB/s on the second, 97% of its rated 273 GB/s (figure 8.6). Together, the 4
stages made the sum 3.5 times as fast on the first GPU and 3.0 times as fast on the second.
Section 8.1.3 predicted 2.63 ms and 0.98 ms at the full rated bandwidth, and the measured 2.99 ms
and 1.02 ms are close to both predictions. The Rust shuffle kernel matched the C++ shuffle
stage.
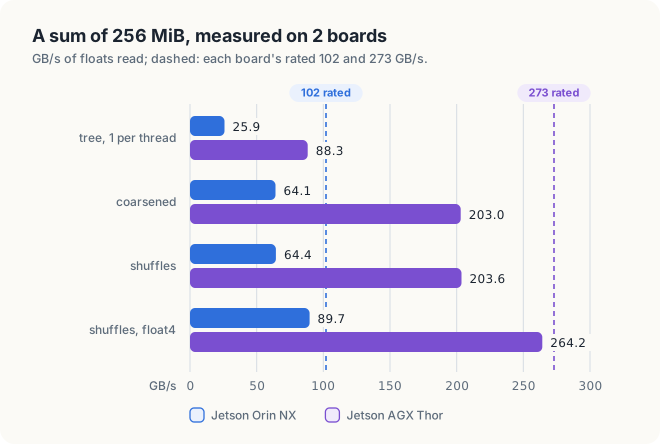
8.6.2 Reproducibility of the sum
The 5 runs of the shuffle sum printed the same value, 33,557,632.0, and the Rust kernel printed it
as well. The float sum by atomicAdd in Chapter 5 gave a different answer on each run, because
the threads added their values in whatever order they arrived. In a tree, the code determines the
order. Thread \(i\) always adds the same elements in the same order, each warp always shuffles
the same pairs, and the second launch always adds the 1,024 partial sums in the same way. The same
order of additions produces the same roundings and therefore the same bits.
Note, however, that the order depends on the shape of the launch. The tree with one element per
thread and the float4 version group the values differently from the coarsened versions, and
both printed 33,557,628.0, 1 float step lower. A program that must reproduce its results across
machines must therefore fix its block size and grid size, not only its algorithm.
A sum runs with 512 blocks instead of 1,024. Will its answer match the 1,024-block answer bit for bit?
Not necessarily. With 512 blocks, thread \(i\) reads elements \(i\), \(i + 131{,}072\), …, a different set from the 1,024-block grid, so the partial sums round differently. The answer is still the same on every run with 512 blocks.
8.7 Scan
8.7.1 Inclusive and exclusive scan
An inclusive scan of an array \(a\) computes, at every position \(i\), the sum of elements 0 to \(i\): \(y_i = a_0 + a_1 + \cdots + a_i\). An exclusive scan leaves out element \(i\) itself: \(y_i = a_0 + \cdots + a_{i-1}\), with \(y_0 = 0\). Scans are also called prefix sums, because \(y_i\) is the sum of the prefix of the array that ends at \(i\).
| \(i\) | 0 | 1 | 2 | 3 | 4 | 5 | 6 | 7 |
|---|---|---|---|---|---|---|---|---|
| \(a_i\) | 3 | 1 | 4 | 1 | 5 | 9 | 2 | 6 |
| inclusive | 3 | 4 | 8 | 9 | 14 | 23 | 25 | 31 |
| exclusive | 0 | 3 | 4 | 8 | 9 | 14 | 23 | 25 |
A scan gives each element the position at which it is stored when selected elements are packed together. For this reason, it is the core of stream compaction, which keeps the elements that pass a test and stores them contiguously in a shorter array. For example, to keep the values above 3 from 3, 1, 4, 1, 5, 9, 2, 6, we first set a flag of 1 for each value above 3, which gives 0, 0, 1, 0, 1, 1, 0, 1. The exclusive scan of the flags is 0, 0, 0, 1, 1, 2, 3, 3. Each kept value is then written to the position given by its scan value: 4 to position 0, 5 to position 1, 9 to position 2 and 6 to position 3. The output is 4, 5, 9, 6, and its length, 4, is the last scan value plus the last flag.
Because every thread computes its output position independently, all threads can write at the same time. Radix sort, the allocation of outputs of varying size, and sparse matrix formats use scans in the same way.
8.7.2 Warp-level scan
A scan within a warp uses the opposite shuffle, __shfl_up_sync, in which lane \(k\) receives
the value of lane \(k - d\). At offset 1, every lane from lane 1 upwards adds the value of the
lane to its left. Each lane then holds the sum of 2 values, and at offset 2 it adds the sum of the
2 values before those; at offset 4, it adds the sum of the 4 values before those. After offsets
1, 2 and 4, each of 8 lanes holds the sum of all lanes up to and including its own (figure 8.7).
A warp of 32 lanes needs 5 offsets, 1 to 16.
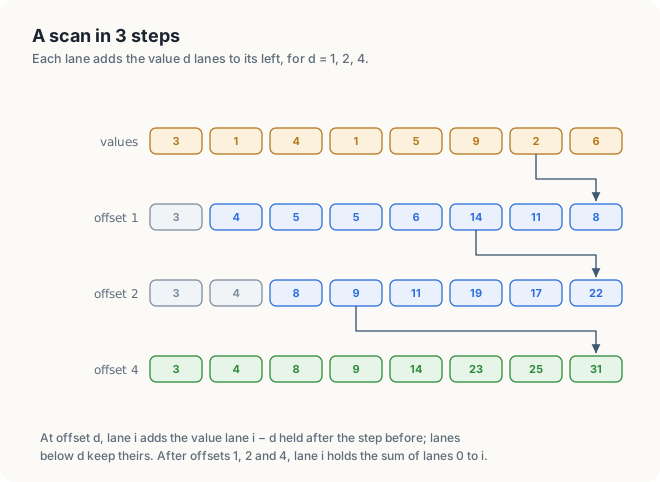
Animation 1 shows the values moving at each of the 3 offsets.
Listing 8.6 A warp scan.
mod kernels {
// ...
#[device]
fn warp_scan(mut v: u32) -> u32 {
let lane = warp::lane_id();
for offset in [1, 2, 4, 8, 16] {
let left = warp::shuffle_up_sync(u32::MAX, v, offset);
if lane >= offset {
v += left;
}
}
v
}
// ...
}// 5. An inclusive scan, 4 elements per thread, 1,024 per block.
__device__ unsigned warpScan(unsigned v)
{
int lane = threadIdx.x % 32;
for (int offset = 1; offset < 32; offset *= 2) {
unsigned left = __shfl_up_sync(0xffffffff, v, offset);
if (lane >= offset) {
v += left;
}
}
return v; // the sum of lanes 0 to `lane`
}
This form of scan performs more work than a sequential scan. At offset \(d\), \(32 - d\) lanes perform an addition, so a warp performs 31 + 30 + 28 + 24 + 16 = 129 additions where a sequential chain needs 31. Within a warp, the extra additions add no time: the 32 lanes execute every step together whether or not a lane adds, and 5 steps take less time than 31. For large scans in shared memory, the work-efficient algorithm due to Blelloch performs \(2(n - 1)\) additions in \(2 \log_2 n\) steps instead; Exercise 6 traces it.
8.7.3 Block-level scan
The kernel scanBlocks scans 1,024 values per block of 256 threads, 4 values per thread, in 4
phases:
- We let each thread load its 4 consecutive values with a single 16-byte
uint4load and scan them in its registers. - The threads scan their 4-value totals with
warpScan. Lane 31 of each warp then holds the total of its warp and writes it to shared memory. - After a barrier, warp 0 scans the 8 warp totals.
- After a second barrier, each thread adds 2 offsets to its 4 values: the total of the warps before its own, and the total of the lanes before it in its own warp.
Listing 8.7 A scan of 1,024 values per block.
mod kernels {
// ...
/// An inclusive scan of 1,024 values per block, 4 per thread.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scan_blocks(
input: &[u32],
mut out: DisjointSlice<u32>,
mut sums: DisjointSlice<u32>,
) {
static mut WARPS: SharedArray<u32, 8> = SharedArray::UNINIT;
let first = thread::index_1d().get() * 4;
let lane = warp::lane_id() as usize;
let warp = thread::threadIdx_x() as usize / 32;
let mut a = [0u32; 4];
let mut own = 0;
for k in 0..4 {
if first + k < input.len() {
own += input[first + k];
}
a[k] = own;
}
let v = warp_scan(own);
if lane == 31 {
// SAFETY: lane 31 of each warp writes its own slot, before the barrier.
unsafe { WARPS[warp] = v };
}
thread::sync_threads();
if warp == 0 {
// SAFETY: only warp 0 touches the slots between the 2 barriers.
let w = warp_scan(if lane < 8 { unsafe { WARPS[lane] } } else { 0 });
if lane < 8 {
unsafe { WARPS[lane] = w };
}
}
thread::sync_threads();
// SAFETY: after the second barrier the slots are only read.
let before = v - own + if warp > 0 { unsafe { WARPS[warp - 1] } } else { 0 };
for k in 0..4 {
if first + k < out.len() {
// SAFETY: thread t alone writes elements 4t to 4t + 3.
unsafe { *out.get_unchecked_mut(first + k) = before + a[k] };
}
}
if thread::threadIdx_x() == BLOCK - 1 {
let block = thread::blockIdx_x() as usize;
// SAFETY: only the last thread of each block writes, at its own block number.
unsafe { *sums.get_unchecked_mut(block) = before + a[3] };
}
}
// ...
}__global__ void scanBlocks(const uint4* in, uint4* out, unsigned* sums, int n4)
{
__shared__ unsigned warps[BLOCK / 32];
int i = blockIdx.x * BLOCK + threadIdx.x;
int lane = threadIdx.x % 32;
int warp = threadIdx.x / 32;
uint4 a = i < n4 ? in[i] : make_uint4(0, 0, 0, 0);
a.y += a.x; // the thread's own 4 values, scanned
a.z += a.y;
a.w += a.z;
unsigned v = warpScan(a.w);
if (lane == 31) {
warps[warp] = v;
}
__syncthreads();
if (warp == 0) {
unsigned w = warpScan(lane < BLOCK / 32 ? warps[lane] : 0);
if (lane < BLOCK / 32) {
warps[lane] = w;
}
}
__syncthreads();
unsigned before = v - a.w + (warp > 0 ? warps[warp - 1] : 0);
a = make_uint4(before + a.x, before + a.y, before + a.z, before + a.w);
if (i < n4) {
out[i] = a;
}
if (threadIdx.x == BLOCK - 1) {
sums[blockIdx.x] = a.w;
}
}
The expression v - a.w computes the second offset. The variable v holds the inclusive warp
scan at this lane, and subtracting the lane’s own total a.w leaves the sum of the lanes before
it. The last thread of the block writes the block’s total to sums.
8.7.4 Hierarchical scan across blocks
Blocks cannot read each other’s results while a kernel runs, so an array larger than 1 block is scanned in 3 steps (figure 8.8):
- every block scans its 1,024 values and writes its total;
- the block totals are scanned, by the same function;
- every value of block \(b\) has the scanned total of blocks 0 to \(b - 1\) added to it.
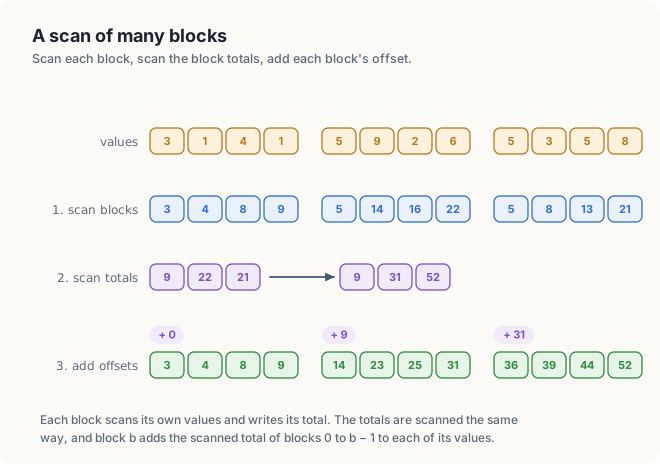
For 67,108,864 values, step 1 runs 65,536 blocks and writes 65,536 totals. Scanning these totals is
the same problem, 1,024 times smaller: 64 blocks, whose 64 totals fit in 1 block. The C++ function
scan therefore calls itself for step 2 until a single block remains. Animation 2 shows the 3
steps on the 12 values of the figure.
Listing 8.8 Adding the offsets, and the whole scan.
mod kernels {
// ...
/// Adds to every value of block b the total of blocks 0 to b - 1.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn add_offsets(mut out: DisjointSlice<u32>, scanned: &[u32]) {
let block = thread::blockIdx_x() as usize;
let first = thread::index_1d().get() * 4;
if block > 0 {
for k in 0..4 {
if first + k < out.len() {
// SAFETY: thread t alone writes elements 4t to 4t + 3.
unsafe { *out.get_unchecked_mut(first + k) += scanned[block - 1] };
}
}
}
}
// ...
}
/// Buffers for the block totals and their scan, per level: n / 1,024, / 1,024 again, ... 1.
fn levels(stream: &Arc<CudaStream>, mut n: usize) -> Result<Levels, Error> {
let mut levels = Vec::new();
while n > 1 {
n = n.div_ceil(1024);
let totals = DeviceBuffer::<u32>::zeroed(stream, n)?;
let scanned = DeviceBuffer::<u32>::zeroed(stream, n)?;
levels.push((totals, scanned));
}
Ok(levels)
}
/// Scans each block, then the block totals (by the same function), then adds them.
fn scan(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
input: &DeviceBuffer<u32>,
out: &mut DeviceBuffer<u32>,
levels: &mut [(DeviceBuffer<u32>, DeviceBuffer<u32>)],
) -> Result<(), Error> {
let blocks = input.len().div_ceil(1024) as u32;
let config = LaunchConfig1D::new(blocks, BLOCK, 0);
let ((totals, scanned), rest) = levels.split_first_mut().ok_or("no level left")?;
module.scan_blocks(stream, &module.prepare_scan_blocks(config)?, input, out, totals)?;
if blocks > 1 {
scan(module, stream, totals, scanned, rest)?;
module.add_offsets(stream, &module.prepare_add_offsets(config)?, out, scanned)?;
}
Ok(())
}__global__ void addOffsets(uint4* out, const unsigned* sums, int n4)
{
int i = blockIdx.x * BLOCK + threadIdx.x;
if (blockIdx.x > 0 && i < n4) {
unsigned s = sums[blockIdx.x - 1];
uint4 a = out[i];
out[i] = make_uint4(a.x + s, a.y + s, a.z + s, a.w + s);
}
}
// Scans each block, then the block totals (by the same function), then adds them.
// n is a multiple of 4. The totals are padded to a multiple of 4 as well: the padding
// comes after the last real total, so it changes none of the sums that are used.
void scan(const unsigned* in, unsigned* out, int n, unsigned* scratch)
{
int blocks = (n / 4 + BLOCK - 1) / BLOCK;
scanBlocks<<<blocks, BLOCK>>>((const uint4*)in, (uint4*)out, scratch, n / 4);
if (blocks > 1) {
int padded = (blocks + 3) / 4 * 4;
scan(scratch, scratch, padded, scratch + padded);
addOffsets<<<blocks, BLOCK>>>((uint4*)out, scratch, n / 4);
}
}
The totals of each level are scanned in place, in scratch, which holds all levels one after
another. The number of totals is rounded up to a multiple of 4, so that the next level can load
them as uint4. The rounding adds unused values after the last real total. Because an inclusive
scan never carries a value backwards, these values change none of the sums that are used.
The Rust version loads its 4 values with 4 ordinary loads and writes them through
get_unchecked_mut, because thread \(t\) writes elements \(4t\) to \(4t + 3\) rather than
element \(t\). A Rust function cannot borrow 1 buffer as both input and output, so each level
has its own pair of buffers, totals and scanned, which are allocated before the timing starts.
8.7.5 Performance of the scan
The test scans 67,108,864 random values from 0 to 3 and checks every result against a scan computed on the CPU. The reported bandwidth counts the bytes that the job requires: the input read once and the output written once, 2 × 256 MiB.
inclusive scan of 67108864 values # Orin NX
13.19 ms 40.7 GB/s last 100652862 correct: yes
inclusive scan of 67108864 values # Thor
5.88 ms 91.4 GB/s last 100652862 correct: yes
$ cargo oxide run # Orin NX, then Thor
inclusive scan of 67108864 values
19.38 ms 27.7 GB/s last 100652862 correct: yes
inclusive scan of 67108864 values
5.48 ms 98.0 GB/s last 100652862 correct: yes
Every value matched the CPU scan. The 3 steps, however, move more bytes than the job requires. Step 1 reads the input and writes the output, and step 3 reads the output and writes it again, so 4 × 256 MiB cross the memory in all. The memory therefore moved about 2 × 40.7 = 81 GB/s on the first GPU and 2 × 91.4 = 183 GB/s on the second, 80% and 67% of their rated bandwidth. A single-pass scan passes each block’s total directly to the next block while the kernel runs, so that each value is read once and written once. The CUB library of Chapter 11 provides one. The Rust scan, which uses 4 ordinary loads per thread, ran slower than the C++ scan on the first GPU and faster on the second in this run; over several runs, its bandwidth on the second GPU varied between 96 and 128 GB/s.
8.8 Histogram with wide loads
In Chapter 5, section 5.5.2, we privatized a histogram of bytes. Each block counts into 256 bins
in shared memory and adds them to the global bins once. This made the kernel 6 to 28 times as fast
as the version with global atomics. Measured as a bandwidth, however, its speed was still low.
Listing 5.7, run here as histBytes, read 64 MiB at 13.7 GB/s on the first GPU, 13% of the
memory’s rated bandwidth.
An input in which every byte is 7 shows where the time goes. In that case, every atomic operation of a warp targets the same bin, which is the worst possible contention. Yet these bytes were counted no more slowly than random bytes: 16.8 GB/s against 13.7 GB/s. Contention was therefore not the limit. Each byte cost 1 load instruction, and the 1-byte loads of a warp fetch only 32 bytes, 1 sector, per instruction. The kernel was limited by its loads.
The kernel histWords reads 16 bytes per thread with a single uint4 load, 512 bytes per warp.
It extracts the 4 bytes of each 32-bit word by shifting and masking: (w >> 8 * k) & 255 is byte
\(k\) of the word w.
Listing 8.9 A histogram reading 16 bytes per load.
mod kernels {
// ...
/// Adds the 4 bytes of the word `w` to the 256 shared bins that start at `local`.
#[device]
fn count_word(local: *mut u32, w: u32) {
let mut k = 0;
#[unroll]
while k < 4 {
let byte = (w >> (8 * k)) & 255;
// SAFETY: `local` points to 256 bins and byte < 256. Every access to the bins
// between the 2 barriers of the kernel is atomic.
let bin = unsafe { BlockAtomicU32::from_ptr(local.add(byte as usize)) };
bin.fetch_add(1, AtomicOrdering::Relaxed);
k += 1;
}
}
// ...
}
mod kernels {
// ...
/// A histogram of bytes in shared bins, reading 16 bytes per load.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn hist_quads(words: &[u32], bins: &[DeviceAtomicU32]) {
static mut LOCAL: SharedArray<u32, 256> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
let quads = vector::as_vectors::<U32x4>(words).unwrap_or(&[]);
// SAFETY: each thread zeroes only its own bin, before the barrier.
unsafe { LOCAL[tid] = 0 };
thread::sync_threads();
// SAFETY: the pointer is only used through atomics, between the 2 barriers.
let local = unsafe { (*&raw mut LOCAL).as_mut_ptr() };
let grid = (thread::gridDim_x() * BLOCK) as usize;
let mut i = thread::index_1d().get();
while i < quads.len() {
let [x, y, z, w] = quads[i].to_array();
count_word(local, x);
count_word(local, y);
count_word(local, z);
count_word(local, w);
i += grid;
}
thread::sync_threads();
// SAFETY: after the barrier no thread writes LOCAL again.
let local = unsafe { LOCAL[tid] };
bins[tid].fetch_add(local, AtomicOrdering::Relaxed);
}
}__device__ void countWord(unsigned* local, unsigned w)
{
for (int k = 0; k < 4; ++k) {
atomicAdd(&local[(w >> 8 * k) & 255], 1u);
}
}
__global__ void histWords(const uint4* data, unsigned* bins, int n16)
{
__shared__ unsigned local[256];
local[threadIdx.x] = 0;
__syncthreads();
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n16; i += gridDim.x * BLOCK) {
uint4 q = data[i];
countWord(local, q.x);
countWord(local, q.y);
countWord(local, q.z);
countWord(local, q.w);
}
__syncthreads();
atomicAdd(&bins[threadIdx.x], local[threadIdx.x]);
}
histogram of 64 MiB, average of 20 runs # Orin NX
random bytes 1 byte per load 4.92 ms 13.7 GB/s
random bytes 16 bytes per load 0.81 ms 82.9 GB/s total 67108864
all 7 1 byte per load 3.99 ms 16.8 GB/s
all 7 16 bytes per load 0.72 ms 93.4 GB/s total 67108864
histogram of 64 MiB, average of 20 runs # Thor
random bytes 1 byte per load 1.35 ms 49.7 GB/s
random bytes 16 bytes per load 0.35 ms 190.9 GB/s total 67108864
all 7 1 byte per load 1.24 ms 54.1 GB/s
all 7 16 bytes per load 0.32 ms 210.6 GB/s total 67108864
With 16-byte loads, the same atomic operations ran 6.1 times as fast for random bytes on the first GPU and 3.8 times as fast on the second, which is 81% and 70% of rated bandwidth (figure 8.9). Every total is 67,108,864, 1 count per byte. A version with 1 set of 256 bins per warp, intended to reduce contention further, was also measured. It ran no faster on either GPU, so the listing leaves it out.
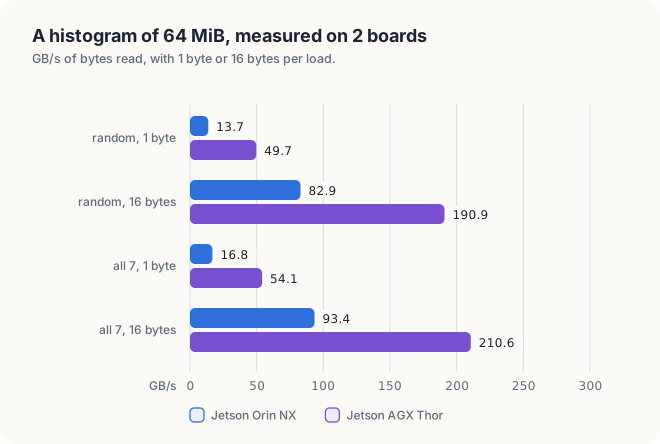
Listing 8.10 reads 4-byte words, 4 bytes per load:
Listing 8.10 A histogram reading 4 bytes per load.
mod kernels {
// ...
/// A histogram of bytes in shared bins, reading 4 bytes per load.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn hist_words(words: &[u32], bins: &[DeviceAtomicU32]) {
static mut LOCAL: SharedArray<u32, 256> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
// SAFETY: each thread zeroes only its own bin, before the barrier.
unsafe { LOCAL[tid] = 0 };
thread::sync_threads();
let stride = (thread::gridDim_x() * BLOCK) as usize;
let mut i = thread::index_1d().get();
while i < words.len() {
for k in 0..4 {
let byte = (words[i] >> (8 * k)) & 255;
// SAFETY: between the 2 barriers every access to LOCAL is atomic.
let bin = unsafe {
let base = (*&raw mut LOCAL).as_mut_ptr();
BlockAtomicU32::from_ptr(base.add(byte as usize))
};
bin.fetch_add(1, AtomicOrdering::Relaxed);
}
i += stride;
}
thread::sync_threads();
// SAFETY: after the barrier no thread writes LOCAL again.
let local = unsafe { LOCAL[tid] };
bins[tid].fetch_add(local, AtomicOrdering::Relaxed);
}
// ...
}__global__ void histUint(const unsigned* data, unsigned* bins, int n4)
{
__shared__ unsigned local[256];
local[threadIdx.x] = 0;
__syncthreads();
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n4; i += gridDim.x * BLOCK) {
countWord(local, data[i]);
}
__syncthreads();
atomicAdd(&bins[threadIdx.x], local[threadIdx.x]);
}
$ cargo oxide run # Orin NX, then Thor
histogram of 64 MiB, 4 bytes per load
1.27 ms 52.8 GB/s total 67108864
histogram of 64 MiB, 4 bytes per load
0.38 ms 176.4 GB/s total 67108864
Loads of 4 bytes already gave 3.9 and 3.5 times the speed of 1-byte loads, and 16-byte loads provided the rest of the gain.
Measure before optimizing. The histogram was limited by its loads, not by the contention that privatization was designed to avoid.
8.9 Comparison of the 3 patterns
| Pattern | Computes | Combining step | Shared state | Measured, best stage |
|---|---|---|---|---|
| Reduction | 1 value from \(n\) | tree: registers, shuffles, 1 barrier per block, 2 launches | none | 88% and 97% of rated |
| Scan | \(n\) running sums | warp scan by shuffles, block scan, 3 steps across blocks | none | 80% and 67% of rated, counting the bytes moved |
| Histogram | counts per bin | atomics on private bins in shared memory, 1 fold per block | 256 bins | 81% and 70% of rated |
The three kernels follow the same method. Each does as much of the work as possible in registers, combines values within a warp by shuffles, and then combines the warps of a block through shared memory. It combines results across blocks only once, through global memory or a second launch. Each optimization was kept only when a measurement showed that it removed a cost.
8.10 The complete programs
Listing 8.11 The complete programs. code/oxide/ch08_reduce/src/main.rs code/ch08_reduction/reduce.cu
//! Chapter 8 in Rust: a sum in 4 stages (tree, coarsened, shuffles, 16-byte loads), a scan,
//! and histograms reading 4 and 16 bytes per load.
//!
//! cargo oxide run
use std::sync::Arc;
use std::time::Instant;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, LaunchConfig1D};
use cuda_device::atomic::{AtomicOrdering, BlockAtomicU32, DeviceAtomicU32};
use cuda_device::{DisjointSlice, SharedArray, cuda_module, device, kernel, launch_contract};
use cuda_device::vector::{self, F32x4, U32x4};
use cuda_device::{thread, warp};
const BLOCK: u32 = 256;
const GRID: u32 = 1024;
type Error = Box<dyn std::error::Error>;
type Levels = Vec<(DeviceBuffer<u32>, DeviceBuffer<u32>)>;
#[cuda_module]
mod kernels {
use super::*;
/// 1. A tree in shared memory, 1 element per thread.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_tree(input: &[f32], mut partial: DisjointSlice<f32>) {
static mut S: SharedArray<f32, 256> = SharedArray::UNINIT;
let t = thread::threadIdx_x() as usize;
let i = thread::index_1d().get();
let value = if i < input.len() { input[i] } else { 0.0 };
// SAFETY: each thread writes only its own slot, before the first barrier.
unsafe { S[t] = value };
let mut step: usize = 0;
#[unroll]
while step < 8 {
let stride = (BLOCK as usize / 2) >> step; // 128, 64, ... 1
thread::sync_threads();
if t < stride {
// SAFETY: between 2 barriers thread t alone writes slot t, and it reads
// slot t + stride, which no thread writes at this stride.
unsafe { S[t] += S[t + stride] };
}
step += 1;
}
if t == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = S[0] };
}
}
/// 2. Each thread first sums many elements in a register, then 1 tree per block.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_coarse(input: &[f32], mut partial: DisjointSlice<f32>) {
static mut S: SharedArray<f32, 256> = SharedArray::UNINIT;
let t = thread::threadIdx_x() as usize;
let grid = (thread::gridDim_x() * BLOCK) as usize;
let mut sum = 0.0;
let mut i = thread::index_1d().get();
while i < input.len() {
sum += input[i];
i += grid;
}
// SAFETY: each thread writes only its own slot, before the first barrier.
unsafe { S[t] = sum };
let mut step: usize = 0;
#[unroll]
while step < 8 {
let stride = (BLOCK as usize / 2) >> step; // 128, 64, ... 1
thread::sync_threads();
if t < stride {
// SAFETY: between 2 barriers thread t alone writes slot t, and it reads
// slot t + stride, which no thread writes at this stride.
unsafe { S[t] += S[t + stride] };
}
step += 1;
}
if t == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = S[0] };
}
}
#[device]
fn warp_sum(mut v: f32) -> f32 {
for offset in [16, 8, 4, 2, 1] {
v += warp::shuffle_down_f32(v, offset);
}
v
}
#[device]
fn warp_scan(mut v: u32) -> u32 {
let lane = warp::lane_id();
for offset in [1, 2, 4, 8, 16] {
let left = warp::shuffle_up_sync(u32::MAX, v, offset);
if lane >= offset {
v += left;
}
}
v
}
/// Each thread sums many elements, each warp shuffles, 1 barrier per block.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_shuffle(input: &[f32], mut partial: DisjointSlice<f32>) {
static mut WARPS: SharedArray<f32, 8> = SharedArray::UNINIT;
let stride = (thread::gridDim_x() * BLOCK) as usize;
let lane = warp::lane_id() as usize;
let warp = thread::threadIdx_x() as usize / 32;
let mut sum = 0.0;
let mut i = thread::index_1d().get();
while i < input.len() {
sum += input[i];
i += stride;
}
sum = warp_sum(sum);
if lane == 0 {
// SAFETY: lane 0 of each warp writes its own slot, before the barrier.
unsafe { WARPS[warp] = sum };
}
thread::sync_threads();
if warp == 0 {
// SAFETY: after the barrier the slots are only read.
sum = warp_sum(if lane < 8 { unsafe { WARPS[lane] } } else { 0.0 });
if lane == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = sum };
}
}
}
/// The sum of `v` over the 256 threads of a block, returned to thread 0.
#[device]
fn block_sum(v: f32) -> f32 {
static mut WARPS: SharedArray<f32, 8> = SharedArray::UNINIT;
let lane = warp::lane_id() as usize;
let warp = thread::threadIdx_x() as usize / 32;
let v = warp_sum(v);
if lane == 0 {
// SAFETY: lane 0 of each warp writes its own slot, before the barrier.
unsafe { WARPS[warp] = v };
}
thread::sync_threads();
// SAFETY: after the barrier the slots are only read.
let w = if lane < 8 { unsafe { WARPS[lane] } } else { 0.0 };
if warp == 0 { warp_sum(w) } else { 0.0 }
}
/// 4. The shuffle sum, loading 4 floats per instruction.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_shuffle4(input: &[f32], mut partial: DisjointSlice<f32>) {
let quads = vector::as_vectors::<F32x4>(input).unwrap_or(&[]);
let grid = (thread::gridDim_x() * BLOCK) as usize;
let mut sum = 0.0;
let mut i = thread::index_1d().get();
while i < quads.len() {
let [x, y, z, w] = quads[i].to_array();
sum += x + y + z + w;
i += grid;
}
let sum = block_sum(sum);
if thread::threadIdx_x() == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = sum };
}
}
/// An inclusive scan of 1,024 values per block, 4 per thread.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scan_blocks(
input: &[u32],
mut out: DisjointSlice<u32>,
mut sums: DisjointSlice<u32>,
) {
static mut WARPS: SharedArray<u32, 8> = SharedArray::UNINIT;
let first = thread::index_1d().get() * 4;
let lane = warp::lane_id() as usize;
let warp = thread::threadIdx_x() as usize / 32;
let mut a = [0u32; 4];
let mut own = 0;
for k in 0..4 {
if first + k < input.len() {
own += input[first + k];
}
a[k] = own;
}
let v = warp_scan(own);
if lane == 31 {
// SAFETY: lane 31 of each warp writes its own slot, before the barrier.
unsafe { WARPS[warp] = v };
}
thread::sync_threads();
if warp == 0 {
// SAFETY: only warp 0 touches the slots between the 2 barriers.
let w = warp_scan(if lane < 8 { unsafe { WARPS[lane] } } else { 0 });
if lane < 8 {
unsafe { WARPS[lane] = w };
}
}
thread::sync_threads();
// SAFETY: after the second barrier the slots are only read.
let before = v - own + if warp > 0 { unsafe { WARPS[warp - 1] } } else { 0 };
for k in 0..4 {
if first + k < out.len() {
// SAFETY: thread t alone writes elements 4t to 4t + 3.
unsafe { *out.get_unchecked_mut(first + k) = before + a[k] };
}
}
if thread::threadIdx_x() == BLOCK - 1 {
let block = thread::blockIdx_x() as usize;
// SAFETY: only the last thread of each block writes, at its own block number.
unsafe { *sums.get_unchecked_mut(block) = before + a[3] };
}
}
/// Adds to every value of block b the total of blocks 0 to b - 1.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn add_offsets(mut out: DisjointSlice<u32>, scanned: &[u32]) {
let block = thread::blockIdx_x() as usize;
let first = thread::index_1d().get() * 4;
if block > 0 {
for k in 0..4 {
if first + k < out.len() {
// SAFETY: thread t alone writes elements 4t to 4t + 3.
unsafe { *out.get_unchecked_mut(first + k) += scanned[block - 1] };
}
}
}
}
/// A histogram of bytes in shared bins, reading 4 bytes per load.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn hist_words(words: &[u32], bins: &[DeviceAtomicU32]) {
static mut LOCAL: SharedArray<u32, 256> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
// SAFETY: each thread zeroes only its own bin, before the barrier.
unsafe { LOCAL[tid] = 0 };
thread::sync_threads();
let stride = (thread::gridDim_x() * BLOCK) as usize;
let mut i = thread::index_1d().get();
while i < words.len() {
for k in 0..4 {
let byte = (words[i] >> (8 * k)) & 255;
// SAFETY: between the 2 barriers every access to LOCAL is atomic.
let bin = unsafe {
let base = (*&raw mut LOCAL).as_mut_ptr();
BlockAtomicU32::from_ptr(base.add(byte as usize))
};
bin.fetch_add(1, AtomicOrdering::Relaxed);
}
i += stride;
}
thread::sync_threads();
// SAFETY: after the barrier no thread writes LOCAL again.
let local = unsafe { LOCAL[tid] };
bins[tid].fetch_add(local, AtomicOrdering::Relaxed);
}
/// Adds the 4 bytes of the word `w` to the 256 shared bins that start at `local`.
#[device]
fn count_word(local: *mut u32, w: u32) {
let mut k = 0;
#[unroll]
while k < 4 {
let byte = (w >> (8 * k)) & 255;
// SAFETY: `local` points to 256 bins and byte < 256. Every access to the bins
// between the 2 barriers of the kernel is atomic.
let bin = unsafe { BlockAtomicU32::from_ptr(local.add(byte as usize)) };
bin.fetch_add(1, AtomicOrdering::Relaxed);
k += 1;
}
}
/// A histogram of bytes in shared bins, reading 16 bytes per load.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn hist_quads(words: &[u32], bins: &[DeviceAtomicU32]) {
static mut LOCAL: SharedArray<u32, 256> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
let quads = vector::as_vectors::<U32x4>(words).unwrap_or(&[]);
// SAFETY: each thread zeroes only its own bin, before the barrier.
unsafe { LOCAL[tid] = 0 };
thread::sync_threads();
// SAFETY: the pointer is only used through atomics, between the 2 barriers.
let local = unsafe { (*&raw mut LOCAL).as_mut_ptr() };
let grid = (thread::gridDim_x() * BLOCK) as usize;
let mut i = thread::index_1d().get();
while i < quads.len() {
let [x, y, z, w] = quads[i].to_array();
count_word(local, x);
count_word(local, y);
count_word(local, z);
count_word(local, w);
i += grid;
}
thread::sync_threads();
// SAFETY: after the barrier no thread writes LOCAL again.
let local = unsafe { LOCAL[tid] };
bins[tid].fetch_add(local, AtomicOrdering::Relaxed);
}
}
/// Average time of 20 runs of `launch`, in milliseconds, after 1 warm-up run.
fn time_ms(
stream: &Arc<CudaStream>,
mut launch: impl FnMut() -> Result<(), Error>,
) -> Result<f64, Error> {
launch()?;
stream.synchronize()?;
let start = Instant::now();
for _ in 0..20 {
launch()?;
}
stream.synchronize()?;
Ok(start.elapsed().as_secs_f64() * 1e3 / 20.0)
}
/// Prints a stage's time and bandwidth over `n` floats, and the sum it left in `total`.
fn report(
stream: &Arc<CudaStream>,
name: &str,
ms: f64,
n: usize,
total: &DeviceBuffer<f32>,
) -> Result<(), Error> {
let sum = total.to_host_vec(stream)?[0];
let gb = (n * 4) as f64 / 1e9 / (ms / 1e3);
println!(" {name:22} {ms:6.2} ms {gb:6.1} GB/s sum {sum:.1}");
Ok(())
}
/// Times the 4 stages of the sum. A run is the stage, then 1 block over its partial sums.
fn sums(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
input: &DeviceBuffer<f32>,
) -> Result<(), Error> {
let n = input.len();
let mut leaves = DeviceBuffer::<f32>::zeroed(stream, n / BLOCK as usize)?;
let mut partial = DeviceBuffer::<f32>::zeroed(stream, GRID as usize)?;
let mut total = DeviceBuffer::<f32>::zeroed(stream, 1)?;
let full = LaunchConfig1D::new(GRID, BLOCK, 0);
let tree = module.prepare_sum_tree(LaunchConfig1D::new(n as u32 / BLOCK, BLOCK, 0))?;
let coarse = module.prepare_sum_coarse(full)?;
let shuffle = module.prepare_sum_shuffle(full)?;
let shuffle4 = module.prepare_sum_shuffle4(full)?;
let last = module.prepare_sum_shuffle(LaunchConfig1D::new(1, BLOCK, 0))?;
println!("sum of {n} floats, the 4 stages, average of 20 runs");
let ms = time_ms(stream, || {
module.sum_tree(stream, &tree, input, &mut leaves)?;
Ok(module.sum_shuffle(stream, &last, &leaves, &mut total)?)
})?;
report(stream, "tree, 1 per thread", ms, n, &total)?;
let ms = time_ms(stream, || {
module.sum_coarse(stream, &coarse, input, &mut partial)?;
Ok(module.sum_shuffle(stream, &last, &partial, &mut total)?)
})?;
report(stream, "coarsened", ms, n, &total)?;
let ms = time_ms(stream, || {
module.sum_shuffle(stream, &shuffle, input, &mut partial)?;
Ok(module.sum_shuffle(stream, &last, &partial, &mut total)?)
})?;
report(stream, "shuffles", ms, n, &total)?;
let ms = time_ms(stream, || {
module.sum_shuffle4(stream, &shuffle4, input, &mut partial)?;
Ok(module.sum_shuffle(stream, &last, &partial, &mut total)?)
})?;
report(stream, "shuffles, F32x4", ms, n, &total)
}
/// Numbers from a small linear congruential generator, so the run needs no extra crate.
fn random(n: usize, seed: u32) -> Vec<u32> {
let mut state = seed;
(0..n)
.map(|_| {
state = state.wrapping_mul(1_664_525).wrapping_add(1_013_904_223);
state
})
.collect()
}
/// Buffers for the block totals and their scan, per level: n / 1,024, / 1,024 again, ... 1.
fn levels(stream: &Arc<CudaStream>, mut n: usize) -> Result<Levels, Error> {
let mut levels = Vec::new();
while n > 1 {
n = n.div_ceil(1024);
let totals = DeviceBuffer::<u32>::zeroed(stream, n)?;
let scanned = DeviceBuffer::<u32>::zeroed(stream, n)?;
levels.push((totals, scanned));
}
Ok(levels)
}
/// Scans each block, then the block totals (by the same function), then adds them.
fn scan(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
input: &DeviceBuffer<u32>,
out: &mut DeviceBuffer<u32>,
levels: &mut [(DeviceBuffer<u32>, DeviceBuffer<u32>)],
) -> Result<(), Error> {
let blocks = input.len().div_ceil(1024) as u32;
let config = LaunchConfig1D::new(blocks, BLOCK, 0);
let ((totals, scanned), rest) = levels.split_first_mut().ok_or("no level left")?;
module.scan_blocks(stream, &module.prepare_scan_blocks(config)?, input, out, totals)?;
if blocks > 1 {
scan(module, stream, totals, scanned, rest)?;
module.add_offsets(stream, &module.prepare_add_offsets(config)?, out, scanned)?;
}
Ok(())
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let n = 64 << 20;
// 1. A sum of 67,108,864 floats in [0, 1).
let values: Vec<f32> = random(n, 1)
.iter()
.map(|&r| (r >> 8) as f32 / 16_777_216.0)
.collect();
let floats = DeviceBuffer::from_host(&stream, &values)?;
let mut partial = DeviceBuffer::<f32>::zeroed(&stream, GRID as usize)?;
let mut total = DeviceBuffer::<f32>::zeroed(&stream, 1)?;
let blocks = module.prepare_sum_shuffle(LaunchConfig1D::new(GRID, BLOCK, 0))?;
let last = module.prepare_sum_shuffle(LaunchConfig1D::new(1, BLOCK, 0))?;
let mut sum = || -> Result<(), Error> {
module.sum_shuffle(&stream, &blocks, &floats, &mut partial)?;
Ok(module.sum_shuffle(&stream, &last, &partial, &mut total)?)
};
for _ in 0..10 {
time_ms(&stream, &mut sum)?; // warm up the clocks
}
let ms = time_ms(&stream, &mut sum)?;
let gpu = total.to_host_vec(&stream)?[0];
let exact: f64 = values.iter().map(|&v| v as f64).sum();
let gb = (n * 4) as f64 / 1e9 / (ms / 1e3);
println!("sum of {n} floats, average of 20 runs");
println!(" shuffles {ms:6.2} ms {gb:6.1} GB/s sum {gpu:.1}");
println!(" exact (f64) sum {exact:.1}");
// 2. An inclusive scan of values 0 to 3.
let counts: Vec<u32> = random(n, 2).iter().map(|&r| r >> 30).collect();
let input = DeviceBuffer::from_host(&stream, &counts)?;
let mut out = DeviceBuffer::<u32>::zeroed(&stream, n)?;
let mut levels = levels(&stream, n)?;
let ms = time_ms(&stream, || scan(&module, &stream, &input, &mut out, &mut levels))?;
let result = out.to_host_vec(&stream)?;
let mut running = 0u32;
let correct = counts.iter().zip(&result).all(|(&c, &r)| {
running += c;
r == running
});
let gb = (2 * n * 4) as f64 / 1e9 / (ms / 1e3);
let verdict = if correct { "yes" } else { "no" };
println!("inclusive scan of {n} values");
println!(" {ms:6.2} ms {gb:6.1} GB/s last {} correct: {verdict}", result[n - 1]);
// 3. A histogram of 64 MiB of random bytes, read as 4-byte words.
let words = DeviceBuffer::from_host(&stream, &random(n / 4, 3))?;
let hist = module.prepare_hist_words(LaunchConfig1D::new(GRID, BLOCK, 0))?;
let scratch = DeviceBuffer::<u32>::zeroed(&stream, 256)?.cast_elem::<DeviceAtomicU32>();
let ms = time_ms(&stream, || Ok(module.hist_words(&stream, &hist, &words, &scratch)?))?;
let bins = DeviceBuffer::<u32>::zeroed(&stream, 256)?.cast_elem::<DeviceAtomicU32>();
module.hist_words(&stream, &hist, &words, &bins)?;
let counts = bins.cast_elem::<u32>().to_host_vec(&stream)?;
let total: u64 = counts.iter().map(|&c| c as u64).sum();
let gb = n as f64 / 1e9 / (ms / 1e3);
println!("histogram of 64 MiB, 4 bytes per load");
println!(" {ms:6.2} ms {gb:6.1} GB/s total {total}");
// 4. The histogram reading 16 bytes per load, and the 4 stages of the sum.
let wide = module.prepare_hist_quads(LaunchConfig1D::new(GRID, BLOCK, 0))?;
let ms = time_ms(&stream, || Ok(module.hist_quads(&stream, &wide, &words, &scratch)?))?;
let bins = DeviceBuffer::<u32>::zeroed(&stream, 256)?.cast_elem::<DeviceAtomicU32>();
module.hist_quads(&stream, &wide, &words, &bins)?;
let counts = bins.cast_elem::<u32>().to_host_vec(&stream)?;
let total: u64 = counts.iter().map(|&c| c as u64).sum();
let gb = n as f64 / 1e9 / (ms / 1e3);
println!("histogram of 64 MiB, 16 bytes per load");
println!(" {ms:6.2} ms {gb:6.1} GB/s total {total}");
sums(&module, &stream, &floats)?;
Ok(())
}// Chapter 8: a sum, a scan and a histogram at memory speed, measured.
// Build: nvcc -arch=native reduce.cu -o reduce
#include <chrono>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cuda_runtime.h>
const int BLOCK = 256; // threads per block, a power of 2
const int GRID = 1024; // blocks of the grid-stride kernels
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// Average time of 20 runs of `launch`, in milliseconds, after 1 warm-up run.
template <typename F>
double timeKernel(F launch)
{
launch();
check(cudaDeviceSynchronize());
double t0 = nowMs();
for (int r = 0; r < 20; ++r) {
launch();
}
check(cudaGetLastError());
check(cudaDeviceSynchronize());
return (nowMs() - t0) / 20;
}
// 1. A tree in shared memory, 1 element per thread.
__global__ void sumTree(const float* in, float* partial, int n)
{
    __shared__ float s[BLOCK];
    int i = blockIdx.x * BLOCK + threadIdx.x;
    s[threadIdx.x] = i < n ? in[i] : 0.0f;

    for (int stride = BLOCK / 2; stride > 0; stride /= 2) {
        __syncthreads();
        if (threadIdx.x < stride) {
            s[threadIdx.x] += s[threadIdx.x + stride];
        }
    }
    if (threadIdx.x == 0) {
        partial[blockIdx.x] = s[0];
    }
}
// 2. Each thread first sums many elements in a register, then 1 tree per block.
__global__ void sumCoarse(const float* in, float* partial, int n)
{
    __shared__ float s[BLOCK];
    float sum = 0.0f;
    for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n; i += gridDim.x * BLOCK) {
        sum += in[i];
    }
    s[threadIdx.x] = sum;

    for (int stride = BLOCK / 2; stride > 0; stride /= 2) {
        __syncthreads();
        if (threadIdx.x < stride) {
            s[threadIdx.x] += s[threadIdx.x + stride];
        }
    }
    if (threadIdx.x == 0) {
        partial[blockIdx.x] = s[0];
    }
}
// 3. Shuffles within each warp, and 1 barrier per block.
__device__ float warpSum(float v)
{
    for (int offset = 16; offset > 0; offset /= 2) {
        v += __shfl_down_sync(0xffffffff, v, offset);
    }
    return v;                                 // the warp's total, in lane 0
}

__device__ float blockSum(float v)
{
    __shared__ float warps[BLOCK / 32];
    int lane = threadIdx.x % 32;
    int warp = threadIdx.x / 32;

    v = warpSum(v);
    if (lane == 0) {
        warps[warp] = v;
    }
    __syncthreads();

    if (warp == 0) {
        v = warpSum(lane < BLOCK / 32 ? warps[lane] : 0.0f);
    }
    return v;                                 // the block's total, in thread 0
}

__global__ void sumShuffle(const float* in, float* partial, int n)
{
    float sum = 0.0f;
    for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n; i += gridDim.x * BLOCK) {
        sum += in[i];
    }

    sum = blockSum(sum);
    if (threadIdx.x == 0) {
        partial[blockIdx.x] = sum;
    }
}
// 4. The same, loading 4 floats per instruction; n4 is the number of float4s.
__global__ void sumShuffle4(const float4* in, float* partial, int n4)
{
    float sum = 0.0f;
    for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n4; i += gridDim.x * BLOCK) {
        float4 v = in[i];
        sum += v.x + v.y + v.z + v.w;
    }

    sum = blockSum(sum);
    if (threadIdx.x == 0) {
        partial[blockIdx.x] = sum;
    }
}
// 5. An inclusive scan, 4 elements per thread, 1,024 per block.
__device__ unsigned warpScan(unsigned v)
{
int lane = threadIdx.x % 32;
for (int offset = 1; offset < 32; offset *= 2) {
unsigned left = __shfl_up_sync(0xffffffff, v, offset);
if (lane >= offset) {
v += left;
}
}
return v; // the sum of lanes 0 to `lane`
}
__global__ void scanBlocks(const uint4* in, uint4* out, unsigned* sums, int n4)
{
__shared__ unsigned warps[BLOCK / 32];
int i = blockIdx.x * BLOCK + threadIdx.x;
int lane = threadIdx.x % 32;
int warp = threadIdx.x / 32;
uint4 a = i < n4 ? in[i] : make_uint4(0, 0, 0, 0);
a.y += a.x; // the thread's own 4 values, scanned
a.z += a.y;
a.w += a.z;
unsigned v = warpScan(a.w);
if (lane == 31) {
warps[warp] = v;
}
__syncthreads();
if (warp == 0) {
unsigned w = warpScan(lane < BLOCK / 32 ? warps[lane] : 0);
if (lane < BLOCK / 32) {
warps[lane] = w;
}
}
__syncthreads();
unsigned before = v - a.w + (warp > 0 ? warps[warp - 1] : 0);
a = make_uint4(before + a.x, before + a.y, before + a.z, before + a.w);
if (i < n4) {
out[i] = a;
}
if (threadIdx.x == BLOCK - 1) {
sums[blockIdx.x] = a.w;
}
}
__global__ void addOffsets(uint4* out, const unsigned* sums, int n4)
{
int i = blockIdx.x * BLOCK + threadIdx.x;
if (blockIdx.x > 0 && i < n4) {
unsigned s = sums[blockIdx.x - 1];
uint4 a = out[i];
out[i] = make_uint4(a.x + s, a.y + s, a.z + s, a.w + s);
}
}
// Scans each block, then the block totals (by the same function), then adds them.
// n is a multiple of 4. The totals are padded to a multiple of 4 as well: the padding
// comes after the last real total, so it changes none of the sums that are used.
void scan(const unsigned* in, unsigned* out, int n, unsigned* scratch)
{
int blocks = (n / 4 + BLOCK - 1) / BLOCK;
scanBlocks<<<blocks, BLOCK>>>((const uint4*)in, (uint4*)out, scratch, n / 4);
if (blocks > 1) {
int padded = (blocks + 3) / 4 * 4;
scan(scratch, scratch, padded, scratch + padded);
addOffsets<<<blocks, BLOCK>>>((uint4*)out, scratch, n / 4);
}
}
// 6. Histograms of bytes in shared bins (Chapter 5): 1 byte, 16 bytes or 4 bytes per load.
__global__ void histBytes(const unsigned char* data, unsigned* bins, int n)
{
__shared__ unsigned local[256];
local[threadIdx.x] = 0;
__syncthreads();
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n; i += gridDim.x * BLOCK) {
atomicAdd(&local[data[i]], 1u);
}
__syncthreads();
atomicAdd(&bins[threadIdx.x], local[threadIdx.x]);
}
__device__ void countWord(unsigned* local, unsigned w)
{
for (int k = 0; k < 4; ++k) {
atomicAdd(&local[(w >> 8 * k) & 255], 1u);
}
}
__global__ void histWords(const uint4* data, unsigned* bins, int n16)
{
__shared__ unsigned local[256];
local[threadIdx.x] = 0;
__syncthreads();
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n16; i += gridDim.x * BLOCK) {
uint4 q = data[i];
countWord(local, q.x);
countWord(local, q.y);
countWord(local, q.z);
countWord(local, q.w);
}
__syncthreads();
atomicAdd(&bins[threadIdx.x], local[threadIdx.x]);
}
__global__ void histUint(const unsigned* data, unsigned* bins, int n4)
{
__shared__ unsigned local[256];
local[threadIdx.x] = 0;
__syncthreads();
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n4; i += gridDim.x * BLOCK) {
countWord(local, data[i]);
}
__syncthreads();
atomicAdd(&bins[threadIdx.x], local[threadIdx.x]);
}
unsigned nextRandom(unsigned& state)
{
state = state * 1664525u + 1013904223u;
return state;
}
void sums(const float* in, float* partial, float* total, int n)
{
    double bytes = n * sizeof(float);
    std::printf("sum of %d floats (%d MiB), average of 20 runs\n", n, int(bytes) >> 20);

    auto finish = [&](int blocks) { sumShuffle<<<1, BLOCK>>>(partial, total, blocks); };
    auto report = [&](const char* name, double ms) {
        float t;
        check(cudaMemcpy(&t, total, sizeof(float), cudaMemcpyDeviceToHost));
        double gb = bytes / ms / 1e6;
        std::printf("  %-22s %6.2f ms  %6.1f GB/s  sum %.1f\n", name, ms, gb, t);
    };

    report("tree, 1 per thread", timeKernel([&] {
        sumTree<<<n / BLOCK, BLOCK>>>(in, partial, n);
        finish(n / BLOCK);
    }));
    report("coarsened", timeKernel([&] {
        sumCoarse<<<GRID, BLOCK>>>(in, partial, n);
        finish(GRID);
    }));
    report("shuffles", timeKernel([&] {
        sumShuffle<<<GRID, BLOCK>>>(in, partial, n);
        finish(GRID);
    }));
    report("shuffles, float4", timeKernel([&] {
        sumShuffle4<<<GRID, BLOCK>>>((const float4*)in, partial, n / 4);
        finish(GRID);
    }));
}
void scans(int n)
{
std::vector<unsigned> values(n), expected(n), result(n);
unsigned state = 2;
unsigned running = 0;
for (int i = 0; i < n; ++i) {
values[i] = nextRandom(state) >> 30; // 0, 1, 2 or 3
running += values[i];
expected[i] = running;
}
unsigned *in, *out, *scratch;
check(cudaMalloc(&in, n * sizeof(unsigned)));
check(cudaMalloc(&out, n * sizeof(unsigned)));
check(cudaMalloc(&scratch, (n / 512 + 64) * sizeof(unsigned)));
check(cudaMemcpy(in, values.data(), n * sizeof(unsigned), cudaMemcpyHostToDevice));
double ms = timeKernel([&] { scan(in, out, n, scratch); });
check(cudaMemcpy(result.data(), out, n * sizeof(unsigned), cudaMemcpyDeviceToHost));
double gb = 2.0 * n * sizeof(unsigned) / ms / 1e6;
std::printf("inclusive scan of %d values\n", n);
std::printf(" %6.2f ms %6.1f GB/s last %u correct: %s\n", ms, gb, result[n - 1],
result == expected ? "yes" : "no");
check(cudaFree(in));
check(cudaFree(out));
check(cudaFree(scratch));
}
void histograms(int n)
{
std::vector<unsigned char> random(n), sevens(n, 7);
unsigned state = 3;
for (int i = 0; i < n; ++i) {
random[i] = nextRandom(state) >> 24;
}
unsigned char* data;
unsigned* bins;
check(cudaMalloc(&data, n));
check(cudaMalloc(&bins, 256 * sizeof(unsigned)));
std::printf("histogram of %d MiB, average of 20 runs\n", n >> 20);
for (auto* bytes : {&random, &sevens}) {
check(cudaMemcpy(data, bytes->data(), n, cudaMemcpyHostToDevice));
const char* name = bytes == &random ? "random bytes" : "all 7 ";
double ms1 = timeKernel([&] {
check(cudaMemsetAsync(bins, 0, 256 * sizeof(unsigned)));
histBytes<<<GRID, BLOCK>>>(data, bins, n);
});
double ms16 = timeKernel([&] {
check(cudaMemsetAsync(bins, 0, 256 * sizeof(unsigned)));
histWords<<<GRID, BLOCK>>>((const uint4*)data, bins, n / 16);
});
std::vector<unsigned> counts(256);
check(cudaMemcpy(counts.data(), bins, 1024, cudaMemcpyDeviceToHost));
long long total = 0;
for (unsigned c : counts) {
total += c;
}
std::printf(" %s 1 byte per load %6.2f ms %6.1f GB/s\n", name, ms1,
n / ms1 / 1e6);
std::printf(" %s 16 bytes per load %6.2f ms %6.1f GB/s total %lld\n", name,
ms16, n / ms16 / 1e6, total);
}
check(cudaMemcpy(data, random.data(), n, cudaMemcpyHostToDevice));
double ms4 = timeKernel([&] {
check(cudaMemsetAsync(bins, 0, 256 * sizeof(unsigned)));
histUint<<<GRID, BLOCK>>>((const unsigned*)data, bins, n / 4);
});
std::vector<unsigned> counts(256);
check(cudaMemcpy(counts.data(), bins, 1024, cudaMemcpyDeviceToHost));
long long total = 0;
for (unsigned c : counts) {
total += c;
}
double gbPerS = n / ms4 / 1e6;
std::printf(" random bytes 4 bytes per load %6.2f ms", ms4);
std::printf(" %6.1f GB/s total %lld\n", gbPerS, total);
check(cudaFree(data));
check(cudaFree(bins));
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %d SMs, L2 cache %d MiB\n",
prop.name, prop.multiProcessorCount, prop.l2CacheSize >> 20);
const int n = 64 << 20; // 67,108,864 values, 256 MiB of floats
std::vector<float> values(n);
unsigned state = 1;
for (int i = 0; i < n; ++i) {
values[i] = (nextRandom(state) >> 8) / 16777216.0f; // in [0, 1)
}
float *in, *partial, *total;
check(cudaMalloc(&in, n * sizeof(float)));
check(cudaMalloc(&partial, n / BLOCK * sizeof(float)));
check(cudaMalloc(&total, sizeof(float)));
check(cudaMemcpy(in, values.data(), n * sizeof(float), cudaMemcpyHostToDevice));
for (int k = 0; k < 10; ++k) { // warm up: clocks rise under sustained load
timeKernel([&] { sumShuffle<<<GRID, BLOCK>>>(in, partial, n); });
}
sums(in, partial, total, n);
double exact = 0.0;
float serial = 0.0f;
for (float v : values) {
exact += v;
serial += v;
}
std::printf("exact sum (double) %.1f\n", exact);
std::printf("CPU, float, 1 by 1 %.1f\n", serial);
std::printf("GPU, shuffles, 5 runs ");
for (int r = 0; r < 5; ++r) {
sumShuffle<<<GRID, BLOCK>>>(in, partial, n);
sumShuffle<<<1, BLOCK>>>(partial, total, GRID);
float t;
check(cudaMemcpy(&t, total, sizeof(float), cudaMemcpyDeviceToHost));
std::printf(" %.1f", t);
}
std::printf("\n");
check(cudaFree(in));
check(cudaFree(partial));
check(cudaFree(total));
scans(n);
histograms(n);
}
Common mistakes
- A block size that is not a power of 2 in a halving tree. The levels no longer split evenly, and some values are skipped.
- A shuffle that only some lanes execute. Every lane named in the mask must call
__shfl_down_sync; calling it insideif (lane < 8)is undefined. - Reading the partial result of a lane other than lane 0 after a shuffle sum. Only lane 0 holds the total.
- A missing barrier between writing the warp totals and reading them. We measured the effect in Chapter 5.
- Summing many floats sequentially into a float. Above 224, small values are lost.
- Comparing results bit for bit across launch shapes. A different grid groups the additions differently.
- Timing a scan with allocations inside the timed loop. Allocate the buffers of every level first.
Summary
- A reduction combines \(n\) values with an associative operator. A tree performs the same \(n - 1\) operations as a sequential chain, in \(\log_2 n\) steps.
- A float sum of values below 1, computed sequentially, stopped at 224 = 16,777,216. The tree on the GPU produced the float nearest to the exact sum.
- A tree with one element per thread reached a quarter to a third of rated bandwidth. Coarsening to 256 elements per thread made it 2.3 to 2.5 times as fast.
- Warp shuffles combine the registers of a warp without shared memory or barriers. After coarsening they changed little, because the tree had become a small cost.
- With
float4loads, the sum reached 88% and 97% of rated bandwidth on the 2 GPUs, with the same bits on every run. - A scan within a warp takes 5 shuffle steps. A scan of many blocks scans the blocks, scans their totals, and adds the offsets, and it moves the output twice.
- The privatized histogram of Chapter 5 was limited by its 1-byte loads; 16-byte loads made it 3.8 to 6.1 times as fast.
Chapter 9 applies the same approach to matrix multiplication, a computation that reuses every value it loads many times and can therefore run faster than the memory bandwidth alone would allow.
Exercises
- A tree sums 512 values per block, 1 per thread. How many levels and how many barriers does it need? How many does the shuffle version of section 8.5 need?
- In
blockSum, why does lane 0 of each warp writewarps[warp], and not every lane? What would go wrong if every lane wrote its ownv? - Compute the largest number of floats with values in [0, 1) that can be summed sequentially into a float before the sum stops growing, and check it with a small CPU program.
- Change
GRIDto 256 and to 4,096 and runreduce. Explain the change in speed, and check whether the bits of the sum change. - Write
warpMaxwith__shfl_down_syncand use it to find the largest value of the array. Does the result depend on the launch shape, as the float sum does? - Trace the Blelloch scan on 3, 1, 4, 1: an up-sweep that stores the partial sums of a tree, then a down-sweep that gives each left child its parent’s prefix and each right child the parent’s prefix plus the left child’s sum. Check that it yields the exclusive scan 0, 3, 4, 8.
- Use
scanto write stream compaction: keep the values above 1 from 67,108,864 values from 0 to 3, and verify the output length against a count on the CPU. - Rewrite the Rust
hist_wordsto read 16 bytes per thread, as 4 consecutiveu32words, and compare its speed with listing 8.13 on your GPU.
Sources and further reading
- M. Harris, “Optimizing Parallel Reduction in CUDA”, NVIDIA, 2007.
- J. Luitjens, “Faster Parallel Reductions on Kepler”, NVIDIA Technical Blog, 2014.
- G. Blelloch, “Prefix Sums and Their Applications”, Carnegie Mellon University, 1990.
- D. Merrill and M. Garland, “Single-pass Parallel Prefix Scan with Decoupled Look-back”, NVIDIA, 2016.
- N. Higham, “The Accuracy of Floating Point Summation”, SIAM Journal on Scientific Computing, 1993.
- NVIDIA, CUDA C++ Programming Guide, “Warp Shuffle Functions”: https://docs.nvidia.com/cuda/cuda-c-programming-guide/
- D. Kirk and W. Hwu, Programming Massively Parallel Processors, 4th ed., Morgan Kaufmann, 2022, chapters on reduction, prefix sum and histogram.
Chapter 9: Optimized Matrix Multiplication
Matrix multiplication is one of the most important computations in science, engineering and machine learning. The kernels of Chapters 7 and 8 read each input value once and performed 1 or 2 operations with it, so their speed was limited by memory bandwidth. Matrix multiplication behaves differently. Each input value takes part in thousands of operations, and a kernel that loads the value from memory once and keeps it close to the arithmetic units for all of those operations can approach the arithmetic peak of the GPU.
In this chapter, we develop a matrix multiplication kernel in 4 stages and measure each one. Each stage holds the reused values in a faster kind of storage than the stage before: first the hardware caches, then shared memory, then registers. We then examine how register usage limits occupancy, how loops must be written for the cuda-oxide compiler to keep arrays in registers, and how far the best kernel remains from cuBLAS, NVIDIA’s matrix library. Every kernel is shown in CUDA C++ and in Rust.
This chapter covers
- the operations, memory traffic and data reuse of a matrix product
- a kernel with one thread per output element, and the effect of the thread-to-element mapping
- shared-memory tiling
- register tiling with a 4 × 4 output patch per thread
- register usage, occupancy and
__launch_bounds__ - loop unrolling in cuda-oxide with
#[unroll] - a comparison with cuBLAS
The code of the chapter is in
code/ch09_sgemm/
for C++ and in
code/oxide/ch09_sgemm/
for Rust.
9.1 The arithmetic intensity of matrix multiplication
9.1.1 The matrix product
For 2 matrices \(A\) and \(B\) of \(N \times N\) elements, the product \(C = AB\) has elements
\[ C_{ij} = \sum_{k=0}^{N-1} A_{ik} B_{kj} \]
That is, element \((i, j)\) of \(C\) is the dot product of row \(i\) of \(A\) and column \(j\) of \(B\). The row and the column are traversed together, each pair of elements is multiplied, and the products are added. Figure 9.1 computes 1 element of a 4 × 4 product. Row 1 of \(A\) is 0, 1, 3, 2 and column 2 of \(B\) is 0, 2, 1, 1, so \(C_{12}\) = 0 × 0 + 1 × 2 + 3 × 1 + 2 × 1 = 7.
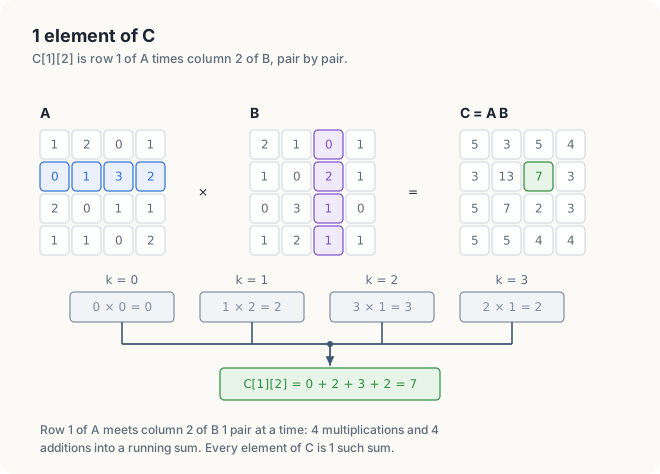
A sequential implementation on a CPU uses 3 nested loops. The 2 outer loops select an element of \(C\), and the inner loop runs over \(k\) along row \(i\) of \(A\) and down column \(j\) of \(B\):
for i ← 0 to N − 1:                 # row of C
    for j ← 0 to N − 1:             # column of C
        sum ← 0
        for k ← 0 to N − 1:
            sum ← sum + A[i][k] × B[k][j]
        C[i][j] ← sum
The single-precision form of this operation is called SGEMM, for single-precision general matrix multiply, after the routine of the BLAS library that computes it. All matrices in this chapter are stored in row-major order: element \((i, j)\) of an \(N \times N\) matrix is at index \(iN + j\).
9.1.2 Operations and memory traffic
Each of the \(N^2\) elements of \(C\) requires \(N\) multiplications and \(N\) additions, so the product performs \(2N^3\) floating-point operations. For \(N\) = 4,096, this is 2 × 4,0963 = 137.4 × 10⁹ operations, or 137.4 GFLOP. At the same time, the product must read \(A\) and \(B\) and write \(C\) at least once. These are \(3N^2\) floats of 4 bytes each, \(12N^2\) bytes, which is 201 MB for \(N\) = 4,096. The ratio of the 2 numbers is the highest arithmetic intensity that the computation can reach: \(2N^3 / 12N^2 = N/6\), or 683 FLOP per byte for \(N\) = 4,096.
| Symbol | Meaning | For \(N\) = 4,096 |
|---|---|---|
| \(2N^3\) | operations | 137.4 GFLOP |
| \(12N^2\) | least possible traffic | 201 MB |
| \(N/6\) | highest possible intensity | 683 FLOP per byte |
We measure the kernels of this chapter on 2 GPUs: a Jetson Orin NX, with an FP32 peak of 2.4 TFLOP/s and 102 GB/s of memory bandwidth, and a Jetson AGX Thor, with 8.1 TFLOP/s and 273 GB/s. In the text we call them the smaller and the larger GPU. The smaller GPU moves 201 MB in 2.0 ms at 102 GB/s and performs 137.4 GFLOP in 57 ms at 2.4 TFLOP/s. The arithmetic takes 28 times as long as the minimum traffic. A kernel whose speed is limited by the arithmetic rate of the hardware is said to be compute-bound, and matrix multiplication can be compute-bound provided that each value crosses from memory to the chip approximately once.
9.1.3 Data reuse
The condition “approximately once” is the central difficulty of this chapter. Each value of \(A\) takes part in \(N\) products. In figure 9.2, \(A_{11}\) is multiplied by each of the 4 values of row 1 of \(B\) and contributes to all 4 elements of row 1 of \(C\). For \(N\) = 4,096, each value is used 4,096 times. Using a value again without loading it from memory again is called reuse.
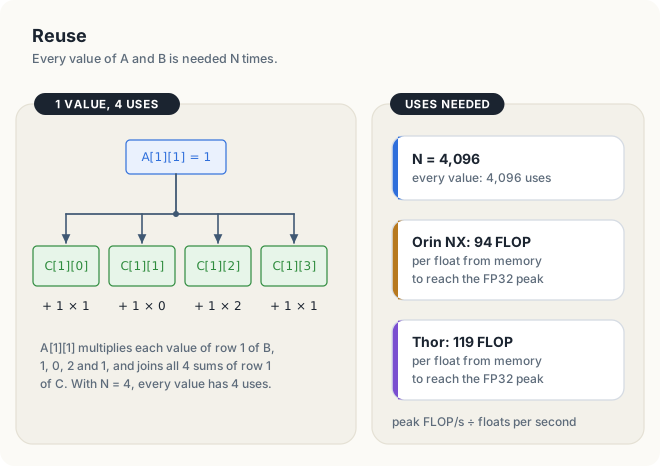
The amount of reuse that a GPU needs follows from 2 of its specifications. The memory delivers a certain number of floats per second, and the arithmetic units perform a certain number of operations per second. The ratio of the 2 is the number of operations that each float loaded from memory must supply if the arithmetic units are never to wait. We count reuse in this unit, FLOP per float, which is 4 times the FLOP per byte of Chapter 2 because a float occupies 4 bytes. For the smaller GPU, 102 GB/s is 102 × 109 / 4 = 25.5 × 10⁹ floats per second, and the FP32 units perform 2,400 × 109 FLOP per second. Therefore, each float loaded from memory must supply 2,400 / 25.5 = 94 operations. The table gives the same ratio for other GPUs.
| GPU | FP32 peak | Memory | FLOP per float needed | 137.4 GFLOP at peak |
|---|---|---|---|---|
| Jetson Orin NX 16 GB | 2.4 TFLOP/s | 102 GB/s | 94 | 57 ms |
| Jetson AGX Thor | 8.1 TFLOP/s | 273 GB/s | 119 | 17 ms |
| DGX Spark (GB10) | ~31 TFLOP/s | 273 GB/s | 454 | 4.4 ms |
| GeForce RTX 4090 | 82.6 TFLOP/s | 1,008 GB/s | 328 | 1.7 ms |
| GeForce RTX 5090 | 104.8 TFLOP/s | 1,792 GB/s | 234 | 1.3 ms |
| A100 SXM 80 GB | 19.5 TFLOP/s | 2,039 GB/s | 38 | 7.0 ms |
| H100 SXM | 67 TFLOP/s | 3,350 GB/s | 80 | 2.1 ms |
The peaks and bandwidths are NVIDIA’s figures from Chapter 2, for the ordinary FP32 units. A product with \(N\) = 4,096 offers 4,096 uses of each value, far more than any GPU in the table requires. The 4 kernels of this chapter differ only in how many of those uses each load from memory delivers. We judge each kernel by its rate, \(2N^3\) divided by its execution time, in GFLOP/s.
A fast matrix product loads each value from memory once and uses it many times from storage closer to the arithmetic units.
9.2 A simple matrix multiplication kernel
The most direct kernel assigns each element of \(C\) to its own thread, and each thread
executes the inner loop of the CPU version. Blocks of 16 × 16 threads cover 16 × 16 elements of
\(C\), so a grid of 4,096 / 16 = 256 × 256 blocks covers the whole matrix. In this first
version, threadIdx.x selects the row of the output element, which follows the order in which
the indices are usually written.
KERNEL byColumn, blocks of 16 × 16 threads:
    row ← blockIdx.x × 16 + threadIdx.x
    col ← blockIdx.y × 16 + threadIdx.y
    sum ← 0
    for k ← 0 to N − 1:
        sum ← sum + A[row][k] × B[k][col]
    C[row][col] ← sum
Listing 9.1 1 thread per element, threadIdx.x along a column of C. code/oxide/ch09_sgemm/src/main.rs code/ch09_sgemm/sgemm.cu
mod kernels {
    // ...
    /// 1 thread per element of C, threadIdx.x along a column of C.
    #[kernel]
    #[launch_contract(domain = 2, coordinates = u32, block = (16, 16, 1))]
    pub fn by_column(a: &[f32], b: &[f32], mut c: DisjointSlice<f32, Index2D<N>>) {
        let row = thread::blockIdx_x() as usize * 16 + thread::threadIdx_x() as usize;
        let col = thread::blockIdx_y() as usize * 16 + thread::threadIdx_y() as usize;

        let mut sum = 0.0;
        let mut k = 0;
        #[unroll(4)]
        while k < N {
            sum += a[row * N + k] * b[k * N + col];
            k += 1;
        }

        // SAFETY: each thread has its own (row, col), so no 2 threads write 1 element.
        unsafe { *c.get_unchecked_mut(row * N + col) = sum };
    }
    // ...
}
// 1. 1 thread per element of C, threadIdx.x along a column of C.
__global__ void byColumn(const float* A, const float* B, float* C)
{
int row = blockIdx.x * 16 + threadIdx.x;
int col = blockIdx.y * 16 + threadIdx.y;
float sum = 0.0f;
for (int k = 0; k < N; ++k) {
sum += A[row * N + k] * B[k * N + col];
}
C[row * N + col] = sum;
}
Each thread first computes the row and column of its output element from its block and thread
indices. The loop over k then reads 1 element of row row of \(A\) and 1 element of column
col of \(B\) in each iteration and accumulates their product in the register sum. After the
loop, the thread writes sum to its element of \(C\). The Rust kernel writes through
get_unchecked_mut, because the 2-D launch contract of section 7.4.3 places x along a row.
C = A B, 4096 x 4096 floats # on a Jetson Orin NX
1 per thread, by column 4017.81 ms 34.2 GFLOP/s max error 3.4e-05
The kernel reaches 34.2 GFLOP/s, 1.4% of the smaller GPU’s peak; on the larger GPU it reaches 116.2 GFLOP/s, also 1.4% of peak. The reason is visible in the loop body. Each multiply-add, 2 FLOP, reads 2 floats from global memory, which is 1 FLOP per float, against the 94 FLOP per float that the smaller GPU needs. In total the kernel requests \(2N^3\) floats, 550 GB. Loaded from memory at 102 GB/s, they would take 5.4 s. The kernel took 4.0 s, so the hardware caches served only a small part of the reuse.
The max error column compares 64 elements of \(C\) with a product computed on the CPU in
double precision. The value 3.4 × 10⁻⁵ is the rounding error of 4,096 float additions,
and every kernel of the chapter shows it.
9.3 Mapping threads to rows for coalesced access
Recall from Chapter 7 that a warp is a group of 32 threads with consecutive threadIdx.x
values that execute each instruction together, and that memory serves a warp in sectors,
aligned pieces of 32 bytes that hold 8 floats (section 7.2). The fewer sectors a warp touches in
one load instruction, the less memory traffic the instruction causes. With blocks of 16 × 16, a
warp consists of 16 values of threadIdx.x for each of 2 values of threadIdx.y.
In listing 9.1, threadIdx.x selects the row. At a given step \(k\), the 16 threads with the
same threadIdx.y read A[row * N + k] from 16 different rows of \(A\). These are 16 sectors
for 16 useful floats. If we exchange the roles of x and y, the 16 threads lie along 1 row of
\(C\). They then all read the same element of \(A\), which the hardware delivers once to all
of them in a broadcast, and 16 adjacent elements of \(B\), 64 bytes in 2 sectors. Figure 9.3
counts the sectors for a whole warp: 17 in the first case and 4 in the second.
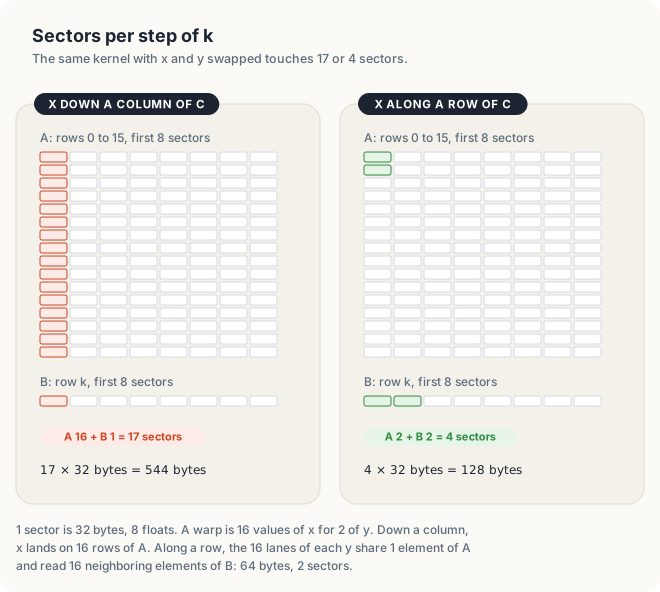
Listing 9.2 1 thread per element, threadIdx.x along a row of C.
mod kernels {
// ...
/// 1 thread per element of C, threadIdx.x along a row of C.
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (16, 16, 1))]
pub fn by_row(a: &[f32], b: &[f32], mut c: DisjointSlice<f32, Index2D<N>>) {
let row = thread::index_2d_row();
let col = thread::index_2d_col();
let mut sum = 0.0;
let mut k = 0;
#[unroll(4)]
while k < N {
sum += a[row * N + k] * b[k * N + col];
k += 1;
}
if let Some(idx) = thread::index_2d::<N>()
&& let Some(out) = c.get_mut(idx)
{
*out = sum;
}
}
// ...
}// 2. The same, threadIdx.x along a row of C.
__global__ void byRow(const float* A, const float* B, float* C)
{
int row = blockIdx.y * 16 + threadIdx.y;
int col = blockIdx.x * 16 + threadIdx.x;
float sum = 0.0f;
for (int k = 0; k < N; ++k) {
sum += A[row * N + k] * B[k * N + col];
}
C[row * N + col] = sum;
}
The only change from listing 9.1 is in the first 2 lines of the kernel: the row now comes from
blockIdx.y and threadIdx.y, and the column from blockIdx.x and threadIdx.x.
The Rust kernel uses the 2-D launch contract of section 7.4.3. The functions
thread::index_2d_row() and index_2d_col() return the row and the column with x along the row,
and the output type DisjointSlice<f32, Index2D<N>> lets each thread write its own element of
\(C\) without unsafe. In Section 9.7, we explain the while loop and the #[unroll(4)] attribute.
1 per thread, by row 739.14 ms 185.9 GFLOP/s max error 3.4e-05 # Orin NX
1 per thread, by row 230.54 ms 596.2 GFLOP/s max error 3.4e-05 # Thor
The same arithmetic now runs 5.4 times as fast on the smaller GPU and 5.1 times as fast on the
larger one, while the bytes per step fell by 544 / 128 = 4.25 times. The kernel still requests
550 GB, now in 0.74 s, which is 744 GB/s, 7.3 times the memory bandwidth of the smaller GPU.
Therefore most requests never reached memory. The reuse does take place, but in hardware caches
whose contents the program does not control. In general, threadIdx.x should index the
dimension that moves along a row in memory.
9.4 Shared-memory tiling
9.4.1 The tiled algorithm
Recall from section 7.4 that shared memory is a small memory inside each SM that is shared by the threads of 1 block and filled explicitly by the program. Tiling moves the reuse from the caches into shared memory, where the program decides which values stay.
A block of \(T \times T\) threads computes a \(T \times T\) tile of \(C\), 1 element per thread. To do so, it needs a strip of \(T\) complete rows of \(A\) and a strip of \(T\) complete columns of \(B\), each \(N\) values long. The block traverses the 2 strips in steps of \(T\) values. At each step, it copies a \(T \times T\) tile of each strip into shared memory, 1 value per thread. Every thread then adds the \(T\) products of its row of the A tile and its column of the B tile.
KERNEL tiled, blocks of T × T threads; thread (x, y) owns C[row][col]:
sum ← 0
for k0 ← 0, T, 2T, …, N − T:
tileA[y][x] ← A[row][k0 + x] # each thread copies 1 value of A
tileB[y][x] ← B[k0 + y][col] # and 1 value of B
wait until the whole block has copied
for k ← 0 to T − 1:
sum ← sum + tileA[y][k] × tileB[k][x]
wait until the whole block has read
C[row][col] ← sum
Figure 9.4 shows 1 step with \(N\) = 8 and \(T\) = 2. The block owns the tile of \(C\) in rows 2 and 3 and columns 4 and 5. Each value in shared memory is read by 2 threads: an element of the A tile by the 2 threads of its row, and an element of the B tile by the 2 threads of its column. With tiles of 16 × 16, each value copied is read 16 times, so the number of global memory reads falls by a factor of 16.
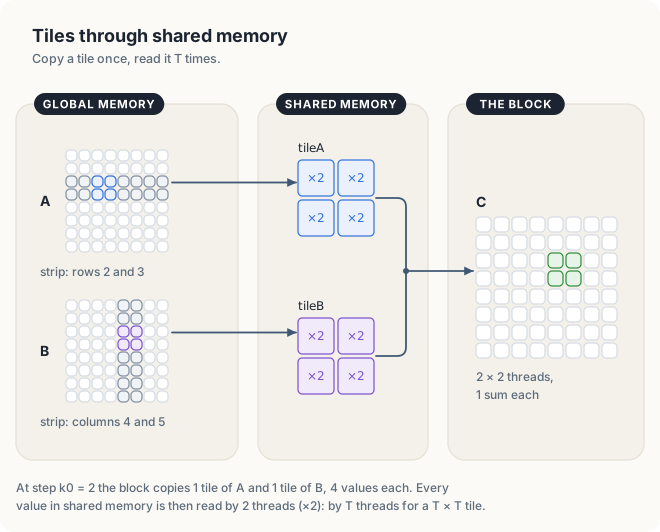
Animation 1 shows the same block through all 4 steps.
Listing 9.3 The tiled kernel.
mod kernels {
// ...
/// A block of 16 x 16 threads computes a 16 x 16 tile of C, from shared memory.
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (16, 16, 1))]
pub fn tiled(a: &[f32], b: &[f32], mut c: DisjointSlice<f32, Index2D<N>>) {
static mut TILE_A: SharedArray<f32, 256> = SharedArray::UNINIT;
static mut TILE_B: SharedArray<f32, 256> = SharedArray::UNINIT;
let x = thread::threadIdx_x() as usize;
let y = thread::threadIdx_y() as usize;
let row = thread::index_2d_row();
let col = thread::index_2d_col();
let mut sum = 0.0;
let mut k0 = 0;
while k0 < N {
// SAFETY: each thread writes only its own slot of each tile.
unsafe {
TILE_A[y * 16 + x] = a[row * N + k0 + x];
TILE_B[y * 16 + x] = b[(k0 + y) * N + col];
}
thread::sync_threads();
let mut k = 0;
#[unroll]
while k < 16 {
// SAFETY: between the 2 barriers the tiles are only read.
sum += unsafe { TILE_A[y * 16 + k] * TILE_B[k * 16 + x] };
k += 1;
}
thread::sync_threads();
k0 += 16;
}
if let Some(idx) = thread::index_2d::<N>()
&& let Some(out) = c.get_mut(idx)
{
*out = sum;
}
}
// ...
}// 3. A block of T x T threads computes a T x T tile of C, from tiles in shared memory.
template <int T>
__global__ void tiled(const float* A, const float* B, float* C)
{
__shared__ float tileA[T][T];
__shared__ float tileB[T][T];
int x = threadIdx.x;
int y = threadIdx.y;
int row = blockIdx.y * T + y;
int col = blockIdx.x * T + x;
float sum = 0.0f;
for (int k0 = 0; k0 < N; k0 += T) {
tileA[y][x] = A[row * N + k0 + x];
tileB[y][x] = B[(k0 + y) * N + col];
__syncthreads();
for (int k = 0; k < T; ++k) {
sum += tileA[y][k] * tileB[k][x];
}
__syncthreads();
}
C[row * N + col] = sum;
}
The kernel declares the 2 tiles as __shared__ arrays of \(T \times T\) floats. In each
iteration of the outer loop over k0, every thread copies 1 element of \(A\) into tileA and
1 element of \(B\) into tileB. Both copies are coalesced, because threads with adjacent x
read adjacent elements of a row of \(A\) and of a row of \(B\). The first __syncthreads()
ensures that no thread reads a tile before all of it has been written. The inner loop then
computes \(T\) products from shared memory. The second __syncthreads() ensures that no thread
overwrites a tile in the next iteration while another thread is still reading it.
In Rust, the tiles are SharedArrays declared static mut, as in Chapter 8, and the barrier is
thread::sync_threads(). A write to shared memory is unsafe, because the compiler cannot prove
that 2 threads never write the same element. The SAFETY comment states why they do not.
9.4.2 Global and shared memory reads of the tiled kernel
Let us count the reads of 1 step with tiles of 16 × 16. The block copies 2 tiles of 16 × 16 floats from global memory, 512 floats. Its 256 threads each perform 16 multiply-adds, which is 256 × 16 × 2 = 8,192 FLOP. The reuse from global memory is therefore 8,192 / 512 = 16 FLOP per float, and \(T\) FLOP per float in general. Each multiply-add still reads 2 values from shared memory, 1 from each tile.
At 16 FLOP per float, the 25.5 × 10⁹ floats per second of the smaller GPU can supply at most 16 × 25.5 = 408 GFLOP/s, and the 68.25 × 10⁹ floats per second of the larger GPU at most 1,092 GFLOP/s.
tiles of 16 x 16 501.76 ms 273.9 GFLOP/s max error 3.4e-05 # Orin NX
tiles of 16 x 16 144.69 ms 949.9 GFLOP/s max error 3.4e-05 # Thor
The tiled kernel reaches 67% of this limit on the smaller GPU and 87% on the larger one. However, a second limit lies close behind the first, in shared memory itself. The shared memory of each SM delivers 128 bytes per cycle from 32 banks of 4 bytes, which is 32 floats. The 128 FP32 units of the SM perform 128 multiply-adds per cycle. At 2 shared-memory reads per multiply-add, the units would request 256 floats per cycle, 8 times what shared memory delivers. Broadcasts make some of those reads cheaper, but no choice of tile size changes the 2 reads per multiply-add. Only a kernel that performs fewer shared-memory reads per multiply-add can remove this limit.
9.5 Register tiling with 4 × 4 output patches
9.5.1 Computing several outputs per thread
In the tiled kernel, each thread computes 1 sum, so each multiply-add needs 2 new operands. A thread that computes a 4 × 4 patch of \(C\) keeps 16 sums in registers. For each \(k\), it reads 4 values of \(A\), 1 from each of its 4 rows, and 4 values of \(B\), 1 from each of its 4 columns, and multiplies every pair. Figure 9.5 shows 1 value of \(k\): the values 1, 2, 0, 3 of \(A\) and 2, 1, 0, 1 of \(B\) give 16 products from 8 reads. In linear algebra, the 16 products form an outer product. Keeping several results of each thread in registers in this way is called register tiling.
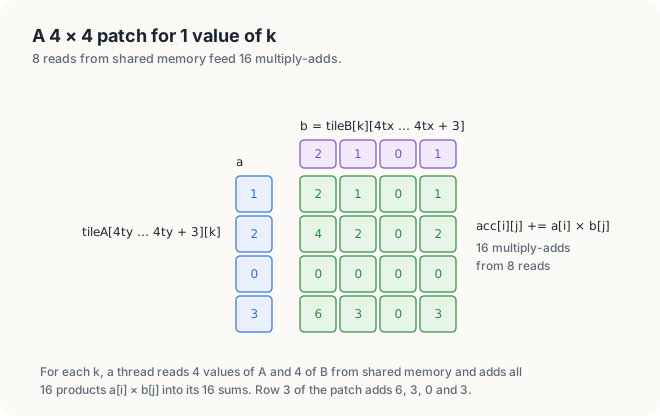
Animation 2 shows 3 values of \(k\), with each outer product added into the 16 sums.
9.5.2 Assigning output elements to threads
A block of 256 threads, arranged as 16 × 16, now computes a 64 × 64 tile of \(C\): 4,096 elements, 16 per thread. Thread \((t_x, t_y)\) computes rows \(4t_y\) to \(4t_y + 3\) and columns \(4t_x\) to \(4t_x + 3\) of the block’s tile, as figure 9.6 shows. The grid has 4,096 / 64 = 64 blocks along each side, 4,096 blocks in all.
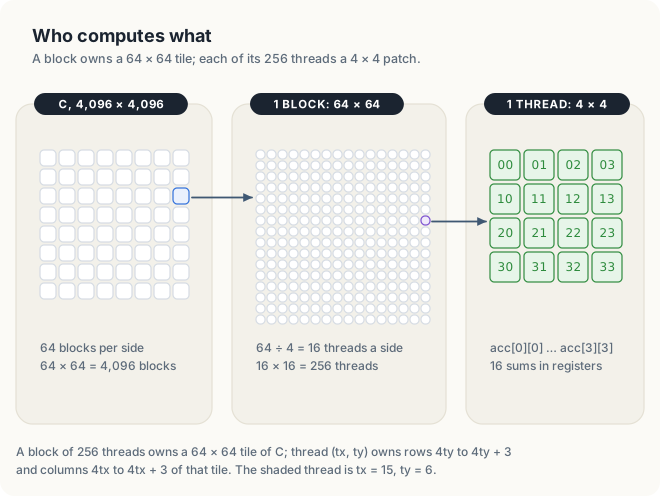
At each step the block copies a 64 × 16 tile of \(A\) and a 16 × 64 tile of \(B\), 1,024 floats each, so each of the 256 threads copies 4 values of each.
KERNEL patches, blocks of 256 threads; thread (tx, ty) owns a 4 × 4 patch:
acc[4][4] ← 0 # 16 sums, in registers
for k0 ← 0, 16, 32, …, N − 16:
copy a 64 × 16 tile of A and a 16 × 64 tile of B, 4 values of each per thread
wait until the whole block has copied
for k ← 0 to 15:
a[0..3] ← tileA[4ty .. 4ty + 3][k] # 4 reads
b[0..3] ← tileB[k][4tx .. 4tx + 3] # 4 reads
for i, j ← 0 to 3:
acc[i][j] ← acc[i][j] + a[i] × b[j] # 16 multiply-adds
wait until the whole block has read
write the 16 sums to C
9.5.3 The register-tiled kernel
Listing 9.4 The 4 × 4 patch kernel.
mod kernels {
// ...
/// A block of 256 threads computes a 64 x 64 tile of C, each thread a 4 x 4 patch.
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (16, 16, 1))]
pub fn patches(a: &[f32], b: &[f32], mut c: DisjointSlice<f32, Index2D<N>>) {
static mut TILE_A: SharedArray<f32, { 64 * 17 }> = SharedArray::UNINIT;
static mut TILE_B: SharedArray<f32, { 16 * 64 }> = SharedArray::UNINIT;
let tx = thread::threadIdx_x() as usize;
let ty = thread::threadIdx_y() as usize;
let row0 = thread::blockIdx_y() as usize * 64;
let col0 = thread::blockIdx_x() as usize * 64;
let mut acc = [[0.0f32; 4]; 4];
let mut k0 = 0;
while k0 < N {
let mut e = ty * 16 + tx;
while e < 1024 {
// SAFETY: element e of each tile is written by 1 thread.
unsafe {
TILE_A[e / 16 * 17 + e % 16] = a[(row0 + e / 16) * N + k0 + e % 16];
TILE_B[e] = b[(k0 + e / 64) * N + col0 + e % 64];
}
e += 256;
}
thread::sync_threads();
let mut k = 0;
#[unroll]
while k < 16 {
let mut av = [0.0f32; 4];
let mut bv = [0.0f32; 4];
let mut i = 0;
#[unroll]
while i < 4 {
// SAFETY: between the 2 barriers the tiles are only read.
unsafe {
av[i] = TILE_A[(ty * 4 + i) * 17 + k];
bv[i] = TILE_B[k * 64 + tx * 4 + i];
}
i += 1;
}
let mut ij = 0;
#[unroll]
while ij < 16 {
acc[ij / 4][ij % 4] += av[ij / 4] * bv[ij % 4];
ij += 1;
}
k += 1;
}
thread::sync_threads();
k0 += 16;
}
for i in 0..4 {
for j in 0..4 {
let at = (row0 + ty * 4 + i) * N + col0 + tx * 4 + j;
// SAFETY: the 4 x 4 patches of all threads cover C once, without overlap.
unsafe { *c.get_unchecked_mut(at) = acc[i][j] };
}
}
}
}// 4. A block of 256 threads computes a 64 x 64 tile of C, each thread a 4 x 4 patch of it.
template <int MIN_BLOCKS>
__global__ void __launch_bounds__(256, MIN_BLOCKS)
patches(const float* A, const float* B, float* C)
{
__shared__ float tileA[64][16 + 1]; // 1 column of padding (Chapter 7)
__shared__ float tileB[16][64];
int tx = threadIdx.x % 16;
int ty = threadIdx.x / 16;
int row0 = blockIdx.y * 64;
int col0 = blockIdx.x * 64;
float acc[4][4] = {};
for (int k0 = 0; k0 < N; k0 += 16) {
for (int e = threadIdx.x; e < 64 * 16; e += 256) {
tileA[e / 16][e % 16] = A[(row0 + e / 16) * N + k0 + e % 16];
tileB[e / 64][e % 64] = B[(k0 + e / 64) * N + col0 + e % 64];
}
__syncthreads();
for (int k = 0; k < 16; ++k) {
float a[4], b[4];
for (int i = 0; i < 4; ++i) {
a[i] = tileA[ty * 4 + i][k];
b[i] = tileB[k][tx * 4 + i];
}
for (int i = 0; i < 4; ++i) {
for (int j = 0; j < 4; ++j) {
acc[i][j] += a[i] * b[j];
}
}
}
__syncthreads();
}
for (int i = 0; i < 4; ++i) {
for (int j = 0; j < 4; ++j) {
C[(row0 + ty * 4 + i) * N + col0 + tx * 4 + j] = acc[i][j];
}
}
}
The kernel begins by computing the thread’s position (tx, ty) in the 16 × 16 arrangement and
the first row and column, row0 and col0, of the block’s tile. The array acc holds the 16
sums. In each iteration over k0, the loop over e copies the 2 tiles, 4 elements of each per
thread, and the barrier waits for the copy to finish. For each of the 16 values of k, the thread
then loads its 4 values of tileA into a and its 4 values of tileB into b, and the 2 nested
loops over i and j add the 16 products into acc. After the last step, the thread writes its
16 sums to \(C\).
The A tile has 1 column of padding. The threads of a warp with the same ty read the same
tileA element, which is a broadcast. The 2 values of ty within a warp read rows that are 4
apart. Without padding, these are 4 × 16 = 64 words apart and fall in the same bank; with 17
columns they are 68 words apart, which places them 4 banks apart (section 7.5). The template
parameter MIN_BLOCKS and __launch_bounds__ are discussed in section 9.6; with MIN_BLOCKS
= 1 they have no effect.
The Rust kernel writes 16 elements per thread, which thread::index_2d cannot express. It
therefore writes through get_unchecked_mut, with the argument that the patches of all threads
cover \(C\) exactly once.
We can now count the reads of 1 step of the 64 × 64 tile. The block reads 64 × 16 + 16 × 64 = 2,048 floats from global memory and performs 64 × 64 elements × 16 values of \(k\) × 2 = 131,072 FLOP. The reuse from global memory is therefore 131,072 / 2,048 = 64 FLOP per float, 4 times that of the 16 × 16 tile. Each thread makes 8 shared-memory reads for 16 multiply-adds, so the kernel performs 0.5 shared-memory reads per multiply-add, against 2 in the tiled kernel.
4 x 4 per thread 152.47 ms 901.4 GFLOP/s max error 3.4e-05 # Orin NX
4 x 4 per thread 42.66 ms 3222.0 GFLOP/s max error 3.4e-05 # Thor
Register tiling makes the product 3.3 times as fast on the smaller GPU and 3.4 times as fast on the larger one: 901.4 GFLOP/s, 38% of the smaller GPU’s peak, and 3,222.0 GFLOP/s, 40% of the larger GPU’s peak. At 64 FLOP per float, memory could now supply 1,632 GFLOP/s on the smaller GPU and 4,368 GFLOP/s on the larger one, so memory bandwidth is no longer the first limit. Figure 9.7 compares the three kernels by the number of floats that 1 thread reads for 16 multiply-adds, and where it reads them from.
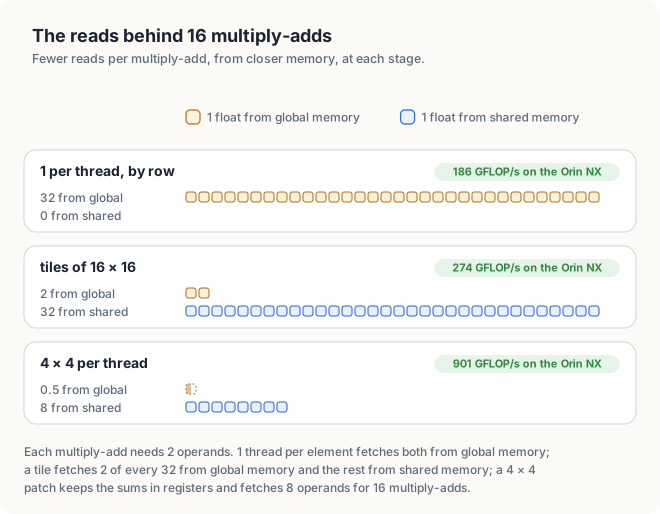
9.6 Occupancy and launch bounds
9.6.1 Register usage and occupancy
The 16 sums, the 8 operands and the indices of the patch kernel are held in registers. Recall from
Chapter 2 that occupancy is the number of warps resident on an SM relative to the maximum
number the SM can hold. Each SM of both GPUs has 65,536 registers and can hold at most 1,536
threads. The program asks the CUDA runtime how many registers the compiler assigned to each
kernel, with cudaFuncGetAttributes, and how many blocks of a kernel fit on an SM, with
cudaOccupancyMaxActiveBlocksPerMultiprocessor.
Listing 9.5 Querying registers and occupancy.
/// Registers per thread, blocks per SM and spilled bytes, as the GPU reports them.
fn resources(
module: &kernels::LoadedModule,
name: &str,
kernel: &str,
) -> Result<(), Error> {
let function = module.as_cuda_module().load_function(kernel)?;
let registers = function.num_registers()?;
let blocks = function.max_active_blocks_per_multiprocessor(256, 0)?;
let spilled = function.local_size_bytes()?;
print!(" {name:<26} {registers:3} registers");
print!(" {blocks} blocks per SM");
println!(" {spilled:2} bytes spilled");
Ok(())
}// Registers per thread, blocks per SM and spilled bytes, as the GPU reports them.
template <typename K>
void resources(const char* name, K kernel, int threads)
{
cudaFuncAttributes attr;
check(cudaFuncGetAttributes(&attr, kernel));
int blocks;
check(cudaOccupancyMaxActiveBlocksPerMultiprocessor(&blocks, kernel, threads, 0));
std::printf(" %-26s %3d registers", name, attr.numRegs);
std::printf(" %d blocks per SM", blocks);
std::printf(" %2zu bytes spilled\n", attr.localSizeBytes);
}
In Rust, num_registers, local_size_bytes and max_active_blocks_per_multiprocessor are
methods of the CudaFunction that the loaded module returns for a kernel name.
resources # Orin NX
tiles of 16 x 16 38 registers 6 blocks per SM 0 bytes spilled
tiles of 32 x 32 37 registers 1 blocks per SM 0 bytes spilled
4 x 4 per thread 80 registers 3 blocks per SM 0 bytes spilled
4 x 4, at least 4 blocks 64 registers 4 blocks per SM 0 bytes spilled
4 x 4, at least 6 blocks 40 registers 6 blocks per SM 16 bytes spilled
At 80 registers per thread, a block of 256 threads needs 80 × 256 = 20,480 registers. Since 65,536 / 20,480 = 3.2, 3 blocks fit on an SM: 768 threads, half of the 1,536 that the SM can hold (figure 9.8). The tiled kernel uses 38 registers per thread, so 6 blocks fit, 1,536 threads, which reaches the thread limit.
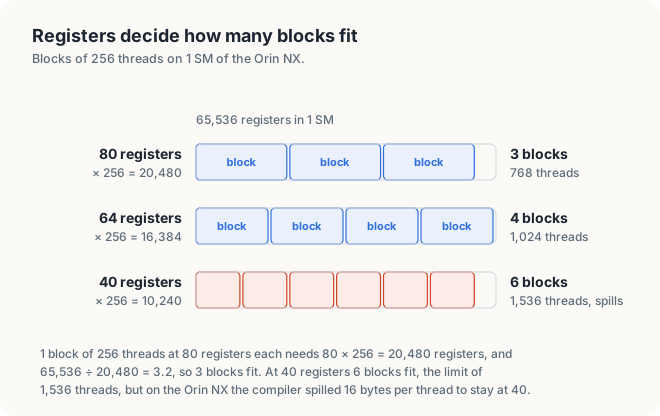
A tile of 32 × 32 requires a block of 1,024 threads, so only 1 block fits on an SM. At each of its barriers, every thread on the SM waits, and no other block is available to run in the meantime. As a result, the 32 × 32 tile ran at 222.1 GFLOP/s against 273.9 GFLOP/s for the 16 × 16 tile on the smaller GPU, and at 783.4 against 949.9 GFLOP/s on the larger one, even though it offers twice the reuse.
9.6.2 __launch_bounds__
The qualifier __launch_bounds__(maxThreads, minBlocks) tells the compiler that the kernel is
launched with at most maxThreads threads per block and that at least minBlocks blocks should
fit on an SM. The compiler then limits the number of registers per thread to make this possible.
When the kernel needs more registers than the limit allows, the compiler spills: it keeps some
values in local memory, a per-thread area of global memory accessed through the caches, and loads
them back when they are needed.
4 x 4 per thread 152.47 ms 901.4 GFLOP/s # Orin NX
4 x 4, at least 4 blocks 147.48 ms 931.9 GFLOP/s
4 x 4, at least 6 blocks 147.91 ms 929.2 GFLOP/s
4 x 4 per thread 42.66 ms 3222.0 GFLOP/s # Thor
4 x 4, at least 4 blocks 42.30 ms 3249.4 GFLOP/s
4 x 4, at least 6 blocks 42.10 ms 3264.2 GFLOP/s
On the smaller GPU, requesting 4 blocks reduced the registers to 64 and gained 3%. Requesting 6 blocks reduced them to 40, spilled 16 bytes per thread, and gained the same 3%. On the larger GPU, the compiler chose 48 registers without any bound, which allows 5 blocks per SM, and requesting 6 blocks gained 1%. Doubling the number of resident warps therefore gained at most 3%. Additional warps help only while the kernel waits for something that they can hide, and each thread of the patch kernel already has 16 independent multiply-adds to issue.
Occupancy is a means, not a goal. __launch_bounds__ trades registers for blocks, and the trade
can cause spills; measure each setting.
9.7 Loop unrolling in cuda-oxide
The Rust kernels of listings 9.1 to 9.4 write their loops as while loops marked with
#[unroll], a cuda-oxide attribute that asks the compiler to replicate the loop body once per
iteration. After unrolling, a loop over i from 0 to 3 becomes 4 copies of its body, with i a
constant in each copy. The expressions av[i] and acc[i][j] then refer to fixed registers, and
the bounds check of every index into a fixed-size array is removed. A loop that is not unrolled
must keep acc in memory, because an instruction cannot select a register by an index computed
at run time. The CUDA C++ compiler unrolls short loops with constant bounds automatically.
cuda-oxide, at the revision used in this book, unrolls only loops marked #[unroll], and it does
not unroll for loops over ranges.
The first version of the crate used for loops. The table compares that version with the same
kernels compiled with #[kernel(unchecked_indexing)], which removes every bounds check, and with
the while loops of the listings.
| Rust kernel on the Orin NX | for loops | for loops, unchecked_indexing | while loops, #[unroll] |
|---|---|---|---|
| 1 per thread | 62.4 GFLOP/s | 71.3 GFLOP/s | 193.2 GFLOP/s |
| tiles of 16 × 16 | 201.8 GFLOP/s | 275.1 GFLOP/s | 274.7 GFLOP/s |
| 4 × 4 per thread | 575.6 GFLOP/s | 595.4 GFLOP/s | 844.9 GFLOP/s |
With #[kernel(unchecked_indexing)], an index out of range is undefined behavior, as in C++.
Removing the checks helped the tiled kernel, whose cost was the checks, but not the patch kernel,
whose cost was keeping its arrays in memory. The listings therefore keep the bounds checks and
unroll the loops.
$ cargo oxide run # on a Jetson Orin NX
C = A B, 4096 x 4096 floats
1 per thread 711.52 ms 193.2 GFLOP/s max error 3.4e-5
tiles of 16 x 16 500.39 ms 274.7 GFLOP/s max error 3.4e-5
4 x 4 per thread 162.67 ms 844.9 GFLOP/s max error 3.4e-5
$ cargo oxide run # on a Jetson AGX Thor
C = A B, 4096 x 4096 floats
1 per thread 209.81 ms 655.1 GFLOP/s max error 3.4e-5
tiles of 16 x 16 146.99 ms 935.0 GFLOP/s max error 3.4e-5
4 x 4 per thread 47.69 ms 2881.8 GFLOP/s max error 3.4e-5
The Rust kernels match the C++ kernels within 10% for one element per thread and for tiles, and reach 94% and 89% of the C++ patch kernel on the 2 GPUs.
Why can an unrolled loop keep acc[i][j] in registers, and a loop that is not unrolled cannot?
Registers have fixed names that are chosen when the program is compiled; no instruction selects a
register by a value computed at run time. After unrolling, every acc[i][j] has constant i and
j, so each one names 1 register. In a loop, i changes at run time, so acc must be placed in
memory that can be indexed: local memory.
9.8 Comparison with cuBLAS
The program also times cuBLAS’s cublasSgemm on the same matrices. cuBLAS stores matrices in
column-major order, so the call asks it for \(B^T A^T\), which in row-major storage is
\(AB\).
$ ./sgemm # on a Jetson Orin NX
GPU: Orin, 8 SMs
C = A B, 4096 x 4096 floats
1 per thread, by column 4017.81 ms 34.2 GFLOP/s max error 3.4e-05
1 per thread, by row 739.14 ms 185.9 GFLOP/s max error 3.4e-05
tiles of 16 x 16 501.76 ms 273.9 GFLOP/s max error 3.4e-05
tiles of 32 x 32 618.78 ms 222.1 GFLOP/s max error 3.4e-05
4 x 4 per thread 152.47 ms 901.4 GFLOP/s max error 3.4e-05
4 x 4, at least 4 blocks 147.48 ms 931.9 GFLOP/s max error 3.4e-05
4 x 4, at least 6 blocks 147.91 ms 929.2 GFLOP/s max error 3.4e-05
cuBLAS 91.92 ms 1495.3 GFLOP/s max error 1.9e-05
$ ./sgemm # on a Jetson AGX Thor
GPU: NVIDIA Thor, 20 SMs
C = A B, 4096 x 4096 floats
1 per thread, by column 1183.23 ms 116.2 GFLOP/s max error 3.4e-05
1 per thread, by row 230.54 ms 596.2 GFLOP/s max error 3.4e-05
tiles of 16 x 16 144.69 ms 949.9 GFLOP/s max error 3.4e-05
tiles of 32 x 32 175.43 ms 783.4 GFLOP/s max error 3.4e-05
4 x 4 per thread 42.66 ms 3222.0 GFLOP/s max error 3.4e-05
4 x 4, at least 4 blocks 42.30 ms 3249.4 GFLOP/s max error 3.4e-05
4 x 4, at least 6 blocks 42.10 ms 3264.2 GFLOP/s max error 3.4e-05
cuBLAS 22.25 ms 6176.5 GFLOP/s max error 3.4e-05
From the first kernel to the best, the product became 27 times as fast on the smaller GPU, from 34.2 to 931.9 GFLOP/s, and 28 times as fast on the larger one, from 116.2 to 3,264.2 GFLOP/s. The best kernel reaches 39% and 40% of the FP32 peak. cuBLAS reaches 62% and 76%, so the best kernel of this chapter runs at 62% and 53% of the speed of cuBLAS (figure 9.9). Repeated runs on each GPU agreed within 2%.
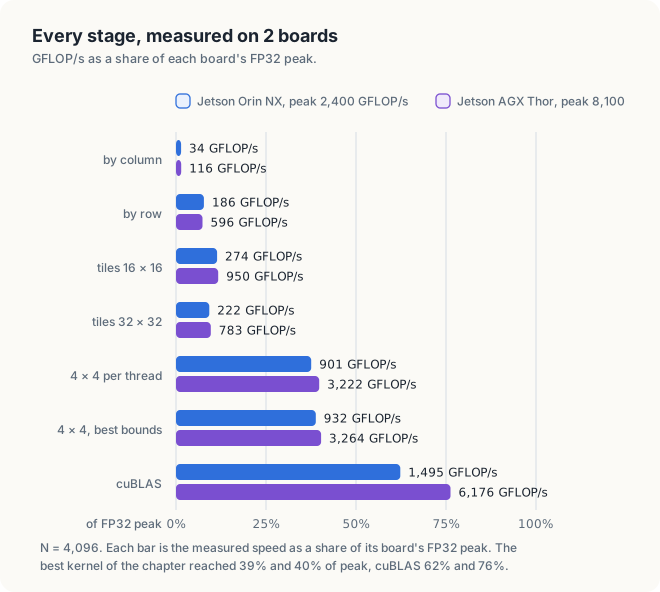
The remaining gap comes from techniques beyond the scope of this chapter, which cuBLAS combines and tunes for each GPU:
- Larger patches. With 8 × 8 elements per thread, a kernel reads shared memory 8 times less than with one element per thread, against 4 times less for 4 × 4, at the cost of more registers.
- Wide shared-memory loads. 4 operands can be read with 1
float4load, as in Chapter 7. - Double buffering. The next pair of tiles is copied while the current pair is used, so that the barrier never waits for memory.
- Warp tiling. The patches of each warp are arranged so that its shared-memory reads fall in as few banks and instructions as possible.
Tensor cores, units that multiply small matrices in 1 instruction, are faster still. In their TF32 mode they keep 10 bits of the float’s mantissa instead of 23, so cuBLAS uses them for SGEMM only when the program allows it. Chapter 11 returns to cuBLAS.
9.9 The complete programs
Listing 9.6 The complete programs. code/oxide/ch09_sgemm/src/main.rs code/ch09_sgemm/sgemm.cu
//! Chapter 9 in Rust: matrix multiplication by rows, by shared tiles, by 4 x 4 patches.
//!
//! cargo oxide run
use std::time::Instant;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, LaunchConfig2D};
use cuda_device::thread::Index2D;
use cuda_device::{DisjointSlice, SharedArray, cuda_module, kernel, launch_contract, thread};
const N: usize = 4096; // C = A B, all N x N, stored row by row
type Error = Box<dyn std::error::Error>;
#[cuda_module]
mod kernels {
use super::*;
/// 1 thread per element of C, threadIdx.x along a column of C.
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (16, 16, 1))]
pub fn by_column(a: &[f32], b: &[f32], mut c: DisjointSlice<f32, Index2D<N>>) {
let row = thread::blockIdx_x() as usize * 16 + thread::threadIdx_x() as usize;
let col = thread::blockIdx_y() as usize * 16 + thread::threadIdx_y() as usize;
let mut sum = 0.0;
let mut k = 0;
#[unroll(4)]
while k < N {
sum += a[row * N + k] * b[k * N + col];
k += 1;
}
// SAFETY: each thread has its own (row, col), so no 2 threads write 1 element.
unsafe { *c.get_unchecked_mut(row * N + col) = sum };
}
/// 1 thread per element of C, threadIdx.x along a row of C.
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (16, 16, 1))]
pub fn by_row(a: &[f32], b: &[f32], mut c: DisjointSlice<f32, Index2D<N>>) {
let row = thread::index_2d_row();
let col = thread::index_2d_col();
let mut sum = 0.0;
let mut k = 0;
#[unroll(4)]
while k < N {
sum += a[row * N + k] * b[k * N + col];
k += 1;
}
if let Some(idx) = thread::index_2d::<N>()
&& let Some(out) = c.get_mut(idx)
{
*out = sum;
}
}
/// A block of 16 x 16 threads computes a 16 x 16 tile of C, from shared memory.
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (16, 16, 1))]
pub fn tiled(a: &[f32], b: &[f32], mut c: DisjointSlice<f32, Index2D<N>>) {
static mut TILE_A: SharedArray<f32, 256> = SharedArray::UNINIT;
static mut TILE_B: SharedArray<f32, 256> = SharedArray::UNINIT;
let x = thread::threadIdx_x() as usize;
let y = thread::threadIdx_y() as usize;
let row = thread::index_2d_row();
let col = thread::index_2d_col();
let mut sum = 0.0;
let mut k0 = 0;
while k0 < N {
// SAFETY: each thread writes only its own slot of each tile.
unsafe {
TILE_A[y * 16 + x] = a[row * N + k0 + x];
TILE_B[y * 16 + x] = b[(k0 + y) * N + col];
}
thread::sync_threads();
let mut k = 0;
#[unroll]
while k < 16 {
// SAFETY: between the 2 barriers the tiles are only read.
sum += unsafe { TILE_A[y * 16 + k] * TILE_B[k * 16 + x] };
k += 1;
}
thread::sync_threads();
k0 += 16;
}
if let Some(idx) = thread::index_2d::<N>()
&& let Some(out) = c.get_mut(idx)
{
*out = sum;
}
}
/// A block of 256 threads computes a 64 x 64 tile of C, each thread a 4 x 4 patch.
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (16, 16, 1))]
pub fn patches(a: &[f32], b: &[f32], mut c: DisjointSlice<f32, Index2D<N>>) {
static mut TILE_A: SharedArray<f32, { 64 * 17 }> = SharedArray::UNINIT;
static mut TILE_B: SharedArray<f32, { 16 * 64 }> = SharedArray::UNINIT;
let tx = thread::threadIdx_x() as usize;
let ty = thread::threadIdx_y() as usize;
let row0 = thread::blockIdx_y() as usize * 64;
let col0 = thread::blockIdx_x() as usize * 64;
let mut acc = [[0.0f32; 4]; 4];
let mut k0 = 0;
while k0 < N {
let mut e = ty * 16 + tx;
while e < 1024 {
// SAFETY: element e of each tile is written by 1 thread.
unsafe {
TILE_A[e / 16 * 17 + e % 16] = a[(row0 + e / 16) * N + k0 + e % 16];
TILE_B[e] = b[(k0 + e / 64) * N + col0 + e % 64];
}
e += 256;
}
thread::sync_threads();
let mut k = 0;
#[unroll]
while k < 16 {
let mut av = [0.0f32; 4];
let mut bv = [0.0f32; 4];
let mut i = 0;
#[unroll]
while i < 4 {
// SAFETY: between the 2 barriers the tiles are only read.
unsafe {
av[i] = TILE_A[(ty * 4 + i) * 17 + k];
bv[i] = TILE_B[k * 64 + tx * 4 + i];
}
i += 1;
}
let mut ij = 0;
#[unroll]
while ij < 16 {
acc[ij / 4][ij % 4] += av[ij / 4] * bv[ij % 4];
ij += 1;
}
k += 1;
}
thread::sync_threads();
k0 += 16;
}
for i in 0..4 {
for j in 0..4 {
let at = (row0 + ty * 4 + i) * N + col0 + tx * 4 + j;
// SAFETY: the 4 x 4 patches of all threads cover C once, without overlap.
unsafe { *c.get_unchecked_mut(at) = acc[i][j] };
}
}
}
}
/// Average time of `runs` runs of `launch`, in milliseconds, after 1 warm-up run.
fn time_ms<F>(stream: &CudaStream, runs: u32, mut launch: F) -> Result<f64, Error>
where
F: FnMut() -> Result<(), Error>,
{
launch()?;
stream.synchronize()?;
let start = Instant::now();
for _ in 0..runs {
launch()?;
}
stream.synchronize()?;
Ok(start.elapsed().as_secs_f64() * 1e3 / runs as f64)
}
/// Registers per thread, blocks per SM and spilled bytes, as the GPU reports them.
fn resources(
module: &kernels::LoadedModule,
name: &str,
kernel: &str,
) -> Result<(), Error> {
let function = module.as_cuda_module().load_function(kernel)?;
let registers = function.num_registers()?;
let blocks = function.max_active_blocks_per_multiprocessor(256, 0)?;
let spilled = function.local_size_bytes()?;
print!(" {name:<26} {registers:3} registers");
print!(" {blocks} blocks per SM");
println!(" {spilled:2} bytes spilled");
Ok(())
}
/// Values in [-0.5, 0.5) from a small linear congruential generator.
fn random(n: usize, state: &mut u32) -> Vec<f32> {
let mut values = Vec::with_capacity(n);
for _ in 0..n {
*state = state.wrapping_mul(1_664_525).wrapping_add(1_013_904_223);
values.push((*state >> 8) as f32 / 16_777_216.0 - 0.5);
}
values
}
/// The largest difference from a double-precision product, over 64 elements of C.
fn max_error(a: &[f32], b: &[f32], c: &[f32]) -> f64 {
let mut worst: f64 = 0.0;
for s in 0..64 {
let i = s * 977 % N;
let j = (s * 1231 + 7) % N;
let mut exact = 0.0;
for k in 0..N {
exact += a[i * N + k] as f64 * b[k * N + j] as f64;
}
worst = worst.max((exact - c[i * N + j] as f64).abs());
}
worst
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let mut state = 1;
let a_host = random(N * N, &mut state);
let b_host = random(N * N, &mut state);
let a = DeviceBuffer::from_host(&stream, &a_host)?;
let b = DeviceBuffer::from_host(&stream, &b_host)?;
let mut c = DeviceBuffer::<f32>::zeroed(&stream, N * N)?;
let g16 = (N / 16) as u32;
let g64 = (N / 64) as u32;
let columns = module.prepare_by_column(LaunchConfig2D::new((g16, g16), (16, 16), 0))?;
let rows = module.prepare_by_row(LaunchConfig2D::new((g16, g16), (16, 16), 0))?;
let tiles = module.prepare_tiled(LaunchConfig2D::new((g16, g16), (16, 16), 0))?;
let patch = module.prepare_patches(LaunchConfig2D::new((g64, g64), (16, 16), 0))?;
// Warm up: the clocks rise under sustained load.
for _ in 0..10 {
time_ms(&stream, 5, || Ok(module.patches(&stream, &patch, &a, &b, &mut c)?))?;
}
let report = |name: &str, ms: f64, c: &DeviceBuffer<f32>| -> Result<(), Error> {
let gflops = 2.0 * (N * N * N) as f64 / ms / 1e6;
let error = max_error(&a_host, &b_host, &c.to_host_vec(&stream)?);
println!(" {name:<26} {ms:8.2} ms {gflops:7.1} GFLOP/s max error {error:.1e}");
Ok(())
};
println!("C = A B, {N} x {N} floats");
let launch = || Ok(module.by_column(&stream, &columns, &a, &b, &mut c)?);
let ms = time_ms(&stream, 2, launch)?;
report("1 per thread, by column", ms, &c)?;
let ms = time_ms(&stream, 3, || Ok(module.by_row(&stream, &rows, &a, &b, &mut c)?))?;
report("1 per thread, by row", ms, &c)?;
let ms = time_ms(&stream, 5, || Ok(module.tiled(&stream, &tiles, &a, &b, &mut c)?))?;
report("tiles of 16 x 16", ms, &c)?;
let ms = time_ms(&stream, 10, || Ok(module.patches(&stream, &patch, &a, &b, &mut c)?))?;
report("4 x 4 per thread", ms, &c)?;
println!("resources");
resources(&module, "tiles of 16 x 16", "tiled")?;
resources(&module, "4 x 4 per thread", "patches")?;
Ok(())
}// Chapter 9: matrix multiplication, from 1 thread per element to a 4 x 4 patch per thread.
// Build: nvcc -arch=native sgemm.cu -o sgemm -lcublas
#include <chrono>
#include <cmath>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cublas_v2.h>
#include <cuda_runtime.h>
using Matrix = std::vector<float>;
const int N = 4096; // C = A B, all N x N, stored row by row
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// Average time of `runs` runs of `launch`, in milliseconds, after 1 warm-up run.
template <typename F>
double timeKernel(F launch, int runs)
{
launch();
check(cudaDeviceSynchronize());
double t0 = nowMs();
for (int r = 0; r < runs; ++r) {
launch();
}
check(cudaGetLastError());
check(cudaDeviceSynchronize());
return (nowMs() - t0) / runs;
}
// 1. 1 thread per element of C, threadIdx.x along a column of C.
__global__ void byColumn(const float* A, const float* B, float* C)
{
    int row = blockIdx.x * 16 + threadIdx.x;
    int col = blockIdx.y * 16 + threadIdx.y;

    float sum = 0.0f;
    for (int k = 0; k < N; ++k) {
        sum += A[row * N + k] * B[k * N + col];
    }

    C[row * N + col] = sum;
}
// 2. The same, threadIdx.x along a row of C.
__global__ void byRow(const float* A, const float* B, float* C)
{
    int row = blockIdx.y * 16 + threadIdx.y;
    int col = blockIdx.x * 16 + threadIdx.x;

    float sum = 0.0f;
    for (int k = 0; k < N; ++k) {
        sum += A[row * N + k] * B[k * N + col];
    }

    C[row * N + col] = sum;
}
// 3. A block of T x T threads computes a T x T tile of C, from tiles in shared memory.
template <int T>
__global__ void tiled(const float* A, const float* B, float* C)
{
    __shared__ float tileA[T][T];
    __shared__ float tileB[T][T];
    int x = threadIdx.x;
    int y = threadIdx.y;
    int row = blockIdx.y * T + y;
    int col = blockIdx.x * T + x;

    float sum = 0.0f;
    for (int k0 = 0; k0 < N; k0 += T) {
        tileA[y][x] = A[row * N + k0 + x];
        tileB[y][x] = B[(k0 + y) * N + col];
        __syncthreads();

        for (int k = 0; k < T; ++k) {
            sum += tileA[y][k] * tileB[k][x];
        }
        __syncthreads();
    }

    C[row * N + col] = sum;
}
// 4. A block of 256 threads computes a 64 x 64 tile of C, each thread a 4 x 4 patch of it.
template <int MIN_BLOCKS>
__global__ void __launch_bounds__(256, MIN_BLOCKS)
patches(const float* A, const float* B, float* C)
{
    __shared__ float tileA[64][16 + 1];       // 1 column of padding (Chapter 7)
    __shared__ float tileB[16][64];
    int tx = threadIdx.x % 16;
    int ty = threadIdx.x / 16;
    int row0 = blockIdx.y * 64;
    int col0 = blockIdx.x * 64;

    float acc[4][4] = {};
    for (int k0 = 0; k0 < N; k0 += 16) {
        for (int e = threadIdx.x; e < 64 * 16; e += 256) {
            tileA[e / 16][e % 16] = A[(row0 + e / 16) * N + k0 + e % 16];
            tileB[e / 64][e % 64] = B[(k0 + e / 64) * N + col0 + e % 64];
        }
        __syncthreads();

        for (int k = 0; k < 16; ++k) {
            float a[4], b[4];
            for (int i = 0; i < 4; ++i) {
                a[i] = tileA[ty * 4 + i][k];
                b[i] = tileB[k][tx * 4 + i];
            }

            for (int i = 0; i < 4; ++i) {
                for (int j = 0; j < 4; ++j) {
                    acc[i][j] += a[i] * b[j];
                }
            }
        }
        __syncthreads();
    }

    for (int i = 0; i < 4; ++i) {
        for (int j = 0; j < 4; ++j) {
            C[(row0 + ty * 4 + i) * N + col0 + tx * 4 + j] = acc[i][j];
        }
    }
}
// Registers per thread, blocks per SM and spilled bytes, as the GPU reports them.
template <typename K>
void resources(const char* name, K kernel, int threads)
{
    cudaFuncAttributes attr;
    check(cudaFuncGetAttributes(&attr, kernel));

    int blocks;
    check(cudaOccupancyMaxActiveBlocksPerMultiprocessor(&blocks, kernel, threads, 0));

    std::printf("  %-26s %3d registers", name, attr.numRegs);
    std::printf("  %d blocks per SM", blocks);
    std::printf("  %2zu bytes spilled\n", attr.localSizeBytes);
}
// Values in [-0.5, 0.5) from a small linear congruential generator.
void fillRandom(Matrix& m, unsigned& state)
{
for (float& v : m) {
state = state * 1664525u + 1013904223u;
v = (state >> 8) / 16777216.0f - 0.5f;
}
}
// The largest difference from a double-precision product, over 64 elements of C.
double maxError(const Matrix& a, const Matrix& b, const Matrix& c)
{
double worst = 0.0;
for (int s = 0; s < 64; ++s) {
int i = s * 977 % N;
int j = (s * 1231 + 7) % N;
double exact = 0.0;
for (int k = 0; k < N; ++k) {
exact += double(a[i * N + k]) * b[k * N + j];
}
worst = std::fmax(worst, std::fabs(exact - c[i * N + j]));
}
return worst;
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %d SMs\n", prop.name, prop.multiProcessorCount);
Matrix a(N * N), b(N * N), c(N * N);
unsigned state = 1;
fillRandom(a, state);
fillRandom(b, state);
size_t bytes = size_t(N) * N * sizeof(float);
float *A, *B, *C;
check(cudaMalloc(&A, bytes));
check(cudaMalloc(&B, bytes));
check(cudaMalloc(&C, bytes));
check(cudaMemcpy(A, a.data(), bytes, cudaMemcpyHostToDevice));
check(cudaMemcpy(B, b.data(), bytes, cudaMemcpyHostToDevice));
auto report = [&](const char* name, double ms) {
check(cudaMemcpy(c.data(), C, bytes, cudaMemcpyDeviceToHost));
double gflops = 2.0 * N * N * N / ms / 1e6;
std::printf(" %-26s %8.2f ms %7.1f GFLOP/s", name, ms, gflops);
std::printf(" max error %.1e\n", maxError(a, b, c));
};
// cuBLAS stores matrices by column: B^T A^T in its terms is A B in ours.
cublasHandle_t handle;
cublasCreate(&handle);
float one = 1.0f, zero = 0.0f;
auto op = CUBLAS_OP_N;
auto cublas = [&] {
cublasSgemm(handle, op, op, N, N, N, &one, B, N, A, N, &zero, C, N);
};
dim3 block16(16, 16), grid16(N / 16, N / 16);
dim3 block32(32, 32), grid32(N / 32, N / 32);
dim3 grid64(N / 64, N / 64);
auto column = [&] { byColumn<<<grid16, block16>>>(A, B, C); };
auto row = [&] { byRow<<<grid16, block16>>>(A, B, C); };
auto tiles16 = [&] { tiled<16><<<grid16, block16>>>(A, B, C); };
auto tiles32 = [&] { tiled<32><<<grid32, block32>>>(A, B, C); };
auto patches1 = [&] { patches<1><<<grid64, 256>>>(A, B, C); };
auto patches4 = [&] { patches<4><<<grid64, 256>>>(A, B, C); };
auto patches6 = [&] { patches<6><<<grid64, 256>>>(A, B, C); };
for (int k = 0; k < 10; ++k) { // warm up: clocks rise under sustained load
timeKernel(cublas, 5);
}
std::printf("C = A B, %d x %d floats\n", N, N);
report("1 per thread, by column", timeKernel(column, 2));
report("1 per thread, by row", timeKernel(row, 3));
report("tiles of 16 x 16", timeKernel(tiles16, 5));
report("tiles of 32 x 32", timeKernel(tiles32, 5));
report("4 x 4 per thread", timeKernel(patches1, 10));
report("4 x 4, at least 4 blocks", timeKernel(patches4, 10));
report("4 x 4, at least 6 blocks", timeKernel(patches6, 10));
report("cuBLAS", timeKernel(cublas, 10));
std::printf("resources\n");
resources("tiles of 16 x 16", tiled<16>, 256);
resources("tiles of 32 x 32", tiled<32>, 1024);
resources("4 x 4 per thread", patches<1>, 256);
resources("4 x 4, at least 4 blocks", patches<4>, 256);
resources("4 x 4, at least 6 blocks", patches<6>, 256);
cublasDestroy(handle);
check(cudaFree(A));
check(cudaFree(B));
check(cudaFree(C));
}
Common mistakes
threadIdx.xon the row index of a row-major output. Adjacent threads then read and write elements \(N\) floats apart; the kernel ran 5 times slower.- A missing second barrier in a tiled loop. The next iteration overwrites a tile while other threads are still reading it.
- Tiles so large that 1 block fills an SM. At every barrier the whole SM waits.
- Forcing occupancy.
__launch_bounds__with a highminBlockscan cause register spills; measure each setting. - Small fixed-size arrays in a loop that is not unrolled. The C++ compiler unrolls loops with
constant bounds automatically; in cuda-oxide, write the loop as
whilewith#[unroll]. - Comparing only against the peak. A library such as cuBLAS shows what the hardware can reach on the same problem.
Summary
- A product of \(N \times N\) matrices performs \(2N^3\) operations on \(3N^2\) values. Each value has \(N\) uses, and a GPU needs about 100 uses per load from memory: 94 FLOP per float on the Orin NX and 119 on the Thor.
- The kernel with one thread per element ran at 1.4% of peak. Mapping
threadIdx.xalong a row reduced the sectors per warp from 17 to 4 and made the kernel 5 times as fast, with the caches serving most of the reuse. - Tiles of \(T \times T\) in shared memory give \(T\) FLOP per float from global memory, but still 2 shared-memory reads per multiply-add.
- A 4 × 4 patch per thread keeps 16 sums in registers and reads 8 values for 16 multiply-adds. It ran 3.3 to 3.4 times as fast as the tiled kernel, at 38% to 40% of peak.
- The registers per thread determine occupancy.
__launch_bounds__trades registers for blocks and can cause spills; the best setting gained 3%. - In cuda-oxide,
whileloops with#[unroll]kept the patch in registers with the bounds checks in place; the Rust kernels reached 89% to 110% of the C++ kernels. - cuBLAS reached 62% and 76% of peak; the best kernel of the chapter ran at 62% and 53% of the speed of cuBLAS.
In Part IV, we turn to the C++ code around such kernels. In Chapter 10, we develop resource-safe buffers and error handling, and Chapter 11 the CUDA libraries, including cuBLAS.
Exercises
- Compute the time that a product of 2 matrices of 8,192 × 8,192 floats needs at the FP32 peak of your GPU, and the least memory traffic it needs. Is it compute-bound?
- Compute the FLOP per float that your GPU needs from its peak and its memory bandwidth. Which kernel of the chapter first provides that much reuse?
- In listing 9.1, how many distinct sectors of \(B\) does 1 warp read at each \(k\)? How many in listing 9.2?
- Derive the reuse of \(T\) FLOP per float for a \(T \times T\) tile, and compute it for \(T\) = 8, 16 and 32.
- The patch kernel reads
tileB[k][tx * 4 + i]. Which banks do the 16 threads with the sametyaccess fori = 0? Is there a bank conflict? - Change the patch to 8 × 4 elements per thread, so that a block computes a 128 × 64 tile. Count its reuse, registers and blocks per SM, and measure it.
- Remove
#[unroll]from the inner loops of the Rust patch kernel, run it, and explain the result. - Run
sgemmwith \(N\) = 1,024 and 8,192. How does the gap to cuBLAS change, and why?
Sources and further reading
- NVIDIA, CUDA C++ Programming Guide, “Shared Memory” and “Launch Bounds”: https://docs.nvidia.com/cuda/cuda-c-programming-guide/
- NVIDIA, CUDA C++ Best Practices Guide, “Occupancy” and “Register Pressure”: https://docs.nvidia.com/cuda/cuda-c-best-practices-guide/
- NVIDIA, cuBLAS Library,
cublasSgemmand math modes: https://docs.nvidia.com/cuda/cublas/ - V. Volkov and J. Demmel, “Benchmarking GPUs to Tune Dense Linear Algebra”, SC08, 2008.
- S. Boehm, “How to Optimize a CUDA Matmul Kernel for cuBLAS-like Performance”, 2022.
- D. Kirk and W. Hwu, Programming Massively Parallel Processors, 4th ed., Morgan Kaufmann, 2022, chapters on matrix multiplication and tiling.
Chapter 10: Modern C++ for CUDA
The host code of Chapters 3 to 9 was written in the style of the CUDA C API. Device memory is
allocated with cudaMalloc and released with cudaFree, every API call returns an error code
of type cudaError_t, and every size passed to a copy is a number of bytes. This style keeps
each step of a program visible, which is why we used it for the first programs. It also leaves
3 responsibilities to the programmer at every call site. Every allocation must be freed on
every path out of a function, every error code must be examined, and every size must be given
in the unit that the called function expects. The compiler checks none of them.
In this chapter, we use the features of modern C++, the language as standardized in 2011 and
later, to make the compiler enforce these rules. We first run 3 short programs in which each
rule is broken, and measure the consequences. We then rewrite them with a class that frees its
memory in its destructor, an error-checking function, template kernels, functions compiled for
both host and device, compile-time checks, the cuda:: library and C++20 concepts. We measure
each technique to confirm that it adds no run-time cost. Each one also has a Rust counterpart,
which we show alongside, since Rust makes most of these rules part of the language.
This chapter covers
- Three errors that the CUDA C API does not detect, run and measured
- RAII: allocation in a constructor and release in a destructor
- ownership: why copying is forbidden and moving is allowed
- error reporting with exceptions and
std::source_location, without a macro - template kernels and their instantiations
__host__ __device__functions, and rounding differences between host and deviceconstexprandstatic_assertcuda::std::span,cuda::atomic_refand thread scopes- C++20 concepts
- the corresponding features of Rust:
Drop, moves,?, generic kernels and trait bounds
The code of the chapter is in
code/ch10_modern/
for C++ and in
code/oxide/ch10_modern/
for Rust. The outputs in this chapter come from 2 integrated GPUs: a Jetson Orin NX (8 SMs,
102 GB/s, CUDA 12.6), whose runs the listings show, and a Jetson AGX Thor (20 SMs, 273 GB/s,
CUDA 13.2), which gives the same counts.
10.1 Problems with raw CUDA C
A resource is anything a program acquires from the system and must later return, such as
device memory, a stream, an event or an open file. The CUDA C API manages resources with pairs
of calls, such as cudaMalloc and cudaFree, and it reports failures through return values of
type cudaError_t. Both conventions work correctly as long as the caller remembers to make the
second call and to examine the return value. In this section, we look at what happens when the
caller does not. The program raw.cu contains 3 such errors, each in a few lines of code that
look reasonable.
10.1.1 Measuring the device memory in use
To detect a leak, we need an exact count of the device memory that a program holds. The programs
of this chapter allocate with cudaMallocAsync(&pointer, bytes, stream), the stream-ordered
allocator introduced in CUDA 11.2. It behaves like cudaMalloc, with two differences. First,
the allocation and the matching cudaFreeAsync are ordered in a stream, the queue of GPU work
introduced in Chapter 6, in the same way as kernel launches. Second, the memory comes from a
pool, a reserve of device memory that the driver keeps for each GPU and reuses between
allocations. The pool records the number of bytes that have been allocated and not yet freed in
the attribute cudaMemPoolAttrUsedMemCurrent, which Listing 10.1 reads and converts to MiB.
Listing 10.1 The bytes in use from the pool, in MiB. code/ch10_modern/raw.cu
/// Bytes in use from the pool that stream-ordered allocations draw on, in MiB.
fn pool_mib(ctx: &CudaContext) -> Result<f64, DriverError> {
    ctx.synchronize()?;

    let mut pool = std::ptr::null_mut();
    let mut used: u64 = 0;
    let used_ptr = (&mut used as *mut u64).cast::<c_void>();

    // SAFETY: both out-pointers are valid for the length of each call.
    unsafe {
        sys::cuDeviceGetDefaultMemPool(&mut pool, ctx.cu_device()).result()?;
        sys::cuMemPoolGetAttribute(pool, USED_MEM, used_ptr).result()?;
    }
    Ok(used as f64 / 1_048_576.0)
}
// Bytes in use from the pool that cudaMallocAsync draws on, in MiB.
double poolMiB()
{
cudaMemPool_t pool;
cudaDeviceGetDefaultMemPool(&pool, 0);
unsigned long long used = 0;
cudaMemPoolGetAttribute(pool, cudaMemPoolAttrUsedMemCurrent, &used);
return used / 1048576.0;
}
The older function cudaMemGetInfo is not suitable for this purpose. It reports the free memory
of the whole device, which other programs also change. On an integrated GPU, which shares its
memory with the operating system, an allocation of 128 MiB changed the free memory reported by
cudaMemGetInfo by only 0.5 MiB on the first GPU and by 129 MiB on the second. The pool’s
count, in contrast, depends only on the allocations of our own program.
10.1.2 Memory leaks on early returns
A memory leak occurs when a program has allocated memory and no longer holds its address, so that the memory can no longer be freed. Listing 10.2 shows a function that scales a vector on the GPU and contains such a leak.
Listing 10.2 An early return before the frees.
/// Mistake 1 of raw.cu: ManuallyDrop turns the drops off, so the frees are written by
/// hand, and the early return skips them.
fn scale_by_hand(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
factor: f32,
) -> Result<Option<Vec<f32>>, Error> {
let mut input = ManuallyDrop::new(pool_copy(stream, host)?);
let mut out = ManuallyDrop::new(pool_copy(stream, host)?);
if factor == 0.0 {
return Ok(None); // nothing to scale
}
let config = LaunchConfig1D::new(blocks_for(host.len()), BLOCK, 0);
let prepared = module.prepare_scale::<f32>(config)?;
module.scale(stream, &prepared, factor, &input, &mut out)?;
let result = out.to_host_vec(stream)?;
// SAFETY: neither buffer is used after its drop.
unsafe {
ManuallyDrop::drop(&mut input);
ManuallyDrop::drop(&mut out);
}
Ok(Some(result))
}// Mistake 1: the early return skips both frees.
bool scaleOnGpu(const std::vector<float>& host, std::vector<float>& result, float factor)
{
int n = static_cast<int>(host.size());
size_t bytes = n * sizeof(float);
float* in = nullptr;
float* out = nullptr;
cudaMallocAsync(&in, bytes, 0);
cudaMallocAsync(&out, bytes, 0);
if (factor == 0.0f) {
return false; // nothing to scale
}
cudaMemcpy(in, host.data(), bytes, cudaMemcpyHostToDevice);
scale<<<(n + 255) / 256, 256>>>(in, out, n, factor);
cudaMemcpy(result.data(), out, bytes, cudaMemcpyDeviceToHost);
cudaFreeAsync(in, 0);
cudaFreeAsync(out, 0);
return true;
}
The function allocates 2 device buffers, in and out, with the 2 calls to cudaMallocAsync.
It then copies the input to the device, launches the kernel scale, copies the result back, and
frees both buffers at the end. However, when the factor is 0, there is nothing to compute, and
the function returns false before it reaches the 2 calls to cudaFreeAsync. The early return
is correct by itself. The error is that it skips the frees. The pointers in and out are
local variables, so the return destroys them, and with them the only record of where the 2
buffers are. The memory remains allocated until the program exits.
Each buffer holds N = 2,097,152 floats of 4 bytes, which is 8 MiB, so each early return leaks 16 MiB. The test program calls the function 8 times with a factor of 0, which should leave 8 × 16 MiB = 128 MiB allocated, and then reads the pool’s count:
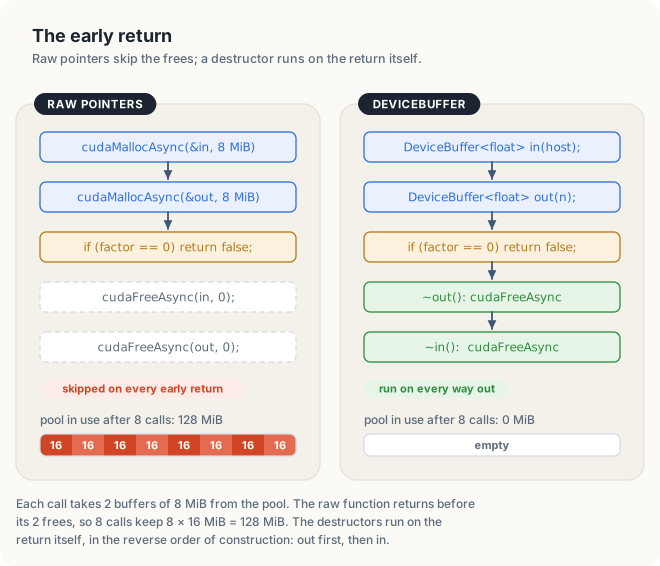
$ nvcc -arch=native raw.cu -o raw && ./raw
1. 8 calls that return early: 128.0 MiB lost
The measured 128.0 MiB agrees with the calculation. No error was reported, and none will be, because as far as CUDA is concerned the program still owns the memory. A long-running program, such as a server or a training job that calls this function millions of times, will eventually run out of device memory, long after the leak occurred and in code that has nothing to do with it.
In Rust, frees are written by hand only after ManuallyDrop has turned the automatic ones off,
and the Rust function of Listing 10.2 then loses the same 128.0 MiB.
10.1.3 Unchecked launch errors
Recall from Chapter 3 that a GPU contains several streaming multiprocessors (SMs), the
processors that execute the threads of a kernel; the Jetson Orin NX has 8 of them. A block
is a group of threads that are launched together, run on the same SM, and can share memory and
synchronize with each other. The compute capability is a version number, such as 8.7 for
the Orin NX, that NVIDIA assigns to each GPU generation and that determines which features the
generation has. Since compute capability 2.0, every CUDA GPU limits a block to at most 1,024
threads. The second error in raw.cu launches blocks of 2,048 threads, twice the limit.
Listing 10.3 A launch that exceeds the block size limit.
/// The launch of 2,048 threads per block. The `?` returns before any kernel runs.
fn launch_too_wide(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
) -> Result<(), Error> {
let input = pool_copy(stream, host)?;
let mut out = pool_copy(stream, host)?;
let blocks = (host.len() as u32) / 2048;
let prepared = module.prepare_scale::<f32>(LaunchConfig1D::new(blocks, 2048, 0))?;
module.scale(stream, &prepared, 2.0, &input, &mut out)?;
Ok(())
}
fn main() -> Result<(), Error> {
// ...
match launch_too_wide(&module, &stream, &host) {
Ok(()) => passed = false,
Err(error) => println!(" 2048 threads per block returned: {error}"),
}
println!(" after the error: {:.1} MiB in use", pool_mib(&ctx)?);
// ...
}int main()
{
// ...
// Mistake 2: 2,048 threads per block is over the limit of 1,024. Nothing reports it.
scale<<<N / 2048, 2048>>>(in, out, N, 2.0f);
cudaMemcpy(result.data(), out, bytes, cudaMemcpyDeviceToHost);
std::printf("2. 2048 threads per block: out[0] = %.1f, expected 2.0\n", result[0]);
cudaError_t err = cudaGetLastError();
std::printf(" the error, found only by asking: %s\n", cudaGetErrorString(err));
// ...
}
2. 2048 threads per block: out[0] = 0.0, expected 2.0
the error, found only by asking: invalid configuration argument
The launch syntax <<<...>>> has no return value, so a launch that fails cannot return an error
code to its caller. Instead, CUDA records the error, and the next call to cudaGetLastError
returns it. In the meantime, the program continues. Let us follow the first element of out
through the program. Before the launch, cudaMemset, which fills device memory with a given
byte, writes 0 into every byte of out, so out[0] is 0.0. The launch is rejected, and no
thread runs. The copy that follows the launch succeeds, but it copies an array that no kernel
has written, so out[0] still holds the 0.0 written by cudaMemset, where the kernel would
have written 1.0 × 2 = 2.0. A program that does not call cudaGetLastError continues with wrong
data and reports nothing. On the second GPU, CUDA 13.2 describes the same failure as invalid argument. The wording of the message differs between CUDA versions, but in both cases the error
is visible only to a program that asks for it.
The Rust launch of Listing 10.3 never reaches the driver: prepare_scale returns an Err, and
the ? passes it to the caller (section 10.2.6).
10.1.4 Size errors in copies
The function cudaMemcpy(dst, src, count, kind) copies count bytes. Its pointer
parameters have type void*, a pointer to memory of no particular type, so the function cannot
know that they point to floats and cannot check a count of floats against them. The third error
in raw.cu passes N, the number of floats, where the number of bytes, N * sizeof(float),
was intended.
Listing 10.4 A count of floats passed as a count of bytes.
/// Mistake 3 of raw.cu: the driver's copy counts bytes, but `host.len()` counts floats.
fn copy_count_as_bytes(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
) -> Result<usize, Error> {
let input = DeviceBuffer::<f32>::zeroed(stream, host.len())?;
let mut out = DeviceBuffer::<f32>::zeroed(stream, host.len())?;
let src = host.as_ptr().cast::<c_void>();
// SAFETY: both sides hold 4 bytes per float, so host.len() bytes fit in each.
check(unsafe { sys::cuMemcpyHtoD_v2(input.cu_deviceptr(), src, host.len()) })?;
let config = LaunchConfig1D::new(blocks_for(host.len()), BLOCK, 0);
let prepared = module.prepare_scale::<f32>(config)?;
module.scale(stream, &prepared, 2.0, &input, &mut out)?;
let result = out.to_host_vec(stream)?;
Ok(result.iter().filter(|&&x| x == 2.0).count())
}int main()
{
// ...
// Mistake 3: N counts floats, but cudaMemcpy counts bytes.
cudaMemset(in, 0, bytes);
cudaMemcpy(in, host.data(), N, cudaMemcpyHostToDevice);
scale<<<N / 256, 256>>>(in, out, N, 2.0f);
cudaMemcpy(result.data(), out, bytes, cudaMemcpyDeviceToHost);
int correct = 0;
for (float x : result) {
correct += (x == 2.0f);
}
std::printf("3. a copy of N bytes, not N floats: %d of %d correct\n", correct, N);
// ...
}
Consider a small example with N = 16. The host array holds 16 floats of 4 bytes, or 64 bytes.
The call cudaMemcpy(in, host, 16, ...) copies 16 bytes, which are the first 16 ÷ 4 = 4 floats.
The other 12 floats of in keep the value 0.0 written by cudaMemset. The kernel doubles every
element, so 4 results are 2.0 and 12 are 0.0: only 1 result in 4 is correct, as Figure 10.2
shows.
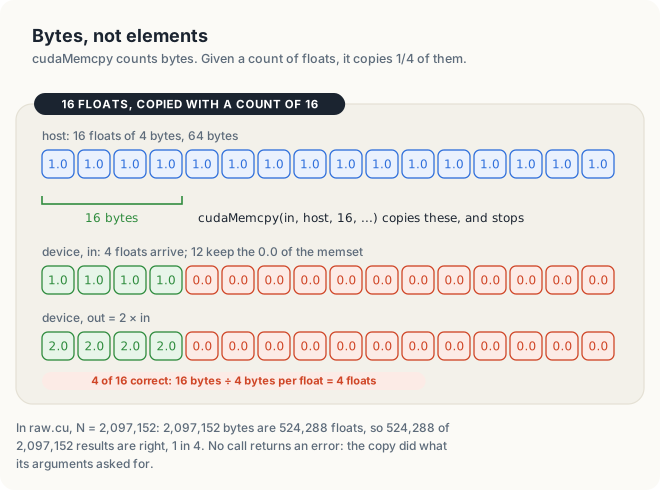
3. a copy of N bytes, not N floats: 524288 of 2097152 correct
With N = 2,097,152, the copy moved 2,097,152 bytes, which are 524,288 floats, so again exactly 1
result in 4 is correct. Every call returned cudaSuccess, because the API did exactly what its
arguments asked for.
The Rust function calls the driver’s copy inside unsafe and also finds 524,288 of 2,097,152
correct: unsafe states that the copy stays inside both arrays, which it does, not that the count
is the one intended.
In 3 short programs, the CUDA C API lost 128 MiB of memory, skipped a kernel and copied 1/4 of an array, and none of these errors produced a message.
10.2 RAII: The Device Buffer
The three errors of section 10.1 have a common cause. Each rule, such as “every allocation is freed”, must be applied by hand at every place in the program where it is relevant, and a single omission is enough to break it. C++ allows us to state such a rule once, inside a type, and have the compiler apply it wherever the type is used. We begin with the rule that every allocation is freed.
10.2.1 Constructors, destructors and scope
A scope is a region of a program, delimited by braces { }, in which a name is visible. The
body of a function is a scope, and so is the body of a loop. An object of a class type is
created by a constructor, a member function of the class that runs when the object is
defined. The object is destroyed by its destructor, ~ClassName(), a member function that
the compiler calls when the object’s lifetime ends. The lifetime of an object is the period
during which the object exists, from its construction to its destruction. For a local variable,
the lifetime ends when control leaves its scope, whichever way it leaves: through the closing
brace, a return, a break, or an exception that passes through the scope.
Before we name the technique, let us follow 1 call of the function of Listing 10.2 with a factor
of 0, first as written and then with the 2 pointers replaced by objects whose destructor frees
the memory. As written, the function performs 4 steps. It allocates in, and the pool holds
8 MiB; it allocates out, and the pool holds 16 MiB; it tests the factor; and it returns. The
return removes the local variables in and out, which are plain addresses, and 16 MiB remain
allocated with no variable that records where they are. With objects, the first 3 steps are the
same. At the return, however, the compiler destroys the 2 local objects, in the reverse order of
their construction. The destructor of out frees 8 MiB, the destructor of in frees the other
8 MiB, and the pool holds 0 MiB. Neither version contains a call to cudaFreeAsync on the path
of the early return. The second version obtains its 2 frees from the type of its variables.
Key observation A release written in a destructor runs on every path out of the scope, because the compiler, not the programmer, writes the call at each exit.
Definition 10.1 RAII. Resource acquisition is initialization (RAII) is the practice of acquiring a resource in the constructor of an object and releasing it in the destructor of the same object. The resource then lives exactly as long as the object.
Example. An object of the class DeviceBuffer<float> of section 10.2.2, created with a count
of 2,097,152, allocates 8 MiB in its constructor and frees the 8 MiB in its destructor when its
scope ends, whether by the closing brace, by a return or by an exception.
Because the compiler, and not the programmer, inserts the call to the destructor, the release happens on every path out of the scope. The pseudocode below marks where the compiler inserts these calls.
{ # a scope opens
buffer ← DeviceBuffer(n) # constructor: allocate n elements
... # use buffer
if done early: return # compiler inserts: destroy buffer, then return
...
} # compiler inserts: destroy buffer
# destroy = destructor: free the allocation
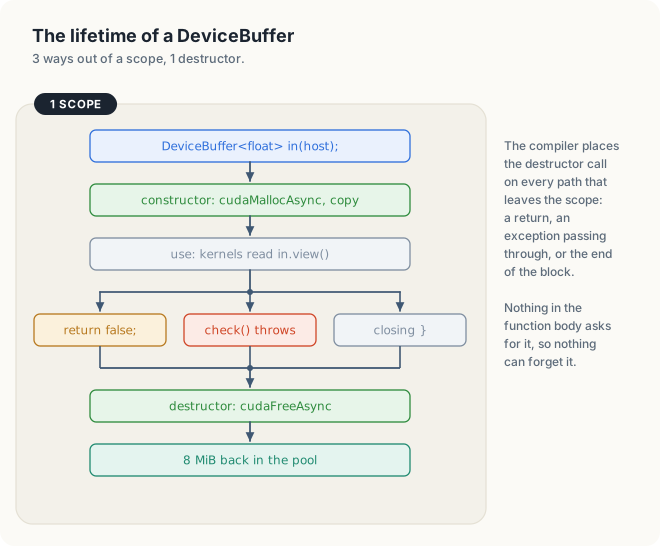
The C++ standard library already uses RAII. A std::vector frees its array in its destructor,
and a std::unique_ptr deletes the object it points to. Device memory needs a class of its own
only because new and delete manage host memory, while device memory is allocated and freed
through CUDA calls.
10.2.2 The class
DeviceBuffer<T> holds count values of type T in device memory. Listing 10.5 shows its
constructors and destructor.
Listing 10.5 DeviceBuffer and PoolBuffer: construction and destruction. code/ch10_modern/device_buffer.hpp
/// `count` values of T in device memory from the pool, owned by exactly 1 variable.
struct PoolBuffer<T> {
ptr: sys::CUdeviceptr,
count: usize,
stream: Arc<CudaStream>,
elements: PhantomData<T>,
}
impl<T: DeviceCopy> PoolBuffer<T> {
#[track_caller]
fn new(stream: &Arc<CudaStream>, count: usize) -> Result<Self, Error> {
let mut ptr = 0;
let bytes = count * size_of::<T>();
// SAFETY: `ptr` is a valid out-pointer, and the stream belongs to this context.
check(unsafe { sys::cuMemAllocAsync(&mut ptr, bytes, stream.cu_stream()) })?;
let elements = PhantomData;
Ok(Self { ptr, count, stream: stream.clone(), elements })
}
#[track_caller]
fn from_host(stream: &Arc<CudaStream>, host: &[T]) -> Result<Self, Error> {
let buffer = Self::new(stream, host.len())?;
let src = host.as_ptr().cast::<c_void>();
// SAFETY: the buffer and `host` both hold buffer.bytes() bytes.
check(unsafe { sys::cuMemcpyHtoD_v2(buffer.ptr, src, buffer.bytes()) })?;
Ok(buffer)
}
}
impl<T> Drop for PoolBuffer<T> {
fn drop(&mut self) {
// A drop cannot report an error, so the result is ignored.
// SAFETY: `ptr` came from cuMemAllocAsync, and only this drop frees it.
let _ = unsafe { sys::cuMemFreeAsync(self.ptr, self.stream.cu_stream()) };
}
}// `count` values of T in device memory, owned by exactly 1 object.
template <typename T>
class DeviceBuffer {
static_assert(std::is_trivially_copyable_v<T>, "device memory holds plain bytes");
public:
explicit DeviceBuffer(std::size_t count) : count_(count)
{
check(cudaMallocAsync(&data_, bytes(), 0));
}
explicit DeviceBuffer(const std::vector<T>& host) : DeviceBuffer(host.size())
{
check(cudaMemcpy(data_, host.data(), bytes(), cudaMemcpyHostToDevice));
}
~DeviceBuffer()
{
release();
}
// ...
};
The Rust type PoolBuffer<T> frees its memory in the method drop of the trait Drop, which
section 10.2.6 describes.
The first constructor allocates count elements. The second constructor allocates enough
elements for a host vector and copies the vector into them. The destructor frees the
allocation. We explain three details of this code.
First, the size in bytes is always computed from the type: bytes() returns
count_ * sizeof(T). Since no caller ever writes a byte count, the error of section 10.1.4
cannot occur.
Second, the second constructor delegates the allocation to the first, with
: DeviceBuffer(host.size()), before its body copies the data. A constructor that begins by
calling another constructor of the same class in this way is called a delegating
constructor. If the copy throws an exception
(section 10.2.4), the object has already been constructed, so its destructor runs and the
allocation is freed.
Third, the static_assert rejects types that cannot be stored in device memory. A type is
trivially copyable when copying its bytes produces a valid copy of the object. float,
int and a struct of floats are trivially copyable. A std::string is not, because it holds a
pointer to host memory, and a copy of its bytes on the device would contain an address that the
GPU cannot use. DeviceBuffer<std::string> is therefore a compile error. We describe
static_assert in more detail in Section 10.5.
Note also that the first constructor is declared explicit. Without this keyword, the compiler
would convert a number into a buffer implicitly, and a function that takes a
DeviceBuffer<float> would accept the argument 5 and allocate 5 floats.
10.2.3 Ownership and move semantics
A class that frees memory in its destructor must define what it means to copy one of its
objects. C++ performs a copy with 2 member functions. The copy constructor creates a new
object from an existing one, as in DeviceBuffer<float> b = a;. The copy assignment
operator overwrites an existing object with the contents of another, as in b = a; when b
already exists. If a class does not define them, the compiler generates both, and the generated
versions copy every member, field by field.
Let us follow 1 allocation through such a field-by-field copy. Suppose that a holds
data_ = 0x7f00 and count_ = 2,097,152, the 8 MiB of a buffer of floats. The statement
b = a copies both fields, so b also holds 0x7f00 and 2,097,152. At the end of the scope,
the destructor of b frees 0x7f00, and then the destructor of a frees 0x7f00 a second time.
Freeing the same allocation twice is called a double free. It corrupts the records of the
allocator, which may later hand out memory that another buffer is still using.
The same allocation can instead pass from a to b in 2 steps: copy the 2 fields to b, then
write nullptr and 0 into the fields of a. Afterward b holds 0x7f00 and a holds
nullptr. At the end of the scope, the destructor of b frees 0x7f00, and the destructor of
a finds nullptr and frees nothing. The allocation is freed exactly once. In both cases, only
the 16 bytes of the 2 fields are copied, never the 8 MiB of data they describe.
Key observation 2 objects that hold the same address free it
twice. If the object that gives up the address is left holding nullptr, exactly 1 object frees
it.
Definition 10.2 Owner and move. The owner of an allocation is the object whose destructor frees it. A move transfers an allocation from 1 owner to another: the new object takes the address, and the old object is left empty, so that its destructor frees nothing.
Example. After b = std::move(a), b owns the 8 MiB at 0x7f00 and a holds nullptr.
For this reason, each allocation has exactly 1 owner. Copying is forbidden: the 2 declarations
marked = delete in Listing 10.6 remove the copy constructor and the copy assignment operator,
so b = a does not compile. Moving, however, is allowed. The function std::move(a) moves
nothing by itself. It marks a as an object whose contents may be taken, and the compiler then
calls the move constructor or the move assignment operator, the 2 member functions that
perform the transfer, instead of the copy operations. Figure 10.4 shows both cases.
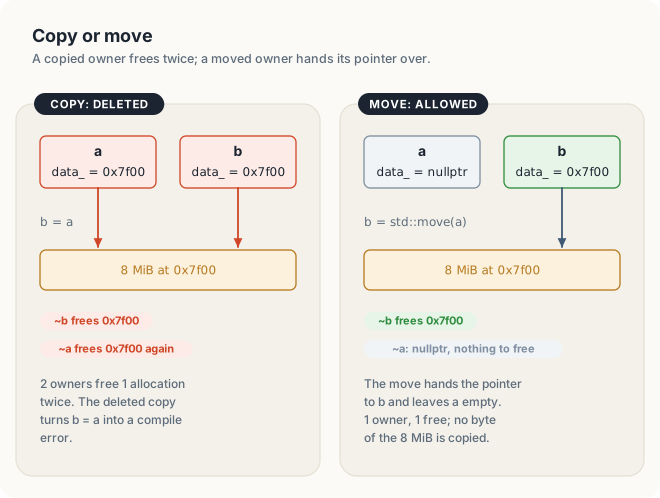
Listing 10.6 Copies deleted, moves allowed.
/// A move: `b` takes the allocation, and the name `a` can no longer be used.
fn move_once(stream: &Arc<CudaStream>, host: &[f32]) -> Result<usize, Error> {
let a = PoolBuffer::from_host(stream, host)?;
let b = a;
Ok(b.len())
}// `count` values of T in device memory, owned by exactly 1 object.
template <typename T>
class DeviceBuffer {
// ...
DeviceBuffer(const DeviceBuffer&) = delete;
DeviceBuffer& operator=(const DeviceBuffer&) = delete;
DeviceBuffer(DeviceBuffer&& other) noexcept
: data_(std::exchange(other.data_, nullptr)), count_(std::exchange(other.count_, 0))
{
}
DeviceBuffer& operator=(DeviceBuffer&& other) noexcept
{
if (this != &other) {
release();
data_ = std::exchange(other.data_, nullptr);
count_ = std::exchange(other.count_, 0);
}
return *this;
}
// ...
};
The move constructor uses std::exchange(other.data_, nullptr), which returns the old value of
other.data_ and stores nullptr in its place in a single step. The move assignment operator
first frees the memory that *this held, then takes the pointer of other. The test this != &other prevents a self-assignment such as a = std::move(a) from freeing the buffer that it is
about to keep. Both move operations are declared noexcept, a promise that they never throw.
The promise is easy to keep, because they only exchange 2 values.
C++ programmers refer to this set of member functions as the rule of 5. A class that defines
any of the destructor, copy constructor, copy assignment, move constructor and move assignment
usually needs to define or delete all 5. The table lists the choices that DeviceBuffer makes.
| Member | DeviceBuffer | Reason |
|---|---|---|
| destructor | frees data_ | the object owns the allocation |
| copy constructor | deleted | 2 owners would free twice |
| copy assignment | deleted | same |
| move constructor | takes the pointer, leaves nullptr | 1 owner after the move |
| move assignment | frees its own, then takes the pointer | same, without leaking the old buffer |
With the copy operations deleted, an accidental copy becomes a compile error. We added the line
DeviceBuffer<float> copy = in; to the program and compiled it:
copy.cu(113): error: function "DeviceBuffer<T>::DeviceBuffer(const DeviceBuffer<T> &) [with T=float]" (declared at line 59 of device_buffer.hpp) cannot be referenced -- it is a deleted function
DeviceBuffer<float> copy = in;
^
In Rust, let b = a; moves the buffer, as move_once in Listing 10.6 does, and a later use of
a is the compile error:
error[E0382]: borrow of moved value: `a`
--> src/main.rs:224:17
|
222 | let a = PoolBuffer::from_host(stream, host)?;
| - move occurs because `a` has type `PoolBuffer<f32>`, which does not implement the `Copy` trait
223 | let b = a;
| - value moved here
224 | let first = a.len();
| ^ value borrowed here after move
Listing 10.7 shows the rest of the class: the functions that give access to the memory, and the single function that frees it.
Listing 10.7 Access, and the 1 place that frees.
impl<T> PoolBuffer<T> {
fn len(&self) -> usize {
self.count
}
fn bytes(&self) -> usize {
self.count * size_of::<T>()
}
}
impl<T> Drop for PoolBuffer<T> {
fn drop(&mut self) {
// A drop cannot report an error, so the result is ignored.
// SAFETY: `ptr` came from cuMemAllocAsync, and only this drop frees it.
let _ = unsafe { sys::cuMemFreeAsync(self.ptr, self.stream.cu_stream()) };
}
}// `count` values of T in device memory, owned by exactly 1 object.
template <typename T>
class DeviceBuffer {
// ...
T* data() const { return data_; }
std::size_t size() const { return count_; }
std::size_t bytes() const { return count_ * sizeof(T); }
cuda::std::span<const T> view() const { return {data_, count_}; }
cuda::std::span<T> span() { return {data_, count_}; }
std::vector<T> toHost() const
{
std::vector<T> host(count_);
check(cudaMemcpy(host.data(), data_, bytes(), cudaMemcpyDeviceToHost));
return host;
}
private:
void release()
{
if (data_ != nullptr) { // a moved-from buffer owns nothing
cudaFreeAsync(data_, 0);
}
}
T* data_ = nullptr;
std::size_t count_ = 0;
};
view() returns a read-only view of the buffer and span() a writable one; we introduce
the type of these views in section 10.6.1. release() tests for nullptr because a buffer that has
been moved from no longer owns any memory. A Rust value that has been moved from is never
dropped, so drop needs no such test.
10.2.4 Error reporting without a macro
In Chapters 3 to 9, we checked each CUDA call with a small function that printed the error and
ended the program. Many CUDA programs use a macro instead, CHECK(call). A macro is a name that
the preprocessor, a text-substitution step that runs before the compiler proper, replaces
with other text wherever the name appears. Programs use a macro here for one reason: the
preprocessor replaces __FILE__ and __LINE__ with the file name and line number of the place
where the macro is written, so the message names the call that failed. For example, CHECK
written on line 40 of app.cu produces a message that contains app.cu and 40. Before C++20, a
function had no way to find out where it was called from. C++20 added std::source_location for
this purpose.
A default argument is a value that a function parameter takes when the caller omits it. When
std::source_location::current() is used as a default argument, it is evaluated at the call
site, so it records the file and line of the caller rather than a line inside check. Listing
10.8 shows the function.
Listing 10.8 check, with the caller's file and line.
/// Turn a driver result into an error that names the caller's file and line.
#[track_caller]
fn check(result: sys::CUresult) -> Result<(), Error> {
let place = Location::caller();
match result.result() {
Ok(()) => Ok(()),
Err(error) => Err(format!("{}:{}: {error}", place.file(), place.line()).into()),
}
}using Where = std::source_location;
// Throw if a CUDA call failed. The default argument records the caller's file and line.
inline void check(cudaError_t err, Where where = Where::current())
{
if (err == cudaSuccess) {
return;
}
std::string place = std::string(where.file_name()) + ":" + std::to_string(where.line());
throw std::runtime_error(place + ": " + cudaGetErrorString(err));
}
In Rust, the attribute #[track_caller] makes Location::caller() return the file and line of
the call, so the Rust check needs no macro either.
check reports a failure by throwing an exception, an object that travels up the chain of
function calls until a catch clause handles it. On its way, the exception leaves every scope
it passes through, and every local object in those scopes is destroyed. The destruction of local
objects while an exception travels up the chain of calls is called stack unwinding. It is
the path labeled “check() throws” in Figure 10.3. For example, if main calls a function f
that holds 2 buffers, and check throws inside f, the 2 destructors of f run first, and
only then does the exception reach the catch in main. As a result, the buffers of a function
that fails are freed before the error reaches the code that handles it.
Note that the destructor itself does not call check. A destructor may run while an exception
is already traveling, and if a second exception is thrown at that moment, the program ends with
std::terminate, a standard function that stops the program immediately. The destructor
therefore frees the memory and ignores the result. A program that needs to know whether a free
succeeded can call cudaDeviceSynchronize through check before the buffer goes out of scope.
10.2.5 The errors of section 10.1, revisited
We can now rewrite the functions of section 10.1 with DeviceBuffer and check. Listing 10.9
shows the function with the early return and the launch with 2,048 threads per block.
Listing 10.9 The early return and the launch over the limit, with DeviceBuffer and check. code/ch10_modern/modern.cu
/// The function of raw.cu. Every return, early or not, drops both buffers.
fn scale_on_gpu(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
factor: f32,
) -> Result<Option<Vec<f32>>, Error> {
let input = pool_copy(stream, host)?;
let mut out = pool_copy(stream, host)?;
if factor == 0.0 {
return Ok(None);
}
let blocks = blocks_for(host.len());
let prepared = module.prepare_scale::<f32>(LaunchConfig1D::new(blocks, BLOCK, 0))?;
module.scale(stream, &prepared, factor, &input, &mut out)?;
Ok(Some(out.to_host_vec(stream)?))
}
/// The launch of 2,048 threads per block. The `?` returns before any kernel runs.
fn launch_too_wide(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
) -> Result<(), Error> {
let input = pool_copy(stream, host)?;
let mut out = pool_copy(stream, host)?;
let blocks = (host.len() as u32) / 2048;
let prepared = module.prepare_scale::<f32>(LaunchConfig1D::new(blocks, 2048, 0))?;
module.scale(stream, &prepared, 2.0, &input, &mut out)?;
Ok(())
}// The function of raw.cu: the early return frees both buffers.
bool scaleOnGpu(const std::vector<float>& host, std::vector<float>& result, float factor)
{
DeviceBuffer<float> in(host);
DeviceBuffer<float> out(host.size());
if (factor == 0.0f) {
return false;
}
transform<<<blocksFor(in.size()), BLOCK>>>(in.view(), out.span(), Scale{factor});
check(cudaGetLastError());
result = out.toHost();
return true;
}
void launchTooWide(const std::vector<float>& host)
{
DeviceBuffer<float> in(host);
DeviceBuffer<float> out(host.size());
transform<<<N / 2048, 2048>>>(in.view(), out.span(), Scale{2.0f});
check(cudaGetLastError());
}
The function main in Listing 10.10 makes the same 8 calls as raw.cu, launches the 2,048
threads inside a try block, and copies 2,097,152 floats through the constructor that takes a
host vector.
Listing 10.10 The measurements of section 10.1, repeated.
fn main() -> Result<(), Error> {
// ...
println!("ownership");
let before = pool_mib(&ctx)?;
for _ in 0..8 {
scale_on_gpu(&module, &stream, &host, 0.0)?;
}
let lost = pool_mib(&ctx)? - before;
println!(" 8 calls that return early: {lost:.1} MiB lost");
passed &= lost == 0.0;
match launch_too_wide(&module, &stream, &host) {
Ok(()) => passed = false,
Err(error) => println!(" 2048 threads per block returned: {error}"),
}
println!(" after the error: {:.1} MiB in use", pool_mib(&ctx)?);
let result = scale_on_gpu(&module, &stream, &host, 2.0)?.unwrap_or_default();
let correct = result.iter().filter(|&&x| x == 2.0).count();
println!(" copies sized by the type: {correct} of {N} correct");
passed &= correct == N;
// ...
}int main()
{
// ...
std::printf("ownership\n");
double before = poolMiB();
for (int call = 0; call < 8; ++call) {
scaleOnGpu(host, result, 0.0f);
}
double lost = poolMiB() - before;
std::printf(" 8 calls that return early: %.1f MiB lost\n", lost);
passed = passed && lost == 0.0;
try {
launchTooWide(host);
passed = false;
} catch (const std::runtime_error& e) {
std::printf(" 2048 threads per block threw: %s\n", e.what());
}
std::printf(" after the exception: %.1f MiB in use\n", poolMiB());
scaleOnGpu(host, result, 2.0f);
int correct = 0;
for (float x : result) {
correct += (x == 2.0f);
}
std::printf(" copies sized by the type: %d of %d correct\n", correct, N);
passed = passed && correct == N;
// ...
}
$ nvcc -std=c++20 --extended-lambda -arch=native modern.cu -o modern && ./modern
GPU: Orin, 8 SMs
ownership
8 calls that return early: 0.0 MiB lost
2048 threads per block threw: modern.cu:134: invalid configuration argument
after the exception: 0.0 MiB in use
copies sized by the type: 2097152 of 2097152 correct
All three errors are gone. The early returns leaked 0.0 MiB. The launch error became an exception
that names line 134, the check(cudaGetLastError()) after the launch, and the 2 buffers of
launchTooWide, 16 MiB in total, were freed while the exception traveled to main. Every
element was copied correctly, because no caller states a byte count.
10.2.6 RAII in Rust
Rust builds RAII into the language. A trait in Rust is a named set of methods that a type
can implement; a function can then require that its argument type implements the trait. The
destructor of a type is the method drop of the trait Drop, and the compiler calls it when
the owner of a value goes out of scope. cuda-core, the host-side crate (Rust package) of
cuda-oxide, provides a DeviceBuffer<T> that implements Drop by freeing its allocation, so a
Rust program has no free to forget. Ownership is also the default. The statement let b = a;
moves the buffer, and any later use of a is a compile error. A copy must be requested
explicitly, and DeviceBuffer does not provide one.
Rust reports errors as values of type Result<T, E>, which is either Ok(value) or
Err(error). The ? operator after a call returns the Err from the enclosing function
immediately. Like any other return, this return drops every local buffer.
Listing 10.11 shows the Rust version of the function with the early return. The helper
pool_copy allocates from the same pool as the C++ program, so that the 2 counts can be
compared. The safe cuda-core functions, such as DeviceBuffer::from_host, allocate with the
synchronous cuMemAlloc, a function of the CUDA driver API (Chapter 12) that the pool does not
count. uninitialized_async takes the memory from the pool. A Rust function marked unsafe
performs operations whose correctness the compiler cannot check, and a caller must write the
call inside an unsafe block, which states that the programmer has checked it.
uninitialized_async is unsafe only because the contents of the buffer are undefined until
they are written, and the copy on the next line writes every element.
Listing 10.11 The early return, with buffers that free themselves. code/oxide/ch10_modern/src/main.rs
/// A copy of `host` in device memory from the pool, freed when the buffer is dropped.
fn pool_copy<T: DeviceCopy>(
stream: &Arc<CudaStream>,
host: &[T],
) -> Result<DeviceBuffer<T>, DriverError> {
// SAFETY: the copy below writes every element before anything reads one.
let mut buffer = unsafe { DeviceBuffer::uninitialized_async(stream, host.len())? };
buffer.copy_from_host(stream, host)?;
Ok(buffer)
}
/// The function of raw.cu. Every return, early or not, drops both buffers.
fn scale_on_gpu(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
factor: f32,
) -> Result<Option<Vec<f32>>, Error> {
let input = pool_copy(stream, host)?;
let mut out = pool_copy(stream, host)?;
if factor == 0.0 {
return Ok(None);
}
let blocks = blocks_for(host.len());
let prepared = module.prepare_scale::<f32>(LaunchConfig1D::new(blocks, BLOCK, 0))?;
module.scale(stream, &prepared, factor, &input, &mut out)?;
Ok(Some(out.to_host_vec(stream)?))
}// `count` values of T in device memory, owned by exactly 1 object.
template <typename T>
class DeviceBuffer {
// ...
explicit DeviceBuffer(std::size_t count) : count_(count)
{
check(cudaMallocAsync(&data_, bytes(), 0));
}
explicit DeviceBuffer(const std::vector<T>& host) : DeviceBuffer(host.size())
{
check(cudaMemcpy(data_, host.data(), bytes(), cudaMemcpyHostToDevice));
}
// ...
};
// The function of raw.cu: the early return frees both buffers.
bool scaleOnGpu(const std::vector<float>& host, std::vector<float>& result, float factor)
{
DeviceBuffer<float> in(host);
DeviceBuffer<float> out(host.size());
if (factor == 0.0f) {
return false;
}
transform<<<blocksFor(in.size()), BLOCK>>>(in.view(), out.span(), Scale{factor});
check(cudaGetLastError());
result = out.toHost();
return true;
}
The Rust launch in Listing 10.12 carries a launch contract (Chapter 13): the kernel declares
that it runs in blocks of 256 threads, and prepare_scale checks the requested configuration
against this declaration on the host, before any call to the driver. The listing also shows the
only way to leak a buffer in safe Rust. std::mem::forget takes ownership of a value and never
drops it. It is part of safe Rust, because a leak cannot cause a program to read or write the
wrong memory, but it must be written explicitly.
Listing 10.12 The launch over the limit, and the only way to leak.
/// The launch of 2,048 threads per block. The `?` returns before any kernel runs.
fn launch_too_wide(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
) -> Result<(), Error> {
let input = pool_copy(stream, host)?;
let mut out = pool_copy(stream, host)?;
let blocks = (host.len() as u32) / 2048;
let prepared = module.prepare_scale::<f32>(LaunchConfig1D::new(blocks, 2048, 0))?;
module.scale(stream, &prepared, 2.0, &input, &mut out)?;
Ok(())
}
/// The same function with `std::mem::forget`: the only way to skip a drop.
fn forget_on_gpu(stream: &Arc<CudaStream>, host: &[f32]) -> Result<(), DriverError> {
let input = pool_copy(stream, host)?;
std::mem::forget(input);
Ok(())
}void launchTooWide(const std::vector<float>& host)
{
DeviceBuffer<float> in(host);
DeviceBuffer<float> out(host.size());
transform<<<N / 2048, 2048>>>(in.view(), out.span(), Scale{2.0f});
check(cudaGetLastError());
}
// The only way to skip a destructor: a buffer created with new and never deleted.
void leakOnGpu(const std::vector<float>& host)
{
new DeviceBuffer<float>(host);
}
$ cargo oxide run
ownership
8 calls that return early: 0.0 MiB lost
2048 threads per block returned: scale: block (2048, 1, 1) does not match required block (256, 1, 1)
after the error: 0.0 MiB in use
copies sized by the type: 2097152 of 2097152 correct
8 calls with mem::forget: 64.0 MiB lost
Each of the 8 calls of forget_on_gpu forgot 1 buffer of 8 MiB, for the 64.0 MiB shown. The
other results match those of the C++ program, with 1 difference: the wrong block size was
rejected before it reached the driver. In C++, the counterpart of forget is a buffer created
with new and never deleted, and 8 calls of leakOnGpu lost the same 64.0 MiB.
A function creates a DeviceBuffer, then calls a function that throws. Who frees the buffer, and when?
The destructor of the buffer frees it, while the exception passes through the function’s scope
on its way to a catch. The code of the function after the throwing call never runs, but the
compiler destroys every local object in every scope that the exception leaves.
10.3 Templates: One Kernel, Many Types
10.3.1 Templates and instantiation
The kernel scale of raw.cu multiplies floats. A program that also needs to multiply doubles
and ints would need 3 copies of this kernel. Let us compare the float copy with the double copy
line by line. The parameter in changes from const float* to const double*, the parameter
out from float* to double*, and the factor from float to double. The index
computation, the bounds test and the multiplication are the same text in both. The 3 copies
therefore differ in 1 word, the element type, written in 3 places. C++ templates remove this
duplication by turning that word into a parameter.
Definition 10.3 Template and instantiation. A template is
a function or class written in terms of a template parameter, a placeholder for a type, such
as T. When the program uses the template with a particular type, the compiler substitutes the
type for the parameter and compiles the result, which is called an instantiation of the
template.
Example. From 1 template transform<T, F>, the uses transform<float, Scale<float>> and
transform<double, Scale<double>> produce 2 instantiations, 2 different kernels in the binary.
A template is not yet code. Only its instantiations are compiled into machine code, each exactly as if it had been written by hand, so a program contains 1 kernel for each type with which it uses the template.
Our kernel is generic in two ways: in the element type T, and in the operation F applied to
each element. Its pseudocode is that of scale, with the multiplication replaced by a call to
f.
KERNEL transform<T, F>(in, out, f): # T: element type, F: operation from T to T
i ← blockIdx.x × blockDim.x + threadIdx.x # this thread's index (Chapter 3)
if i < length of in:
out[i] ← f(in[i])
Listing 10.13 A template kernel and an operation to pass to it.
mod kernels {
// ...
/// out[i] = f(input[i]), for any T and any operation f from T to T, such as a closure.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn transform<T, F>(f: F, input: &[T], mut out: DisjointSlice<T>)
where
T: Copy,
F: Fn(T) -> T + Copy,
{
let idx = thread::index_1d();
let i = idx.get();
if let Some(slot) = out.get_mut(idx) {
*slot = f(input[i]);
}
}
// ...
}// out[i] = f(in[i]), for any number type T and any operation f from T to T.
template <Number T, UnaryOp<T> F>
__global__ void transform(cuda::std::span<const T> in, cuda::std::span<T> out, F f)
{
std::size_t i = blockIdx.x * std::size_t(blockDim.x) + threadIdx.x;
if (i < in.size()) {
out[i] = f(in[i]);
}
}
template <Number T>
struct Scale {
T factor;
__host__ __device__ T operator()(T x) const { return factor * x; }
};
The line template <Number T, UnaryOp<T> F> states that T must be a numeric type and F an
operation that maps a T to a T; we define both conditions in section 10.7. The arguments in
and out are spans, which carry their length together with the pointer, so the bounds check
compares i with in.size() rather than with a separate n that might belong to another array
(section 10.6.1). The index i is a std::size_t of 64 bits, so the kernel also works on
arrays of more than 231 elements.
Scale<T> is a function object, a struct with an operator(). The member function
operator() is the function that C++ runs when an object is followed by parentheses, so an
object triple of type Scale<float> with factor = 3 can be called as triple(x), and
triple(2.0f) returns 6.0. It stores its state, the factor, as a member, and it is passed to
the GPU as a kernel argument of sizeof(T) bytes. Its operator() is marked __host__ __device__ so that the kernel can call it; we explain these qualifiers in section 10.4. The Rust kernel transform takes a closure, the
Rust form of a lambda, as its operation f.
Let us run transform<float, Scale<float>> by hand on 4 values, in = 1, 2, 3, 4, with f =
triple. With blocks of 256 threads, 1 block is launched, and threads 0 to 3 pass the test i < in.size(), since the span in has size 4. Thread 2 reads in[2] = 3, calls f(3), and writes
9 into out[2]. The 4 threads write 3, 6, 9, 12. Threads 4 to 255 fail the test and write
nothing.
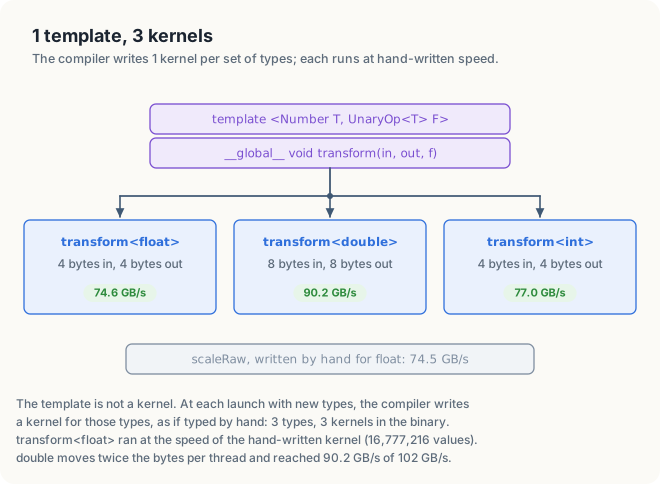
The timing function in Listing 10.14 is itself a template. The single call timeType<double>
creates a Scale<double> and launches transform<double, Scale<double>>, so the compiler
instantiates the whole chain from that 1 line.
Listing 10.14 1 timing function, instantiated for 3 types.
/// Time scale::<T> on `data`, print the rate, and check every result.
fn time_scale<T>(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
name: &str,
data: &[T],
factor: T,
) -> Result<bool, Error>
where
T: DeviceCopy + Mul<Output = T> + PartialEq,
{
let input = DeviceBuffer::from_host(stream, data)?;
let mut out = DeviceBuffer::<T>::zeroed(stream, data.len())?;
let blocks = blocks_for(data.len());
let prepared = module.prepare_scale::<T>(LaunchConfig1D::new(blocks, BLOCK, 0))?;
let mut launch = || Ok(module.scale(stream, &prepared, factor, &input, &mut out)?);
let ms = time_ms(stream, 20, &mut launch)?;
let bytes = 2 * data.len() * size_of::<T>();
println!(" {name:<14} {ms:7.2} ms {:6.1} GB/s", bytes as f64 / ms / 1e6);
let result = out.to_host_vec(stream)?;
Ok(result.iter().zip(data).all(|(&y, &x)| y == factor * x))
}// Time transform<T> on BIG values; return true if every result is right.
template <Number T>
bool timeType(const char* name, int runs)
{
std::vector<T> host(BIG);
for (int i = 0; i < BIG; ++i) {
host[i] = static_cast<T>(i % 1000);
}
DeviceBuffer<T> in(host);
DeviceBuffer<T> out(host.size());
Scale<T> triple{3};
auto launch = [&] {
transform<<<blocksFor(BIG), BLOCK>>>(in.view(), out.span(), triple);
};
double ms = timeKernel(launch, runs);
double gbs = 2.0 * BIG * sizeof(T) / ms / 1e6;
std::printf(" %-22s %7.2f ms %6.1f GB/s\n", name, ms, gbs);
std::vector<T> result = out.toHost();
for (int i = 0; i < BIG; ++i) {
if (result[i] != triple(host[i])) {
return false;
}
}
return true;
}
10.3.2 Lambdas as operations
A lambda is a function object written in place. The expression
[](float v) { return 2.0f * v; } defines an unnamed struct with that operator() and creates
an object of it. The unnamed struct is called the closure type of the lambda. The square
brackets at the start of the lambda are its capture list, which names the variables of the
surrounding code that the lambda may use; here the list is empty. Passing such a lambda to a
kernel looks natural, but it does not compile:
hostlambda.cu(227): error: The closure type for a lambda ("lambda [](float)->float", defined at hostlambda.cu:224) cannot be used in the template argument type of a __global__ function template instantiation, unless the lambda is defined within a __device__ or __global__ function, or the flag '-extended-lambda' is specified and the lambda is an extended lambda (a __device__ or __host__ __device__ lambda defined within a __host__ or __host__ __device__ function)
A lambda written in host code is a host function, and the GPU cannot execute host code. The
error message names the solution. An extended lambda carries __device__ or __host__ __device__ after its capture list, and the compiler then generates a device version of it. The
program must be compiled with --extended-lambda. We use 2 extended lambdas in Section 10.4.2.
A lambda can also capture variables, which copies them into the lambda object, as in
[factor](float v) {...}. For example, if the host variable factor holds 3.0 when the lambda
is created, the lambda object contains its own float with the value 3.0, and the lambda
multiplies by 3.0 even if factor changes later. The copies are passed to the GPU with the
kernel’s arguments, so they must be trivially copyable. A capture by reference, [&factor],
would pass the address of a host variable, which the GPU cannot use, and nvcc rejects it with
the error An extended __device__ lambda cannot capture variables by reference.
10.3.3 The run-time cost of templates
A template, a function object and a span are abstractions. They give names to things that the
hand-written kernel did directly. To measure their cost, we compare transform<float> with
scaleRaw, the C-style kernel of raw.cu, on the same 16,777,216 floats, and run the other 2
instantiations alongside. Each measurement follows 500 ms of warm-up, because a GPU raises the
clock rates of its cores and of its memory only under sustained load.
1 template, 3 types, 16777216 values
raw pointers, float 1.80 ms 74.5 GB/s
transform<float> 1.80 ms 74.6 GB/s
transform<double> 2.98 ms 90.2 GB/s
transform<int> 1.74 ms 77.0 GB/s
The rate counts each element read once and written once. For float, that is
2 × 16,777,216 × 4 bytes = 134.2 MB, divided by the time. transform<float> and scaleRaw both
took 1.80 ms, so the abstractions have no measurable cost. Repeated runs vary by 10 to 20% in
both directions, and the 2 kernels varied together. transform<double> moved twice as many
bytes, 268.4 MB, in 1.66 times the time. With 8 bytes per element, each load and store of a
thread carries twice as much data, and the kernel came closer to the GPU’s memory bandwidth of
102 GB/s: 90.2 GB/s is 88% of it.
A kernel is said to be memory-bound if its time is set by the number of bytes it moves
rather than by its arithmetic. Each thread of transform<float> performs 1 multiplication for
every 8 bytes it reads and writes, so each of these kernels is memory-bound. The shortest
possible time on any GPU then follows from the number of bytes moved and the memory
bandwidth, the maximum number of bytes that the memory can transfer per second. For example,
134.2 MB at 102 GB/s take 134.2 / 102 = 1.32 ms.
| GPU | Memory bandwidth | Least time for transform<float>, 134.2 MB |
|---|---|---|
| Jetson Orin NX 16 GB | 102 GB/s | 1.32 ms |
| Jetson AGX Thor | 273 GB/s | 0.49 ms |
| DGX Spark (GB10) | 273 GB/s | 0.49 ms |
| GeForce RTX 4090 | 1,008 GB/s | 0.133 ms |
| GeForce RTX 5090 | 1,792 GB/s | 0.075 ms |
| A100 SXM 80 GB | 2,039 GB/s | 0.066 ms |
| H100 SXM | 3,350 GB/s | 0.040 ms |
The measured 1.80 ms corresponds to 74.6 GB/s, 73% of the GPU’s 102 GB/s. A template does not change this limit; only moving fewer bytes would.
10.3.4 Generic kernels in Rust
Rust’s equivalent of templates is generics: a function with a type parameter T and a list
of conditions on that type. The compiler instantiates a generic function for each type it is
used with, a process that Rust calls monomorphization. cuda-oxide applies it to kernels, so
scale::<f32> and scale::<f64> become 2 separate kernels.
Listing 10.15 A generic kernel.
mod kernels {
// ...
/// out[i] = factor * input[i], for any T that can be multiplied.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scale<T>(factor: T, input: &[T], mut out: DisjointSlice<T>)
where
T: Copy + Mul<Output = T>,
{
let idx = thread::index_1d();
let i = idx.get();
if let Some(slot) = out.get_mut(idx) {
*slot = factor * input[i];
}
}
// ...
}// out[i] = f(in[i]), for any number type T and any operation f from T to T.
template <Number T, UnaryOp<T> F>
__global__ void transform(cuda::std::span<const T> in, cuda::std::span<T> out, F f)
{
std::size_t i = blockIdx.x * std::size_t(blockDim.x) + threadIdx.x;
if (i < in.size()) {
out[i] = f(in[i]);
}
}
template <Number T>
struct Scale {
T factor;
__host__ __device__ T operator()(T x) const { return factor * x; }
};
A trait bound is a condition, written after a type parameter, that the type must implement
the named traits. The bound T: Copy + Mul<Output = T> lists the operations that the body
needs: values of T can be copied (the trait Copy), and 2 of them can be multiplied to give a
T (the trait Mul with result type T). f32, f64 and i32 satisfy both; a String
satisfies neither. The host side names the type when it prepares the launch,
prepare_scale::<T>, and a generic host function, such as the timing function in Listing 10.16,
can do so for its own T.
Listing 10.16 1 generic timing function for 3 types.
/// Time scale::<T> on `data`, print the rate, and check every result.
fn time_scale<T>(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
name: &str,
data: &[T],
factor: T,
) -> Result<bool, Error>
where
T: DeviceCopy + Mul<Output = T> + PartialEq,
{
let input = DeviceBuffer::from_host(stream, data)?;
let mut out = DeviceBuffer::<T>::zeroed(stream, data.len())?;
let blocks = blocks_for(data.len());
let prepared = module.prepare_scale::<T>(LaunchConfig1D::new(blocks, BLOCK, 0))?;
let mut launch = || Ok(module.scale(stream, &prepared, factor, &input, &mut out)?);
let ms = time_ms(stream, 20, &mut launch)?;
let bytes = 2 * data.len() * size_of::<T>();
println!(" {name:<14} {ms:7.2} ms {:6.1} GB/s", bytes as f64 / ms / 1e6);
let result = out.to_host_vec(stream)?;
Ok(result.iter().zip(data).all(|(&y, &x)| y == factor * x))
}// Time transform<T> on BIG values; return true if every result is right.
template <Number T>
bool timeType(const char* name, int runs)
{
std::vector<T> host(BIG);
for (int i = 0; i < BIG; ++i) {
host[i] = static_cast<T>(i % 1000);
}
DeviceBuffer<T> in(host);
DeviceBuffer<T> out(host.size());
Scale<T> triple{3};
auto launch = [&] {
transform<<<blocksFor(BIG), BLOCK>>>(in.view(), out.span(), triple);
};
double ms = timeKernel(launch, runs);
double gbs = 2.0 * BIG * sizeof(T) / ms / 1e6;
std::printf(" %-22s %7.2f ms %6.1f GB/s\n", name, ms, gbs);
std::vector<T> result = out.toHost();
for (int i = 0; i < BIG; ++i) {
if (result[i] != triple(host[i])) {
return false;
}
}
return true;
}
1 generic kernel, 3 types, 16777216 values
scale::<f32> 1.92 ms 69.9 GB/s
scale::<f64> 2.88 ms 93.3 GB/s
scale::<i32> 1.77 ms 75.7 GB/s
The Rust instantiations ran within 7% of the C++ ones, which is inside the variation between runs, and in the same order: double reaches the highest rate in bytes per second.
10.4 __host__ __device__ Functions
10.4.1 Compiling a function for both processors
CUDA marks every function with the processor it is compiled for. A __global__ function is a
kernel. It is launched from the host and runs on the device. A __device__ function runs on the
device and is called from device code. A function with no qualifier, or with __host__, runs on
the host. A function marked __host__ __device__ is compiled twice from 1 definition, once for
each processor, and can be called from either side.
This makes a simple test possible: run the function on the CPU, run it in a kernel, and check that the 2 results agree. Testing a GPU result against a CPU result computed by the same source code is called differential testing.
for each x in the test values:
cpu[x] ← f(x) # host compilation
gpu ← run f on every x in a kernel # device compilation
count the x where the bits of cpu[x] and gpu[x] differ
A function compiled for both processors may use only what exists on both: arithmetic, the CUDA
math functions such as fmaf, sqrtf and expf, and plain C++. A part that must differ
between the 2 compilations is guarded by the macro __CUDA_ARCH__, which the compiler defines
only while it compiles device code:
__host__ __device__ float logOf(float x)
{
#ifdef __CUDA_ARCH__
return __logf(x); // device: the fast hardware approximation
#else
return std::log(x); // host: the standard library
#endif
}
The Rust programs of this book have no counterpart of this guard: a Rust function called from a kernel is compiled for both processors from the same text (section 10.4.3).
10.4.2 Floating-point differences between host and device
As an example, we use the polynomial 1 + x + x²/2 + x³/6, the first 4 terms of the series of ex. Horner’s rule evaluates a polynomial from its highest coefficient down by nesting the multiplications. It writes the polynomial as 1 + x(1 + x(1/2 + x/6)), which takes 3 multiplications, each followed by an addition. At x = 1, for example, the 3 steps give 1/2 + 1/6 = 0.6667, then 1 + 0.6667 = 1.6667, then 1 + 1.6667 = 2.6667. Listing 10.17 writes it in two ways.
Listing 10.17 1 polynomial, written 2 ways, for both processors.
/// 1 + x + x^2/2 + x^3/6, the first 4 terms of e^x, by Horner's rule.
fn exp_poly(x: f32) -> f32 {
1.0 + x * (1.0 + x * (0.5 + x * (1.0 / 6.0)))
}
/// The same polynomial, with every multiply-add rounded once.
fn exp_poly_fma(x: f32) -> f32 {
let p = x.mul_add(1.0 / 6.0, 0.5);
let p = x.mul_add(p, 1.0);
x.mul_add(p, 1.0)
}// 1 + x + x^2/2 + x^3/6, the first 4 terms of e^x, by Horner's rule.
__host__ __device__ float expPoly(float x)
{
return 1.0f + x * (1.0f + x * (0.5f + x * (1.0f / 6.0f)));
}
// The same polynomial, with every multiply-add rounded once, on both sides.
__host__ __device__ float expPolyFma(float x)
{
float p = fmaf(x, 1.0f / 6.0f, 0.5f);
p = fmaf(x, p, 1.0f);
return fmaf(x, p, 1.0f);
}
The test in Listing 10.18 wraps each function in an extended __host__ __device__ lambda, runs
it in transform on 2,097,152 values from −1 to 1, calls the same lambda on the CPU, and
compares the bits of the results with memcmp.
Listing 10.18 The differential test.
fn main() -> Result<(), Error> {
// ...
let prepared = module.prepare_poly(config)?;
module.poly(&stream, &prepared, &x, &mut y)?;
let gpu = y.to_host_vec(&stream)?;
let plain_differ = xs.iter().zip(&gpu).filter(|&(&x, &y)| exp_poly(x) != y).count();
println!(" x * y + z: {plain_differ} of {N} differ from the CPU");
let prepared = module.prepare_poly_fma(config)?;
module.poly_fma(&stream, &prepared, &x, &mut y)?;
let gpu = y.to_host_vec(&stream)?;
let fused_differ = xs.iter().zip(&gpu).filter(|&(&x, &y)| exp_poly_fma(x) != y).count();
println!(" mul_add: {fused_differ} of {N} differ from the CPU");
passed &= fused_differ == 0;
// ...
}int main()
{
// ...
auto plain = [] __host__ __device__ (float v) { return expPoly(v); };
auto fused = [] __host__ __device__ (float v) { return expPolyFma(v); };
transform<<<blocksFor(N), BLOCK>>>(x.view(), y.span(), plain);
check(cudaGetLastError());
std::vector<float> gpuPlain = y.toHost();
transform<<<blocksFor(N), BLOCK>>>(x.view(), y.span(), fused);
check(cudaGetLastError());
std::vector<float> gpuFused = y.toHost();
int plainDiffer = 0;
int fusedDiffer = 0;
for (int i = 0; i < N; ++i) {
float cpuPlain = plain(xs[i]);
float cpuFused = fused(xs[i]);
plainDiffer += std::memcmp(&cpuPlain, &gpuPlain[i], sizeof(float)) != 0;
fusedDiffer += std::memcmp(&cpuFused, &gpuFused[i], sizeof(float)) != 0;
}
std::printf(" x * y + z: %d of %d differ from the CPU\n", plainDiffer, N);
std::printf(" fmaf: %d of %d differ from the CPU\n", fusedDiffer, N);
passed = passed && fusedDiffer == 0;
// ...
}
1 function on both sides, 2097152 values in [-1, 1)
x * y + z: 585903 of 2097152 differ from the CPU
fmaf: 0 of 2097152 differ from the CPU
The version written as x * y + z differs in 585,903 values, 28% of them, although both
processors executed the same source code. To see how 1 expression can produce 2 results, let us
compute a × b + c by hand with a = 1.23, b = 4.56 and c = −5.60. A float keeps a fixed number of
binary digits, and we imitate it with decimal arithmetic that keeps 3 significant digits.
Suppose first that the multiplication and the addition are 2 separate operations, each rounded to 3 digits. The exact product 1.23 × 4.56 = 5.6088 is rounded to 5.61, and 5.61 − 5.60 gives 0.0100. Suppose instead that the 2 operations are performed as 1, and only the final result is rounded. The exact value 1.23 × 4.56 − 5.60 = 0.0088 is rounded to 0.00880. The 2 results differ by 14%, because the first rounding discarded 0.0012 of the product, and the subtraction of a nearly equal number then made that small part the largest part of the result. Figure 10.6 shows both computations.
Key observation a × b + c computed as 2 operations is rounded twice, and computed as 1 operation it is rounded once. The 2 results can differ in their last digits, and neither of them is wrong.
Definition 10.4 Fused multiply-add. A fused multiply-add (FMA) computes a × b + c as a single operation with a single rounding at the end, so the product is kept exact inside the addition.
Example. With 3 significant digits, the FMA of 1.23, 4.56 and −5.60 gives 0.00880, while a multiplication followed by an addition gives 0.0100.
The GPU has an FMA instruction, and by default the device compiler fuses each x * (...) + ...
in expPoly into it. The host compiler used here does not fuse, so the CPU rounds twice at each
of the 3 steps where the GPU rounds once.
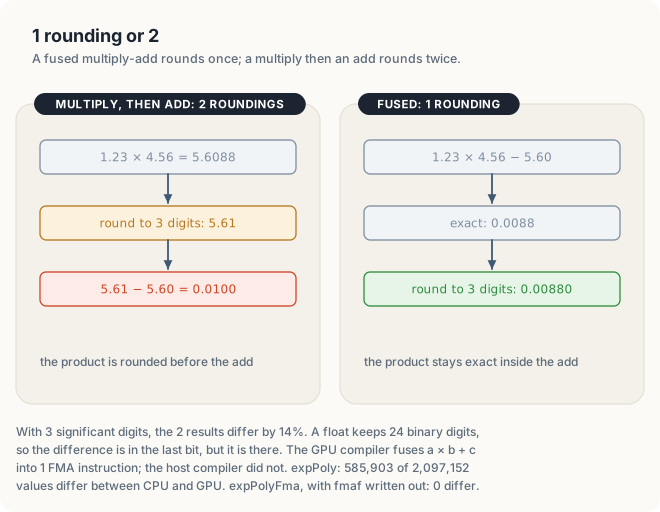
A float keeps 24 binary digits, so in expPoly the 2 results differ only in their last binary
digits, by about 1 part in 107. Neither result is wrong. Each follows the rounding
rules for its own sequence of operations, and the fused version rounds fewer times. However, a
differential test that expects identical bits fails on 28% of its inputs. expPolyFma writes
each step as fmaf(a, b, c), which rounds once on both processors, because the host’s fmaf
follows the same rule of IEEE 754, the standard that defines the floating-point formats and
how each operation rounds. Its 0 differences confirm that the device compilation is correct.
The compiler option nvcc --fmad=false would disable fusion for the whole file, but it would
also make every kernel in the file slower, because each fused operation becomes 2 instructions.
Writing fmaf where the bits must agree states the intent in the code, at the place where it
applies.
The same source code can produce different bits on the CPU and the GPU, because the GPU fuses a
multiplication and an addition into an operation with 1 rounding. Use fmaf (or mul_add in
Rust) where the two sides must agree bit for bit.
10.4.3 Host and device functions in Rust
In cuda-oxide, an ordinary Rust function that is called from a kernel is compiled for the device as well as for the host, so it needs no qualifier.
Listing 10.19 The polynomial, called by a kernel and by the CPU.
/// 1 + x + x^2/2 + x^3/6, the first 4 terms of e^x, by Horner's rule.
fn exp_poly(x: f32) -> f32 {
1.0 + x * (1.0 + x * (0.5 + x * (1.0 / 6.0)))
}
/// The same polynomial, with every multiply-add rounded once.
fn exp_poly_fma(x: f32) -> f32 {
let p = x.mul_add(1.0 / 6.0, 0.5);
let p = x.mul_add(p, 1.0);
x.mul_add(p, 1.0)
}// 1 + x + x^2/2 + x^3/6, the first 4 terms of e^x, by Horner's rule.
__host__ __device__ float expPoly(float x)
{
return 1.0f + x * (1.0f + x * (0.5f + x * (1.0f / 6.0f)));
}
// The same polynomial, with every multiply-add rounded once, on both sides.
__host__ __device__ float expPolyFma(float x)
{
float p = fmaf(x, 1.0f / 6.0f, 0.5f);
p = fmaf(x, p, 1.0f);
return fmaf(x, p, 1.0f);
}
x.mul_add(a, b) is Rust’s FMA. The kernels poly and poly_fma call the 2 functions, and
main compares their results with those of the same functions run on the CPU.
1 function on both sides, 2097152 values in [-1, 1)
x * y + z: 585903 of 2097152 differ from the CPU
mul_add: 0 of 2097152 differ from the CPU
The counts are identical to those of the C++ program. The device compiler fuses, the host
compiler does not (Rust never fuses on its own), and mul_add rounds once on both processors.
10.5 constexpr and static_assert
A constant expression is an expression whose value the compiler can compute while it
compiles the program. A variable declared constexpr must be initialized with a constant
expression, and a function declared constexpr can be evaluated by the compiler when its
arguments are constant expressions. A static_assert(condition, message) evaluates its
condition during compilation and stops the compilation with the message when the condition is
false. Together, these features move checks from run time to compile time.
A useful application is checking the block size. A warp is a group of 32 threads of a block that the hardware executes together, 1 instruction for all 32. A block size that is not a multiple of 32 leaves the last warp of every block partly idle, and a size above 1,024 threads cannot be launched at all (section 10.1.3). Listing 10.20 checks both conditions while compiling.
Listing 10.20 The block size, checked while compiling.
const BLOCK: u32 = 256;
const _: () = assert!(BLOCK % 32 == 0, "a block is a whole number of warps");
const _: () = assert!(BLOCK <= 1024, "a block holds at most 1,024 threads");
const fn blocks_for(n: usize) -> u32 {
n.div_ceil(BLOCK as usize) as u32
}
const _: () = assert!(blocks_for(1000) == 4);constexpr int BLOCK = 256;
static_assert(BLOCK % 32 == 0, "a block is a whole number of warps");
static_assert(BLOCK <= 1024, "a block holds at most 1,024 threads");
constexpr int blocksFor(std::size_t n)
{
return static_cast<int>((n + BLOCK - 1) / BLOCK);
}
static_assert(blocksFor(1000) == 4);
The function blocksFor computes the number of blocks needed for a given number of elements,
rounding up. For 1,000 elements and blocks of 256 threads, it computes
(1,000 + 256 − 1) / 256 = 1,255 / 256 = 4 in integer division. Four blocks hold 1,024 threads,
enough for 1,000 elements, whereas 3 blocks, with 768 threads, would not be. Because blocksFor
is constexpr, the compiler performs this division itself, and the assertion
static_assert(blocksFor(1000) == 4) holds.
If we change the first line to constexpr int BLOCK = 100;, the file no longer compiles:
block100.cu(15): error: static assertion failed with "a block is a whole number of warps"
static_assert(BLOCK % 32 == 0, "a block is a whole number of warps");
^
block100.cu(23): error: static assertion failed
static_assert(blocksFor(1000) == 4);
^
With blocks of 100 threads, 1,000 elements need 10 blocks, so the second assertion fails as
well. A constexpr constant is preferable to #define BLOCK 256 because it has a type and a
scope and can be used in a static_assert, whereas a macro is text that the preprocessor pastes
wherever its name appears.
Rust writes the same checks as constant assertions. An assert! inside a const item is
evaluated by the compiler, and a false condition is a compile error.
Listing 10.21 The checks of Listing 10.20.
const BLOCK: u32 = 256;
const _: () = assert!(BLOCK % 32 == 0, "a block is a whole number of warps");
const _: () = assert!(BLOCK <= 1024, "a block holds at most 1,024 threads");
const fn blocks_for(n: usize) -> u32 {
n.div_ceil(BLOCK as usize) as u32
}
const _: () = assert!(blocks_for(1000) == 4);constexpr int BLOCK = 256;
static_assert(BLOCK % 32 == 0, "a block is a whole number of warps");
static_assert(BLOCK <= 1024, "a block holds at most 1,024 threads");
constexpr int blocksFor(std::size_t n)
{
return static_cast<int>((n + BLOCK - 1) / BLOCK);
}
static_assert(blocksFor(1000) == 4);
With const BLOCK: u32 = 100;, both Rust assertions fail while compiling:
error[E0080]: evaluation panicked: a block is a whole number of warps
--> src/main.rs:21:15
|
21 | const _: () = assert!(BLOCK % 32 == 0, "a block is a whole number of warps");
| ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^ evaluation of `_` failed here
error[E0080]: evaluation panicked: assertion failed: blocks_for(1000) == 4
--> src/main.rs:28:15
|
28 | const _: () = assert!(blocks_for(1000) == 4);
| ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^ evaluation of `_` failed here
10.6 CUDA 12 and the cuda:: Namespace
CUDA includes a C++ library for device code called libcu++. A namespace is a named group
of declarations, which keeps names of different libraries apart; the full name std::vector
means the name vector in the namespace std of the standard library. The names of libcu++ are
in 2 namespaces: cuda::std:: holds versions of standard library types that work in device
code, and cuda:: holds extensions specific to the GPU. Both headers used in this section,
<cuda/std/span> and <cuda/atomic>, are available in CUDA 12.6 and in CUDA 13.2.
10.6.1 cuda::std::span
The C-style kernel scale received a pointer and a separate count n. Consider a program with
2 device arrays: a, at address 0x7f00, with 1,000 floats, and b, with 2,000 floats. A call
scale<<<8, 256>>>(a, out, 2000, 2.0f) passes the count of b together with the pointer of
a. The kernel cannot tell, because it receives 2 unrelated numbers, 0x7f00 and 2,000. Threads
0 to 999 read a correctly. Threads 1,000 to 1,999 pass the test i < n and read the 1,000
floats that follow a in memory, which belong to another allocation or to none. No error is
reported. The mistake becomes impossible if the length travels together with the pointer from
the place where both are known, the buffer.
Definition 10.5 Span. A span is a pointer and a length kept together: a view of a contiguous array that the span does not own. Destroying a span frees nothing.
Example. A span of the array a above holds the 2 values 0x7f00 and 1,000. A kernel that
receives it tests i < in.size(), that is i < 1000.
cuda::std::span<const T> allows reading, and cuda::std::span<T> allows writing as well.
DeviceBuffer::view() and span() return one of each, and transform receives them:
fn scale_on_gpu(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
factor: f32,
) -> Result<Option<Vec<f32>>, Error> {
// ...
module.scale(stream, &prepared, factor, &input, &mut out)?;
// ...
}transform<<<blocksFor(in.size()), BLOCK>>>(in.view(), out.span(), Scale{factor});
The length of a span comes from the buffer it views, so the bounds check i < in.size() always
uses the correct length. A span occupies 16 bytes, a pointer
and a length, and it is passed to the kernel by value like any other argument. A Rust slice,
&[T], has always consisted of a pointer and a length, which is why the Rust kernels of this
book never take a separate count.
10.6.2 cuda::atomic_ref and thread scopes
Recall from Chapter 5 why a shared counter needs special care. An ordinary increment count += 1 is 3 steps: read the value, add 1, write the result. Suppose the counter holds 5 and 2
threads increment it at the same time. Both read 5, both compute 6, and both write 6. 2
increments were made, but the counter rose by 1, and 1 count is lost. An atomic operation on
a memory location completes as a single indivisible step, so that no other thread can observe or
modify the location partway through it. With an atomic increment, the second thread reads 6, not
5, and the counter ends at 7. cuda::atomic_ref<int, scope> applies atomic operations to an
ordinary int that already exists, in this example a counter in a DeviceBuffer<int>. The
int itself remains a plain int.
The memory order of an atomic operation specifies what other memory accesses it orders, that
is, whether writes made before the operation become visible to a thread that observes its
result. cuda::memory_order_relaxed orders nothing except the counter itself. This is
sufficient for a count, and it is the least expensive order.
The thread scope specifies the set of threads that must agree on the value. For example, a counter in shared memory, the on-chip memory that only the threads of 1 block can access, is never seen by the threads of other blocks, so only the threads of its block need to agree on it. A counter in global memory, the main memory of the GPU, can be reached by every thread of the kernel. The narrower the set, the less work the hardware must do to keep those threads in agreement. The table lists the 3 scopes.
| Scope | The threads that must agree | Example |
|---|---|---|
cuda::thread_scope_block | the threads of 1 block | a counter in shared memory (Chapter 5) |
cuda::thread_scope_device | every thread of 1 GPU | a counter in global memory |
cuda::thread_scope_system | the CPU and every GPU | a flag in memory both processors write |
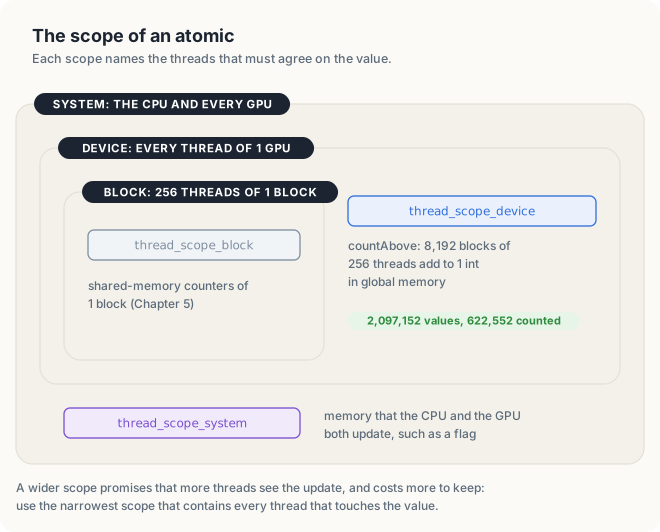
Listing 10.22 A count with cuda::atomic_ref.
mod kernels {
// ...
/// Count the values above a threshold. DeviceAtomicU32 adds atomically, device-wide.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn count_above(input: &[f32], threshold: f32, count: &[DeviceAtomicU32]) {
let i = thread::index_1d().get();
if i < input.len() && input[i] > threshold {
count[0].fetch_add(1, AtomicOrdering::Relaxed);
}
}
}// Count the values above a threshold. atomic_ref makes an ordinary int atomic.
template <Number T>
__global__ void countAbove(cuda::std::span<const T> in, T threshold, int* count)
{
std::size_t i = blockIdx.x * std::size_t(blockDim.x) + threadIdx.x;
if (i < in.size() && in[i] > threshold) {
cuda::atomic_ref<int, cuda::thread_scope_device> total(*count);
total.fetch_add(1, cuda::memory_order_relaxed);
}
}
The kernel in Listing 10.22 counts the results of expPolyFma that are greater than 1.5. Its
2,097,152 threads, in 8,192 blocks of 256, all add to a single int in global memory, so the
scope must be the whole device.
span and atomic_ref: 622552 values above 1.5, CPU 622552
PASSED
We can verify this count by hand. The polynomial reaches 1.5 at x = 0.40629, slightly to the right of ln 1.5 = 0.40547, because the polynomial is smaller than ex for x > 0. The inputs are evenly spaced from −1 to 1, so the fraction above 0.40629 is (1 − 0.40629) ÷ 2 = 0.29686, and 0.29686 × 2,097,152 = 622,552 values, the number that both processors counted.
The Rust programs of Chapter 5 use DeviceAtomicU32 from cuda-device, which serves the same
purpose. The Rust kernel count_above of Listing 10.22 uses it and counted the same 622,552
values.
10.7 C++20 Concepts
A template accepts any type for which its body compiles. The body of transform contains only
out[i] = f(in[i]), and C++ converts between number types implicitly. An operation f that
takes a float and returns a bool therefore passes: the bool is converted to a float and
stored. The template compiles, and every result is 0.0 or 1.0. The mistake is in the call, but
the body of the template has no way to see it, because the body never states what type f must
return. A condition written next to the template parameters can state it.
Definition 10.6 Concept. A concept is a named condition on template parameters that the compiler checks when the template is used. A use whose types do not satisfy the condition is a compile error at the call.
Example. The concept Number<T> of Listing 10.23 holds for float and int and fails for
std::string, so transform<std::string, ...> is rejected at the call.
Listing 10.23 defines the 2 concepts that transform requires.
Listing 10.23 2 concepts.
mod kernels {
// ...
/// out[i] = f(input[i]), for any T and any operation f from T to T, such as a closure.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn transform<T, F>(f: F, input: &[T], mut out: DisjointSlice<T>)
where
T: Copy,
F: Fn(T) -> T + Copy,
// ...
}template <typename T>
concept Number = std::integral<T> || std::floating_point<T>;
template <typename F, typename T>
concept UnaryOp = std::invocable<F, T> && std::same_as<std::invoke_result_t<F, T>, T>;
Number<T> holds when T is an integer or floating-point type. UnaryOp<F, T> holds when an
F can be called with a T and returns exactly a T. Writing UnaryOp<T> F in the template’s
parameter list applies the concept to F, with T as its second argument. We can evaluate both
conditions by hand for 2 calls. For transform with T = float and F = Scale<float>,
Number<float> holds, and Scale<float> called with a float returns a float, so
UnaryOp<Scale<float>, float> holds as well. For F = a lambda of type (float)->bool, the
lambda can be called with a float, but it returns a bool, which is not exactly a float, so
UnaryOp fails.
To see what these conditions prevent, we replaced Scale{factor} in scaleOnGpu with an
operation that returns a bool, [] __device__ (float v) { return v > 0.0f; }, and compiled it
first against a version of transform without the concepts. It compiled without a warning,
because C++ converts a bool to a float implicitly, and it ran:
copies sized by the type: 0 of 2097152 correct
Every result was 1.0, the float value of true, and none was the expected 2.0. With the
concepts, the same call does not compile:
concept.cu(118): error: no instance of function template "transform" matches the argument list
argument types are: (cuda::std::__4::span<const float, 18446744073709551615UL>, cuda::std::__4::span<float, 18446744073709551615UL>, lambda [](float)->bool)
concept.cu(36): note #3327-D: candidate function template "transform" failed deduction
The message points to the call and shows the type of the lambda, (float)->bool, which is the
error. Template argument deduction is the step in which the compiler works out the template
parameters, here T and F, from the types of the arguments of a call. When a deduced type
fails a concept, the compiler discards the template, and the message reports that deduction
failed. A Rust generic states its conditions in the same way, as trait bounds. Rust checks
them when the function is used, and also when it is defined: the body of scale<T> may perform
only the operations that Copy + Mul<Output = T> allows. The closure |v: f32| v > 0.0, passed
to the Rust kernel transform, fails its bound F: Fn(T) -> T at the call:
error[E0271]: expected `{closure@main.rs:455:20}` to return `f32`, but it returns `bool`
--> src/main.rs:455:29
|
455 | let positive = |v: f32| v > 0.0;
| -------- ^^^^^^^ expected `f32`, found `bool`
| |
| this closure
456 | let prepared = module.prepare_transform_for(&0.0f32, &positive, config)?;
| --------------------- --------- closure used here
10.8 Style Summary
Figure 10.8 collects the errors examined in this chapter and shows where each is detected in the C API, in modern C++ and in Rust.
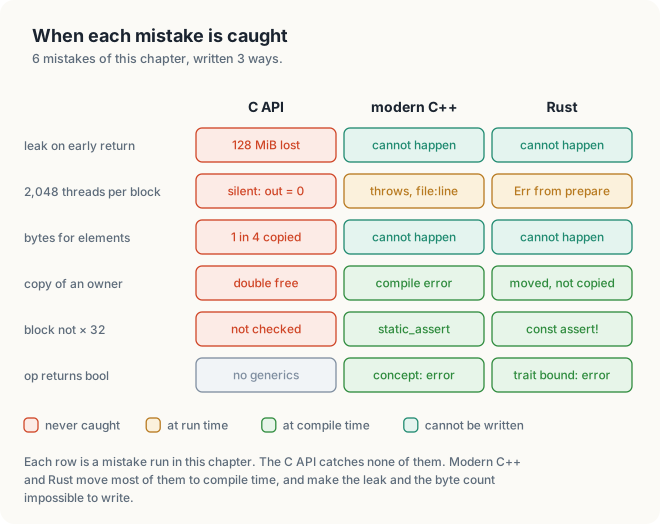
The common principle is to turn a rule that the programmer must remember into a rule that the
program cannot break. Some rules can no longer be broken because no call site performs the step
any more: a destructor frees the memory, and a type computes the byte count. Some violations
become compile errors: deleted copies, static_assert and concepts. The remaining ones become
run-time errors that cannot be ignored, such as an exception or an Err passed up by ?. What
C++ cannot check, such as index arithmetic, Rust kernels confine to DisjointSlice, the
cuda-oxide output type through which each thread can write only the element at its own index,
and to unsafe blocks with a written justification (Chapter 13). The table summarizes the
replacements.
| C-style habit | Modern replacement | What the compiler now does |
|---|---|---|
cudaMalloc and cudaFree by hand | DeviceBuffer<T> | frees on every path, forbids 2 owners |
| byte counts at each call | sizes from sizeof(T) inside the class | no call site writes a byte count |
CHECK macro | check() with std::source_location, exceptions | names the failed line; frees while unwinding |
| 1 kernel per type | template kernels and function objects | writes 1 kernel per type |
#define TILE 16 | constexpr int TILE = 16 and static_assert | checks configuration while compiling |
pointer and separate n | cuda::std::span | keeps the length with the pointer |
atomicAdd on a raw pointer | cuda::atomic_ref with a scope | states which threads must agree |
| unconstrained templates | concepts | rejects a wrong operation at the call |
None of these techniques has a run-time cost: transform<float> ran at 74.6 GB/s, and the
hand-written kernel at 74.5 GB/s.
10.9 The complete programs
Listing 10.24 The complete programs. code/oxide/ch10_modern/src/main.rs, code/ch10_modern/device_buffer.hpp, code/ch10_modern/raw.cu, code/ch10_modern/modern.cu
//! Chapter 10 in Rust: ownership frees device memory, generic kernels, 1 function, 2 sides.
//!
//! cargo oxide run
use std::ffi::c_void;
use std::marker::PhantomData;
use std::mem::ManuallyDrop;
use std::ops::Mul;
use std::panic::Location;
use std::sync::Arc;
use std::time::Instant;
use cuda_core::sys;
use cuda_core::sys::CUmemPool_attribute_enum_CU_MEMPOOL_ATTR_USED_MEM_CURRENT as USED_MEM;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, DeviceCopy, DriverError, IntoResult};
use cuda_core::LaunchConfig1D;
use cuda_device::atomic::{AtomicOrdering, DeviceAtomicU32};
use cuda_device::{DisjointSlice, cuda_module, kernel, launch_contract, thread};
const BLOCK: u32 = 256;
const _: () = assert!(BLOCK % 32 == 0, "a block is a whole number of warps");
const _: () = assert!(BLOCK <= 1024, "a block holds at most 1,024 threads");
const fn blocks_for(n: usize) -> u32 {
n.div_ceil(BLOCK as usize) as u32
}
const _: () = assert!(blocks_for(1000) == 4);
const N: usize = 1 << 21;
const BIG: usize = 1 << 24;
type Error = Box<dyn std::error::Error>;
/// 1 + x + x^2/2 + x^3/6, the first 4 terms of e^x, by Horner's rule.
fn exp_poly(x: f32) -> f32 {
1.0 + x * (1.0 + x * (0.5 + x * (1.0 / 6.0)))
}
/// The same polynomial, with every multiply-add rounded once.
fn exp_poly_fma(x: f32) -> f32 {
let p = x.mul_add(1.0 / 6.0, 0.5);
let p = x.mul_add(p, 1.0);
x.mul_add(p, 1.0)
}
#[cuda_module]
mod kernels {
use super::*;
/// out[i] = factor * input[i], for any T that can be multiplied.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scale<T>(factor: T, input: &[T], mut out: DisjointSlice<T>)
where
T: Copy + Mul<Output = T>,
{
let idx = thread::index_1d();
let i = idx.get();
if let Some(slot) = out.get_mut(idx) {
*slot = factor * input[i];
}
}
/// out[i] = f(input[i]), for any T and any operation f from T to T, such as a closure.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn transform<T, F>(f: F, input: &[T], mut out: DisjointSlice<T>)
where
T: Copy,
F: Fn(T) -> T + Copy,
{
let idx = thread::index_1d();
let i = idx.get();
if let Some(slot) = out.get_mut(idx) {
*slot = f(input[i]);
}
}
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn poly(x: &[f32], mut y: DisjointSlice<f32>) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(slot) = y.get_mut(idx) {
*slot = exp_poly(x[i]);
}
}
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn poly_fma(x: &[f32], mut y: DisjointSlice<f32>) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(slot) = y.get_mut(idx) {
*slot = exp_poly_fma(x[i]);
}
}
/// Count the values above a threshold. DeviceAtomicU32 adds atomically, device-wide.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn count_above(input: &[f32], threshold: f32, count: &[DeviceAtomicU32]) {
let i = thread::index_1d().get();
if i < input.len() && input[i] > threshold {
count[0].fetch_add(1, AtomicOrdering::Relaxed);
}
}
}
/// Bytes in use from the pool that stream-ordered allocations draw on, in MiB.
fn pool_mib(ctx: &CudaContext) -> Result<f64, DriverError> {
ctx.synchronize()?;
let mut pool = std::ptr::null_mut();
let mut used: u64 = 0;
let used_ptr = (&mut used as *mut u64).cast::<c_void>();
// SAFETY: both out-pointers are valid for the length of each call.
unsafe {
sys::cuDeviceGetDefaultMemPool(&mut pool, ctx.cu_device()).result()?;
sys::cuMemPoolGetAttribute(pool, USED_MEM, used_ptr).result()?;
}
Ok(used as f64 / 1_048_576.0)
}
/// Mistake 1 of raw.cu: ManuallyDrop turns the drops off, so the frees are written by
/// hand, and the early return skips them.
fn scale_by_hand(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
factor: f32,
) -> Result<Option<Vec<f32>>, Error> {
let mut input = ManuallyDrop::new(pool_copy(stream, host)?);
let mut out = ManuallyDrop::new(pool_copy(stream, host)?);
if factor == 0.0 {
return Ok(None); // nothing to scale
}
let config = LaunchConfig1D::new(blocks_for(host.len()), BLOCK, 0);
let prepared = module.prepare_scale::<f32>(config)?;
module.scale(stream, &prepared, factor, &input, &mut out)?;
let result = out.to_host_vec(stream)?;
// SAFETY: neither buffer is used after its drop.
unsafe {
ManuallyDrop::drop(&mut input);
ManuallyDrop::drop(&mut out);
}
Ok(Some(result))
}
/// Mistake 3 of raw.cu: the driver's copy counts bytes, but `host.len()` counts floats.
fn copy_count_as_bytes(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
) -> Result<usize, Error> {
let input = DeviceBuffer::<f32>::zeroed(stream, host.len())?;
let mut out = DeviceBuffer::<f32>::zeroed(stream, host.len())?;
let src = host.as_ptr().cast::<c_void>();
// SAFETY: both sides hold 4 bytes per float, so host.len() bytes fit in each.
check(unsafe { sys::cuMemcpyHtoD_v2(input.cu_deviceptr(), src, host.len()) })?;
let config = LaunchConfig1D::new(blocks_for(host.len()), BLOCK, 0);
let prepared = module.prepare_scale::<f32>(config)?;
module.scale(stream, &prepared, 2.0, &input, &mut out)?;
let result = out.to_host_vec(stream)?;
Ok(result.iter().filter(|&&x| x == 2.0).count())
}
/// Turn a driver result into an error that names the caller's file and line.
#[track_caller]
fn check(result: sys::CUresult) -> Result<(), Error> {
let place = Location::caller();
match result.result() {
Ok(()) => Ok(()),
Err(error) => Err(format!("{}:{}: {error}", place.file(), place.line()).into()),
}
}
/// `count` values of T in device memory from the pool, owned by exactly 1 variable.
struct PoolBuffer<T> {
ptr: sys::CUdeviceptr,
count: usize,
stream: Arc<CudaStream>,
elements: PhantomData<T>,
}
impl<T: DeviceCopy> PoolBuffer<T> {
#[track_caller]
fn new(stream: &Arc<CudaStream>, count: usize) -> Result<Self, Error> {
let mut ptr = 0;
let bytes = count * size_of::<T>();
// SAFETY: `ptr` is a valid out-pointer, and the stream belongs to this context.
check(unsafe { sys::cuMemAllocAsync(&mut ptr, bytes, stream.cu_stream()) })?;
let elements = PhantomData;
Ok(Self { ptr, count, stream: stream.clone(), elements })
}
#[track_caller]
fn from_host(stream: &Arc<CudaStream>, host: &[T]) -> Result<Self, Error> {
let buffer = Self::new(stream, host.len())?;
let src = host.as_ptr().cast::<c_void>();
// SAFETY: the buffer and `host` both hold buffer.bytes() bytes.
check(unsafe { sys::cuMemcpyHtoD_v2(buffer.ptr, src, buffer.bytes()) })?;
Ok(buffer)
}
}
/// A move: `b` takes the allocation, and the name `a` can no longer be used.
fn move_once(stream: &Arc<CudaStream>, host: &[f32]) -> Result<usize, Error> {
let a = PoolBuffer::from_host(stream, host)?;
let b = a;
Ok(b.len())
}
impl<T> PoolBuffer<T> {
fn len(&self) -> usize {
self.count
}
fn bytes(&self) -> usize {
self.count * size_of::<T>()
}
}
impl<T> Drop for PoolBuffer<T> {
fn drop(&mut self) {
// A drop cannot report an error, so the result is ignored.
// SAFETY: `ptr` came from cuMemAllocAsync, and only this drop frees it.
let _ = unsafe { sys::cuMemFreeAsync(self.ptr, self.stream.cu_stream()) };
}
}
/// The early return of raw.cu with PoolBuffer: both drops run on the return.
fn early_return_pool(
stream: &Arc<CudaStream>,
host: &[f32],
factor: f32,
) -> Result<bool, Error> {
let input = PoolBuffer::from_host(stream, host)?;
let out = PoolBuffer::<f32>::new(stream, input.len())?;
if factor == 0.0 {
return Ok(false);
}
Ok(out.len() == input.len())
}
/// A copy of `host` in device memory from the pool, freed when the buffer is dropped.
fn pool_copy<T: DeviceCopy>(
stream: &Arc<CudaStream>,
host: &[T],
) -> Result<DeviceBuffer<T>, DriverError> {
// SAFETY: the copy below writes every element before anything reads one.
let mut buffer = unsafe { DeviceBuffer::uninitialized_async(stream, host.len())? };
buffer.copy_from_host(stream, host)?;
Ok(buffer)
}
/// The function of raw.cu. Every return, early or not, drops both buffers.
fn scale_on_gpu(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
factor: f32,
) -> Result<Option<Vec<f32>>, Error> {
let input = pool_copy(stream, host)?;
let mut out = pool_copy(stream, host)?;
if factor == 0.0 {
return Ok(None);
}
let blocks = blocks_for(host.len());
let prepared = module.prepare_scale::<f32>(LaunchConfig1D::new(blocks, BLOCK, 0))?;
module.scale(stream, &prepared, factor, &input, &mut out)?;
Ok(Some(out.to_host_vec(stream)?))
}
/// The launch of 2,048 threads per block. The `?` returns before any kernel runs.
fn launch_too_wide(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
) -> Result<(), Error> {
let input = pool_copy(stream, host)?;
let mut out = pool_copy(stream, host)?;
let blocks = (host.len() as u32) / 2048;
let prepared = module.prepare_scale::<f32>(LaunchConfig1D::new(blocks, 2048, 0))?;
module.scale(stream, &prepared, 2.0, &input, &mut out)?;
Ok(())
}
/// The same function with `std::mem::forget`: the only way to skip a drop.
fn forget_on_gpu(stream: &Arc<CudaStream>, host: &[f32]) -> Result<(), DriverError> {
let input = pool_copy(stream, host)?;
std::mem::forget(input);
Ok(())
}
/// Average time of `runs` runs of `launch`, in milliseconds, after 500 ms of warm-up:
/// the clocks of the GPU and of its memory rise under sustained load.
fn time_ms<F>(stream: &CudaStream, runs: u32, mut launch: F) -> Result<f64, Error>
where
F: FnMut() -> Result<(), Error>,
{
let start = Instant::now();
while start.elapsed().as_millis() < 500 {
launch()?;
stream.synchronize()?;
}
let start = Instant::now();
for _ in 0..runs {
launch()?;
}
stream.synchronize()?;
Ok(start.elapsed().as_secs_f64() * 1e3 / runs as f64)
}
/// Time scale::<T> on `data`, print the rate, and check every result.
fn time_scale<T>(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
name: &str,
data: &[T],
factor: T,
) -> Result<bool, Error>
where
T: DeviceCopy + Mul<Output = T> + PartialEq,
{
let input = DeviceBuffer::from_host(stream, data)?;
let mut out = DeviceBuffer::<T>::zeroed(stream, data.len())?;
let blocks = blocks_for(data.len());
let prepared = module.prepare_scale::<T>(LaunchConfig1D::new(blocks, BLOCK, 0))?;
let mut launch = || Ok(module.scale(stream, &prepared, factor, &input, &mut out)?);
let ms = time_ms(stream, 20, &mut launch)?;
let bytes = 2 * data.len() * size_of::<T>();
println!(" {name:<14} {ms:7.2} ms {:6.1} GB/s", bytes as f64 / ms / 1e6);
let result = out.to_host_vec(stream)?;
Ok(result.iter().zip(data).all(|(&y, &x)| y == factor * x))
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let host = vec![1.0f32; N];
let mut passed = true;
println!("ownership");
let before = pool_mib(&ctx)?;
for _ in 0..8 {
scale_on_gpu(&module, &stream, &host, 0.0)?;
}
let lost = pool_mib(&ctx)? - before;
println!(" 8 calls that return early: {lost:.1} MiB lost");
passed &= lost == 0.0;
match launch_too_wide(&module, &stream, &host) {
Ok(()) => passed = false,
Err(error) => println!(" 2048 threads per block returned: {error}"),
}
println!(" after the error: {:.1} MiB in use", pool_mib(&ctx)?);
let result = scale_on_gpu(&module, &stream, &host, 2.0)?.unwrap_or_default();
let correct = result.iter().filter(|&&x| x == 2.0).count();
println!(" copies sized by the type: {correct} of {N} correct");
passed &= correct == N;
for _ in 0..8 {
forget_on_gpu(&stream, &host)?;
}
println!(" 8 calls with mem::forget: {:.1} MiB lost", pool_mib(&ctx)? - before);
println!("1 generic kernel, 3 types, {BIG} values");
let floats: Vec<f32> = (0..BIG).map(|i| (i % 1000) as f32).collect();
let doubles: Vec<f64> = (0..BIG).map(|i| (i % 1000) as f64).collect();
let ints: Vec<i32> = (0..BIG).map(|i| (i % 1000) as i32).collect();
passed &= time_scale(&module, &stream, "scale::<f32>", &floats, 3.0)?;
passed &= time_scale(&module, &stream, "scale::<f64>", &doubles, 3.0)?;
passed &= time_scale(&module, &stream, "scale::<i32>", &ints, 3)?;
println!("1 function on both sides, {N} values in [-1, 1)");
let xs: Vec<f32> = (0..N).map(|i| -1.0 + 2.0 * i as f32 / N as f32).collect();
let x = DeviceBuffer::from_host(&stream, &xs)?;
let mut y = DeviceBuffer::<f32>::zeroed(&stream, N)?;
let config = LaunchConfig1D::new(blocks_for(N), BLOCK, 0);
let prepared = module.prepare_poly(config)?;
module.poly(&stream, &prepared, &x, &mut y)?;
let gpu = y.to_host_vec(&stream)?;
let plain_differ = xs.iter().zip(&gpu).filter(|&(&x, &y)| exp_poly(x) != y).count();
println!(" x * y + z: {plain_differ} of {N} differ from the CPU");
let prepared = module.prepare_poly_fma(config)?;
module.poly_fma(&stream, &prepared, &x, &mut y)?;
let gpu = y.to_host_vec(&stream)?;
let fused_differ = xs.iter().zip(&gpu).filter(|&(&x, &y)| exp_poly_fma(x) != y).count();
println!(" mul_add: {fused_differ} of {N} differ from the CPU");
passed &= fused_differ == 0;
println!("the mistakes of raw.cu, in Rust");
let before = pool_mib(&ctx)?;
for _ in 0..8 {
scale_by_hand(&module, &stream, &host, 0.0)?;
}
let lost = pool_mib(&ctx)? - before;
println!(" 1. 8 calls with ManuallyDrop that return early: {lost:.1} MiB lost");
let correct = copy_count_as_bytes(&module, &stream, &host)?;
println!(" 3. a copy of N bytes, not N floats: {correct} of {N} correct");
println!("PoolBuffer, check and closures");
let before = pool_mib(&ctx)?;
for _ in 0..8 {
early_return_pool(&stream, &host, 0.0)?;
}
let lost = pool_mib(&ctx)? - before;
println!(" 8 calls that return early: {lost:.1} MiB lost");
passed &= lost == 0.0;
let moved = move_once(&stream, &host)?;
let in_use = pool_mib(&ctx)? - before;
println!(" after a move: {moved} values, {in_use:.1} MiB in use");
passed &= moved == N;
if let Err(error) = PoolBuffer::<f32>::new(&stream, 1 << 45) {
println!(" 128 TiB returned: {error}");
}
let factor = 3.0f32;
let triple = move |v: f32| factor * v;
let input = DeviceBuffer::from_host(&stream, &floats)?;
let mut out = DeviceBuffer::<f32>::zeroed(&stream, BIG)?;
let config = LaunchConfig1D::new(blocks_for(BIG), BLOCK, 0);
let prepared = module.prepare_transform_for(&factor, &triple, config)?;
module.transform(&stream, &prepared, triple, &input, &mut out)?;
let result = out.to_host_vec(&stream)?;
let correct = result.iter().zip(&floats).filter(|&(&y, &x)| y == triple(x)).count();
println!(" transform with a closure: {correct} of {BIG} correct");
passed &= correct == BIG;
let count = DeviceBuffer::<u32>::zeroed(&stream, 1)?.cast_elem::<DeviceAtomicU32>();
let config = LaunchConfig1D::new(blocks_for(N), BLOCK, 0);
let prepared = module.prepare_count_above(config)?;
module.count_above(&stream, &prepared, &y, 1.5, &count)?;
let gpu_count = count.cast_elem::<u32>().to_host_vec(&stream)?[0] as usize;
let cpu_count = gpu.iter().filter(|&&v| v > 1.5).count();
println!("slice and DeviceAtomicU32: {gpu_count} values above 1.5, CPU {cpu_count}");
passed &= gpu_count == cpu_count;
if passed {
println!("PASSED");
Ok(())
} else {
Err("FAILED".into())
}
}device_buffer.hpp
// Chapter 10: a check without a macro, and a device allocation that frees itself.
#pragma once
#include <cstddef>
#include <source_location>
#include <stdexcept>
#include <string>
#include <type_traits>
#include <utility>
#include <vector>
#include <cuda/std/span>
#include <cuda_runtime.h>
using Where = std::source_location;
// Throw if a CUDA call failed. The default argument records the caller's file and line.
inline void check(cudaError_t err, Where where = Where::current())
{
if (err == cudaSuccess) {
return;
}
std::string place = std::string(where.file_name()) + ":" + std::to_string(where.line());
throw std::runtime_error(place + ": " + cudaGetErrorString(err));
}
// Bytes in use from the pool that cudaMallocAsync draws on, in MiB.
inline double poolMiB()
{
cudaMemPool_t pool;
check(cudaDeviceGetDefaultMemPool(&pool, 0));
unsigned long long used = 0;
check(cudaMemPoolGetAttribute(pool, cudaMemPoolAttrUsedMemCurrent, &used));
return used / 1048576.0;
}
// `count` values of T in device memory, owned by exactly 1 object.
template <typename T>
class DeviceBuffer {
static_assert(std::is_trivially_copyable_v<T>, "device memory holds plain bytes");
public:
explicit DeviceBuffer(std::size_t count) : count_(count)
{
check(cudaMallocAsync(&data_, bytes(), 0));
}
explicit DeviceBuffer(const std::vector<T>& host) : DeviceBuffer(host.size())
{
check(cudaMemcpy(data_, host.data(), bytes(), cudaMemcpyHostToDevice));
}
~DeviceBuffer()
{
release();
}
DeviceBuffer(const DeviceBuffer&) = delete;
DeviceBuffer& operator=(const DeviceBuffer&) = delete;
DeviceBuffer(DeviceBuffer&& other) noexcept
: data_(std::exchange(other.data_, nullptr)), count_(std::exchange(other.count_, 0))
{
}
DeviceBuffer& operator=(DeviceBuffer&& other) noexcept
{
if (this != &other) {
release();
data_ = std::exchange(other.data_, nullptr);
count_ = std::exchange(other.count_, 0);
}
return *this;
}
T* data() const { return data_; }
std::size_t size() const { return count_; }
std::size_t bytes() const { return count_ * sizeof(T); }
cuda::std::span<const T> view() const { return {data_, count_}; }
cuda::std::span<T> span() { return {data_, count_}; }
std::vector<T> toHost() const
{
std::vector<T> host(count_);
check(cudaMemcpy(host.data(), data_, bytes(), cudaMemcpyDeviceToHost));
return host;
}
private:
void release()
{
if (data_ != nullptr) { // a moved-from buffer owns nothing
cudaFreeAsync(data_, 0);
}
}
T* data_ = nullptr;
std::size_t count_ = 0;
};
raw.cu
// Chapter 10: 3 mistakes that the CUDA C API lets through. Each one runs and does damage.
// Build: nvcc -arch=native raw.cu -o raw
#include <cstdio>
#include <vector>
#include <cuda_runtime.h>
const int N = 1 << 21; // 2,097,152 floats, 8 MiB per buffer
const int CALLS = 8;
__global__ void scale(const float* in, float* out, int n, float factor)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
out[i] = factor * in[i];
}
}
// Bytes in use from the pool that cudaMallocAsync draws on, in MiB.
double poolMiB()
{
    cudaMemPool_t pool;
    cudaDeviceGetDefaultMemPool(&pool, 0);

    unsigned long long used = 0;
    cudaMemPoolGetAttribute(pool, cudaMemPoolAttrUsedMemCurrent, &used);
    return used / 1048576.0;
}
// Mistake 1: the early return skips both frees.
bool scaleOnGpu(const std::vector<float>& host, std::vector<float>& result, float factor)
{
    int n = static_cast<int>(host.size());
    size_t bytes = n * sizeof(float);

    float* in = nullptr;
    float* out = nullptr;
    cudaMallocAsync(&in, bytes, 0);
    cudaMallocAsync(&out, bytes, 0);

    if (factor == 0.0f) {
        return false;                         // nothing to scale
    }

    cudaMemcpy(in, host.data(), bytes, cudaMemcpyHostToDevice);
    scale<<<(n + 255) / 256, 256>>>(in, out, n, factor);
    cudaMemcpy(result.data(), out, bytes, cudaMemcpyDeviceToHost);

    cudaFreeAsync(in, 0);
    cudaFreeAsync(out, 0);
    return true;
}
int main()
{
std::vector<float> host(N, 1.0f);
std::vector<float> result(N, 0.0f);
size_t bytes = N * sizeof(float);
double before = poolMiB();
for (int call = 0; call < CALLS; ++call) {
scaleOnGpu(host, result, 0.0f);
}
double lost = poolMiB() - before;
std::printf("1. %d calls that return early: %.1f MiB lost\n", CALLS, lost);
float* in = nullptr;
float* out = nullptr;
cudaMallocAsync(&in, bytes, 0);
cudaMallocAsync(&out, bytes, 0);
cudaMemcpy(in, host.data(), bytes, cudaMemcpyHostToDevice);
cudaMemset(out, 0, bytes);
// Mistake 2: 2,048 threads per block is over the limit of 1,024. Nothing reports it.
scale<<<N / 2048, 2048>>>(in, out, N, 2.0f);
cudaMemcpy(result.data(), out, bytes, cudaMemcpyDeviceToHost);
std::printf("2. 2048 threads per block: out[0] = %.1f, expected 2.0\n", result[0]);
cudaError_t err = cudaGetLastError();
std::printf(" the error, found only by asking: %s\n", cudaGetErrorString(err));
// Mistake 3: N counts floats, but cudaMemcpy counts bytes.
cudaMemset(in, 0, bytes);
cudaMemcpy(in, host.data(), N, cudaMemcpyHostToDevice);
scale<<<N / 256, 256>>>(in, out, N, 2.0f);
cudaMemcpy(result.data(), out, bytes, cudaMemcpyDeviceToHost);
int correct = 0;
for (float x : result) {
correct += (x == 2.0f);
}
std::printf("3. a copy of N bytes, not N floats: %d of %d correct\n", correct, N);
cudaFreeAsync(in, 0);
cudaFreeAsync(out, 0);
}
modern.cu
// Chapter 10: the work of raw.cu with RAII, templates, span, atomic_ref and concepts.
// Build: nvcc -std=c++20 --extended-lambda -arch=native modern.cu -o modern
#include <chrono>
#include <cmath>
#include <concepts>
#include <cstdio>
#include <cstring>
#include <stdexcept>
#include <vector>
#include <cuda/atomic>
#include "device_buffer.hpp"
constexpr int BLOCK = 256;
static_assert(BLOCK % 32 == 0, "a block is a whole number of warps");
static_assert(BLOCK <= 1024, "a block holds at most 1,024 threads");
constexpr int blocksFor(std::size_t n)
{
return static_cast<int>((n + BLOCK - 1) / BLOCK);
}
static_assert(blocksFor(1000) == 4);
const int N = 1 << 21; // 2,097,152 values, as in raw.cu
const int BIG = 1 << 24; // 16,777,216 values for timing
template <typename T>
concept Number = std::integral<T> || std::floating_point<T>;
template <typename F, typename T>
concept UnaryOp = std::invocable<F, T> && std::same_as<std::invoke_result_t<F, T>, T>;
// out[i] = f(in[i]), for any number type T and any operation f from T to T.
template <Number T, UnaryOp<T> F>
__global__ void transform(cuda::std::span<const T> in, cuda::std::span<T> out, F f)
{
std::size_t i = blockIdx.x * std::size_t(blockDim.x) + threadIdx.x;
if (i < in.size()) {
out[i] = f(in[i]);
}
}
template <Number T>
struct Scale {
T factor;
__host__ __device__ T operator()(T x) const { return factor * x; }
};
// The C-style kernel of raw.cu, kept to compare its speed.
__global__ void scaleRaw(const float* in, float* out, int n, float factor)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
out[i] = factor * in[i];
}
}
// 1 + x + x^2/2 + x^3/6, the first 4 terms of e^x, by Horner's rule.
__host__ __device__ float expPoly(float x)
{
return 1.0f + x * (1.0f + x * (0.5f + x * (1.0f / 6.0f)));
}
// The same polynomial, with every multiply-add rounded once, on both sides.
__host__ __device__ float expPolyFma(float x)
{
float p = fmaf(x, 1.0f / 6.0f, 0.5f);
p = fmaf(x, p, 1.0f);
return fmaf(x, p, 1.0f);
}
// Count the values above a threshold. atomic_ref makes an ordinary int atomic.
template <Number T>
__global__ void countAbove(cuda::std::span<const T> in, T threshold, int* count)
{
std::size_t i = blockIdx.x * std::size_t(blockDim.x) + threadIdx.x;
if (i < in.size() && in[i] > threshold) {
cuda::atomic_ref<int, cuda::thread_scope_device> total(*count);
total.fetch_add(1, cuda::memory_order_relaxed);
}
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// Average time of `runs` runs of `launch`, in milliseconds, after 500 ms of warm-up:
// the clocks of the GPU and of its memory rise under sustained load.
template <typename F>
double timeKernel(F launch, int runs)
{
double start = nowMs();
while (nowMs() - start < 500.0) {
launch();
check(cudaDeviceSynchronize());
}
double t0 = nowMs();
for (int r = 0; r < runs; ++r) {
launch();
}
check(cudaGetLastError());
check(cudaDeviceSynchronize());
return (nowMs() - t0) / runs;
}
// The function of raw.cu: the early return frees both buffers.
bool scaleOnGpu(const std::vector<float>& host, std::vector<float>& result, float factor)
{
    DeviceBuffer<float> in(host);
    DeviceBuffer<float> out(host.size());

    if (factor == 0.0f) {
        return false;
    }

    transform<<<blocksFor(in.size()), BLOCK>>>(in.view(), out.span(), Scale{factor});
    check(cudaGetLastError());
    result = out.toHost();
    return true;
}

void launchTooWide(const std::vector<float>& host)
{
    DeviceBuffer<float> in(host);
    DeviceBuffer<float> out(host.size());

    transform<<<N / 2048, 2048>>>(in.view(), out.span(), Scale{2.0f});
    check(cudaGetLastError());
}
// The only way to skip a destructor: a buffer created with new and never deleted.
void leakOnGpu(const std::vector<float>& host)
{
new DeviceBuffer<float>(host);
}
// Time transform<T> on BIG values; return true if every result is right.
template <Number T>
bool timeType(const char* name, int runs)
{
std::vector<T> host(BIG);
for (int i = 0; i < BIG; ++i) {
host[i] = static_cast<T>(i % 1000);
}
DeviceBuffer<T> in(host);
DeviceBuffer<T> out(host.size());
Scale<T> triple{3};
auto launch = [&] {
transform<<<blocksFor(BIG), BLOCK>>>(in.view(), out.span(), triple);
};
double ms = timeKernel(launch, runs);
double gbs = 2.0 * BIG * sizeof(T) / ms / 1e6;
std::printf(" %-22s %7.2f ms %6.1f GB/s\n", name, ms, gbs);
std::vector<T> result = out.toHost();
for (int i = 0; i < BIG; ++i) {
if (result[i] != triple(host[i])) {
return false;
}
}
return true;
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %d SMs\n", prop.name, prop.multiProcessorCount);
std::vector<float> host(N, 1.0f);
std::vector<float> result(N, 0.0f);
bool passed = true;
std::printf("ownership\n");
double before = poolMiB();
for (int call = 0; call < 8; ++call) {
scaleOnGpu(host, result, 0.0f);
}
double lost = poolMiB() - before;
std::printf(" 8 calls that return early: %.1f MiB lost\n", lost);
passed = passed && lost == 0.0;
try {
launchTooWide(host);
passed = false;
} catch (const std::runtime_error& e) {
std::printf(" 2048 threads per block threw: %s\n", e.what());
}
std::printf(" after the exception: %.1f MiB in use\n", poolMiB());
scaleOnGpu(host, result, 2.0f);
int correct = 0;
for (float x : result) {
correct += (x == 2.0f);
}
std::printf(" copies sized by the type: %d of %d correct\n", correct, N);
passed = passed && correct == N;
for (int call = 0; call < 8; ++call) {
leakOnGpu(host);
}
double leaked = poolMiB() - before;
std::printf(" 8 calls with new and no delete: %.1f MiB lost\n", leaked);
std::printf("1 template, 3 types, %d values\n", BIG);
{
DeviceBuffer<float> in(std::vector<float>(BIG, 1.0f));
DeviceBuffer<float> out(BIG);
auto launch = [&] {
scaleRaw<<<blocksFor(BIG), BLOCK>>>(in.data(), out.data(), BIG, 3.0f);
};
double ms = timeKernel(launch, 20);
double gbs = 2.0 * BIG * sizeof(float) / ms / 1e6;
std::printf(" %-22s %7.2f ms %6.1f GB/s\n", "raw pointers, float", ms, gbs);
}
passed = timeType<float>("transform<float>", 20) && passed;
passed = timeType<double>("transform<double>", 20) && passed;
passed = timeType<int>("transform<int>", 20) && passed;
std::printf("1 function on both sides, %d values in [-1, 1)\n", N);
std::vector<float> xs(N);
for (int i = 0; i < N; ++i) {
xs[i] = -1.0f + 2.0f * i / N;
}
DeviceBuffer<float> x(xs);
DeviceBuffer<float> y(N);
auto plain = [] __host__ __device__ (float v) { return expPoly(v); };
auto fused = [] __host__ __device__ (float v) { return expPolyFma(v); };
transform<<<blocksFor(N), BLOCK>>>(x.view(), y.span(), plain);
check(cudaGetLastError());
std::vector<float> gpuPlain = y.toHost();
transform<<<blocksFor(N), BLOCK>>>(x.view(), y.span(), fused);
check(cudaGetLastError());
std::vector<float> gpuFused = y.toHost();
int plainDiffer = 0;
int fusedDiffer = 0;
for (int i = 0; i < N; ++i) {
float cpuPlain = plain(xs[i]);
float cpuFused = fused(xs[i]);
plainDiffer += std::memcmp(&cpuPlain, &gpuPlain[i], sizeof(float)) != 0;
fusedDiffer += std::memcmp(&cpuFused, &gpuFused[i], sizeof(float)) != 0;
}
std::printf(" x * y + z: %d of %d differ from the CPU\n", plainDiffer, N);
std::printf(" fmaf: %d of %d differ from the CPU\n", fusedDiffer, N);
passed = passed && fusedDiffer == 0;
DeviceBuffer<int> count(1);
check(cudaMemset(count.data(), 0, sizeof(int)));
countAbove<<<blocksFor(N), BLOCK>>>(y.view(), 1.5f, count.data());
check(cudaGetLastError());
int gpuCount = count.toHost()[0];
int cpuCount = 0;
for (float v : gpuFused) {
cpuCount += (v > 1.5f);
}
std::printf("span and atomic_ref: %d values above 1.5, CPU %d\n", gpuCount, cpuCount);
passed = passed && gpuCount == cpuCount;
std::printf(passed ? "PASSED\n" : "FAILED\n");
return passed ? 0 : 1;
}
Common mistakes
- Copying an owner. A struct that holds a raw device pointer and is copied leads to 2 frees
of the same memory. Delete the copy operations and move with
std::move. - Throwing from a destructor. A destructor can run while an exception is traveling, and a second exception ends the program. Free the memory and ignore the result there.
- Passing a host lambda to a kernel. Mark the lambda
__device__or__host__ __device__and compile with--extended-lambda. - Capturing by reference in a device lambda. The capture passes a host address to the GPU. Capture by value, and only trivially copyable values.
- Comparing CPU and GPU results bit for bit with plain
a * b + c. The GPU fuses the expression into an FMA. Writefmafwhere the bits must agree, or compare with a tolerance. - Using a wider thread scope than necessary.
thread_scope_systemcosts more thanthread_scope_device. Use the narrowest scope that contains every thread that accesses the value. - Measuring without a warm-up. With 0.3 s of warm-up, the kernels of this chapter ran at 33 to 48 GB/s; with 500 ms before each measurement, at 70 to 90 GB/s. The clock rates of a GPU and of its memory rise only under sustained load.
Summary
- The CUDA C API leaves 3 responsibilities at every call site. When they were neglected, 8 early returns leaked 128 MiB, a kernel was skipped without a message, and only 1 float in 4 was copied.
- RAII acquires a resource in a constructor and releases it in the destructor, which the compiler
runs on every path out of a scope. With
DeviceBuffer<T>, the early returns leaked 0.0 MiB. - Each allocation has 1 owner: copies are deleted, and a move transfers the pointer and leaves
nullptrbehind. check()withstd::source_locationnames the failed line without a macro, and its exception frees every buffer in the scopes it leaves.- Template kernels produce 1 kernel per type at the speed of a hand-written kernel: 74.6 GB/s against 74.5 GB/s.
__host__ __device__functions are compiled for both processors. The GPU’s FMA made 585,903 of 2,097,152 results differ in the last bits untilfmafmade both sides round once.constexpr,static_assert, spans,cuda::atomic_refwith a scope, and concepts each turn a rule into something that the compiler checks.- Rust provides each of these as part of the language:
Drop, moves,Resultand?, generics with trait bounds, and constant assertions. Leaking memory requires an explicitmem::forget.
In Chapter 11, we find these techniques in NVIDIA’s libraries. Thrust’s device_vector is a
DeviceBuffer with algorithms, CUB is a library of template building blocks, and cuBLAS
provides the matrix product of Chapter 9.
Exercises
- Remove the
= deletefrom the copy constructor ofDeviceBuffer, writeb = a, and run the program. What happens at the end of the scope, and why? - Add a
release()that frees early and leaves the object empty, and use it in a loop that allocates a large buffer in each iteration. Show withpoolMiB()that the peak stays at 1 buffer. - Write
DeviceBuffer<std::string> s(4);and read the error. Which property ofstd::stringdoes it reject? - Write a
__host__ __device__functionlerp(a, b, t) = a + t × (b − a), test it differentially on 1,048,576 values, and count the differences. Rewrite it withfmafso that none remain. - Instantiate
transformforunsigned charand measure it. Explain the rate from the number of bytes each thread moves. - Change
countAbovetothread_scope_blockand run it. Is the count still correct on your GPU? Is it guaranteed to be? - Write a concept
Floatingthat accepts onlyfloatanddouble, and use it on a kernel that callssqrt. What error doestransform<int>give now? - In Rust, replace
pool_copywithDeviceBuffer::from_hostinscale_on_gpu. Does the pool still count the buffers? Why?
Sources and further reading
- NVIDIA, CUDA C++ Programming Guide, “Function Execution Space Specifiers”, “Extended Lambdas” and “Stream Ordered Memory Allocator”: https://docs.nvidia.com/cuda/cuda-c-programming-guide/
- NVIDIA, libcu++ documentation,
cuda::std::span,cuda::atomic_refand thread scopes: https://nvidia.github.io/cccl/libcudacxx/ - NVIDIA, CUDA Floating Point and IEEE 754, on fused multiply-add and differences between CPU and GPU results: https://docs.nvidia.com/cuda/floating-point/
- B. Stroustrup, The C++ Programming Language, 4th ed., Addison-Wesley, 2013, chapters on resource management, copy and move, and templates.
- cppreference, “RAII”, “The rule of three/five/zero”, “std::source_location”, “Constraints and concepts”: https://en.cppreference.com/
- S. Klabnik and C. Nichols, The Rust Programming Language, chapters “Understanding Ownership” and “Generic Types, Traits, and Lifetimes”: https://doc.rust-lang.org/book/
Chapter 11: The Library Ecosystem - Thrust, CUB & cuBLAS
In Chapters 8 and 9, we wrote a sum, a scan, a histogram and a matrix product as our own kernels and measured each version. The CUDA toolkit already contains tuned implementations of all of these operations. A library is a collection of routines written, tested and tuned by other programmers, which a program calls instead of implementing the operation itself. NVIDIA ships several libraries with every toolkit and tunes them for each new GPU generation.
In this chapter, we place each library next to the kernel it replaces and measure both on the
same GPU. The measurements come from a Jetson Orin NX, an integrated GPU with 8 SMs (streaming
multiprocessors), 102 GB/s of memory bandwidth and 2.4 TFLOP/s of FP32 throughput, with all runs
made on the same day. FP32 is the 32-bit floating-point format of the C++ type float, and
1 TFLOP/s is 1012 floating-point operations per second. We will use them to answer 2
practical questions: when a library is as fast as a hand-written kernel, and what a library call
costs beyond the kernels it launches. We will find that on large inputs the libraries match or
exceed our kernels, while on small inputs most of the time of a convenient library call goes to
memory allocation and synchronization rather than to computation. Synchronization here means
that the host stops and waits until the GPU has finished the work submitted so far.
This chapter covers
- the libraries Thrust, CUB, cuBLAS, cuFFT and cuRAND, and the kernels of earlier chapters that each one replaces
- reductions with Thrust, and fusing 2 passes into 1 with
transform_reduce - the single-pass scan, which moves half the bytes of the scan in Chapter 8
- radix sort, built from a histogram and a scan
- the temporary storage that a library call needs, and the cost of allocating it on every call
- CUB’s block-level primitives inside a custom kernel, and their counterparts in cuda-oxide
- calling cuBLAS with row-major matrices
- TF32 tensor cores: speed and accuracy
- choosing between a library and a custom kernel
The code of the chapter is in
code/ch11_libraries/
for C++ and in
code/oxide/ch11_blocks/
for Rust.
11.1 Libraries in the CUDA toolkit
11.1.1 The libraries and what they replace
The 5 libraries of this chapter cover most of the algorithms of Part III, as well as a few
that we do not implement by hand. All of them are installed with the CUDA toolkit.
Before we look at the table below, we need 4 terms. A reduction combines all the elements
of an array into 1 value with an operation such as addition; the sum of Chapter 8 is a
reduction. GEMM (general matrix multiply) is the matrix product \(C = AB\) of Chapter 9,
and SGEMM is its single-precision version, on floats. Temporary storage, also called
scratch memory, is device memory that an algorithm needs only while it runs. For example, a
sum of 1,024 blocks writes 1 partial sum per block, 1,024 floats or 4 KiB, which the final step
adds and which are not needed afterward. A header is a source file that a program includes
with #include, and a link flag such as -lcublas tells the linker to add a compiled
library file to the executable.
| Library | What it provides | Replaces | Header, link flag |
|---|---|---|---|
| Thrust | whole-array algorithms called from the host: reduce, transform, scan, sort | Chapter 8’s sum and scan | <thrust/...>, none |
| CUB | the same algorithms with temporary storage managed by the caller, and primitives for use inside a kernel | Chapter 8’s block sum and block scan | <cub/cub.cuh>, none |
| cuBLAS | dense linear algebra: SGEMM, matrix-vector products, dot products | Chapter 9’s SGEMM | <cublas_v2.h>, -lcublas |
| cuFFT | fast Fourier transforms | not implemented in this book | <cufft.h>, -lcufft |
| cuRAND | random numbers on the GPU | not implemented in this book | <curand.h>, -lcurand |
Thrust and CUB consist entirely of C++ templates (Chapter 10) in header files. They are compiled
into the program together with the rest of its code and therefore need no link flag. Both belong
to the CUDA C++ Core Libraries (CCCL), together with libcu++, which provides the
cuda::std:: versions of the C++ standard library that we use below. The CCCL version is tied
to the toolkit: CUDA 12.6 ships CCCL 2.5, and CUDA 13.2 ships CCCL 3.2. cuBLAS, cuFFT and
cuRAND, on the other hand, are compiled libraries and must be linked with a flag.
We describe each library briefly before we arrange them. Thrust is a library of
algorithms on whole arrays, such as sum, sort and scan, that a host program calls in 1 line,
in the manner of the C++ standard library; Thrust launches the kernels itself. CUB (CUDA
UnBound) provides the same algorithms with more control left to the caller, and also provides
building blocks, such as the sum of the values of 1 block, that a programmer calls from inside
a kernel of their own. cuBLAS is NVIDIA’s implementation of the standard routines of linear
algebra, among them GEMM. For example, a sum of 1,000,000 floats is 1 call of thrust::reduce,
2 calls of cub::DeviceReduce::Sum, or 1 kernel of our own in which each block calls
cub::BlockReduce and writes 1 partial sum.
Fig. 11.1 arranges the libraries by where they are called from and by who manages the memory they use.
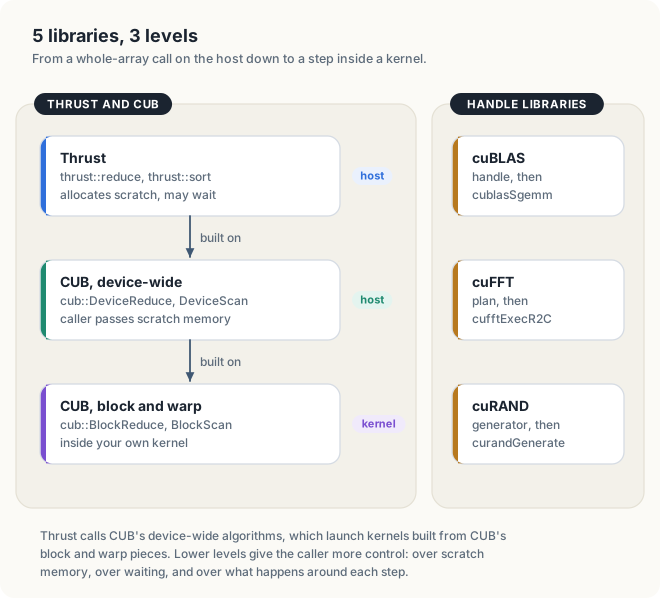
The 3 levels trade convenience for control. A Thrust call does everything for the programmer. It allocates its temporary storage, launches its kernels and, in the case of a reduction, returns the result to the host. A CUB device-wide call performs the same work but leaves 2 decisions to the caller: where the temporary storage comes from, and when the host waits for the result. A CUB block-level call performs only 1 step of an algorithm, inside a kernel that the programmer writes. Since Thrust is built on CUB, the kernels launched at the top 2 levels are the same. In Sections 11.2 and 11.3, we measure what the difference in convenience costs.
11.1.2 Advantages and limits of a library
A library has 3 advantages over a kernel written for a single program. First, its authors select a different kernel for each GPU generation, the family of GPUs that share 1 design, such as the GPUs of compute capability 8.x, with block sizes, load widths and algorithms tuned on that hardware. Second, it can use algorithms whose implementation effort a single program could not justify. The scan of Section 11.2.3, for example, relies on a protocol between thread blocks that we did not attempt in Chapter 8. Third, it is tested on every release against reference results and on a wide range of input shapes.
A library also has a limitation, which we measure in this chapter. It does not know the context in which it is called. It cannot know that the same temporary storage could serve 1,000 consecutive calls, or that the result will be used by another kernel on the GPU rather than by the host. The programmer knows these facts and can pass them to the library by calling it at one of the lower levels of Fig. 11.1.
NOTE: cuda-oxide, the Rust compiler used in this book, has no bindings to Thrust, CUB,
cuBLAS, cuFFT or cuRAND at revision b7fe543. A Rust program can call these C libraries
through Rust’s foreign function interface (FFI), the mechanism by which Rust code declares
and calls functions written in C. We use it for NVRTC in Chapter 12; its use for these
libraries is beyond the scope of this chapter.
cuda-oxide does provide its own block-level primitives for use inside a kernel, the
counterparts of CUB’s lowest level, and we measure them in Section 11.3.2.
11.2 Thrust: whole-array algorithms
11.2.1 Reduction with thrust::reduce
Thrust’s algorithms have the names and parameters of the algorithms in the C++ standard library.
A range of elements is given by 2 positions, first and last. Such a position is called an
iterator: an object that marks 1 element of a sequence and can be advanced to the next. A
raw pointer is the simplest iterator. The range is half-open: it contains first and every
element up to, but not including, last. For example, with in pointing to an array of 8
floats, the range in to in + 8 covers elements 0 to 7, and in + 8 itself marks the
position just past the end. The first argument of the call is an execution policy, which
specifies where the algorithm runs. The policy thrust::device runs the algorithm on the GPU,
on data in device memory.
thrust::reduce(policy, first, last, initial value)
→ initial value + every element in [first, last), combined in any order
The phrase “in any order” matters, and a small example shows why. Take the 8 values 3, 1, 2, 0, 1, 2, 0, 1. A sequential loop adds them from left to right: 3, 4, 6, 6, 7, 9, 9, 10. A tree reduction, as in the kernels of Chapter 8, adds neighboring pairs in rounds. Round 1 gives 3 + 1 = 4, 2 + 0 = 2, 1 + 2 = 3 and 0 + 1 = 1; round 2 gives 4 + 2 = 6 and 3 + 1 = 4; round 3 gives 6 + 4 = 10. Both orders reach 10, but the tree takes 3 rounds instead of 7 steps, and the 4 additions of round 1 can run at the same time on 4 threads. With integers the order makes no difference. With floats, every addition rounds, and different orders round at different places.
Key observation A parallel reduction adds the same elements in a different order from a sequential loop. With floats, the 2 results can differ in their last digits, although neither is less accurate.
Like the kernels of Chapter 8, thrust::reduce adds the elements in a tree. The order of the
additions therefore differs from that of a sequential loop, and the result is rounded
differently, though not less accurately. Listing 11.1 times thrust::reduce on the
67,108,864 floats (256 MiB) of Chapter 8, next to the fastest kernel of that chapter.
Listing 11.1 A sum with thrust::reduce, timed. code/ch11_libraries/reduce_scan.cu
fn main() -> Result<(), Error> {
// ...
let ms = time_ms(&stream, || {
module.sum_blocks(&stream, &blocks.0, &input, &mut partial)?;
Ok(module.sum_blocks(&stream, &blocks.1, &partial, &mut total)?)
})?;
let rate = gb / ms * 1e3;
let sum_blocks = total.to_host_vec(&stream)?[0];
println!(" block_reduce {ms:6.2} ms {rate:6.1} GB/s sum {sum_blocks:.1}");
// ...
}bool sums(const float* in, float* partial, float* total, int n, double exact)
{
// ...
float t = 0.0f;
auto thrustSum = [&] { t = thrust::reduce(thrust::device, in, in + n, 0.0f); };
ms = timeMs(thrustSum);
ok &= report("thrust::reduce", ms, bytes, t, exact);
// ...
}
cuda-oxide has no call that sums a whole array, so the Rust tab times the 2 launches of
block_reduce from Section 11.3.2.
Note that thrust::reduce returns the sum to the host as a float. The call therefore also
waits for the GPU to finish and copies 4 bytes back to the host. The program compares every
sum with a sum computed in double precision and prints PASSED when all of them agree to 1 part
in 100,000.
$ ./reduce_scan
GPU: Orin, 8 SMs, L2 cache 2 MiB
sum of 67108864 floats (256 MiB), average of 20 runs
Chapter 8, float4 + shuffles 2.87 ms 93.4 GB/s sum 33557628.0
same, cub::BlockReduce 2.90 ms 92.5 GB/s sum 33557624.0
cub::DeviceReduce::Sum 2.92 ms 91.8 GB/s sum 33557628.0
(CUB asked for 1279 bytes of temporary storage)
thrust::reduce 2.89 ms 93.0 GB/s sum 33557628.0
The 4 implementations ran within 2% of each other, at 91.8 to 93.4 GB/s, which is 90% to 92% of the GPU’s 102 GB/s. Recall from Chapter 8 that this is the limit for a sum: the kernel reads each byte once and performs 1 addition for every 4 bytes, so its speed is set by the memory. A kernel is said to be memory-bound if its performance is limited by the memory bandwidth of the hardware, and no library can read data faster than the memory delivers it. The sums differ in their last digits because each implementation adds the elements in a different order. All of them are within 7 of the exact value 33,557,630.3, a relative error of 2 × 10⁻⁷. The times varied by up to 20% across 3 runs, so a difference of a few percent between the 4 lines is not significant.
11.2.2 Fusing transform and reduce
The sum of squares \(\sum_i x_i^2\) can be written with 2 Thrust calls.
thrust::transform squares every element and writes the squares to a second array, and
thrust::reduce then adds the elements of the second array. Let us count the memory traffic
for the 4 floats 1, 2, 3, 4, which occupy 16 bytes. The first call reads the 16 bytes and
writes the squares 1, 4, 9, 16 into a second array of 16 bytes. The second call reads those 16
bytes again and adds them to 30. In all, 48 bytes cross the memory bus. A single loop could
instead read 1, square it, add it to a running total, and go on to 2, so that each square exists
only in a register, the storage of 1 thread inside the SM, and never reaches memory. The
same total 30 then costs 16 bytes of traffic.
Definition 11.1 Pass and fusion. A pass is 1 traversal of an array in memory. Fusion combines several passes into 1, so that each intermediate value is passed on in a register instead of being written to memory and read back.
Example. thrust::transform followed by thrust::reduce makes 2 passes over the sum of
squares; thrust::transform_reduce makes 1, squaring each element as it reads it and adding the
square immediately.
The benefit of fusion follows from the number of bytes each version moves. For 256 MiB of
floats, transform reads 256 MiB and writes 256 MiB of squares, and reduce reads the 256
MiB of squares again, for a total of 768 MiB, 3 times the input. transform_reduce reads the
input once, 256 MiB. At the 92 GB/s measured in Section 11.2.1, 768 MiB (805 MB) take about
8.8 ms and 256 MiB (268 MB) take about 2.9 ms.
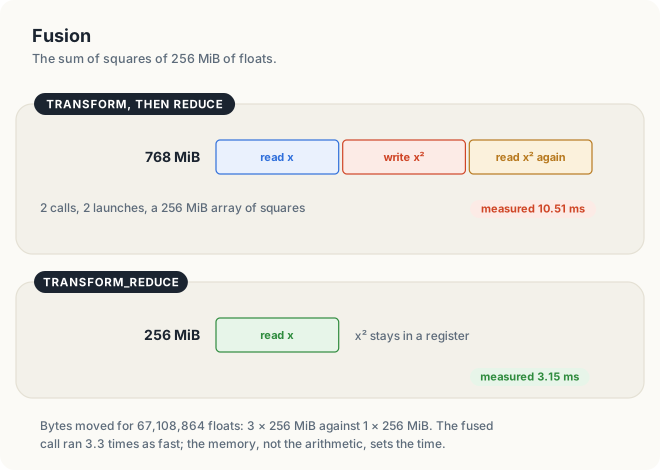
Thrust takes the operation to apply to each element as a functor, an object that can be
called like a function, as the function objects of Chapter 10 are. An object sq of a struct
whose operator() returns x * x gives sq(3.0f) = 9.0. In Listing 11.2, the functor Square
is declared __host__ __device__ so that it is compiled for the GPU, and
cuda::std::plus<float> is the addition of the standard library, in the cuda::std version
that can be called on both the host and the device.
Listing 11.2 The sum of squares in 2 passes and in 1.
mod kernels {
// ...
/// out[i] = f(input[i]), 1 element per thread: the work of thrust::transform.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn map<F>(f: F, input: &[f32], mut out: DisjointSlice<f32>)
where
F: Fn(f32) -> f32 + Copy,
{
let idx = thread::index_1d();
let i = idx.get();
if let Some(slot) = out.get_mut(idx) {
*slot = f(input[i]);
}
}
/// 1 partial sum of f(input[i]) per block, each f(x) kept in a register: the work
/// of thrust::transform_reduce.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn map_sum<F>(f: F, input: &[f32], mut partial: DisjointSlice<f32>)
where
F: Fn(f32) -> f32 + Copy,
{
static mut WARPS: SharedArray<f32, 8> = SharedArray::UNINIT;
let stride = (thread::gridDim_x() * BLOCK) as usize;
let block = this_thread_block();
let mut sum = 0.0;
let mut i = thread::index_1d().get();
while i < input.len() {
sum += f(input[i]);
i += stride;
}
sum = block_reduce::<f32, Sum, 8>(&block, sum, &raw mut WARPS);
if thread::threadIdx_x() == 0 {
let b = thread::blockIdx_x() as usize;
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(b) = sum };
}
}
}
/// The sum of squares of 64 Mi floats in 2 passes and in 1.
fn sums_of_squares(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
values: &[f32],
) -> Result<bool, Error> {
let n = values.len();
let exact: f64 = values.iter().map(|&v| v as f64 * v as f64).sum();
let input = DeviceBuffer::from_host(stream, values)?;
let mut squares = DeviceBuffer::<f32>::zeroed(stream, n)?;
let mut partial = DeviceBuffer::<f32>::zeroed(stream, GRID as usize)?;
let mut total = DeviceBuffer::<f32>::zeroed(stream, 1)?;
let each = module.prepare_map(LaunchConfig1D::new(n as u32 / BLOCK, BLOCK, 0))?;
let grid = module.prepare_map_sum(LaunchConfig1D::new(GRID, BLOCK, 0))?;
let fused = module.prepare_map_sum(LaunchConfig1D::new(GRID, BLOCK, 0))?;
let one = module.prepare_map_sum(LaunchConfig1D::new(1, BLOCK, 0))?;
let square = |v: f32| v * v;
let same = |v: f32| v;
let gb = (n * 4) as f64 / 1e9;
println!("sum of squares, GB/s of input read");
let ms = time_ms(stream, || {
module.map(stream, &each, square, &input, &mut squares)?;
module.map_sum(stream, &grid, same, &squares, &mut partial)?;
Ok(module.map_sum(stream, &one, same, &partial, &mut total)?)
})?;
let two_passes = total.to_host_vec(stream)?[0];
let rate = gb / ms * 1e3;
println!(" map, then map_sum {ms:6.2} ms {rate:6.1} GB/s sum {two_passes:.1}");
let ms = time_ms(stream, || {
module.map_sum(stream, &fused, square, &input, &mut partial)?;
Ok(module.map_sum(stream, &one, same, &partial, &mut total)?)
})?;
let one_pass = total.to_host_vec(stream)?[0];
let rate = gb / ms * 1e3;
println!(" map_sum, fused {ms:6.2} ms {rate:6.1} GB/s sum {one_pass:.1}");
println!(" exact (f64) sum {exact:.1}");
let close = |s: f32| (s as f64 - exact).abs() < 1e-5 * exact;
Ok(close(two_passes) && close(one_pass))
}struct Square {
__host__ __device__ float operator()(float v) const { return v * v; }
};
bool sumsOfSquares(const float* in, float* squares, int n, double exact)
{
double bytes = n * 4.0;
Square square;
cuda::std::plus<float> plus;
std::printf("sum of squares, GB/s of input read\n");
float t = 0.0f;
auto twoPasses = [&] {
thrust::transform(thrust::device, in, in + n, squares, square);
t = thrust::reduce(thrust::device, squares, squares + n, 0.0f);
};
double ms = timeMs(twoPasses);
bool ok = report("transform, then reduce", ms, bytes, t, exact);
auto fused = [&] {
t = thrust::transform_reduce(thrust::device, in, in + n, square, 0.0f, plus);
};
ms = timeMs(fused);
ok &= report("transform_reduce", ms, bytes, t, exact);
return ok;
}
In the Rust tab, the generic kernels map and map_sum take the closure square in the role
of the functor Square.
sum of squares, GB/s of input read
transform, then reduce 10.51 ms 25.5 GB/s sum 22372548.0
transform_reduce 3.15 ms 85.3 GB/s sum 22372548.0
The fused version ran 3.3 times as fast, close to the factor of 3 predicted from the bytes moved. The remainder is accounted for by the second kernel launch and the allocation of the intermediate array in the 2-pass version. Note that the GB/s column counts only the 256 MiB of input. The 2-pass version therefore shows a third of the memory bandwidth, although the memory was as busy as in the fused version.
A chain of library calls writes every intermediate result to memory and reads it back. For memory-bound work, fusing the chain into a single call divides the time by the number of passes saved.
11.2.3 Single-pass scan
A scan, or prefix sum, replaces each element of an array by the running total up to that element. An inclusive scan includes the element itself in its total, whereas an exclusive scan stops immediately before it and therefore starts at 0. For the values 3, 1, 2, 0, the 2 scans are:
| i | 0 | 1 | 2 | 3 |
|---|---|---|---|---|
| value | 3 | 1 | 2 | 0 |
| inclusive scan | 3 | 4 | 6 | 6 |
| exclusive scan | 0 | 3 | 4 | 6 |
The exclusive scan is the inclusive scan shifted right by 1 position. Element \(i\) of the exclusive scan is the number of items that come before position \(i\), and we use exactly this property in Section 11.2.4.
Definition 11.2 Scan. The inclusive scan of \(x_0, x_1, \dots, x_{n-1}\) is the array \(y\) with \(y_i = x_0 + x_1 + \dots + x_i\). The exclusive scan is the array \(z\) with \(z_0 = 0\) and \(z_i = x_0 + \dots + x_{i-1}\).
Example. For 3, 1, 2, 0, element 2 of the inclusive scan is 3 + 1 + 2 = 6, and element 2 of the exclusive scan is 3 + 1 = 4.
The scan of Chapter 8 made 3 passes. Each block scanned its 1,024 values and wrote them out, a second kernel scanned the block totals, and a third kernel read every value again to add the offset of its block. CUB, which Thrust calls internally, performs the scan in a single pass with a method called decoupled look-back.
To see how 1 pass can suffice, consider 4 blocks whose values add up to the block totals 6, 10, 4 and 8. Block 2 needs to know the sum of everything before it, 6 + 10 = 16, before it can write its first output. In the method of Chapter 8, a separate kernel computed 16 after every block had finished. In decoupled look-back, each block keeps a small record in global memory, a flag with 2 fields: a status and a number. The status is aggregate when the number is the block’s own total, and prefix when the number is the running total up to and including that block.
Let us follow block 2. It scans its own values in registers, finds its total 4, and publishes aggregate 4. It then looks at the flag of block 1, the block to its left. Suppose block 1 has so far published only aggregate 10. Block 2 adds 10 and looks one block further left, at block 0, which has published prefix 6. Block 2 adds 6, and the sum before it is 10 + 6 = 16. It publishes prefix 16 + 4 = 20 for the blocks to its right, adds 16 to each of its scanned values, and writes them out once, in their final form. The search to the left stops at the first prefix it finds, so it is usually short.
Key observation A block needs only the total of the elements before it, not the elements themselves. Blocks therefore wait for each other only on a few bytes of flags, never on the data, and every value is read once and written once.
The saving can again be counted in bytes. For 64 Mi values of 4 bytes (256 MiB), the first kernel of Chapter 8 reads 256 MiB and writes 256 MiB, and the third kernel reads and writes them again; the block totals are 1,024 times smaller and add little. The total is 1,024 MiB. Decoupled look-back reads 256 MiB and writes 256 MiB, a total of 512 MiB. Measured on the same day, the scan of Chapter 8 took 12.49 ms, which corresponds to 1,074 MB / 12.49 ms = 86 GB/s of actual memory traffic, although its program reports 43.0 GB/s because it counts only the 512 MiB that a scan must move.
Listing 11.3 An inclusive scan with Thrust, an exclusive scan with CUB.
fn main() -> Result<(), Error> {
// ...
// 2. Each block of 256 values 0 to 3, scanned with block_scan.
let counts: Vec<u32> = random(n, 2).iter().map(|&r| r >> 30).collect();
let input = DeviceBuffer::from_host(&stream, &counts)?;
let mut out = DeviceBuffer::<u32>::zeroed(&stream, n)?;
let config = LaunchConfig1D::new((n as u32).div_ceil(BLOCK), BLOCK, 0);
let scan = module.prepare_scan_blocks(config)?;
module.scan_blocks(&stream, &scan, &input, &mut out)?;
// ...
}bool scans(int n)
{
// ...
auto thrustScan = [&] { thrust::inclusive_scan(thrust::device, in, in + n, out); };
double ms = timeMs(thrustScan);
check(cudaMemcpy(result.data(), out, n * sizeof(unsigned), cudaMemcpyDeviceToHost));
bool ok = result == inclusive;
std::printf(" thrust::inclusive_scan %6.2f ms", ms);
std::printf(" %6.1f GB/s", bytes / ms / 1e6);
std::printf(" last %u correct: %s\n", result[n - 1], ok ? "yes" : "no");
size_t tempBytes = 0;
cub::DeviceScan::ExclusiveSum(nullptr, tempBytes, in, out, n);
void* temp;
check(cudaMalloc(&temp, tempBytes));
auto cubScan = [&] { cub::DeviceScan::ExclusiveSum(temp, tempBytes, in, out, n); };
ms = timeMs(cubScan);
// ...
}
cuda-oxide has no scan of a whole array; the Rust tab scans each block of 256 values with
block_scan, the kernel of Listing 11.8.
scan of 67108864 values 0 to 3, average of 20 runs
thrust::inclusive_scan 7.88 ms 68.2 GB/s last 100652862 correct: yes
cub::DeviceScan::ExclusiveSum 7.23 ms 74.3 GB/s last 100652860 correct: yes
Both lines count 512 MiB, the bytes a scan must move. The library scans ran at 68.2 and 74.3 GB/s, against 43.0 GB/s for the scan of Chapter 8: 1.6 to 1.7 times as fast, almost entirely because they move half the bytes. The 2 last values differ by 2, the value of the last element, which the exclusive scan does not include.
11.2.4 Radix sort
Sorting is the clearest case for a library, because the fastest GPU sorting algorithm is long
and difficult to write. The algorithm is radix sort. Most sorting algorithms, such as the
std::sort of the C++ library, are comparison sorts: they learn the order only by asking
which of 2 keys comes first. Radix sort never compares 2 keys. It sorts them 1 digit at a time,
starting with the lowest digit.
Definition 11.3 Radix sort and stability. A radix sort sorts keys in 1 pass per digit, from the lowest digit to the highest, and in each pass orders the keys by that digit alone. A pass is stable if keys with the same digit keep the relative order they had before the pass.
Example. The keys 21 and 28 have the same tens digit, 2. After the pass on the ones digit, 21 comes before 28; a stable pass on the tens digit keeps 21 before 28.
Stability is what preserves the order established by the lower digits. Each pass is built from two algorithms of Chapter 8. A histogram counts how many keys have each digit. An exclusive scan of the counts then gives the first output position of each digit’s group. Finally, every key is written to the next free position of its group. Writing each element to a position computed for it, rather than to the next position in order, is called a scatter:
radix sort, digits of b bits, keys of B bits:
for shift ← 0, b, 2b, … , B − b:
digit(k) ← (k >> shift) mod 2^b
count[d] ← number of keys with digit d # a histogram
start[d] ← count[0] + … + count[d − 1] # an exclusive scan
for each key k, in order: # a stable scatter
out[start[digit(k)]] ← k
start[digit(k)] ← start[digit(k)] + 1
keys ← out
Fig. 11.3 sorts 6 keys of 2 decimal digits, so that the digits can be read directly.
Worked example: 53, 21, 37, 28, 15, 31
- Pass 1, the ones digit: 3, 1, 7, 8, 5, 1. Counts: digit 1 twice, digits 3, 5, 7 and 8 once each.
- Exclusive scan of the counts: digit 1 starts at 0, digit 3 at 2, digit 5 at 3, digit 7 at 4, digit 8 at 5.
- Scatter, in input order: 21 → 0, 31 → 1, 53 → 2, 15 → 3, 37 → 4, 28 → 5. Result: 21, 31, 53, 15, 37, 28.
- Pass 2, the tens digit: 2, 3, 5, 1, 3, 2. Starts: digit 1 at 0, digit 2 at 1, digit 3 at 3, digit 5 at 5.
- Scatter: 15, 21, 28, 31, 37, 53. The keys are sorted after 2 passes, 1 for each digit.
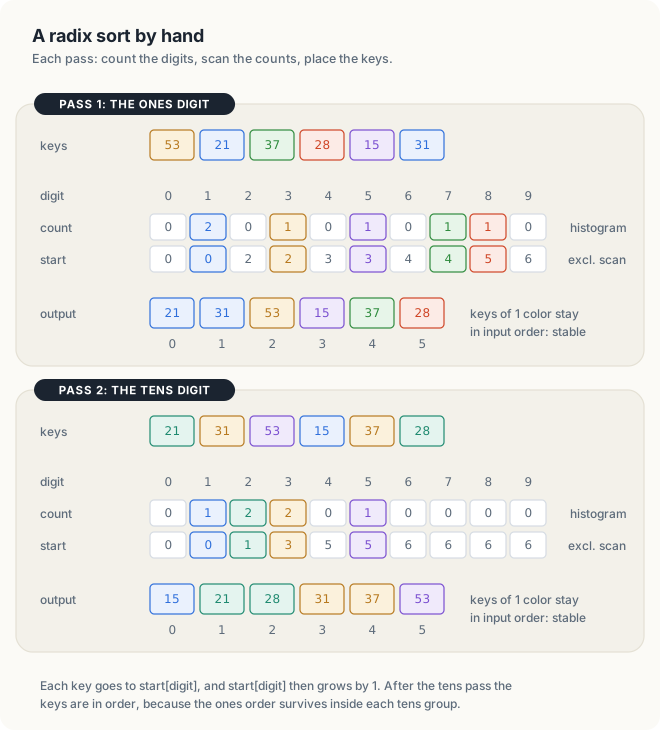
On a GPU the digits are binary. CUB sorts 8 bits per pass, which gives 256 possible digits, so a 32-bit key takes 4 passes, and each pass reads and writes every key. The work of a radix sort therefore grows with the number of keys times the number of passes, not with \(n \log n\) as the work of a comparison sort does. For \(n\) = 16,777,216 = 224 keys, a comparison sort needs on the order of \(n \log_2 n\) = 24\(n\) comparisons, while a radix sort on 32-bit keys makes 4 passes over the \(n\) keys.
Radix sort has 1 requirement. It must know what the bits of a key mean. Thrust uses it only
when the keys are numbers and the order is a standard one, less or greater. If the
program supplies any other comparison, such as the functor Ascending in Listing 11.4,
Thrust cannot look inside it and falls back to a merge sort, a comparison sort that
repeatedly merges 2 sorted runs of keys into 1 longer sorted run and only asks the comparison
which of 2 keys comes first. Ascending produces the same order as less, so the
2 results are identical; only the algorithm differs.
Thrust also needs temporary storage to sort: a second array of keys, plus space for the counts.
By default it allocates this memory with cudaMalloc at the start of each call and frees it
with cudaFree at the end. An allocator is an object that provides memory on request.
Thrust accepts an allocator as part of its execution policy, thrust::cuda::par(allocator), and
then takes its temporary storage from the allocator. The allocator Arena in Listing 11.4 keeps
1 large buffer and hands out pieces of it. During 1 sort, Thrust asks for several pieces, and
Arena hands them out one after another from the start of the buffer. Before the sort returns,
Thrust gives every piece back, and Arena then starts again from the beginning. The next sort
therefore receives the same memory, with no call to cudaMalloc or cudaFree in between.
Listing 11.4 A comparison Thrust cannot see inside, and an allocator that reuses 1 buffer. code/ch11_libraries/sort.cu
// The same order as thrust::less, but Thrust cannot see inside it, so it cannot use a
// radix sort and falls back to a merge sort, which only compares keys.
struct Ascending {
__host__ __device__ bool operator()(unsigned a, unsigned b) const { return a < b; }
};
// Scratch memory for Thrust, allocated once. During a call Thrust asks for temporary
// buffers and gives them all back before it returns. The arena hands out pieces of 1
// large buffer, and starts again from its beginning when every piece is back.
struct Arena {
using value_type = char;
char* base = nullptr;
size_t size = 0;
size_t used = 0;
int live = 0;
char* allocate(std::ptrdiff_t bytes)
{
size_t start = (used + 255) / 256 * 256; // 256-byte aligned
if (start + bytes > size) {
std::fprintf(stderr, "arena too small for %td bytes\n", bytes);
std::exit(1);
}
used = start + bytes;
++live;
return base + start;
}
void deallocate(char*, size_t)
{
--live;
if (live == 0) {
used = 0;
}
}
};
Listing 11.5 4 ways to sort with Thrust.
int main()
{
// ...
auto plain = [&] { thrust::sort(thrust::device, keys, keys + n); };
double ms = timeSort(plain, keys, original, n);
bool ok = report("thrust::sort", ms, n, keys, ascending);
Arena arena;
arena.size = 2 * size_t(n) * 4;
check(cudaMalloc(&arena.base, arena.size));
auto policy = thrust::cuda::par(arena);
auto radix = [&] { thrust::sort(policy, keys, keys + n); };
ms = timeSort(radix, keys, original, n);
ok &= report("thrust::sort, scratch reused", ms, n, keys, ascending);
cuda::std::greater<unsigned> greater;
auto down = [&] { thrust::sort(policy, keys, keys + n, greater); };
ms = timeSort(down, keys, original, n);
ok &= report(" ... with cuda::std::greater", ms, n, keys, descending);
auto merge = [&] { thrust::sort(policy, keys, keys + n, Ascending()); };
ms = timeSort(merge, keys, original, n);
ok &= report(" ... with own comparison", ms, n, keys, ascending);
// ...
}
cuda-oxide provides no sort, so Listings 11.4 and 11.5 have no Rust form; in Chapter 22 we write a radix sort in Rust from its histogram, scan and scatter.
The program sorts 16,777,216 random 32-bit keys (64 MiB) and checks each result against
std::sort on the CPU. It also runs CUB’s own radix sort, cub::DeviceRadixSort, with its
temporary storage allocated once, as described in Section 11.3.3.
$ ./sort
GPU: Orin, 8 SMs
sort of 16777216 random 32-bit keys, average of 5 runs
std::sort, 1 CPU core 1626.26 ms 10.3 Mkeys/s
thrust::sort 24.79 ms 676.7 Mkeys/s correct: yes
thrust::sort, scratch reused 13.05 ms 1285.5 Mkeys/s correct: yes
... with cuda::std::greater 30.92 ms 542.6 Mkeys/s correct: yes
... with own comparison 24.43 ms 686.8 Mkeys/s correct: yes
cub::DeviceRadixSort 8.96 ms 1872.8 Mkeys/s correct: yes
sort of 16777216 keys from 0 to 255
cub::DeviceRadixSort, bits 0 to 31 8.12 ms 2067.2 Mkeys/s correct: yes
cub::DeviceRadixSort, bits 0 to 7 3.13 ms 5356.5 Mkeys/s correct: yes
PASSED
Mkeys/s is millions of keys sorted per second. The output supports 5 observations.
- The GPU sorts 66 to 180 times as fast as 1 CPU core: 24.79 ms or less, against 1,626 ms.
- Allocation accounts for almost half the time of the plain
thrust::sort. With the temporary storage reused, the sort took 13.05 ms instead of 24.79 ms, so about 12 ms of each call went tocudaMallocandcudaFree. A separate test on the same GPU timed 1cudaMallocandcudaFreeof 64 MiB at 10 ms, and of 128 MiB at 20 ms. The cost depends on the state of the system: across 9 runs the difference ranged from 1 ms to 18 ms. On an integrated GPU the device memory is the system memory, which other programs on the CPU use as well. - Merge sort is slower than radix sort. With the comparison hidden in a functor, the same order took 24.43 ms instead of 13.05 ms, 1.9 times as long.
- The fast path depends on what the library recognizes. In CCCL 2.5, Thrust selects radix
sort only if the type of the comparison is exactly
thrust::less<Key>orthrust::greater<Key>.cuda::std::greateris a different type in that version, so the descending sort fell back to merge sort and took 30.92 ms. CCCL 3.2 makesthrust::greateranother name forcuda::std::greater, and the same source code then takes the radix path and runs as fast as the ascending sort. Only a measurement shows which path a call took. - Fewer key bits mean fewer passes. For keys from 0 to 255, only bits 0 to 7 differ.
When told so with
begin_bit= 0 andend_bit= 8, CUB made 1 pass instead of 4 and finished 2.6 times as fast, in 3.13 ms instead of 8.12 ms. The range of the keys is known to the program, not to the library.
The 2 merge sorts differ by 26%, more than their code differs. Sorts that take 20 to 30 ms varied by 20% to 30% between runs, so this difference is within the noise of the measurement.
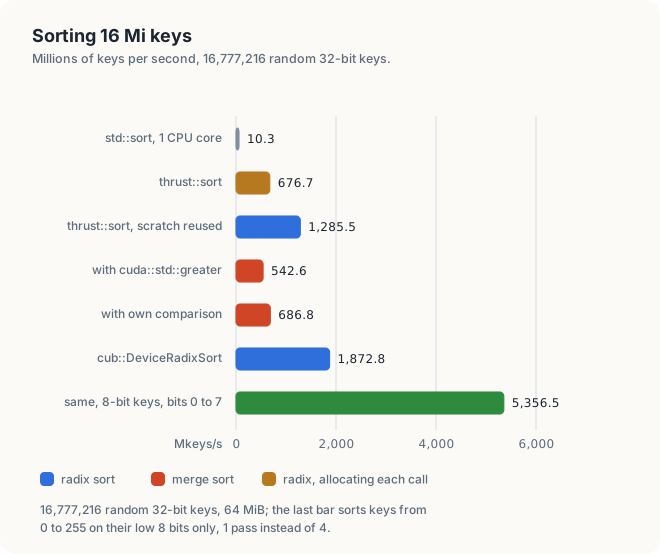
Why does a radix sort need every pass to be stable?
After pass 1 the keys are in order of their lowest digit. Pass 2 groups them by the next digit; within a group, the keys must stay in the order pass 1 left them, or the order of the lower digit is lost. In Fig. 11.3, 21 and 28 share the tens digit 2, and 21 stays ahead of 28 only because pass 2 keeps the order of pass 1.
11.3 CUB: block-level and device-wide primitives
11.3.1 Block-wide reduction with cub::BlockReduce
The lowest level of CUB is used inside a kernel that the programmer writes. Recall that a
block is a group of threads of a kernel that run on the same SM and share its shared
memory, and that a warp is a group of 32 threads of a block that execute each
instruction together. cub::BlockReduce combines 1 value from each thread of a block into a
single value, the task performed by the function blockSum in Chapter 8. That function
first reduced the values within each warp with shuffles, instructions that pass a value
from 1 thread of a warp to another. It then stored 1 partial sum per warp in shared memory
and reduced those partial sums with a final round of shuffles in warp 0.
Let us count the steps for a block of 256 threads, which form 256 / 32 = 8 warps. In the first
step, each warp halves its 32 values 5 times with shuffles, 32 → 16 → 8 → 4 → 2 → 1, and the
thread at lane 0, the position 0 within the warp, holds the warp’s total. In the second
step, the 8 lane-0 threads write 8 totals to shared memory. In the third step, warp 0 reads the
8 totals and reduces them with 3 more shuffles, 8 → 4 → 2 → 1. Thread 0 of the block then holds
the total of all 256 values. Listing 11.6 is the fastest kernel of Chapter 8 with blockSum
replaced by CUB.
Listing 11.6 Chapter 8's sum with cub::BlockReduce.
mod kernels {
// ...
/// The same sum, with cuda-oxide's block_reduce in place of warp_sum and the slots.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_blocks(input: &[f32], mut partial: DisjointSlice<f32>) {
static mut WARPS: SharedArray<f32, 8> = SharedArray::UNINIT;
let stride = (thread::gridDim_x() * BLOCK) as usize;
let block = this_thread_block();
let mut sum = 0.0;
let mut i = thread::index_1d().get();
while i < input.len() {
sum += input[i];
i += stride;
}
sum = block_reduce::<f32, Sum, 8>(&block, sum, &raw mut WARPS);
if thread::threadIdx_x() == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = sum };
}
}
// ...
}// The same kernel, with CUB's block reduction in place of warpSum and blockSum.
__global__ void sumCub(const float4* in, float* partial, int n4)
{
using BlockReduce = cub::BlockReduce<float, BLOCK>;
__shared__ BlockReduce::TempStorage temp;
float sum = 0.0f;
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n4; i += gridDim.x * BLOCK) {
float4 v = in[i];
sum += v.x + v.y + v.z + v.w;
}
sum = BlockReduce(temp).Sum(sum);
if (threadIdx.x == 0) {
partial[blockIdx.x] = sum;
}
}
cub::BlockReduce<float, BLOCK> is a class template, a class written in terms of template
parameters (Chapter 10), here the element type and the number of threads. Both are fixed when
the program is compiled, and CUB selects its algorithm from them.
TempStorage is a type defined inside the class: a region of shared memory sized for the
selected algorithm. The reason for making it a type is that shared memory must be declared
with a size known at compile time, and only CUB knows how many bytes its algorithm needs for
256 floats. Declaring a __shared__ variable of type TempStorage passes that size to the
compiler. The expression BlockReduce(temp) constructs the object on that storage, and
.Sum(sum) returns the total of the block in thread 0.
In the measurements of Section 11.2.1 this kernel ran at 92.5 GB/s, against 93.4 GB/s for the
kernel of Chapter 8, which is within the noise. CUB does not make the kernel faster. It
replaces 25 lines that had to be written and verified by hand, and it handles cases that the
code of Chapter 8 did not, such as block sizes that are not a multiple of 32 and element types
other than float. The same header provides cub::BlockScan, cub::BlockHistogram,
cub::BlockRadixSort, cub::WarpReduce and cub::WarpScan, which are used in the same way.
11.3.2 Block-wide primitives in cuda-oxide
The cooperative_groups module of cuda-oxide provides the Rust counterparts: warp_reduce,
warp_scan, block_reduce and block_scan, for the types u32, i32 and f32 and the
operations Sum, Min and Max. They work in the same 3 steps as cub::BlockReduce. Each
warp reduces its 32 values with shuffles, lane 0 of each warp writes the warp’s total to a
slot in shared memory, and warp 0 reduces the slots. The slots are a SharedArray,
cuda-oxide’s type for an array in shared memory, with one element per warp, which is 256 / 32 = 8
elements for a block of 256 threads. The kernel declares the array as a static mut, a variable
that exists once for the whole block rather than once per thread, and that may be modified. A
Rust reference is a pointer that the compiler checks: while a mutable reference exists, the
compiler assumes that nothing else modifies the value. The threads of a block access the array
at the same time, so the compiler cannot guarantee that assumption, and Rust 2024 does not allow
a reference to a static mut. The kernel therefore passes &raw mut WARPS, the Rust 2024
way to obtain a raw pointer to a static mut without creating a reference.
Listing 11.7 Chapter 8's sum with block_reduce. code/oxide/ch11_blocks/src/main.rs
mod kernels {
// ...
/// The same sum, with cuda-oxide's block_reduce in place of warp_sum and the slots.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_blocks(input: &[f32], mut partial: DisjointSlice<f32>) {
static mut WARPS: SharedArray<f32, 8> = SharedArray::UNINIT;
let stride = (thread::gridDim_x() * BLOCK) as usize;
let block = this_thread_block();
let mut sum = 0.0;
let mut i = thread::index_1d().get();
while i < input.len() {
sum += input[i];
i += stride;
}
sum = block_reduce::<f32, Sum, 8>(&block, sum, &raw mut WARPS);
if thread::threadIdx_x() == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = sum };
}
}
// ...
}// The same kernel, with CUB's block reduction in place of warpSum and blockSum.
__global__ void sumCub(const float4* in, float* partial, int n4)
{
using BlockReduce = cub::BlockReduce<float, BLOCK>;
__shared__ BlockReduce::TempStorage temp;
float sum = 0.0f;
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n4; i += gridDim.x * BLOCK) {
float4 v = in[i];
sum += v.x + v.y + v.z + v.w;
}
sum = BlockReduce(temp).Sum(sum);
if (threadIdx.x == 0) {
partial[blockIdx.x] = sum;
}
}
The 8 in block_reduce::<f32, Sum, 8> is the number of warps, and the call checks it at
compile time: a block of more than 32 warps fails to build. block_scan has the same form.
Listing 11.8 scans each block of 256 values, 1 value per thread. The call out.get_mut(i)
returns an Option, a Rust value that is either Some(slot) or None. It is Some for a
thread whose index lies inside the array and None for the threads beyond its end, so the
kernel writes its results without unsafe.
Listing 11.8 A scan of each block with block_scan.
mod kernels {
// ...
/// An inclusive scan of each block of 256 values, 1 value per thread.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scan_blocks(input: &[u32], mut out: DisjointSlice<u32>) {
static mut WARPS: SharedArray<u32, 8> = SharedArray::UNINIT;
let block = this_thread_block();
let i = thread::index_1d();
let v = if i.get() < input.len() { input[i.get()] } else { 0 };
let scanned = block_scan::<u32, Sum, 8>(&block, v, &raw mut WARPS);
if let Some(slot) = out.get_mut(i) {
*slot = scanned;
}
}
// ...
}// An inclusive scan of each block of 256 values, 1 value per thread, with CUB.
__global__ void scanBlocks(const unsigned* in, unsigned* out, int n)
{
using BlockScan = cub::BlockScan<unsigned, BLOCK>;
__shared__ BlockScan::TempStorage temp;
int i = blockIdx.x * BLOCK + threadIdx.x;
unsigned v = i < n ? in[i] : 0;
BlockScan(temp).InclusiveSum(v, v);
if (i < n) {
out[i] = v;
}
}
$ cargo oxide run
sum of 67108864 floats, average of 20 runs
Chapter 8, by hand 3.95 ms 68.0 GB/s sum 33557632.0
block_reduce 4.10 ms 65.5 GB/s sum 33557632.0
exact (f64) sum 33557630.3
block_scan of 67108864 values, 256 per block
first block: [0, 1, 1, 3, 5, 5, 5, 6] ... 403
sum of squares, GB/s of input read
map, then map_sum 14.67 ms 18.3 GB/s sum 22372548.0
map_sum, fused 4.17 ms 64.4 GB/s sum 22372548.0
exact (f64) sum 22372547.9
sum of 4096 floats, microseconds per sum
allocated each time, result copied 40.7 us
allocated once, result copied 24.1 us
allocated once, result kept 8.4 us
PASSED
The 2 Rust sums ran within 4% of each other and produced the same total. Both kernels read 1
float per load, so they reach 68 GB/s rather than the 93 GB/s of the C++ kernels, which use
float4 loads, each of which reads 4 floats, 16 bytes, in 1 instruction; we measured
the same difference in Chapter 8. The first 8 scanned values increase by
0 to 3 at each step, as the inputs 0, 1, 0, 2, 2, 0, 0, 1 require, and the program checked all
67,108,864 results. The last 8 lines are the Rust counterparts of Listings 11.2 and
11.10: the fused sum of squares ran 3.5 times as fast as the 2 passes, and the small sum took
8.4 µs instead of 40.7 µs once the allocation and the copy were removed.
11.3.3 Device-wide calls and temporary storage
The middle level of CUB runs a complete algorithm on a complete array, as Thrust does, but takes its temporary storage from the caller. The caller, however, does not know how many bytes CUB needs: the number depends on the algorithm that CUB selects for the GPU and for the size of the array. CUB therefore answers that question in a first call, and does the work in a second call. A CUB device-wide call is made twice:
1. call with no temporary storage (nullptr) → CUB writes the number of bytes it needs
2. allocate that many bytes, once
3. call with the temporary storage → CUB launches its kernels and returns at once
(repeat step 3 as often as needed, with the same storage)
Listing 11.9 cub::DeviceReduce::Sum, called twice.
fn small_sums(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
values: &[f32],
) -> Result<(), Error> {
// ...
let mut partial = DeviceBuffer::<f32>::zeroed(stream, blocks as usize)?;
let mut total = DeviceBuffer::<f32>::zeroed(stream, 1)?;
let ms = time_ms(stream, || {
module.map_sum(stream, &grid, same, &input, &mut partial)?;
module.map_sum(stream, &one, same, &partial, &mut total)?;
total.to_host_vec(stream)?;
Ok(())
})?;
println!(" allocated once, result copied {:6.1} us", ms * 1e3);
let ms = time_ms(stream, || {
module.map_sum(stream, &grid, same, &input, &mut partial)?;
Ok(module.map_sum(stream, &one, same, &partial, &mut total)?)
})?;
println!(" allocated once, result kept {:6.1} us", ms * 1e3);
// ...
}bool sums(const float* in, float* partial, float* total, int n, double exact)
{
// ...
size_t tempBytes = 0;
cub::DeviceReduce::Sum(nullptr, tempBytes, in, total, n); // asks for the size only
void* temp;
check(cudaMalloc(&temp, tempBytes));
auto cubDevice = [&] { cub::DeviceReduce::Sum(temp, tempBytes, in, total, n); };
ms = timeMs(cubDevice);
ok &= report("cub::DeviceReduce::Sum", ms, bytes, readBack(total), exact);
std::printf(" (CUB asked for %zu bytes of temporary storage)\n", tempBytes);
// ...
}
The Rust kernels need no temporary storage beyond the partial sums, whose number the program knows, so the Rust tab allocates them once and reuses them.
For the sum of 64 Mi floats, CUB asked for 1,279 bytes, enough for the partial sums of its
blocks. The result total remains in device memory, and the call returns without waiting for
the GPU. A call that returns before the GPU has finished the work it requested is called
asynchronous; the host can go on to queue the next kernel while the sum runs. On 256 MiB of
data, where the work itself takes 2.9 ms, neither difference from thrust::reduce matters. On a
small array, however, they determine the time.
Consider a sum of 4,096 floats, 16 KiB. At 92 GB/s, reading 16 KiB takes 16,384 B / 92 GB/s
= 0.18 µs. Listing 11.10 measures three ways of computing this sum. thrust::reduce took 68.1 µs
per sum, CUB with the result copied to the host took 29.9 µs, and CUB with the result left on
the GPU took 8.8 µs. The differences identify where the time goes. Allocating and freeing the
temporary storage costs 68.1 − 29.9 = 38.2 µs, and copying 4 bytes back and waiting for the
GPU costs 29.9 − 8.8 = 21.1 µs. The remaining 8.8 µs are the launch and execution of CUB’s
kernel, which is still 49 times the time the memory needs.
Listing 11.10 3 ways to sum 4,096 floats.
/// A sum of 4,096 floats in 3 ways: storage allocated for each sum and the result
/// copied to the host, as thrust::reduce does; storage allocated once and the result
/// copied; storage allocated once and the result kept on the GPU.
fn small_sums(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
values: &[f32],
) -> Result<(), Error> {
let n = 4096;
let blocks = 16;
let input = DeviceBuffer::from_host(stream, &values[..n])?;
let grid = module.prepare_map_sum(LaunchConfig1D::new(blocks, BLOCK, 0))?;
let one = module.prepare_map_sum(LaunchConfig1D::new(1, BLOCK, 0))?;
let same = |v: f32| v;
println!("sum of {n} floats, microseconds per sum");
let ms = time_ms(stream, || {
let mut partial = DeviceBuffer::<f32>::zeroed(stream, blocks as usize)?;
let mut total = DeviceBuffer::<f32>::zeroed(stream, 1)?;
module.map_sum(stream, &grid, same, &input, &mut partial)?;
module.map_sum(stream, &one, same, &partial, &mut total)?;
total.to_host_vec(stream)?;
Ok(())
})?;
println!(" allocated each time, result copied {:6.1} us", ms * 1e3);
let mut partial = DeviceBuffer::<f32>::zeroed(stream, blocks as usize)?;
let mut total = DeviceBuffer::<f32>::zeroed(stream, 1)?;
let ms = time_ms(stream, || {
module.map_sum(stream, &grid, same, &input, &mut partial)?;
module.map_sum(stream, &one, same, &partial, &mut total)?;
total.to_host_vec(stream)?;
Ok(())
})?;
println!(" allocated once, result copied {:6.1} us", ms * 1e3);
let ms = time_ms(stream, || {
module.map_sum(stream, &grid, same, &input, &mut partial)?;
Ok(module.map_sum(stream, &one, same, &partial, &mut total)?)
})?;
println!(" allocated once, result kept {:6.1} us", ms * 1e3);
Ok(())
}void smallSums(const float* in, float* total)
{
const int n = 4096;
float t = 0.0f;
std::printf("sum of %d floats, microseconds per sum\n", n);
auto thrustSum = [&] { t = thrust::reduce(thrust::device, in, in + n, 0.0f); };
std::printf(" thrust::reduce %6.1f us\n", timeMs(thrustSum) * 1e3);
size_t tempBytes = 0;
cub::DeviceReduce::Sum(nullptr, tempBytes, in, total, n);
void* temp;
check(cudaMalloc(&temp, tempBytes));
auto cubAndCopy = [&] {
cub::DeviceReduce::Sum(temp, tempBytes, in, total, n);
check(cudaMemcpy(&t, total, sizeof(float), cudaMemcpyDeviceToHost));
};
double usCopy = timeMs(cubAndCopy) * 1e3;
std::printf(" cub::DeviceReduce, result copied %6.1f us\n", usCopy);
auto cubOnly = [&] { cub::DeviceReduce::Sum(temp, tempBytes, in, total, n); };
double usOnly = timeMs(cubOnly) * 1e3;
std::printf(" cub::DeviceReduce, result kept %6.1f us\n", usOnly);
check(cudaFree(temp));
}
sum of 4096 floats, microseconds per sum
thrust::reduce 68.1 us
cub::DeviceReduce, result copied 29.9 us
cub::DeviceReduce, result kept 8.8 us
Across 6 runs, thrust::reduce took 44 to 68 µs and CUB with the result kept on the GPU 4.7
to 8.8 µs. In 5 of the 6 runs the 3 lines appeared in the order shown. In the remaining run
the copy back was slow, and CUB with the result copied took 78.6 µs. Operations that wait for
the host vary the most.
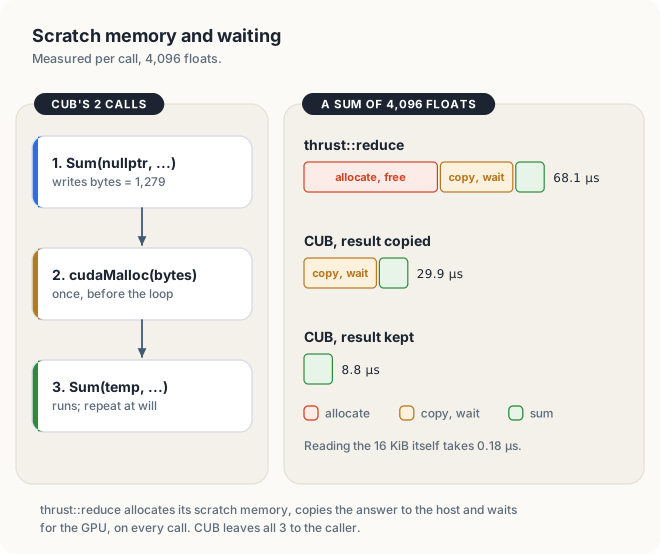
A program that sums 1,000 small arrays per second therefore spends 68 ms of each second in
thrust::reduce, and less than 9 ms with CUB when the result stays on the GPU for the next
kernel. The algorithm is the same in both cases. The difference lies in the information the
program gave the library.
On small inputs, the cost of a library call is allocation and synchronization, not arithmetic. Allocate temporary storage once, and keep results on the GPU when the next step runs there.
11.4 cuBLAS: dense linear algebra
11.4.1 The cuBLAS handle
cuBLAS implements the BLAS (Basic Linear Algebra Subprograms), a standard set of routines first published for Fortran in 1979. The routines are organized in 3 levels: dot products and vector updates (level 1), matrix-vector products (level 2) and matrix-matrix products (level 3), among them SGEMM.
A cuBLAS call needs more information than its arguments carry. It must know which stream to submit its kernels to, where its temporary storage is, and whether it may trade accuracy for speed. A stream (Chapter 6) is a queue of GPU work that runs in order. cuBLAS could keep these settings in global variables, but then 2 host threads that use cuBLAS at the same time, 1 with stream 1 and 1 with stream 2, would overwrite each other’s setting. cuBLAS instead keeps them in an object that the program creates and passes to every call.
Definition 11.4 Handle. A handle is an object, created once by the program, that holds the state of a library: its temporary storage, its stream and its settings. The program passes the handle as the first argument of every call.
Example. cublasCreate(&handle) creates a cuBLAS handle; cublasSetStream(handle, s) makes
every later call with handle submit its kernels to stream s; a second host thread uses its
own handle with its own stream.
The settings in a handle include the math mode of Section 11.4.3. Keeping this state in a handle rather than in global variables allows 2 threads of a program to use cuBLAS at the same time, each with its own handle.
Creating a handle is slow. The program of this section measures it:
cublasCreate took 13.2 ms
13.2 ms is 3,500 times the 3.77 µs per launch of an empty kernel measured in Section 6.7. A program should therefore create 1 handle at startup and pass it to every call.
11.4.2 Row-major and column-major storage
A matrix is stored in memory as a 1-dimensional sequence of numbers, so a program must decide in which order the entries are laid out. We work with 1 small matrix throughout this section, \(A = [1\ 2\ 3;\ 4\ 5\ 6]\), which has 2 rows and 3 columns; the semicolon separates the rows. We number the entries by (row, column) from 0, so the entry 6 is at (1, 2). In every chapter of this book we have stored a matrix row by row, as C and C++ arrays do: row 0 occupies locations 0 to 2 and row 1 locations 3 to 5, so memory holds 1, 2, 3, 4, 5, 6. To find entry (r, c), we skip r complete rows of 3 entries and then c entries, which gives location \(3r + c\). The entry 6 at (1, 2) is at location 3 + 2 = 5.
Fortran, and the original BLAS written in it, store a matrix column by column instead: column 0 occupies locations 0 and 1, column 1 locations 2 and 3, and column 2 locations 4 and 5, so memory holds 1, 4, 2, 5, 3, 6. To find entry (r, c), we skip c complete columns of 2 entries and then r entries, which gives location \(2c + r\). The entry 6 at (1, 2) is now at location 2 × 2 + 1 = 5, and location 1, which held 2 in the first layout, now holds 4.
Definition 11.5 Row-major and column-major order. In row-major order, the rows of a matrix are stored one after another; in a matrix with \(n\) columns, entry (r, c) is at location \(r n + c\). In column-major order, the columns are stored one after another; in a matrix with \(m\) rows, entry (r, c) is at location \(c m + r\).
Example. For the 2 × 3 matrix \(A\) above, entry (0, 1) = 2 is at location 1 in row-major order and at location 2 in column-major order.
cuBLAS keeps the column-major convention of the original BLAS. Let us therefore ask what cuBLAS sees when it receives our row-major memory 1, 2, 3, 4, 5, 6 and is told that the matrix has 3 rows and 2 columns. It reads column 0 from locations 0 to 2, which hold 1, 2, 3, and column 1 from locations 3 to 5, which hold 4, 5, 6. The matrix it sees is \([1\ 4;\ 2\ 5;\ 3\ 6]\). It is the transpose of \(A\), written \(A^T\), the matrix in which rows and columns are exchanged, so that entry (r, c) of \(A^T\) is entry (c, r) of \(A\).
Key observation Entry (r, c) of a row-major \(m \times n\) matrix is at location \(r n + c\), and entry (c, r) of a column-major \(n \times m\) matrix is at location \(r n + c\) as well. A row-major matrix and its column-major transpose occupy memory identically, so a row-major array passed to a column-major library is seen as its transpose.
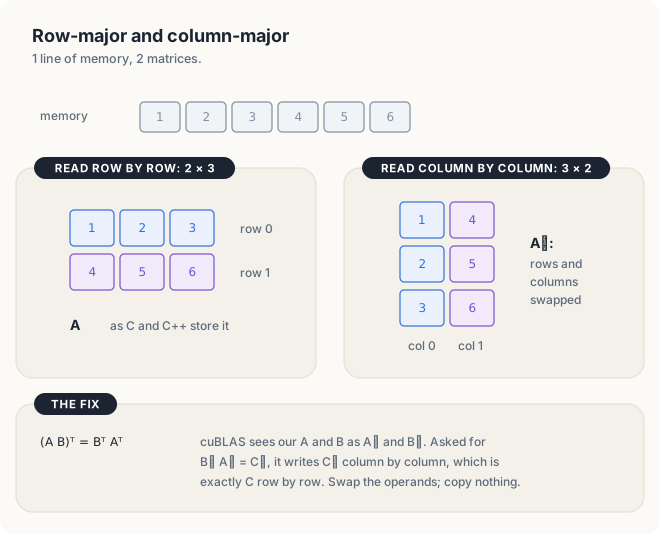
The transpose of a product reverses the order of its factors: \((AB)^T = B^T A^T\). This identity gives the solution. cuBLAS sees our arrays for \(A\) and \(B\) as \(A^T\) and \(B^T\). If we ask cuBLAS for the product of \(B^T\) as its first operand and \(A^T\) as its second, it computes \(B^T A^T = (AB)^T = C^T\) and stores it column by column. A column-major \(C^T\) occupies memory exactly as a row-major \(C\) does. For example, with the matrix \(B\) of the worked example below, \(C = AB = [58\ 64;\ 139\ 154]\), so \(C^T = [58\ 139;\ 64\ 154]\). Stored column by column, \(C^T\) is 58, 64, 139, 154, which is \(C\) stored row by row. Swapping the 2 operands, together with the 2 outer dimensions, is therefore sufficient; no data is copied or transposed.
The location formula \(c m + r\) of column-major order needs 1 more number from the program: how far apart 2 consecutive columns start. For our 2 × 3 matrix, column 1 starts 2 locations after column 0. Now suppose a program stores a 4 × 4 matrix in column-major order and wants cuBLAS to work on its top-left 2 × 2 corner. The corner has 2 rows, but its column 0 starts at location 0 and its column 1 at location 4, because the 4 entries of the first column of the large matrix lie in between. cuBLAS must therefore be told 4, not 2.
Definition 11.6 Leading dimension. The leading dimension of a column-major matrix is the distance in elements between the starts of 2 consecutive columns. Entry (r, c) is at location \(c \cdot ld + r\), where \(ld\) is the leading dimension.
Example. For a complete matrix it equals the number of rows that cuBLAS sees: 2 for the 2 × 3 matrix \(A\). For the 2 × 2 corner of a 4 × 4 matrix it is 4.
Worked example: \(A\) is 2 × 3, \(B = [7\ 8;\ 9\ 10;\ 11\ 12]\) is 3 × 2
- The correct result: row 0 of \(C\) is 1 × 7 + 2 × 9 + 3 × 11 = 58 and 1 × 8 + 2 × 10 + 3 × 12 = 64; row 1 is 139 and 154.
- The incorrect call passes \(A\) and \(B\) as given. cuBLAS reads the memory of \(A\) as 2 rows with leading dimension 2, so its columns are (1, 2), (3, 4), (5, 6): the matrix \([1\ 3\ 5;\ 2\ 4\ 6]\). It reads \(B\) as \([7\ 10;\ 8\ 11;\ 9\ 12]\).
- Their product is \([76\ 103;\ 100\ 136]\), since 1 × 7 + 3 × 8 + 5 × 9 = 76. cuBLAS stores it column by column: 76, 100, 103, 136. The program reads that memory row by row, as \([76\ 100;\ 103\ 136]\). No error is reported, and every element is wrong.
- The correct call passes \(B\) first, with leading dimension 2, and \(A\) second, with leading dimension 3.
Listing 11.11 The incorrect call and the correct one. code/ch11_libraries/gemm.cu
fn small_product(handle: Handle, stream: &Arc<CudaStream>) -> Result<bool, Error> {
// ...
let (one, zero) = (1.0f32, 0.0f32);
let op = CUBLAS_OP_N;
println!("C = A B with A 2 x 3 and B 3 x 2, stored row by row");
print("A", &a, 2, 3);
print("B", &b, 3, 2);
// Wrong: cuBLAS reads each array column by column.
// SAFETY: the 3 pointers address live buffers of 6, 6 and 4 floats, enough for the
// sizes and leading dimensions given.
let result = unsafe {
cublasSgemm_v2(handle, op, op, 2, 2, 3, &one, pa, 2, pb, 3, &zero, pc, 2)
};
ok(result, "cublasSgemm")?;
let c = c_dev.to_host_vec(stream)?;
print("C, operands as given ", &c, 2, 2);
// Right: in column-major terms our arrays hold A^T and B^T. Ask for B^T A^T = C^T,
// whose column-major storage is C row by row.
// SAFETY: as above.
let result = unsafe {
cublasSgemm_v2(handle, op, op, 2, 2, 3, &one, pb, 2, pa, 3, &zero, pc, 2)
};
ok(result, "cublasSgemm")?;
let c = c_dev.to_host_vec(stream)?;
print("C, operands swapped ", &c, 2, 2);
// ...
}// C = A B for a 2 x 3 matrix A and a 3 x 2 matrix B, all stored row by row.
bool smallProduct(cublasHandle_t handle)
{
// ...
float one = 1.0f, zero = 0.0f;
auto op = CUBLAS_OP_N;
std::printf("C = A B with A 2 x 3 and B 3 x 2, stored row by row\n");
print("A", a, 2, 3);
print("B", b, 3, 2);
// Wrong: cuBLAS reads each array column by column.
check(cublasSgemm(handle, op, op, 2, 2, 3, &one, A, 2, B, 3, &zero, C, 2));
check(cudaMemcpy(c.data(), C, 4 * sizeof(float), cudaMemcpyDeviceToHost));
print("C, operands as given ", c, 2, 2);
// Right: in column-major terms our arrays hold A^T and B^T. Ask for B^T A^T = C^T,
// whose column-major storage is C row by row.
check(cublasSgemm(handle, op, op, 2, 2, 3, &one, B, 2, A, 3, &zero, C, 2));
check(cudaMemcpy(c.data(), C, 4 * sizeof(float), cudaMemcpyDeviceToHost));
print("C, operands swapped ", c, 2, 2);
// ...
}
The Rust program declares cublasSgemm_v2, the C function behind cublasSgemm, with
#[link(name = "cublas")], and passes the same arguments.
The 2 calls differ only in the order of their operands and leading dimensions. cuBLAS computes \(C \leftarrow \alpha \cdot \mathrm{op}(A)\,\mathrm{op}(B) + \beta C\), where \(\alpha\) and \(\beta\) are scalars and \(\mathrm{op}\) either leaves an operand as it is or transposes it. With \(\alpha = 1\) and \(\beta = 0\), the formula reduces to \(C \leftarrow AB\); with \(\beta = 1\), it adds the product to the previous contents of \(C\). The arguments after the handle follow that formula:
| Arguments | Meaning | In the correct call |
|---|---|---|
op, op | an operation on each operand; CUBLAS_OP_N means none | none, none |
2, 2, 3 | \(m\), \(n\), \(k\): an \(m \times k\) operand times a \(k \times n\) operand | 2, 2, 3 |
&one | the factor \(\alpha\) | 1 |
B, 2 | the first operand and its leading dimension | \(B^T\), 2 rows |
A, 3 | the second operand and its leading dimension | \(A^T\), 3 rows |
&zero | the factor \(\beta\); 0 ignores the previous contents of \(C\) | 0 |
C, 2 | the result and its leading dimension | \(C^T\), 2 rows |
C = A B with A 2 x 3 and B 3 x 2, stored row by row
A = [1 2 3; 4 5 6]
B = [7 8; 9 10; 11 12]
C, operands as given = [76 100; 103 136]
C, operands swapped = [58 64; 139 154]
Both lines agree with the values computed by hand. In Chapter 9, we called cuBLAS in the same way for square matrices. There the 2 outer dimensions are equal, so only the order of the operands differs, and a test with square matrices alone would not have exposed a wrong leading dimension.
11.4.3 SGEMM performance and TF32 tensor cores
Listing 11.12 runs the product of Chapter 9 with \(N\) = 4,096 twice. The first call uses
cuBLAS’s default math mode, the setting in the handle that states which number formats and
arithmetic units cuBLAS may use; the default is FP32 on the ordinary arithmetic units. Before
the second call, cublasSetMathMode allows the library to use TF32, a number format
described below, on the tensor cores, units that multiply small matrices in a single
instruction.
Listing 11.12 SGEMM in FP32, then with TF32 tensor cores allowed.
fn main() -> Result<(), Error> {
// ...
let (one, zero) = (1.0f32, 0.0f32);
let op = CUBLAS_OP_N;
let n = N as c_int;
let mut gemm = || -> Result<(), Error> {
// SAFETY: the 3 pointers address live buffers of N x N floats.
let result = unsafe {
cublasSgemm_v2(handle, op, op, n, n, n, &one, pb, n, pa, n, &zero, pc, n)
};
ok(result, "cublasSgemm")
};
let report = |name: &str, ms: f64| -> Result<f64, Error> {
let c = c_dev.to_host_vec(&stream)?;
let gflops = 2.0 * (N * N * N) as f64 / ms / 1e6;
let error = max_error(&a, &b, &c);
println!(" {name:<22} {ms:8.2} ms {gflops:7.1} GFLOP/s max error {error:.1e}");
Ok(error)
};
for _ in 0..10 {
time_ms(&stream, 5, &mut gemm)?; // warm up: clocks rise under sustained load
}
println!("C = A B, {N} x {N} floats, average of 10 runs");
let ms = time_ms(&stream, 10, &mut gemm)?;
let fp32 = report("cuBLAS, FP32", ms)?;
// SAFETY: the handle is live.
let result = unsafe { cublasSetMathMode(handle, CUBLAS_TF32_TENSOR_OP_MATH) };
ok(result, "cublasSetMathMode")?;
let ms = time_ms(&stream, 10, &mut gemm)?;
let tf32 = report("cuBLAS, TF32 tensor", ms)?;
// ...
}int main()
{
// ...
float one = 1.0f, zero = 0.0f;
auto op = CUBLAS_OP_N;
auto gemm = [&] {
check(cublasSgemm(handle, op, op, N, N, N, &one, B, N, A, N, &zero, C, N));
};
auto report = [&](const char* name, double ms) {
check(cudaMemcpy(c.data(), C, bytes, cudaMemcpyDeviceToHost));
double gflops = 2.0 * N * N * N / ms / 1e6;
double error = maxError(a, b, c);
std::printf(" %-22s %8.2f ms %7.1f GFLOP/s", name, ms, gflops);
std::printf(" max error %.1e\n", error);
return error;
};
for (int k = 0; k < 10; ++k) { // warm up: clocks rise under sustained load
timeMs(gemm, 5);
}
std::printf("C = A B, %d x %d floats, average of 10 runs\n", N, N);
double fp32 = report("cuBLAS, FP32", timeMs(gemm, 10));
check(cublasSetMathMode(handle, CUBLAS_TF32_TENSOR_OP_MATH));
double tf32 = report("cuBLAS, TF32 tensor", timeMs(gemm, 10));
// ...
}
$ ./gemm
C = A B, 4096 x 4096 floats, average of 10 runs
cuBLAS, FP32 91.34 ms 1504.6 GFLOP/s max error 1.9e-05
cuBLAS, TF32 tensor 21.05 ms 6530.4 GFLOP/s max error 4.0e-03
PASSED
In FP32, cuBLAS reached 1,504.6 GFLOP/s, 63% of the GPU’s FP32 peak of 2.4 TFLOP/s. The
best kernel of Chapter 9 reached 931.9 GFLOP/s, which is 62% of cuBLAS. The column max error compares 64 elements with a product computed in double precision, as in Chapter 9.
With tensor cores allowed, the same call ran 4.3 times as fast, at 6,530.4 GFLOP/s, which is 2.7 times the FP32 peak of the ordinary units. Its error, however, grew 210 times, from 1.9 × 10⁻⁵ to 4.0 × 10⁻³. The reason is the number format. A floating-point number is stored in 3 fields: a sign, an exponent and a mantissa, and its value is ±1.mantissa × 2exponent in binary. For example, 6 = 1.1 (binary) × 22, with exponent 2 and mantissa bits 1000…. The exponent sets the range of magnitudes that the format can hold, and the number of mantissa bits sets how many significant digits it keeps. TF32 (TensorFloat-32) keeps the 8-bit exponent of FP32 and therefore covers the same range of magnitudes, but it keeps only 10 of the 23 bits of the mantissa. Each input is rounded to 10 mantissa bits before it is multiplied, and the products are added in FP32.
The effect of the rounding can be seen on the number 1/3. In binary, 1/3 = 1.010101… × 2−2, with the pattern 01 repeating in the mantissa. FP32 keeps 23 bits of it and stores 0.33333334. TF32 keeps 10 bits, 1.0101010101 in binary, which is 1 + 341/1,024 = 1.3330078, and multiplied by 2−2 gives 0.33325195. The error of 8.1 × 10⁻⁵ is 2.4 × 10⁻⁴ of the value, against 3 × 10⁻⁸ of the value in FP32. A sum of 4,096 such products carries this error into each element of the result.
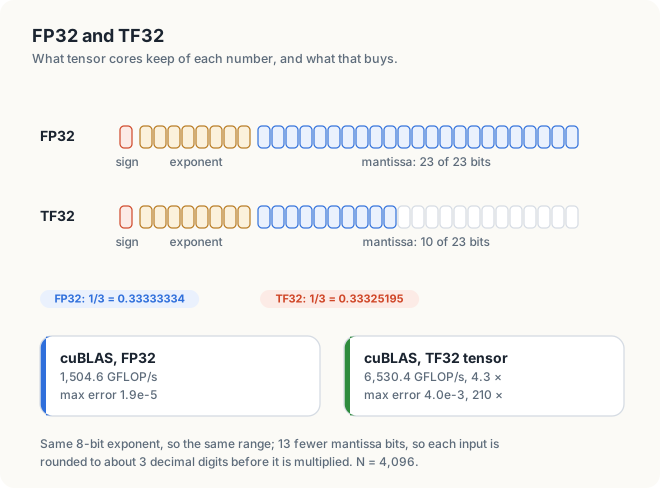
The gain from tensor cores varies widely between GPUs, because data-center GPUs devote a much larger share of the chip to them than consumer GPUs do:
| GPU | FP32 peak | TF32 tensor peak, dense | Ratio |
|---|---|---|---|
| A100 SXM | 19.5 TFLOP/s | 156 TFLOP/s | 8.0 |
| H100 SXM | 67 TFLOP/s | 495 TFLOP/s | 7.4 |
| GeForce RTX 4090 | 82.6 TFLOP/s | 82.6 TFLOP/s | 1.0 |
| The measured GPU | 1.50 TFLOP/s (cuBLAS) | 6.53 TFLOP/s (cuBLAS) | 4.3 |
The peak rates are taken from NVIDIA’s A100, H100 and Ada architecture documents; “dense” excludes the doubled rates quoted for sparse matrices, matrices in which a fixed fraction of the entries is 0 and is skipped by the hardware. TF32 is the default for training neural networks, whose results tolerate errors far larger than 10−3. A simulation that needs 7 correct digits must not use it, and cuBLAS does not use it unless the program asks for it.
11.5 cuFFT and cuRAND
11.5.1 Random number generation with cuRAND
cuRAND generates random numbers on the GPU, either into an array from a call on the host or
inside a kernel, 1 number per thread. A pseudo-random generator computes a sequence that
appears random from a starting value called the seed. The same seed always produces the
same sequence, which makes a run repeatable. CURAND_RNG_PSEUDO_PHILOX4_32_10 selects the
Philox generator, which is counter-based: number \(i\) of the sequence is computed by a
scrambling function from \(i\) and the seed alone. A classical generator instead computes
each number from the previous one, so number 1,000 can be obtained only after numbers 0 to 999.
With a counter-based generator, thread 1,000 applies the function to the counter 1,000 and the
seed directly. Every thread can therefore compute its own numbers without waiting for the
numbers that precede them.
Listing 11.13 16 Mi normal numbers with cuRAND. code/ch11_libraries/fft_rand.cu
fn normal_numbers(stream: &Arc<CudaStream>) -> Result<bool, Error> {
// ...
let mut generator: Generator = std::ptr::null_mut();
let kind = CURAND_RNG_PSEUDO_PHILOX4_32_10;
let out = ptr(&x);
// SAFETY: `generator` is a valid place for cuRAND to store its generator; `out`
// addresses n floats; the stream outlives the generator.
let ms = unsafe {
let result = curandCreateGenerator(&mut generator, kind);
ok(result, "curandCreateGenerator")?;
let result = curandSetPseudoRandomGeneratorSeed(generator, 2024);
ok(result, "curandSetPseudoRandomGeneratorSeed")?;
let result = curandSetStream(generator, stream.cu_stream().cast());
ok(result, "curandSetStream")?;
let result = curandGenerateNormal(generator, out, n, 0.0, 1.0); // warm-up
ok(result, "curandGenerateNormal")?;
stream.synchronize()?;
let start = Instant::now();
let result = curandGenerateNormal(generator, out, n, 0.0, 1.0);
ok(result, "curandGenerateNormal")?;
stream.synchronize()?;
start.elapsed().as_secs_f64() * 1e3
};
// ...
}// 16 Mi numbers from the normal distribution; their mean should be near 0 and their
// standard deviation near 1.
bool normalNumbers()
{
// ...
curandGenerator_t gen;
check(curandCreateGenerator(&gen, CURAND_RNG_PSEUDO_PHILOX4_32_10));
check(curandSetPseudoRandomGeneratorSeed(gen, 2024));
cudaEvent_t start, stop;
check(cudaEventCreate(&start));
check(cudaEventCreate(&stop));
check(curandGenerateNormal(gen, x, n, 0.0f, 1.0f)); // warm-up
check(cudaEventRecord(start));
check(curandGenerateNormal(gen, x, n, 0.0f, 1.0f));
check(cudaEventRecord(stop));
check(cudaEventSynchronize(stop));
float ms;
check(cudaEventElapsedTime(&ms, start, stop));
// ...
}
The program draws 16,777,216 numbers from the normal distribution with mean 0 and standard deviation 1, the bell-shaped distribution in which about 68% of the values lie between −1 and 1. The mean is the average of the values, and the standard deviation measures their typical distance from the mean; it is the square root of the mean of the squared distances. The program checks both parameters with 2 Thrust reductions, one over the numbers and one over their squares.
$ ./fft_rand
cuRAND, 16777216 normal numbers in 1.01 ms (16688 million per second)
mean -0.00042, standard deviation 0.99994
Writing 64 MiB of numbers in 1.01 ms corresponds to 66 GB/s, so the generator runs close to the speed of the memory. The mean of a finite sample is itself random. Its typical deviation from the true mean, called the standard error, is the standard deviation divided by the square root of the number of samples. For 16.8 million samples, the mean of a correct generator is therefore expected to deviate from 0 by about 1 / √16,777,216 = 0.00024. The measured −0.00042 is within 2 of these standard errors.
11.5.2 Fast Fourier transforms with cuFFT
A Fourier transform represents a signal as a sum of waves and gives, for each frequency, the strength of the corresponding wave. For \(N\) samples, the discrete Fourier transform produces \(N\) complex numbers. Computed directly, each of them takes \(N\) multiplications, \(N^2\) in total. The fast Fourier transform (FFT), published by Cooley and Tukey in 1965, divides the problem in halves recursively and needs about \(N \log_2 N\) operations: for \(N\) = 1,024, about 10,240 instead of 1,048,576.
cuFFT works with a plan, which is created once for a given size and kind of transform and can then be executed on any number of arrays of that shape. A plan plays the role of the cuBLAS handle. It holds the choices that cuFFT makes once for a size, such as how to split 1,024 into halves, so that later transforms of that size can skip them. The list of magnitudes, 1 per frequency, is called the spectrum of the signal. For real input, cuFFT returns \(N/2 + 1\) frequencies; the remaining half of the spectrum is a mirror image and carries no additional information. For \(N\) = 1,024, that is 513 frequencies, numbered 0 to 512.
As a test, the program transforms 1,024 samples of \(\sin(50t) + 0.5 \sin(120t)\). The signal consists of 2 waves: 50 cycles over the 1,024 samples with height 1, and 120 cycles with height 0.5. A wave of height \(h\) that completes a whole number of cycles appears as a single frequency of magnitude \(hN/2\). We therefore expect 1 × 1,024 / 2 = 512 at frequency 50, 0.5 × 512 = 256 at frequency 120, and 0, up to rounding, at every other frequency.
Listing 11.14 A plan, then the transform.
fn spectrum(stream: &Arc<CudaStream>) -> Result<bool, Error> {
// ...
let mut plan: c_int = 0;
// SAFETY: `plan` is a valid place for the plan; `x` holds n floats and `spectrum`
// holds `bins` complex numbers, the sizes of a real-to-complex transform of n.
unsafe {
let result = cufftPlan1d(&mut plan, n as c_int, CUFFT_R2C, 1);
ok(result, "cufftPlan1d")?;
let result = cufftSetStream(plan, stream.cu_stream().cast());
ok(result, "cufftSetStream")?;
let result = cufftExecR2C(plan, ptr(&x), ptr(&spectrum));
ok(result, "cufftExecR2C")?;
}
let result = spectrum.to_host_vec(stream)?;
// ...
}// 1,024 samples of sin(50 t) + 0.5 sin(120 t), with t running once around the circle.
// The transform should show 2 peaks, at frequencies 50 and 120, and nothing else.
bool spectrum()
{
// ...
cufftHandle plan;
check(cufftPlan1d(&plan, n, CUFFT_R2C, 1));
check(cufftExecR2C(plan, x, spectrum));
std::vector<cufftComplex> result(bins);
check(cudaMemcpy(result.data(), spectrum, spectrumBytes, cudaMemcpyDeviceToHost));
// ...
}
cuFFT, 1024 samples of sin(50 t) + 0.5 sin(120 t)
frequency 50: magnitude 512.0
frequency 120: magnitude 256.0
PASSED
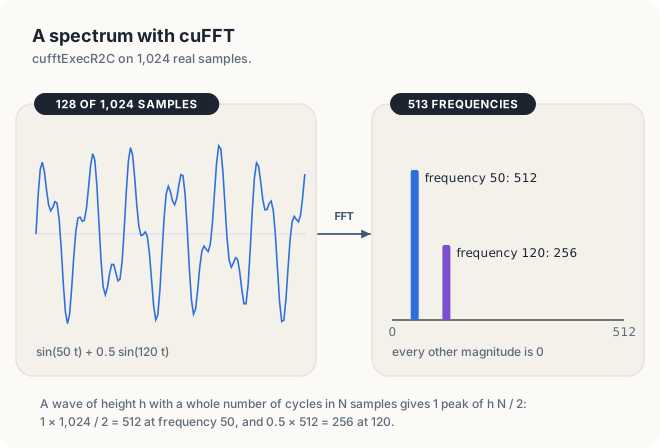
The program prints every frequency whose magnitude exceeds 1. Only the 2 expected frequencies appear, with the expected magnitudes.
11.6 Choosing between a library and a custom kernel
Fig. 11.9 collects the measurements of this chapter for the three algorithms that we also implemented by hand.
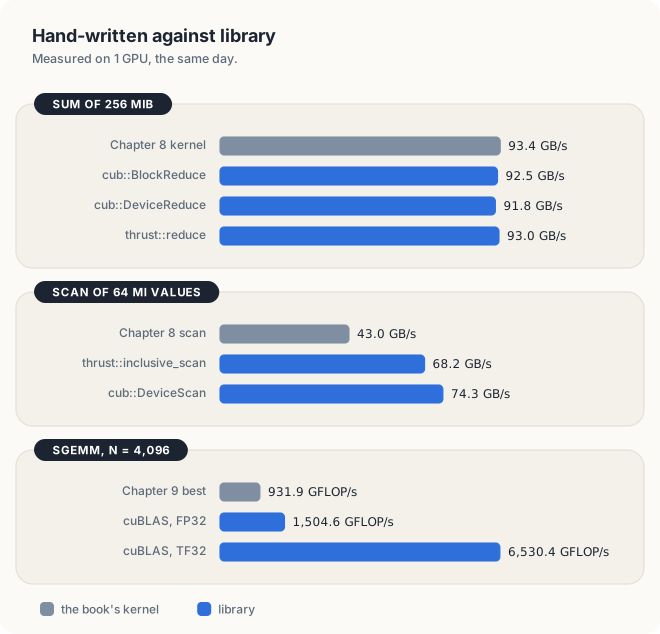
| Problem | Library | Book’s kernel | Measured | Choice |
|---|---|---|---|---|
| sum of a large array | thrust::reduce or CUB | Chapter 8 | 93.0 vs 93.4 GB/s | library: same speed, no code |
| sum of a small array, often | CUB, storage reused, result kept | Chapter 8 | 8.8 µs vs 68.1 µs for thrust::reduce | CUB device-wide call |
| scan | CUB or Thrust | Chapter 8 | 74.3 vs 43.0 GB/s | library: half the bytes |
| sort | CUB radix sort | none | 1,873 Mkeys/s, 180 times 1 CPU core | library |
| SGEMM | cuBLAS | Chapter 9 | 1,505 vs 932 GFLOP/s | library; TF32 if 10 bits suffice |
| a step inside a custom kernel | CUB block level | Chapter 8 | 92.5 vs 93.4 GB/s | CUB inside the kernel |
| a stencil with a halo | none | custom | custom kernel |
The table suggests a sequence of questions to ask when an operation is needed.
- Is the algorithm available in a library? If so, call the library and measure the call. On large inputs, the libraries matched or exceeded every kernel of Part III.
- Is the call slow because of its convenience? On small or repeated inputs, move down a level in Fig. 11.1: use CUB’s device-wide call with temporary storage allocated once and results kept on the GPU, or give Thrust an allocator.
- Does the problem need custom logic for each element? Then write a kernel, but use the block-level primitives of CUB or cuda-oxide inside it. A custom kernel does not have to be written from scratch.
- Is a chain of library calls memory-bound? Each call is a pass over memory. Fuse the
calls, with
transform_reduce, with Thrust’s transform iterators, or with a single custom kernel. A transform iterator is an iterator that applies a functor to each element as it is read, so thatthrust::reduceover a transform iterator that squares its elements computes the sum of squares in 1 pass.
The following 2 examples apply these questions.
Normalizing 100,000,000 floats to the range 0 to 1 requires the smallest and largest
values, followed by 1 multiply-add per element. thrust::minmax_element finds both values
in a single pass that reads 400 MB, and thrust::transform reads the 400 MB again and writes
400 MB of results. The total of 1.2 GB takes about 13 ms at 92 GB/s. A custom kernel cannot
avoid the second pass, because no element can be scaled before the largest value is known,
so it would save nothing.
A 7-point blur of each frame of a video reads 3 neighbors on each side of every pixel. A computation in which each output is computed from a fixed pattern of neighboring inputs is called a stencil, and the inputs that a tile of outputs needs from beyond its own edges are its halo. For a row of 256 pixels, the blur needs 3 more pixels on each side, 262 in all. No library call fits a stencil with a halo of neighbors, so the blur requires a custom kernel. It should read along rows, so that neighboring threads read neighboring pixels (Chapter 7). Tiling in shared memory should be added only if the profiler of Chapter 25 shows the blur to be the slowest stage of the pipeline.
11.7 The complete programs
Listing 11.15 The complete programs for the sums and scans.
//! Chapter 11 in Rust: block_reduce and block_scan, and closures in place of Thrust calls.
//!
//! cargo oxide run
use std::sync::Arc;
use std::time::Instant;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, LaunchConfig1D};
use cuda_device::cooperative_groups::ops::Sum;
use cuda_device::cooperative_groups::{block_reduce, block_scan, this_thread_block};
use cuda_device::{DisjointSlice, SharedArray, cuda_module, device, kernel, launch_contract};
use cuda_device::{thread, warp};
const BLOCK: u32 = 256;
const GRID: u32 = 1024;
type Error = Box<dyn std::error::Error>;
#[cuda_module]
mod kernels {
use super::*;
#[device]
fn warp_sum(mut v: f32) -> f32 {
for offset in [16, 8, 4, 2, 1] {
v += warp::shuffle_down_f32(v, offset);
}
v
}
/// Chapter 8's sum: each warp shuffles, 1 barrier per block, written by hand.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_hand(input: &[f32], mut partial: DisjointSlice<f32>) {
static mut WARPS: SharedArray<f32, 8> = SharedArray::UNINIT;
let stride = (thread::gridDim_x() * BLOCK) as usize;
let lane = warp::lane_id() as usize;
let warp = thread::threadIdx_x() as usize / 32;
let mut sum = 0.0;
let mut i = thread::index_1d().get();
while i < input.len() {
sum += input[i];
i += stride;
}
sum = warp_sum(sum);
if lane == 0 {
// SAFETY: lane 0 of each warp writes its own slot, before the barrier.
unsafe { WARPS[warp] = sum };
}
thread::sync_threads();
if warp == 0 {
// SAFETY: after the barrier the slots are only read.
sum = warp_sum(if lane < 8 { unsafe { WARPS[lane] } } else { 0.0 });
if lane == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = sum };
}
}
}
/// The same sum, with cuda-oxide's block_reduce in place of warp_sum and the slots.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_blocks(input: &[f32], mut partial: DisjointSlice<f32>) {
static mut WARPS: SharedArray<f32, 8> = SharedArray::UNINIT;
let stride = (thread::gridDim_x() * BLOCK) as usize;
let block = this_thread_block();
let mut sum = 0.0;
let mut i = thread::index_1d().get();
while i < input.len() {
sum += input[i];
i += stride;
}
sum = block_reduce::<f32, Sum, 8>(&block, sum, &raw mut WARPS);
if thread::threadIdx_x() == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = sum };
}
}
/// An inclusive scan of each block of 256 values, 1 value per thread.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scan_blocks(input: &[u32], mut out: DisjointSlice<u32>) {
static mut WARPS: SharedArray<u32, 8> = SharedArray::UNINIT;
let block = this_thread_block();
let i = thread::index_1d();
let v = if i.get() < input.len() { input[i.get()] } else { 0 };
let scanned = block_scan::<u32, Sum, 8>(&block, v, &raw mut WARPS);
if let Some(slot) = out.get_mut(i) {
*slot = scanned;
}
}
/// out[i] = f(input[i]), 1 element per thread: the work of thrust::transform.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn map<F>(f: F, input: &[f32], mut out: DisjointSlice<f32>)
where
F: Fn(f32) -> f32 + Copy,
{
let idx = thread::index_1d();
let i = idx.get();
if let Some(slot) = out.get_mut(idx) {
*slot = f(input[i]);
}
}
/// 1 partial sum of f(input[i]) per block, each f(x) kept in a register: the work
/// of thrust::transform_reduce.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn map_sum<F>(f: F, input: &[f32], mut partial: DisjointSlice<f32>)
where
F: Fn(f32) -> f32 + Copy,
{
static mut WARPS: SharedArray<f32, 8> = SharedArray::UNINIT;
let stride = (thread::gridDim_x() * BLOCK) as usize;
let block = this_thread_block();
let mut sum = 0.0;
let mut i = thread::index_1d().get();
while i < input.len() {
sum += f(input[i]);
i += stride;
}
sum = block_reduce::<f32, Sum, 8>(&block, sum, &raw mut WARPS);
if thread::threadIdx_x() == 0 {
let b = thread::blockIdx_x() as usize;
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(b) = sum };
}
}
}
/// Average time of 20 runs of `launch`, in milliseconds, after 1 warm-up run.
fn time_ms(
stream: &Arc<CudaStream>,
mut launch: impl FnMut() -> Result<(), Error>,
) -> Result<f64, Error> {
launch()?;
stream.synchronize()?;
let start = Instant::now();
for _ in 0..20 {
launch()?;
}
stream.synchronize()?;
Ok(start.elapsed().as_secs_f64() * 1e3 / 20.0)
}
/// Numbers from a small linear congruential generator, as in Chapter 8.
fn random(n: usize, seed: u32) -> Vec<u32> {
let mut state = seed;
(0..n)
.map(|_| {
state = state.wrapping_mul(1_664_525).wrapping_add(1_013_904_223);
state
})
.collect()
}
/// The sum of squares of 64 Mi floats in 2 passes and in 1.
fn sums_of_squares(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
values: &[f32],
) -> Result<bool, Error> {
let n = values.len();
let exact: f64 = values.iter().map(|&v| v as f64 * v as f64).sum();
let input = DeviceBuffer::from_host(stream, values)?;
let mut squares = DeviceBuffer::<f32>::zeroed(stream, n)?;
let mut partial = DeviceBuffer::<f32>::zeroed(stream, GRID as usize)?;
let mut total = DeviceBuffer::<f32>::zeroed(stream, 1)?;
let each = module.prepare_map(LaunchConfig1D::new(n as u32 / BLOCK, BLOCK, 0))?;
let grid = module.prepare_map_sum(LaunchConfig1D::new(GRID, BLOCK, 0))?;
let fused = module.prepare_map_sum(LaunchConfig1D::new(GRID, BLOCK, 0))?;
let one = module.prepare_map_sum(LaunchConfig1D::new(1, BLOCK, 0))?;
let square = |v: f32| v * v;
let same = |v: f32| v;
let gb = (n * 4) as f64 / 1e9;
println!("sum of squares, GB/s of input read");
let ms = time_ms(stream, || {
module.map(stream, &each, square, &input, &mut squares)?;
module.map_sum(stream, &grid, same, &squares, &mut partial)?;
Ok(module.map_sum(stream, &one, same, &partial, &mut total)?)
})?;
let two_passes = total.to_host_vec(stream)?[0];
let rate = gb / ms * 1e3;
println!(" map, then map_sum {ms:6.2} ms {rate:6.1} GB/s sum {two_passes:.1}");
let ms = time_ms(stream, || {
module.map_sum(stream, &fused, square, &input, &mut partial)?;
Ok(module.map_sum(stream, &one, same, &partial, &mut total)?)
})?;
let one_pass = total.to_host_vec(stream)?[0];
let rate = gb / ms * 1e3;
println!(" map_sum, fused {ms:6.2} ms {rate:6.1} GB/s sum {one_pass:.1}");
println!(" exact (f64) sum {exact:.1}");
let close = |s: f32| (s as f64 - exact).abs() < 1e-5 * exact;
Ok(close(two_passes) && close(one_pass))
}
/// A sum of 4,096 floats in 3 ways: storage allocated for each sum and the result
/// copied to the host, as thrust::reduce does; storage allocated once and the result
/// copied; storage allocated once and the result kept on the GPU.
fn small_sums(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
values: &[f32],
) -> Result<(), Error> {
let n = 4096;
let blocks = 16;
let input = DeviceBuffer::from_host(stream, &values[..n])?;
let grid = module.prepare_map_sum(LaunchConfig1D::new(blocks, BLOCK, 0))?;
let one = module.prepare_map_sum(LaunchConfig1D::new(1, BLOCK, 0))?;
let same = |v: f32| v;
println!("sum of {n} floats, microseconds per sum");
let ms = time_ms(stream, || {
let mut partial = DeviceBuffer::<f32>::zeroed(stream, blocks as usize)?;
let mut total = DeviceBuffer::<f32>::zeroed(stream, 1)?;
module.map_sum(stream, &grid, same, &input, &mut partial)?;
module.map_sum(stream, &one, same, &partial, &mut total)?;
total.to_host_vec(stream)?;
Ok(())
})?;
println!(" allocated each time, result copied {:6.1} us", ms * 1e3);
let mut partial = DeviceBuffer::<f32>::zeroed(stream, blocks as usize)?;
let mut total = DeviceBuffer::<f32>::zeroed(stream, 1)?;
let ms = time_ms(stream, || {
module.map_sum(stream, &grid, same, &input, &mut partial)?;
module.map_sum(stream, &one, same, &partial, &mut total)?;
total.to_host_vec(stream)?;
Ok(())
})?;
println!(" allocated once, result copied {:6.1} us", ms * 1e3);
let ms = time_ms(stream, || {
module.map_sum(stream, &grid, same, &input, &mut partial)?;
Ok(module.map_sum(stream, &one, same, &partial, &mut total)?)
})?;
println!(" allocated once, result kept {:6.1} us", ms * 1e3);
Ok(())
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let n = 64 << 20;
// 1. A sum of 67,108,864 floats in [0, 1), by hand and with block_reduce.
let values: Vec<f32> = random(n, 1)
.iter()
.map(|&r| (r >> 8) as f32 / 16_777_216.0)
.collect();
let exact: f64 = values.iter().map(|&v| v as f64).sum();
let input = DeviceBuffer::from_host(&stream, &values)?;
let mut partial = DeviceBuffer::<f32>::zeroed(&stream, GRID as usize)?;
let mut total = DeviceBuffer::<f32>::zeroed(&stream, 1)?;
let grid = LaunchConfig1D::new(GRID, BLOCK, 0);
let one = LaunchConfig1D::new(1, BLOCK, 0);
let hand = (module.prepare_sum_hand(grid)?, module.prepare_sum_hand(one)?);
let blocks = (module.prepare_sum_blocks(grid)?, module.prepare_sum_blocks(one)?);
let mut by_hand = || -> Result<(), Error> {
module.sum_hand(&stream, &hand.0, &input, &mut partial)?;
Ok(module.sum_hand(&stream, &hand.1, &partial, &mut total)?)
};
for _ in 0..10 {
time_ms(&stream, &mut by_hand)?; // warm up the clocks
}
let gb = (n * 4) as f64 / 1e9;
println!("sum of {n} floats, average of 20 runs");
let ms = time_ms(&stream, &mut by_hand)?;
let rate = gb / ms * 1e3;
let sum_hand = total.to_host_vec(&stream)?[0];
println!(" Chapter 8, by hand {ms:6.2} ms {rate:6.1} GB/s sum {sum_hand:.1}");
let ms = time_ms(&stream, || {
module.sum_blocks(&stream, &blocks.0, &input, &mut partial)?;
Ok(module.sum_blocks(&stream, &blocks.1, &partial, &mut total)?)
})?;
let rate = gb / ms * 1e3;
let sum_blocks = total.to_host_vec(&stream)?[0];
println!(" block_reduce {ms:6.2} ms {rate:6.1} GB/s sum {sum_blocks:.1}");
println!(" exact (f64) sum {exact:.1}");
// 2. Each block of 256 values 0 to 3, scanned with block_scan.
let counts: Vec<u32> = random(n, 2).iter().map(|&r| r >> 30).collect();
let input = DeviceBuffer::from_host(&stream, &counts)?;
let mut out = DeviceBuffer::<u32>::zeroed(&stream, n)?;
let config = LaunchConfig1D::new((n as u32).div_ceil(BLOCK), BLOCK, 0);
let scan = module.prepare_scan_blocks(config)?;
module.scan_blocks(&stream, &scan, &input, &mut out)?;
let result = out.to_host_vec(&stream)?;
let mut running = 0;
let mut scan_ok = true;
for (i, (&c, &r)) in counts.iter().zip(&result).enumerate() {
if i % BLOCK as usize == 0 {
running = 0;
}
running += c;
scan_ok &= r == running;
}
println!("block_scan of {n} values, 256 per block");
println!(" first block: {:?} ... {}", &result[..8], result[255]);
// 3. The sum of squares in 2 passes and in 1, and 3 ways to sum 4,096 floats.
let squares_ok = sums_of_squares(&module, &stream, &values)?;
small_sums(&module, &stream, &values)?;
let close = |s: f32| (s as f64 - exact).abs() < 1e-5 * exact;
let ok = close(sum_hand) && close(sum_blocks) && scan_ok && squares_ok;
println!("{}", if ok { "PASSED" } else { "FAILED" });
Ok(())
}// Chapter 11: Thrust and CUB against the hand-written sum and scan of Chapter 8.
// Build: nvcc -arch=native -O2 -std=c++17 reduce_scan.cu -o reduce_scan
#include <chrono>
#include <cmath>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cub/cub.cuh>
#include <cuda/std/functional>
#include <cuda_runtime.h>
#include <thrust/execution_policy.h>
#include <thrust/reduce.h>
#include <thrust/scan.h>
#include <thrust/transform.h>
#include <thrust/transform_reduce.h>
const int BLOCK = 256; // threads per block
const int GRID = 1024; // blocks of the hand-written sums
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// Average time of `runs` runs of `run`, in milliseconds, after 1 warm-up run.
template <typename F>
double timeMs(F run, int runs = 20)
{
run();
check(cudaDeviceSynchronize());
double t0 = nowMs();
for (int r = 0; r < runs; ++r) {
run();
}
check(cudaGetLastError());
check(cudaDeviceSynchronize());
return (nowMs() - t0) / runs;
}
unsigned nextRandom(unsigned& state)
{
state = state * 1664525u + 1013904223u;
return state;
}
// Chapter 8's fastest sum: float4 loads, warp shuffles, 1 barrier per block.
__device__ float warpSum(float v)
{
for (int offset = 16; offset > 0; offset /= 2) {
v += __shfl_down_sync(0xffffffff, v, offset);
}
return v;
}
__device__ float blockSum(float v)
{
__shared__ float warps[BLOCK / 32];
int lane = threadIdx.x % 32;
int warp = threadIdx.x / 32;
v = warpSum(v);
if (lane == 0) {
warps[warp] = v;
}
__syncthreads();
if (warp == 0) {
v = warpSum(lane < BLOCK / 32 ? warps[lane] : 0.0f);
}
return v; // the block's total, in thread 0
}
__global__ void sumHand(const float4* in, float* partial, int n4)
{
float sum = 0.0f;
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n4; i += gridDim.x * BLOCK) {
float4 v = in[i];
sum += v.x + v.y + v.z + v.w;
}
sum = blockSum(sum);
if (threadIdx.x == 0) {
partial[blockIdx.x] = sum;
}
}
// The same kernel, with CUB's block reduction in place of warpSum and blockSum.
__global__ void sumCub(const float4* in, float* partial, int n4)
{
using BlockReduce = cub::BlockReduce<float, BLOCK>;
__shared__ BlockReduce::TempStorage temp;
float sum = 0.0f;
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n4; i += gridDim.x * BLOCK) {
float4 v = in[i];
sum += v.x + v.y + v.z + v.w;
}
sum = BlockReduce(temp).Sum(sum);
if (threadIdx.x == 0) {
partial[blockIdx.x] = sum;
}
}
struct Square {
__host__ __device__ float operator()(float v) const { return v * v; }
};
// Prints 1 line of results; true if `sum` is within 1 part in 100,000 of `exact`.
bool report(const char* name, double ms, double bytes, float sum, double exact)
{
double gb = bytes / ms / 1e6;
std::printf(" %-28s %7.2f ms %6.1f GB/s sum %.1f\n", name, ms, gb, sum);
return std::abs(sum - exact) < 1e-5 * exact;
}
float readBack(const float* total)
{
float t;
check(cudaMemcpy(&t, total, sizeof(float), cudaMemcpyDeviceToHost));
return t;
}
bool sums(const float* in, float* partial, float* total, int n, double exact)
{
double bytes = n * 4.0;
const float4* in4 = (const float4*)in;
const float4* partial4 = (const float4*)partial;
std::printf("sum of %d floats (%d MiB), average of 20 runs\n", n, n >> 18);
auto hand = [&] {
sumHand<<<GRID, BLOCK>>>(in4, partial, n / 4);
sumHand<<<1, BLOCK>>>(partial4, total, GRID / 4);
};
double ms = timeMs(hand);
bool ok = report("Chapter 8, float4 + shuffles", ms, bytes, readBack(total), exact);
auto cubBlock = [&] {
sumCub<<<GRID, BLOCK>>>(in4, partial, n / 4);
sumCub<<<1, BLOCK>>>(partial4, total, GRID / 4);
};
ms = timeMs(cubBlock);
ok &= report("same, cub::BlockReduce", ms, bytes, readBack(total), exact);
size_t tempBytes = 0;
cub::DeviceReduce::Sum(nullptr, tempBytes, in, total, n); // asks for the size only
void* temp;
check(cudaMalloc(&temp, tempBytes));
auto cubDevice = [&] { cub::DeviceReduce::Sum(temp, tempBytes, in, total, n); };
ms = timeMs(cubDevice);
ok &= report("cub::DeviceReduce::Sum", ms, bytes, readBack(total), exact);
std::printf(" (CUB asked for %zu bytes of temporary storage)\n", tempBytes);
float t = 0.0f;
auto thrustSum = [&] { t = thrust::reduce(thrust::device, in, in + n, 0.0f); };
ms = timeMs(thrustSum);
ok &= report("thrust::reduce", ms, bytes, t, exact);
check(cudaFree(temp));
return ok;
}
bool sumsOfSquares(const float* in, float* squares, int n, double exact)
{
double bytes = n * 4.0;
Square square;
cuda::std::plus<float> plus;
std::printf("sum of squares, GB/s of input read\n");
float t = 0.0f;
auto twoPasses = [&] {
thrust::transform(thrust::device, in, in + n, squares, square);
t = thrust::reduce(thrust::device, squares, squares + n, 0.0f);
};
double ms = timeMs(twoPasses);
bool ok = report("transform, then reduce", ms, bytes, t, exact);
auto fused = [&] {
t = thrust::transform_reduce(thrust::device, in, in + n, square, 0.0f, plus);
};
ms = timeMs(fused);
ok &= report("transform_reduce", ms, bytes, t, exact);
return ok;
}
void smallSums(const float* in, float* total)
{
const int n = 4096;
float t = 0.0f;
std::printf("sum of %d floats, microseconds per sum\n", n);
auto thrustSum = [&] { t = thrust::reduce(thrust::device, in, in + n, 0.0f); };
std::printf(" thrust::reduce %6.1f us\n", timeMs(thrustSum) * 1e3);
size_t tempBytes = 0;
cub::DeviceReduce::Sum(nullptr, tempBytes, in, total, n);
void* temp;
check(cudaMalloc(&temp, tempBytes));
auto cubAndCopy = [&] {
cub::DeviceReduce::Sum(temp, tempBytes, in, total, n);
check(cudaMemcpy(&t, total, sizeof(float), cudaMemcpyDeviceToHost));
};
double usCopy = timeMs(cubAndCopy) * 1e3;
std::printf(" cub::DeviceReduce, result copied %6.1f us\n", usCopy);
auto cubOnly = [&] { cub::DeviceReduce::Sum(temp, tempBytes, in, total, n); };
double usOnly = timeMs(cubOnly) * 1e3;
std::printf(" cub::DeviceReduce, result kept %6.1f us\n", usOnly);
check(cudaFree(temp));
}
bool scans(int n)
{
std::vector<unsigned> values(n), inclusive(n), result(n);
unsigned state = 2;
unsigned running = 0;
for (int i = 0; i < n; ++i) {
values[i] = nextRandom(state) >> 30; // 0, 1, 2 or 3
running += values[i];
inclusive[i] = running;
}
unsigned *in, *out;
check(cudaMalloc(&in, n * sizeof(unsigned)));
check(cudaMalloc(&out, n * sizeof(unsigned)));
check(cudaMemcpy(in, values.data(), n * sizeof(unsigned), cudaMemcpyHostToDevice));
double bytes = 2.0 * n * sizeof(unsigned); // each value read once, written once
std::printf("scan of %d values 0 to 3, average of 20 runs\n", n);
auto thrustScan = [&] { thrust::inclusive_scan(thrust::device, in, in + n, out); };
double ms = timeMs(thrustScan);
check(cudaMemcpy(result.data(), out, n * sizeof(unsigned), cudaMemcpyDeviceToHost));
bool ok = result == inclusive;
std::printf(" thrust::inclusive_scan %6.2f ms", ms);
std::printf(" %6.1f GB/s", bytes / ms / 1e6);
std::printf(" last %u correct: %s\n", result[n - 1], ok ? "yes" : "no");
size_t tempBytes = 0;
cub::DeviceScan::ExclusiveSum(nullptr, tempBytes, in, out, n);
void* temp;
check(cudaMalloc(&temp, tempBytes));
auto cubScan = [&] { cub::DeviceScan::ExclusiveSum(temp, tempBytes, in, out, n); };
ms = timeMs(cubScan);
check(cudaMemcpy(result.data(), out, n * sizeof(unsigned), cudaMemcpyDeviceToHost));
bool okEx = true;
for (int i = 0; i < n; ++i) {
okEx = okEx && result[i] == inclusive[i] - values[i];
}
std::printf(" cub::DeviceScan::ExclusiveSum %6.2f ms", ms);
std::printf(" %6.1f GB/s", bytes / ms / 1e6);
std::printf(" last %u correct: %s\n", result[n - 1], okEx ? "yes" : "no");
check(cudaFree(temp));
check(cudaFree(in));
check(cudaFree(out));
return ok && okEx;
}
// An inclusive scan of each block of 256 values, 1 value per thread, with CUB.
__global__ void scanBlocks(const unsigned* in, unsigned* out, int n)
{
using BlockScan = cub::BlockScan<unsigned, BLOCK>;
__shared__ BlockScan::TempStorage temp;
int i = blockIdx.x * BLOCK + threadIdx.x;
unsigned v = i < n ? in[i] : 0;
BlockScan(temp).InclusiveSum(v, v);
if (i < n) {
out[i] = v;
}
}
bool blockScans(int n)
{
std::vector<unsigned> values(n), result(n);
unsigned state = 2;
for (int i = 0; i < n; ++i) {
values[i] = nextRandom(state) >> 30; // 0, 1, 2 or 3, as in scans()
}
unsigned *in, *out;
check(cudaMalloc(&in, n * sizeof(unsigned)));
check(cudaMalloc(&out, n * sizeof(unsigned)));
check(cudaMemcpy(in, values.data(), n * sizeof(unsigned), cudaMemcpyHostToDevice));
int blocks = (n + BLOCK - 1) / BLOCK;
scanBlocks<<<blocks, BLOCK>>>(in, out, n);
check(cudaMemcpy(result.data(), out, n * sizeof(unsigned), cudaMemcpyDeviceToHost));
bool ok = true;
unsigned running = 0;
for (int i = 0; i < n; ++i) {
if (i % BLOCK == 0) {
running = 0; // each block starts a scan of its own
}
running += values[i];
ok = ok && result[i] == running;
}
const char* verdict = ok ? "yes" : "no";
std::printf("cub::BlockScan of %d values, 256 per block\n", n);
std::printf(" first block:");
for (int i = 0; i < 8; ++i) {
std::printf(" %u", result[i]);
}
std::printf(" ... %u correct: %s\n", result[BLOCK - 1], verdict);
check(cudaFree(in));
check(cudaFree(out));
return ok;
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %d SMs", prop.name, prop.multiProcessorCount);
std::printf(", L2 cache %d MiB\n", prop.l2CacheSize >> 20);
const int n = 64 << 20; // 67,108,864 floats, 256 MiB
std::vector<float> values(n);
unsigned state = 1;
double exact = 0.0;
double exactSquares = 0.0;
for (int i = 0; i < n; ++i) {
values[i] = (nextRandom(state) >> 8) / 16777216.0f; // in [0, 1), as in Chapter 8
exact += values[i];
exactSquares += double(values[i]) * values[i];
}
float *in, *partial, *total, *squares;
check(cudaMalloc(&in, n * sizeof(float)));
check(cudaMalloc(&partial, GRID * sizeof(float)));
check(cudaMalloc(&total, sizeof(float)));
check(cudaMalloc(&squares, n * sizeof(float)));
check(cudaMemcpy(in, values.data(), n * sizeof(float), cudaMemcpyHostToDevice));
for (int k = 0; k < 10; ++k) { // warm up: clocks rise under sustained load
timeMs([&] { sumHand<<<GRID, BLOCK>>>((const float4*)in, partial, n / 4); });
}
bool ok = sums(in, partial, total, n, exact);
ok &= sumsOfSquares(in, squares, n, exactSquares);
std::printf(" exact (double): sum %.1f, sum of squares %.1f\n", exact, exactSquares);
smallSums(in, total);
check(cudaFree(in));
check(cudaFree(partial));
check(cudaFree(total));
check(cudaFree(squares));
ok &= scans(n);
ok &= blockScans(n);
std::printf("%s\n", ok ? "PASSED" : "FAILED");
}
Listing 11.16 The complete sort.cu. code/ch11_libraries/sort.cu
// Chapter 11: sorting 16 Mi keys with Thrust and CUB, against std::sort on the CPU.
// Build: nvcc -arch=native -O2 -std=c++17 sort.cu -o sort
#include <algorithm>
#include <chrono>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cub/cub.cuh>
#include <cuda/std/functional>
#include <cuda_runtime.h>
#include <thrust/execution_policy.h>
#include <thrust/sort.h>
using Keys = std::vector<unsigned>;
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
unsigned nextRandom(unsigned& state)
{
state = state * 1664525u + 1013904223u;
return state;
}
// The same order as thrust::less, but Thrust cannot see inside it, so it cannot use a
// radix sort and falls back to a merge sort, which only compares keys.
struct Ascending {
__host__ __device__ bool operator()(unsigned a, unsigned b) const { return a < b; }
};
// Scratch memory for Thrust, allocated once. During a call Thrust asks for temporary
// buffers and gives them all back before it returns. The arena hands out pieces of 1
// large buffer, and starts again from its beginning when every piece is back.
struct Arena {
using value_type = char;
char* base = nullptr;
size_t size = 0;
size_t used = 0;
int live = 0;
char* allocate(std::ptrdiff_t bytes)
{
size_t start = (used + 255) / 256 * 256; // 256-byte aligned
if (start + bytes > size) {
std::fprintf(stderr, "arena too small for %td bytes\n", bytes);
std::exit(1);
}
used = start + bytes;
++live;
return base + start;
}
void deallocate(char*, size_t)
{
--live;
if (live == 0) {
used = 0;
}
}
};
// Average time of 5 sorts, in milliseconds. Each sort starts from a fresh copy of
// `original`; only the sort itself is timed.
template <typename F>
double timeSort(F sort, unsigned* keys, const unsigned* original, int n)
{
double total = 0.0;
for (int r = 0; r < 6; ++r) {
check(cudaMemcpy(keys, original, n * 4, cudaMemcpyDeviceToDevice));
check(cudaDeviceSynchronize());
double t0 = nowMs();
sort();
check(cudaDeviceSynchronize());
if (r > 0) { // run 0 warms up
total += nowMs() - t0;
}
}
return total / 5;
}
bool report(const char* name, double ms, int n, const unsigned* keys, const Keys& expected)
{
Keys got(n);
check(cudaMemcpy(got.data(), keys, n * 4, cudaMemcpyDeviceToHost));
bool ok = got == expected;
double rate = n / ms / 1e3; // millions of keys per second
std::printf(" %-34s %7.2f ms %7.1f Mkeys/s", name, ms, rate);
std::printf(" correct: %s\n", ok ? "yes" : "no");
return ok;
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %d SMs\n", prop.name, prop.multiProcessorCount);
const int n = 16 << 20; // 16,777,216 keys of 32 bits, 64 MiB
Keys random(n), small(n);
unsigned state = 5;
for (int i = 0; i < n; ++i) {
random[i] = nextRandom(state);
small[i] = random[i] >> 24; // keys 0 to 255: only 8 bits differ
}
Keys ascending = random;
double t0 = nowMs();
std::sort(ascending.begin(), ascending.end());
double cpuMs = nowMs() - t0;
Keys descending(ascending.rbegin(), ascending.rend());
Keys smallSorted = small;
std::sort(smallSorted.begin(), smallSorted.end());
unsigned *original, *keys, *sorted;
check(cudaMalloc(&original, n * 4));
check(cudaMalloc(&keys, n * 4));
check(cudaMalloc(&sorted, n * 4));
check(cudaMemcpy(original, random.data(), n * 4, cudaMemcpyHostToDevice));
std::printf("sort of %d random 32-bit keys, average of 5 runs\n", n);
double cpuRate = n / cpuMs / 1e3;
std::printf(" %-34s %7.2f ms", "std::sort, 1 CPU core", cpuMs);
std::printf(" %7.1f Mkeys/s\n", cpuRate);
auto plain = [&] { thrust::sort(thrust::device, keys, keys + n); };
double ms = timeSort(plain, keys, original, n);
bool ok = report("thrust::sort", ms, n, keys, ascending);
Arena arena;
arena.size = 2 * size_t(n) * 4;
check(cudaMalloc(&arena.base, arena.size));
auto policy = thrust::cuda::par(arena);
auto radix = [&] { thrust::sort(policy, keys, keys + n); };
ms = timeSort(radix, keys, original, n);
ok &= report("thrust::sort, scratch reused", ms, n, keys, ascending);
cuda::std::greater<unsigned> greater;
auto down = [&] { thrust::sort(policy, keys, keys + n, greater); };
ms = timeSort(down, keys, original, n);
ok &= report(" ... with cuda::std::greater", ms, n, keys, descending);
auto merge = [&] { thrust::sort(policy, keys, keys + n, Ascending()); };
ms = timeSort(merge, keys, original, n);
ok &= report(" ... with own comparison", ms, n, keys, ascending);
size_t tempBytes = 0;
cub::DeviceRadixSort::SortKeys(nullptr, tempBytes, keys, sorted, n);
void* temp;
check(cudaMalloc(&temp, tempBytes));
auto all32 = [&] { cub::DeviceRadixSort::SortKeys(temp, tempBytes, keys, sorted, n); };
ms = timeSort(all32, keys, original, n);
ok &= report("cub::DeviceRadixSort", ms, n, sorted, ascending);
check(cudaMemcpy(original, small.data(), n * 4, cudaMemcpyHostToDevice));
std::printf("sort of %d keys from 0 to 255\n", n);
ms = timeSort(all32, keys, original, n);
ok &= report("cub::DeviceRadixSort, bits 0 to 31", ms, n, sorted, smallSorted);
auto low8 = [&] {
cub::DeviceRadixSort::SortKeys(temp, tempBytes, keys, sorted, n, 0, 8);
};
ms = timeSort(low8, keys, original, n);
ok &= report("cub::DeviceRadixSort, bits 0 to 7", ms, n, sorted, smallSorted);
check(cudaFree(temp));
check(cudaFree(arena.base));
check(cudaFree(original));
check(cudaFree(keys));
check(cudaFree(sorted));
std::printf("%s\n", ok ? "PASSED" : "FAILED");
}
The sort has no Rust program, because cuda-oxide provides no sort (Section 11.2.4).
Listing 11.17 The complete cuBLAS programs.
//! Chapter 11 in Rust: cuBLAS called through its C interface, with row-major matrices,
//! then SGEMM in FP32 and on tensor cores.
//!
//! cargo oxide run --bin gemm
use std::ffi::{c_int, c_void};
use std::sync::Arc;
use std::time::Instant;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer};
const N: usize = 4096; // the matrix size of Chapter 9
type Error = Box<dyn std::error::Error>;
/// A cuBLAS handle: a pointer to state that only cuBLAS reads.
type Handle = *mut c_void;
const CUBLAS_OP_N: c_int = 0;
const CUBLAS_TF32_TENSOR_OP_MATH: c_int = 3;
#[link(name = "cublas")]
unsafe extern "C" {
fn cublasCreate_v2(handle: *mut Handle) -> c_int;
fn cublasSetStream_v2(handle: Handle, stream: *mut c_void) -> c_int;
fn cublasSetMathMode(handle: Handle, mode: c_int) -> c_int;
fn cublasDestroy_v2(handle: Handle) -> c_int;
fn cublasSgemm_v2(
handle: Handle,
op_a: c_int,
op_b: c_int,
m: c_int,
n: c_int,
k: c_int,
alpha: *const f32,
a: *const f32,
lda: c_int,
b: *const f32,
ldb: c_int,
beta: *const f32,
c: *mut f32,
ldc: c_int,
) -> c_int;
}
/// cuBLAS returns 0 for success and an error number otherwise.
fn ok(result: c_int, call: &str) -> Result<(), Error> {
if result == 0 {
return Ok(());
}
Err(format!("{call} failed with cuBLAS error {result}").into())
}
/// The device address of a buffer, as the pointer type cuBLAS takes.
fn ptr(buffer: &DeviceBuffer<f32>) -> *mut f32 {
buffer.cu_deviceptr() as *mut f32
}
/// Average time of `runs` runs of `launch`, in milliseconds, after 1 warm-up run.
fn time_ms<F>(stream: &CudaStream, runs: u32, mut launch: F) -> Result<f64, Error>
where
F: FnMut() -> Result<(), Error>,
{
launch()?;
stream.synchronize()?;
let start = Instant::now();
for _ in 0..runs {
launch()?;
}
stream.synchronize()?;
Ok(start.elapsed().as_secs_f64() * 1e3 / runs as f64)
}
/// 1 row of a matrix as text, its values separated by spaces.
fn row_text(row: &[f32]) -> String {
let values: Vec<String> = row.iter().map(|v| v.to_string()).collect();
values.join(" ")
}
fn print(name: &str, m: &[f32], rows: usize, cols: usize) {
let lines: Vec<String> = m.chunks(cols).take(rows).map(row_text).collect();
println!(" {name} = [{}]", lines.join("; "));
}
/// C = A B for a 2 x 3 matrix A and a 3 x 2 matrix B, all stored row by row.
fn small_product(handle: Handle, stream: &Arc<CudaStream>) -> Result<bool, Error> {
let a = [1.0, 2.0, 3.0, 4.0, 5.0, 6.0];
let b = [7.0, 8.0, 9.0, 10.0, 11.0, 12.0];
let expected = [58.0, 64.0, 139.0, 154.0];
let a_dev = DeviceBuffer::from_host(stream, &a)?;
let b_dev = DeviceBuffer::from_host(stream, &b)?;
let c_dev = DeviceBuffer::<f32>::zeroed(stream, 4)?;
let (pa, pb, pc) = (ptr(&a_dev), ptr(&b_dev), ptr(&c_dev));
let (one, zero) = (1.0f32, 0.0f32);
let op = CUBLAS_OP_N;
println!("C = A B with A 2 x 3 and B 3 x 2, stored row by row");
print("A", &a, 2, 3);
print("B", &b, 3, 2);
// Wrong: cuBLAS reads each array column by column.
// SAFETY: the 3 pointers address live buffers of 6, 6 and 4 floats, enough for the
// sizes and leading dimensions given.
let result = unsafe {
cublasSgemm_v2(handle, op, op, 2, 2, 3, &one, pa, 2, pb, 3, &zero, pc, 2)
};
ok(result, "cublasSgemm")?;
let c = c_dev.to_host_vec(stream)?;
print("C, operands as given ", &c, 2, 2);
// Right: in column-major terms our arrays hold A^T and B^T. Ask for B^T A^T = C^T,
// whose column-major storage is C row by row.
// SAFETY: as above.
let result = unsafe {
cublasSgemm_v2(handle, op, op, 2, 2, 3, &one, pb, 2, pa, 3, &zero, pc, 2)
};
ok(result, "cublasSgemm")?;
let c = c_dev.to_host_vec(stream)?;
print("C, operands swapped ", &c, 2, 2);
Ok(c == expected)
}
/// Values in [-0.5, 0.5) from a small linear congruential generator, as in Chapter 9.
fn random_matrix(state: &mut u32) -> Vec<f32> {
let mut m = Vec::with_capacity(N * N);
for _ in 0..N * N {
*state = state.wrapping_mul(1_664_525).wrapping_add(1_013_904_223);
m.push((*state >> 8) as f32 / 16_777_216.0 - 0.5);
}
m
}
/// Element (i, j) of A B, computed in double precision.
fn exact_element(a: &[f32], b: &[f32], i: usize, j: usize) -> f64 {
let mut sum = 0.0;
for k in 0..N {
sum += a[i * N + k] as f64 * b[k * N + j] as f64;
}
sum
}
/// The largest difference from a double-precision product, over 64 elements of C.
fn max_error(a: &[f32], b: &[f32], c: &[f32]) -> f64 {
let mut worst: f64 = 0.0;
for s in 0..64 {
let i = s * 977 % N;
let j = (s * 1231 + 7) % N;
let exact = exact_element(a, b, i, j);
let error = (exact - c[i * N + j] as f64).abs();
worst = worst.max(error);
}
worst
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
println!("GPU: {}", ctx.device_name()?);
let start = Instant::now();
let mut handle: Handle = std::ptr::null_mut();
// SAFETY: `handle` is a valid place for cuBLAS to store its handle.
let result = unsafe { cublasCreate_v2(&mut handle) };
ok(result, "cublasCreate")?;
println!("cublasCreate took {:.1} ms", start.elapsed().as_secs_f64() * 1e3);
// SAFETY: the handle is live, and the stream lives until the program ends.
let result = unsafe { cublasSetStream_v2(handle, stream.cu_stream().cast()) };
ok(result, "cublasSetStream")?;
let mut passed = small_product(handle, &stream)?;
let mut state = 1;
let a = random_matrix(&mut state);
let b = random_matrix(&mut state);
let a_dev = DeviceBuffer::from_host(&stream, &a)?;
let b_dev = DeviceBuffer::from_host(&stream, &b)?;
let c_dev = DeviceBuffer::<f32>::zeroed(&stream, N * N)?;
let (pa, pb, pc) = (ptr(&a_dev), ptr(&b_dev), ptr(&c_dev));
let (one, zero) = (1.0f32, 0.0f32);
let op = CUBLAS_OP_N;
let n = N as c_int;
let mut gemm = || -> Result<(), Error> {
// SAFETY: the 3 pointers address live buffers of N x N floats.
let result = unsafe {
cublasSgemm_v2(handle, op, op, n, n, n, &one, pb, n, pa, n, &zero, pc, n)
};
ok(result, "cublasSgemm")
};
let report = |name: &str, ms: f64| -> Result<f64, Error> {
let c = c_dev.to_host_vec(&stream)?;
let gflops = 2.0 * (N * N * N) as f64 / ms / 1e6;
let error = max_error(&a, &b, &c);
println!(" {name:<22} {ms:8.2} ms {gflops:7.1} GFLOP/s max error {error:.1e}");
Ok(error)
};
for _ in 0..10 {
time_ms(&stream, 5, &mut gemm)?; // warm up: clocks rise under sustained load
}
println!("C = A B, {N} x {N} floats, average of 10 runs");
let ms = time_ms(&stream, 10, &mut gemm)?;
let fp32 = report("cuBLAS, FP32", ms)?;
// SAFETY: the handle is live.
let result = unsafe { cublasSetMathMode(handle, CUBLAS_TF32_TENSOR_OP_MATH) };
ok(result, "cublasSetMathMode")?;
let ms = time_ms(&stream, 10, &mut gemm)?;
let tf32 = report("cuBLAS, TF32 tensor", ms)?;
passed &= fp32 < 1e-3 && tf32 < 1e-2;
let verdict = if passed { "PASSED" } else { "FAILED" };
println!("{verdict}");
// SAFETY: the handle is live and is not used after this call.
let result = unsafe { cublasDestroy_v2(handle) };
ok(result, "cublasDestroy")?;
Ok(())
}// Chapter 11: cuBLAS with row-major matrices, then SGEMM in FP32 and on tensor cores.
// Build: nvcc -arch=native -O2 gemm.cu -o gemm -lcublas
#include <chrono>
#include <cmath>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cublas_v2.h>
#include <cuda_runtime.h>
using Matrix = std::vector<float>;
const int N = 4096; // the size of Chapter 9
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
void check(cublasStatus_t status)
{
if (status != CUBLAS_STATUS_SUCCESS) {
std::fprintf(stderr, "cuBLAS error: %s\n", cublasGetStatusString(status));
std::exit(1);
}
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// Average time of `runs` runs of `launch`, in milliseconds, after 1 warm-up run.
template <typename F>
double timeMs(F launch, int runs)
{
launch();
check(cudaDeviceSynchronize());
double t0 = nowMs();
for (int r = 0; r < runs; ++r) {
launch();
}
check(cudaDeviceSynchronize());
return (nowMs() - t0) / runs;
}
void print(const char* name, const Matrix& m, int rows, int cols)
{
std::printf(" %s =", name);
for (int i = 0; i < rows; ++i) {
std::printf(i == 0 ? " [" : "; ");
for (int j = 0; j < cols; ++j) {
std::printf(j == 0 ? "%g" : " %g", m[i * cols + j]);
}
}
std::printf("]\n");
}
// C = A B for a 2 x 3 matrix A and a 3 x 2 matrix B, all stored row by row.
bool smallProduct(cublasHandle_t handle)
{
Matrix a = {1, 2, 3,
4, 5, 6};
Matrix b = {7, 8,
9, 10,
11, 12};
Matrix expected = {58, 64,
139, 154};
Matrix c(4);
float *A, *B, *C;
check(cudaMalloc(&A, 6 * sizeof(float)));
check(cudaMalloc(&B, 6 * sizeof(float)));
check(cudaMalloc(&C, 4 * sizeof(float)));
check(cudaMemcpy(A, a.data(), 6 * sizeof(float), cudaMemcpyHostToDevice));
check(cudaMemcpy(B, b.data(), 6 * sizeof(float), cudaMemcpyHostToDevice));
float one = 1.0f, zero = 0.0f;
auto op = CUBLAS_OP_N;
std::printf("C = A B with A 2 x 3 and B 3 x 2, stored row by row\n");
print("A", a, 2, 3);
print("B", b, 3, 2);
// Wrong: cuBLAS reads each array column by column.
check(cublasSgemm(handle, op, op, 2, 2, 3, &one, A, 2, B, 3, &zero, C, 2));
check(cudaMemcpy(c.data(), C, 4 * sizeof(float), cudaMemcpyDeviceToHost));
print("C, operands as given ", c, 2, 2);
// Right: in column-major terms our arrays hold A^T and B^T. Ask for B^T A^T = C^T,
// whose column-major storage is C row by row.
check(cublasSgemm(handle, op, op, 2, 2, 3, &one, B, 2, A, 3, &zero, C, 2));
check(cudaMemcpy(c.data(), C, 4 * sizeof(float), cudaMemcpyDeviceToHost));
print("C, operands swapped ", c, 2, 2);
check(cudaFree(A));
check(cudaFree(B));
check(cudaFree(C));
return c == expected;
}
// Values in [-0.5, 0.5) from a small linear congruential generator, as in Chapter 9.
void fillRandom(Matrix& m, unsigned& state)
{
for (float& v : m) {
state = state * 1664525u + 1013904223u;
v = (state >> 8) / 16777216.0f - 0.5f;
}
}
// The largest difference from a double-precision product, over 64 elements of C.
double maxError(const Matrix& a, const Matrix& b, const Matrix& c)
{
double worst = 0.0;
for (int s = 0; s < 64; ++s) {
int i = s * 977 % N;
int j = (s * 1231 + 7) % N;
double exact = 0.0;
for (int k = 0; k < N; ++k) {
exact += double(a[i * N + k]) * b[k * N + j];
}
worst = std::fmax(worst, std::fabs(exact - c[i * N + j]));
}
return worst;
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %d SMs\n", prop.name, prop.multiProcessorCount);
check(cudaFree(nullptr)); // create the CUDA context before timing
double t0 = nowMs();
cublasHandle_t handle;
check(cublasCreate(&handle));
std::printf("cublasCreate took %.1f ms\n", nowMs() - t0);
bool ok = smallProduct(handle);
Matrix a(N * N), b(N * N), c(N * N);
unsigned state = 1;
fillRandom(a, state);
fillRandom(b, state);
size_t bytes = size_t(N) * N * sizeof(float);
float *A, *B, *C;
check(cudaMalloc(&A, bytes));
check(cudaMalloc(&B, bytes));
check(cudaMalloc(&C, bytes));
check(cudaMemcpy(A, a.data(), bytes, cudaMemcpyHostToDevice));
check(cudaMemcpy(B, b.data(), bytes, cudaMemcpyHostToDevice));
float one = 1.0f, zero = 0.0f;
auto op = CUBLAS_OP_N;
auto gemm = [&] {
check(cublasSgemm(handle, op, op, N, N, N, &one, B, N, A, N, &zero, C, N));
};
auto report = [&](const char* name, double ms) {
check(cudaMemcpy(c.data(), C, bytes, cudaMemcpyDeviceToHost));
double gflops = 2.0 * N * N * N / ms / 1e6;
double error = maxError(a, b, c);
std::printf(" %-22s %8.2f ms %7.1f GFLOP/s", name, ms, gflops);
std::printf(" max error %.1e\n", error);
return error;
};
for (int k = 0; k < 10; ++k) { // warm up: clocks rise under sustained load
timeMs(gemm, 5);
}
std::printf("C = A B, %d x %d floats, average of 10 runs\n", N, N);
double fp32 = report("cuBLAS, FP32", timeMs(gemm, 10));
check(cublasSetMathMode(handle, CUBLAS_TF32_TENSOR_OP_MATH));
double tf32 = report("cuBLAS, TF32 tensor", timeMs(gemm, 10));
ok = ok && fp32 < 1e-3 && tf32 < 1e-2;
std::printf("%s\n", ok ? "PASSED" : "FAILED");
check(cublasDestroy(handle));
check(cudaFree(A));
check(cudaFree(B));
check(cudaFree(C));
}
Listing 11.18 The complete cuRAND and cuFFT programs.
//! Chapter 11 in Rust: random numbers with cuRAND, and the frequencies in a signal with
//! cuFFT, both called through their C interfaces.
//!
//! cargo oxide run --bin fft_rand
use std::ffi::{c_int, c_void};
use std::sync::Arc;
use std::time::Instant;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer};
type Error = Box<dyn std::error::Error>;
/// A cuRAND generator: a pointer to state that only cuRAND reads.
type Generator = *mut c_void;
const CURAND_RNG_PSEUDO_PHILOX4_32_10: c_int = 161;
const CUFFT_R2C: c_int = 0x2a;
#[link(name = "curand")]
unsafe extern "C" {
fn curandCreateGenerator(generator: *mut Generator, kind: c_int) -> c_int;
fn curandSetPseudoRandomGeneratorSeed(generator: Generator, seed: u64) -> c_int;
fn curandSetStream(generator: Generator, stream: *mut c_void) -> c_int;
fn curandGenerateNormal(
generator: Generator,
out: *mut f32,
n: usize,
mean: f32,
sd: f32,
) -> c_int;
fn curandDestroyGenerator(generator: Generator) -> c_int;
}
#[link(name = "cufft")]
unsafe extern "C" {
fn cufftPlan1d(plan: *mut c_int, n: c_int, kind: c_int, batch: c_int) -> c_int;
fn cufftSetStream(plan: c_int, stream: *mut c_void) -> c_int;
fn cufftExecR2C(plan: c_int, input: *mut f32, output: *mut f32) -> c_int;
fn cufftDestroy(plan: c_int) -> c_int;
}
/// cuRAND and cuFFT return 0 for success and an error number otherwise.
fn ok(result: c_int, call: &str) -> Result<(), Error> {
if result == 0 {
return Ok(());
}
Err(format!("{call} failed with error {result}").into())
}
/// The device address of a buffer, as the pointer type the C libraries take.
fn ptr(buffer: &DeviceBuffer<f32>) -> *mut f32 {
buffer.cu_deviceptr() as *mut f32
}
/// 16 Mi numbers from the normal distribution; their mean should be near 0 and their
/// standard deviation near 1.
fn normal_numbers(stream: &Arc<CudaStream>) -> Result<bool, Error> {
let n: usize = 16 << 20;
let x = DeviceBuffer::<f32>::zeroed(stream, n)?;
let mut generator: Generator = std::ptr::null_mut();
let kind = CURAND_RNG_PSEUDO_PHILOX4_32_10;
let out = ptr(&x);
// SAFETY: `generator` is a valid place for cuRAND to store its generator; `out`
// addresses n floats; the stream outlives the generator.
let ms = unsafe {
let result = curandCreateGenerator(&mut generator, kind);
ok(result, "curandCreateGenerator")?;
let result = curandSetPseudoRandomGeneratorSeed(generator, 2024);
ok(result, "curandSetPseudoRandomGeneratorSeed")?;
let result = curandSetStream(generator, stream.cu_stream().cast());
ok(result, "curandSetStream")?;
let result = curandGenerateNormal(generator, out, n, 0.0, 1.0); // warm-up
ok(result, "curandGenerateNormal")?;
stream.synchronize()?;
let start = Instant::now();
let result = curandGenerateNormal(generator, out, n, 0.0, 1.0);
ok(result, "curandGenerateNormal")?;
stream.synchronize()?;
start.elapsed().as_secs_f64() * 1e3
};
// The 2 sums that the C++ program computes with Thrust, here on the host.
let numbers = x.to_host_vec(stream)?;
let sum: f64 = numbers.iter().map(|&v| v as f64).sum();
let sum_of_squares: f64 = numbers.iter().map(|&v| v as f64 * v as f64).sum();
let mean = sum / n as f64;
let sd = (sum_of_squares / n as f64 - mean * mean).sqrt();
let rate = n as f64 / ms / 1e3;
println!("cuRAND, {n} normal numbers in {ms:.2} ms ({rate:.0} million per second)");
println!(" mean {mean:.5}, standard deviation {sd:.5}");
// SAFETY: the generator is live and is not used after this call.
let result = unsafe { curandDestroyGenerator(generator) };
ok(result, "curandDestroyGenerator")?;
let mean_ok = mean.abs() < 1e-3;
let sd_ok = (sd - 1.0).abs() < 1e-3;
Ok(mean_ok && sd_ok)
}
/// 1 sample of sin(50 t) + 0.5 sin(120 t), at step t of n around the circle.
fn sample(t: usize, n: usize) -> f32 {
let angle = 2.0 * std::f64::consts::PI * t as f64 / n as f64;
let wave = (50.0 * angle).sin() + 0.5 * (120.0 * angle).sin();
wave as f32
}
/// 1,024 samples of sin(50 t) + 0.5 sin(120 t), with t running once around the circle.
/// The transform should show 2 peaks, at frequencies 50 and 120, and nothing else.
fn spectrum(stream: &Arc<CudaStream>) -> Result<bool, Error> {
let n = 1024;
let bins = n / 2 + 1; // a real signal needs only half the spectrum
let signal: Vec<f32> = (0..n).map(|t| sample(t, n)).collect();
let x = DeviceBuffer::from_host(stream, &signal)?;
let spectrum = DeviceBuffer::<f32>::zeroed(stream, 2 * bins)?; // (re, im) pairs
let mut plan: c_int = 0;
// SAFETY: `plan` is a valid place for the plan; `x` holds n floats and `spectrum`
// holds `bins` complex numbers, the sizes of a real-to-complex transform of n.
unsafe {
let result = cufftPlan1d(&mut plan, n as c_int, CUFFT_R2C, 1);
ok(result, "cufftPlan1d")?;
let result = cufftSetStream(plan, stream.cu_stream().cast());
ok(result, "cufftSetStream")?;
let result = cufftExecR2C(plan, ptr(&x), ptr(&spectrum));
ok(result, "cufftExecR2C")?;
}
let result = spectrum.to_host_vec(stream)?;
println!("cuFFT, {n} samples of sin(50 t) + 0.5 sin(120 t)");
let mut peaks = 0;
let mut passed = true;
for (f, pair) in result.chunks(2).enumerate() {
let size = (pair[0] as f64).hypot(pair[1] as f64);
if size <= 1.0 {
continue;
}
println!(" frequency {f:3}: magnitude {size:.1}");
peaks += 1;
passed &= f == 50 || f == 120;
}
// SAFETY: the plan is live and is not used after this call.
let result = unsafe { cufftDestroy(plan) };
ok(result, "cufftDestroy")?;
Ok(passed && peaks == 2)
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
let mut passed = normal_numbers(&stream)?;
passed &= spectrum(&stream)?;
let verdict = if passed { "PASSED" } else { "FAILED" };
println!("{verdict}");
Ok(())
}// Chapter 11: random numbers with cuRAND, and the frequencies in a signal with cuFFT.
// Build: nvcc -arch=native -O2 fft_rand.cu -o fft_rand -lcurand -lcufft
#include <cmath>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cuda/std/functional>
#include <cuda_runtime.h>
#include <cufft.h>
#include <curand.h>
#include <thrust/execution_policy.h>
#include <thrust/reduce.h>
#include <thrust/transform_reduce.h>
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
void check(curandStatus_t status)
{
if (status != CURAND_STATUS_SUCCESS) {
std::fprintf(stderr, "cuRAND error %d\n", int(status));
std::exit(1);
}
}
void check(cufftResult status)
{
if (status != CUFFT_SUCCESS) {
std::fprintf(stderr, "cuFFT error %d\n", int(status));
std::exit(1);
}
}
struct Square {
__host__ __device__ float operator()(float v) const { return v * v; }
};
// 16 Mi numbers from the normal distribution; their mean should be near 0 and their
// standard deviation near 1.
bool normalNumbers()
{
const int n = 16 << 20;
float* x;
check(cudaMalloc(&x, n * sizeof(float)));
curandGenerator_t gen;
check(curandCreateGenerator(&gen, CURAND_RNG_PSEUDO_PHILOX4_32_10));
check(curandSetPseudoRandomGeneratorSeed(gen, 2024));
cudaEvent_t start, stop;
check(cudaEventCreate(&start));
check(cudaEventCreate(&stop));
check(curandGenerateNormal(gen, x, n, 0.0f, 1.0f)); // warm-up
check(cudaEventRecord(start));
check(curandGenerateNormal(gen, x, n, 0.0f, 1.0f));
check(cudaEventRecord(stop));
check(cudaEventSynchronize(stop));
float ms;
check(cudaEventElapsedTime(&ms, start, stop));
Square square;
cuda::std::plus<float> plus;
float sum = thrust::reduce(thrust::device, x, x + n, 0.0f);
float squares = thrust::transform_reduce(thrust::device, x, x + n, square, 0.0f, plus);
double mean = sum / n;
double sd = std::sqrt(squares / n - mean * mean);
std::printf("cuRAND, %d normal numbers in %.2f ms", n, ms);
std::printf(" (%.0f million per second)\n", n / ms / 1e3);
std::printf(" mean %.5f, standard deviation %.5f\n", mean, sd);
check(curandDestroyGenerator(gen));
check(cudaEventDestroy(start));
check(cudaEventDestroy(stop));
check(cudaFree(x));
return std::fabs(mean) < 1e-3 && std::fabs(sd - 1.0) < 1e-3;
}
// 1,024 samples of sin(50 t) + 0.5 sin(120 t), with t running once around the circle.
// The transform should show 2 peaks, at frequencies 50 and 120, and nothing else.
bool spectrum()
{
const int n = 1024;
const int bins = n / 2 + 1; // a real signal needs only half the spectrum
const double pi = 3.14159265358979323846;
std::vector<float> signal(n);
for (int t = 0; t < n; ++t) {
double angle = 2.0 * pi * t / n;
signal[t] = std::sin(50 * angle) + 0.5 * std::sin(120 * angle);
}
size_t spectrumBytes = bins * sizeof(cufftComplex);
float* x;
cufftComplex* spectrum;
check(cudaMalloc(&x, n * sizeof(float)));
check(cudaMalloc(&spectrum, spectrumBytes));
check(cudaMemcpy(x, signal.data(), n * sizeof(float), cudaMemcpyHostToDevice));
cufftHandle plan;
check(cufftPlan1d(&plan, n, CUFFT_R2C, 1));
check(cufftExecR2C(plan, x, spectrum));
std::vector<cufftComplex> result(bins);
check(cudaMemcpy(result.data(), spectrum, spectrumBytes, cudaMemcpyDeviceToHost));
std::printf("cuFFT, %d samples of sin(50 t) + 0.5 sin(120 t)\n", n);
int peaks = 0;
bool ok = true;
for (int f = 0; f < bins; ++f) {
double size = std::hypot(result[f].x, result[f].y);
if (size > 1.0) {
std::printf(" frequency %3d: magnitude %.1f\n", f, size);
++peaks;
ok = ok && (f == 50 || f == 120);
}
}
check(cufftDestroy(plan));
check(cudaFree(x));
check(cudaFree(spectrum));
return ok && peaks == 2;
}
int main()
{
bool ok = normalNumbers();
ok &= spectrum();
std::printf("%s\n", ok ? "PASSED" : "FAILED");
}
The 3 Rust programs run with cargo oxide run, cargo oxide run --bin gemm and
cargo oxide run --bin fft_rand in code/oxide/ch11_blocks.
Common mistakes
- Passing row-major data to cuBLAS unchanged. The result is the product of 2 different matrices, and no error is reported. Swap the operands, and check a non-square case by hand.
- Testing only with square matrices. With \(m = n = k\), a wrong leading dimension can go unnoticed; the 2 × 3 example of Section 11.4.2 exposes it.
- Calling a library in a loop over small inputs. Each
thrust::reducecall allocated, waited and copied: 68.1 µs for 0.18 µs of reading. Reuse temporary storage and keep results on the GPU. - Creating a cuBLAS handle for every call.
cublasCreatetook 13 to 22 ms. - Chaining Thrust calls on memory-bound data. Every call is a pass over memory; fuse them.
- Assuming the fast path. A custom comparison, or a standard one that the library version does not recognize, turned a radix sort into a merge sort at half the speed.
- Leaving TF32 enabled where 7 digits are needed. TF32 multiplies with 10-bit mantissas; the SGEMM error grew from 1.9 × 10⁻⁵ to 4.0 × 10⁻³.
- Sorting all 32 bits of keys that use 8.
begin_bitandend_bitreduce the number of passes from 4 to 1.
Summary
- Thrust provides whole-array algorithms called from the host. CUB provides the same algorithms with temporary storage managed by the caller, as well as primitives for use inside a kernel. cuBLAS, cuFFT and cuRAND work through a handle or a plan created once.
- On 256 MiB,
thrust::reduce, CUB and the best kernel of Chapter 8 all ran at 92 to 93 GB/s. Memory-bound work runs at the speed of the memory, regardless of who wrote the kernel. transform_reducefused 2 passes into 1 and ran 3.3 times as fast astransformfollowed byreduce.- CUB’s single-pass scan moves 512 MiB where the scan of Chapter 8 moves 1,024 MiB, and it ran 1.7 times as fast.
- A radix sort performs a histogram, an exclusive scan and a stable scatter for each digit.
On 16 Mi keys the GPU sorted up to 180 times as fast as 1 CPU core. Reusing temporary
storage nearly halved the time of
thrust::sort, and a comparison hidden in a functor nearly doubled it. - On a sum of 4,096 floats,
thrust::reducetook 68.1 µs, of which 38.2 µs went to allocation and 21.1 µs to copying and waiting. CUB with its temporary storage reused and the result kept on the GPU took 8.8 µs. cub::BlockReduceand cuda-oxide’sblock_reducereplace the hand-written block sum of Chapter 8 at the same speed.TempStorageis a type so that its size is known at compile time.- A row-major array is seen by cuBLAS as its transpose; requesting \(B^T A^T\) writes \(C\) in row-major order. cuBLAS ran SGEMM at 1,505 GFLOP/s in FP32, 1.6 times the best kernel of Chapter 9, and at 6,530 GFLOP/s with TF32 tensor cores, with 210 times the error.
In Chapter 12, we go below the libraries. We compile CUDA source code while the program runs, with NVRTC, and load and launch the result through the driver API.
Exercises
- Change the sum of 4,096 floats in
reduce_scan.cuto 65,536 and to 1,048,576 floats. At what size doesthrust::reducecome within 10% of CUB with the result kept on the GPU? Explain the size from the 38.2 µs and 21.1 µs of Section 11.3.3. - Write the sum of squares as
thrust::transforminto athrust::device_vectorfollowed bythrust::reduce, and as a single custom kernel. Predict both times from the bytes moved, then measure them. - Sort the 6 keys 47, 12, 40, 18, 42, 11 by hand with a radix sort on 2 decimal digits. Write the counts, the starting positions and the output of both passes.
- Use
cub::BlockScanin place ofwarpScanin thescanBlockskernel of Chapter 8. Count the lines saved and measure the speed. - In
gemm.cu, compute \(C = AB\) for a 3 × 2 matrix \(A\) and a 2 × 4 matrix \(B\), both stored row by row. Work out all 6 arguments that change, then check the result by hand. - Instead of swapping the operands, call
cublasSgemmwithCUBLAS_OP_Tfor both operands. What does cuBLAS then compute, and in which order is the result stored? - Rerun
sort.cuwiththrust::greater<unsigned>in place ofcuda::std::greater<unsigned>. With which toolkit does the time change, and why? - The measured GPU ran TF32 SGEMM 4.3 times as fast as FP32. The peak rates of the A100
differ by a factor of 8, and those of the RTX 4090 not at all. Look up the FP32 and TF32
peaks of your GPU, predict the ratio, and measure it with
gemm.cu. - Generate 16 Mi uniform numbers with
curandGenerateUniformand estimate π by counting the pairs \((x, y)\) with \(x^2 + y^2 < 1\), usingthrust::count_ifon a zipped pair of arrays. How many correct digits do 8 Mi pairs give?
Sources and further reading
- NVIDIA, CUDA C++ Core Libraries (CCCL): Thrust, CUB and libcu++: https://nvidia.github.io/cccl/
- NVIDIA, cuBLAS Library,
cublasSgemm, leading dimensions andcublasSetMathMode: https://docs.nvidia.com/cuda/cublas/ - NVIDIA, cuFFT Library User’s Guide: https://docs.nvidia.com/cuda/cufft/
- NVIDIA, cuRAND Library: https://docs.nvidia.com/cuda/curand/
- NVIDIA, A100 Tensor Core GPU Architecture (2020), TF32; H100 Tensor Core GPU Architecture (2022); Ada GPU Architecture (2022), the peak rates of Section 11.4.3.
- D. Merrill and M. Garland, “Single-pass Parallel Prefix Scan with Decoupled Look-back”, NVIDIA Technical Report NVR-2016-002, 2016.
- A. Adinets and D. Merrill, “Onesweep: A Faster Least Significant Digit Radix Sort for GPUs”, 2022.
- C. Lawson, R. Hanson, D. Kincaid and F. Krogh, “Basic Linear Algebra Subprograms for Fortran Usage”, ACM Transactions on Mathematical Software 5(3), 1979.
- J. Salmon, M. Moraes, R. Dror and D. Shaw, “Parallel Random Numbers: As Easy as 1, 2, 3”, SC11, 2011 (the Philox generator).
- J. Cooley and J. Tukey, “An Algorithm for the Machine Calculation of Complex Fourier Series”, Mathematics of Computation 19, 1965.
- cuda-oxide,
cuda_device::cooperative_groups(block_reduce,block_scan), revisionb7fe543: https://github.com/NVlabs/cuda-oxide
Chapter 12: NVRTC, Runtime Compilation & the Driver API
So far, every kernel in this book has been compiled by nvcc, the CUDA compiler, together with
the host code of its program. The machine code of the kernel, the binary instructions that
the GPU executes, is placed inside the executable, and the CUDA runtime finds it there when the
host code launches the kernel with <<<...>>>. The data that a kernel
processes arrives at run time, but the instructions that process the data are fixed when the
program is built.
Some applications need kernels that cannot be written in advance. A deep-learning framework fuses several operations into 1 kernel after it has seen the shapes of the tensors, the multi-dimensional arrays on which it computes, such as a batch of 32 images of 224 × 224 pixels. A simulation reads its coefficients from an input file. A tool may let its users write their own kernels. In each case, the best kernel, or the only possible one, is known only while the program runs. In this chapter, we show how a program can generate the source code of a kernel as a string, compile it with NVRTC, the CUDA runtime compilation library, and load and launch the result through the driver API, the lower-level interface on which the CUDA runtime itself is built.
We use one example throughout the chapter: a polynomial of degree 32, evaluated at 16,777,216 points. A generic kernel reads the 33 coefficients from memory. A specialized kernel, generated by the program after the coefficients are known, contains them as constants. The two kernels produce bit-identical results, and we will measure both what the specialized kernel gains and what it costs to compile. The times in this chapter were measured on a Jetson Orin NX, an integrated GPU of compute capability 8.7 with 102 GB/s of memory bandwidth; the programs were also run on a Jetson AGX Thor, of compute capability 11.0.
This chapter covers
- the services of the runtime API, and the driver API objects beneath it: context, module and function
- PTX, cubin and fatbin, and the rules for which code runs on which GPU
- Horner’s rule, and a kernel specialized to its coefficients
- compiling CUDA C++ source from a string with NVRTC, and reading the compilation log
- loading a module, looking up a kernel, and launching it with an array of argument addresses
- the same steps in Rust, where cuda-core is built directly on the driver API
- the cost and benefit of runtime compilation, and the driver’s JIT cache
- sharing 1 context between the runtime API and the driver API
The code of the chapter is in
code/ch12_nvrtc/
for C++ and in
code/oxide/ch12_driver/
for Rust.
12.1 The runtime API and the driver API
12.1.1 What the runtime API does
Recall from Chapter 3 that a kernel is a function that executes on the GPU, once for each
thread of a launch. The functions we have used so far to allocate memory, copy data and launch
kernels, such as cudaMalloc, cudaMemcpy and the <<<...>>> syntax, belong to the CUDA
runtime API. The runtime API is implemented by a library called libcudart, and the names of
its functions begin with cuda.
To see what the runtime API does for a program, let us list what must be known before the launch
polyGeneric<<<65536, 256>>>(X, Y, n, C, degree) of this chapter can start. First, the GPU must
know which memory belongs to the program: X holds a device address such as 0x203a00000, which
is meaningful only among the allocations of this program on this GPU. Second, someone must know
where the machine code of polyGeneric is, among the kernels of the executable. Third, someone
must copy the 5 argument values into the launch: 8 bytes for each of the pointers X, Y and
C, and 4 bytes for each of the integers n and degree. The program states none of these
facts. The runtime API supplies them with 3 services that we have relied on without noticing
them.
- It creates a context. A context, defined below, holds the state of a program on 1 GPU. The runtime API creates 1 context per GPU the first time the program uses that GPU, and every later runtime call uses it.
- It registers the kernels.
nvccadds code to the executable that runs beforemain. This code gives the runtime the machine code of every kernel in the source file, together with the host-side function that represents each kernel. When the program launchespolyGeneric, the runtime therefore already knows which machine code the name refers to. - It packs the arguments. In a launch such as
polyGeneric<<<blocks, threads>>>(X, Y, n, C, degree), the compiler knows the parameter list of the kernel. It checks the types of the 5 arguments and generates the code that copies their values into the launch.
Definition 12.1 Context. A context holds the state of a program on 1 GPU: the memory the program has allocated, the kernels it has loaded, and its streams. A device address is valid only in the context that allocated it.
Example. When the program of this chapter calls cudaMalloc for X, the 64 MiB at
0x203a00000 are recorded in the context of GPU 0; the module that holds polyGeneric is
recorded in the same context.
A context plays a role for the GPU similar to the role a process plays for the CPU: two programs on the same GPU have 2 contexts, and neither can use the addresses of the other.
All 3 services depend on the kernel being known when the program is compiled. A kernel that is generated while the program runs has not been registered, and the compiler never saw its parameter list. The runtime API therefore has no way to launch it, and we need the lower-level interface.
12.1.2 Driver API objects
The runtime API is built on the CUDA driver API. The driver API is implemented by libcuda,
and the names of its functions begin with cu. Note that libcuda is part of the GPU driver,
not of the CUDA toolkit, so it is present on every machine that has an NVIDIA driver installed.
The driver API exposes as explicit objects the things that the runtime API manages for us:
| Object | What it is | Created by |
|---|---|---|
device (CUdevice) | 1 GPU, by number | cuDeviceGet |
context (CUcontext) | the memory, kernels and streams of 1 program on 1 GPU | cuDevicePrimaryCtxRetain |
module (CUmodule) | 1 loaded piece of GPU code, holding one or more kernels | cuModuleLoadData |
function (CUfunction) | 1 kernel inside a module, found by its name | cuModuleGetFunction |
Let us follow the specialized kernel of this chapter through the 4 objects. The program asks for
device 0, the Orin GPU, and receives a CUdevice. It obtains the context of that device, in
which its arrays X and Y live. It hands the driver 3,624 bytes of compiled code that contain
1 kernel, and the driver loads them into the context and returns a module. Finally, it asks the
module for the kernel named poly and receives a function, which it can launch on X and Y.
Definition 12.2 Module and function. A module is a piece
of GPU code loaded into a context; it holds one or more kernels, each recorded under its
symbol name, the name by which the code refers to it. A function (CUfunction) is a
handle to 1 kernel of a loaded module, obtained by looking up its symbol name.
Example. Loading the 3,624-byte cubin of section 12.4 gives a module that holds 1 kernel;
looking up the name poly in it gives the function that cuLaunchKernel launches.
Once a program holds a function object, it can launch the kernel with cuLaunchKernel,
regardless of how the code of the kernel was produced. Figure 12.1 shows the layers. The runtime
API, NVRTC and the Rust crate cuda-core all rest on the same driver API.
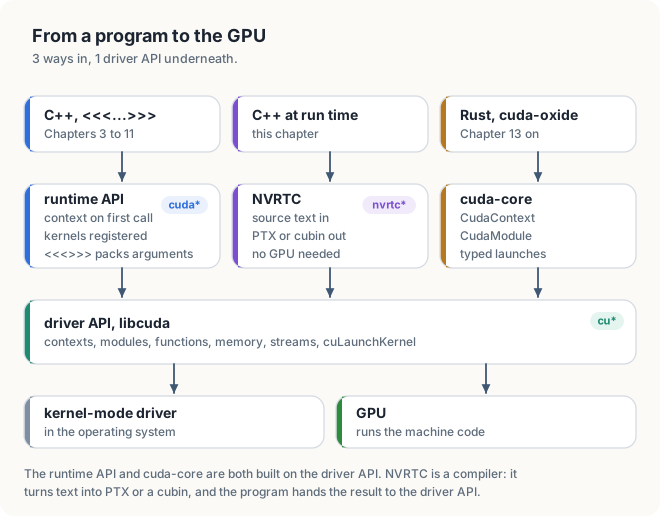
Most runtime API calls correspond to one or more driver API calls:
| Runtime API | Driver API |
|---|---|
| first call creates the context | cuInit, cuDeviceGet, cuDevicePrimaryCtxRetain |
cudaMalloc, cudaFree | cuMemAlloc, cuMemFree |
cudaMemcpy | cuMemcpyHtoD, cuMemcpyDtoH |
kernels registered before main | cuModuleLoadData, cuModuleGetFunction |
kernel<<<grid, block>>>(args...) | cuLaunchKernel(function, grid, block, ..., args) |
12.1.3 cuda-core and the driver API
The Rust programs of this book have used the driver API from the beginning. cuda-core, the host
crate (Rust package) of cuda-oxide, calls libcuda directly and does not use the runtime
API at all. CudaContext::new(0) calls cuInit, cuDeviceGet and cuDevicePrimaryCtxRetain,
and kernels::load(&ctx) passes the GPU code that cargo-oxide embedded in the executable to
cuModuleLoadData. A Rust program that compiles a kernel at run time therefore needs no new
crate. It passes the code it has compiled to the same functions.
12.2 PTX, cubin and fatbin
12.2.1 Virtual and real architectures
Each generation of NVIDIA GPUs has its own instruction set, the set of machine instructions
that its processors understand, together with their binary encoding. The compute capability
identifies a generation and its features with 2 numbers, a major and a minor version: 8.7 for
the Jetson Orin NX and 9.0 for the H100. A compiler target for a particular compute capability
is written as sm_87 or sm_90. Machine code compiled for sm_90 does not run on an sm_87
GPU, because some of its instructions do not exist on the older generation.
To allow code to run on GPUs that did not exist when it was compiled, NVIDIA defines a second,
portable form of GPU code, and compilation is split into 2 steps. Let us follow the polynomial
kernel of this chapter through them. The source text of the kernel is 1,315 bytes long. The
first step translates it into a list of operations for an idealized GPU that no hardware
implements directly, for example “multiply-add 3 registers of 32-bit floats”, without choosing
the binary encoding of any real GPU. For our kernel, this intermediate form is 2,237 bytes of
text, and it is almost the same for every target: 2,237 bytes for the Orin and 2,250 bytes for
the Thor. The second step translates the intermediate form into the machine code of 1 real GPU:
3,624 bytes for sm_87 and 6,368 bytes for sm_110. The second step can run when the program
is built, or later, on the machine where the program runs, once the GPU is known.
Key observation The first step does not depend on the GPU that will run the code, and the second step does. If a program carries the intermediate form, the choice of GPU can wait until the program runs.
Definition 12.3 PTX and JIT compilation. PTX is the
instruction set of a virtual GPU, stored as text. PTX is compiled for a virtual
architecture, such as compute_87, which determines the features the code may use but not the
machine instructions. Compiling code at the moment it is needed, on the machine where it runs,
is called just-in-time (JIT) compilation.
Example. When a program loads the 2,237 bytes of PTX of the polynomial kernel on the Orin, the
GPU driver JIT-compiles them into machine code for sm_87.
The machine code itself is stored in 1 of 2 containers.
Definition 12.4 Cubin and fatbin. A cubin (CUDA binary)
holds machine code for 1 real architecture, such as sm_87. A fatbin (fat binary) bundles
several cubins and PTX in 1 file, so that 1 executable can run on many GPUs.
Example. A fatbin with a cubin for sm_87, a cubin for sm_90 and PTX for compute_87 runs
the first cubin on an Orin, the second on an H100, and JIT-compiles the PTX on a Thor.
nvcc embeds a fatbin in every executable it builds. When the program loads it, the driver
selects the cubin that matches the GPU, or JIT-compiles the PTX if no cubin matches.
Figure 12.2 shows the three forms twice: produced by nvcc before the program runs, and produced by
NVRTC while it runs. The sizes are those of the polynomial kernel of this chapter, compiled for
sm_87.
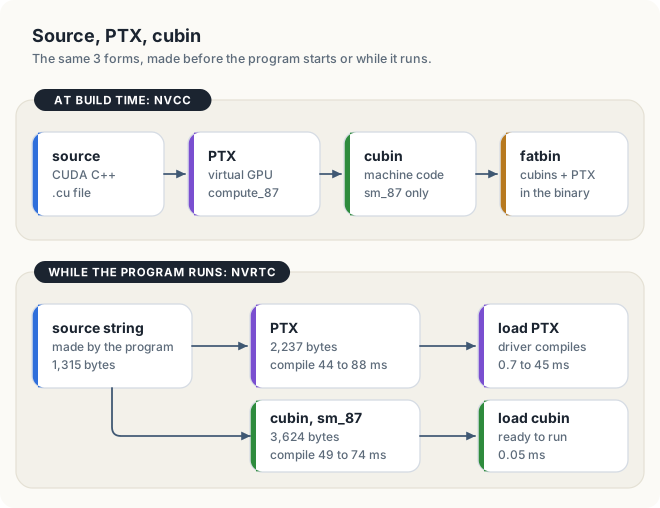
12.2.2 Binary and PTX compatibility
The CUDA programming guide gives two rules that decide whether a piece of GPU code can run on a given GPU:
- A cubin built for compute capability X.y runs on a GPU of compute capability X.z only if z ≥ y. That is, the GPU must belong to the same major generation and have the same or a later minor version.
- PTX compiled for
compute_X.ycan be JIT-compiled for any GPU of compute capability X.y or higher, including GPUs of later major generations.
The following table applies the two rules to code compiled for compute capability 8.0.
| GPU | Compute capability | Real architecture | Runs a cubin for sm_80? | Runs PTX for compute_80? |
|---|---|---|---|---|
| A100 | 8.0 | sm_80 | yes | yes |
| Jetson Orin NX | 8.7 | sm_87 | yes, 8.7 ≥ 8.0 | yes |
| GeForce RTX 4090 | 8.9 | sm_89 | yes, 8.9 ≥ 8.0 | yes |
| H100 | 9.0 | sm_90 | no, major 9 ≠ 8 | yes |
| Jetson AGX Thor | 11.0 | sm_110 | no | yes |
| GeForce RTX 5090 | 12.0 | sm_120 | no | yes |
| DGX Spark (GB10) | 12.1 | sm_121 | no | yes |
A program that compiles its kernels at run time does not face this question. It can ask the driver which GPU it is running on and compile for exactly that GPU, as we will see in section 12.4.2.
12.3 A kernel that depends on run-time values
12.3.1 Horner’s rule
A polynomial of degree \(d\) has \(d + 1\) coefficients:
\[ p(x) = c_0 + c_1 x + c_2 x^2 + \dots + c_d x^d \]
Computing each power of \(x\) separately wastes multiplications. Horner’s rule rewrites the polynomial so that each coefficient costs 1 multiplication and 1 addition:
\[ p(x) = c_0 + x\,(c_1 + x\,(c_2 + \dots + x\,c_d)) \]
The evaluation starts with the highest coefficient. At each step, it multiplies the running value by \(x\) and adds the next lower coefficient. For example, consider \(p(x) = 1 + x/2 + x^2/3\) at \(x = 0.5\). We start with \(p = c_2 = 0.3333\). The first step computes \(p = 0.3333 \times 0.5 + 0.5 = 0.6667\), and the second step computes \(p = 0.6667 \times 0.5 + 1 = 1.3333\). Evaluating the terms separately gives the same value, \(1 + 0.25 + 0.0833 = 1.3333\). Figure 12.3 shows the 2 steps.
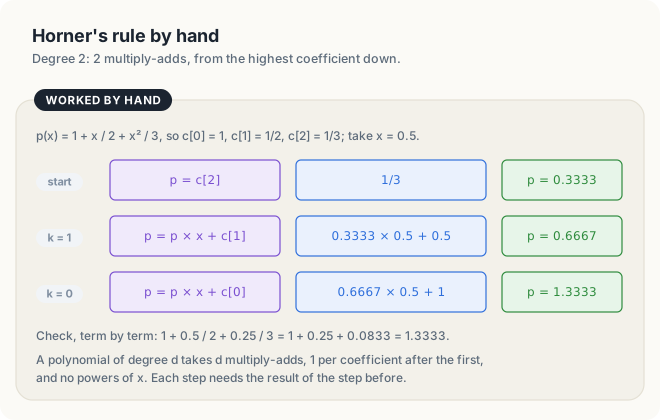
On a GPU, a multiplication followed by an addition is a single instruction, the fused multiply-add (FMA), which rounds the result once instead of twice. A polynomial of degree \(d\) therefore costs \(d\) FMAs per point, or \(2d\) floating-point operations (FLOP):
HORNER(c[0..d], x):
p ← c[d]
for k ← d − 1 down to 0:
p ← p × x + c[k] # 1 fused multiply-add
return p
The example of this chapter has degree \(d\) = 32 and coefficients \(c_k = 1/(k + 1)\), that is, 1, 0.5, 0.3333, and so on down to 0.0303. The polynomial is evaluated at \(N\) = 224 = 16,777,216 points spread evenly over \([-1, 1)\). The whole evaluation performs \(2dN\) = 2 × 32 × 16,777,216 = 1.07 GFLOP and moves \(8N\) = 134.2 MB, since each point requires reading 4 bytes and writing 4 bytes.
12.3.2 The generic kernel
The generic kernel receives the degree and the coefficients as arguments, and each thread
evaluates the polynomial at 1 point. Since nvcc compiles this kernel together with the rest of
the program, before the coefficients are known, the kernel must work for any degree and any
coefficients.
Listing 12.1 The generic kernel.
#[cuda_module]
mod kernels {
use super::*;
/// The degree and the coefficients arrive at run time, in `c`.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn poly_generic(x: &[f32], c: &[f32], mut y: DisjointSlice<f32>) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(out) = y.get_mut(idx) {
let v = x[i];
let mut k = c.len() - 1;
let mut p = c[k];
while k > 0 {
k -= 1;
p = p.mul_add(v, c[k]);
}
*out = p;
}
}
}// Compiled by nvcc with the program: the degree and the coefficients arrive at run time.
__global__ void polyGeneric(const float* x, float* y, int n, const float* c, int degree)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i >= n) {
return;
}
float v = x[i];
float p = c[degree];
for (int k = degree - 1; k >= 0; --k) {
p = p * v + c[k];
}
y[i] = p;
}
In each of the 32 iterations of the loop, the thread reads c[k] from memory, because the
compiler does not know its value. It then decrements and tests k, and finally performs 1 FMA.
All threads of a warp read the same c[k], so the read is served by the cache, a small,
fast memory on the chip that keeps recently read values. However, it is
still an instruction that the GPU must issue, together with the loop instructions, for every one
of the 32 FMAs.
The Rust kernel contains the same loop. It obtains the degree from the length of the slice c,
so it also works for any degree. Note the call to mul_add, which requests the fused
multiply-add explicitly. Unlike a C++ compiler, the Rust compiler does not fuse p * v + c[k]
on its own, because fusing changes the rounding of the result.
12.3.3 Generating the specialized kernel source
Once the program knows the coefficients, it can generate a kernel that contains them. Consider
first the polynomial of degree 2 of Figure 12.3, with the coefficients 1, 0.5 and 0.3333. For
each step of Horner’s rule, the generic kernel performs 4 operations. It reads c[k] from
memory, decrements k, tests whether the loop continues, and performs the FMA. If the program
writes the coefficients into the source text, the same evaluation becomes 3 lines with no loop
and no reads:
p = 0.3333
p = p × v + 0.5 # 1 FMA with a constant
p = p × v + 1 # 1 FMA with a constant
Each step is now 1 operation instead of 4, and the 3 lines compute the same value, 1.3333 at v = 0.5.
Definition 12.5 Specialized kernel. Specializing a kernel means compiling it for particular values that a generic kernel would receive as arguments, so that the values appear in the source as constants.
Example. The polynomial kernel specialized to the coefficients \(c_k = 1/(k + 1)\) contains
the constant 3.125000000e-02 for \(c_{31}\) = 1/32, where the generic kernel reads c[31]
from memory.
The specialized polynomial kernel of degree 32 has no loop and no reads of c. Its body
consists of 32 lines, each of which is 1 FMA with a constant:
SPECIALISED SOURCE(c[0..d]):
text ← kernel header, i, bounds test, v ← x[i]
append "p = c[d];" written as a number
for k ← d − 1 down to 0:
append "p = p * v + c[k];" written as a number
append "y[i] = p;"
return text
Listing 12.2 The program generates the source of the specialized kernel.
/// The fixed first lines of the generated kernel.
const HEAD: &str = r#"extern "C" __global__ void poly(const float* x, float* y, int n)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i >= n) {
return;
}
float v = x[i];
"#;
/// CUDA C++ source text for the polynomial, with its coefficients written in.
fn specialised_source(c: &[f32]) -> String {
let mut src = String::from(HEAD);
src += &format!(" float p = {:.9e}f;\n", c[DEGREE]);
for k in (0..DEGREE).rev() {
src += &format!(" p = p * v + {:.9e}f;\n", c[k]);
}
src += " y[i] = p;\n}\n";
src
}
// ...
}// CUDA C++ source text for the same polynomial, with its coefficients written in.
std::string specialisedSource(const std::vector<float>& c)
{
std::string src = "extern \"C\" __global__ void poly(const float* x, float* y, int n)\n"
"{\n"
" int i = blockIdx.x * blockDim.x + threadIdx.x;\n"
" if (i >= n) {\n"
" return;\n"
" }\n"
"\n"
" float v = x[i];\n";
char line[64];
std::snprintf(line, sizeof line, " float p = %.9ef;\n", c[DEGREE]);
src += line;
for (int k = DEGREE - 1; k >= 0; --k) {
std::snprintf(line, sizeof line, " p = p * v + %.9ef;\n", c[k]);
src += line;
}
src += " y[i] = p;\n}\n";
return src;
}
We explain three details of the generated text. First, the kernel is declared extern "C", which keeps its name exactly poly. C++ allows overloaded functions, several
functions with the same name and different parameter types, such as poly(const float*, float*, int) and poly(const double*, double*, int). To give each of them a distinct symbol name, the
C++ compiler encodes the parameter types into the name. Our kernel becomes _Z4polyPKfPfi: _Z
starts an encoded name, 4poly is the 4-letter name, PKf is a pointer to a constant float,
Pf a pointer to a float, and i an int. This encoding is called name mangling. Since
we look up the kernel by its name in section 12.5.2, the name must be predictable. Second, the
format %.9e of snprintf prints each coefficient in scientific notation: 1 digit, a decimal
point and 9 more digits, followed by a power of 10, for example 3.125000000e-02 = 3.125 ×
10−2 for 1/32. Nine significant decimal digits are sufficient to represent every float
value exactly, and the format prints 10, so each constant in the text is the same float that
the generic kernel reads from memory. Third, the f suffix makes each constant a float.
Without the suffix, 3.125000000e-02 is a double in C++, and the entire FMA would be
performed in double precision.
Figure 12.4 compares the two kernels, together with the execution times that we will measure in section 12.6.
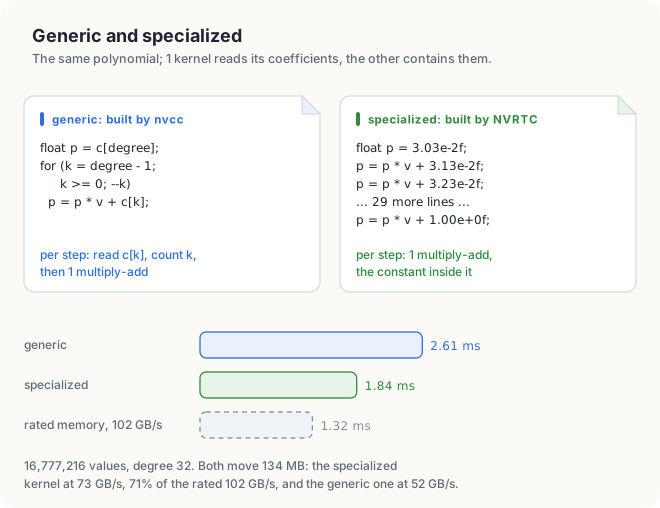
12.4 Compiling source at run time with NVRTC
12.4.1 The NVRTC calls
NVRTC (NVIDIA Runtime Compilation) is a library, libnvrtc, that compiles CUDA C++ source
code held in a string. It contains the same compiler front end as nvcc, the part of a
compiler that reads the source text, checks it and translates it into an intermediate form, but
it requires no files, no nvcc installation and no GPU, and it returns PTX or a cubin as bytes
in memory.
Before we list the calls, let us follow the polynomial kernel from text to launch, with the
sizes measured on the Orin. The program holds the source as a string of 1,315 bytes. NVRTC
compiles the string in 44 to 88 ms and returns either 2,237 bytes of PTX or a cubin of 3,624
bytes for sm_87. The driver loads the image into the context as a module: the cubin in 0.05
ms, the PTX in 13 to 45 ms because the driver must first JIT-compile it, or in about 0.7 ms if
it finds the result of an earlier compilation in its cache (section 12.7). The program looks up
poly in the module and launches it with cuLaunchKernel. In Sections 12.4 and 12.5, we take
these steps in order: compile, load and look up, launch.
A compilation consists of 5 steps:
COMPILE(source, target):
prog ← nvrtcCreateProgram(source, name for messages)
if nvrtcCompileProgram(prog, ["--gpu-architecture=" + target]) fails:
print nvrtcGetProgramLog(prog) # the compiler's error messages
return nothing
image ← nvrtcGetCUBIN(prog) if target is real, such as sm_87
nvrtcGetPTX(prog) if target is virtual, such as compute_87
nvrtcDestroyProgram(prog)
return image
Listing 12.3 Compiling a string with NVRTC.
/// Compile `source` with NVRTC into a cubin for the GPU `arch`, such as "sm_87".
fn compile(source: &str, arch: &str) -> Result<Vec<u8>, Error> {
let src = CString::new(source)?;
let name = CString::new("poly.cu")?;
let option = CString::new(format!("--gpu-architecture={arch}"))?;
let options = [option.as_ptr()];
let none = std::ptr::null();
let mut prog: Program = std::ptr::null_mut();
// SAFETY: every pointer refers to a live, NUL-terminated string, to `prog`, or to a
// buffer of the size NVRTC reported.
unsafe {
let (src, name) = (src.as_ptr(), name.as_ptr());
ok(nvrtcCreateProgram(&mut prog, src, name, 0, none, none), "nvrtcCreateProgram")?;
if nvrtcCompileProgram(prog, 1, options.as_ptr()) != 0 {
let mut size = 0;
ok(nvrtcGetProgramLogSize(prog, &mut size), "nvrtcGetProgramLogSize")?;
let mut log = vec![0u8; size];
ok(nvrtcGetProgramLog(prog, log.as_mut_ptr().cast()), "nvrtcGetProgramLog")?;
nvrtcDestroyProgram(&mut prog);
log.pop(); // the terminating NUL
return Err(String::from_utf8_lossy(&log).into());
}
let mut size = 0;
ok(nvrtcGetCUBINSize(prog, &mut size), "nvrtcGetCUBINSize")?;
let mut cubin = vec![0u8; size];
ok(nvrtcGetCUBIN(prog, cubin.as_mut_ptr().cast()), "nvrtcGetCUBIN")?;
ok(nvrtcDestroyProgram(&mut prog), "nvrtcDestroyProgram")?;
Ok(cubin)
}
}
/// NVRTC returns 0 for success and an error number otherwise.
fn ok(result: c_int, call: &str) -> Result<(), Error> {
if result == 0 {
Ok(())
} else {
Err(format!("{call} failed with NVRTC error {result}").into())
}
}// Compile `source` with NVRTC: a cubin for 1 GPU ("sm_87"), or PTX for the driver.
std::vector<char> compile(const std::string& source, const std::string& arch, bool cubin)
{
nvrtcProgram prog;
check(nvrtcCreateProgram(&prog, source.c_str(), "poly.cu", 0, nullptr, nullptr));
std::string target = cubin ? arch : "compute_" + arch.substr(3);
std::string option = "--gpu-architecture=" + target;
const char* options[] = {option.c_str()};
nvrtcResult result = nvrtcCompileProgram(prog, 1, options);
if (result != NVRTC_SUCCESS) {
size_t logSize;
check(nvrtcGetProgramLogSize(prog, &logSize));
std::string log(logSize, '\0');
check(nvrtcGetProgramLog(prog, log.data()));
std::printf(" compile failed, log:\n%s", log.c_str());
check(nvrtcDestroyProgram(&prog));
return {};
}
size_t size;
std::vector<char> image;
if (cubin) {
check(nvrtcGetCUBINSize(prog, &size));
image.resize(size);
check(nvrtcGetCUBIN(prog, image.data()));
} else {
check(nvrtcGetPTXSize(prog, &size));
image.resize(size);
check(nvrtcGetPTX(prog, image.data()));
}
check(nvrtcDestroyProgram(&prog));
return image;
}
The option --gpu-architecture determines what NVRTC produces. If the target is a real
architecture, such as sm_87, NVRTC produces a cubin, which the program retrieves with
nvrtcGetCUBIN. If the target is a virtual architecture, such as compute_87, NVRTC produces
only PTX. The other options are the same as those of nvcc, passed as strings: -std=c++17,
-default-device, -I and so on.
12.4.2 Selecting the target architecture
The program asks the driver for the compute capability of the GPU and builds the architecture
name from it. For example, a major version of 8 and a minor version of 7 give sm_87. The same
lines of code also create the context described in section 12.5.1.
Listing 12.4 Creating a context and selecting the target for the GPU the program runs on.
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
let (major, minor) = ctx.compute_capability()?;
let arch = format!("sm_{major}{minor}");
let name = ctx.device_name()?;
println!("GPU: {name}, compute capability {major}.{minor}, target {arch}");
// ...
}int main()
{
check(cuInit(0));
CUdevice device;
check(cuDeviceGet(&device, 0));
CUcontext context;
check(cuDevicePrimaryCtxRetain(&context, device));
check(cuCtxSetCurrent(context));
int major, minor;
auto majorAttr = CU_DEVICE_ATTRIBUTE_COMPUTE_CAPABILITY_MAJOR;
auto minorAttr = CU_DEVICE_ATTRIBUTE_COMPUTE_CAPABILITY_MINOR;
check(cuDeviceGetAttribute(&major, majorAttr, device));
check(cuDeviceGetAttribute(&minor, minorAttr, device));
std::string arch = "sm_" + std::to_string(major * 10 + minor);
char name[256];
check(cuDeviceGetName(name, sizeof name, device));
std::printf("GPU: %s, compute capability %d.%d, ", name, major, minor);
std::printf("target %s\n", arch.c_str());
// ...
}
GPU: Orin, compute capability 8.7, target sm_87
GPU: NVIDIA Thor, compute capability 11.0, target sm_110
The same source compiles to a cubin of 3,624 bytes for sm_87 and of 6,368 bytes for sm_110.
The PTX, in contrast, hardly changes, at 2,237 bytes and 2,250 bytes, because it describes the
same virtual machine in both cases.
12.4.3 The compilation log
A program that generates source code can make mistakes in it, as a programmer can. NVRTC
does not print its error messages. Instead, it stores them in the log of the program object,
and the host code must retrieve the log with nvrtcGetProgramLogSize and nvrtcGetProgramLog.
To demonstrate, our program compiles a second copy of its source in which y[i] = p has been
changed to y[i] = q, and prints the log:
a source with a mistake
compile failed, log:
poly.cu(42): error: identifier "q" is undefined
y[i] = q;
^
1 error detected in the compilation of "poly.cu".
poly.cu is the name the program passed to nvrtcCreateProgram; no file of that name exists.
Line 42 is the last line of the generated text: 8 lines of header, 1 line for float p, 32
lines of FMAs, and then y[i] = q. Without the log, the program would only know that the
compilation failed, not why.
12.4.4 Calling NVRTC from Rust
cuda-oxide does not provide an NVRTC wrapper at the revision used in this book, and the Rust
program needs only 7 NVRTC functions, so it declares them itself. A declaration of functions
that are implemented in another language is called a foreign function interface (FFI). The
linker is the program that combines the compiled code of a program with the libraries it
calls into 1 executable. The attribute #[link(name = "nvrtc")], an annotation on the block of
declarations, instructs the linker to link libnvrtc. cuda-oxide’s cuda-bindings crate
already adds the toolkit’s lib64 directory to the linker’s search path, so Cargo.toml is the
same as in Chapter 13 and needs no new dependency. In Rust 2024, the block must be written as
unsafe extern "C", because the compiler cannot verify that the declarations match the library;
the programmer is responsible for that.
Listing 12.5 The 7 NVRTC functions, declared in Rust and taken from the header in C++.
/// An NVRTC program handle, and the 7 NVRTC functions this program calls.
type Program = *mut c_void;
#[link(name = "nvrtc")]
unsafe extern "C" {
fn nvrtcCreateProgram(
prog: *mut Program,
src: *const c_char,
name: *const c_char,
num_headers: c_int,
headers: *const *const c_char,
include_names: *const *const c_char,
) -> c_int;
fn nvrtcCompileProgram(
prog: Program,
num_options: c_int,
options: *const *const c_char,
) -> c_int;
fn nvrtcGetProgramLogSize(prog: Program, size: *mut usize) -> c_int;
fn nvrtcGetProgramLog(prog: Program, log: *mut c_char) -> c_int;
fn nvrtcGetCUBINSize(prog: Program, size: *mut usize) -> c_int;
fn nvrtcGetCUBIN(prog: Program, cubin: *mut c_char) -> c_int;
fn nvrtcDestroyProgram(prog: *mut Program) -> c_int;
}#include <nvrtc.h>
The type Program represents NVRTC’s nvrtcProgram, a pointer to an object whose layout only
NVRTC knows. Each function returns an nvrtcResult, in which 0 indicates success, so c_int is
the appropriate Rust type. The compile function follows the same 5 steps as the C++ version. A
C string has no stored length; it ends at the first byte with the value 0, called the NUL
byte, so the 4 characters poly occupy 5 bytes. CString appends this byte, and the small
helper function ok converts a nonzero result into a Rust error so that the ? operator can
propagate it.
Listing 12.6 The compile function, which calls the functions of Listing 12.5.
/// Compile `source` with NVRTC into a cubin for the GPU `arch`, such as "sm_87".
fn compile(source: &str, arch: &str) -> Result<Vec<u8>, Error> {
let src = CString::new(source)?;
let name = CString::new("poly.cu")?;
let option = CString::new(format!("--gpu-architecture={arch}"))?;
let options = [option.as_ptr()];
let none = std::ptr::null();
let mut prog: Program = std::ptr::null_mut();
// SAFETY: every pointer refers to a live, NUL-terminated string, to `prog`, or to a
// buffer of the size NVRTC reported.
unsafe {
let (src, name) = (src.as_ptr(), name.as_ptr());
ok(nvrtcCreateProgram(&mut prog, src, name, 0, none, none), "nvrtcCreateProgram")?;
if nvrtcCompileProgram(prog, 1, options.as_ptr()) != 0 {
let mut size = 0;
ok(nvrtcGetProgramLogSize(prog, &mut size), "nvrtcGetProgramLogSize")?;
let mut log = vec![0u8; size];
ok(nvrtcGetProgramLog(prog, log.as_mut_ptr().cast()), "nvrtcGetProgramLog")?;
nvrtcDestroyProgram(&mut prog);
log.pop(); // the terminating NUL
return Err(String::from_utf8_lossy(&log).into());
}
let mut size = 0;
ok(nvrtcGetCUBINSize(prog, &mut size), "nvrtcGetCUBINSize")?;
let mut cubin = vec![0u8; size];
ok(nvrtcGetCUBIN(prog, cubin.as_mut_ptr().cast()), "nvrtcGetCUBIN")?;
ok(nvrtcDestroyProgram(&mut prog), "nvrtcDestroyProgram")?;
Ok(cubin)
}
}
/// NVRTC returns 0 for success and an error number otherwise.
fn ok(result: c_int, call: &str) -> Result<(), Error> {
if result == 0 {
Ok(())
} else {
Err(format!("{call} failed with NVRTC error {result}").into())
}
}// Compile `source` with NVRTC: a cubin for 1 GPU ("sm_87"), or PTX for the driver.
std::vector<char> compile(const std::string& source, const std::string& arch, bool cubin)
{
nvrtcProgram prog;
check(nvrtcCreateProgram(&prog, source.c_str(), "poly.cu", 0, nullptr, nullptr));
std::string target = cubin ? arch : "compute_" + arch.substr(3);
std::string option = "--gpu-architecture=" + target;
const char* options[] = {option.c_str()};
nvrtcResult result = nvrtcCompileProgram(prog, 1, options);
if (result != NVRTC_SUCCESS) {
size_t logSize;
check(nvrtcGetProgramLogSize(prog, &logSize));
std::string log(logSize, '\0');
check(nvrtcGetProgramLog(prog, log.data()));
std::printf(" compile failed, log:\n%s", log.c_str());
check(nvrtcDestroyProgram(&prog));
return {};
}
size_t size;
std::vector<char> image;
if (cubin) {
check(nvrtcGetCUBINSize(prog, &size));
image.resize(size);
check(nvrtcGetCUBIN(prog, image.data()));
} else {
check(nvrtcGetPTXSize(prog, &size));
image.resize(size);
check(nvrtcGetPTX(prog, image.data()));
}
check(nvrtcDestroyProgram(&prog));
return image;
}
The source text generated by the Rust program describes the same kernel. Rust prints the
exponent of a floating-point number without a leading zero, as in 3.125000000e-2, so its
source is 1,281 bytes long instead of 1,315. The CUDA C++ compiler reads both spellings as the
same number.
12.5 Loading and launching with the driver API
12.5.1 Contexts
Listing 12.4 began with 4 driver API calls. cuInit(0) initializes the driver API. It must be
called before any other cu function, and its argument must be 0. cuDeviceGet converts the
device number 0 into a CUdevice. cuDevicePrimaryCtxRetain returns the primary context of
the device, which is the single context per GPU that the runtime API uses, and increments the
count of its users. The driver destroys the primary context only when this count returns to 0,
so a context retained by two parts of a program, for example the runtime API and our own code,
survives until both have released it. Finally, cuCtxSetCurrent makes this context the
current context of the calling host thread. Every later driver call made by that CPU thread,
such as cuModuleLoadData, operates on this context without naming it.
The driver API can also create additional contexts with cuCtxCreate. However, a device pointer
belongs to the context that allocated it and is not valid in any other context. A program that
combined the runtime API with a context of its own would therefore hold 2 separate sets of
memory. By retaining the primary context, the program uses a single context throughout, as
we discuss further in section 12.8. At the end of the program, cuDevicePrimaryCtxRelease
decrements the count of users.
12.5.2 Modules and functions
cuModuleLoadData loads 1 image, which may be PTX, a cubin or a fatbin, into the current
context and returns a module. cuModuleGetFunction then looks up a kernel in the module by its
name.
Listing 12.7 Loading an image and looking up the kernel in it.
fn main() -> Result<(), Error> {
// ...
let start = Instant::now();
let special = ctx.load_module_from_image(&cubin)?;
let poly = special.load_function("poly")?;
let load_ms = start.elapsed().as_secs_f64() * 1e3;
println!(" load cubin {load_ms:8.2} ms");
// ...
}// Load a PTX or cubin image into the current context and find the kernel `name` in it.
CUfunction loadKernel(const std::vector<char>& image, const char* name, CUmodule& module)
{
check(cuModuleLoadData(&module, image.data()));
CUfunction kernel;
check(cuModuleGetFunction(&kernel, module, name));
return kernel;
}
The name passed to cuModuleGetFunction must be the symbol name in the machine code. In section
12.3.3, we used extern "C" to keep that name as poly. A copy of the program whose generated
source omitted extern "C" compiled without any error, but then failed at the lookup:
GPU: Orin, compute capability 8.7, target sm_87
NVRTC, a polynomial of degree 32, 1304 bytes of source
compile to PTX 50.01 ms 2309 bytes
compile to cubin 51.30 ms 3752 bytes
CUDA driver error: CUDA_ERROR_NOT_FOUND
The module contained a kernel named _Z4polyPKfPfi, but no kernel named poly. A second copy
of the program, which compiled its cubin for sm_90 and loaded it on the sm_87 GPU, failed
one step earlier, in cuModuleLoadData, with CUDA_ERROR_INVALID_SOURCE. As the compatibility
rules of section 12.2.2 state, the driver does not load machine code built for a different
generation.
12.5.3 Kernel arguments
cuLaunchKernel takes the function, the grid and block dimensions, the number of bytes of
dynamic shared memory, which is shared memory whose size is chosen at the launch rather than
written into the kernel, a stream, and the arguments of the kernel. Unlike the <<<...>>>
syntax, the driver API does not know the parameter list of the kernel at compile time. The
driver obtains the size of each parameter from the module, so it needs only 1 piece of
information from the program for each parameter: the address at which the value of the
argument is stored. The program passes these addresses as an array of void*.
For example, the specialized kernel is declared as poly(const float* x, float* y, int n). The
host variables X and Y hold device addresses, and the host variable n holds 16,777,216.
The argument array is therefore args[0] = &X, args[1] = &Y and args[2] = &n. At the
launch, the driver reads 8 bytes at args[0], 8 bytes at args[1] and 4 bytes at args[2], a
total of 8 + 8 + 4 = 20 bytes, and copies them into the parameters x, y and n of the
kernel.
Listing 12.8 The argument array and the 2 launches.
fn main() -> Result<(), Error> {
// ...
let blocks = (N as u32).div_ceil(BLOCK);
let config = module.prepare_poly_generic(LaunchConfig1D::new(blocks, BLOCK, 0))?;
let mut x_ptr = x.cu_deviceptr();
let mut y_ptr = y.cu_deviceptr();
let mut n = N as c_int;
let mut args: [*mut c_void; 3] = [
(&raw mut x_ptr).cast(),
(&raw mut y_ptr).cast(),
(&raw mut n).cast(),
];
let mut generic = || -> Result<(), Error> {
Ok(module.poly_generic(&stream, &config, &x, &c, &mut y)?)
};
let mut specialised = || -> Result<(), Error> {
let grid = (blocks, 1, 1);
let block = (BLOCK, 1, 1);
// SAFETY: `poly` takes (const float*, float*, int); args points to 2 device
// pointers and an int, all alive, and the grid covers N exactly once.
unsafe { launch_kernel_on_stream(&poly, grid, block, 0, &stream, &mut args)? };
Ok(())
};
// ...
}int main()
{
// ...
int n = N;
int degree = DEGREE;
unsigned threads = 256;
unsigned blocks = (N + threads - 1) / threads;
void* args[] = {&X, &Y, &n};
auto generic = [&] { polyGeneric<<<blocks, threads>>>(X, Y, n, C, degree); };
auto special = [&] {
check(cuLaunchKernel(poly, blocks, 1, 1, threads, 1, 1, 0, nullptr, args, nullptr));
};
// ...
}
The lambda special launches 65,536 blocks of 256 threads, 1 thread per point, on the
default stream, the stream used when the program names none (nullptr), and with no dynamic
shared memory (0). The last argument, extra, provides an
alternative way to pass the arguments as a single packed buffer; we leave it empty.
A common mistake is to write X where &X is required. Figure 12.5 shows why this fails. We
ran a copy of the program with void* args[] = {X, Y, &n};. It ran the generic kernel and then
terminated at the first cuLaunchKernel:
$ ./nvrtc # with void* args[] = {X, Y, &n};
GPU: Orin, compute capability 8.7, target sm_87
NVRTC, a polynomial of degree 32, 1315 bytes of source
...
generic, nvcc, <<<...>>> 2.897 ms 370.6 GFLOP/s
Segmentation fault
$ echo $?
139
The driver interpreted the device address stored in X as the host address of an argument, and
the CPU’s read from that address failed. A segmentation fault is the error that the
operating system raises when a program accesses an address that it is not allowed to access; the
system then stops the program with the signal SIGSEGV, number 11. A shell reports a program
stopped by signal \(s\) with the exit code 128 + \(s\), so exit code 139 is 128 + 11, signal
11, SIGSEGV. On another system, the read might succeed and silently pass a meaningless value
to the kernel instead.
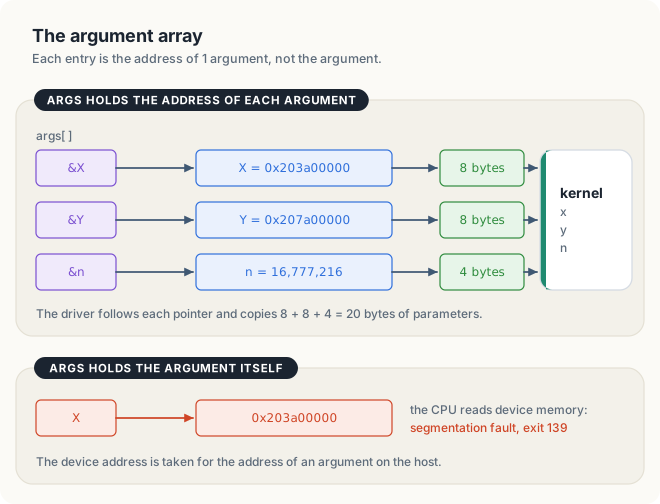
cuLaunchKernel reads each argument through the address the program gives it. Pass &X, never
X.
12.5.4 Loading and launching from Rust
cuda-core wraps the same 3 driver steps. CudaContext::load_module_from_image calls
cuModuleLoadData and returns a CudaModule, which unloads itself with cuModuleUnload when
it is dropped. load_function calls cuModuleGetFunction. launch_kernel_on_stream calls
cuLaunchKernel with a slice of argument addresses. This function is marked unsafe because,
like the C++ driver API, it cannot check that the addresses match the parameters of the kernel.
Listing 12.9 Loading the NVRTC cubin, with the raw launch beside the typed launch.
fn main() -> Result<(), Error> {
// ...
let start = Instant::now();
let special = ctx.load_module_from_image(&cubin)?;
let poly = special.load_function("poly")?;
let load_ms = start.elapsed().as_secs_f64() * 1e3;
println!(" load cubin {load_ms:8.2} ms");
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let x = DeviceBuffer::from_host(&stream, &x_host)?;
let c = DeviceBuffer::from_host(&stream, &c_host)?;
let mut y = DeviceBuffer::<f32>::zeroed(&stream, N)?;
let blocks = (N as u32).div_ceil(BLOCK);
let config = module.prepare_poly_generic(LaunchConfig1D::new(blocks, BLOCK, 0))?;
let mut x_ptr = x.cu_deviceptr();
let mut y_ptr = y.cu_deviceptr();
let mut n = N as c_int;
let mut args: [*mut c_void; 3] = [
(&raw mut x_ptr).cast(),
(&raw mut y_ptr).cast(),
(&raw mut n).cast(),
];
let mut generic = || -> Result<(), Error> {
Ok(module.poly_generic(&stream, &config, &x, &c, &mut y)?)
};
let mut specialised = || -> Result<(), Error> {
let grid = (blocks, 1, 1);
let block = (BLOCK, 1, 1);
// SAFETY: `poly` takes (const float*, float*, int); args points to 2 device
// pointers and an int, all alive, and the grid covers N exactly once.
unsafe { launch_kernel_on_stream(&poly, grid, block, 0, &stream, &mut args)? };
Ok(())
};
// ...
}int main()
{
// ...
CUmodule ptxModule, cubinModule;
t0 = nowMs();
loadKernel(ptx, "poly", ptxModule);
t1 = nowMs();
CUfunction poly = loadKernel(cubin, "poly", cubinModule);
t2 = nowMs();
std::printf(" load PTX %8.2f ms\n", t1 - t0);
std::printf(" load cubin %8.2f ms\n", t2 - t1);
// ...
}
int main()
{
// ...
int n = N;
int degree = DEGREE;
unsigned threads = 256;
unsigned blocks = (N + threads - 1) / threads;
void* args[] = {&X, &Y, &n};
auto generic = [&] { polyGeneric<<<blocks, threads>>>(X, Y, n, C, degree); };
auto special = [&] {
check(cuLaunchKernel(poly, blocks, 1, 1, threads, 1, 1, 0, nullptr, args, nullptr));
};
// ...
}
x.cu_deviceptr() returns the device address held by a DeviceBuffer as a u64, so x_ptr
plays the role of X in the C++ program. The expression &raw mut x_ptr takes the address of
x_ptr without creating a Rust reference, and .cast() converts it into the untyped
*mut c_void that the driver expects.
The typed launch, module.poly_generic(...), performs the same work behind a checked
signature, the list of parameter types of a function, which the compiler compares with the
arguments of each call. The #[cuda_module] attribute reads the parameter list of each kernel
when the crate is compiled and generates a method with matching Rust types, so a misplaced
argument becomes a compile error rather than a crash. A copy of the crate that swapped &mut y
and &c failed to build:
error[E0308]: mismatched types
--> src/main.rs:188:62
|
188 | Ok(module.poly_generic(&stream, &config, &x, &mut y, &c)?)
| ------------ ^^ types differ in mutability
| |
| arguments to this method are incorrect
|
= note: expected mutable reference `&mut DeviceBuffer<_>`
found reference `&DeviceBuffer<_>`
A kernel compiled at run time has no such signature at build time, in either language. When we compile kernels at run time, the program, not the compiler, is responsible for passing correct arguments.
12.6 Cost and benefit of runtime compilation
We now measure what runtime compilation costs and what it gains. The C++ program compiles the specialized kernel to PTX and to a cubin and loads both. It then runs the generic kernel for about 0.4 s so that the GPU reaches its steady clock frequency, and times 20 runs of each kernel. To verify the results, it compares all 16,777,216 outputs of the two kernels with each other, and checks every 4,099th output against Horner’s rule evaluated in double precision on the CPU.
$ ./nvrtc
GPU: Orin, compute capability 8.7, target sm_87
NVRTC, a polynomial of degree 32, 1315 bytes of source
compile to PTX 45.74 ms 2237 bytes
compile to cubin 51.99 ms 3624 bytes
load PTX 0.68 ms
load cubin 0.05 ms
p(x) for 16777216 values of x
generic, nvcc, <<<...>>> 2.605 ms 412.1 GFLOP/s
specialised, NVRTC, cuLaunch 1.840 ms 583.4 GFLOP/s
max error 5.1e-07, generic vs specialised 0.0e+00
a source with a mistake
...
PASSED
Compiling the source took 45.74 ms to produce PTX and 51.99 ms to produce a cubin, because NVRTC runs the complete compiler on the CPU once for each output. Across repeated runs, the compile time ranged from 44 ms to 88 ms, depending on the load that other programs placed on the CPU. Loading the PTX took only 0.68 ms in this run because the driver found a compiled copy in its cache; in section 12.7 we explain the cache and show that a load without it costs 13 to 45 ms. Loading the cubin took 0.05 ms, since a cubin is already machine code and only needs to be copied into the context.
The specialized kernel ran 2.605 / 1.840 = 1.42 times as fast as the generic kernel. Across the
quiet runs, the ratio ranged from 1.3 to 1.46, because the GPU clock varies between runs, as we
observed in Chapter 6. The two kernels agree to the last bit, a difference of 0.0, because both
perform the same FMAs on the same float values in the same order. Both are within
5.1 × 10⁻⁷ of the double-precision value.
To understand why the specialized kernel is faster, let us apply the analysis of arithmetic intensity from Chapter 1. Recall that the arithmetic intensity of a kernel is the number of floating-point operations it performs per byte it moves to or from memory. For each point, the kernel performs 32 FMAs, which are 64 FLOP, and moves 8 bytes, so its arithmetic intensity is 64 / 8 = 8 FLOP/B. The ridge point of a GPU is the intensity at which the time for the arithmetic equals the time for the memory traffic: its peak rate of operations divided by its memory bandwidth. A kernel below the ridge point waits for memory; a kernel above it waits for arithmetic. The GPU on which we measured can perform 2,400 GFLOP/s, and its memory delivers 102 GB/s, so its ridge point is 2,400 / 102 = 23.5 FLOP/B. Since 8 FLOP/B is below the ridge point, the computation is memory-bound, and its shortest possible time is the time to move 134.2 MB at 102 GB/s, or 1.32 ms. The specialized kernel took 1.840 ms, which corresponds to 134.2 MB / 1.840 ms = 72.9 GB/s, or 71% of the rated bandwidth. This is about the rate that a plain copy reaches on the same GPU, 68 to 78 GB/s in Chapter 7. The generic kernel, at 2.605 ms, reached only 51.5 GB/s.
The specialized kernel therefore runs at the speed of memory, and its 32 FMAs per point add no
time. The generic kernel, however, issues more instructions per point: a read of c[k] and the
loop control for k at each step. Since an intensity of 8 FLOP/B is not far below the ridge
point, these additional instructions make the SMs, rather than memory, the limiting resource. A
polynomial of lower degree would leave more headroom, and specialization would gain less; a
polynomial of higher degree would gain more. Exercise 3 asks you to measure this.
The Rust program gives the same result:
$ cargo oxide run
GPU: Orin, compute capability 8.7, target sm_87
NVRTC, 1281 bytes of source
compile to cubin 57.66 ms 3624 bytes
load cubin 0.56 ms
p(x) for 16777216 values of x
generic, typed launch 2.857 ms 375.9 GFLOP/s
specialised, raw launch 1.955 ms 549.3 GFLOP/s
max error 5.1e-7, generic vs specialised 0.0e0
a source with a mistake
...
PASSED
The specialized kernel is the same NVRTC cubin as in C++, and its time of 1.96 ms against 1.84
ms is within the 10% by which runs vary. The generic Rust kernel, compiled by cuda-oxide, ran
within 10% of the generic C++ kernel, and its results match those of the specialized kernel bit
for bit, because mul_add performs the same fused operation. When you run the programs on your
own GPU, the ratio of the 2 kernel times is the number to compare.
Whether runtime compilation pays off depends on how often the kernel runs. Each run of the specialized kernel saves 2.61 − 1.84 = 0.77 ms, while compiling the cubin and loading it costs 51.99 + 0.05 = 52 ms once. If \(T_c\) is the time to compile and load, and \(t_g\) and \(t_s\) are the times of 1 run of the generic and the specialized kernel, the number of runs needed to break even is
\[ \frac{T_c}{t_g - t_s} = \frac{52 \text{ ms}}{0.77 \text{ ms}} = 68 \]
A program that evaluates the polynomial 68 times or more gains from compiling it; a program that evaluates it once loses about 51 ms. Figure 12.6 places all of these costs on a single logarithmic time axis.
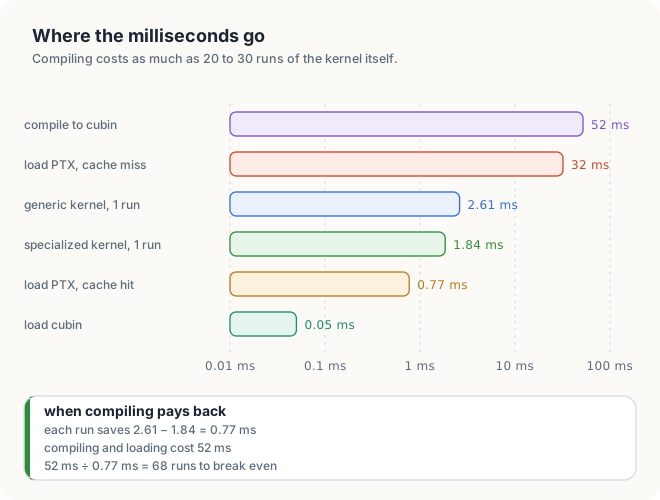
Runtime compilation costs tens of milliseconds once. It pays off when the kernel it produces runs many times.
12.7 The JIT cache
Loading PTX requires the driver to compile it into machine code, and this compilation takes time. Consider a program that loads the 2,237 bytes of PTX of our kernel and is started 10 times a day. Without help, the driver compiles the same PTX for the same GPU 10 times, at 13 to 45 ms each, and produces the same machine code each time. The result of the first compilation could have served all 10 runs, provided that it is stored somewhere that outlives the process and is found again by a later process.
Definition 12.6 JIT cache. The JIT cache is a directory in which the driver stores machine code that it has JIT-compiled from PTX. Each entry is found by a key derived from the PTX, the GPU and the driver version.
Example. The first load of the polynomial PTX on the Orin compiles it in 31.98 ms and stores the result; the next process that loads the same PTX copies the stored code in 0.77 ms.
The first load of a given PTX compiles it and stores the result. Later loads, in the same process or in any later process, copy the stored machine code instead, as figure 12.7 shows.
4 environment variables, named text values that a shell passes to every program it starts, control the cache:
| Variable | Effect |
|---|---|
CUDA_CACHE_PATH | the cache directory; ~/.nv/ComputeCache when unset |
CUDA_CACHE_MAXSIZE | the most the cache may hold, in bytes |
CUDA_CACHE_DISABLE | 1 turns the cache off |
CUDA_FORCE_PTX_JIT | 1 makes the driver ignore cubins and JIT-compile the PTX of every fatbin |
To measure the effect of the cache, we pointed CUDA_CACHE_PATH at an empty directory and ran
the program twice, and then once more with the cache disabled:
$ export CUDA_CACHE_PATH=$PWD/jitcache # an empty directory
$ ./nvrtc | grep 'load PTX'
load PTX 31.98 ms # miss: compiled, then stored
$ ./nvrtc | grep 'load PTX'
load PTX 0.77 ms # hit
$ CUDA_CACHE_DISABLE=1 ./nvrtc | grep 'load PTX'
load PTX 14.44 ms # compiled every time
In this sequence, a load that hit the cache was 31.98 / 0.77 = 42 times faster than a load that missed it. Across repeated runs, a load without the cache took 13 to 45 ms, and a load from the cache 0.68 to 0.97 ms. After the 3 runs, the cache directory held 24 KB. The driver discards the cache whenever it is upgraded, because a new driver version may compile the same PTX differently.
Note that the cache stores the work of the driver, not the work of NVRTC. A program that compiles source code at run time pays the NVRTC compile time, 44 to 88 ms in our measurements, every time it runs, unless it keeps the result itself. A long-running program can compile each distinct source once and keep the module loaded. A program that is started often can save the cubin to a file, named by a hash of the source, the target architecture and the NVRTC version, and load the file on the next run. A hash is a short number computed from the bytes of its input, such that a change of any byte almost certainly changes the number; 2 sources with the same hash can therefore be treated as the same source.
12.8 Using the runtime API and the driver API together
The C++ program of this chapter uses both APIs in the same process. The runtime API allocates
memory, copies data and launches polyGeneric with <<<...>>>, while the driver API loads the
modules produced by NVRTC and launches poly. The pointer X returned by cudaMalloc is
passed directly in the argument array of cuLaunchKernel. This works because both APIs operate
on the same context: the primary context, which the runtime API uses for all of its calls and
which cuDevicePrimaryCtxRetain returns, as figure 12.8 shows.
Since CUDA 12.2, the driver also loads the kernels of a module lazily by default
(CUDA_MODULE_LOADING=LAZY). Lazy loading postpones the preparation of each kernel until
the kernel is first needed: part of the loading work moves from cuModuleLoadData to the first
launch of each kernel, and a kernel that is never launched is never prepared. The warm-up runs
of section 12.6 absorb this cost, so the measured times include only the kernels themselves.
12.9 When to compile at run time
Runtime compilation is worth its cost in three situations:
- The kernel depends on values known only at run time, and it runs often enough to repay the compilation, as in section 12.6. Typical values are sizes, shapes, coefficients, and the choice of operations to fuse. The PyTorch compiler, for example, generates fused kernels after it has seen the tensor shapes of a model.
- The kernel source comes from outside the program. A tool that lets its users write kernels, or a Python library such as CuPy that accepts CUDA C++ source as a string, compiles that source with NVRTC.
- The program must run on GPUs it was not built for. Compiling at start-up for the GPU that is present produces the best machine code for that GPU, including GPUs released after the program.
Runtime compilation is the wrong choice for a kernel whose source never changes. Such a kernel
is better compiled once by nvcc on the developer’s machine, where the compiler warnings are
visible to the developer. A fatbin with cubins for the known GPUs and PTX for the newest virtual
architecture also covers future GPUs:
$ nvcc app.cu -o app -gencode arch=compute_87,code=[sm_87,sm_90,compute_87]
Here, arch=compute_87 names the virtual architecture for which the source is compiled, and
code= lists the contents of the fatbin: cubins for sm_87 and sm_90, and the compute_87
PTX itself, which the driver can JIT-compile on any later GPU. The following table summarizes
the choices.
| Situation | Choose |
|---|---|
| fixed kernel, known GPUs | nvcc, cubins in the fatbin |
| fixed kernel, future GPUs too | nvcc, cubins + PTX for the newest virtual architecture |
| kernel depends on run-time values, runs many times | NVRTC to a cubin for the GPU found |
| user-supplied kernel | NVRTC, with the log shown to the user |
| kernel depends on run-time values, runs once | the generic kernel |
12.10 The complete programs
Listing 12.10 The complete programs.
//! Chapter 12 in Rust: a kernel compiled by NVRTC while the program runs, loaded and
//! launched through cuda-core, the crate that wraps the CUDA driver API.
//!
//! cargo oxide run
use std::ffi::{CString, c_char, c_int, c_void};
use std::time::Instant;
use cuda_core::launch_kernel_on_stream;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, LaunchConfig1D};
use cuda_device::{DisjointSlice, cuda_module, kernel, launch_contract, thread};
const N: usize = 1 << 24; // 16,777,216 values of x
const DEGREE: usize = 32; // p(x) = c[0] + c[1] x + ... + c[32] x^32
const BLOCK: u32 = 256;
type Error = Box<dyn std::error::Error>;
#[cuda_module]
mod kernels {
use super::*;
/// The degree and the coefficients arrive at run time, in `c`.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn poly_generic(x: &[f32], c: &[f32], mut y: DisjointSlice<f32>) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(out) = y.get_mut(idx) {
let v = x[i];
let mut k = c.len() - 1;
let mut p = c[k];
while k > 0 {
k -= 1;
p = p.mul_add(v, c[k]);
}
*out = p;
}
}
}
/// An NVRTC program handle, and the 7 NVRTC functions this program calls.
type Program = *mut c_void;
#[link(name = "nvrtc")]
unsafe extern "C" {
fn nvrtcCreateProgram(
prog: *mut Program,
src: *const c_char,
name: *const c_char,
num_headers: c_int,
headers: *const *const c_char,
include_names: *const *const c_char,
) -> c_int;
fn nvrtcCompileProgram(
prog: Program,
num_options: c_int,
options: *const *const c_char,
) -> c_int;
fn nvrtcGetProgramLogSize(prog: Program, size: *mut usize) -> c_int;
fn nvrtcGetProgramLog(prog: Program, log: *mut c_char) -> c_int;
fn nvrtcGetCUBINSize(prog: Program, size: *mut usize) -> c_int;
fn nvrtcGetCUBIN(prog: Program, cubin: *mut c_char) -> c_int;
fn nvrtcDestroyProgram(prog: *mut Program) -> c_int;
}
/// The fixed first lines of the generated kernel.
const HEAD: &str = r#"extern "C" __global__ void poly(const float* x, float* y, int n)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i >= n) {
return;
}
float v = x[i];
"#;
/// CUDA C++ source text for the polynomial, with its coefficients written in.
fn specialised_source(c: &[f32]) -> String {
let mut src = String::from(HEAD);
src += &format!(" float p = {:.9e}f;\n", c[DEGREE]);
for k in (0..DEGREE).rev() {
src += &format!(" p = p * v + {:.9e}f;\n", c[k]);
}
src += " y[i] = p;\n}\n";
src
}
/// Compile `source` with NVRTC into a cubin for the GPU `arch`, such as "sm_87".
fn compile(source: &str, arch: &str) -> Result<Vec<u8>, Error> {
let src = CString::new(source)?;
let name = CString::new("poly.cu")?;
let option = CString::new(format!("--gpu-architecture={arch}"))?;
let options = [option.as_ptr()];
let none = std::ptr::null();
let mut prog: Program = std::ptr::null_mut();
// SAFETY: every pointer refers to a live, NUL-terminated string, to `prog`, or to a
// buffer of the size NVRTC reported.
unsafe {
let (src, name) = (src.as_ptr(), name.as_ptr());
ok(nvrtcCreateProgram(&mut prog, src, name, 0, none, none), "nvrtcCreateProgram")?;
if nvrtcCompileProgram(prog, 1, options.as_ptr()) != 0 {
let mut size = 0;
ok(nvrtcGetProgramLogSize(prog, &mut size), "nvrtcGetProgramLogSize")?;
let mut log = vec![0u8; size];
ok(nvrtcGetProgramLog(prog, log.as_mut_ptr().cast()), "nvrtcGetProgramLog")?;
nvrtcDestroyProgram(&mut prog);
log.pop(); // the terminating NUL
return Err(String::from_utf8_lossy(&log).into());
}
let mut size = 0;
ok(nvrtcGetCUBINSize(prog, &mut size), "nvrtcGetCUBINSize")?;
let mut cubin = vec![0u8; size];
ok(nvrtcGetCUBIN(prog, cubin.as_mut_ptr().cast()), "nvrtcGetCUBIN")?;
ok(nvrtcDestroyProgram(&mut prog), "nvrtcDestroyProgram")?;
Ok(cubin)
}
}
/// NVRTC returns 0 for success and an error number otherwise.
fn ok(result: c_int, call: &str) -> Result<(), Error> {
if result == 0 {
Ok(())
} else {
Err(format!("{call} failed with NVRTC error {result}").into())
}
}
/// Average time of `runs` runs of `launch`, in milliseconds, after 1 warm-up run.
fn time_ms<F>(stream: &CudaStream, runs: u32, mut launch: F) -> Result<f64, Error>
where
F: FnMut() -> Result<(), Error>,
{
launch()?;
stream.synchronize()?;
let start = Instant::now();
for _ in 0..runs {
launch()?;
}
stream.synchronize()?;
Ok(start.elapsed().as_secs_f64() * 1e3 / runs as f64)
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
let (major, minor) = ctx.compute_capability()?;
let arch = format!("sm_{major}{minor}");
let name = ctx.device_name()?;
println!("GPU: {name}, compute capability {major}.{minor}, target {arch}");
let c_host: Vec<f32> = (0..=DEGREE).map(|k| 1.0 / (k + 1) as f32).collect();
let x_host: Vec<f32> = (0..N).map(|i| 2.0 * i as f32 / N as f32 - 1.0).collect();
let source = specialised_source(&c_host);
let start = Instant::now();
let cubin = compile(&source, &arch)?;
let compile_ms = start.elapsed().as_secs_f64() * 1e3;
println!("NVRTC, {} bytes of source", source.len());
println!(" compile to cubin {compile_ms:8.2} ms {:6} bytes", cubin.len());
let start = Instant::now();
let special = ctx.load_module_from_image(&cubin)?;
let poly = special.load_function("poly")?;
let load_ms = start.elapsed().as_secs_f64() * 1e3;
println!(" load cubin {load_ms:8.2} ms");
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let x = DeviceBuffer::from_host(&stream, &x_host)?;
let c = DeviceBuffer::from_host(&stream, &c_host)?;
let mut y = DeviceBuffer::<f32>::zeroed(&stream, N)?;
let blocks = (N as u32).div_ceil(BLOCK);
let config = module.prepare_poly_generic(LaunchConfig1D::new(blocks, BLOCK, 0))?;
let mut x_ptr = x.cu_deviceptr();
let mut y_ptr = y.cu_deviceptr();
let mut n = N as c_int;
let mut args: [*mut c_void; 3] = [
(&raw mut x_ptr).cast(),
(&raw mut y_ptr).cast(),
(&raw mut n).cast(),
];
let mut generic = || -> Result<(), Error> {
Ok(module.poly_generic(&stream, &config, &x, &c, &mut y)?)
};
let mut specialised = || -> Result<(), Error> {
let grid = (blocks, 1, 1);
let block = (BLOCK, 1, 1);
// SAFETY: `poly` takes (const float*, float*, int); args points to 2 device
// pointers and an int, all alive, and the grid covers N exactly once.
unsafe { launch_kernel_on_stream(&poly, grid, block, 0, &stream, &mut args)? };
Ok(())
};
for _ in 0..20 {
time_ms(&stream, 5, &mut generic)?; // warm up: clocks rise under sustained load
}
let flop = 2.0 * DEGREE as f64 * N as f64;
println!("p(x) for {N} values of x");
let ms = time_ms(&stream, 20, &mut generic)?;
let y_generic = y.to_host_vec(&stream)?;
println!(" generic, typed launch {ms:7.3} ms {:6.1} GFLOP/s", flop / ms / 1e6);
let ms = time_ms(&stream, 20, &mut specialised)?;
let y_special = y.to_host_vec(&stream)?;
println!(" specialised, raw launch {ms:7.3} ms {:6.1} GFLOP/s", flop / ms / 1e6);
let mut worst: f64 = 0.0;
for i in (0..N).step_by(4099) {
let mut exact = 0.0;
for k in (0..=DEGREE).rev() {
exact = exact * x_host[i] as f64 + c_host[k] as f64;
}
worst = worst.max((exact - y_special[i] as f64).abs());
}
let mut differ: f32 = 0.0;
for i in 0..N {
differ = differ.max((y_generic[i] - y_special[i]).abs());
}
println!(" max error {worst:.1e}, generic vs specialised {differ:.1e}");
println!("a source with a mistake");
let broken = source.replace("y[i] = p", "y[i] = q");
if let Err(log) = compile(&broken, &arch) {
print!(" compile failed, log:\n{log}");
}
if worst < 1e-4 && differ < 1e-5 {
println!("PASSED");
Ok(())
} else {
Err("FAILED".into())
}
}// Chapter 12: a kernel written, compiled and launched while the program runs.
// Build: nvcc -arch=native nvrtc.cu -o nvrtc -lnvrtc -lcuda
#include <chrono>
#include <cmath>
#include <cstdio>
#include <cstdlib>
#include <string>
#include <vector>
#include <cuda.h>
#include <cuda_runtime.h>
#include <nvrtc.h>
const int N = 1 << 24; // 16,777,216 values of x
const int DEGREE = 32; // p(x) = c[0] + c[1] x + ... + c[32] x^32
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA runtime error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
void check(CUresult err)
{
if (err != CUDA_SUCCESS) {
const char* name = "unknown";
cuGetErrorName(err, &name);
std::fprintf(stderr, "CUDA driver error: %s\n", name);
std::exit(1);
}
}
void check(nvrtcResult err)
{
if (err != NVRTC_SUCCESS) {
std::fprintf(stderr, "NVRTC error: %s\n", nvrtcGetErrorString(err));
std::exit(1);
}
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// Average time of `runs` runs of `launch`, in milliseconds, after 1 warm-up run.
template <typename F>
double timeKernel(F launch, int runs)
{
launch();
check(cudaDeviceSynchronize());
double t0 = nowMs();
for (int r = 0; r < runs; ++r) {
launch();
}
check(cudaGetLastError());
check(cudaDeviceSynchronize());
return (nowMs() - t0) / runs;
}
// Compiled by nvcc with the program: the degree and the coefficients arrive at run time.
__global__ void polyGeneric(const float* x, float* y, int n, const float* c, int degree)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i >= n) {
return;
}
float v = x[i];
float p = c[degree];
for (int k = degree - 1; k >= 0; --k) {
p = p * v + c[k];
}
y[i] = p;
}
// CUDA C++ source text for the same polynomial, with its coefficients written in.
std::string specialisedSource(const std::vector<float>& c)
{
std::string src = "extern \"C\" __global__ void poly(const float* x, float* y, int n)\n"
"{\n"
" int i = blockIdx.x * blockDim.x + threadIdx.x;\n"
" if (i >= n) {\n"
" return;\n"
" }\n"
"\n"
" float v = x[i];\n";
char line[64];
std::snprintf(line, sizeof line, " float p = %.9ef;\n", c[DEGREE]);
src += line;
for (int k = DEGREE - 1; k >= 0; --k) {
std::snprintf(line, sizeof line, " p = p * v + %.9ef;\n", c[k]);
src += line;
}
src += " y[i] = p;\n}\n";
return src;
}
// Compile `source` with NVRTC: a cubin for 1 GPU ("sm_87"), or PTX for the driver.
std::vector<char> compile(const std::string& source, const std::string& arch, bool cubin)
{
nvrtcProgram prog;
check(nvrtcCreateProgram(&prog, source.c_str(), "poly.cu", 0, nullptr, nullptr));
std::string target = cubin ? arch : "compute_" + arch.substr(3);
std::string option = "--gpu-architecture=" + target;
const char* options[] = {option.c_str()};
nvrtcResult result = nvrtcCompileProgram(prog, 1, options);
if (result != NVRTC_SUCCESS) {
size_t logSize;
check(nvrtcGetProgramLogSize(prog, &logSize));
std::string log(logSize, '\0');
check(nvrtcGetProgramLog(prog, log.data()));
std::printf(" compile failed, log:\n%s", log.c_str());
check(nvrtcDestroyProgram(&prog));
return {};
}
size_t size;
std::vector<char> image;
if (cubin) {
check(nvrtcGetCUBINSize(prog, &size));
image.resize(size);
check(nvrtcGetCUBIN(prog, image.data()));
} else {
check(nvrtcGetPTXSize(prog, &size));
image.resize(size);
check(nvrtcGetPTX(prog, image.data()));
}
check(nvrtcDestroyProgram(&prog));
return image;
}
// Load a PTX or cubin image into the current context and find the kernel `name` in it.
CUfunction loadKernel(const std::vector<char>& image, const char* name, CUmodule& module)
{
check(cuModuleLoadData(&module, image.data()));
CUfunction kernel;
check(cuModuleGetFunction(&kernel, module, name));
return kernel;
}
int main()
{
check(cuInit(0));
CUdevice device;
check(cuDeviceGet(&device, 0));
CUcontext context;
check(cuDevicePrimaryCtxRetain(&context, device));
check(cuCtxSetCurrent(context));
int major, minor;
auto majorAttr = CU_DEVICE_ATTRIBUTE_COMPUTE_CAPABILITY_MAJOR;
auto minorAttr = CU_DEVICE_ATTRIBUTE_COMPUTE_CAPABILITY_MINOR;
check(cuDeviceGetAttribute(&major, majorAttr, device));
check(cuDeviceGetAttribute(&minor, minorAttr, device));
std::string arch = "sm_" + std::to_string(major * 10 + minor);
char name[256];
check(cuDeviceGetName(name, sizeof name, device));
std::printf("GPU: %s, compute capability %d.%d, ", name, major, minor);
std::printf("target %s\n", arch.c_str());
std::vector<float> c(DEGREE + 1), x(N), yGeneric(N), ySpecial(N);
for (int k = 0; k <= DEGREE; ++k) {
c[k] = 1.0f / (k + 1);
}
for (int i = 0; i < N; ++i) {
x[i] = 2.0f * i / N - 1.0f;
}
std::string source = specialisedSource(c);
std::printf("NVRTC, a polynomial of degree %d, ", DEGREE);
std::printf("%zu bytes of source\n", source.size());
double t0 = nowMs();
std::vector<char> ptx = compile(source, arch, false);
double t1 = nowMs();
std::vector<char> cubin = compile(source, arch, true);
double t2 = nowMs();
std::printf(" compile to PTX %8.2f ms %6zu bytes\n", t1 - t0, ptx.size());
std::printf(" compile to cubin %8.2f ms %6zu bytes\n", t2 - t1, cubin.size());
CUmodule ptxModule, cubinModule;
t0 = nowMs();
loadKernel(ptx, "poly", ptxModule);
t1 = nowMs();
CUfunction poly = loadKernel(cubin, "poly", cubinModule);
t2 = nowMs();
std::printf(" load PTX %8.2f ms\n", t1 - t0);
std::printf(" load cubin %8.2f ms\n", t2 - t1);
size_t bytes = size_t(N) * sizeof(float);
size_t coeffBytes = c.size() * sizeof(float);
float *X, *Y, *C;
check(cudaMalloc(&X, bytes));
check(cudaMalloc(&Y, bytes));
check(cudaMalloc(&C, coeffBytes));
check(cudaMemcpy(X, x.data(), bytes, cudaMemcpyHostToDevice));
check(cudaMemcpy(C, c.data(), coeffBytes, cudaMemcpyHostToDevice));
int n = N;
int degree = DEGREE;
unsigned threads = 256;
unsigned blocks = (N + threads - 1) / threads;
void* args[] = {&X, &Y, &n};
auto generic = [&] { polyGeneric<<<blocks, threads>>>(X, Y, n, C, degree); };
auto special = [&] {
check(cuLaunchKernel(poly, blocks, 1, 1, threads, 1, 1, 0, nullptr, args, nullptr));
};
for (int k = 0; k < 20; ++k) { // warm up: clocks rise under sustained load
timeKernel(generic, 5);
}
double flop = 2.0 * DEGREE * N;
std::printf("p(x) for %d values of x\n", N);
double ms = timeKernel(generic, 20);
check(cudaMemcpy(yGeneric.data(), Y, bytes, cudaMemcpyDeviceToHost));
std::printf(" generic, nvcc, <<<...>>> %7.3f ms", ms);
std::printf(" %6.1f GFLOP/s\n", flop / ms / 1e6);
ms = timeKernel(special, 20);
check(cudaMemcpy(ySpecial.data(), Y, bytes, cudaMemcpyDeviceToHost));
std::printf(" specialised, NVRTC, cuLaunch %7.3f ms", ms);
std::printf(" %6.1f GFLOP/s\n", flop / ms / 1e6);
double worst = 0.0;
for (int i = 0; i < N; i += 4099) {
double exact = 0.0;
for (int k = DEGREE; k >= 0; --k) {
exact = exact * x[i] + c[k];
}
worst = std::fmax(worst, std::fabs(exact - ySpecial[i]));
}
double differ = 0.0;
for (int i = 0; i < N; ++i) {
differ = std::fmax(differ, std::fabs(yGeneric[i] - ySpecial[i]));
}
std::printf(" max error %.1e, generic vs specialised %.1e\n", worst, differ);
std::printf("a source with a mistake\n");
std::string broken = source;
broken.replace(broken.find("y[i] = p"), 8, "y[i] = q");
compile(broken, arch, true);
check(cuModuleUnload(ptxModule));
check(cuModuleUnload(cubinModule));
check(cudaFree(X));
check(cudaFree(Y));
check(cudaFree(C));
check(cuDevicePrimaryCtxRelease(device));
std::printf(worst < 1e-4 && differ == 0.0 ? "PASSED\n" : "FAILED\n");
}
Common mistakes
- Passing
Xinstead of&Xin the argument array. The driver reads each argument through the address in the array; with the device address in its place, the program crashed with a segmentation fault. - Omitting
extern "C"from the kernel declaration. The name is mangled, andcuModuleGetFunctionreturnsCUDA_ERROR_NOT_FOUND. - Ignoring the compilation log.
nvrtcCompileProgramreports only that the compilation failed; the reason is in the log. - Writing a constant without the
fsuffix.0.5is adoublein C++, and the arithmetic around it is performed in double precision. - Loading a cubin built for another GPU. A cubin for
sm_90does not load on ansm_87GPU. Ask the driver for the compute capability and compile for it. - Creating a second context. Memory from
cudaMallocbelongs to the primary context. Retain that context instead of creating a new one withcuCtxCreate. - Compiling in a loop. Compile each distinct source once, keep the module, and reuse it.
Summary
- The runtime API creates a context, registers kernels and packs arguments, and all 3 services require the kernel to exist when the program is built. The driver API exposes the objects beneath it: device, context, module and function. cuda-core is built directly on the driver API.
- PTX is portable code for a virtual GPU and is JIT-compiled by the driver; a cubin is machine code for 1 GPU generation; a fatbin bundles both.
- NVRTC compiles CUDA C++ from a string in 5 calls, to PTX or to a cubin for the GPU that the program finds. Its error messages are in the compilation log.
cuModuleLoadData,cuModuleGetFunctionandcuLaunchKernelload, look up and launch the result. The argument array holds the address of each argument.- A polynomial of degree 32 specialized to its coefficients ran 1.3 to 1.46 times as fast as the generic kernel, at 71% of the rated memory bandwidth, with bit-identical results. Compiling it cost about 52 ms, which was repaid after 68 runs.
- The JIT cache reduced a PTX load of 13 to 45 ms to about 0.7 ms for every later process.
- Retaining the primary context allows the runtime API and the driver API to share memory.
In Chapter 13, we begin Part V, in which every kernel is written in Rust with cuda-oxide. The
kernels::load call in each of those programs is the driver API load described in this chapter.
Exercises
- Compile the specialized source to a cubin for
compute_87instead ofsm_87. What doesnvrtcGetCUBINSizereturn, and why? - Change the program to load only the PTX, with
CUDA_CACHE_DISABLE=1, and time 10 loads in 1 process. Does the driver compile the PTX again each time? - Run the program for degrees 4, 8, 16, 32, 64 and 128. Plot the time of both kernels against the degree, mark the degree at which the computation stops being memory-bound on your GPU, and explain where the ratio of the 2 kernel times grows.
- Write the coefficients with
%.3einstead of%.9e. Does the result still match the generic kernel bit for bit? How large is the difference? - Remove
extern "C"from the generated source, and look up the kernel by its mangled name,_Z4polyPKfPfi. Then find the name without guessing: NVRTC’snvrtcAddNameExpressionandnvrtcGetLoweredNamereturn the mangled name of a C++ function. - Save the cubin to a file named by a hash of the source and the target, and load it with
cuModuleLoadDataon the next run. How long does the program take to reach the first launch? - In the Rust program, change
argsto holdx_ptr as *mut c_voidinstead of its address. Run it, and explain the result with figure 12.5. - Using the break-even formula of section 12.6, how many runs would repay the compilation on a GPU on which the specialized and generic kernels take 0.08 ms and 0.11 ms?
- The program compiles for
sm_87rather than forcompute_60, which would run on every GPU since 2016. Explain why, using the load times of the cubin and the PTX in sections 12.6 and 12.7, and what an older virtual architecture prevents the compiler from using. - A data center upgrades its GPU driver overnight. What happens to the first run of each program the next morning? Which programs are not affected, and why?
Sources and further reading
- NVIDIA, NVRTC User Guide: https://docs.nvidia.com/cuda/nvrtc/
- NVIDIA, CUDA Driver API, modules and execution control: https://docs.nvidia.com/cuda/cuda-driver-api/
- NVIDIA, CUDA C++ Programming Guide, “Compilation with NVCC”, “Binary Compatibility”, “PTX Compatibility”, “Just-in-Time Compilation” and “Lazy Loading”: https://docs.nvidia.com/cuda/cuda-c-programming-guide/
- NVIDIA, CUDA Environment Variables: https://docs.nvidia.com/cuda/cuda-c-programming-guide/#cuda-environment-variables
- NVIDIA, NVCC, “GPU Compilation” and
-gencode: https://docs.nvidia.com/cuda/cuda-compiler-driver-nvcc/ - NVIDIA, cuda-oxide,
cuda-corecrate (CudaContext,CudaModule,launch_kernel_on_stream), rev b7fe543: https://github.com/NVlabs/cuda-oxide
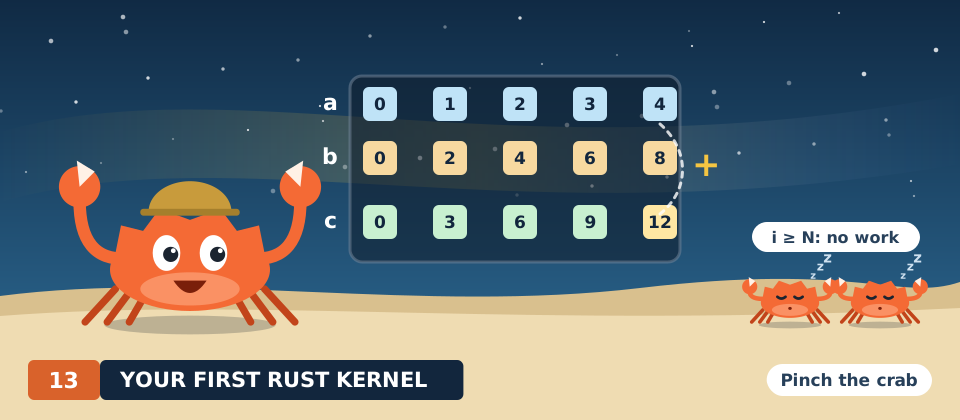
Chapter 13: Your First Rust Kernel
This chapter covers
- the mapping of data elements to GPU threads
- the computation of a thread’s global index from its block index and thread index
- the installation of cuda-oxide and the contents of
Cargo.toml - a vector-addition kernel written in Rust
- the host program: device buffers, the kernel launch and the copy back
- Two common launch errors and their real output
In this part, we write GPU kernels in Rust with cuda-oxide, NVIDIA’s compiler backend that compiles ordinary Rust functions into GPU code. The kernel and the host program that launches it are written in the same .rs file, and both are built with a single command.
The first kernel adds 2 vectors. We choose this computation because its arithmetic is trivial, so that we can concentrate on the structure of a GPU program: how threads are mapped to data, how data is moved between host and device, and how a kernel is launched. The kernels of the later chapters in this part, dot products, matrix multiplication, stencils and scans, use the same structure.
cuda-oxide is experimental. cuda-oxide is a young project, and its API changes much faster than
the API of CUDA C++. We wrote the Rust programs of this book in November 2026 against commit
b7fe543 of cuda-oxide (21 August 2026), with Rust nightly-2026-04-03 and CUDA 12.6, and every
program pins that commit in its Cargo.toml. The API has changed since then: later versions of
cuda-oxide require CUDA 13 and a stable Rust toolchain, and some of the names and signatures used
here may differ in them. A reader who needs an API that does not break between releases should use
CUDA C++, which we show beside every Rust program. The concepts do not depend on the version. The
mapping of threads to data, the launch configuration, shared memory, barriers and the arguments
for why a kernel is correct carry over unchanged to any version of cuda-oxide and to CUDA C++, and
so does everything we learn with them.
13.1 Vector addition
Vector addition takes 2 vectors a and b of the same length N and produces a third vector c, each of whose elements is the sum of the 2 input elements at the same position:
c[i] = a[i] + b[i] for every i from 0 to N - 1
For 4 elements:
| i | a[i] | b[i] | c[i] |
|---|---|---|---|
| 0 | 0.0 | 0.0 | 0.0 |
| 1 | 1.0 | 2.0 | 3.0 |
| 2 | 2.0 | 4.0 | 6.0 |
| 3 | 3.0 | 6.0 | 9.0 |
Note that the computation of c[2] requires only a[2] and b[2]. It does not require c[1] or any other element of c. The elements of c are therefore independent of each other, and they can be computed in any order, or all at the same time. This independence is what allows a GPU to speed up the computation.
13.2 One thread per element
On a CPU, vector addition is written as a loop, and 1 core executes the iterations one after another: element 0, then element 1, then element 2.
On a GPU, the programmer writes the body of the loop as a function, and the GPU executes 1 instance of that function for each element. Each instance is executed by a thread. Thread 0 computes c[0], thread 1 computes c[1], and so on, and the threads run at the same time (figure 13.1). The loop has been replaced by the set of threads. Each thread corresponds to 1 iteration of the original loop.
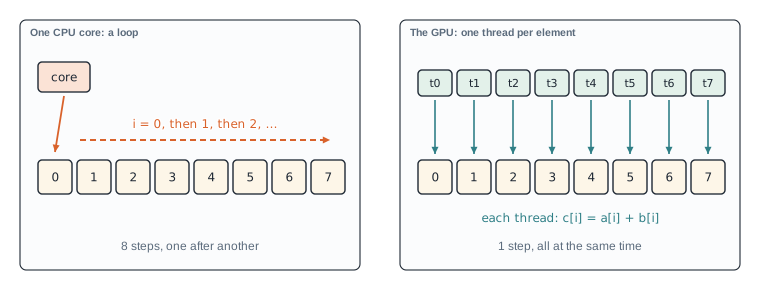
The function that the threads execute is called a kernel. The host program, which runs on the CPU, launches the kernel and decides how many threads execute it.
NOTE: A kernel is a function that runs on the GPU, once per thread. It is written once. The hardware decides how many of the threads run at the same moment.
13.3 Thread indices
Since every thread executes the same code, each thread needs a way to determine which element it is responsible for. Thread 7, for example, must add a[7] and b[7] and not some other pair. The GPU provides this information through built-in indices.
Threads are launched in groups called blocks. All blocks of a launch contain the same number of threads, and the blocks of a launch together form the grid. Each thread can read 2 numbers:
- the index of the block it belongs to, the block index
- its position within that block, the thread index
From these 2 numbers the thread computes its global index:
i = block_index × threads_per_block + thread_index
Consider N = 20 elements and blocks of 8 threads. The grid must contain at least 20 threads, so the number of blocks is 20 / 8 = 2.5 rounded up to 3, which gives 24 threads (figure 13.2).
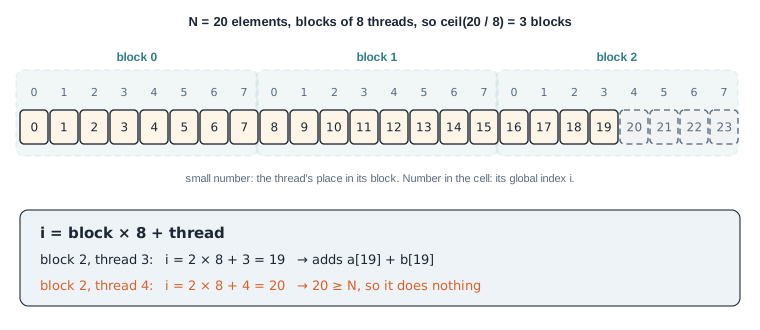
Thread 3 of block 2 computes 2 × 8 + 3 = 19 and adds a[19] and b[19]. Thread 4 of block 2 computes 20. There is no element 20, so this thread must not access memory.
Such spare threads exist whenever N is not a multiple of the block size, which is the usual case. Every kernel therefore contains a guard that disables the threads whose index lies past the end of the data. In CUDA C++ the programmer writes this guard by hand, and omitting it is a common bug. In cuda-oxide the guard is enforced by the type of the output parameter, as we show in section 13.6.
13.4 Structure of the program
The complete program is given below in pseudocode. The kernel consists of 4 lines. The rest is the host program, which prepares the data and launches the kernel.
KERNEL vector_add(a, b, c):
i ← block_index × block_size + thread_index
if i < length(c):
c[i] ← a[i] + b[i]
HOST:
make a and b in CPU memory
copy a and b to GPU memory; make an empty c there
blocks ← ceil(N / block_size)
launch vector_add with (blocks × block_size) threads
copy c back to CPU memory
check c against a plain CPU loop
The kernel operates on GPU memory. The host program therefore copies the inputs to the GPU, launches the kernel, and copies the result back to CPU memory (figure 13.3).
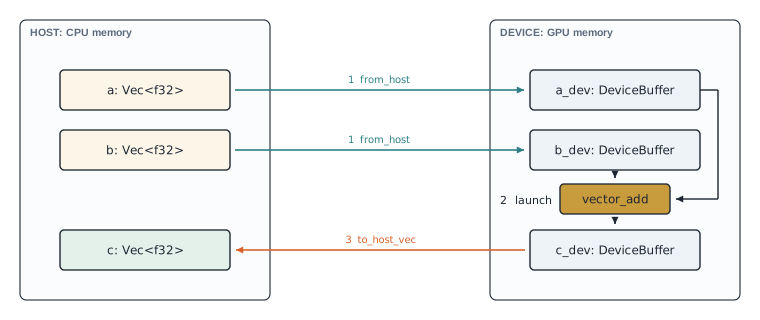
NOTE: On an integrated GPU, the CPU and the GPU share the same physical memory, and the program still copies. The copy places the data in memory allocated for the GPU, and the same code then runs unchanged on a discrete GPU with its own memory. We describe ways to avoid the copy in later chapters.
13.5 Setting up cuda-oxide
A cuda-oxide program requires 4 components:
| You need | Version | How to check |
|---|---|---|
| Linux | Ubuntu 22.04 or 24.04 | lsb_release -a |
| An NVIDIA GPU | Ampere or newer (sm_80+) | nvidia-smi |
| The CUDA Toolkit | 12.x or 13.x | nvcc --version |
| Rust nightly | the version cuda-oxide pins | installed for you by rustup |
The build is driven by a cargo subcommand. We install it and then let it check the machine:
$ cargo +nightly-2026-04-03 install --git https://github.com/NVlabs/cuda-oxide.git cargo-oxide
$ cargo oxide doctor
doctor reports any missing component: a GPU, the toolkit, LLVM, or the compiler backend. On first use, cargo-oxide downloads and builds the backend once and caches it. Any problem that doctor reports must be fixed before the program can be built.
Project layout
The project consists of 3 files:
vector_add/
├── Cargo.toml
├── rust-toolchain.toml
└── src/
└── main.rs
TIP:
cargo oxide new vector_addcreates the same layout with a working example inside. Writing the 3 files by hand once shows the purpose of each.
rust-toolchain.toml
cuda-oxide is a backend of the Rust compiler, so it requires 1 exact nightly version of the compiler. This file makes cargo select that version for every command run in the directory:
[toolchain]
channel = "nightly-2026-04-03"
components = ["rust-src", "rustc-dev", "rust-analyzer", "clippy", "rustfmt", "llvm-tools"]
The component rust-src allows the compiler to build the standard library for the GPU. rustc-dev contains the compiler internals that the backend links against. llvm-tools provides the code generator that translates the kernel into GPU instructions.
Cargo.toml
[package]
name = "vector_add"
version = "0.1.0"
edition = "2024"
# A standalone crate: not part of any parent workspace.
[workspace]
[dependencies]
# Device side: #[kernel], thread indexing, DisjointSlice.
cuda-device = { git = "https://github.com/NVlabs/cuda-oxide.git", rev = "b7fe543b863cdef46362e5f69797906b84d499c7" }
# Host side: the #[cuda_module] macro that generates the typed launcher.
cuda-host = { git = "https://github.com/NVlabs/cuda-oxide.git", rev = "b7fe543b863cdef46362e5f69797906b84d499c7" }
# Host runtime: context, stream, device buffers, launch configurations.
cuda-core = { git = "https://github.com/NVlabs/cuda-oxide.git", rev = "b7fe543b863cdef46362e5f69797906b84d499c7" }
The entries have the following meaning:
edition = "2024"is the Rust edition for which cuda-oxide is written.- The empty
[workspace]table marks the crate as standalone. Without it, cargo searches the parent directories for a workspace, and inside this book’s repository it would find the wrong one. cuda-devicecontains everything the kernel uses on the GPU:#[kernel], the thread indices andDisjointSlice.cuda-hostprovides#[cuda_module], the macro that generates the host-side launch functions for the kernels.cuda-coreis the host runtime: the GPU context, streams, device buffers and launch configurations.- All 3 crates come from the same git repository.
revpins 1 exact commit, so that the program builds the same way in the future. The same commit must be used for all 3 crates.
13.6 The kernel
The program begins with its imports. Each name is explained where it is used.
use std::time::Instant;
use cuda_core::{CudaContext, DeviceBuffer, LaunchConfig1D};
use cuda_device::{DisjointSlice, cuda_module, kernel, launch_bounds, launch_contract, thread};#include <chrono>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cuda_runtime.h>
Two constants set the size of the problem. N is chosen not to be a multiple of 256, so that the last block contains spare threads, as in figure 13.2.
/// Threads per block. The kernel's launch contract names the same number.
const BLOCK: u32 = 256;
/// The number of elements. It is not a multiple of `BLOCK`, so the last
/// block has threads with no element to add.
const N: usize = 1_000_003;// Threads per block. The kernel's launch bounds name the same number.
const int BLOCK = 256;
// The number of elements. It is not a multiple of BLOCK, so the last
// block has threads with no element to add.
const int N = 1000003;
The kernel itself is defined inside a module:
#[cuda_module]
mod kernels {
use super::*;
/// One thread adds one pair of elements.
#[kernel]
#[launch_bounds(256)]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn vector_add(a: &[f32], b: &[f32], mut c: DisjointSlice<f32>) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(out) = c.get_mut(idx) {
*out = a[i] + b[i];
}
}
}// One thread adds one pair of elements.
__global__ void __launch_bounds__(256)
vectorAdd(const float* a, const float* b, float* c, int n)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
c[i] = a[i] + b[i];
}
}
We examine its parts from the outside in.
#[cuda_module] mod kernels groups the kernels that the program launches. At build time, cuda-oxide compiles everything inside the module for the GPU and embeds the result in the executable. It also generates host functions that load this code and launch each kernel; we use them in section 13.7.
#[kernel] marks vector_add as a GPU entry point, a function that the host can launch. The CPU never executes its body. The function is type-checked like any other Rust function, so a type error in a kernel is a compile error.
#[launch_bounds(256)] tells the compiler that a block never contains more than 256 threads. With this limit known, the compiler can decide how many registers each thread may use.
#[launch_contract(domain = 1, block = (256, 1, 1))] states how the kernel must be launched: with a 1-dimensional grid, and with blocks of exactly 256 threads. The host checks the contract before every launch. In Section 13.9, we show what happens when a launch violates it.
The parameters have ordinary Rust types. a and b are shared slices, &[f32], because every thread may read any element of them. The output c has the type DisjointSlice<f32>, which is what makes the kernel free of data races.
DisjointSlice
If 2 threads wrote the same element at the same time, the final value would depend on which write happened last. Such a situation is called a data race, and Rust’s ownership rules are designed to exclude it. A &mut [f32] cannot be given to many threads at once, because a mutable reference permits only 1 writer.
DisjointSlice never gives a thread access to the whole slice. Instead, each thread may request exactly 1 element, the element at its own global index (figure 13.4).
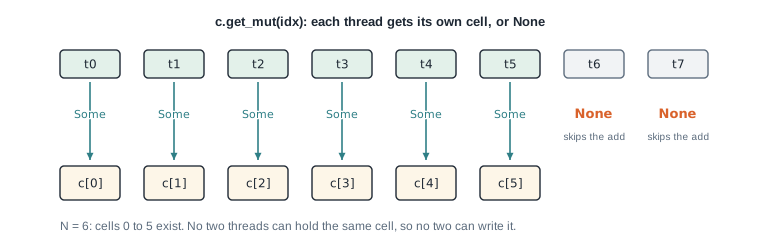
get_mut returns Some with the thread's own element, or None for a thread past the end.The body of the kernel consists of the following statements:
let idx = thread::index_1d();
let i = idx.get();
if let Some(out) = c.get_mut(idx) {
*out = a[i] + b[i];
}int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
c[i] = a[i] + b[i];
}
thread::index_1d()computes block index × block size + thread index, the formula of section 13.3, and returns the result as a special index type. A value of this type can only be obtained from the thread’s own position, so a thread cannot construct the index of another thread.idx.get()returns the same number as a plainusize, which is used to readaandb.c.get_mut(idx)returnsSome(&mut f32)when the index lies insidec, andNonewhen it lies past the end. This is the guard of section 13.3. The kernel contains no explicitif i < n; the type ofcrequires the kernel to handle the spare threads.a[i]andb[i]are ordinary Rust indexing operations and are bounds-checked. Ifawere shorter thanc, the thread would stop with an error instead of reading memory outside the array.
The last point differs from CUDA C++, where a read past the end of an array returns whatever bytes are stored at that address.
13.7 The host program
The host program follows the pseudocode of section 13.4 step by step. It is compiled together with the kernel, from the same file, by a single command (figure 13.5).
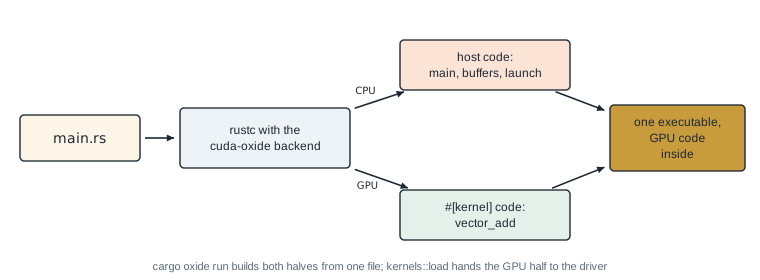
Context, stream and device buffers
fn main() -> Result<(), Box<dyn std::error::Error>> {
// 1. Inputs on the host.
let a: Vec<f32> = (0..N).map(|i| i as f32).collect();
let b: Vec<f32> = (0..N).map(|i| 2.0 * i as f32).collect();
// 2. A context on GPU 0, and the stream that orders our work on it.
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// 3. Copy the inputs to device memory and allocate the output.
let a_dev = DeviceBuffer::from_host(&stream, &a)?;
let b_dev = DeviceBuffer::from_host(&stream, &b)?;
let mut c_dev = DeviceBuffer::<f32>::zeroed(&stream, N)?;
// ...
}int main()
{
// 1. Inputs on the host.
std::vector<float> a(N), b(N);
for (int i = 0; i < N; ++i) {
a[i] = float(i);
b[i] = 2.0f * float(i);
}
// 2. GPU 0, and a stream that orders our work on it.
check(cudaSetDevice(0));
cudaStream_t stream;
check(cudaStreamCreate(&stream));
// 3. Copy the inputs to device memory and allocate the output.
size_t bytes = N * sizeof(float);
float *a_dev, *b_dev, *c_dev;
check(cudaMalloc(&a_dev, bytes));
check(cudaMalloc(&b_dev, bytes));
check(cudaMalloc(&c_dev, bytes));
check(cudaMemcpyAsync(a_dev, a.data(), bytes, cudaMemcpyHostToDevice, stream));
check(cudaMemcpyAsync(b_dev, b.data(), bytes, cudaMemcpyHostToDevice, stream));
check(cudaMemsetAsync(c_dev, 0, bytes, stream));
// ...
}
CudaContext::new(0)opens GPU number 0. A context holds all the state that the program owns on that GPU, including its memory allocations and its loaded code.- A stream is a queue of GPU work. Operations issued to the same stream are executed in the order in which they were issued. This ordering guarantees that the copy, the launch and the copy back happen in sequence without any explicit synchronization.
DeviceBuffer::from_hostallocates GPU memory and copies a slice into it.DeviceBuffer::zeroedallocates GPU memory and fills it with zeros. Each buffer frees its GPU memory when it is dropped, in the same way that aVecfrees its heap memory.
Loading the module and launching the kernel
fn main() -> Result<(), Box<dyn std::error::Error>> {
// ...
// 4. Load the GPU code that the compiler embedded in this binary.
// SAFETY: the bundle was built from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
// 5. Enough blocks to cover N: ceil(N / BLOCK).
let blocks = (N as u32).div_ceil(BLOCK);
let prepared = module.prepare_vector_add(LaunchConfig1D::new(blocks, BLOCK, 0))?;
// 6. Launch, then copy the result back. The copy waits for the kernel.
let start = Instant::now();
module.vector_add(&stream, &prepared, &a_dev, &b_dev, &mut c_dev)?;
let c = c_dev.to_host_vec(&stream)?;
let gpu_time = start.elapsed();
// ...
}int main()
{
// ...
// 4. Enough blocks to cover N: ceil(N / BLOCK).
int blocks = (N + BLOCK - 1) / BLOCK;
// 5. Launch, then copy the result back. The copy waits for the kernel.
std::vector<float> c(N);
auto start = std::chrono::steady_clock::now();
vectorAdd<<<blocks, BLOCK, 0, stream>>>(a_dev, b_dev, c_dev, N);
check(cudaGetLastError());
check(cudaMemcpyAsync(c.data(), c_dev, bytes, cudaMemcpyDeviceToHost, stream));
check(cudaStreamSynchronize(stream));
double gpuMs = msSince(start);
// ...
}
Loading. kernels::load is generated by #[cuda_module]. It passes the GPU code embedded in the executable to the driver. The call is unsafe because the program asserts that the embedded code was generated from this kernels module. The comment above the call states this, as the comment of every unsafe block should. The C++ program has no such step: nvcc links the GPU code into the executable, and the CUDA runtime loads it before the first launch.
Grid size. div_ceil divides and rounds up. 1,000,003 / 256 = 3906.26, so the grid contains 3907 blocks. Rounding down would leave the last elements without a thread.
Preparation. prepare_vector_add is also generated, from the launch contract. It checks the launch configuration against the contract in #[launch_contract] and against the limits of the GPU. If both checks pass, it returns a PreparedLaunch value, which records that the configuration has been checked.
Launch. module.vector_add(...) takes the PreparedLaunch value and the buffers. The launch requires no unsafe: the configuration has been checked, and the buffer types match the parameter types of the kernel, so the launch is safe Rust.
Copy back. to_host_vec copies c_dev into a new Vec<f32>. It is issued to the same stream as the launch, so it begins only after the kernel has finished.
Checking the result
A GPU result must be checked against an independent computation. The program computes the same sums with a plain CPU iterator and compares every element:
/// The same computation on one CPU core, used as the reference answer.
fn vector_add_cpu(a: &[f32], b: &[f32]) -> Vec<f32> {
a.iter()
.zip(b)
.map(|(x, y)| x + y)
.collect()
}// The same computation on one CPU core, used as the reference answer.
std::vector<float> vectorAddCpu(const std::vector<float>& a, const std::vector<float>& b)
{
std::vector<float> c(a.size());
for (size_t i = 0; i < a.size(); ++i) {
c[i] = a[i] + b[i];
}
return c;
}
fn main() -> Result<(), Box<dyn std::error::Error>> {
// ...
// 7. Check every element against the CPU.
let start = Instant::now();
let expected = vector_add_cpu(&a, &b);
let cpu_time = start.elapsed();
let wrong = c
.iter()
.zip(&expected)
.filter(|(got, want)| got != want)
.count();
// ...
}int main()
{
// ...
// 6. Check every element against the CPU.
start = std::chrono::steady_clock::now();
std::vector<float> expected = vectorAddCpu(a, b);
double cpuMs = msSince(start);
int wrong = 0;
for (int i = 0; i < N; ++i) {
wrong += c[i] != expected[i];
}
// ...
}
An exact comparison with != is correct here, because a single addition of 2 f32 values gives the same bits on the GPU as on the CPU. In later chapters we add many numbers in a different order on each side, and those comparisons need a tolerance.
13.8 Running the program
The program is built and run from the vector_add directory:
$ cargo oxide run
The C++ program is built with nvcc -O3 -arch=native vector_add.cu -o vector_add in code/cuda/ch13_vector_add and prints the same lines with its own times.
The first build takes 1 to 2 minutes, because cargo compiles the cuda-oxide crates. Later builds take a few seconds. On a Jetson Orin NX 16 GB (sm_87, 8 SMs) with CUDA 12.6, the program printed:
elements 1000003
blocks 3907 x 256 threads = 1000192 threads
idle threads 189
c[0..4] [0.0, 3.0, 6.0, 9.0]
c[N-1] 3000006
gpu + copy 2.756107ms
cpu 1.814993ms
PASSED: all 1000003 elements match the CPU
The output agrees with the hand calculation:
- 3907 blocks of 256 threads give 1,000,192 threads, of which 189 are spare. These threads called
get_mutand receivedNone. c[0..4]matches the table of section 13.1.- The last element is
a + b = 1,000,002 + 2,000,004 = 3,000,006.
Performance
The timing lines show that the GPU took longer than 1 CPU core. The reason lies in the ratio of arithmetic to memory traffic.
For each element, the kernel reads 8 bytes, writes 4 bytes, and performs 1 addition: 1 floating-point operation for every 12 bytes moved. In Chapter 1, we called this ratio the arithmetic intensity, and a value of 1/12 FLOP/byte is among the lowest a kernel can have. The arithmetic units of the GPU spend almost all their time waiting for memory. In addition, the gpu + copy timer includes the copy of 4 MB back to the CPU and the first kernel launch of the process.
Two runs on the same machine gave 2.8 ms and 3.1 ms for the GPU line, and 1.8 ms and 2.2 ms for the CPU line, so these values are approximate. The conclusion does not depend on them. A GPU is faster when each byte it loads is used for many arithmetic operations, or when the data remain on the GPU across many kernels. Matrix multiplication, later in this part, is the first kernel in this part for which this holds.
13.9 Common launch errors
Two mistakes are common in a first kernel. The real output of each is shown below.
The block size does not match the contract. The launch is changed to blocks of 128 threads:
LaunchConfig1D::new(blocks, 128, 0)vectorAdd<<<blocks, 128, 0, stream>>>(a_dev, b_dev, c_dev, N);
The C++ launch has no contract and runs without an error; only the comparison with the CPU finds the mistake:
c[N-1] 0
FAILED: 499907 elements differ from the CPU
prepare_vector_add rejects the configuration before any work reaches the GPU:
Error: BlockShapeMismatch { kernel: "vector_add", required: (256, 1, 1), actual: (128, 1, 1) }
Without the contract, the kernel would run with half the planned number of threads and leave half of c as zeros, without any error. The contract turns a wrong result into an error message.
The number of blocks is rounded down. div_ceil is replaced by integer division:
let blocks = N as u32 / BLOCK; // 3906 blocks: 67 threads shortint blocks = N / BLOCK; // 3906 blocks: 67 threads short
This configuration passes every check, because a smaller grid is a legal launch. The result is wrong:
c[N-1] 0
Error: "FAILED: 67 elements differ from the CPU"
The C++ program prints the same count:
c[N-1] 0
FAILED: 67 elements differ from the CPU
3906 × 256 = 999,936 threads, 67 fewer than N. The last 67 elements were not assigned to any thread, so they kept the zeros written by DeviceBuffer::zeroed. The comparison of every element with the CPU result detects this error; no type can detect a grid that is too small.
13.10 The complete program
code/oxide/vector_add/src/main.rs and code/cuda/ch13_vector_add/vector_add.cu, as built and run above:
//! Vector addition on the GPU with cuda-oxide: c[i] = a[i] + b[i].
//!
//! Build and run from this directory:
//!
//! cargo oxide run
use std::time::Instant;
use cuda_core::{CudaContext, DeviceBuffer, LaunchConfig1D};
use cuda_device::{DisjointSlice, cuda_module, kernel, launch_bounds, launch_contract, thread};
/// Threads per block. The kernel's launch contract names the same number.
const BLOCK: u32 = 256;
/// The number of elements. It is not a multiple of `BLOCK`, so the last
/// block has threads with no element to add.
const N: usize = 1_000_003;
#[cuda_module]
mod kernels {
use super::*;
/// One thread adds one pair of elements.
#[kernel]
#[launch_bounds(256)]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn vector_add(a: &[f32], b: &[f32], mut c: DisjointSlice<f32>) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(out) = c.get_mut(idx) {
*out = a[i] + b[i];
}
}
}
/// The same computation on one CPU core, used as the reference answer.
fn vector_add_cpu(a: &[f32], b: &[f32]) -> Vec<f32> {
a.iter()
.zip(b)
.map(|(x, y)| x + y)
.collect()
}
fn main() -> Result<(), Box<dyn std::error::Error>> {
// 1. Inputs on the host.
let a: Vec<f32> = (0..N).map(|i| i as f32).collect();
let b: Vec<f32> = (0..N).map(|i| 2.0 * i as f32).collect();
// 2. A context on GPU 0, and the stream that orders our work on it.
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// 3. Copy the inputs to device memory and allocate the output.
let a_dev = DeviceBuffer::from_host(&stream, &a)?;
let b_dev = DeviceBuffer::from_host(&stream, &b)?;
let mut c_dev = DeviceBuffer::<f32>::zeroed(&stream, N)?;
// 4. Load the GPU code that the compiler embedded in this binary.
// SAFETY: the bundle was built from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
// 5. Enough blocks to cover N: ceil(N / BLOCK).
let blocks = (N as u32).div_ceil(BLOCK);
let prepared = module.prepare_vector_add(LaunchConfig1D::new(blocks, BLOCK, 0))?;
// 6. Launch, then copy the result back. The copy waits for the kernel.
let start = Instant::now();
module.vector_add(&stream, &prepared, &a_dev, &b_dev, &mut c_dev)?;
let c = c_dev.to_host_vec(&stream)?;
let gpu_time = start.elapsed();
// 7. Check every element against the CPU.
let start = Instant::now();
let expected = vector_add_cpu(&a, &b);
let cpu_time = start.elapsed();
let wrong = c
.iter()
.zip(&expected)
.filter(|(got, want)| got != want)
.count();
println!("elements {N}");
println!("blocks {blocks} x {BLOCK} threads = {} threads", blocks * BLOCK);
println!("idle threads {}", blocks as usize * BLOCK as usize - N);
println!("c[0..4] {:?}", &c[..4]);
println!("c[N-1] {}", c[N - 1]);
println!("gpu + copy {gpu_time:?}");
println!("cpu {cpu_time:?}");
if wrong == 0 {
println!("PASSED: all {N} elements match the CPU");
Ok(())
} else {
Err(format!("FAILED: {wrong} elements differ from the CPU").into())
}
}// Chapter 13: vector addition on the GPU in CUDA C++, c[i] = a[i] + b[i].
// Build: nvcc -O3 -arch=native vector_add.cu -o vector_add
#include <chrono>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cuda_runtime.h>
// Threads per block. The kernel's launch bounds name the same number.
const int BLOCK = 256;
// The number of elements. It is not a multiple of BLOCK, so the last
// block has threads with no element to add.
const int N = 1000003;
// Stops the program if a CUDA call failed.
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
// One thread adds one pair of elements.
__global__ void __launch_bounds__(256)
vectorAdd(const float* a, const float* b, float* c, int n)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
c[i] = a[i] + b[i];
}
}
// The same computation on one CPU core, used as the reference answer.
std::vector<float> vectorAddCpu(const std::vector<float>& a, const std::vector<float>& b)
{
std::vector<float> c(a.size());
for (size_t i = 0; i < a.size(); ++i) {
c[i] = a[i] + b[i];
}
return c;
}
// Milliseconds since `start`.
double msSince(std::chrono::steady_clock::time_point start)
{
auto elapsed = std::chrono::steady_clock::now() - start;
return std::chrono::duration<double, std::milli>(elapsed).count();
}
int main()
{
// 1. Inputs on the host.
std::vector<float> a(N), b(N);
for (int i = 0; i < N; ++i) {
a[i] = float(i);
b[i] = 2.0f * float(i);
}
// 2. GPU 0, and a stream that orders our work on it.
check(cudaSetDevice(0));
cudaStream_t stream;
check(cudaStreamCreate(&stream));
// 3. Copy the inputs to device memory and allocate the output.
size_t bytes = N * sizeof(float);
float *a_dev, *b_dev, *c_dev;
check(cudaMalloc(&a_dev, bytes));
check(cudaMalloc(&b_dev, bytes));
check(cudaMalloc(&c_dev, bytes));
check(cudaMemcpyAsync(a_dev, a.data(), bytes, cudaMemcpyHostToDevice, stream));
check(cudaMemcpyAsync(b_dev, b.data(), bytes, cudaMemcpyHostToDevice, stream));
check(cudaMemsetAsync(c_dev, 0, bytes, stream));
// 4. Enough blocks to cover N: ceil(N / BLOCK).
int blocks = (N + BLOCK - 1) / BLOCK;
// 5. Launch, then copy the result back. The copy waits for the kernel.
std::vector<float> c(N);
auto start = std::chrono::steady_clock::now();
vectorAdd<<<blocks, BLOCK, 0, stream>>>(a_dev, b_dev, c_dev, N);
check(cudaGetLastError());
check(cudaMemcpyAsync(c.data(), c_dev, bytes, cudaMemcpyDeviceToHost, stream));
check(cudaStreamSynchronize(stream));
double gpuMs = msSince(start);
// 6. Check every element against the CPU.
start = std::chrono::steady_clock::now();
std::vector<float> expected = vectorAddCpu(a, b);
double cpuMs = msSince(start);
int wrong = 0;
for (int i = 0; i < N; ++i) {
wrong += c[i] != expected[i];
}
std::printf("elements %d\n", N);
std::printf("blocks %d x %d threads", blocks, BLOCK);
std::printf(" = %d threads\n", blocks * BLOCK);
std::printf("idle threads %d\n", blocks * BLOCK - N);
std::printf("c[0..4] [%.1f, %.1f, %.1f, %.1f]\n", c[0], c[1], c[2], c[3]);
std::printf("c[N-1] %.0f\n", c[N - 1]);
std::printf("gpu + copy %.6fms\n", gpuMs);
std::printf("cpu %.6fms\n", cpuMs);
check(cudaFree(a_dev));
check(cudaFree(b_dev));
check(cudaFree(c_dev));
check(cudaStreamDestroy(stream));
if (wrong == 0) {
std::printf("PASSED: all %d elements match the CPU\n", N);
return 0;
}
std::fprintf(stderr, "FAILED: %d elements differ from the CPU\n", wrong);
return 1;
}
Summary
- A kernel is the body of a loop. The GPU runs 1 instance per thread, and each thread computes 1 element.
- A thread computes its element as
i = block index × block size + thread index. The number of blocks isceil(N / block size), so the last block usually contains spare threads. DisjointSlice::get_mutgives each thread its own output element, orNonepast the end. The type excludes both data races and a missing bounds guard.#[launch_contract]makes the launch checked and safe. Only the loading of the embedded GPU code remainsunsafe.- The host program copies the inputs to the GPU, launches the kernel, copies the result back, and checks it against the CPU.
- Vector addition is memory-bound. It performs 1 addition for every 12 bytes. The GPU is faster on kernels that perform more arithmetic per byte.
In the next chapter, we make the kernel generic. A single map kernel takes any closure, so that c[i] = a[i] + b[i], SAXPY (y = αx + y) and other element-wise operations share 1 kernel. It also launches fewer threads than there are elements, using the grid-stride loop.
Exercises
- Change
Nto 1024. How many blocks does the program launch, and how many threads are idle? Predict the numbers, then run the program. - Write
vector_sub, which computesc[i] = a[i] - b[i], as a second#[kernel]in the same module, and launch it aftervector_add. - Change
aso that it has 1 element fewer thanbandc. Which line stops the kernel, and why doesget_mutnot catch the error? - Move the
Instant::now()for the GPU so that it measures only the launch, withoutto_host_vec. What do you observe, and why? (Hint: a launch only queues work on the stream.)
Elementwise Operations and Reductions
In the next 2 chapters, we develop the 2 simplest patterns of parallel computation. In an elementwise operation, or map, every element of the output is computed from the elements at the same position in the inputs. In a reduction, all elements of the input are combined into 1 value, such as a sum, a maximum or a count. Almost every GPU program contains both patterns. The activation function of a neural network layer is a map, the length of a vector is computed by a reduction, and a dot product is a map followed by a reduction.
The idea that connects the 2 patterns is the dependence between the iterations of the sequential loop. In a map, iteration \(i\) reads and writes only position \(i\), so the iterations share nothing, and each iteration can be given to its own thread. In a reduction, every iteration reads the running result of the iteration before it, which forms a chain as long as the array. This chain is broken by a property of the operator, not of the hardware. Because addition is associative and commutative, the additions can be regrouped into a tree, and the additions within each level of the tree are independent of each other. The 2 chapters also share 1 result of the measurements. Each element is used exactly once, so neither pattern can reuse data, and the speed of both is set by the memory bandwidth of the GPU.
In Chapter 14, we develop the map on SAXPY, the operation \(y \leftarrow a x + y\), which replaces each element of a vector \(y\) by \(a\) times the element of \(x\) at the same position plus the old element of \(y\). We work it out by hand on 12 elements. We first give every element its own thread, using just enough blocks to cover the array and a guard that stops the threads beyond its end. We then introduce the grid-stride loop, in which fewer threads than elements cover the array, and prove that it updates each element exactly once. Finally, we write a generic map that takes a Rust closure or a C++ lambda, and we measure how close SAXPY comes to the bandwidth of the memory.
In Chapter 15, we develop the reduction on the dot product of 2 vectors of 16 small integers. We turn the tree of additions into a kernel that works in shared memory, step by step, with a barrier between consecutive steps, and we prove the tree correct with a loop invariant. We then replace most of the barriers by warp shuffles, and we combine the sums of the blocks either with a second launch or with atomic additions, whose order changes the last bits of a floating-point result.
Both chapters build on the first Rust kernel of Chapter 13, from which we take DisjointSlice and
the safe launch path, and on Chapters 7 and 8, in which we introduced coalesced access, the
grid-stride loop and the reduction in C++. Every algorithm is given both in CUDA C++ and in Rust
with cuda-oxide.
Chapter 14: Map and SAXPY
This chapter depicts what happens under the hood when a GPU applies the same small calculation to every element of an array. We’ll examine how we give the elements to threads, how the threads’ reads reach memory, and why the speed of such a program is set by the memory and not by the arithmetic units.
So far we’ve written one kernel, the vector addition of Chapter 13. In that kernel, we used one thread for each element, and each thread added 2 numbers. Vector addition belongs to a large family of computations called maps. In a map, every output element depends only on the input elements at the same position. Scaling a vector, converting the pixels of an image to gray and applying an activation function to every value of a tensor are all maps. In this chapter, we study the family through one member, SAXPY, and we build two GPU versions of it. In the first version, we again use one thread per element. In the second version, we use fewer threads than elements and let each thread process several elements in a loop.
This chapter covers
- SAXPY and the map pattern, worked by hand on 12 elements
- the sequential loop and its count of operations and bytes
- one thread per element, the grid that covers \(n\) elements, and the guard \(i < n\)
- the grid-stride loop, for grids with fewer threads than elements
- a proof that the grid-stride loop updates every element exactly once
- 2 broken variants, a missing guard and a wrong stride
- arithmetic intensity, and why SAXPY is limited by memory bandwidth
- generic maps with Rust closures and C++ lambdas
- measured bandwidth, and the number of blocks a loop needs to reach it
The code of this chapter is in
code/oxide/ch14_map_saxpy/
for Rust and in
code/cuda/ch14_map_saxpy/
for C++. The Rust crate uses the same Cargo.toml and rust-toolchain.toml as the vector addition
of Chapter 13.
14.1 Updating every element of an array
14.1.1 A worked example
We use one pair of vectors for the whole chapter, so that you can check every number with a pencil. Each vector has 12 elements. We also need one number by which we multiply the first vector. This number is called the scalar, and we choose \(a = 2\).
\[ x = (2, 7, 1, 8, 2, 8, 1, 8, 2, 8, 4, 5), \qquad y = (3, 1, 4, 1, 5, 9, 2, 6, 5, 3, 5, 8). \]
We number the positions of a vector from 0. We write \(x_i\) for the element of \(x\) at position \(i\). For example, \(x_0 = 2\) is the first element of \(x\), and \(x_9 = 8\) is the tenth.
The calculation we want is simple to state. For every position \(i\), we take twice the element of \(x\) and add the element of \(y\) at the same position. For position 0, this gives \(2 \cdot 2 + 3 = 7\). For position 1, it gives \(2 \cdot 7 + 1 = 15\). We continue in the same way for the other 10 positions. Figure 14.1 shows all 12 results.
We’ll follow one of these results through every version of the program in this chapter. It is position 9, where \(2 \cdot 8 + 3 = 19\). We’ll also meet a faulty program in Section 14.5. That program produces 8 at position 2, where the correct result is \(2 \cdot 1 + 4 = 6\).
14.1.2 SAXPY and the map pattern
We need one piece of notation before we state the definition. We write \([a, b)\) for the integers from \(a\) up to, but not including, \(b\). For example, \(i \in [0, 12)\) means that \(i\) takes the values \(0, 1, \ldots, 11\). These are exactly the 12 positions of our vectors.
Definition 14.1 SAXPY. Let \(a\) be a number, and let \(x\) and \(y\) be vectors of \(n\) single-precision floating-point numbers. SAXPY replaces each element of \(y\) by \(a\) times the element of \(x\) plus the old element of \(y\).
\[ y_i \leftarrow a\,x_i + y_i \qquad \text{for every } i \in [0, n). \]
Example. With \(a = 2\), \(x_9 = 8\) and \(y_9 = 3\), SAXPY sets \(y_9\) to 19.
| Symbol | Meaning | In the example |
|---|---|---|
| \(n\) | number of elements in each vector | 12 |
| \(i\) | position of an element, from 0 to \(n - 1\) | 9 |
| \(a\) | the scalar that multiplies \(x\) | 2 |
| \(x_i\) | element of \(x\) at position \(i\) | \(x_9 = 8\) |
| \(y_i\) | element of \(y\) at position \(i\), before and after the update | \(y_9 = 3\), then 19 |
| \(\leftarrow\) | “is replaced by” |
The arrow \(\leftarrow\) means that we compute the right-hand side with the old value of \(y_i\) and then store the result in \(y_i\). The new value takes the place of the old one. A computation that stores its result in one of its inputs is said to work in place.
The name SAXPY comes from the Basic Linear Algebra Subprograms, usually called BLAS. BLAS is a standard collection of routines for linear algebra. Its first version appeared in 1979, when scientific programs were written in Fortran and every computer vendor shipped its own fast version of the same routines.1 The letter S stands for single precision, and AXPY stands for “\(a\) times \(x\) plus \(y\)”. The routine is still in every BLAS library today, including NVIDIA’s cuBLAS.
SAXPY is one member of a larger family. In every member of the family, we compute output element \(i\) from the input elements at position \(i\), and from nothing else.
Definition 14.2 Map. A map applies one function \(f\) to the elements at each position of one or more input arrays of length \(n\). It produces an output array of length \(n\).
\[ z_i = f(x_i, y_i, \ldots) \qquad \text{for every } i \in [0, n). \]
Example. SAXPY is a map with 2 inputs and \(f(x, y) = a x + y\). Vector addition is a map with \(f(x, y) = x + y\). The computation \(y_i \leftarrow \max(x_i, y_i)\) is a map with \(f(x, y) = \max(x, y)\).
| Symbol | Meaning | SAXPY on the example |
|---|---|---|
| \(f\) | the function we apply at every position | \(f(x, y) = 2x + y\) |
| \(x_i, y_i, \ldots\) | the input elements at position \(i\), one from each input array | \(x_9 = 8\), \(y_9 = 3\) |
| \(z_i\) | the output element at position \(i\) | \(z_9 = f(8, 3) = 19\) |
The dots in \(f(x_i, y_i, \ldots)\) mean that a map may have any number of input arrays. In SAXPY, the output array \(z\) is the array \(y\) itself, because SAXPY works in place.
Exercises
14.1 Compute elements 0 to 3 of SAXPY on the worked example with \(a = 3\) instead of 2.
14.2 Which of these computations are maps? (a) \(z_i = x_i^2\); (b) \(z_i = x_i - x_{i-1}\);
(c) \(z_i = x_i / s\), where \(s\) is the sum of all elements of \(x\). Explain your answer.
14.3 SAXPY overwrites \(y\). Name one advantage and one risk of computing in place.
14.2 The sequential algorithm
14.2.1 The loop
On a CPU, we write Definition 14.1 as a single loop. The loop visits the positions one after another and updates each of them.
Saxpy(\(a, x, y, n\))
- for \(\mathsf{index} \in [0, n)\) {
- \(y_{\mathsf{index}} = a \cdot x_{\mathsf{index}} + y_{\mathsf{index}}\) // 2 reads, 1 write, 2 FLOP
- }
We want to judge the cost of this loop later, so we count 2 quantities for each pass through it. The first quantity is the arithmetic. A floating-point operation, written FLOP for short, is one addition, subtraction, multiplication or division of floating-point numbers. Line 2 performs 2 of them. It multiplies \(a\) by \(x_i\), and it adds \(y_i\) to the product.
The second quantity is the data that line 2 moves between the processor and memory. Line 2 reads 2 values, \(x_i\) and \(y_i\). It writes one value, the new \(y_i\). Each value is a float of 4 bytes, so line 2 moves \(3 \cdot 4 = 12\) bytes.
Line 2 runs once for each position, that is, \(n\) times. For our 12 elements, the loop therefore performs \(12 \cdot 2 = 24\) FLOP and moves \(12 \cdot 12 = 144\) bytes. At the end of the chapter, we measure arrays of \(n = 16{,}777{,}216 = 2^{24}\) elements. For those arrays, the loop performs 33.6 million FLOP and moves 201.3 MB. A CPU core performs the passes one after another, in the order shown in Figure 14.2.
14.2.2 Whether the passes depend on each other
Before we run the passes of the loop at the same time, we must know whether any pass needs the result of another pass. If pass 9 needed the value that pass 8 writes, pass 9 would have to wait for pass 8, and the two could not run together.
Consider what each pass uses. Pass \(i\) reads \(x_i\) and \(y_i\), and it writes \(y_i\). For example, pass 9 reads \(x_9 = 8\) and \(y_9 = 3\), and it writes 19. No other pass reads or writes position 9. The same is true at every position. The 12 passes therefore use 12 separate pairs of memory locations, and no pass ever needs a value that another pass produces.
This property is not automatic. A computation can look similar and still lack it. Consider the running sum of \(y\), defined by \(s_i = s_{i-1} + y_i\). The value \(s_i\) is the sum of the first \(i + 1\) elements of \(y\), and we compute it from the previous sum \(s_{i-1}\). To compute \(s_9\), we therefore need \(s_8\). To compute \(s_8\), we need \(s_7\), and so the chain continues back to \(s_0\). The top half of Figure 14.3 draws the data that each result of SAXPY uses. Every arrow stays inside its own column. The bottom half draws the same for the running sum, where every result is joined to the result before it.
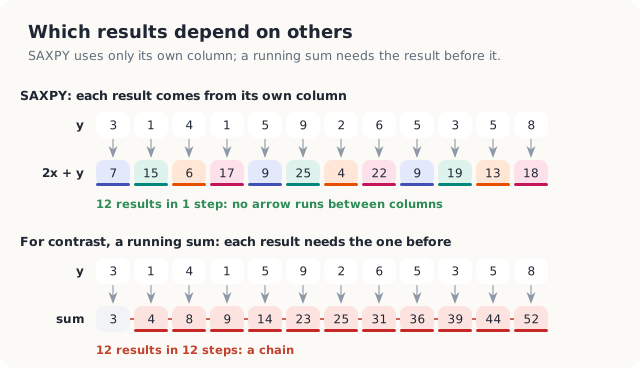
Key observation Pass \(i\) of Saxpy reads and writes only position \(i\). No pass uses a value that another pass produces. We may therefore run the 12 passes in any order, and in particular all at the same time, each on its own thread.
The running sum does not have this property, and it needs a different algorithm. In Chapter 15, we develop such an algorithm for a closely related computation, the sum of all elements of an array. In Chapter 21, we return to the running sum itself.
Exercises
14.4 How many FLOP and how many bytes does Saxpy need for
\(n = 1{,}000\)?
14.5 The loop \(y_i = y_{i+1} + x_i\) for \(i \in [0, n - 1)\) also reads and writes \(y\).
Is it a map? What goes wrong if we run its passes at the same time?
14.3 Giving every element its own thread
14.3.1 Numbering the threads
The key observation suggests that we give every position its own thread. To do so, we need the terms with which a GPU program describes its threads. We met them in Chapter 13, and we recall them here.
Definition 14.3 Kernel and thread. A kernel is a function that the GPU runs many times at once. Each of these runs is a thread. All threads run the same code, and each thread has its own position and its own variables.
Example. We’ll run SAXPY on the example as a kernel with 16 threads. We use 12 of them to compute one element each.
Definition 14.4 Block and grid. A block is a group of
threads that run on the same streaming multiprocessor (SM) of the GPU. The threads of a block can
share a fast memory and can wait for one another. The grid is the set of all blocks of one
launch of a kernel. Each thread can read 3 numbers. The number blockIdx.x is the index of its
block in the grid, blockDim.x is the number of threads in a block, and threadIdx.x is the
index of the thread within its block.
Example. A grid of 2 blocks of 8 threads has 16 threads. Thread 1 of block 1 reads
blockIdx.x = 1, blockDim.x = 8 and threadIdx.x = 1.
We want each thread to find the element it is responsible for. The simplest plan is to number all threads of the grid in one sequence, starting at 0, and to let thread number \(\mathsf{globalIdx}\) handle element \(\mathsf{globalIdx}\). The 3 numbers above are enough to compute this sequence number.
Let us work it out for block number \(b\). Blocks 0 to \(b - 1\) come before block \(b\).
Each of them holds blockDim.x threads, so together they hold \(b \cdot\) blockDim.x threads.
The first thread of block \(b\) therefore gets the number \(b \cdot\) blockDim.x. The other
threads of block \(b\) follow it, so we add the index of a thread within its block. The result
is called the global index of the thread, and we write it as \(\mathsf{globalIdx}\).
\[ \mathsf{globalIdx} = \mathsf{blockIdx{.}x} \cdot \mathsf{blockDim{.}x} + \mathsf{threadIdx{.}x}. \]
| Symbol | Meaning | Thread 1 of block 1 |
|---|---|---|
| \(\mathsf{blockIdx{.}x}\) | number of the thread’s block in the grid | 1 |
| \(\mathsf{blockDim{.}x}\) | number of threads in every block | 8 |
| \(\mathsf{blockIdx{.}x} \cdot \mathsf{blockDim{.}x}\) | number of threads in the blocks before this one | \(1 \cdot 8 = 8\) |
| \(\mathsf{threadIdx{.}x}\) | index of the thread within its block | 1 |
| \(\mathsf{globalIdx}\) | global index, the thread’s number in the whole grid | \(8 + 1 = 9\) |
In our example, thread 1 of block 1 has the global index \(1 \cdot 8 + 1 = 9\). We therefore use
this thread to compute element 9, as shown in Figure 14.4. No 2 threads of the grid get the same
global index. Threads of the same block differ in threadIdx.x. Threads of different blocks fall
into different runs of blockDim.x consecutive numbers.
14.3.2 Covering an array of any length
When we launch a kernel, we choose 2 numbers. The first is the number of threads in each block, which we call \(\mathsf{blockDim{.}x}\). The second is the number of blocks in the grid. To give every element its own thread, we need at least \(n\) threads. A grid of \(\mathsf{blocks}\) blocks holds \(\mathsf{blocks} \cdot \mathsf{blockDim{.}x}\) threads, so we need \(\mathsf{blocks} \cdot \mathsf{blockDim{.}x} \ge n\), which means at least \(n / \mathsf{blockDim{.}x}\) blocks. The number of blocks must be a whole number, so we round \(n / \mathsf{blockDim{.}x}\) up to the next integer.
\[ \text{blocks} = \lceil n / B \rceil. \]
| Symbol | Meaning | In the example |
|---|---|---|
| \(n\) | number of elements | 12 |
| \(\mathsf{blockDim{.}x}\) | number of threads in each block (blockDim.x) | 8 |
| \(\lceil n / \mathsf{blockDim{.}x} \rceil\) | \(n / \mathsf{blockDim{.}x}\) rounded up to the next integer | \(\lceil 1.5 \rceil = 2\) |
With \(n = 12\) and \(\mathsf{blockDim{.}x} = 8\), the quotient \(12 / 8 = 1.5\) is rounded up to 2. The 2 blocks hold 16 threads. Threads 0 to 11 each have one element. Threads 12 to 15, the last 4 threads of block 1, have no element at all. In general, the grid has \(\mathsf{blockDim{.}x} \cdot \lceil n / \mathsf{blockDim{.}x} \rceil - n\) threads without an element, which is always fewer than \(\mathsf{blockDim{.}x}\). In our example, there are \(16 - 12 = 4\) of them. For the measured arrays, \(n = 2^{24}\) is a multiple of \(\mathsf{blockDim{.}x} = 256\), so the grid has exactly 65,536 blocks and every thread has an element.
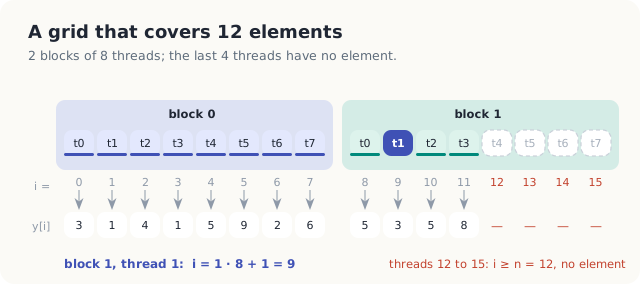
A thread without an element must not read or write memory, because the positions from \(n\) onwards do not belong to \(y\). We therefore let every thread first compare its global index with \(n\). We now obtain the parallel algorithm from Saxpy. We delete the loop, and we let the global index play the role of the loop variable \(\mathsf{index}\). Every thread runs the following procedure.
Saxpy-Kernel(\(a, x, y, n\))
- \(\mathsf{index} = \mathsf{blockIdx{.}x} \cdot \mathsf{blockDim{.}x} + \mathsf{threadIdx{.}x}\) // the global index
- if \(\mathsf{index} \lt n\) { // the guard
- \(y_{\mathsf{index}} = a \cdot x_{\mathsf{index}} + y_{\mathsf{index}}\) // 2 reads, 1 write in global memory
- }
We launch Saxpy-Kernel on a grid of \(\lceil n / \mathsf{blockDim{.}x} \rceil\) blocks of \(\mathsf{blockDim{.}x}\) threads. Line 1 computes the global index with the formula of Section 14.3.1. Line 2 is called the guard, also known as the bounds check. When a thread’s index lies at or beyond the end of the array, line 2 skips the update, and the thread does nothing. Line 3 is line 2 of Saxpy. We now run it once per thread instead of once per pass of a loop. In our example, thread 9 passes the guard because \(9 < 12\), and it computes \(y_9 = 19\). Thread 13 fails the guard because \(13 \ge 12\), and it does nothing.
14.3.3 What one thread reads and writes
To understand the cost of a thread’s work, we need to know where the vectors are stored. They are stored in the main memory of the GPU.
Definition 14.5 Global memory and registers. Global memory is the main memory of the GPU, also called device memory. Every thread of every block can read and write it. It holds gigabytes, and a read takes several hundred clock cycles to return its value. Registers hold the variables of a single thread and return a value in about one cycle.
Example. The vectors \(x\) and \(y\) are in global memory. The product \(2 \cdot 8\) that we compute in thread 1 of block 1 is in a register.
Figure 14.5 follows thread 1 of block 1. We read \(x_9 = 8\) and \(y_9 = 3\) from global memory, compute \(2 \cdot 8 + 3 = 19\) in registers, and write 19 back to \(y_9\). The thread makes 2 reads and one write, moves 12 bytes and performs 2 FLOP. This is exactly the work of one pass of the sequential loop.
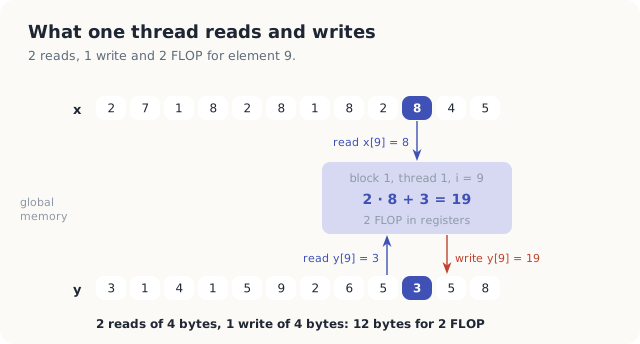
The parallel algorithm therefore does the same total work as the sequential one. On the example, it performs 24 FLOP and moves 144 bytes, and in general it moves 12 bytes per element. What changes is the time. The \(n\) passes no longer form a sequence of \(n\) steps. With enough threads, we can perform all of them in a single step.
One cost stays the same, however. We still move 12 bytes per element through global memory, and no arrangement of threads can reduce this amount. Every value of \(x\) and \(y\) is used exactly once, so there is nothing that one thread could reuse from another. In Section 14.6, we show that this cost of 12 bytes per element sets the speed of SAXPY.
Exercises
14.6 With blocks of 8 threads, which thread computes element 5, and which element does thread 3
of block 1 compute?
14.7 How many blocks of 256 threads cover \(n = 1{,}000{,}000\) elements, and how many threads
have no element?
14.8 A program launches \(n / B\) blocks, rounded down, instead of \(\lceil n / B \rceil\).
Which elements of the example are never computed with \(B = 8\)?
14.4 Arrays with more elements than threads
14.4.1 Why we might want fewer threads
With Saxpy-Kernel, we launch one thread for every element. For the measured arrays of 16,777,216 elements, we therefore launch 16,777,216 threads. The GPU can’t hold all of these threads at the same time. An SM of the measured GPU can hold up to 1,536 threads, and with 8 SMs the whole GPU can hold up to 12,288. The hardware therefore runs the 65,536 blocks of 256 threads in about 1,366 rounds. It starts a new block whenever an earlier block finishes.
This arrangement works well. In Section 14.8, we measure that it runs close to the speed of the memory. It does, however, tie the size of the grid to the length of the array. There are three situations in which we would rather choose the number of threads ourselves.
The first situation arises when a kernel does some work once per thread, in addition to its work per element. The dot product of Chapter 15 is an example. There, we let every thread add up its products in a register. At the end, we must combine the sums of all threads, and this costs time in proportion to the number of threads. If each thread handles 64 elements instead of one, we have 64 times fewer sums to combine.
The second situation arises when we want the grid to fit the GPU. The measured GPU can hold up to 12,288 threads at once. A grid of 6 blocks of 256 threads per SM fills all of its SMs, whatever the length of the array. We can then choose the grid from 2 properties of the GPU, its number of SMs and the number of threads that each SM can hold, instead of from \(n\).
The third situation arises when we process many arrays of different lengths. In cuda-oxide, we
prepare a launch once for a given grid, with a method such as prepare_saxpy, and we can then
launch it many times. If the grid does not depend on \(n\), one prepared launch serves arrays of
every length.
14.4.2 Dividing the elements among the threads
Suppose now that the grid has \(\mathsf{gridSize}\) threads in total and that \(\mathsf{gridSize}\) is smaller than \(n\). Each thread must then process several elements. We must divide the elements so that every element is processed exactly once. In our example, we use \(\mathsf{gridSize} = 4\) threads, arranged as 2 blocks of 2 threads, for the 12 elements. Each thread then processes \(12 / 4 = 3\) elements.
There are 2 natural ways to divide the elements. Both are drawn in Figure 14.6, and in both we write \(\mathsf{globalIdx}\) for the global index of a thread, from 0 to 3. In the first way, which we call chunks, thread \(\mathsf{globalIdx}\) takes the 3 neighboring elements \(3 \cdot \mathsf{globalIdx}\), \(3 \cdot \mathsf{globalIdx} + 1\) and \(3 \cdot \mathsf{globalIdx} + 2\). For example, thread 3 takes elements 9, 10 and 11. In the second way, which we call a stride, thread \(\mathsf{globalIdx}\) takes every fourth element, starting at its own index. It takes elements \(\mathsf{globalIdx}\), \(\mathsf{globalIdx} + 4\) and \(\mathsf{globalIdx} + 8\). For example, thread 1 takes elements 1, 5 and 9.
Both ways are correct, because each gives every element to exactly one thread. They are not equally fast. The difference comes from 2 properties of the hardware. Threads run in groups of 32, and global memory is read in pieces of 32 bytes. We define both properties now.
Definition 14.6 Warp and lane. A warp is a group of 32 threads of a block with consecutive indices, such as threads 0 to 31 or threads 32 to 63. The SM issues each instruction for a whole warp at once, so the 32 threads of a warp perform their reads at the same moment. The position of a thread within its warp, from 0 to 31, is called its lane.
Example. A block of 256 threads consists of 8 warps. In our small example, the 4 threads play the role of the lanes of one warp.
Definition 14.7 Coalesced access. The memory system reads global memory in aligned pieces of 32 bytes, called segments. A read by a warp is coalesced when its 32 threads use neighboring addresses. The 32 reads of 4 bytes then fall into 4 segments of 32 bytes, 128 bytes in all, and every byte that the memory delivers is used.
Example. If lanes 0 to 31 read \(x_0\) to \(x_{31}\), the warp reads 128 neighboring bytes, and the read is coalesced.
Parcels on a delivery van. Picture a courier company whose van always drives to one street and carries a crate of 8 parcels for 8 neighboring houses. The crate is filled at the depot, and it goes out whole, even if only one house on that street ordered something. Suppose 32 people order parcels at the same time. If they live in 32 neighboring houses, the company needs 4 trips, and every parcel in every crate is wanted. If they live 3 houses apart from each other, the 32 houses are spread over 12 streets. The company now needs 12 trips, and two thirds of each crate is unwanted.
The analogy maps directly onto the hardware. The 32 people are the 32 threads of a warp. The houses are memory addresses, and a parcel is one float of 4 bytes. A street with its crate of 8 parcels is a segment of 32 bytes, and a trip of the van is one segment read from memory. The analogy breaks down in one respect. A real van could leave the unwanted parcels behind, but the memory always delivers the whole segment, so the unused bytes still cost time on the memory bus.
We can now compare the 2 ways of dividing the elements. Each thread processes its elements one after another, in steps. In each step, the threads of a warp issue their reads together.
Consider the first step of the chunk division. The 4 threads of our example read elements 0, 3, 6 and 9. These lie 12 bytes apart and are spread over 40 bytes. In a real warp of 32 threads with chunks of 3 elements, the 32 addresses of one read instruction are again 12 bytes apart, and they span 384 bytes. That is 12 segments of 32 bytes. The memory delivers all 384 bytes, but the warp uses only the 128 bytes that hold its 32 floats. Two thirds of the bytes read are wasted.
Now consider the first step of the stride division. The 4 threads read elements 0, 1, 2 and 3, which occupy 16 neighboring bytes. In a warp of 32 threads, the 32 floats occupy 128 neighboring bytes, which is exactly 4 segments. Every byte that the memory delivers is used. The same holds in every later step, because each step moves all addresses forward by the same amount. The stride division therefore keeps every read of every warp coalesced. Figure 14.6 shows all 3 steps.
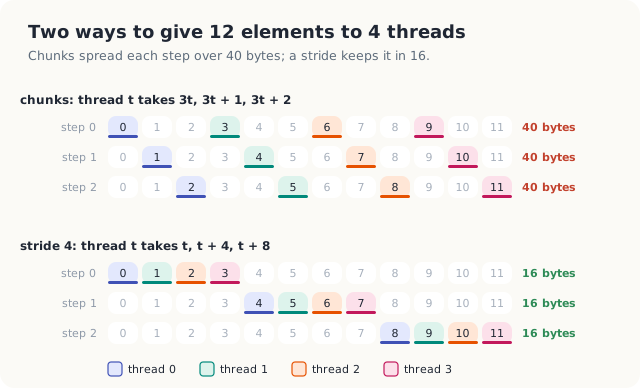
| Thread \(\mathsf{globalIdx}\) | Block, thread in block | Elements | Values of \(y\) after SAXPY |
|---|---|---|---|
| 0 | 0, 0 | 0, 4, 8 | 7, 9, 9 |
| 1 | 0, 1 | 1, 5, 9 | 15, 25, 19 |
| 2 | 1, 0 | 2, 6, 10 | 6, 4, 13 |
| 3 | 1, 1 | 3, 7, 11 | 17, 22, 18 |
Table 14.1 The stride assignment on the example: 4 threads, 12 elements, \(\mathsf{gridSize} = 4\).
14.4.3 The grid-stride loop
Table 14.1 lists the stride division for the example. Thread 1 starts at element 1. Each further element lies 4 places after the previous one, because 4 is the number of threads in the grid. In general, the stride division gives thread \(\mathsf{globalIdx}\) the elements \(\mathsf{globalIdx}, \mathsf{globalIdx} + \mathsf{gridSize}, \mathsf{globalIdx} + 2 \cdot \mathsf{gridSize}, \ldots\) that lie below \(n\). Here \(\mathsf{globalIdx}\) is the global index of Section 14.3.1, and \(\mathsf{gridSize}\) is the number of threads in the grid. A loop that walks through these elements is called a grid-stride loop. Mark Harris of NVIDIA gave the pattern this name in a widely read article in 2013.2
Definition 14.8 Grid-stride loop. In a grid-stride loop, each
thread starts at its global index \(\mathsf{globalIdx}\) and moves forward by the number of threads in the grid,
\(\mathsf{gridSize} = \mathsf{gridDim{.}x} \cdot \mathsf{blockDim{.}x}\). Here gridDim.x is the number of blocks of
the grid. The distance \(\mathsf{gridSize}\) is called the stride.
Example. With 2 blocks of 2 threads, \(\mathsf{gridSize} = 4\). Thread 1 of block 0, whose global index is 1, visits elements 1, 5 and 9.
Grid-Stride-Saxpy(\(a, x, y, n\))
- \(\mathsf{gridSize} = \mathsf{gridDim{.}x} \cdot \mathsf{blockDim{.}x}\) // threads in the grid
- \(\mathsf{index} = \mathsf{blockIdx{.}x} \cdot \mathsf{blockDim{.}x} + \mathsf{threadIdx{.}x}\) // the global index
- while \(\mathsf{index} \lt n\) {
- \(y_{\mathsf{index}} = a \cdot x_{\mathsf{index}} + y_{\mathsf{index}}\)
- \(\mathsf{index} = \mathsf{index} + \mathsf{gridSize}\)
- }
Lines 2 and 4 are lines 1 and 3 of Saxpy-Kernel. The guard of Saxpy-Kernel has become the condition of the loop in line 3. A thread whose index is already at least \(n\) therefore runs the loop 0 times. Line 5 moves the index forward by the stride. In our example, thread 1 runs the loop 3 times, with \(\mathsf{index} = 1\), 5 and 9. It computes 15, 25 and 19, and it leaves the loop when \(\mathsf{index} = 13\), because \(13 \ge 12\).
Let us count how many elements a thread processes. We number the passes through the loop with \(\mathsf{pass}\), starting from 0. In pass \(\mathsf{pass}\), the thread is at element \(\mathsf{globalIdx} + \mathsf{pass} \cdot \mathsf{gridSize}\). Thread \(\mathsf{globalIdx}\) processes every element \(\mathsf{globalIdx} + \mathsf{pass} \cdot \mathsf{gridSize}\) that is smaller than \(n\), and there are \(\lceil (n - \mathsf{globalIdx}) / \mathsf{gridSize} \rceil\) of them. For thread 1 of our example, \(\lceil (12 - 1) / 4 \rceil = \lceil 2.75 \rceil = 3\), which matches its 3 passes.
| Symbol | Meaning | Thread 1 of the example |
|---|---|---|
| \(\mathsf{globalIdx}\) | global index of the thread, which is also its first element | 1 |
| \(\mathsf{gridSize}\) | number of threads in the grid, the stride | 4 |
| \(\mathsf{pass}\) | number of the pass through the loop, from 0 | 0, 1, 2 |
| \(\mathsf{globalIdx} + \mathsf{pass} \cdot \mathsf{gridSize}\) | element processed in pass \(\mathsf{pass}\) | 1, 5, 9 |
| \(\lceil (n - \mathsf{globalIdx}) / \mathsf{gridSize} \rceil\) | number of elements the thread processes | 3 |
For \(n = 12\) and \(\mathsf{gridSize} = 4\), each of the 4 threads processes 3 elements. For \(\mathsf{gridSize} = 5\), threads 0 and 1 process 3 elements, and threads 2, 3 and 4 process 2. The loop therefore handles a length \(n\) that is not a multiple of \(\mathsf{gridSize}\) without any extra code.
Exercises
14.9 With \(\mathsf{gridSize} = 5\), list the elements of the example that each thread processes.
14.10 A warp of 32 threads uses chunks of 4 elements. How many 32-byte segments does one read
instruction need, and how many of the delivered bytes are used?
14.11 How many times does the loop of Grid-Stride-Saxpy run for thread 7
of a grid of 2,048 threads and \(n = 16{,}777{,}216\)?
14.5 Making sure every element is updated exactly once
Both kernels are short, but each depends on one detail that is easy to get wrong. In Saxpy-Kernel, this detail is the guard. In Grid-Stride-Saxpy, it is the stride. In this section, we remove or change each of them in turn and follow the effect on the example.
14.5.1 Threads past the end of the array
Suppose that we delete line 2 of Saxpy-Kernel and keep the launch of 2 blocks of 8 threads. Threads 12 to 15 then no longer stop. Each of them computes the address of its element \(y_{\mathsf{index}}\), which lies \(4 \cdot \mathsf{index}\) bytes after the start of \(y\). The 4 threads therefore use the addresses 48 to 60 bytes past the start of \(y\). They write \(2 x_{\mathsf{index}} + y_{\mathsf{index}}\) there, into memory that does not belong to \(y\), as shown in Figure 14.7.
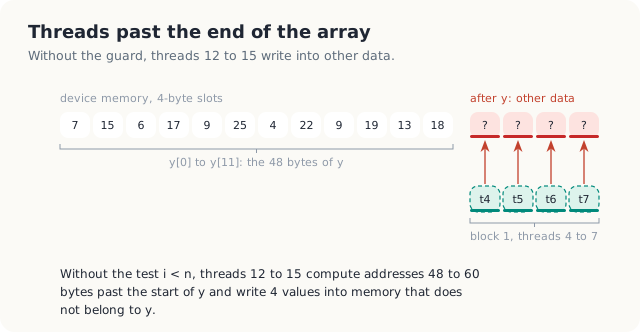
We ran the C++ kernel without the guard. To make the effect visible, we placed 4 more slots of other data after each vector. The slots after \(x\) held the value 1, and the slots after \(y\) held 100. The program printed the following.
y[0..12): 7 15 6 17 9 25 4 22 9 19 13 18
other data: 102 102 102 102
no error
The 12 elements of \(y\) are correct. The 4 values after \(y\), however, have changed from 100 to \(2 \cdot 1 + 100 = 102\). The GPU reported no error. The 4 slots lay inside memory that the program owned, so nothing stopped the writes. In a real program, those slots would hold another array. The wrong values would then appear later, in a computation that has nothing to do with SAXPY, and the cause would be hard to find.
In Rust, we cannot make this mistake in the same kernel. Its output is a DisjointSlice<f32>. The
only way to obtain a writable element of it is y.get_mut(thread_id), and that method returns None
when thread_id lies at or beyond the end of the slice. The guard is therefore part of the type of the
output, and a kernel without it does not compile.
14.5.2 A proof that the grid-stride loop is correct
Grid-Stride-Saxpy is correct only if it updates every element exactly once. An element that is never updated keeps its old value. An element that is updated twice receives \(a x_{\mathsf{index}}\) twice, because the second update reads the result of the first. For example, if \(y_9\) were updated twice, it would become \(2 \cdot 8 + 19 = 35\) instead of 19. We therefore prove that the grid-stride loop updates every element exactly once.
Table 14.1 already suggests which thread updates which element. Thread 1 updates elements 1, 5 and 9. Each of these leaves the remainder 1 when we divide it by \(\mathsf{gridSize} = 4\). We write \(\mathsf{element} \bmod \mathsf{gridSize}\) for the remainder of \(\mathsf{element}\) divided by \(\mathsf{gridSize}\). For example, \(9 \bmod 4 = 1\), because \(9 = 2 \cdot 4 + 1\), and element 9 is indeed updated by thread 1. The theorem states that the same holds for every element.
Theorem 14.1 When every thread of a grid of \(\mathsf{gridSize}\) threads has finished Grid-Stride-Saxpy, every element \(y_{\mathsf{element}}\) with \(\mathsf{element} \in [0, n)\) has been updated exactly once, by the thread whose global index is \(\mathsf{element} \bmod \mathsf{gridSize}\).
Proof. The proof has 2 parts. In the first part, we describe what one thread does. In the second part, we show that the threads together update every element once.
Fix a thread with global index \(\mathsf{globalIdx} \in [0, \mathsf{gridSize})\). We show that the loop of lines 3 to 6 keeps the following statement true at the start of every pass. Such a statement is called a loop invariant. At the start of pass \(\mathsf{pass}\), \(\mathsf{index} = \mathsf{globalIdx} + \mathsf{pass} \cdot \mathsf{gridSize}\), and the thread has updated exactly the elements \(\mathsf{globalIdx} + j \cdot \mathsf{gridSize}\) with \(j \in [0, \mathsf{pass})\). For thread 1 of the example, at the start of pass 2, the invariant says that \(\mathsf{index} = 1 + 2 \cdot 4 = 9\) and that the thread has updated elements 1 and 5.
Initialization. Before pass 0, line 2 has set \(\mathsf{index} = \mathsf{globalIdx}\), and the thread has not yet updated any element. Both parts of the invariant hold with \(\mathsf{pass} = 0\), because \(\mathsf{globalIdx} + 0 \cdot \mathsf{gridSize} = \mathsf{globalIdx}\) and the range \([0, 0)\) is empty.
Maintenance. Assume that the invariant holds at the start of pass \(\mathsf{pass}\), and that \(\mathsf{index} < n\), so that the pass runs. Line 4 updates element \(\mathsf{index} = \mathsf{globalIdx} + \mathsf{pass} \cdot \mathsf{gridSize}\). Line 5 sets \(\mathsf{index} = \mathsf{globalIdx} + \mathsf{pass} \cdot \mathsf{gridSize} + \mathsf{gridSize} = \mathsf{globalIdx} + (\mathsf{pass} + 1) \cdot \mathsf{gridSize}\). The thread has now updated the elements \(\mathsf{globalIdx} + j \cdot \mathsf{gridSize}\) with \(j \in [0, \mathsf{pass} + 1)\), which is the invariant for pass \(\mathsf{pass} + 1\).
Termination. The loop ends at the first \(\mathsf{pass}\) with \(\mathsf{globalIdx} + \mathsf{pass} \cdot \mathsf{gridSize} \ge n\). By the invariant, the thread has then updated exactly the elements below \(n\) of the form \(\mathsf{globalIdx} + j \cdot \mathsf{gridSize}\). It has updated each of them only once, because \(\mathsf{index}\) grows with every pass, so no value of \(\mathsf{index}\) repeats.
For the second part, take any element \(\mathsf{element} \in [0, n)\), and write \(\mathsf{element} = j \cdot \mathsf{gridSize} + r\) with \(r = \mathsf{element} \bmod \mathsf{gridSize}\). The thread with \(\mathsf{globalIdx} = r\) updates \(\mathsf{element}\) in its pass \(j\). Every other thread updates only elements whose remainder is its own index \(\mathsf{globalIdx} \ne r\), so it never updates \(\mathsf{element}\). Hence \(\mathsf{element}\) is updated exactly once. In the example, element \(9 = 2 \cdot 4 + 1\) is updated by thread 1 in its pass 2, and by no other thread.
The proof relies on 2 facts about the launch. The first is that the grid has exactly \(\mathsf{gridSize}\) threads, with the global indices 0 to \(\mathsf{gridSize} - 1\). The second is that line 1 computes this same \(\mathsf{gridSize}\). If line 1 computes a different number, the remainders no longer separate the threads, and 2 threads may update the same element. The next section shows what happens then.
14.5.3 A stride that is too small
A common mistake is to move forward by the number of threads in a block, blockDim.x, instead of
the number of threads in the grid. In our example, line 1 then computes \(\mathsf{gridSize} = 2\) instead of 4.
Thread 0 visits elements 0, 2, 4, 6, 8 and 10. Thread 2, which is thread 0 of block 1, starts at
element 2 and visits elements 2, 4, 6, 8 and 10. In the same way, threads 1 and 3 both visit the
odd elements from 3 onwards. Each of the elements 2 to 11 is therefore updated by 2 threads.
Figure 14.8 shows one order in which the 2 updates of element 2 can happen. Thread 0 updates \(y_2\) from 4 to \(2 \cdot 1 + 4 = 6\). Thread 2 then reads the 6 and writes \(2 \cdot 1 + 6 = 8\).
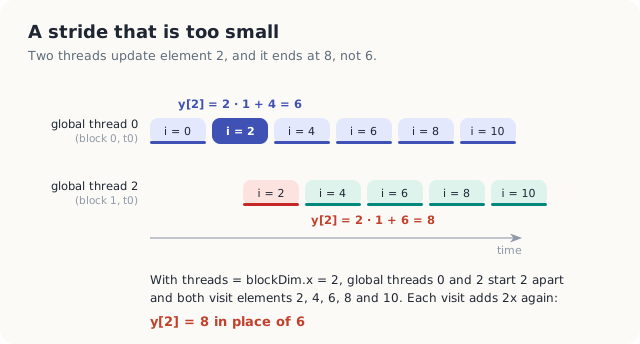
We ran the C++ program with int threads = blockDim.x; in place of gridDim.x * blockDim.x. On
the 12 elements of the example, the output was correct. The 2 blocks ran at the same moment on 2
SMs. Both threads read \(y_2 = 4\) before either of them wrote, and both wrote 6. On the measured
arrays, with 8 blocks of 256 threads, the program used \(\mathsf{gridSize} = 256\) instead of 2,048, and it
reported the following errors.
y[256] = 644, expected 324 (x = 128, y = 4)
y[257] = 647.5, expected 326.25 (x = 128.5, y = 5)
y[258] = 651, expected 328.5 (x = 129, y = 6)
loop, 1 per SM: 2366 wrong elements
Let us check the first line. Element 256 is visited by thread 0 of block 0 in its second pass, because \(0 + 1 \cdot 256 = 256\). It is also visited by thread 0 of block 1 in its first pass, because that thread’s global index is 256. The measured program uses \(a = 2.5\) and \(x_{256} = 128\), so each update adds \(2.5 \cdot 128 = 320\). The second visit read the result of the first and added 320 again. The result is \(4 + 320 + 320 = 644\), where the correct value is 324.
In 3 further runs, the count of wrong elements was 3,197, 2,781 and 3,038. In most double visits, the second thread read \(y_{\mathsf{index}}\) before the first thread’s write had arrived, and it wrote the correct value by chance. A bug of this kind can pass a small test and fail a large one, and it can fail by a different amount on every run.
Rule In an in-place map, every element must be updated by exactly
one thread, exactly once. Compute the stride from the whole grid, gridDim.x * blockDim.x, and the
starting index from the global index.
Rust does not catch this mistake. In the grid-stride kernel, we cannot use get_mut, because
get_mut accepts only the index of the calling thread, while the loop writes at the computed
indices \(\mathsf{globalIdx} + \mathsf{pass} \cdot \mathsf{gridSize}\). We therefore call get_unchecked_mut(index) inside an unsafe block. Above the
block, we write a comment that begins with // SAFETY: and states the argument of Theorem 14.1 in
2 lines. The compiler does not check this argument. A wrong stride therefore compiles in Rust as
well, and the comment then states something false.
Exercises
14.12 In Theorem 14.1, where does the proof use the fact that line 1 computes the number of
threads of the whole grid?
14.13 With the wrong stride \(\mathsf{gridSize} = 2\) on the example, which elements can end up wrong, and what
is the wrong value of \(y_9\) if both updates happen one after the other?
14.14 A kernel computes the starting index as threadIdx.x instead of the global index, with the
correct stride. Which elements of the example are updated twice, and which are never updated?
14.6 What limits the speed of SAXPY
14.6.1 Arithmetic intensity
Recall from Section 14.3.3 that SAXPY moves 12 bytes for every 2 FLOP. A GPU has 2 separate limits. Its memory can deliver only so many bytes per second, and its arithmetic units can perform only so many FLOP per second. To find out which limit SAXPY reaches first, we compare the FLOP that SAXPY performs per byte with the FLOP that the GPU can perform per byte.
Definition 14.9 Memory bandwidth and peak arithmetic rate. The memory bandwidth of a GPU is the largest number of bytes per second that its global memory can deliver. The peak arithmetic rate is the largest number of FLOP per second that its arithmetic units can perform.
Example. The Jetson Orin NX has a memory bandwidth of 102 GB/s and a single-precision peak of 2.4 TFLOP/s. The Jetson AGX Thor has 273 GB/s and 8.1 TFLOP/s.
Definition 14.10 Arithmetic intensity and ridge point. The arithmetic intensity of a kernel is the number of FLOP it performs per byte it moves to or from global memory. The ridge point of a GPU is its peak arithmetic rate divided by its memory bandwidth. It is the number of FLOP the GPU can perform in the time its memory delivers one byte. A kernel whose arithmetic intensity lies below the ridge point is called memory-bound, which means that its speed is limited by the memory bandwidth.
Example. SAXPY has an arithmetic intensity of \(2 / 12 = 0.17\) FLOP/B. The ridge point of the Orin NX is \(2{,}400 / 102 = 23.5\) FLOP/B.
To read the ridge point, consider the Orin NX. In the time its memory needs to deliver one byte, its arithmetic units can perform 23.5 FLOP. SAXPY has only 0.17 FLOP of work for each byte. The arithmetic units therefore spend most of their time waiting for data. The ridge point of the Thor is \(8{,}100 / 273 = 29.7\) FLOP/B. The arithmetic intensity of SAXPY lies 141 times below the first ridge point and 178 times below the second, as shown in Figure 14.9. Every GPU in the table of Chapter 2 has a ridge point above 10 FLOP/B, so SAXPY is memory-bound on all of them.
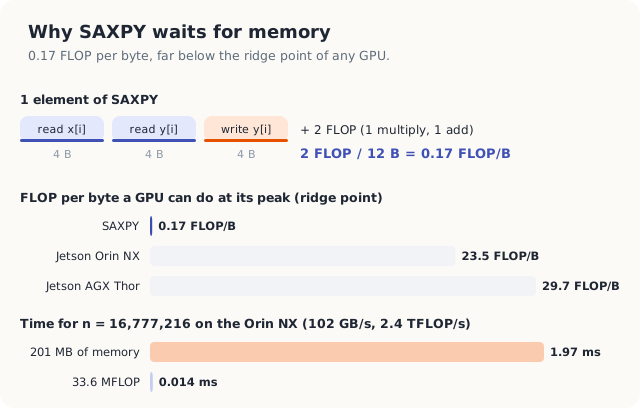
14.6.2 The shortest time the memory allows
A memory-bound kernel cannot finish before all of its bytes have passed through the memory. SAXPY on \(n\) elements moves \(12n\) bytes. A GPU whose memory bandwidth is \(W\) bytes per second needs at least \(12n / W\) seconds to move them. The time \(T\) of SAXPY therefore satisfies
\[ T \ge \frac{12\,n}{W}. \]
| Symbol | Meaning | Measured arrays on the Orin NX |
|---|---|---|
| \(T\) | time of one run of SAXPY | at least 1.97 ms |
| \(n\) | number of elements | \(2^{24} = 16{,}777{,}216\) |
| \(12\) | bytes moved per element, 2 reads and one write of 4 bytes | 12 |
| \(12n\) | bytes moved in total | 201.3 MB |
| \(W\) | memory bandwidth of the GPU | 102 GB/s |
For \(n = 2^{24}\), the 201.3 MB of SAXPY need at least \(201.3 \text{ MB} / 102 \text{ GB/s} = 1.97\) ms on the Orin NX. Its 33.6 million FLOP would take only \(33.6 \text{ MFLOP} / 2.4 \text{ TFLOP/s} = 0.014\) ms. A faster arithmetic unit would therefore not change the time of SAXPY at all. Only a faster memory would. Table 14.2 gives this shortest time for 4 GPUs.
| GPU | Memory bandwidth | Least time for \(n = 2^{24}\) | FLOP rate at that time |
|---|---|---|---|
| Jetson Orin NX 16 GB | 102 GB/s | 1.97 ms | 17 GFLOP/s |
| Jetson AGX Thor | 273 GB/s | 0.74 ms | 46 GFLOP/s |
| GeForce RTX 4090 | 1,008 GB/s | 0.20 ms | 168 GFLOP/s |
| H100 SXM | 3,350 GB/s | 0.060 ms | 558 GFLOP/s |
Table 14.2 The least time of SAXPY on \(2^{24}\) elements, from the memory bandwidth. Bandwidths from NVIDIA's data sheets.
The last column divides the 33.6 million FLOP by the least time. Even on an H100, SAXPY at its shortest time performs 558 GFLOP/s, less than 1% of that GPU’s single-precision peak of 67 TFLOP/s. We therefore measure the speed of a map in bytes per second, and we judge a map program by how close it comes to the memory bandwidth. In Section 14.8, we measure how close our programs come.
Exercises
14.15 DAXPY is SAXPY on 8-byte double-precision values. What is its arithmetic intensity, and
what is its least time for \(n = 2^{24}\) on the Orin NX?
14.16 A map computes \(z_i = \sqrt{x_i^2 + y_i^2}\) into a third array. Count its bytes per
element, counting a square root as one FLOP, and decide whether it is memory-bound on the Orin NX.
14.7 Writing the kernels in Rust and C++
14.7.1 The SAXPY kernel
We now turn the pseudocode into code. Listing 14.1 shows Saxpy-Kernel in both languages, with one thread per element.
Listing 14.1 SAXPY, one thread per element. Rust C++
mod kernels {
// ...
/// y[index] = a * x[index] + y[index], one thread per element.
#[kernel]
#[launch_bounds(256)]
#[launch_contract(domain = 1)]
pub fn saxpy(a: f32, x: &[f32], mut y: DisjointSlice<f32>) {
let thread_id = thread::index_1d();
let index = thread_id.get();
if let Some(y_element) = y.get_mut(thread_id) {
*y_element = a * x[index] + *y_element;
}
}
// ...
}// y[index] = a * x[index] + y[index], one thread per element.
__global__ void saxpy(float a, const float* x, float* y, int n)
{
int index = blockIdx.x * blockDim.x + threadIdx.x;
if (index < n) {
y[index] = a * x[index] + y[index];
}
}
In C++, we write line 1 of the pseudocode out with blockIdx.x, blockDim.x and threadIdx.x,
and the guard of line 2 is the if (i < n). In Rust, thread::index_1d() computes the same global
index, and y.get_mut(thread_id) performs the guard. It returns Some with a mutable reference to
element thread_id when the index is in range, and None otherwise. Recall from Chapter 13 that the
type of thread_id is ThreadIndex, and that only thread::index_1d() can create one. A thread can
therefore obtain a writable reference only to its own element. In both languages, we pass the
scalar a by value. The host copies its 4 bytes into the launch, and every thread reads the same
value.
The 2 attributes above the Rust kernel describe how we may launch it. #[launch_bounds(256)]
promises that no block has more than 256 threads. #[launch_contract(domain = 1)] states that the
kernel uses a one-dimensional grid. Together they let the host prepare a launch with any block
size up to 256 and check it once, before the first launch, so that the launch call itself needs no
unsafe. We use this freedom for the worked example. The following code runs the kernel on 2
blocks of 8 threads, the grid of Figure 14.4.
fn worked_example(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
) -> Result<usize, Error> {
// ...
let cover = module.prepare_saxpy(LaunchConfig1D::new(2, 8, 0))?;
module.saxpy(stream, &cover, 2.0, &x, &mut y)?;
// ...
}// Runs SAXPY with a = 2 on the 12 elements of the worked example, first with 2 blocks
// of 8 threads, then with a grid-stride loop on 2 blocks of 2 threads. Returns the
// number of wrong elements.
int workedExample()
{
// ...
saxpy<<<2, 8>>>(2.0f, x, y, 12);
// ...
}
14.7.2 Passing the function as an argument
We write the grid-stride loop as a generic map. A generic map is a kernel that applies any function
f of 2 floats, and the function of SAXPY is one example. We pass the function to the kernel as an argument.
In Rust, f is a closure. In C++, it is a lambda.
Definition 14.11 Closure. A closure is a function without a name, written inside another function, that can use the variables of the function in which it is written. A variable that a closure uses is said to be captured. C++ calls the same construct a lambda.
Example. In Rust, move |x: f32, y: f32| a * x + y is a closure of 2 parameters that captures
a. In C++, [a] __device__ (float x, float y) { return a * x + y; } is the corresponding lambda.
Listing 14.2 shows the grid-stride kernel. In each pass of its loop, it applies the function f
to one element.
Listing 14.2 The grid-stride loop, generic over the function applied to each element.
mod kernels {
// ...
/// y[index] = f(x[index], y[index]) for every index that starts at this thread's global
/// index and steps by grid_size, the number of threads in the grid.
#[kernel]
#[launch_bounds(256)]
#[launch_contract(domain = 1)]
pub fn map_stride<F>(f: F, x: &[f32], mut y: DisjointSlice<f32>)
where
F: Fn(f32, f32) -> f32 + Copy,
{
let grid_size = (thread::gridDim_x() * thread::blockDim_x()) as usize;
let mut index = thread::index_1d().get();
while index < y.len() {
// SAFETY: this thread writes only indices whose remainder modulo grid_size is
// its global index, and no 2 threads of the grid share a global index.
let y_element = unsafe { y.get_unchecked_mut(index) };
*y_element = f(x[index], *y_element);
index += grid_size;
}
}
}// y[index] = f(x[index], y[index]) for every index that starts at this thread's global
// index and steps by gridSize, the number of threads in the grid.
template <typename F>
__global__ void mapStride(F f, const float* x, float* y, int n)
{
int gridSize = gridDim.x * blockDim.x;
for (int index = blockIdx.x * blockDim.x + threadIdx.x; index < n; index += gridSize) {
y[index] = f(x[index], y[index]);
}
}
The code follows the pseudocode line by line. The variable grid_size (gridSize in C++) is \(\mathsf{gridSize}\) of line
- The first value of
indexis line 2, and the loop condition is line 3. Line 4 has become the callf(x[index], y[index]), and line 5 is the stepindex += grid_size. In C++, we write the loop as aforstatement. In Rust, we write it as awhileloop over a plainusize.
The Rust loop writes at the computed index index, which is not the thread’s own ThreadIndex. We
therefore call get_unchecked_mut(index) in an unsafe block, and its SAFETY comment repeats the
argument of Theorem 14.1. The method also skips the bounds check, which the loop condition
index < y.len() already makes unnecessary.
We pass the function as the first argument of the launch. Listing 14.3 builds the SAXPY closure, prepares the launch for the example’s 2 blocks of 2 threads, and launches the kernel.
Listing 14.3 A closure that captures \(a\), passed to the grid-stride kernel.
fn worked_example(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
) -> Result<usize, Error> {
// ...
let a = 2.0f32;
let axpy = move |x: f32, y: f32| a * x + y;
y.copy_from_host(stream, &Y12)?;
let stride = module.prepare_map_stride(LaunchConfig1D::new(2, 2, 0))?;
module.map_stride(stream, &stride, axpy, &x, &mut y)?;
// ...
}// Runs SAXPY with a = 2 on the 12 elements of the worked example, first with 2 blocks
// of 8 threads, then with a grid-stride loop on 2 blocks of 2 threads. Returns the
// number of wrong elements.
int workedExample()
{
// ...
float a = 2.0f;
auto axpy = [a] __device__ (float x, float y) { return a * x + y; };
check(cudaMemcpy(y, Y12, bytes, cudaMemcpyHostToDevice));
mapStride<<<2, 2>>>(axpy, x, y, 12);
// ...
}
Two mechanisms make a function argument work on the GPU. They are the same in both languages, and Figure 14.10 draws them.
The first mechanism concerns the code of the function. Every closure has its own type, and the
program cannot write down the name of that type. In Rust, we therefore make the kernel generic over
a type parameter F with the bound Fn(f32, f32) -> f32 + Copy. The bound says that we can call a
value of type F with 2 floats and get a float back, and that we can copy its values byte for
byte. The compiler then generates a separate copy of the kernel for every closure type with which
we launch it. This process is called monomorphization. In C++, the kernel is a template,
template <typename F>, and the compiler instantiates it once for every lambda type in the same
way. Inside each copy, the call f(...) calls one known function, so the compiler can place its
body directly into the loop. This step is called inlining.
The second mechanism concerns the data of the function. A closure value consists of the variables
it captures. The closure axpy holds the 4 bytes of a. The launch copies these bytes into a
kernel parameter, exactly as it copies the scalar a of Listing 14.1.
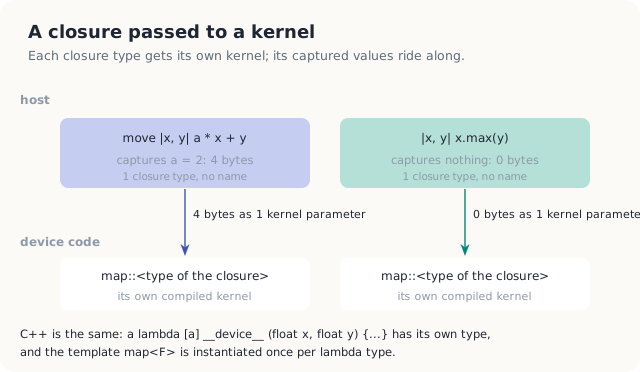
The 2 languages check different properties of the function argument. C++ requires the lambda to be
marked __device__, and nvcc accepts such a lambda in host code only with the option
--extended-lambda. It rejects a lambda that captures by reference, [&], with the error
An extended __device__ lambda cannot capture variables by reference. A lambda that captures a
host pointer by value, however, compiles. In Rust, the bound Copy rejects any closure that owns
memory, such as a closure that captures a Vec<f32>. The keyword move makes the closure copy a
instead of borrowing it. A Rust closure that borrows a host variable still compiles, because a
reference is Copy. In both cases, the GPU then reads a host address. We show the result in the
Common mistakes at the end of the chapter.
We also launch the one-thread-per-element form of the generic map, the kernel map. We launch it
with the closure axpy and with a second closure, |x, y| x.max(y), which captures nothing. We
check both results element by element against the CPU.
Exercises
14.17 Write the closure, in Rust and in C++, that turns the generic map into
\(y_i \leftarrow x_i - y_i\). How many bytes does its kernel parameter hold?
14.18 Why must the Rust bound include Copy? What would a closure that captured a Vec<f32> mean
on the GPU?
14.19 Listing 14.2 computes grid_size from blockDim_x() in Rust and blockDim.x in C++. Why is
this safer than a constant 256?
14.8 Measurements
14.8.1 Platform and method
The measurements come from an integrated GPU, a Jetson Orin NX 16 GB, with 8 SMs and a memory bandwidth of 102 GB/s. We fill \(x\) and \(y\) with \(2^{24}\) values each, which is 64 MiB per vector. This is much more than the 2 MiB L2 cache of the GPU, so every launch reads and writes global memory and not the cache. The values are \(x_i = (i \bmod 1024) \cdot 0.5\), \(y_i = i \bmod 7\) and \(a = 2.5\). With these values, every product \(2.5\,x_i\) is a multiple of 1.25 below 1,280, and a float represents every such number exactly. For example, \(x_{256} = 128\) gives the product 320. No result is rounded, so we can compare the GPU’s results with the CPU’s for exact equality.
We first run each kernel for 500 ms, so that the GPU raises its clock. We then time 50 launches with CUDA events. The rate is the 201.3 MB of one launch divided by the time of one launch. Repeated runs differed by up to 5%.
14.8.2 Results
The Rust program printed the following lines. The C++ program prints the same lines, with “lambda” in place of “closure”.
$ cargo oxide run
GPU: Orin, 8 SMs, at most 1536 threads per SM
worked example: n = 12, a = 2
x 2 7 1 8 2 8 1 8 2 8 4 5
y 3 1 4 1 5 9 2 6 5 3 5 8
2 blocks of 8 7 15 6 17 9 25 4 22 9 19 13 18
2 blocks of 2, loop 7 15 6 17 9 25 4 22 9 19 13 18
SAXPY on 16777216 floats, a = 2.5: 12 bytes and 2 FLOP per element
kernel threads per thr time rate wrong
saxpy 16777216 1.0 2.240 ms 89.9 GB/s 0
map, closure axpy 16777216 1.0 2.215 ms 90.9 GB/s 0
map, closure max: 0 wrong
loop, 1 per SM 2048 8192.0 6.122 ms 32.9 GB/s 0
loop, 2 per SM 4096 4096.0 3.373 ms 59.7 GB/s 0
loop, 3 per SM 6144 2730.7 2.575 ms 78.2 GB/s 0
loop, 6 per SM 12288 1365.3 2.279 ms 88.3 GB/s 0
loop, 12 per SM 24576 682.7 2.186 ms 92.1 GB/s 0
loop, 48 per SM 98304 170.7 2.191 ms 91.9 GB/s 0
device-to-device copy, 8 bytes per element 1.579 ms 85.0 GB/s
PASSED
The first 6 lines are the worked example. Both kernels produce the row of Figure 14.1, with
\(y_9 = 19\). In the table below the example, the column per thr is the number of elements per
thread. The column wrong counts the elements that differ from the CPU’s result, and it is 0 for
every kernel. Table 14.3 collects the times of both languages.
| Kernel | Threads | Rust time | Rust rate | C++ time | C++ rate |
|---|---|---|---|---|---|
| SAXPY, one thread per element | 16,777,216 | 2.240 ms | 89.9 GB/s | 2.208 ms | 91.2 GB/s |
| generic map, closure or lambda | 16,777,216 | 2.215 ms | 90.9 GB/s | 2.219 ms | 90.7 GB/s |
| grid-stride loop, 1 block per SM | 2,048 | 6.122 ms | 32.9 GB/s | 5.949 ms | 33.8 GB/s |
| grid-stride loop, 2 blocks per SM | 4,096 | 3.373 ms | 59.7 GB/s | 3.292 ms | 61.1 GB/s |
| grid-stride loop, 3 blocks per SM | 6,144 | 2.575 ms | 78.2 GB/s | 2.502 ms | 80.5 GB/s |
| grid-stride loop, 6 blocks per SM | 12,288 | 2.279 ms | 88.3 GB/s | 2.163 ms | 93.1 GB/s |
| grid-stride loop, 12 blocks per SM | 24,576 | 2.186 ms | 92.1 GB/s | 2.178 ms | 92.4 GB/s |
| grid-stride loop, 48 blocks per SM | 98,304 | 2.191 ms | 91.9 GB/s | 2.232 ms | 90.2 GB/s |
| device-to-device copy (driver) | 1.579 ms | 85.0 GB/s | 1.579 ms | 85.0 GB/s |
Table 14.3 SAXPY on \(2^{24}\) elements on the measured GPU. The rate is 201.3 MB divided by the time; the copy moves 134.2 MB.
Figure 14.11 plots the same rates. We draw 3 conclusions from them. First, the 2 languages run at
the same speed, within the variation between runs. Second, the generic map with a closure or a
lambda is as fast as the hand-written SAXPY kernel. Monomorphization produced the same arithmetic on
the same data, and the value of a arrives in a kernel parameter in both cases. Third, no kernel
exceeds 93.1 GB/s, which is 91% of the 102 GB/s of the memory.
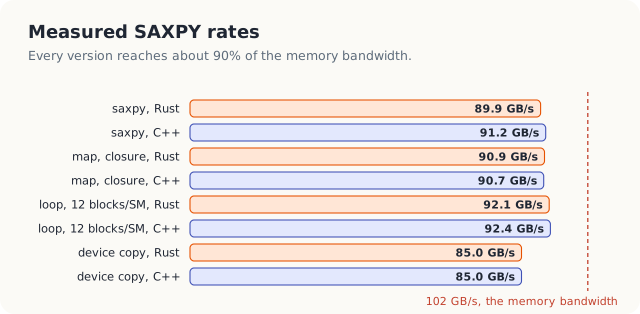
14.8.3 Why SAXPY reaches 91 GB/s and not 102 GB/s
In Section 14.6.2, we predicted a time of at least 1.97 ms at 102 GB/s. The kernels took 2.16 ms to 2.24 ms, which is 10% to 14% longer.
The figure of 102 GB/s is the rate at the pins of the memory chips. The memory bus of the measured GPU is 128 bits wide, so it moves 16 bytes per transfer, and it performs 6,400 million transfers per second. This gives \(16 \text{ B} \cdot 6.4 \cdot 10^9 \text{ /s} = 102.4 \text{ GB/s}\). The memory cannot use every one of those transfers for our data, however. It must refresh its rows at regular intervals. It must open a row before it can read from it. It also loses time each time the bus turns around from reading to writing. SAXPY writes one value for every 2 values that it reads, so its stream of requests changes direction often.3
We have 2 other measurements that tell us what a program can expect from this memory. The driver’s own device-to-device copy, which also reads and writes, reached 85.0 GB/s, which is less than SAXPY. The dot product of Chapter 15, which only reads, reaches 92 GB/s to 100 GB/s. The 90 GB/s to 93 GB/s of SAXPY lie between these 2 rates, at 88% to 91% of the pin rate. We have nothing left to remove from the kernel. It reads each input once, writes each output once, and every read and write is coalesced.
14.8.4 How many blocks a grid-stride loop needs
The grid-stride rows of Table 14.3 show a second effect. With one block of 256 threads per SM, the loop reaches only 32.9 GB/s, which is a third of the bandwidth. The rate almost doubles with 2 blocks per SM and rises again with 3. From 6 blocks onwards, it matches the kernel with one thread per element. The kernel is the same in every row. Only the number of threads changes.
To explain this effect, we use a law from the theory of queues. The law relates the rate at which a system completes requests to the number of requests it works on at once.
Definition 14.12 Little’s law. In a system that serves requests, the throughput \(X\) is the number of requests completed per unit of time. The latency \(L\) is the time from the start of a request to its completion. The concurrency \(C\) is the number of requests in progress at once. In a steady state, the 3 quantities satisfy
\[ X = \frac{C}{L}. \]
Example. With 16,384 bytes of reads in progress and a latency of 0.50 µs, the memory delivers \(16{,}384 \text{ B} / 0.50\ \mu\text{s} = 32.8\) GB/s.
| Symbol | Meaning | 1 block per SM |
|---|---|---|
| \(X\) | throughput, the bytes delivered by the memory per second | 32.9 GB/s measured |
| \(C\) | concurrency, the bytes of reads in progress at once | 16,384 B |
| \(L\) | latency, the time from issuing a read to receiving its data | 0.50 µs |
A pizza kitchen. Picture a kitchen with a large oven. Every pizza needs 10 minutes in the oven, however many pizzas are inside. If the cooks put in one pizza at a time, the kitchen finishes 6 pizzas an hour. If they keep 4 pizzas in the oven at all times, it finishes 24 an hour. The oven did not get faster. The kitchen only kept more orders in progress. The rate goes on rising in this way until the oven is full, and after that more waiting orders do not help.
The mapping to the hardware is direct. The oven is the memory system, and the 10 minutes are the latency \(L\) of a read. The pizzas in the oven are the bytes of reads in progress, \(C\), and the pizzas finished per hour are the throughput \(X\). A full oven is the memory bandwidth. The analogy breaks down in one respect. A real oven bakes every pizza in the same time, while the latency of a memory read grows as the memory gets busier.
The reasoning behind the law is short. If the memory works on \(C\) bytes at a time, and each byte takes \(L\) seconds to arrive, then \(C\) bytes are completed every \(L\) seconds. The memory therefore delivers \(C / L\) bytes per second. To raise the throughput without changing the latency, a program must keep more bytes in progress at once.
We now apply the law to the grid-stride loop. In each pass, a thread issues its 2 reads of 4 bytes, 8 bytes in all. It cannot issue the reads of the next pass before it has stored the current result. Each thread therefore keeps about 8 bytes in flight. With one block per SM, the GPU runs \(8 \cdot 256 = 2{,}048\) threads, which keep \(2{,}048 \cdot 8 = 16{,}384\) bytes in flight. The measured 32.9 GB/s then gives a latency of \(L = C / X = 16{,}384 \text{ B} / 32.9 \text{ GB/s} = 0.50\) µs. That is about 500 cycles of the GPU’s clock, which matches the latency of global memory in Definition 14.5.
If the latency stays fixed, the law predicts twice the rate for twice the concurrency. For 2 blocks per SM, it predicts 65.8 GB/s, and we measured 59.7 GB/s and 61.1 GB/s. For 3 blocks, it predicts 98.7 GB/s, and we measured 78.2 GB/s and 80.5 GB/s. Beyond 3 blocks, the bandwidth caps the rate, as shown in Figure 14.12. The measurements fall below the prediction at 2 and 3 blocks for 2 reasons. The latency grows as the memory gets busier, and a thread does not have 8 bytes in flight at every moment, because it also computes, stores and tests the loop condition.
We can also read the law the other way, to find how many bytes must be in flight to reach the bandwidth. The answer is \(C = X L = 102 \text{ GB/s} \cdot 0.50\ \mu\text{s} = 51\) KB. At 8 bytes per thread, this is 6,375 threads, or about 3.1 blocks of 256 threads on each of the 8 SMs.
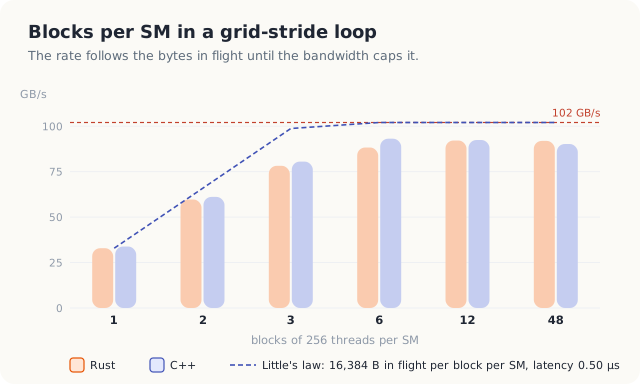
The measured GPU can hold up to 1,536 threads per SM, which is 6 blocks of 256 threads. A grid of 6 blocks per SM therefore fills the GPU in one round, and the measurements show no gain beyond it. In general, we should launch a grid-stride loop with at least as many blocks as the GPU can hold at once. The host program computes this number from 2 values that it reads from the device, the number of SMs and the number of threads per SM.
Exercises
14.20 From Table 14.3, compute the fraction of the 102 GB/s that each language reaches with one
thread per element.
14.21 A GPU with 132 SMs, 2,048 threads per SM and 3,350 GB/s has a memory latency of about 0.6 µs.
How many bytes must be in flight to reach its bandwidth, and how many blocks of 256 threads per SM
provide them at 8 bytes per thread?
14.9 Limits of what we built
Our kernels reach about 90% of the memory’s pin rate, and no change to the kernel can do much better, because the kernel already reads and writes each byte only once. The only way to make SAXPY faster is to move fewer bytes. In a real program, we do this by fusing SAXPY with the computation that comes before it or after it. If the next step of the program reads \(y\) again, a single kernel that computes both steps saves one write and one read of the whole array. In Chapter 15, we fuse a map with a sum in exactly this way.
In practice, most programs do not write SAXPY by hand. They call cublasSaxpy from NVIDIA’s cuBLAS
library, or they write thrust::transform with a lambda in C++. These library calls are memory-bound
in the same way as our kernels. We build the kernel by hand because
every map, and every library call that implements one, faces the same questions of grid size,
guard, stride and bytes per element.
14.10 The complete programs
Listing 14.4 gives the complete programs, from which every piece of code in this chapter was taken.
Listing 14.4 The complete programs. code/oxide/ch14_map_saxpy/src/main.rs code/cuda/ch14_map_saxpy/saxpy.cu
//! Chapter 14: SAXPY, y = a x + y, with 1 thread per element, as a generic map that
//! takes a closure, and with a grid-stride loop that uses fewer threads than elements.
//!
//! cargo oxide run
use std::sync::Arc;
use std::time::Instant;
use cuda_core::sys::CUevent_flags_enum_CU_EVENT_DEFAULT as TIMING;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, LaunchConfig1D};
use cuda_device::{DisjointSlice, cuda_module, kernel, thread};
use cuda_device::{launch_bounds, launch_contract};
const BLOCK: u32 = 256;
const N: usize = 1 << 24;
const A: f32 = 2.5;
const RUNS: u32 = 50;
/// The worked example of the chapter: 12 elements, a = 2.
const X12: [f32; 12] = [2.0, 7.0, 1.0, 8.0, 2.0, 8.0, 1.0, 8.0, 2.0, 8.0, 4.0, 5.0];
const Y12: [f32; 12] = [3.0, 1.0, 4.0, 1.0, 5.0, 9.0, 2.0, 6.0, 5.0, 3.0, 5.0, 8.0];
type Error = Box<dyn std::error::Error>;
#[cuda_module]
mod kernels {
use super::*;
/// y[index] = a * x[index] + y[index], one thread per element.
#[kernel]
#[launch_bounds(256)]
#[launch_contract(domain = 1)]
pub fn saxpy(a: f32, x: &[f32], mut y: DisjointSlice<f32>) {
let thread_id = thread::index_1d();
let index = thread_id.get();
if let Some(y_element) = y.get_mut(thread_id) {
*y_element = a * x[index] + *y_element;
}
}
/// y[index] = f(x[index], y[index]), one thread per element, for any function f.
#[kernel]
#[launch_bounds(256)]
#[launch_contract(domain = 1)]
pub fn map<F>(f: F, x: &[f32], mut y: DisjointSlice<f32>)
where
F: Fn(f32, f32) -> f32 + Copy,
{
let thread_id = thread::index_1d();
let index = thread_id.get();
if let Some(y_element) = y.get_mut(thread_id) {
*y_element = f(x[index], *y_element);
}
}
/// y[index] = f(x[index], y[index]) for every index that starts at this thread's global
/// index and steps by grid_size, the number of threads in the grid.
#[kernel]
#[launch_bounds(256)]
#[launch_contract(domain = 1)]
pub fn map_stride<F>(f: F, x: &[f32], mut y: DisjointSlice<f32>)
where
F: Fn(f32, f32) -> f32 + Copy,
{
let grid_size = (thread::gridDim_x() * thread::blockDim_x()) as usize;
let mut index = thread::index_1d().get();
while index < y.len() {
// SAFETY: this thread writes only indices whose remainder modulo grid_size is
// its global index, and no 2 threads of the grid share a global index.
let y_element = unsafe { y.get_unchecked_mut(index) };
*y_element = f(x[index], *y_element);
index += grid_size;
}
}
}
/// Milliseconds per launch: 500 ms of warm-up, then RUNS launches timed with events.
fn time_ms<F>(stream: &CudaStream, mut launch: F) -> Result<f64, Error>
where
F: FnMut() -> Result<(), Error>,
{
let warm = Instant::now();
while warm.elapsed().as_millis() < 500 {
launch()?;
stream.synchronize()?;
}
let start = stream.record_event(Some(TIMING))?;
for _ in 0..RUNS {
launch()?;
}
let stop = stream.record_event(Some(TIMING))?;
stop.synchronize()?;
Ok(start.elapsed_ms(&stop)? as f64 / RUNS as f64)
}
/// Resets y, runs `launch` once, and counts the elements that differ from a x + y.
fn wrong<F>(
stream: &Arc<CudaStream>,
y: &mut DeviceBuffer<f32>,
x0: &[f32],
y0: &[f32],
mut launch: F,
) -> Result<usize, Error>
where
F: FnMut(&mut DeviceBuffer<f32>) -> Result<(), Error>,
{
y.copy_from_host(stream, y0)?;
launch(y)?;
let got = y.to_host_vec(stream)?;
let expect = x0.iter().zip(y0).map(|(&x, &y)| A * x + y);
Ok(got.iter().zip(expect).filter(|(g, e)| **g != *e).count())
}
fn report(name: &str, threads: u32, bytes: usize, ms: f64, wrong: usize) {
let gbs = bytes as f64 / ms / 1e6;
let each = N as f64 / threads as f64;
print!(" {name:<20} {threads:>9} {each:>7.1}");
println!(" {ms:>7.3} ms {gbs:>6.1} GB/s {wrong:>5}");
}
fn show(name: &str, values: &[f32]) {
let row: Vec<String> = values.iter().map(|v| format!("{v:3}")).collect();
println!(" {name:<20}{}", row.join(""));
}
/// Runs SAXPY with a = 2 on the 12 elements of the worked example, first with 2 blocks
/// of 8 threads, then with a grid-stride loop on 2 blocks of 2 threads. Returns the
/// number of wrong elements.
fn worked_example(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
) -> Result<usize, Error> {
let x = DeviceBuffer::from_host(stream, &X12)?;
let mut y = DeviceBuffer::from_host(stream, &Y12)?;
let expect: Vec<f32> = X12.iter().zip(&Y12).map(|(x, y)| 2.0 * x + y).collect();
println!("worked example: n = 12, a = 2");
show("x", &X12);
show("y", &Y12);
let cover = module.prepare_saxpy(LaunchConfig1D::new(2, 8, 0))?;
module.saxpy(stream, &cover, 2.0, &x, &mut y)?;
let first = y.to_host_vec(stream)?;
show("2 blocks of 8", &first);
let a = 2.0f32;
let axpy = move |x: f32, y: f32| a * x + y;
y.copy_from_host(stream, &Y12)?;
let stride = module.prepare_map_stride(LaunchConfig1D::new(2, 2, 0))?;
module.map_stride(stream, &stride, axpy, &x, &mut y)?;
let second = y.to_host_vec(stream)?;
show("2 blocks of 2, loop", &second);
let bad_first = first.iter().zip(&expect).filter(|(g, e)| g != e).count();
let bad_second = second.iter().zip(&expect).filter(|(g, e)| g != e).count();
Ok(bad_first + bad_second)
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let name = ctx.device_name()?;
let sms = ctx.multiprocessor_count()?;
let per_sm = ctx.max_threads_per_multiprocessor()?;
println!("GPU: {name}, {sms} SMs, at most {per_sm} threads per SM");
let mut failed = worked_example(&module, &stream)?;
println!("SAXPY on {N} floats, a = {A}: 12 bytes and 2 FLOP per element");
let x0: Vec<f32> = (0..N).map(|i| (i % 1024) as f32 * 0.5).collect();
let y0: Vec<f32> = (0..N).map(|i| (i % 7) as f32).collect();
let x = DeviceBuffer::from_host(&stream, &x0)?;
let mut y = DeviceBuffer::from_host(&stream, &y0)?;
let a = A;
let axpy = move |x: f32, y: f32| a * x + y;
let blocks = (N as u32).div_ceil(BLOCK);
let one_each = LaunchConfig1D::new(blocks, BLOCK, 0);
let bytes = 12 * N;
println!(" kernel threads per thr time rate wrong");
let saxpy = module.prepare_saxpy(one_each)?;
let mut launch = |y: &mut DeviceBuffer<f32>| {
Ok(module.saxpy(&stream, &saxpy, A, &x, y)?)
};
let bad = wrong(&stream, &mut y, &x0, &y0, &mut launch)?;
let ms = time_ms(&stream, || launch(&mut y))?;
report("saxpy", blocks * BLOCK, bytes, ms, bad);
failed += bad;
let map = module.prepare_map(one_each)?;
let mut launch = |y: &mut DeviceBuffer<f32>| {
Ok(module.map(&stream, &map, axpy, &x, y)?)
};
let bad = wrong(&stream, &mut y, &x0, &y0, &mut launch)?;
let ms = time_ms(&stream, || launch(&mut y))?;
report("map, closure axpy", blocks * BLOCK, bytes, ms, bad);
failed += bad;
let larger = |x: f32, y: f32| x.max(y);
let max = module.prepare_map(one_each)?;
y.copy_from_host(&stream, &y0)?;
module.map(&stream, &max, larger, &x, &mut y)?;
let got = y.to_host_vec(&stream)?;
let expect = x0.iter().zip(&y0).map(|(x, y)| x.max(*y));
let bad = got.iter().zip(expect).filter(|(g, e)| **g != *e).count();
println!(" map, closure max: {bad} wrong");
failed += bad;
for k in [1, 2, 3, 6, 12, 48] {
let grid = LaunchConfig1D::new(sms * k, BLOCK, 0);
let stride = module.prepare_map_stride(grid)?;
let mut launch = |y: &mut DeviceBuffer<f32>| {
Ok(module.map_stride(&stream, &stride, axpy, &x, y)?)
};
let bad = wrong(&stream, &mut y, &x0, &y0, &mut launch)?;
let ms = time_ms(&stream, || launch(&mut y))?;
report(&format!("loop, {k} per SM"), sms * k * BLOCK, bytes, ms, bad);
failed += bad;
}
let mut copy = DeviceBuffer::<f32>::zeroed(&stream, N)?;
let ms = time_ms(&stream, || Ok(copy.copy_from_device_async(&x, &stream)?))?;
let gbs = (8 * N) as f64 / ms / 1e6;
println!(" device-to-device copy, 8 bytes per element {ms:>7.3} ms {gbs:>6.1} GB/s");
if failed == 0 {
println!("PASSED");
} else {
println!("FAILED: {failed} wrong elements");
}
Ok(())
}// Chapter 14: SAXPY, y = a x + y, with 1 thread per element, as a generic map that
// takes a lambda, and with a grid-stride loop that uses fewer threads than elements.
// Build: nvcc -O3 -arch=native --extended-lambda saxpy.cu -o saxpy
#include <algorithm>
#include <chrono>
#include <cstdio>
#include <cstdlib>
#include <string>
#include <vector>
#include <cuda_runtime.h>
const int BLOCK = 256;
const int N = 1 << 24;
const float A = 2.5f;
const int RUNS = 50;
// The worked example of the chapter: 12 elements, a = 2.
const float X12[12] = {2, 7, 1, 8, 2, 8, 1, 8, 2, 8, 4, 5};
const float Y12[12] = {3, 1, 4, 1, 5, 9, 2, 6, 5, 3, 5, 8};
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
// y[index] = a * x[index] + y[index], one thread per element.
__global__ void saxpy(float a, const float* x, float* y, int n)
{
int index = blockIdx.x * blockDim.x + threadIdx.x;
if (index < n) {
y[index] = a * x[index] + y[index];
}
}
// y[index] = f(x[index], y[index]), one thread per element, for any function f.
template <typename F>
__global__ void map(F f, const float* x, float* y, int n)
{
int index = blockIdx.x * blockDim.x + threadIdx.x;
if (index < n) {
y[index] = f(x[index], y[index]);
}
}
// y[index] = f(x[index], y[index]) for every index that starts at this thread's global
// index and steps by gridSize, the number of threads in the grid.
template <typename F>
__global__ void mapStride(F f, const float* x, float* y, int n)
{
int gridSize = gridDim.x * blockDim.x;
for (int index = blockIdx.x * blockDim.x + threadIdx.x; index < n; index += gridSize) {
y[index] = f(x[index], y[index]);
}
}
// Milliseconds per launch: 500 ms of warm-up, then RUNS launches timed with events.
template <typename L>
float timeMs(L launch)
{
auto warm = std::chrono::steady_clock::now();
while (std::chrono::steady_clock::now() - warm < std::chrono::milliseconds(500)) {
launch();
check(cudaDeviceSynchronize());
}
cudaEvent_t start, stop;
check(cudaEventCreate(&start));
check(cudaEventCreate(&stop));
check(cudaEventRecord(start));
for (int r = 0; r < RUNS; ++r) {
launch();
}
check(cudaEventRecord(stop));
check(cudaEventSynchronize(stop));
float ms = 0;
check(cudaEventElapsedTime(&ms, start, stop));
check(cudaEventDestroy(start));
check(cudaEventDestroy(stop));
return ms / RUNS;
}
// Resets y, runs `launch` once, and counts the elements that differ from a x + y.
template <typename L>
int wrong(float* y, const std::vector<float>& x0, const std::vector<float>& y0, L launch)
{
size_t bytes = N * sizeof(float);
check(cudaMemcpy(y, y0.data(), bytes, cudaMemcpyHostToDevice));
launch();
check(cudaGetLastError());
std::vector<float> got(N);
check(cudaMemcpy(got.data(), y, bytes, cudaMemcpyDeviceToHost));
int bad = 0;
for (int i = 0; i < N; ++i) {
bad += got[i] != A * x0[i] + y0[i];
}
return bad;
}
void report(const char* name, long threads, float ms, int bad)
{
double gbs = 12.0 * N / ms / 1e6;
double each = double(N) / threads;
std::printf(" %-20s %9ld %7.1f", name, threads, each);
std::printf(" %7.3f ms %6.1f GB/s %5d\n", ms, gbs, bad);
}
void show(const char* name, const float* values)
{
std::printf(" %-20s", name);
for (int i = 0; i < 12; ++i) {
std::printf("%3.0f", values[i]);
}
std::printf("\n");
}
// Runs SAXPY with a = 2 on the 12 elements of the worked example, first with 2 blocks
// of 8 threads, then with a grid-stride loop on 2 blocks of 2 threads. Returns the
// number of wrong elements.
int workedExample()
{
size_t bytes = 12 * sizeof(float);
float *x, *y;
check(cudaMalloc(&x, bytes));
check(cudaMalloc(&y, bytes));
check(cudaMemcpy(x, X12, bytes, cudaMemcpyHostToDevice));
check(cudaMemcpy(y, Y12, bytes, cudaMemcpyHostToDevice));
std::printf("worked example: n = 12, a = 2\n");
show("x", X12);
show("y", Y12);
float first[12], second[12];
saxpy<<<2, 8>>>(2.0f, x, y, 12);
check(cudaMemcpy(first, y, bytes, cudaMemcpyDeviceToHost));
show("2 blocks of 8", first);
float a = 2.0f;
auto axpy = [a] __device__ (float x, float y) { return a * x + y; };
check(cudaMemcpy(y, Y12, bytes, cudaMemcpyHostToDevice));
mapStride<<<2, 2>>>(axpy, x, y, 12);
check(cudaMemcpy(second, y, bytes, cudaMemcpyDeviceToHost));
show("2 blocks of 2, loop", second);
int bad = 0;
for (int i = 0; i < 12; ++i) {
float expect = 2.0f * X12[i] + Y12[i];
bad += (first[i] != expect) + (second[i] != expect);
}
check(cudaFree(x));
check(cudaFree(y));
return bad;
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
int sms = prop.multiProcessorCount;
std::printf("GPU: %s, %d SMs, ", prop.name, sms);
std::printf("at most %d threads per SM\n", prop.maxThreadsPerMultiProcessor);
int failed = workedExample();
std::printf("SAXPY on %d floats, a = %.1f: 12 bytes and 2 FLOP per element\n", N, A);
std::vector<float> x0(N), y0(N);
for (int i = 0; i < N; ++i) {
x0[i] = (i % 1024) * 0.5f;
y0[i] = i % 7;
}
size_t bytes = N * sizeof(float);
float *x, *y, *copy;
check(cudaMalloc(&x, bytes));
check(cudaMalloc(&y, bytes));
check(cudaMalloc(©, bytes));
check(cudaMemcpy(x, x0.data(), bytes, cudaMemcpyHostToDevice));
float a = A;
auto axpy = [a] __device__ (float x, float y) { return a * x + y; };
int blocks = (N + BLOCK - 1) / BLOCK;
long all = long(blocks) * BLOCK;
std::printf(" kernel threads per thr time rate wrong\n");
auto plain = [&] { saxpy<<<blocks, BLOCK>>>(A, x, y, N); };
int bad = wrong(y, x0, y0, plain);
report("saxpy", all, timeMs(plain), bad);
failed += bad;
auto generic = [&] { map<<<blocks, BLOCK>>>(axpy, x, y, N); };
bad = wrong(y, x0, y0, generic);
report("map, lambda axpy", all, timeMs(generic), bad);
failed += bad;
auto larger = [] __device__ (float x, float y) { return fmaxf(x, y); };
check(cudaMemcpy(y, y0.data(), bytes, cudaMemcpyHostToDevice));
map<<<blocks, BLOCK>>>(larger, x, y, N);
std::vector<float> got(N);
check(cudaMemcpy(got.data(), y, bytes, cudaMemcpyDeviceToHost));
bad = 0;
for (int i = 0; i < N; ++i) {
bad += got[i] != std::max(x0[i], y0[i]);
}
std::printf(" map, lambda max: %d wrong\n", bad);
failed += bad;
for (int k : {1, 2, 3, 6, 12, 48}) {
int grid = sms * k;
auto loop = [&] { mapStride<<<grid, BLOCK>>>(axpy, x, y, N); };
bad = wrong(y, x0, y0, loop);
std::string name = "loop, " + std::to_string(k) + " per SM";
report(name.c_str(), long(grid) * BLOCK, timeMs(loop), bad);
failed += bad;
}
auto copyAll = [&] { cudaMemcpyAsync(copy, x, bytes, cudaMemcpyDeviceToDevice); };
float ms = timeMs(copyAll);
double gbs = 8.0 * N / ms / 1e6;
std::printf(" device-to-device copy, 8 bytes per element ");
std::printf(" %7.3f ms %6.1f GB/s\n", ms, gbs);
check(cudaFree(x));
check(cudaFree(y));
check(cudaFree(copy));
if (failed == 0) {
std::printf("PASSED\n");
} else {
std::printf("FAILED: %d wrong elements\n", failed);
}
return 0;
}
Common mistakes
A missing guard lets threads write past the end of an array. Without if (i < n), the threads of
the last block whose index lies at or beyond \(n\) write past the end of the array, and the GPU
usually reports nothing (Section 14.5.1). In Rust, DisjointSlice::get_mut makes the guard part of
the type.
A stride computed from the block instead of the grid makes several blocks update the same
elements. With blockDim.x in place of gridDim.x * blockDim.x, the result of an in-place map is
wrong, by a different amount on each run (Section 14.5.3).
Calling get_mut with a computed index does not compile. In a grid-stride loop, the index index is a
usize, and get_mut accepts only the ThreadIndex of the calling thread. If we replace
get_unchecked_mut(index) in Listing 14.2 by y.get_mut(index), the build stops with the following error.
$ cargo oxide build
error[E0308]: mismatched types
--> src/main.rs:73:48
|
73 | if let Some(y_element) = y.get_mut(index) {
| ------- ^^^^^ expected `ThreadIndex<'_>`, found `usize`
| |
| arguments to this method are incorrect
A closure that refers to a host variable makes the GPU read a host address. The Rust closure
move |x: f32, y: f32| x + y + host[0], with let host = &x0;, compiles, because a reference is
Copy. On the measured GPU, the next synchronization then reports
Error: DriverError(700, "an illegal memory access was encountered"). A C++ lambda that captures a
host pointer by value, [hp], compiles and fails with the same error. nvcc rejects a capture by
reference outright.
A grid-stride loop with too few blocks leaves the memory idle. With one block of 256 threads per SM, the loop reached a third of the bandwidth (Section 14.8.4). We should size the grid from the number of SMs, so that it contains at least one full round of resident blocks.
Arrays that fit in the cache give misleading rates. A GPU with a large L2 cache keeps small arrays between launches, and the measured rate then describes the cache and not the memory. The arrays of this chapter, 128 MiB together, are larger than the L2 cache of every GPU in Table 14.2.
Summary
- A map computes each output element from the input elements at the same position. SAXPY, \(y \leftarrow a x + y\), is a map. On the example, it turns \(y_9 = 3\) into \(2 \cdot 8 + 3 = 19\).
- The sequential loop performs \(n\) passes of 2 FLOP and 12 bytes each. No pass uses a value that another pass produces, so we can give each pass its own thread.
- With blocks of \(B\) threads, \(\lceil n / B \rceil\) blocks cover \(n\) elements, and the guard \(i < n\) stops the extra threads. For the example, this means 2 blocks of 8 threads and 4 idle threads.
- A grid-stride loop lets \(P < n\) threads cover the array. Thread \(t\) takes \(t, t + P, t + 2P, \ldots\), which keeps every read of every warp coalesced. Theorem 14.1 proves that each element is updated exactly once. With a wrong stride, 2,366 elements of the measured arrays were updated twice.
- SAXPY performs 0.17 FLOP per byte, far below the ridge point of every GPU, so its time is at least \(12 n / W\). For \(2^{24}\) elements at 102 GB/s, this is 1.97 ms.
- A generic map takes a Rust closure or a C++ lambda. The compiler builds one kernel per closure type, and the captured values travel in one kernel parameter.
- On the measured GPU, SAXPY ran at 90 GB/s to 93 GB/s in both languages, about 90% of the 102 GB/s of the memory. A grid-stride loop needs about 3 blocks of 256 threads per SM to keep enough bytes in flight, and 6 to fill the GPU.
In Chapter 15, we combine many values into one, which is the second basic pattern of parallel programming.
Exercises
- Run the program on your GPU. From its first line, compute how many blocks of 256 threads fit on one SM, and check whether the grid-stride rate stops rising at about that number of blocks per SM.
- Write a generic map that computes \(y_i \leftarrow \max(0, x_i) + y_i\) and measure it. Does the extra comparison change the rate? Explain your answer with the arithmetic intensity.
- Change the Rust closure
axpyso that it captures 2 values,aandb, and computes \(a x + b y\). How large is the kernel parameter that carries it? - Using the latency of 0.50 µs from Section 14.8.4, predict the rate of the grid-stride kernel with one block of 256 threads per SM on a GPU with 20 SMs and 273 GB/s. How many blocks per SM would reach the bandwidth?
- Suppose each thread of the grid-stride loop handled 2 elements per pass and issued 16 bytes of reads before computing. By Little’s law, how many blocks per SM would keep the memory of the measured GPU busy?
- Prove that Saxpy-Kernel updates every element exactly once when we launch it with \(\lceil n / B \rceil\) blocks of \(B\) threads.
- Write SAXPY on
f64in both languages and measure it. Is its time twice that of thef32version, as the byte count predicts?
Sources and further reading
- A. Pathak, An Introduction to Tiled Parallel Programming, Simplified, 2026. The style of worked example, pseudocode and proof used in this part of the book.
- T. H. Cormen, C. E. Leiserson, R. L. Rivest and C. Stein, Introduction to Algorithms, 4th ed., MIT Press, 2022. The pseudocode conventions and loop-invariant proofs.
- C. L. Lawson, R. J. Hanson, D. R. Kincaid and F. T. Krogh, “Basic Linear Algebra Subprograms for Fortran Usage”, ACM Transactions on Mathematical Software 5(3), 1979. The original definition of SAXPY.
- M. Harris, “CUDA Pro Tip: Write Flexible Kernels with Grid-Stride Loops”, NVIDIA Technical Blog, 2013.
- J. D. C. Little, “A Proof for the Queuing Formula: L = λW”, Operations Research 9(3), 1961.
- NVIDIA, CUDA C++ Programming Guide, sections “Extended Lambdas” and “Compute Capabilities”.
- The Rust Reference, chapters “Closure expressions” and “Closure types”. The cuda-oxide repository, https://github.com/NVlabs/cuda-oxide.
-
Lawson, Hanson, Kincaid and Krogh published the first set of these routines in 1979. Later sets, called Level 2 and Level 3 BLAS, added matrix-vector and matrix-matrix routines. ↩
-
M. Harris, “CUDA Pro Tip: Write Flexible Kernels with Grid-Stride Loops”, NVIDIA Technical Blog, 2013. ↩
-
The memory chips are LPDDR5 on this GPU. A refresh, a row opening and a change of direction each take a fixed number of cycles during which the bus carries no data. ↩
Chapter 15: Reduction and the Dot Product
The dot product of 2 vectors multiplies the vectors element by element and adds up the products. It is the inner loop of a matrix-vector product, it gives the length of a vector and the angle between 2 vectors, and every iterative solver computes several dot products in each step to decide how far it is from convergence. The multiplications form a map, the pattern of Chapter 14, and they can run in parallel in the same way. The additions cannot be treated in this way. All products must flow into a single number, and the obvious loop adds them one after another, each addition waiting for the one before it. A computation that combines many values into 1 value in this way is called a reduction, and it is the second basic pattern of parallel programming.
In this chapter, we develop the parallel reduction on the dot product of 2 vectors of 16 small integers. We first write the sequential loop and examine its chain of dependent additions. We then use the associativity of addition to regroup the additions into a tree, in which many additions can be performed at the same time. The tree becomes a kernel in which the threads of a block add their values in shared memory, step by step, with a barrier between consecutive steps. We remove a barrier to see the wrong sum that results, and we prove with a loop invariant that the tree is correct when all barriers are present. After that, we replace most of the barriers by warp shuffles, and we compare two ways of combining the sums of different blocks, a second launch and atomic additions. Finally, we implement all designs in Rust with cuda-oxide and in CUDA C++. From the measurements, we explain why the fused kernel runs more than twice as fast as a map followed by a separate reduction, and why atomic additions change the last bits of the result from run to run.
This chapter covers
- the dot product as a map followed by a reduction, worked by hand on 16 elements
- the sequential sum and its chain of dependent additions
- associativity, commutativity and the reduction tree
- the tree in shared memory: strides, active threads and barriers, step by step
- a missing barrier and the wrong sum it produces
- a loop-invariant proof that the tree computes the sum
- warp shuffles and a block sum with 1 barrier
- combining the block sums with a second launch or with atomic additions
- why the order of float additions changes the result
- measured rates in Rust and C++ against the memory bandwidth
The code of the chapter is in
code/oxide/ch15_dot_product/
(Rust) and
code/cuda/ch15_dot_product/
(C++). The Rust crate uses the same Cargo.toml and rust-toolchain.toml as Chapter 13.
15.1 The problem
15.1.1 A worked example
We use the same pair of vectors throughout the chapter, so that every number can be checked by hand. Each vector holds 16 small integers.
\[ \begin{aligned} a &= (1, 2, 3, 1, 5, 1, 2, 3,\ 3, 1, 2, 3, 1, 3, 2, 1),\\ b &= (2, 3, 1, 4, 1, 1, 4, 1,\ 1, 2, 2, 2, 1, 3, 1, 4). \end{aligned} \]
As in Chapter 14, we number the positions from 0 and write \(a_i\) for the element of \(a\) at position \(i\), so that \(a_0 = 1\) and \(b_0 = 2\). We multiply the 2 vectors position by position. The first 8 products are \(a_0 b_0 = 1 \cdot 2 = 2\), \(a_1 b_1 = 2 \cdot 3 = 6\), 3, 4, 5, 1, 8 and 3, and they add up to 32. The last 8 products are 3, 2, 4, 6, 1, 9, 2 and 4, and they add up to 31. The dot product is therefore \(32 + 31 = 63\), as shown in Figure 15.1.
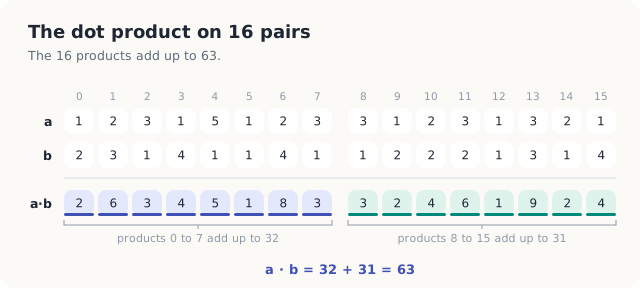
The example contains 3 numbers that appear again and again in the chapter. The first 8 products add up to 32, the last 8 products add up to 31, and all 16 products add up to 63. Later in the chapter, the GPU splits the work exactly along this line, with one block for each half of the vectors. The faulty kernels of Sections 15.4 and 15.6 then produce 24 instead of 32, and 31 instead of 63.
15.1.2 Definitions
Definition 15.1 Dot product. The dot product of 2 vectors \(a\) and \(b\) of \(n\) elements is
\[ a \cdot b = \sum_{i \in [0, n)} a_i\, b_i . \]
Example. For the vectors above, \(a \cdot b = 2 + 6 + 3 + \cdots + 4 = 63\).
| Symbol | Meaning | In the example |
|---|---|---|
| \(n\) | number of elements in each vector | 16 |
| \(i\) | position, from 0 to \(n - 1\) | 0 to 15 |
| \(a_i, b_i\) | elements of \(a\) and \(b\) at position \(i\) | \(a_1 = 2\), \(b_1 = 3\) |
| \(a_i\, b_i\) | product at position \(i\) | \(a_1 b_1 = 6\) |
| \(\sum_{i \in [0, n)}\) | sum over all positions \(i\) from 0 to \(n - 1\) | \(2 + 6 + \cdots + 4\) |
| \(a \cdot b\) | the dot product | 63 |
The dot product consists of two parts. The first part computes the products, which we call \(p_i = a_i b_i\), so that \(p_0 = 2\) and \(p_1 = 6\) in our example. The products form a map in the sense of Definition 14.2, since each of them depends only on the elements at position \(i\). The second part, the sum, then combines all \(n\) products into 1 number. A computation of this second kind has a name of its own.
Definition 15.2 Reduction. A reduction combines the \(n\) elements of an array into 1 value with a binary operator \(\oplus\), as \(p_0 \oplus p_1 \oplus \cdots \oplus p_{n-1}\). The identity of the operator is the value \(e\) with \(e \oplus v = v\) for every \(v\).
Example. The sum is a reduction with \(\oplus = +\) and identity 0. The maximum is a reduction with \(\oplus = \max\) and identity \(-\infty\).
The symbol \(\oplus\) stands for any operator that takes 2 values and returns 1 value. For the dot product, \(\oplus\) is ordinary addition, so the reduction is \(p_0 + p_1 + \cdots + p_{15} = 2 + 6 + \cdots + 4 = 63\). The identity is the value that changes nothing when it is combined with another value. For addition, the identity is 0, since \(0 + 6 = 6\). We need the identity later, when a thread that has no value of its own must still contribute something to a reduction.
Exercises
15.1 Compute the dot product of \((1, 0, 2, 3)\) and \((4, 5, 1, 2)\).
15.2 What are the operator and the identity of a reduction that counts the elements of an array
that are larger than 10?
15.3 In the worked example, which position contributes the largest product, and how much does it
contribute?
15.2 The sequential algorithm
15.2.1 The loop and its chain
On a CPU, Definition 15.1 becomes a single loop that keeps a running sum \(\mathsf{sum}\) and adds 1 product to it in each iteration.
Dot(\(a, b, n\))
- \(\mathsf{sum} = 0\)
- for \(i \in [0, n)\) {
- \(\mathsf{sum} = \mathsf{sum} + a_i \cdot b_i\) // 2 reads, 2 FLOP
- }
- return \(\mathsf{sum}\)
Line 3 executes \(n\) times. Each time, it reads 2 floats, which is 8 bytes, and performs 2 FLOP, 1 multiplication and 1 addition. Our example therefore performs 32 FLOP on 128 bytes. The vectors that we measure at the end of the chapter have \(n = 2^{24}\) elements, and for them the loop performs 33.6 million FLOP on 134.2 MB.
Recall that in the loop of SAXPY in Chapter 14, the iterations shared nothing. This loop is different. Iteration \(i\) reads \(\mathsf{sum}\), which iteration \(i - 1\) wrote, so it cannot start before iteration \(i - 1\) has finished. In our example, the running sum takes the values 2, 8, 11, 15, 20, 21, 29, 32, 35, 37, 41, 47, 48, 57, 59 and 63, and each of these values is obtained from the one before it, as shown in Figure 15.2. For example, the value 11 after iteration 2 is \(8 + 3\), and it could not be computed before the 8 was known. The 16 multiplications are independent of each other, but the 16 additions form a chain of 16 steps. As long as the additions are performed in this order, no number of threads can shorten the chain.
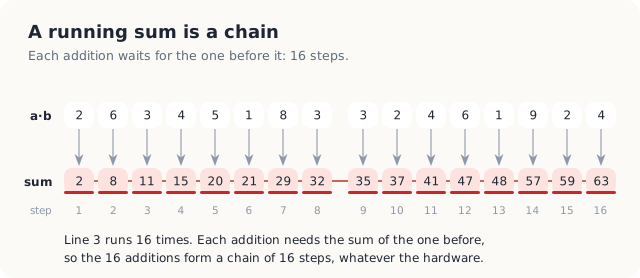
15.2.2 Regrouping the additions
Note, however, that the order of the chain is a choice that the loop makes, not a property of the sum. The sum \(2 + 6 + 3 + 4\) can also be computed as \((2 + 6) + (3 + 4) = 8 + 7 = 15\), and in this form the 2 additions inside the parentheses do not depend on each other. Addition has 2 properties that allow this and any other order.
Definition 15.3 Associative and commutative operators. An operator \(\oplus\) is associative if \((u \oplus v) \oplus w = u \oplus (v \oplus w)\) for all values, so that the parentheses of a long expression may be placed anywhere. It is commutative if \(u \oplus v = v \oplus u\), so that the operands may be reordered.
Example. Integer addition is both: \((2 + 6) + 3 = 2 + (6 + 3) = 11\) and \(2 + 6 = 6 + 2\). Subtraction is neither: \((2 - 6) - 3 = -7\), but \(2 - (6 - 3) = -1\).
Associativity lets us add the 16 products in pairs, then add the sums of the pairs in pairs, and continue in this way until 1 value remains, as shown in Figure 15.3. The first step adds 8 independent pairs, from \(2 + 6 = 8\) and \(3 + 4 = 7\) to \(2 + 4 = 6\). The second step adds 4 pairs of these sums, the third step adds 2 pairs, and the fourth step adds \(32 + 31 = 63\). The tree performs \(8 + 4 + 2 + 1 = 15\) additions, which is as many as the chain needs after its first addition to 0. It performs them, however, in 4 steps instead of 16, because the additions within each step are independent of each other.
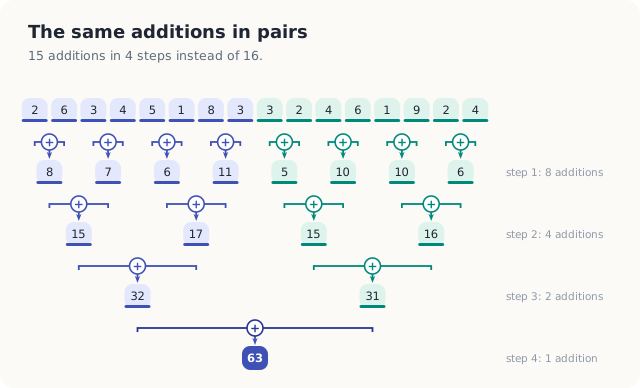
In general, a tree reduces \(n\) values with \(n - 1\) operations. Every step halves the number of values, so the number of steps is the number of times that \(n\) can be halved before 1 value remains. This number is \(\log_2 n\), rounded up when \(n\) is not a power of 2, which we write \(\lceil \log_2 n \rceil\). For our 16 products, \(\log_2 16 = 4\), since 16 halves to 8, 4, 2 and 1 in 4 steps. For \(n = 2^{24}\), the chain is 16,777,216 steps long, while the tree is only 24 steps deep.
Key observation Because addition is associative and commutative, the 16 products may be added in any grouping. Added in pairs, then in pairs of pairs, they need 4 steps instead of 16, and the additions within each step are independent, so a different thread can perform each of them.
Floating-point addition is associative only approximately, because every addition rounds its result. In Section 15.6.3, we show what this changes. Until then, we work with the exact integers of the example.
Exercises
15.4 Draw the tree for the 8 values \(4, 1, 3, 5, 2, 2, 6, 1\). How many additions and how many
steps does it take?
15.5 How many steps does a tree need for \(n = 1{,}000\) values? Explain the rounding up.
15.6 The maximum is associative and commutative. Run the tree of Figure 15.3 with \(\max\) in
place of \(+\).
15.3 A tree in shared memory
15.3.1 What the threads of a block need
Suppose that we give each addition of the tree to its own thread. In the second step, for example, some thread must add the sums 8 and 7, which were computed in the first step by 2 other threads. Each addition therefore combines 2 values that 2 different threads produced in the step before. The threads must exchange values, and a thread must know when the value that it needs is ready. Recall from Definition 14.4 that a block provides both: a memory that all of its threads can read and write, and a way for its threads to wait for one another.
Definition 15.4 Shared memory. Shared memory is a small memory on each SM, typically 48 KB to 228 KB, that the threads of 1 block can all read and write and no other thread can access. It responds within a few cycles. Each block receives its own copy of every shared array, which exists from the start of the block to its end and starts with undefined contents.
Example. Block 0 of our example holds its 8 products in a shared array cells of 8 floats;
block 1 has its own cells.
Definition 15.5 Barrier. A barrier is a point in a kernel that
no thread of a block may pass until every thread of the block has reached it. All writes to shared
memory made before the barrier are visible to every thread of the block after it. In CUDA C++, the
barrier is __syncthreads(), and in cuda-oxide, it is thread::sync_threads().
Example. After a barrier, thread 0 of block 0 can read the product that thread 4 stored before the barrier.
15.3.2 Which cells a thread adds
We now place the values of a block in a shared array, 1 value per thread, and call the elements of this array cells. In block 0 of our example, cell \(k\) holds the product \(p_k\), so the 8 cells hold 2, 6, 3, 4, 5, 1, 8 and 3. The tree of Figure 15.3 adds neighboring cells: cells 0 and 1, cells 2 and 3, cells 4 and 5, and cells 6 and 7. On a GPU, we prefer a different pairing, in which the 2 cells of a pair lie a fixed distance apart. We call this distance the stride. Recall that \(\mathsf{threadIdx{.}x}\) is the position of a thread in its block. In a step with a given \(\mathsf{stride}\), we let every thread whose \(\mathsf{threadIdx{.}x}\) is smaller than \(\mathsf{stride}\) add cell \(\mathsf{threadIdx{.}x} + \mathsf{stride}\) into its own cell, \(\mathsf{threadIdx{.}x}\). With 8 cells, the strides are 4, 2 and 1. In the first step, with \(\mathsf{stride} = 4\), threads 0 to 3 add cells 4 to 7 into cells 0 to 3. For example, thread 2 adds cell \(2 + 4 = 6\) into cell 2. In the second step, with \(\mathsf{stride} = 2\), threads 0 and 1 add cells 2 and 3 into cells 0 and 1. In the third step, with \(\mathsf{stride} = 1\), thread 0 adds cell 1 into cell 0.
| Symbol | Meaning | Thread 2, first step of block 0 |
|---|---|---|
| \(\mathsf{stride}\) | stride: distance between the 2 cells of a pair, and number of working threads | 4 |
| \(\mathsf{threadIdx{.}x}\) | index of the thread in its block, which works only if \(\mathsf{threadIdx{.}x} < \mathsf{stride}\) | 2 |
| \(\mathsf{threadIdx{.}x} + \mathsf{stride}\) | cell that the thread reads and adds into its own cell | 6 |
The stride pairing adds \(p_0 + p_4\) where Figure 15.3 added \(p_0 + p_1\), so it relies on commutativity as well as on associativity. In return, the threads that work in each step are always the lowest \(\mathsf{stride}\) threads, 0 to \(\mathsf{stride} - 1\), and they read the neighboring cells \(\mathsf{stride}\) to \(2\,\mathsf{stride} - 1\). This has 2 advantages in a block of 256 threads. In the first steps, whole warps are busy and whole warps are idle, instead of half the threads of every warp being idle, and the cells that a warp reads at once are neighbors in memory.
In Figure 15.4, we run this pairing in block 0 of the example. The 8 cells start with the products 2, 6, 3, 4, 5, 1, 8 and 3. With \(\mathsf{stride} = 4\), threads 0 to 3 compute \(2 + 5 = 7\), \(6 + 1 = 7\), \(3 + 8 = 11\) and \(4 + 3 = 7\). With \(\mathsf{stride} = 2\), threads 0 and 1 compute \(7 + 11 = 18\) and \(7 + 7 = 14\). With \(\mathsf{stride} = 1\), thread 0 computes \(18 + 14 = 32\). In the same way, block 1 computes 4, 11, 6 and 10 in the first step, 10 and 21 in the second, and 31 in the third.
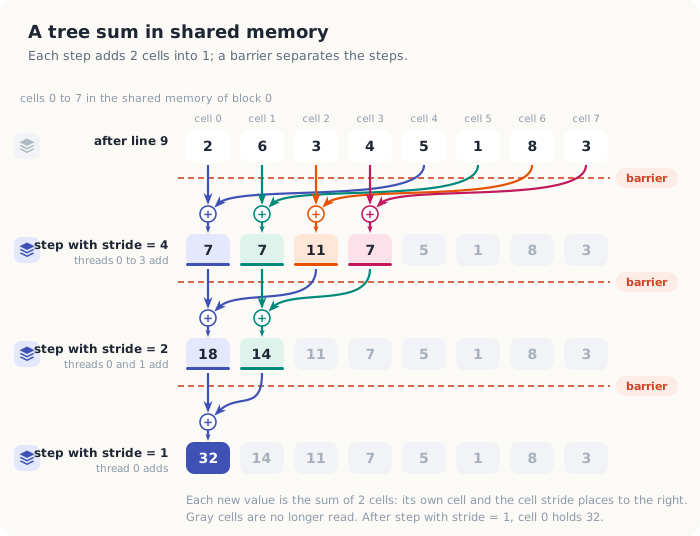
15.3.3 The algorithm
In our example, each block has 8 threads, and each thread holds exactly 1 product. A real block,
however, has \(\mathsf{blockDim{.}x} = 256\) threads, and a real vector has millions of elements, many more than the
threads of the grid. Each thread therefore begins with the grid-stride loop of Chapter 14. It
multiplies the elements \(\mathsf{index}, \mathsf{index} + \mathsf{gridSize}, \mathsf{index} + 2\,\mathsf{gridSize}, \ldots\) of the 2 vectors and adds the products in a
register, where \(\mathsf{index}\) starts at the thread’s global index and \(\mathsf{gridSize}\) is the number of threads in the grid. The
products are never stored in memory. The tree then combines the \(\mathsf{blockDim{.}x}\) register sums of the block,
and thread 0 writes the block’s sum to a partial sum array, which holds one element per block.
Every thread executes the following procedure, in which cells is a shared array of \(\mathsf{blockDim{.}x}\)
floats and \(\mathsf{mySum}\) is the thread’s register sum.
Dot-Block(\(a, b, \mathsf{partial}, n\))
- \(\mathsf{index} = \mathsf{blockIdx{.}x} \times \mathsf{blockDim{.}x} + \mathsf{threadIdx{.}x}\) // first element
- \(\mathsf{gridSize} = \mathsf{gridDim{.}x} \times \mathsf{blockDim{.}x}\) // threads in the grid
- \(\mathsf{mySum} = 0\)
- while \(\mathsf{index} \lt n\) { // the grid-stride loop of Chapter 14
- \(\mathsf{mySum} = \mathsf{mySum} + a_{\mathsf{index}} \times b_{\mathsf{index}}\)
- \(\mathsf{index} = \mathsf{index} + \mathsf{gridSize}\)
- }
- \(\mathsf{cells}[\mathsf{threadIdx{.}x}] = \mathsf{mySum}\)
- Barrier() // every cell holds its value
- for \(\mathsf{stride} = \mathsf{blockDim{.}x}/2, \mathsf{blockDim{.}x}/4, \ldots, 1\) {
- if \(\mathsf{threadIdx{.}x} \lt \mathsf{stride}\) {
- \(\mathsf{cells}[\mathsf{threadIdx{.}x}] = \mathsf{cells}[\mathsf{threadIdx{.}x}] + \mathsf{cells}[\mathsf{threadIdx{.}x} + \mathsf{stride}]\)
- }
- Barrier() // this step is complete
- }
- if \(\mathsf{threadIdx{.}x} = 0\) {
- \(\mathsf{partial}[\mathsf{blockIdx{.}x}] = \mathsf{cells}[0]\)
- }
| Symbol | Meaning | Thread 2 of block 0, example |
|---|---|---|
| \(\mathsf{blockDim{.}x}\) | number of threads in a block | 8 (256 in the measured program) |
| \(\mathsf{threadIdx{.}x}\) | index of the thread in its block (threadIdx.x) | 2 |
| \(\mathsf{index}\) | element the thread processes next; starts at its global index | 2 |
| \(\mathsf{gridSize}\) | number of threads in the grid, and the distance from one of the thread’s elements to the next | \(2 \cdot 8 = 16\) |
| \(\mathsf{mySum}\) | the thread’s register sum | \(a_2 b_2 = 3\) |
| \(\mathsf{stride}\) | stride of the current step of the tree | 4, 2, 1 |
Lines 1 to 7 compute the thread’s register sum. On the example, launched with 2 blocks of 8
threads, \(\mathsf{gridSize} = 16 = n\), so the loop runs once, and \(\mathsf{mySum}\) is the thread’s single product. For
instance, thread 2 of block 0 sets \(\mathsf{mySum} = a_2 b_2 = 3 \cdot 1 = 3\) and then leaves the loop, since
\(2 + 16 = 18 \ge 16\). Line 8 stores the sum in the thread’s own cell, and the barrier of line 9
waits until all \(\mathsf{blockDim{.}x}\) cells are filled. Lines 10 to 15 are the tree of Figure 15.4, with a barrier
after every step, and lines 16 to 18 write the block’s sum. On the example, block 0 writes 32 into
partial[0], and block 1 writes 31 into partial[1]. In Section 15.6, we add the partial sums.
Note that lines 9 and 14 lie outside every if. The barrier of line 14 is therefore executed by
all \(\mathsf{blockDim{.}x}\) threads in every step, including the threads with \(\mathsf{threadIdx{.}x} \ge \mathsf{stride}\), which have nothing to
add.
15.3.4 Counting
Let us count the work of the tree. A block of \(\mathsf{blockDim{.}x}\) threads performs \(\mathsf{blockDim{.}x} - 1\) additions in its tree, in \(\log_2 \mathsf{blockDim{.}x}\) steps, with \(\log_2 \mathsf{blockDim{.}x} + 1\) barriers: 1 barrier in line 9 and 1 barrier after each step. For our block of 8 threads, this is 7 additions in 3 steps, with 4 barriers. For \(\mathsf{blockDim{.}x} = 256\), it is 255 additions in 8 steps, with 9 barriers. The number of working threads halves in every step, from 128 through 64, 32, 16, 8, 4 and 2 to 1. In the last 5 steps, at most 16 threads work, all of them in warp 0, and the other 7 warps wait at the barrier.
The cost of the tree is paid once per block, not once per element. With a grid of 1,024 blocks of 256 threads, \(\mathsf{gridSize} = 262{,}144\), and each thread adds \(2^{24} / 262{,}144 = 64\) products in lines 4 to 7 before the tree begins. The kernel reads every element of \(a\) and \(b\) exactly once, which is 8 bytes per element, and it performs 2 FLOP per element. Its arithmetic intensity is therefore \(2 / 8 = 0.25\) FLOP/B, far below the ridge point of any GPU (Section 14.6). Like SAXPY, the dot product is memory-bound.
Exercises
15.7 Run Figure 15.4 for block 1, whose cells start with 3, 2, 4, 6, 1, 9, 2, 4. Which threads
work in each step, and what does each compute?
15.8 For \(\mathsf{blockDim{.}x} = 512\), how many steps, additions and barriers does the tree take?
15.9 With 1,024 blocks of 256 threads and \(n = 10^6\), how many products does thread 0 add in
lines 4 to 7, and how many does thread 262,143 add?
15.4 Correctness
The threads of a block run at different speeds, and they read cells that other threads write. As a result, 2 things can go wrong. A thread can read a cell before the thread responsible for it has written the value of the current step, and a thread can overwrite a cell that another thread has not yet read. The 2 barriers prevent both errors. In this section, we remove the barrier of line 14 and follow the effect on the example, and we then prove that the kernel with both barriers is correct.
15.4.1 Without the barrier between the steps
Suppose that line 14 is deleted, and that in block 0, thread 2 runs late. Thread 0 finishes its addition for \(\mathsf{stride} = 4\), which is \(2 + 5 = 7\), and moves on to \(\mathsf{stride} = 2\), where it needs cell 2. Thread 2 should have stored \(3 + 8 = 11\) there, but it has not yet done so, and cell 2 still holds the product 3, as shown in Figure 15.5. Thread 0 therefore computes \(7 + 3 = 10\) instead of 18, and in the last step, it computes \(10 + 14 = 24\) instead of 32.
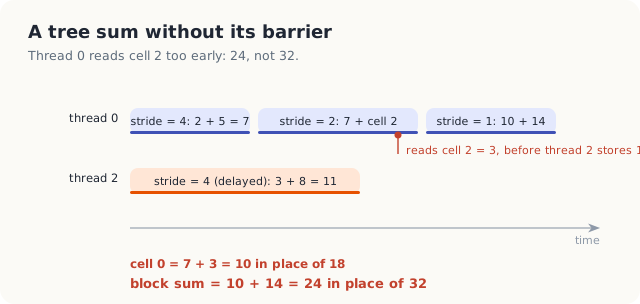
We deleted the barrier from both programs and ran them. The C++ build also contained the faulty plain addition of Section 15.6.2, which affects only the last column of the output. The C++ program printed the following lines.
exact tests map+red tree shuffle atomic
worked example, 16 pairs 63 26 63 63 expected 63
0s and 1s, 16777216 pairs 2796203 760424 2796203 338598 expected 2796203
The column tree holds the results of the kernel without the barrier, 26 instead of 63 for the
worked example. The Rust program returned 36 for the worked example and 778,180 for the second
test. On \(2^{24}\) floats in \([0, 1)\), the tree returned 920,497.0 (C++) and 1,159,452.9 (Rust)
instead of 4,195,680.0, and a second run gave different wrong values, 756,503 and 778,042, for the
second test. The program runs the example on the real block of 256 threads, so the precise wrong
value differs from the 24 of Figure 15.5. Without the barrier, nothing orders the store of 1 step
before the loads of the next step. The warps of a block reach each step at different times, and
the compiler may also load a cell earlier than the program text suggests, because it assumes that
no other thread changes the cell in between. Every wrong value has the same cause as the wrong
value in Figure 15.5.
The barrier of line 9 protects the first step in the same way. Without it, thread 0 could add cell 4 before thread 4 has stored its sum there, and it would then add whatever the undefined shared memory held.
15.4.2 A proof that the tree is correct
With both barriers in place, the tree computes the block’s sum. To prove this, we follow which products each cell holds at the start of every step, as shown in Figure 15.6. At the start of the step with stride \(\mathsf{stride} = 4\), cell 0 holds \(p_0\). At the start of the step with \(\mathsf{stride} = 2\), it holds \(p_0 + p_4\), and at the start of the step with \(\mathsf{stride} = 1\), it holds \(p_0 + p_2 + p_4 + p_6\). After the last step, it holds all 8 products. We can describe this pattern with remainders. At the start of the step with stride \(\mathsf{stride}\), cell \(k\) holds the products whose index \(j\) leaves the remainder \(k\) when divided by \(2\,\mathsf{stride}\). For example, at the start of the step with \(\mathsf{stride} = 2\), we have \(2\,\mathsf{stride} = 4\), and the indices 0 and 4 are exactly the indices below 8 that leave the remainder 0 when divided by 4, so cell 0 holds \(p_0 + p_4 = 2 + 5 = 7\).
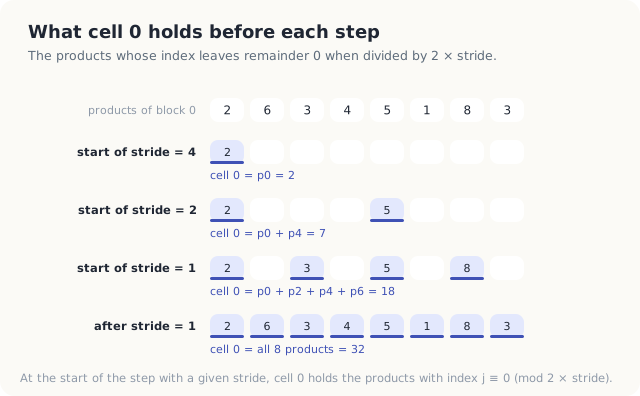
We write \(j \equiv k \pmod{2\,\mathsf{stride}}\), read “\(j\) is congruent to \(k\) modulo \(2\,\mathsf{stride}\)”, when \(j\) and \(k\) leave the same remainder when divided by \(2\,\mathsf{stride}\). For example, \(6 \equiv 2 \pmod{4}\), since both 6 and 2 leave the remainder 2 when divided by 4. The theorem and its proof use this notation.
Theorem 15.1 Let \(\mathsf{blockDim{.}x}\) be a power of 2 and let \(v_j\) be the value that thread \(j\) of a block stores in line 8 of Dot-Block. When the loop of lines 10 to 15 finishes, \(\mathsf{cells}[0] = \sum_{j \in [0, \mathsf{blockDim{.}x})} v_j\).
Proof. We show that the loop maintains the following invariant: at the start of the iteration with stride \(\mathsf{stride}\), for every \(k \in [0, 2\,\mathsf{stride})\),
\[ \mathsf{cells}[k] = \sum_{j \in [0, B),\ j \equiv k \ (\mathrm{mod}\ 2s)} v_j . \]
| Symbol | Meaning | Block 0 of the example, \(\mathsf{stride} = 2\), \(k = 1\) |
|---|---|---|
| \(\mathsf{blockDim{.}x}\) | number of threads, and cells, in the block | 8 |
| \(v_j\) | value stored by thread \(j\) in line 8 | \(v_1 = 6\), \(v_5 = 1\) |
| \(\mathsf{stride}\) | stride of the current iteration | 2 |
| \(k\) | a cell that is still read, \(k < 2\,\mathsf{stride}\) | 1 |
| \(j \equiv k \pmod{2\,\mathsf{stride}}\) | \(j\) leaves the remainder \(k\) when divided by \(2\,\mathsf{stride}\) | \(j = 1, 5\) |
| \(\mathsf{cells}[k]\) | content of cell \(k\) at the start of the iteration | \(6 + 1 = 7\) |
In words, at the start of each iteration, the first \(2\,\mathsf{stride}\) cells together hold all \(\mathsf{blockDim{.}x}\) values, and cell \(k\) holds those values whose index leaves the remainder \(k\). In Figure 15.4, at the start of the step with \(\mathsf{stride} = 2\), cell 1 indeed holds \(6 + 1 = 7\), the sum of \(v_1\) and \(v_5\).
Initialization. The first iteration has \(\mathsf{stride} = \mathsf{blockDim{.}x}/2\), so \(2\,\mathsf{stride} = \mathsf{blockDim{.}x}\), and the only \(j \in [0, \mathsf{blockDim{.}x})\) with \(j \equiv k \pmod{\mathsf{blockDim{.}x}}\) is \(k\) itself. The sum in the invariant therefore consists of the single value \(v_k\). Line 8 stored \(v_k\) in \(\mathsf{cells}[k]\), and the barrier of line 9 makes every one of these stores complete before any thread reads a cell in line 12. The invariant therefore holds.
Maintenance. Assume that the invariant holds at the start of the iteration with stride \(\mathsf{stride}\). In line 12, each thread \(\mathsf{threadIdx{.}x} < \mathsf{stride}\) reads cells \(\mathsf{threadIdx{.}x}\) and \(\mathsf{threadIdx{.}x} + \mathsf{stride}\) and writes cell \(\mathsf{threadIdx{.}x}\). The cells written, \([0, \mathsf{stride})\), and the cells that are only read, \([\mathsf{stride}, 2\,\mathsf{stride})\), do not overlap, and each cell of \([0, \mathsf{stride})\) is written by exactly 1 thread. Hence, no read in this iteration sees a write of this iteration, except the thread’s own. After line 12, for \(\mathsf{threadIdx{.}x} < \mathsf{stride}\), cell \(\mathsf{threadIdx{.}x}\) holds the sum over \(j \equiv \mathsf{threadIdx{.}x} \pmod{2\,\mathsf{stride}}\) plus the sum over \(j \equiv \mathsf{threadIdx{.}x} + \mathsf{stride} \pmod{2\,\mathsf{stride}}\). An index \(j\) belongs to one of these 2 groups exactly when it leaves the remainder \(\mathsf{threadIdx{.}x}\) when divided by \(\mathsf{stride}\), so the 2 sums together are the sum over \(j \equiv \mathsf{threadIdx{.}x} \pmod{\mathsf{stride}}\). For example, with \(\mathsf{stride} = 2\) and \(\mathsf{threadIdx{.}x} = 1\), cell 1 holds \(v_1 + v_5\) and cell 3 holds \(v_3 + v_7\), and their sum is the sum over the odd \(j\), that is, over \(j \equiv 1 \pmod{2}\). The barrier of line 14 makes these writes complete before any thread starts the next iteration. That iteration has the stride \(\mathsf{stride}/2\), and \(2 \cdot (\mathsf{stride}/2) = \mathsf{stride}\), so the invariant holds for the next iteration.
Termination. After the iteration with \(\mathsf{stride} = 1\), the maintenance step shows that cell 0 holds the sum over \(j \equiv 0 \pmod{1}\). Every integer leaves the remainder 0 when divided by 1, so this is the sum over all \(j \in [0, \mathsf{blockDim{.}x})\).
The proof uses each barrier once, the barrier of line 9 in the initialization and the barrier of line 14 in the maintenance. Removing either barrier breaks exactly the step of the proof that uses it, and in Section 15.4.1, we saw the wrong value that follows.
Rule Every thread of a block must reach every barrier. Never place
a barrier inside a branch that only some threads of the block take, such as the if of line 11.
A barrier inside if t < s would be reached by \(\mathsf{stride}\) threads but awaited by all \(\mathsf{blockDim{.}x}\) threads.
The behavior of such a kernel is undefined, and in practice, it hangs or returns wrong values.
15.4.3 Shared memory in Rust
In cuda-oxide, a shared array is a static mut of type SharedArray<f32, 256> declared inside
the kernel. Rust requires an unsafe block for every access to a static mut, because the
compiler cannot prove that 2 threads do not access it at the same time. If we write the store of
line 8 without the block, the build stops with the following error.
$ cargo oxide build
error[E0133]: use of mutable static is unsafe and requires unsafe block
--> src/main.rs:117:9
|
117 | CELLS[t] = products(a, b);
| ^^^^^ use of mutable static
|
= note: mutable statics can be mutated by multiple threads: aliasing violations or data races will cause undefined behavior
The program’s // SAFETY: comments state the two facts that the proof of Theorem 15.1 uses. The
first is that each thread writes only its own cell before the barrier of line 9. The second is that
in each step, each working thread alone writes its own cell and reads cell
\(\mathsf{threadIdx{.}x} + \mathsf{stride}\), which no thread writes in that step. The compiler accepts the program without the barrier as well, because the unsafe
blocks are still there, and only the argument in their comments is then false.
Exercises
15.10 Without the barrier of line 14, suppose thread 1 of block 1 runs late in step \(\mathsf{stride} = 4\).
Which cell does thread 0 read too early in step \(\mathsf{stride} = 2\), and what block sum results?
15.11 In the proof of Theorem 15.1, where is it used that \(\mathsf{blockDim{.}x}\) is a power of 2? What goes wrong
for \(\mathsf{blockDim{.}x} = 6\)?
15.12 Explain why moving the barrier of line 14 inside the if of line 11 can make the kernel
hang.
15.5 Warp shuffles
15.5.1 Exchanging registers within a warp
Recall from Section 15.3.4 that the last 5 steps of the tree in a block of 256 threads run with 16, 8, 4, 2 and 1 working threads, all of them in warp 0. Each of these steps nevertheless ends with a barrier for the whole block, at which 7 idle warps wait. The threads of 1 warp, however, can exchange values without shared memory and without a barrier.
Definition 15.6 Warp shuffle. A warp shuffle is an instruction with which every lane of a warp (Definition 14.6) reads a register of another lane of the same warp. In the form shuffle down with offset \(\mathsf{distance}\), lane \(k\) receives the value that lane \(k + \mathsf{distance}\) holds; a lane with \(k + \mathsf{distance} \ge 32\) receives its own value. All lanes named in the instruction’s mask execute it together, so the values are exchanged without a barrier.
Example. With offset 4, lane 0 receives the value of lane 4, and lane 3 the value of lane 7.
A shuffle closely resembles a step of the tree. In a tree step, each working thread adds cell \(\mathsf{threadIdx{.}x} + \mathsf{stride}\) into its own cell. A shuffle-down by \(\mathsf{distance}\), followed by an addition, lets each lane add the register of the lane \(\mathsf{distance}\) places to its right into its own register, which is the same step with registers in place of cells and \(\mathsf{distance}\) in place of \(\mathsf{stride}\). A sequence of shuffles with offsets 16, 8, 4, 2 and 1, each followed by an addition, is therefore the tree of Section 15.3 inside 1 warp. In Figure 15.7, we draw it on 8 lanes with the products of block 0, so that only the last 3 of the 5 steps, with offsets 4, 2 and 1, are needed. The registers take the same values as the cells of Figure 15.4: 7, 7, 11 and 7 after offset 4, then 18 and 14, and finally 32.
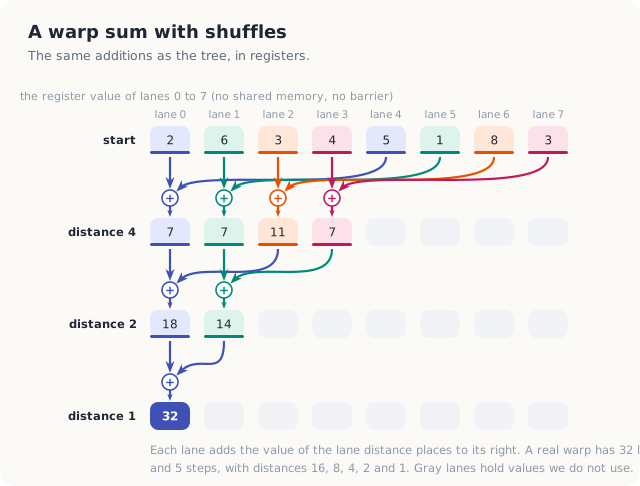
Warp-Sum(\(\mathsf{value}\))
- for \(\mathsf{distance} = 16, 8, 4, 2, 1\) {
- \(\mathsf{value} = \mathsf{value} + \) Shuffle-Down\((\mathsf{value}, \mathsf{distance})\) // lane k adds lane k + distance
- }
- return \(\mathsf{value}\) // the sum of the warp, in lane 0
15.5.2 A block sum with 1 barrier
A shuffle reaches only the lanes of its own warp, so Warp-Sum alone cannot add the values of a whole block. A block of 256 threads consists of 8 warps. Each warp first reduces its 32 values with Warp-Sum, and lane 0 of each warp stores the warp’s sum in 1 of 8 shared slots, called \(\mathsf{warps}[0]\) to \(\mathsf{warps}[7]\). A single barrier makes the 8 sums visible to all threads, and warp 0 then reduces them with a second Warp-Sum, as shown in Figure 15.8. In the procedure below, \(\mathsf{lane}\) is the position of the thread within its warp and \(\mathsf{warpIndex}\) is the number of its warp. For example, thread 70 of the block has \(\mathsf{lane} = 70 \bmod 32 = 6\) and \(w = \lfloor 70 / 32 \rfloor = 2\), where \(\lfloor \cdot \rfloor\) rounds down.
Block-Sum(\(\mathsf{mySum}\))
- \(\mathsf{lane} = \mathsf{threadIdx{.}x} \bmod 32\) // position in the warp
- \(\mathsf{warpIndex} = \lfloor \mathsf{threadIdx{.}x} / 32 \rfloor\) // warp number in the block
- \(\mathsf{warpTotal} = \) Warp-Sum\((\mathsf{mySum})\)
- if \(\mathsf{lane} = 0\) {
- \(\mathsf{warpSums}[\mathsf{warpIndex}] = \mathsf{warpTotal}\)
- }
- Barrier()
- if \(\mathsf{warpIndex} \ne 0\) {
- return 0 // only warp 0 finishes the sum
- }
- \(\mathsf{value} = \mathsf{warpSums}[\mathsf{lane}]\) if \(\mathsf{lane} \lt 8\), else 0
- return Warp-Sum\((\mathsf{value})\) // the block sum, in thread 0
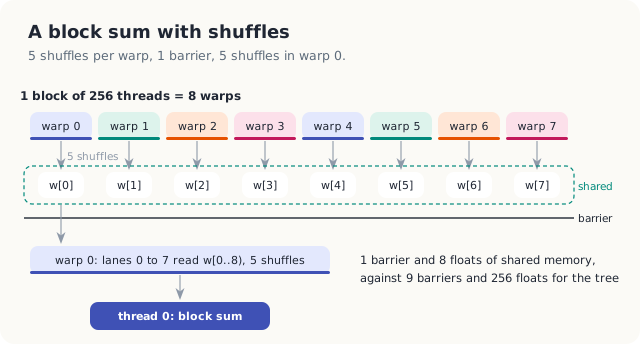
In line 11, lanes 8 to 31 of warp 0 contribute 0, the identity of addition, so the second Warp-Sum adds exactly the 8 warp sums. Only warp 0 calls Warp-Sum the second time, and all 32 of its lanes do so, as the shuffle requires. Compared with the tree of Section 15.3, Block-Sum uses 1 barrier instead of 9, and 8 floats of shared memory instead of 256. A fused kernel with shuffles computes the register sum \(\mathsf{mySum}\) with lines 1 to 7 of Dot-Block, and it replaces lines 8 to 15 by \(\mathsf{mySum} = \) Block-Sum\((\mathsf{mySum})\).
Exercises
15.13 In Warp-Sum on 32 lanes holding the values 0 to 31, what does lane
0 hold after each of the 5 steps?
15.14 Why may lines 11 and 12 of Block-Sum not read warpSums before the
barrier of line 7?
15.6 Combining the block results
15.6.1 A second launch
After Dot-Block has run on the example, partial[0] = 32 and
partial[1] = 31. The 2 numbers were computed by different blocks, and the threads of different
blocks can share neither a barrier nor shared memory. In fact, the blocks of a large grid do not
even run at the same time. The end of a kernel, however, is a point that every block has passed. A
second kernel launched on the same stream starts only after the first kernel has finished, so it
sees every partial sum. We therefore launch a sum kernel with 1 block, which adds the partial sums
with the same grid-stride loop and block sum. On the example, it computes \(32 + 31 = 63\), as shown
on the left of Figure 15.9.
15.6.2 Atomic additions
The second launch can be avoided if every block adds its sum directly into the result. This requires an addition that no other thread can interrupt.
Definition 15.7 Atomic operation. An atomic operation is a
read-modify-write of 1 memory location that executes as 1 indivisible step. No other thread can
access the location between the read and the write. atomicAdd(p, v) in C++ and
fetch_add(v, ...) on a DeviceAtomicF32 in Rust add \(\mathsf{mySum}\) to the value at \(p\) atomically.
Example. If block 1 finishes first, it atomically changes the result from 0 to 31, and block 0 then changes it from 31 to 63.
Figure 15.9 compares the two methods. With the second launch, the 2 partial sums are added in an order that the program fixes. With atomic additions, they are added in the order in which the blocks finish, and this order changes from run to run.
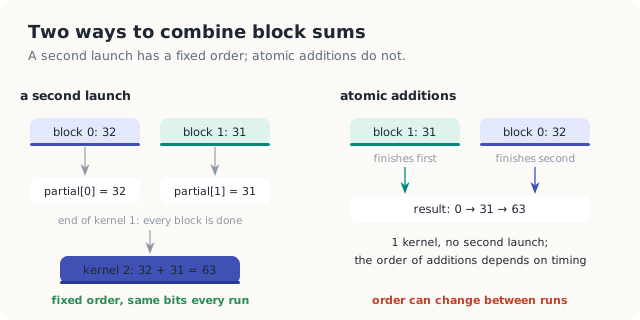
The addition must be atomic. With an ordinary *result += total, a block reads the result, adds
its sum and writes the result back, in 3 separate steps. Suppose that block 0 and block 1 both read
0 before either of them writes. Block 0 then writes \(0 + 32 = 32\), block 1 writes \(0 + 31 =
31\), and the later write wins, so the result is 31 instead of 63, as shown in Figure 15.10.
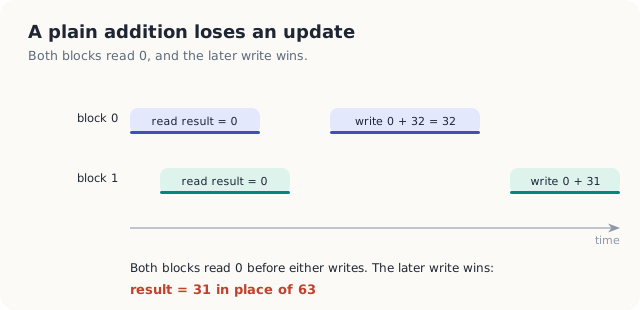
We replaced atomicAdd(result, total) by *result += total in the C++ program. The 0-and-1 test
returned 338,598 instead of 2,796,203, and the dot product of the random floats returned 100
different values in 100 runs, from 479,931.1 to 528,424.6, which is about 12% of the correct
4,195,680. The worked example was launched with 1,024 blocks, of which only block 0 has a nonzero
sum. It returned the correct 63 in 1 run and 0 in another run, because a block with the sum 0 read
the result before block 0 wrote 63, and it wrote its 0 afterward.
15.6.3 The order of float additions
The 2 correct methods add the same numbers in different orders. For integers, the order does not matter. For floats, it does, because every addition rounds its result to the nearest float.
A float has 24 significant bits. Every integer up to \(2^{24} = 16{,}777{,}216\) can therefore be represented as a float, but beyond \(2^{24}\), the floats are 2 apart, so only the even integers are floats. In Figure 15.11, we add 16,777,216, 1 and 1 in 2 orders. From left to right, the first addition gives \(16{,}777{,}216 + 1 = 16{,}777{,}217\), which is not a float and rounds back to 16,777,216, and the second \(+ 1\) is lost in the same way. With the small values first, \(1 + 1 = 2\), and \(16{,}777{,}216 + 2 = 16{,}777{,}218\) is exact.
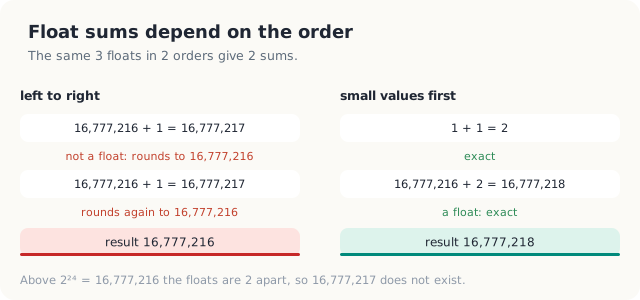
With a second launch, the order of every addition is fixed. We let each thread add its elements in the order of its loop, the shuffles combine fixed pairs of lanes, and the last block adds the partial sums in a fixed pattern. The result is therefore the same, bit for bit, in every run with the same grid. With atomic additions, the 1,024 block sums arrive in an order that depends on timing, and the last bits of the result can change from run to run. Both results are correct to the precision of a float.
The program uses this observation to verify itself exactly, in the same way as the paper on tiled matrix multiplication does with small integers. Its second test fills \(a\) with 1 at every position divisible by 3 and \(b\) with 1 at every position divisible by 2, and with 0 elsewhere. Every product, every partial sum and the total are then integers no larger than \(2^{24}\), and all of them are floats. No addition rounds, every order gives the same result, and every method must return exactly 2,796,203, the number of positions below \(2^{24}\) that are divisible by 6.
Exercises
15.15 With 4 blocks whose sums are 10, 20, 30 and 40, list 2 orders of atomic additions and the
intermediate values of the result for each.
15.16 Why does the 0-and-1 test stay exact with \(n = 2^{24}\), but not necessarily with
\(n = 2^{25}\)?
15.17 In the faulty plain addition, what is the smallest wrong result the worked example can
produce, and what is the largest?
15.7 Implementation
15.7.1 The register sum
We implement the grid-stride loop of lines 1 to 7 as a device function, that is, a function that
runs on the GPU and is called from kernels rather than launched by the host. In C++, a device
function is marked __device__, and in Rust, it is marked #[device]. The following code computes
the register sum of 1 thread.
Listing 15.1 The register sum of 1 thread: lines 1 to 7 of Dot-Block.
mod kernels {
// ...
/// The sum of a[index] * b[index] over this thread's elements, a grid apart.
#[device]
fn products(a: &[f32], b: &[f32]) -> f32 {
let grid_size = (thread::gridDim_x() * BLOCK) as usize;
let mut index = thread::index_1d().get();
let mut sum = 0.0;
while index < a.len() {
sum += a[index] * b[index];
index += grid_size;
}
sum
}
// ...
}// The sum of a[index] * b[index] over this thread's elements, a grid apart.
__device__ float products(const float* a, const float* b, int n)
{
int gridSize = gridDim.x * blockDim.x;
float sum = 0.0f;
for (int index = blockIdx.x * blockDim.x + threadIdx.x; index < n; index += gridSize) {
sum += a[index] * b[index];
}
return sum;
}
The loop reads a[i] and b[i] and adds their product to sum without storing the product. In
Rust, the slices are indexed with an ordinary usize. The loop condition i < a.len() lets the
compiler drop the bounds check on a, and the check on b costs 1 comparison per 8 bytes loaded,
which does not change the speed of a memory-bound loop. The Rust function computes \(\mathsf{gridSize}\) from the
constant BLOCK, which the launch contract of every kernel that calls the function fixes at 256.
15.7.2 The tree kernel
Listing 15.2 shows the complete fused kernel with the tree in shared memory, which is Dot-Block in both languages.
Listing 15.2 The fused kernel with the tree in shared memory: Dot-Block.
mod kernels {
// ...
/// Fused: products and a tree in shared memory, 1 partial sum per block.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn dot_tree(a: &[f32], b: &[f32], mut partial: DisjointSlice<f32>) {
static mut CELLS: SharedArray<f32, 256> = SharedArray::UNINIT;
let thread_idx = thread::threadIdx_x() as usize;
// SAFETY: each thread writes only its own cell, before the barrier.
unsafe { CELLS[thread_idx] = products(a, b) };
thread::sync_threads();
let mut step: usize = 0;
#[unroll]
while step < 8 {
let stride: usize = 128 >> step;
if thread_idx < stride {
// SAFETY: in this step, this thread alone writes its cell and reads cell
// thread_idx + stride, which no thread writes in this step.
unsafe { CELLS[thread_idx] += CELLS[thread_idx + stride] };
}
thread::sync_threads();
step += 1;
}
if thread_idx == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = CELLS[0] };
}
}
// ...
}// Fused: products and a tree in shared memory, 1 partial sum per block.
__global__ void dotTree(const float* a, const float* b, float* partial, int n)
{
__shared__ float cells[BLOCK];
cells[threadIdx.x] = products(a, b, n);
__syncthreads();
for (int stride = BLOCK / 2; stride > 0; stride /= 2) {
if (threadIdx.x < stride) {
cells[threadIdx.x] += cells[threadIdx.x + stride];
}
__syncthreads();
}
if (threadIdx.x == 0) {
partial[blockIdx.x] = cells[0];
}
}
The call products(a, b) performs lines 1 to 7, the store into cells[t] or CELLS[t] is
line 8, and the first barrier is line 9. The loop performs lines 10 to 15, with the barrier of
line 14 after the if, and the final if t == 0 performs lines 16 to 18.
The two languages differ in 3 places. First, C++ declares the shared array with __shared__, while
Rust declares a static mut SharedArray<f32, 256>. The length of the Rust array is part of its
type, and this is why the Rust kernel’s launch contract fixes the block at exactly 256 threads.
Every access to the array is in an unsafe block with its argument (Section 15.4.3). Second, the
C++ loop halves stride directly, whereas the Rust loop counts step from 0 to 7 and computes
stride = 128 >> step, which is 128, 64, 32 and so on down to 1. The reason is that cuda-oxide unrolls a
loop marked #[unroll] only when the loop has an integer counter that is compared with a constant
and increased by a constant. With s /= 2, the compiler reports that the loop was not unrolled.
Third, thread 0 writes partial[blockIdx.x], at an index that is not its own global index, so Rust
uses get_unchecked_mut, with the argument that only thread 0 of each block writes, and only at
its own block number.
15.7.3 The warp and block sums
Listing 15.3 shows Warp-Sum and Block-Sum as device functions.
Listing 15.3 Warp-Sum and Block-Sum.
mod kernels {
// ...
/// The sum of `value` over the 32 lanes of a warp, left in lane 0.
#[device]
fn warp_sum(mut value: f32) -> f32 {
let mut step: u32 = 0;
#[unroll]
while step < 5 {
value += warp::shuffle_down_f32(value, 16u32 >> step);
step += 1;
}
value
}
/// The sum of `value` over the 256 threads of a block, returned to thread 0.
#[device]
fn block_sum(value: f32) -> f32 {
static mut WARP_SUMS: SharedArray<f32, 8> = SharedArray::UNINIT;
let lane = warp::lane_id() as usize;
let warp_index = thread::threadIdx_x() as usize / 32;
let value = warp_sum(value);
if lane == 0 {
// SAFETY: lane 0 of each warp writes its own slot, before the barrier.
unsafe { WARP_SUMS[warp_index] = value };
}
thread::sync_threads();
// SAFETY: after the barrier the slots are only read.
let warp_total = if lane < 8 { unsafe { WARP_SUMS[lane] } } else { 0.0 };
if warp_index == 0 { warp_sum(warp_total) } else { 0.0 }
}
// ...
}// The sum of value over the 32 lanes of a warp, left in lane 0.
__device__ float warpSum(float value)
{
for (int distance = 16; distance > 0; distance /= 2) {
value += __shfl_down_sync(0xffffffff, value, distance);
}
return value;
}
// The sum of value over the 256 threads of a block, returned to thread 0.
__device__ float blockSum(float value)
{
__shared__ float warpSums[8];
int lane = threadIdx.x % 32;
int warpIndex = threadIdx.x / 32;
value = warpSum(value);
if (lane == 0) {
warpSums[warpIndex] = value;
}
__syncthreads();
float warpTotal = lane < 8 ? warpSums[lane] : 0.0f;
return warpIndex == 0 ? warpSum(warpTotal) : 0.0f;
}
The calls __shfl_down_sync(0xffffffff, v, offset) and warp::shuffle_down_f32(v, offset) are
the shuffle of Definition 15.6. The mask 0xffffffff has all 32 bits set and therefore names all
32 lanes, and the Rust function applies the same mask. In Rust, the offset is computed as
16u32 >> step, which gives 16, 8, 4, 2 and 1 for step from 0 to 4. The counter is declared
u32, and the shifted constant is written 16u32, because with both types left to inference, the
GPU backend of cuda-oxide stopped with an internal error about a shift of a 64-bit value by a
32-bit amount. The shared array WARP_SUMS is declared inside the device function, and every block
that calls block_sum still receives its own 8 slots.
15.7.4 Combining the block sums
Listing 15.4 shows the fused kernel that combines the block sums with 1 atomic addition per block.
Listing 15.4 The fused kernel with an atomic addition per block.
mod kernels {
// ...
/// Fused: products, warp shuffles, and 1 atomic addition per block.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn dot_atomic(a: &[f32], b: &[f32], result: &[DeviceAtomicF32]) {
let total = block_sum(products(a, b));
if thread::threadIdx_x() == 0 {
result[0].fetch_add(total, AtomicOrdering::Relaxed);
}
}
}// Fused: products, warp shuffles, and 1 atomic addition per block.
__global__ void dotAtomic(const float* a, const float* b, float* result, int n)
{
float total = blockSum(products(a, b, n));
if (threadIdx.x == 0) {
atomicAdd(result, total);
}
}
In Rust, the result is a slice of DeviceAtomicF32, received as a shared reference &[...]
rather than a mutable one. Like the atomic types of the Rust standard library, the atomic type
permits modification through a shared reference, because each modification is 1 indivisible
operation. The kernel therefore needs no unsafe. AtomicOrdering::Relaxed asks for atomicity and
nothing more, which suffices here, because the host reads the result only after the kernel has
finished. A device buffer of DeviceAtomicF32 cannot be copied with to_host_vec, so the Rust
program uses 2 small kernels, clear and publish. The first sets the result to 0 before the
launch, and the second copies it into an ordinary float afterward. In C++, the program sets the
result to 0 with cudaMemsetAsync.
The host prepares every launch once, and it runs the 4 designs with 1 closure in Rust and 1 function in C++. Listing 15.5 shows the launches. The map followed by a reduction needs 3 launches, each fused kernel with a second launch needs 2, and the atomic design needs 3 in Rust and 2 in C++.
Listing 15.5 The launches of the 4 designs.
fn main() -> Result<(), Error> {
// ...
let grid = LaunchConfig1D::new(GRID, BLOCK, 0);
let one = LaunchConfig1D::new(1, BLOCK, 0);
let map = LaunchConfig1D::new(N as u32 / BLOCK, BLOCK, 0);
let multiply = module.prepare_multiply(map)?;
let reduce = module.prepare_sum(grid)?;
let last = module.prepare_sum(one)?;
let tree = module.prepare_dot_tree(grid)?;
let shuffle = module.prepare_dot_shuffle(grid)?;
let clear = module.prepare_clear(one)?;
let atomic = module.prepare_dot_atomic(grid)?;
let publish = module.prepare_publish(one)?;
// Launches 1 dot product; the result ends in `buf.total`.
let run = |method: Method, buf: &mut Buffers| -> Result<(), Error> {
let (a, b, stream) = (&buf.a, &buf.b, &stream);
match method {
Method::MapReduce => {
module.multiply(stream, &multiply, a, b, &mut buf.products)?;
module.sum(stream, &reduce, &buf.products, &mut buf.partial)?;
module.sum(stream, &last, &buf.partial, &mut buf.total)?;
}
Method::Tree => {
module.dot_tree(stream, &tree, a, b, &mut buf.partial)?;
module.sum(stream, &last, &buf.partial, &mut buf.total)?;
}
Method::Shuffle => {
module.dot_shuffle(stream, &shuffle, a, b, &mut buf.partial)?;
module.sum(stream, &last, &buf.partial, &mut buf.total)?;
}
Method::Atomic => {
module.clear(stream, &clear, &buf.atomic)?;
module.dot_atomic(stream, &atomic, a, b, &buf.atomic)?;
module.publish(stream, &publish, &buf.atomic, &mut buf.total)?;
}
}
Ok(())
};
// ...
}// Launches 1 dot product; the result ends in buf.total.
void run(Method method, const Buffers& buf)
{
int n = buf.n;
int mapBlocks = (n + BLOCK - 1) / BLOCK;
switch (method) {
case MAP_REDUCE:
multiply<<<mapBlocks, BLOCK>>>(buf.a, buf.b, buf.products, n);
sum<<<GRID, BLOCK>>>(buf.products, buf.partial, n);
sum<<<1, BLOCK>>>(buf.partial, buf.total, GRID);
break;
case TREE:
dotTree<<<GRID, BLOCK>>>(buf.a, buf.b, buf.partial, n);
sum<<<1, BLOCK>>>(buf.partial, buf.total, GRID);
break;
case SHUFFLE:
dotShuffle<<<GRID, BLOCK>>>(buf.a, buf.b, buf.partial, n);
sum<<<1, BLOCK>>>(buf.partial, buf.total, GRID);
break;
case ATOMIC:
check(cudaMemsetAsync(buf.total, 0, sizeof(float)));
dotAtomic<<<GRID, BLOCK>>>(buf.a, buf.b, buf.total, n);
break;
}
check(cudaGetLastError());
}
Exercises
15.18 Write a fused kernel that combines 1 atomic addition per warp instead of per block. How many
atomic operations does 1 run perform with 1,024 blocks of 256 threads?
15.19 Reuse block_sum to compute \(\sum a_i^2\), the squared length of a vector. How many bytes
per element does it read?
15.8 Measurements
15.8.1 Platform and method
The measurements come from an integrated GPU, a Jetson Orin NX 16 GB, with 8 SMs and a memory bandwidth of 102 GB/s. Each program first runs the 2 exact tests of Section 15.6.3. It then computes the dot product of \(2^{24}\) pairs of floats in \([0, 1)\), drawn from a fixed generator, with each of the 4 designs, which is 64 MiB per vector. Every design runs 10 times as a warm-up and 20 times under CUDA events. The rate is the number of bytes that the design must move, 16 or 8 per pair, divided by its time. The program then runs the second-launch and atomic designs 100 times each and counts the distinct results. Repeated runs differed by up to 9%.
15.8.2 Results
The Rust program printed the following lines.
$ cargo oxide run
GPU: Orin, 8 SMs
exact tests map+red tree shuffle atomic
worked example, 16 pairs 63 63 63 63 expected 63
0s and 1s, 16777216 pairs 2796203 2796203 2796203 2796203 expected 2796203
16777216 pairs of floats in [0, 1), 20 runs
method time bytes/pair rate result
map, then reduce 3.334 ms 16 B 80.5 GB/s 4195680.0
fused, shared tree 1.409 ms 8 B 95.2 GB/s 4195680.0
fused, shuffles 1.405 ms 8 B 95.5 GB/s 4195680.0
fused, atomic combine 1.405 ms 8 B 95.5 GB/s 4195681.0
exact, in double precision 4195680.2
distinct results in 100 runs
second launch 1 from 4195680.0 to 4195680.0
atomic 3 from 4195680.5 to 4195681.5
largest relative error 3.20e-7
PASSED
Every design returns 63 for the worked example and exactly 2,796,203 for the 0-and-1 test. In the
table of floats, the column bytes/pair gives the bytes that each design moves per pair of
elements, and the line exact, in double precision gives the exact result for comparison.
Table 15.1 collects the times of both languages.
| Design | Bytes per pair | Rust time | Rust rate | C++ time | C++ rate |
|---|---|---|---|---|---|
| map, then reduce | 16 | 3.334 ms | 80.5 GB/s | 3.096 ms | 86.7 GB/s |
| fused, tree in shared memory | 8 | 1.409 ms | 95.2 GB/s | 1.412 ms | 95.1 GB/s |
| fused, warp shuffles | 8 | 1.405 ms | 95.5 GB/s | 1.456 ms | 92.2 GB/s |
| fused, atomic combine | 8 | 1.405 ms | 95.5 GB/s | 1.389 ms | 96.6 GB/s |
Table 15.1 The dot product of \(2^{24}\) pairs on the measured GPU. Least times at 102 GB/s: 2.63 ms for 16 bytes per pair, 1.32 ms for 8.
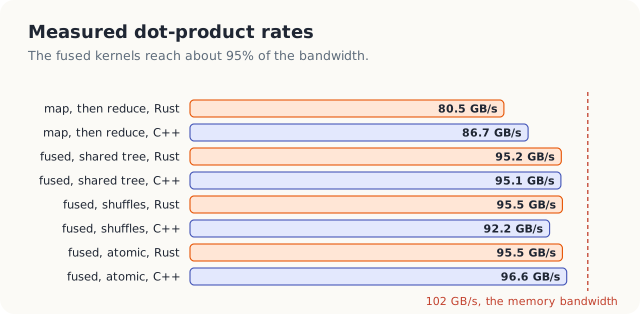
15.8.3 Why the fused kernel is more than twice as fast
We first count the bytes. The design that stores the products reads \(a_i\) and \(b_i\), writes \(p_i\), and reads \(p_i\) back in the reduction. These are 4 accesses of 4 bytes each, so the design moves 16 bytes per pair, or 268 MB for \(2^{24}\) pairs. The fused kernels read only \(a_i\) and \(b_i\), which is 8 bytes per pair, or 134 MB, as shown in Figure 15.13. At 102 GB/s, these amounts take at least 2.63 ms and 1.32 ms, a ratio of 2.
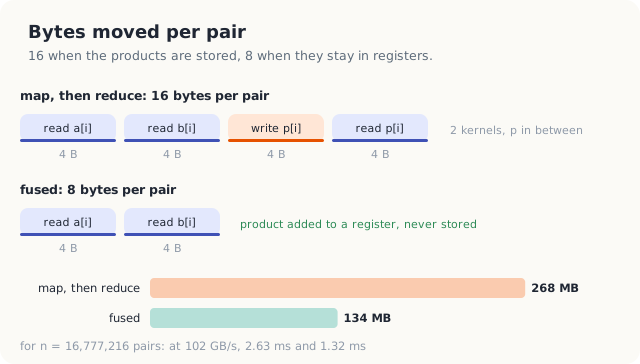
The measured ratio is \(3.334 / 1.405 = 2.4\) in Rust and \(3.096 / 1.412 = 2.2\) in C++. Halving the bytes accounts for a factor of 2. The rest comes from the lower rate of the first design, 80.5 GB/s and 86.7 GB/s against 95 GB/s. Its multiplication kernel writes one value for every 2 values that it reads, as SAXPY does, and recall from Chapter 14 that SAXPY reached at most 93 GB/s, for the reasons given in Section 14.8.3. The fused kernels only read, and they reach 92 GB/s to 97 GB/s, which is 90% to 95% of the pin rate of the memory. The Rust map-then-reduce design ran 8% to 11% slower than the C++ design in every run, while the fused kernels ran at the same speed in both languages.
15.8.4 Barriers, shuffles and atomics
The tree with 9 barriers and the warp shuffles with 1 barrier run at the same speed, 1.409 ms and 1.405 ms in Rust. We let each thread add 64 products in its register before the block sum begins, so the 9 barriers of a block cost time only once per \(64 \cdot 256 = 16{,}384\) products, which is a small part of its time. In Chapter 8, we found the same for the plain sum. After coarsening, its tree and its shuffle sum ran at 64.1 GB/s and 64.4 GB/s. Shuffles matter where combinations are frequent, as in the many short reductions of a softmax over the rows of a matrix (Chapter 23).
The atomic design is as fast as the others, because its 1,024 atomic additions are few, and its
extra launches, clear and publish, each run only 1 block. Its results, however, differ. The
exact dot product, computed in double precision on the CPU, is 4,195,680.2. Between
\(2^{22} = 4{,}194{,}304\) and \(2^{23}\), the floats are 0.5 apart, so the nearest float is
4,195,680.0. The second-launch designs return exactly this value, and the 100 runs of the shuffle
design returned the same bits every time. The atomic design returned 3 different values in 100
runs, 4,195,680.5, 4,195,681.0 and 4,195,681.5, which lie 1 to 3 float steps above the nearest
float, and in other runs, it also returned 4,195,680.0. All of these values are correct to a
relative error of \(3.2 \cdot 10^{-7}\), which is about the precision of a float. A program that
must reproduce its results bit for bit, for example to compare two versions of a simulation, needs
the second launch.
Exercises
15.20 From Table 15.1, compute the fraction of the 102 GB/s that each fused design reaches in each
language.
15.21 Predict the time of the fused dot product of \(2^{26}\) pairs on the measured GPU, and on a GPU
with 3,350 GB/s.
15.9 The complete programs
Listing 15.6 gives the complete programs, from which every excerpt of this chapter was taken.
Listing 15.6 The complete programs. code/oxide/ch15_dot_product/src/main.rs code/cuda/ch15_dot_product/dot.cu
//! Chapter 15: the dot product of 2 vectors as a reduction, 4 ways: map then reduce,
//! a fused kernel with a tree in shared memory, a fused kernel with warp shuffles, and
//! a fused kernel that combines its block results with atomic additions.
//!
//! cargo oxide run
use std::collections::BTreeSet;
use std::sync::Arc;
use cuda_core::sys::CUevent_flags_enum_CU_EVENT_DEFAULT as TIMING;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, LaunchConfig1D};
use cuda_device::atomic::{AtomicOrdering, DeviceAtomicF32};
use cuda_device::{DisjointSlice, SharedArray, cuda_module, device, kernel, launch_contract};
use cuda_device::{thread, warp};
const BLOCK: u32 = 256;
const GRID: u32 = 1024;
const N: usize = 1 << 24;
const RUNS: u32 = 20;
/// The worked example of the chapter: 16 pairs whose products add up to 63.
const A16: [f32; 16] = [1., 2., 3., 1., 5., 1., 2., 3., 3., 1., 2., 3., 1., 3., 2., 1.];
const B16: [f32; 16] = [2., 3., 1., 4., 1., 1., 4., 1., 1., 2., 2., 2., 1., 3., 1., 4.];
type Error = Box<dyn std::error::Error>;
#[cuda_module]
mod kernels {
use super::*;
/// The sum of `value` over the 32 lanes of a warp, left in lane 0.
#[device]
fn warp_sum(mut value: f32) -> f32 {
let mut step: u32 = 0;
#[unroll]
while step < 5 {
value += warp::shuffle_down_f32(value, 16u32 >> step);
step += 1;
}
value
}
/// The sum of `value` over the 256 threads of a block, returned to thread 0.
#[device]
fn block_sum(value: f32) -> f32 {
static mut WARP_SUMS: SharedArray<f32, 8> = SharedArray::UNINIT;
let lane = warp::lane_id() as usize;
let warp_index = thread::threadIdx_x() as usize / 32;
let value = warp_sum(value);
if lane == 0 {
// SAFETY: lane 0 of each warp writes its own slot, before the barrier.
unsafe { WARP_SUMS[warp_index] = value };
}
thread::sync_threads();
// SAFETY: after the barrier the slots are only read.
let warp_total = if lane < 8 { unsafe { WARP_SUMS[lane] } } else { 0.0 };
if warp_index == 0 { warp_sum(warp_total) } else { 0.0 }
}
/// The sum of a[index] * b[index] over this thread's elements, a grid apart.
#[device]
fn products(a: &[f32], b: &[f32]) -> f32 {
let grid_size = (thread::gridDim_x() * BLOCK) as usize;
let mut index = thread::index_1d().get();
let mut sum = 0.0;
while index < a.len() {
sum += a[index] * b[index];
index += grid_size;
}
sum
}
/// Map: products[index] = a[index] * b[index], one element per thread.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn multiply(a: &[f32], b: &[f32], mut element_products: DisjointSlice<f32>) {
let thread_id = thread::index_1d();
let index = thread_id.get();
if let Some(out) = element_products.get_mut(thread_id) {
*out = a[index] * b[index];
}
}
/// Reduce: 1 partial sum of `input` per block.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum(input: &[f32], mut partial: DisjointSlice<f32>) {
let grid_size = (thread::gridDim_x() * BLOCK) as usize;
let mut index = thread::index_1d().get();
let mut my_sum = 0.0;
while index < input.len() {
my_sum += input[index];
index += grid_size;
}
let total = block_sum(my_sum);
if thread::threadIdx_x() == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = total };
}
}
/// Fused: products and a tree in shared memory, 1 partial sum per block.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn dot_tree(a: &[f32], b: &[f32], mut partial: DisjointSlice<f32>) {
static mut CELLS: SharedArray<f32, 256> = SharedArray::UNINIT;
let thread_idx = thread::threadIdx_x() as usize;
// SAFETY: each thread writes only its own cell, before the barrier.
unsafe { CELLS[thread_idx] = products(a, b) };
thread::sync_threads();
let mut step: usize = 0;
#[unroll]
while step < 8 {
let stride: usize = 128 >> step;
if thread_idx < stride {
// SAFETY: in this step, this thread alone writes its cell and reads cell
// thread_idx + stride, which no thread writes in this step.
unsafe { CELLS[thread_idx] += CELLS[thread_idx + stride] };
}
thread::sync_threads();
step += 1;
}
if thread_idx == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = CELLS[0] };
}
}
/// Fused: products and warp shuffles, 1 partial sum per block.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn dot_shuffle(a: &[f32], b: &[f32], mut partial: DisjointSlice<f32>) {
let total = block_sum(products(a, b));
if thread::threadIdx_x() == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = total };
}
}
/// Sets the atomic result to 0 before a run of `dot_atomic`.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn clear(result: &[DeviceAtomicF32]) {
if thread::index_1d().get() == 0 {
result[0].store(0.0, AtomicOrdering::Relaxed);
}
}
/// Copies the atomic result into an ordinary float that the host can read.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn publish(result: &[DeviceAtomicF32], mut out: DisjointSlice<f32>) {
if let Some(value) = out.get_mut(thread::index_1d()) {
*value = result[0].load(AtomicOrdering::Relaxed);
}
}
/// Fused: products, warp shuffles, and 1 atomic addition per block.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn dot_atomic(a: &[f32], b: &[f32], result: &[DeviceAtomicF32]) {
let total = block_sum(products(a, b));
if thread::threadIdx_x() == 0 {
result[0].fetch_add(total, AtomicOrdering::Relaxed);
}
}
}
/// The 4 ways of computing the dot product that the program compares.
#[derive(Clone, Copy)]
enum Method {
MapReduce,
Tree,
Shuffle,
Atomic,
}
const METHODS: [(&str, Method, usize); 4] = [
("map, then reduce", Method::MapReduce, 16),
("fused, shared tree", Method::Tree, 8),
("fused, shuffles", Method::Shuffle, 8),
("fused, atomic combine", Method::Atomic, 8),
];
/// The device memory of 1 problem.
struct Buffers {
a: DeviceBuffer<f32>,
b: DeviceBuffer<f32>,
products: DeviceBuffer<f32>,
partial: DeviceBuffer<f32>,
total: DeviceBuffer<f32>,
atomic: DeviceBuffer<DeviceAtomicF32>,
}
impl Buffers {
fn new(stream: &Arc<CudaStream>, a: &[f32], b: &[f32]) -> Result<Self, Error> {
Ok(Buffers {
a: DeviceBuffer::from_host(stream, a)?,
b: DeviceBuffer::from_host(stream, b)?,
products: DeviceBuffer::zeroed(stream, a.len())?,
partial: DeviceBuffer::zeroed(stream, GRID as usize)?,
total: DeviceBuffer::zeroed(stream, 1)?,
atomic: DeviceBuffer::<f32>::zeroed(stream, 1)?.cast_elem(),
})
}
}
/// Runs 1 method once and returns its result.
fn result<R>(
run: &R,
method: Method,
buf: &mut Buffers,
stream: &CudaStream,
) -> Result<f32, Error>
where
R: Fn(Method, &mut Buffers) -> Result<(), Error>,
{
run(method, buf)?;
Ok(buf.total.to_host_vec(stream)?[0])
}
/// Milliseconds per run of 1 method: 10 warm-up runs, then RUNS runs timed with events.
fn time_ms<R>(
run: &R,
method: Method,
buf: &mut Buffers,
stream: &CudaStream,
) -> Result<f64, Error>
where
R: Fn(Method, &mut Buffers) -> Result<(), Error>,
{
for _ in 0..10 {
run(method, buf)?;
}
let start = stream.record_event(Some(TIMING))?;
for _ in 0..RUNS {
run(method, buf)?;
}
let stop = stream.record_event(Some(TIMING))?;
stop.synchronize()?;
Ok(start.elapsed_ms(&stop)? as f64 / RUNS as f64)
}
/// Floats in [0, 1) from a small linear congruential generator.
fn random(n: usize, seed: u32) -> Vec<f32> {
let mut state = seed;
(0..n)
.map(|_| {
state = state.wrapping_mul(1_664_525).wrapping_add(1_013_904_223);
(state >> 8) as f32 / 16_777_216.0
})
.collect()
}
/// Every method on 1 input whose dot product is an integer that a float holds exactly.
/// Returns the number of methods whose result differs from `expect`.
fn exact_test<R>(
run: &R,
stream: &Arc<CudaStream>,
label: &str,
a: &[f32],
b: &[f32],
) -> Result<usize, Error>
where
R: Fn(Method, &mut Buffers) -> Result<(), Error>,
{
let expect: f32 = a.iter().zip(b).map(|(x, y)| x * y).sum();
let mut buf = Buffers::new(stream, a, b)?;
let mut bad = 0;
print!(" {label:<26}");
for (_, method, _) in METHODS {
let got = result(run, method, &mut buf, stream)?;
print!(" {got:>9}");
bad += usize::from(got != expect);
}
println!(" expected {expect}");
Ok(bad)
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let name = ctx.device_name()?;
let sms = ctx.multiprocessor_count()?;
println!("GPU: {name}, {sms} SMs");
let grid = LaunchConfig1D::new(GRID, BLOCK, 0);
let one = LaunchConfig1D::new(1, BLOCK, 0);
let map = LaunchConfig1D::new(N as u32 / BLOCK, BLOCK, 0);
let multiply = module.prepare_multiply(map)?;
let reduce = module.prepare_sum(grid)?;
let last = module.prepare_sum(one)?;
let tree = module.prepare_dot_tree(grid)?;
let shuffle = module.prepare_dot_shuffle(grid)?;
let clear = module.prepare_clear(one)?;
let atomic = module.prepare_dot_atomic(grid)?;
let publish = module.prepare_publish(one)?;
// Launches 1 dot product; the result ends in `buf.total`.
let run = |method: Method, buf: &mut Buffers| -> Result<(), Error> {
let (a, b, stream) = (&buf.a, &buf.b, &stream);
match method {
Method::MapReduce => {
module.multiply(stream, &multiply, a, b, &mut buf.products)?;
module.sum(stream, &reduce, &buf.products, &mut buf.partial)?;
module.sum(stream, &last, &buf.partial, &mut buf.total)?;
}
Method::Tree => {
module.dot_tree(stream, &tree, a, b, &mut buf.partial)?;
module.sum(stream, &last, &buf.partial, &mut buf.total)?;
}
Method::Shuffle => {
module.dot_shuffle(stream, &shuffle, a, b, &mut buf.partial)?;
module.sum(stream, &last, &buf.partial, &mut buf.total)?;
}
Method::Atomic => {
module.clear(stream, &clear, &buf.atomic)?;
module.dot_atomic(stream, &atomic, a, b, &buf.atomic)?;
module.publish(stream, &publish, &buf.atomic, &mut buf.total)?;
}
}
Ok(())
};
println!("exact tests map+red tree shuffle atomic");
let mut failed = exact_test(&run, &stream, "worked example, 16 pairs", &A16, &B16)?;
let ones_a: Vec<f32> = (0..N).map(|index| f32::from(index % 3 == 0)).collect();
let ones_b: Vec<f32> = (0..N).map(|index| f32::from(index % 2 == 0)).collect();
failed += exact_test(&run, &stream, "0s and 1s, 16777216 pairs", &ones_a, &ones_b)?;
let a = random(N, 1);
let b = random(N, 2);
let exact: f64 = a.iter().zip(&b).map(|(&x, &y)| x as f64 * y as f64).sum();
let mut buf = Buffers::new(&stream, &a, &b)?;
let error = |r: f32| ((r as f64 - exact) / exact).abs();
let mut worst = 0.0f64;
println!("{N} pairs of floats in [0, 1), {RUNS} runs");
println!(" method time bytes/pair rate result");
for (name, method, per_pair) in METHODS {
let ms = time_ms(&run, method, &mut buf, &stream)?;
let got = result(&run, method, &mut buf, &stream)?;
worst = worst.max(error(got));
let gbs = (N * per_pair) as f64 / ms / 1e6;
print!(" {name:<22} {ms:6.3} ms {per_pair:>8} B");
println!(" {gbs:6.1} GB/s {got:.1}");
}
println!(" {:<54} {exact:.1}", "exact, in double precision");
println!("distinct results in 100 runs");
for (name, method) in [("second launch", Method::Shuffle), ("atomic", Method::Atomic)] {
let mut seen = BTreeSet::new();
for _ in 0..100 {
seen.insert(result(&run, method, &mut buf, &stream)?.to_bits());
}
let low = f32::from_bits(*seen.first().ok_or("no result")?);
let high = f32::from_bits(*seen.last().ok_or("no result")?);
println!(" {name:<14} {:3} from {low:.1} to {high:.1}", seen.len());
worst = worst.max(error(low)).max(error(high));
}
println!("largest relative error {worst:.2e}");
if failed == 0 && worst < 1e-5 {
println!("PASSED");
} else {
println!("FAILED");
}
Ok(())
}// Chapter 15: the dot product of 2 vectors as a reduction, 4 ways: map then reduce,
// a fused kernel with a tree in shared memory, a fused kernel with warp shuffles, and
// a fused kernel that combines its block results with atomic additions.
// Build: nvcc -O3 -arch=native dot.cu -o dot
#include <cmath>
#include <cstdio>
#include <cstdlib>
#include <cstring>
#include <set>
#include <vector>
#include <cuda_runtime.h>
const int BLOCK = 256;
const int GRID = 1024;
const int N = 1 << 24;
const int RUNS = 20;
// The worked example of the chapter: 16 pairs whose products add up to 63.
const float A16[16] = {1, 2, 3, 1, 5, 1, 2, 3, 3, 1, 2, 3, 1, 3, 2, 1};
const float B16[16] = {2, 3, 1, 4, 1, 1, 4, 1, 1, 2, 2, 2, 1, 3, 1, 4};
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
// The sum of value over the 32 lanes of a warp, left in lane 0.
__device__ float warpSum(float value)
{
for (int distance = 16; distance > 0; distance /= 2) {
value += __shfl_down_sync(0xffffffff, value, distance);
}
return value;
}
// The sum of value over the 256 threads of a block, returned to thread 0.
__device__ float blockSum(float value)
{
__shared__ float warpSums[8];
int lane = threadIdx.x % 32;
int warpIndex = threadIdx.x / 32;
value = warpSum(value);
if (lane == 0) {
warpSums[warpIndex] = value;
}
__syncthreads();
float warpTotal = lane < 8 ? warpSums[lane] : 0.0f;
return warpIndex == 0 ? warpSum(warpTotal) : 0.0f;
}
// The sum of a[index] * b[index] over this thread's elements, a grid apart.
__device__ float products(const float* a, const float* b, int n)
{
int gridSize = gridDim.x * blockDim.x;
float sum = 0.0f;
for (int index = blockIdx.x * blockDim.x + threadIdx.x; index < n; index += gridSize) {
sum += a[index] * b[index];
}
return sum;
}
// Map: elementProducts[index] = a[index] * b[index], one element per thread.
__global__ void multiply(const float* a, const float* b, float* elementProducts, int n)
{
int index = blockIdx.x * blockDim.x + threadIdx.x;
if (index < n) {
elementProducts[index] = a[index] * b[index];
}
}
// Reduce: 1 partial sum of input per block.
__global__ void sum(const float* input, float* partial, int n)
{
int gridSize = gridDim.x * blockDim.x;
float mySum = 0.0f;
for (int index = blockIdx.x * blockDim.x + threadIdx.x; index < n; index += gridSize) {
mySum += input[index];
}
float total = blockSum(mySum);
if (threadIdx.x == 0) {
partial[blockIdx.x] = total;
}
}
// Fused: products and a tree in shared memory, 1 partial sum per block.
__global__ void dotTree(const float* a, const float* b, float* partial, int n)
{
__shared__ float cells[BLOCK];
cells[threadIdx.x] = products(a, b, n);
__syncthreads();
for (int stride = BLOCK / 2; stride > 0; stride /= 2) {
if (threadIdx.x < stride) {
cells[threadIdx.x] += cells[threadIdx.x + stride];
}
__syncthreads();
}
if (threadIdx.x == 0) {
partial[blockIdx.x] = cells[0];
}
}
// Fused: products and warp shuffles, 1 partial sum per block.
__global__ void dotShuffle(const float* a, const float* b, float* partial, int n)
{
float total = blockSum(products(a, b, n));
if (threadIdx.x == 0) {
partial[blockIdx.x] = total;
}
}
// Fused: products, warp shuffles, and 1 atomic addition per block.
__global__ void dotAtomic(const float* a, const float* b, float* result, int n)
{
float total = blockSum(products(a, b, n));
if (threadIdx.x == 0) {
atomicAdd(result, total);
}
}
enum Method { MAP_REDUCE, TREE, SHUFFLE, ATOMIC };
struct MethodInfo {
const char* name;
Method method;
int bytesPerPair;
};
const MethodInfo METHODS[4] = {
{"map, then reduce", MAP_REDUCE, 16},
{"fused, shared tree", TREE, 8},
{"fused, shuffles", SHUFFLE, 8},
{"fused, atomic combine", ATOMIC, 8},
};
// The device memory of 1 problem.
struct Buffers {
int n;
float *a, *b, *products, *partial, *total;
};
Buffers upload(const std::vector<float>& a, const std::vector<float>& b)
{
Buffers buf;
buf.n = a.size();
size_t bytes = buf.n * sizeof(float);
check(cudaMalloc(&buf.a, bytes));
check(cudaMalloc(&buf.b, bytes));
check(cudaMalloc(&buf.products, bytes));
check(cudaMalloc(&buf.partial, GRID * sizeof(float)));
check(cudaMalloc(&buf.total, sizeof(float)));
check(cudaMemcpy(buf.a, a.data(), bytes, cudaMemcpyHostToDevice));
check(cudaMemcpy(buf.b, b.data(), bytes, cudaMemcpyHostToDevice));
return buf;
}
void release(Buffers& buf)
{
check(cudaFree(buf.a));
check(cudaFree(buf.b));
check(cudaFree(buf.products));
check(cudaFree(buf.partial));
check(cudaFree(buf.total));
}
// Launches 1 dot product; the result ends in buf.total.
void run(Method method, const Buffers& buf)
{
int n = buf.n;
int mapBlocks = (n + BLOCK - 1) / BLOCK;
switch (method) {
case MAP_REDUCE:
multiply<<<mapBlocks, BLOCK>>>(buf.a, buf.b, buf.products, n);
sum<<<GRID, BLOCK>>>(buf.products, buf.partial, n);
sum<<<1, BLOCK>>>(buf.partial, buf.total, GRID);
break;
case TREE:
dotTree<<<GRID, BLOCK>>>(buf.a, buf.b, buf.partial, n);
sum<<<1, BLOCK>>>(buf.partial, buf.total, GRID);
break;
case SHUFFLE:
dotShuffle<<<GRID, BLOCK>>>(buf.a, buf.b, buf.partial, n);
sum<<<1, BLOCK>>>(buf.partial, buf.total, GRID);
break;
case ATOMIC:
check(cudaMemsetAsync(buf.total, 0, sizeof(float)));
dotAtomic<<<GRID, BLOCK>>>(buf.a, buf.b, buf.total, n);
break;
}
check(cudaGetLastError());
}
// Runs method once and returns its result.
float result(Method method, const Buffers& buf)
{
float value;
run(method, buf);
check(cudaMemcpy(&value, buf.total, sizeof(float), cudaMemcpyDeviceToHost));
return value;
}
// Milliseconds per run of method: 10 warm-up runs, then RUNS runs timed with events.
float timeMs(Method method, const Buffers& buf)
{
for (int warmup = 0; warmup < 10; ++warmup) {
run(method, buf);
}
cudaEvent_t start, stop;
check(cudaEventCreate(&start));
check(cudaEventCreate(&stop));
check(cudaEventRecord(start));
for (int timed = 0; timed < RUNS; ++timed) {
run(method, buf);
}
check(cudaEventRecord(stop));
check(cudaEventSynchronize(stop));
float ms = 0;
check(cudaEventElapsedTime(&ms, start, stop));
check(cudaEventDestroy(start));
check(cudaEventDestroy(stop));
return ms / RUNS;
}
// Floats in [0, 1) from a small linear congruential generator.
std::vector<float> random(int n, unsigned seed)
{
std::vector<float> v(n);
unsigned state = seed;
for (int i = 0; i < n; ++i) {
state = state * 1664525u + 1013904223u;
v[i] = (state >> 8) / 16777216.0f;
}
return v;
}
// Every method on 1 input whose dot product is an integer that a float holds exactly.
// Returns the number of methods whose result differs from expect.
int exactTest(const char* label, const std::vector<float>& a, const std::vector<float>& b)
{
float expect = 0;
for (size_t i = 0; i < a.size(); ++i) {
expect += a[i] * b[i];
}
Buffers buf = upload(a, b);
int bad = 0;
std::printf(" %-26s", label);
for (const MethodInfo& m : METHODS) {
float got = result(m.method, buf);
std::printf(" %9.0f", got);
bad += got != expect;
}
std::printf(" expected %.0f\n", expect);
release(buf);
return bad;
}
unsigned bits(float f)
{
unsigned u;
std::memcpy(&u, &f, sizeof(u));
return u;
}
float fromBits(unsigned u)
{
float f;
std::memcpy(&f, &u, sizeof(f));
return f;
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %d SMs\n", prop.name, prop.multiProcessorCount);
std::printf("exact tests map+red tree shuffle atomic\n");
std::vector<float> a16(A16, A16 + 16), b16(B16, B16 + 16);
int failed = exactTest("worked example, 16 pairs", a16, b16);
std::vector<float> onesA(N), onesB(N);
for (int i = 0; i < N; ++i) {
onesA[i] = i % 3 == 0;
onesB[i] = i % 2 == 0;
}
failed += exactTest("0s and 1s, 16777216 pairs", onesA, onesB);
std::vector<float> a = random(N, 1);
std::vector<float> b = random(N, 2);
double exact = 0;
for (int i = 0; i < N; ++i) {
exact += double(a[i]) * b[i];
}
Buffers buf = upload(a, b);
double worst = 0;
std::printf("%d pairs of floats in [0, 1), %d runs\n", N, RUNS);
std::printf(" method time bytes/pair rate result\n");
for (const MethodInfo& m : METHODS) {
float ms = timeMs(m.method, buf);
float got = result(m.method, buf);
worst = std::fmax(worst, std::fabs((got - exact) / exact));
double gbs = double(N) * m.bytesPerPair / ms / 1e6;
std::printf(" %-22s %6.3f ms %8d B", m.name, ms, m.bytesPerPair);
std::printf(" %6.1f GB/s %.1f\n", gbs, got);
}
std::printf(" %-54s %.1f\n", "exact, in double precision", exact);
std::printf("distinct results in 100 runs\n");
const MethodInfo combine[2] = {{"second launch", SHUFFLE, 8}, {"atomic", ATOMIC, 8}};
for (const MethodInfo& m : combine) {
std::set<unsigned> seen;
for (int trial = 0; trial < 100; ++trial) {
seen.insert(bits(result(m.method, buf)));
}
float low = fromBits(*seen.begin());
float high = fromBits(*seen.rbegin());
std::printf(" %-14s %3zu from %.1f to %.1f\n", m.name, seen.size(), low, high);
worst = std::fmax(worst, std::fabs((low - exact) / exact));
worst = std::fmax(worst, std::fabs((high - exact) / exact));
}
release(buf);
std::printf("largest relative error %.2e\n", worst);
if (failed == 0 && worst < 1e-5) {
std::printf("PASSED\n");
} else {
std::printf("FAILED\n");
}
return 0;
}
Common mistakes
Storing the products of a map that a reduction consumes. The array of products doubles the memory traffic of a memory-bound computation. The map should instead be fused into the reduction, so that the products stay in a register.
A missing barrier between the steps of the tree. The kernel compiles in both languages and returns a wrong sum that changes from run to run (Section 15.4.1).
A barrier inside a branch that only some threads take. Every thread of the block must reach
every __syncthreads() or thread::sync_threads().
A plain addition where an atomic one is needed. *result += total from many blocks loses most
of the additions (Section 15.6.2).
Expecting identical bits from atomic float additions. The order of the additions changes from run to run, and so can the last bits of the result. When results must repeat exactly, the block sums should be combined with a second launch.
An unsafe block without its argument. Each access to a shared array needs a stated reason
why no other thread writes the same element at the same time, and this reason usually names a
barrier.
Summary
- The dot product is a map, \(p_i = a_i b_i\), followed by a reduction, the sum. On the example, the 16 products add up to \(32 + 31 = 63\).
- The sequential sum is a chain of \(n\) dependent additions. Because addition is associative and commutative, the additions can be regrouped into a tree of \(\log_2 n\) steps, 4 for the example.
- In shared memory, each step lets the threads with \(\mathsf{threadIdx{.}x} < \mathsf{stride}\) add cell \(\mathsf{threadIdx{.}x} + \mathsf{stride}\) into their own cell; block 0 of the example computes 7, 7, 11, 7, then 18, 14, then 32. A barrier must follow every step: without it, the example’s block summed to 24 instead of 32, and the real programs returned 26 and 36 instead of 63.
- Theorem 15.1 proves the tree correct with the invariant that, at the start of the step with stride \(\mathsf{stride}\), cell \(k\) holds the values whose index \(j\) leaves the remainder \(k\) when divided by \(2\,\mathsf{stride}\).
- Warp shuffles exchange registers within a warp without a barrier; a block sum with shuffles needs 1 barrier and 8 shared floats instead of 9 and 256.
- Block sums are combined by a second launch, in a fixed order, or by atomic additions, in the order the blocks finish. A plain addition loses sums. Atomic float additions gave 3 different last bits in 100 runs; the second launch gave the same bits every time.
- The fused kernels read 8 bytes per pair and ran at 92 GB/s to 97 GB/s on the measured GPU, 2.2 to 2.4 times as fast as a map followed by a reduction, which moves 16.
Exercises
- Compute the least time of the fused dot product of \(2^{26}\) pairs on your GPU from its
memory bandwidth. Change
Nin both programs and compare. - Change both programs to
f64. The fused kernel then reads 16 bytes per pair. Is its time twice that of thef32version? - Change
GRIDfrom 1,024 to 64 and to 8,192. How many products does each thread add in each case, and how do the times of the tree and shuffle kernels change? - In Listing 15.2, which cells does thread 5 read and write in each of the 8 steps? In which steps is it idle?
- Write the maximum of an array as a reduction, reusing the tree of Dot-Block with \(\max\) in place of \(+\). What must the threads with no element store in line 8?
- Prove that Block-Sum returns the sum of the 256 values to thread 0, using Theorem 15.1 for each warp.
- The exact dot product of the measured vectors is 4,195,680.2. Explain why no float program can return it, and which float is the best possible answer.
Sources and further reading
- A. Pathak, An Introduction to Tiled Parallel Programming, Simplified, 2026. The style of worked example, broken variants and loop-invariant proof used here, and the exact verification with small integers.
- T. H. Cormen, C. E. Leiserson, R. L. Rivest and C. Stein, Introduction to Algorithms, 4th ed., MIT Press, 2022. Pseudocode conventions and loop invariants.
- M. Harris, “Optimizing Parallel Reduction in CUDA”, NVIDIA, 2007.
- J. Luitjens, “Faster Parallel Reductions on Kepler”, NVIDIA Technical Blog, 2014.
- D. Goldberg, “What Every Computer Scientist Should Know About Floating-Point Arithmetic”, ACM Computing Surveys 23(1), 1991.
- NVIDIA, CUDA C++ Programming Guide, sections “Warp Shuffle Functions”, “Atomic Functions” and “Synchronization Functions”.
- The Rust Reference, “Static items” and “Unsafety”; the cuda-oxide repository, https://github.com/NVlabs/cuda-oxide.
Matrix Multiplication
In the next 3 chapters, we compute the same product, \(C = AB\), with 3 kernels, and we derive each kernel from the one before it. The matrix product is the classic first example of parallel programming on a GPU, for 2 reasons. First, every entry of \(C\) can be computed independently of the others, which makes the product easy to parallelize. Second, every input value is needed by many entries of \(C\). As a result, the cost of the product depends mainly on how often each input value is read, and on the memory from which it is read.
The 3 chapters are built on 1 idea. When several threads need the same value, the value should be fetched once from slow storage into fast storage, and all of these threads should then read it from the fast storage. In Chapter 16, we count what happens without this idea. In the direct kernel, there is 1 thread for each entry of \(C\), and each thread fetches every operand of its dot product from global memory. With \(A\) of size \(M \times K\) and \(B\) of size \(K \times N\), there are \(MN\) threads, and each thread fetches \(2K\) values, namely \(K\) values from a row of \(A\) and \(K\) values from a column of \(B\). This is 1 fetch for every floating-point operation.
In Chapter 17, we apply the idea to a block of threads and its shared memory. The threads of a block copy square pieces of \(A\) and \(B\), called tiles, into shared memory, which divides the number of fetches from global memory by the tile width \(T\), the number of rows and columns in a tile. In Chapter 18, we apply the idea to a single thread and its registers, which divides the number of reads from shared memory by the size of the block of \(C\) that each thread computes.
All 3 chapters work with the same pair of 4 × 4 matrices, whose product begins with \(c_{00} = 11\) and \(c_{01} = 13\). In Chapter 16, we compute the product by hand and with the sequential algorithm, we introduce threads, blocks, grids and the memories of the device, and we derive the direct kernel. In Chapter 17, we split each dot product into phases and stage tiles in shared memory. We then show, on the example, the wrong values 7 and 15 that appear when either of the kernel’s 2 barriers is removed, and we prove the tiled kernel correct with a loop invariant. In Chapter 18, we let each thread compute a block of entries of \(C\) as a sum of outer products, and we measure register tiles from 1 × 1 to 8 × 8.
In each chapter, we implement the kernel in Rust with cuda-oxide and in CUDA C++, show the 2
versions side by side, check the results exactly against the CPU, and measure them. We build on
Chapter 9, where we developed the same sequence of kernels in CUDA C++ and compared them with
cuBLAS, and on Chapters 13 to 15, where we introduced kernels, DisjointSlice, launch contracts
and shared memory in Rust.
Chapter 16: Matrix Multiplication, One Thread per Entry
The product of 2 matrices is the most studied computation on the GPU. It is the core of the dense linear algebra in scientific simulations, and the layers of a neural network spend most of their time computing it. It is also the standard first example of a parallel algorithm, for 2 reasons. First, every entry of the result can be computed independently of every other entry, so the work divides naturally among many threads. Second, the same input values are needed by many entries of the result, which makes it easy to count how often each value is read from memory, and therefore to see where the time goes.
In this chapter, we derive the simplest GPU kernel for the matrix product. We work with a single pair of 4 × 4 matrices from the first section to the last, small enough that every number can be checked with a pencil. We first compute the product by hand and with a sequential algorithm on the CPU. We then introduce the parts of the GPU that the kernel needs, namely threads, blocks and grids, and the memories of the device. After that, we write the direct kernel, in which 1 thread computes 1 entry of the result, and we count how often it reads each input value from memory. This count leads to the observation on which the tiled kernel of Chapter 17 is built. Finally, we implement the kernel in Rust with cuda-oxide and in CUDA C++, and we measure it.
This chapter covers
- the matrix product, worked by hand on a 4 × 4 example
- row-major storage and the sequential algorithm, with a count of its work
- threads, blocks and grids in 1, 2 and 3 dimensions
- the memories of the device, and why global memory is the expensive one
- the direct kernel, and the number of values it fetches from global memory
- the kernel in Rust (
DisjointSlice,Runtime2DIndex, launch contracts, a generic element type) and in CUDA C++ (a template) - measured speeds, and why they are far below the arithmetic peak
The code of the chapter is in
code/oxide/ch16_matmul_naive/
for Rust and in
code/cuda/ch16_matmul_naive/
for C++.
We write algorithms in the style of Cormen, Leiserson, Rivest and Stein, with procedure names in
small capitals, numbered lines, mathematical notation, and braces that delimit blocks. The range
\([a, b)\) denotes the integers \(a, a + 1, \ldots, b - 1\), exactly like a..b in Rust. For
example, \(i \in [0, 4)\) means that \(i\) takes the values 0, 1, 2 and 3. Indices start at 0
throughout.
16.1 The matrix product
16.1.1 A worked example
We use the same pair of matrices throughout this chapter and the two chapters that follow it. The 2 factors, \(A\) and \(B\), and their product, \(C\), are
\[ \underbrace{\begin{pmatrix} 1 & 2 & 3 & 4 \\ 5 & 6 & 7 & 8 \\ 9 & 10 & 11 & 12 \\ 13 & 14 & 15 & 16 \end{pmatrix}}_{A} \times \underbrace{\begin{pmatrix} 1 & 0 & 2 & 1 \\ 0 & 1 & 1 & 2 \\ 2 & 1 & 0 & 1 \\ 1 & 2 & 1 & 0 \end{pmatrix}}_{B} = \underbrace{\begin{pmatrix} 11 & 13 & 8 & 8 \\ 27 & 29 & 24 & 24 \\ 43 & 45 & 40 & 40 \\ 59 & 61 & 56 & 56 \end{pmatrix}}_{C}. \]
Each entry of \(C\) is computed from 1 row of \(A\) and 1 column of \(B\). To obtain the top-left entry of \(C\), which is 11, we walk along row 0 of \(A\) and down column 0 of \(B\) at the same time, multiply the 2 numbers we meet at each step, and add the 4 products. Row 0 of \(A\) holds 1, 2, 3 and 4, and column 0 of \(B\) holds 1, 0, 2 and 1, so the entry is \(1 \cdot 1 + 2 \cdot 0 + 3 \cdot 2 + 4 \cdot 1 = 1 + 0 + 6 + 4 = 11\), as shown in Figure 16.1. Every other entry of \(C\) is computed in the same way from a different pair of a row and a column. For example, the entry in row 0 and column 1 pairs row 0 of \(A\) with column 1 of \(B\), which holds 0, 1, 1 and 2, and equals \(1 \cdot 0 + 2 \cdot 1 + 3 \cdot 1 + 4 \cdot 2 = 13\).
The 2 entries we have just computed, \(c_{00} = 11\) and \(c_{01} = 13\), will appear again in Chapter 17. In that chapter, we remove 1 line at a time from a correct kernel, and the 2 incorrect kernels that result produce the values 7 and 15 in their place.
16.1.2 Definition
The rule we have just used pairs a row of \(A\) with a column of \(B\), entry by entry, so a row of \(A\) and a column of \(B\) must have the same length. We call that length \(K\). In our example, every row of \(A\) and every column of \(B\) holds 4 values, so \(K = 4\). We write \(a_{is}\) for the entry of \(A\) in row \(i\) and column \(s\); for example, \(a_{02} = 3\) and \(a_{21} = 10\). In the same way, \(b_{sj}\) is the entry of \(B\) in row \(s\) and column \(j\), and \(c_{ij}\) is the entry of \(C\) in row \(i\) and column \(j\).
Definition 16.1 Matrix product. Let \(A\) be an \(M \times K\) matrix and \(B\) a \(K \times N\) matrix. Their product \(C = AB\) is the \(M \times N\) matrix with entries
\[ c_{ij} = \sum_{s \in [0, K)} a_{is}\, b_{sj}, \qquad i \in [0, M),\ j \in [0, N). \]
In words, \(c_{ij}\) is the dot product of row \(i\) of \(A\) and column \(j\) of \(B\), that is, the sum of the products of their entries, taken in pairs.
Example. In our example, \(M = K = N = 4\), and the definition gives \(c_{00} = 1 \cdot 1 + 2 \cdot 0 + 3 \cdot 2 + 4 \cdot 1 = 11\), the sum of Figure 16.1.
| Symbol | Meaning | In the example |
|---|---|---|
| \(M\) | number of rows of \(A\) and of \(C\) | 4 |
| \(N\) | number of columns of \(B\) and of \(C\) | 4 |
| \(K\) | number of columns of \(A\) and of rows of \(B\), the length of each dot product | 4 |
| \(i, j\) | row and column of the entry of \(C\) being computed | 0, 0 for \(c_{00}\) |
| \(s\) | position along row \(i\) of \(A\) and down column \(j\) of \(B\) | 0, 1, 2, 3 |
| \(a_{is}\) | entry of \(A\) in row \(i\), column \(s\) | \(a_{02} = 3\) for \(i = 0\), \(s = 2\) |
| \(b_{sj}\) | entry of \(B\) in row \(s\), column \(j\) | \(b_{20} = 2\) for \(s = 2\), \(j = 0\) |
The term with \(s = 2\) in the sum for \(c_{00}\) is therefore \(a_{02}\, b_{20} = 3 \cdot 2 = 6\), the third of the 4 products in Figure 16.1.
The 3 sizes play different roles. \(M\) is the number of rows of \(A\) and of \(C\), and \(N\) is the number of columns of \(B\) and of \(C\). \(K\) is the length of every dot product. Note that \(K\) does not appear in the shape of the result at all; it only determines how much work each entry takes. For example, the product of a 2 × 3 matrix and a 3 × 5 matrix has \(M = 2\), \(K = 3\) and \(N = 5\), and it is a 2 × 5 matrix whose 10 entries are each a sum of 3 products. The kernels of this part accept any 3 sizes, and we measure them on square matrices, \(M = N = K = n\).
16.1.3 Storage in row-major order
The memory of a computer is a single line of numbered locations, so a 2-dimensional matrix must be laid out along that line. The usual choice copies the matrix out in the order in which we read a page, that is, row 0 first, then row 1, then row 2, and so on to the last row (Figure 16.2). Consider the entry 10 of \(A\), which lies in row 2 and column 1. Rows 0 and 1 come before it, and they hold 8 values. Within row 2, 1 entry comes before it. The entry 10 is therefore preceded by \(8 + 1 = 9\) values, and since locations are numbered from 0, it is stored at location \(2 \cdot 4 + 1 = 9\).
In general, to find the entry in row \(r\) and column \(c\), we skip the \(r\) complete rows above it and then the \(c\) entries that precede it in its own row.
Definition 16.2 Row-major order. In row-major order, the rows of a matrix are stored one after another. In a matrix whose rows have width \(W\), entry \((r, c)\) is stored at location
\[ \text{Index}(r, c, W) = r \cdot W + c. \]
The number \(W\) is called the row width of the matrix.
Example. \(A\) has rows of width 4, so \(a_{21} = 10\) is stored at \(\text{Index}(2, 1, 4) = 9\).
| Symbol | Meaning | For \(a_{21} = 10\) |
|---|---|---|
| \(r\) | row of the entry, which is also the number of complete rows before it | 2 |
| \(c\) | column of the entry, which is also the number of entries before it in its row | 1 |
| \(W\) | row width, the number of entries in each row | 4 |
| \(r \cdot W + c\) | location of the entry in memory | \(2 \cdot 4 + 1 = 9\) |
Row-major order has a consequence that we use often in the later chapters. Neighbors in a row are neighbors in memory, while neighbors in a column lie \(W\) locations apart. For example, \(a_{21} = 10\) and \(a_{22} = 11\) are stored at locations 9 and 10, whereas \(a_{21} = 10\) and \(a_{31} = 14\) are stored at locations 9 and 13. In the product, matrix \(A\) has rows of width \(K\), and matrices \(B\) and \(C\) have rows of width \(N\). Therefore, entry \(a_{is}\) is stored at location \(iK + s\), entry \(b_{sj}\) at location \(sN + j\), and entry \(c_{ij}\) at location \(iN + j\). Rust slices, C arrays, and every matrix in this book use row-major order.
Exercises
16.1 Compute \(c_{23}\) from Definition 16.1. Which row of \(A\) and which column of \(B\)
do you use?
16.2 At which location is \(b_{31}\) stored, in row-major order with \(W = 4\)? Which value
does it hold?
16.3 A matrix of 3 rows is stored in row-major order in 12 locations. What is its row width, and
where is entry \((2, 0)\)?
16.2 The sequential algorithm
On a CPU, Definition 16.1 becomes 3 nested loops. The outer 2 loops choose an entry of \(C\), one row \(\mathsf{row}\) and one column \(\mathsf{col}\) at a time, and the inner loop adds up the \(K\) products for that entry.
Matrix-Multiply(\(A, B, C, M, K, N\))
- for \(\mathsf{row} \in [0, M)\) {
- for \(\mathsf{col} \in [0, N)\) {
- \(c_{\mathsf{row}, \mathsf{col}} = 0\)
- for \(\mathsf{inner} \in [0, K)\) {
- \(c_{\mathsf{row}, \mathsf{col}} = c_{\mathsf{row}, \mathsf{col}} + a_{\mathsf{row}, \mathsf{inner}} \cdot b_{\mathsf{inner}, \mathsf{col}}\)
- }
- }
- }
Let us count the work. Line 5 executes once for every choice of \(\mathsf{row}\), \(\mathsf{col}\) and \(\mathsf{inner}\). There are \(M\) choices of \(\mathsf{row}\), \(N\) choices of \(\mathsf{col}\) and \(K\) choices of \(\mathsf{inner}\), so line 5 executes \(MNK\) times. Each execution is 1 multiply-add, that is, 1 multiplication followed by 1 addition. We count work in floating-point operations (FLOP), so 1 multiply-add is 2 FLOP, and the whole product is \(2MNK\) FLOP. Our example needs \(4 \cdot 4 \cdot 4 = 64\) multiply-adds, or 128 FLOP. The count grows quickly with the size. For 2 matrices of size 1,024 × 1,024, the product needs \(1{,}024^3 = 1.07 \times 10^9\) multiply-adds, and for 2 matrices of size 4,096 × 4,096, it needs \(6.9 \times 10^{10}\) multiply-adds, which is \(1.37 \times 10^{11}\) FLOP.
The CPU performs these multiply-adds one after another, and it visits the entries of \(C\) in order, row by row, as shown in Figure 16.3. At visit 7, it computes \(c_{12}\), the entry in row 1 and column 2. Line 5 runs 4 times, for \(\mathsf{inner} = 0, 1, 2, 3\), and pairs row 1 of \(A\), which holds 5, 6, 7 and 8, with column 2 of \(B\), which holds 2, 1, 0 and 1. The result is \(c_{12} = 5 \cdot 2 + 6 \cdot 1 + 7 \cdot 0 + 8 \cdot 1 = 24\).
Nothing in the algorithm requires this order. Visit 7 reads row 1 of \(A\) and column 2 of \(B\), which no visit changes, and it writes \(c_{12}\), which no other visit reads or writes. The same holds for each of the 16 visits. The visits are therefore independent of one another, and they could all take place at the same time. A GPU is built for exactly this situation, and in the next section, we describe the parts of it that we need.
Exercises
16.4 Show that Matrix-Multiply reads each entry of
\(A\) exactly \(N\) times. How many times does it read each entry of \(B\)?
16.5 How many FLOP does the product of a 300 × 500 matrix and a 500 × 700 matrix take?
16.6 Exchange the loops over \(\mathsf{col}\) and \(\mathsf{inner}\) in the algorithm. Is the result still correct?
Which line must move?
16.3 The graphics processor
16.3.1 Host and device
A computer with a GPU contains 2 processors, each with its own memory. We call the CPU and its memory the host, and the GPU and its memory the device. Data move between the 2 memories only when the program copies them explicitly. For this reason, every program of this part follows the same 5 steps, shown in Figure 16.4. The host creates \(A\) and \(B\), copies them to the device, and launches the computation; when the computation has finished, the host copies \(C\) back and checks it.
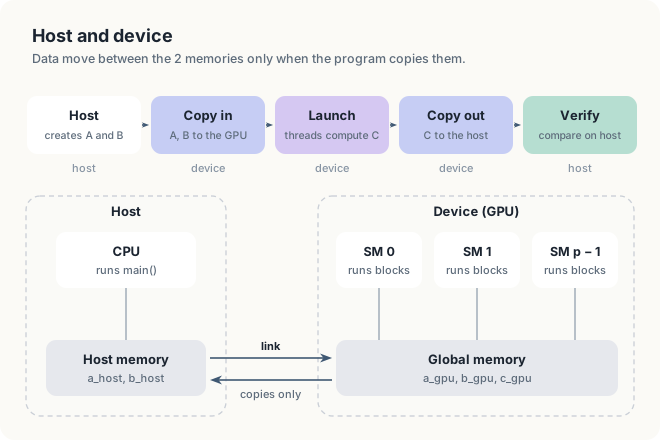
On an integrated GPU, the host and the device share 1 physical memory. The program nevertheless copies between the host’s buffers and the device’s buffers, and the 5 steps are the same.
16.3.2 Threads, blocks and grids
Recall from Section 16.2 that no entry of \(C\) depends on any other, so all 16 entries may be computed at the same time. A GPU takes advantage of such independence by running 1 function many times at once, each time on a different piece of the data.
Definition 16.3 Kernel and thread. A kernel is a function that the GPU runs many times at once. Each of these runs is called a thread. Every thread has its own position among the threads and its own variables.
Example. We will run the direct kernel of Section 16.4 with 16 threads, 1 per entry of \(C\). The thread at row 1 and column 2 computes \(c_{12} = 24\).
The GPU organizes the threads of a kernel on 2 levels. Threads are grouped into blocks, and the blocks together form a grid.
Definition 16.4 Block and grid. A block is a group of threads that run on the same processor of the device, share a region of fast memory, and can wait for one another. The grid is the set of all blocks of 1 launch.
Example. With blocks of 2 × 2 threads, a grid of 2 × 2 blocks covers \(C\). Block \((0, 0)\) computes \(c_{00}\), \(c_{01}\), \(c_{10}\) and \(c_{11}\).
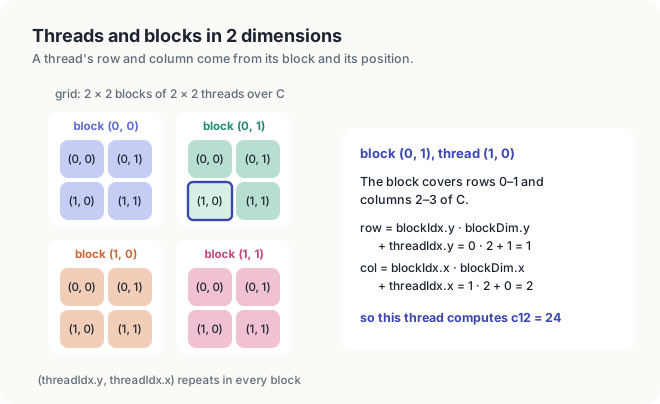
Blocks and grids can extend along 1, 2 or 3 axes, named \(x\), \(y\) and \(z\), and we choose the shape to match the data. For each thread, the GPU provides 3 values from which the thread can work out which piece of the data belongs to it. The value \(\mathsf{blockIdx}\) is the position of the thread’s block within the grid, \(\mathsf{threadIdx}\) is the position of the thread within its block, and \(\mathsf{blockDim}\) is the size of a block, that is, the number of threads it holds along each axis. Each of the 3 values has 1 component per axis, written with a suffix; for example, \(\mathsf{threadIdx{.}x}\) is the position of the thread along the axis \(x\). We first see how a thread uses these values in 1 dimension, where the computation is easiest to follow.
1 dimension. Suppose that a vector of 12 elements is handled by blocks of 4 threads, so that 3 blocks lie side by side, as in Figure 16.6. Consider thread 1 of block 2. Blocks 0 and 1 come before block 2, and together they cover elements 0 to 7. Block 2 therefore starts at element 8, and its thread 1 handles element \(8 + 1 = 9\). In general, a block starts at element \(\mathsf{blockIdx{.}x} \cdot \mathsf{blockDim{.}x}\), because each of the \(\mathsf{blockIdx{.}x}\) blocks before it covers \(\mathsf{blockDim{.}x}\) elements. A thread then adds its own position within the block, so it handles element
\[ \mathsf{index} = \mathsf{blockIdx{.}x} \cdot \mathsf{blockDim{.}x} + \mathsf{threadIdx{.}x}. \]
| Symbol | Meaning | Thread 1 of block 2 |
|---|---|---|
| \(\mathsf{blockIdx{.}x}\) | position of the block in the grid | 2 |
| \(\mathsf{blockDim{.}x}\) | number of threads in a block | 4 |
| \(\mathsf{threadIdx{.}x}\) | position of the thread within its block | 1 |
| \(\mathsf{index}\) | element that the thread handles | \(2 \cdot 4 + 1 = 9\) |
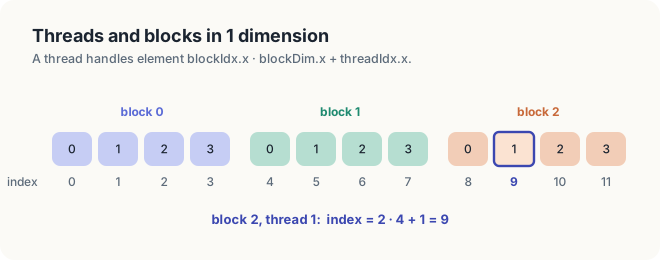
2 dimensions. A matrix has rows and columns, so we arrange the threads of a block, and the blocks of the grid, in rows and columns as well. The axis \(x\) counts columns, and the axis \(y\) counts rows. For the matrix product, we cut \(C\) into squares and give each square to one block. Each thread computes one entry of its block’s square. The number of threads along a row of the block is \(\mathsf{blockDim{.}x}\), and the number along a column is \(\mathsf{blockDim{.}y}\). We use square blocks, so the 2 numbers are equal. In our example, \(\mathsf{blockDim{.}x} = \mathsf{blockDim{.}y} = 2\), so each block holds 4 threads, which compute a 2 × 2 square of \(C\), and 2 × 2 blocks cover the 4 × 4 matrix, as in Figure 16.5.
We write all positions as (row, column). The position of a thread within its block is (\(\mathsf{threadIdx{.}y}\), \(\mathsf{threadIdx{.}x}\)): \(\mathsf{threadIdx{.}y}\) is the row of the thread within its block, and \(\mathsf{threadIdx{.}x}\) is its column. In the same way, the position of a block within the grid is (\(\mathsf{blockIdx{.}y}\), \(\mathsf{blockIdx{.}x}\)). Thus, thread \((1, 0)\) of block \((0, 1)\), which is outlined in Figure 16.5, is the thread in row 1 and column 0 of the block that lies in row 0 and column 1 of the grid. For this thread, \(\mathsf{threadIdx{.}y} = 1\), \(\mathsf{threadIdx{.}x} = 0\), \(\mathsf{blockIdx{.}y} = 0\) and \(\mathsf{blockIdx{.}x} = 1\).
Let us find the entry of \(C\) that this thread computes. Its block covers rows 0 and 1 and columns 2 and 3 of \(C\). Each block row of the grid covers \(\mathsf{blockDim{.}y}\) rows of \(C\), and each block column covers \(\mathsf{blockDim{.}x}\) columns, so the top-left corner of block \((0, 1)\) is at row \(0 \cdot 2 = 0\) and column \(1 \cdot 2 = 2\). Within the block, the thread lies 1 row down and 0 columns across from that corner. It therefore computes the entry in row \(0 + 1 = 1\) and column \(2 + 0 = 2\), which is \(c_{12}\). The same reasoning applies to every thread. We call the row and the column of the entry that a thread computes \(\mathsf{row}\) and \(\mathsf{col}\), and they are
\[ \mathsf{row} = \mathsf{blockIdx{.}y} \cdot \mathsf{blockDim{.}y} + \mathsf{threadIdx{.}y}, \qquad \mathsf{col} = \mathsf{blockIdx{.}x} \cdot \mathsf{blockDim{.}x} + \mathsf{threadIdx{.}x}. \]
| Symbol | Meaning | Thread \((1, 0)\) of block \((0, 1)\) |
|---|---|---|
| \(\mathsf{blockIdx{.}y}\) | row of the block within the grid | 0 |
| \(\mathsf{blockIdx{.}x}\) | column of the block within the grid | 1 |
| \(\mathsf{threadIdx{.}y}\) | row of the thread within its block | 1 |
| \(\mathsf{threadIdx{.}x}\) | column of the thread within its block | 0 |
| \(\mathsf{blockDim{.}y}\), \(\mathsf{blockDim{.}x}\) | number of threads along each side of a block | 2 |
| \(\mathsf{row}\) | row of the entry of \(C\) that the thread computes | \(0 \cdot 2 + 1 = 1\) |
| \(\mathsf{col}\) | column of the entry of \(C\) that the thread computes | \(1 \cdot 2 + 0 = 2\) |
As a second example, thread \((0, 1)\) of block \((0, 0)\) has \(\mathsf{threadIdx{.}y} = 0\) and \(\mathsf{threadIdx{.}x} = 1\),
and it computes the entry with \(\mathsf{row} = 0 \cdot 2 + 0 = 0\) and
\(\mathsf{col} = 0 \cdot 2 + 1 = 1\), that is, \(c_{01} = 13\). Within block \((0, 0)\),
the 4 threads \((0, 0)\), \((0, 1)\), \((1, 0)\) and \((1, 1)\) compute \(c_{00}\),
\(c_{01}\), \(c_{10}\) and \(c_{11}\), so for this block, the position of a thread and the
position of its entry coincide. In cuda-oxide, the values \(\mathsf{row}\) and
\(\mathsf{col}\) are returned by thread::index_2d_row() and thread::index_2d_col().
The choice of \(x\) for the column is deliberate. The GPU executes the threads of a block in groups of 32 threads with consecutive positions, and it counts positions along \(x\) first.
Definition 16.5 Warp. A warp is a group of 32 threads of a block with consecutive positions, counted along \(x\) first, that the hardware issues together: 1 instruction is fetched and executed for all 32 threads at once.
Example. In a block of 16 × 16 threads, threads \((0, 0)\) to \((0, 15)\) and \((1, 0)\) to \((1, 15)\) form warp 0.
Since \(x\) runs along the columns, the threads of a warp compute neighboring entries of a row of \(C\). For example, the 16 threads \((0, 0)\) to \((0, 15)\) of warp 0 compute 16 neighboring entries of 1 row of \(C\). At each step of the dot product, these threads read the same entry of \(A\) and 16 neighboring entries of a row of \(B\), which lie next to each other in memory by Definition 16.2. The memory delivers such neighboring values together, in 1 transaction. In Section 9.3, we measured the opposite choice, with \(x\) along the rows, and found it to be 5.4 times slower.
3 dimensions. For data in a volume, such as temperatures on a 3-dimensional mesh, we add the axis \(z\) and reason in the same way along each of the 3 axes. Along \(x\), a thread has the position
\[ x = \mathsf{blockIdx{.}x} \cdot \mathsf{blockDim{.}x} + \mathsf{threadIdx{.}x}, \]
and the positions \(y\) and \(z\) are computed in the same way from the components \(y\) and \(z\) of the 3 values. Figure 16.7 covers a 4 × 2 × 4 volume with 4 blocks of 2 × 2 × 2 threads. Here, we write positions in the order \((x, y, z)\). Thread \((1, 0, 0)\) of block \((1, 0, 1)\) lies at \(x = 1 \cdot 2 + 1 = 3\), \(y = 0 \cdot 2 + 0 = 0\) and \(z = 1 \cdot 2 + 0 = 2\).
| Symbol | Meaning | Thread \((1, 0, 0)\) of block \((1, 0, 1)\), along \(x\) |
|---|---|---|
| \(\mathsf{blockIdx{.}x}\) | position of the block along \(x\) | 1 |
| \(\mathsf{blockDim{.}x}\) | number of threads in a block along \(x\) | 2 |
| \(\mathsf{threadIdx{.}x}\) | position of the thread within its block along \(x\) | 1 |
| \(x\) | position of the thread in the volume along \(x\) | \(1 \cdot 2 + 1 = 3\) |
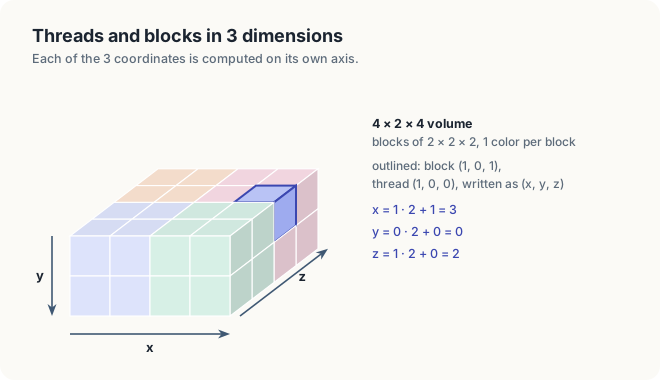
When we launch a kernel, we give the size of the grid and the size of a block, each as a triple \((x, y, z)\). For the matrix product, we use a grid of \((\lceil N/\mathsf{blockDim{.}x} \rceil, \lceil M/\mathsf{blockDim{.}y} \rceil, 1)\) blocks. The notation \(\lceil N/\mathsf{blockDim{.}x} \rceil\) denotes the quotient rounded up to the next integer. The grid needs \(\lceil N/\mathsf{blockDim{.}x} \rceil\) blocks along \(x\) to cover the \(N\) columns of \(C\), and \(\lceil M/\mathsf{blockDim{.}y} \rceil\) blocks along \(y\) to cover its \(M\) rows. In our example, \(N = M = 4\) and the blocks are 2 × 2, so the grid has \(\lceil 4/2 \rceil = 2\) blocks along each axis, as in Figure 16.5. The rounding up matters when the block width does not divide the size of the matrix. For example, with \(N = 1{,}000\) and blocks of 16 × 16 threads, the quotient is \(1{,}000 / 16 = 62.5\), so the grid needs 63 blocks along \(x\). These 63 blocks cover \(63 \cdot 16 = 1{,}008\) columns, and the last block therefore has 8 threads in each of its rows that lie past the last column of \(C\).
16.3.3 Scheduling and scope
The device executes blocks on processors of its own, which are called streaming multiprocessors.
Definition 16.6 Streaming multiprocessor. A streaming multiprocessor (SM) is 1 of the processors of a GPU. It contains arithmetic units, registers and shared memory, and it runs whole blocks: at launch, each block is assigned to 1 SM and stays there until it finishes.
Example. The Jetson Orin NX has 8 SMs, and the Jetson AGX Thor has 20.
An SM can hold several blocks at once. If the grid has more blocks than the SMs can hold, the remaining blocks wait, and they run in later waves, as shown in Figure 16.8. In the figure, 2 SMs hold 2 blocks each, so 4 of the 8 blocks run in the first wave and the other 4 in the second. The GPU runs blocks in no guaranteed order. Therefore, a correct kernel must never depend on the order in which its blocks run.
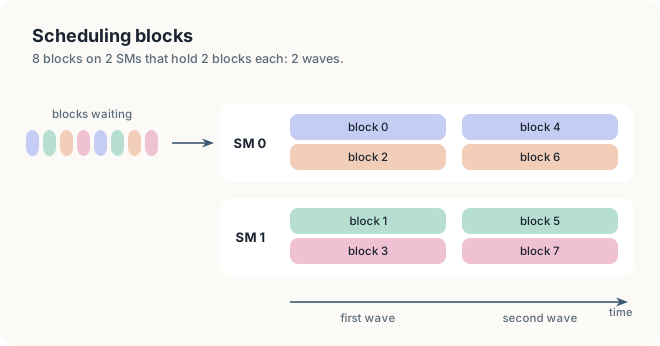
The block is also the unit of cooperation between threads. Threads in the same block share a region of shared memory and can wait for one another at a barrier, which we define in Chapter 17. Threads in different blocks can do neither, and they can exchange data only through global memory, as shown in Figure 16.9. The direct kernel of this chapter needs no cooperation at all, since every thread works alone. The tiled kernel of Chapter 17, in contrast, depends on it.
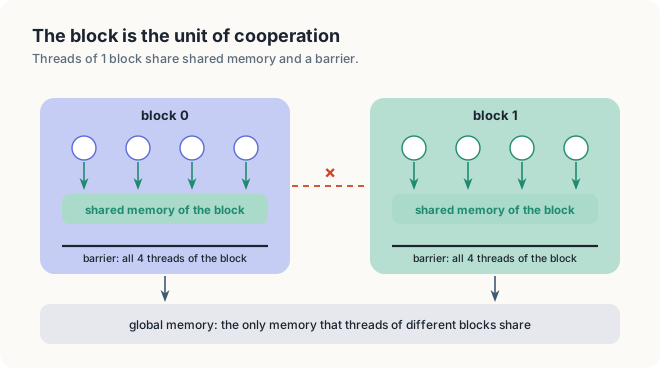
16.3.4 Memories of the device
To compute \(c_{12}\), a thread needs row 1 of \(A\) and column 2 of \(B\). How long the thread waits for these values depends on where they are stored, so we now describe the memories inside the device, which are shown in Figure 16.10.
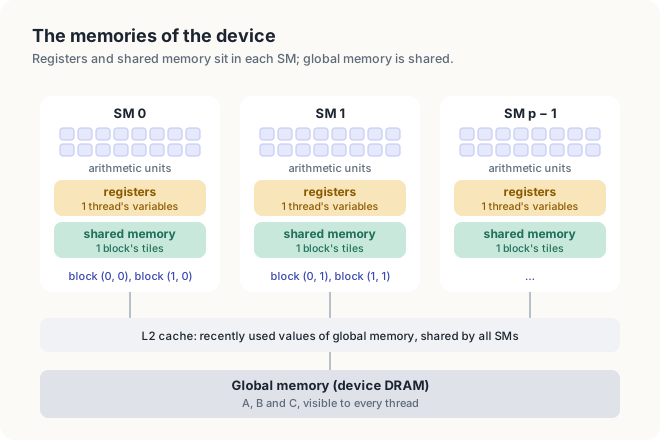
Definition 16.7 Registers, shared memory, global memory. Registers hold the variables of a single thread and respond in about 1 cycle. Shared memory belongs to a block. Every thread of the block can read and write it, no other thread can, it responds within a few cycles, and values enter it only when threads of the block store them there. Global memory is visible to every thread, holds gigabytes, and takes several hundred cycles to respond. Between the SMs and global memory sits the L2 cache, which keeps recently used values of global memory; the program has no control over its contents. Each SM also has a smaller L1 cache of its own.
Example. In the direct kernel, the variable sum lives in a register, and \(A\), \(B\) and
\(C\) live in global memory. The tiled kernel of Chapter 17 adds tiles in shared memory.
| Storage | Visible to | Latency | Capacity |
|---|---|---|---|
| Registers | 1 thread | about 1 cycle | 65,536 values of 4 bytes per SM |
| Shared memory | 1 block | a few cycles | 48 to 228 KB per SM |
| L2 cache | all SMs | tens to 100 cycles | a few MB to tens of MB |
| Global memory | all threads | hundreds of cycles | gigabytes |
The table suggests a strategy. Arithmetic and registers are cheap, whereas global memory is expensive, since a read from it takes hundreds of cycles. A fast kernel therefore fetches each value from global memory as few times as possible, and it takes its operands from storage closer to the arithmetic units whenever it can. The direct kernel of the next section does not yet do this, and we will count what that costs.
Exercises
16.7 Which entry of \(C\) does thread \((0, 1)\) of block \((1, 1)\) compute in Figure 16.5?
16.8 With blocks of 16 × 16 threads, how many blocks cover a 1,000 × 1,000 matrix \(C\)? How many threads
in the edge blocks have no entry to compute?
16.9 A grid has 132 blocks, and the device has 66 SMs that each hold 1 block at a time. How many
waves are needed?
16.4 The direct kernel
16.4.1 The algorithm
We obtain the simplest GPU kernel from Matrix-Multiply by removing its 2 outer loops. In the sequential algorithm, these loops chose the entry \(c_{ij}\) to compute. In the kernel, there is one thread for every entry of \(C\), and the position of a thread in the grid takes the place of the 2 outer loops. The thread computes the entry \(c_{\mathsf{row}, \mathsf{col}}\), whose row and column come from the formulas of Section 16.3.2. Every thread executes the following procedure.
Direct-Kernel(\(A, B, C, M, K, N\))
- \(\mathsf{row} = \mathsf{blockIdx{.}y} \cdot \mathsf{blockDim{.}y} + \mathsf{threadIdx{.}y}\)
- \(\mathsf{col} = \mathsf{blockIdx{.}x} \cdot \mathsf{blockDim{.}x} + \mathsf{threadIdx{.}x}\)
- if \(\mathsf{row} \notin [0, M)\) or \(\mathsf{col} \notin [0, N)\) { // thread lies outside C
- return
- }
- \(\mathsf{sum} = 0\)
- for \(\mathsf{inner} \in [0, K)\) {
- \(\mathsf{sum} = \mathsf{sum} + a_{\mathsf{row}, \mathsf{inner}} \cdot b_{\mathsf{inner}, \mathsf{col}}\) // 2 reads from global memory
- }
- \(c_{\mathsf{row}, \mathsf{col}} = \mathsf{sum}\)
Lines 1 and 2 compute the position of the thread’s entry with the formulas of Section 16.3.2. Lines 3 to 5 end the thread at once if its entry lies outside \(C\), which happens when the size of the matrix is not a multiple of the block width. Lines 6 to 9 are the inner loop of Matrix-Multiply, with the partial sum kept in the variable \(\mathsf{sum}\), which lives in a register. Line 10 stores the result in global memory. We let every thread write a different entry of \(C\), and every thread reads only \(A\) and \(B\), which no thread writes. Therefore, the threads never interfere with one another. In Figure 16.11, we follow a single thread through its work.
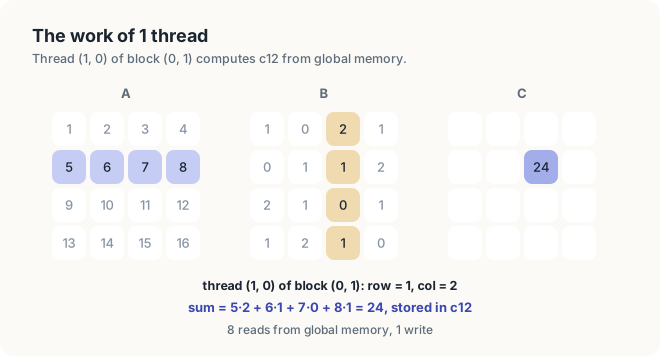
The thread is thread \((1, 0)\) of block \((0, 1)\), in blocks of 2 × 2 threads. Lines 1 and 2 give \(\mathsf{row} = 0 \cdot 2 + 1 = 1\) and \(\mathsf{col} = 1 \cdot 2 + 0 = 2\). Both values lie inside \(C\), so the test of line 3 fails and the thread continues. The loop runs for \(\mathsf{inner} = 0, 1, 2, 3\). In the pass with \(\mathsf{inner} = 0\), line 8 reads \(a_{10} = 5\) and \(b_{02} = 2\) and adds their product, 10, to \(\mathsf{sum}\). The remaining 3 passes add \(6 \cdot 1\), \(7 \cdot 0\) and \(8 \cdot 1\), so that \(\mathsf{sum}\) ends at \(5 \cdot 2 + 6 \cdot 1 + 7 \cdot 0 + 8 \cdot 1 = 24\), and line 10 stores 24 in \(c_{12}\). Each pass of line 8 fetches 1 value of \(A\) and 1 value of \(B\) from global memory, so the thread makes \(4 \cdot 2 = 8\) fetches and 1 write.
16.4.2 Correctness
The direct kernel needs only a short argument. Fix a thread with \(\mathsf{row} \in [0, M)\) and
\(\mathsf{col} \in [0, N)\). We claim that before the pass of line 8 with index \(\mathsf{inner}\), the
variable sum holds the first \(\mathsf{inner}\) terms of the dot product, that is,
\[ \mathsf{sum} = \sum_{j \in [0, \mathsf{inner})} a_{\mathsf{row}, j}\, b_{j, \mathsf{col}}. \]
Here \(j\) runs over the terms that have already been added, from 0 to \(\mathsf{inner} - 1\). For
example, for thread \((1, 0)\) of block \((0, 1)\), before the pass with \(\mathsf{inner} = 2\), sum
holds \(a_{10}\, b_{02} + a_{11}\, b_{12} = 5 \cdot 2 + 6 \cdot 1 = 16\). The claim holds for
\(\mathsf{inner} = 0\), where the sum is empty and sum is 0 by line 6, and each pass of line 8 adds the
next term, so the claim holds before every pass. When the loop ends, \(\mathsf{inner} = K\), and sum holds
all \(K\) terms, which is \(c_{\mathsf{row}, \mathsf{col}}\) by Definition 16.1. Finally, no
other thread has the same \((\mathsf{row}, \mathsf{col})\), because any 2 threads differ either
in their block or in their position within it. Therefore, no other thread writes that entry.
The only part of the kernel that requires care is the guard of lines 3 to 5. Without the guard, a thread past the last column computes an index \(\mathsf{row} \cdot N + \mathsf{col}\) that lands in the next row. For example, with \(N = 1{,}000\), the thread with \(\mathsf{row} = 0\) and \(\mathsf{col} = 1{,}000\) would write location 1,000, which holds the entry in row 1 and column 0. A thread past the last row writes beyond the end of \(C\). To observe this, we removed lines 3 to 5 from the C++ kernel and ran it on matrices of 1,000 × 1,000. A grid of 63 × 63 blocks of 16 × 16 threads covers 1,008 rows and 1,008 columns, so it overhangs the matrices by 8 rows and 8 columns. The program reported the following error.
kernel: an illegal memory access was encountered
The threads in the 8 extra rows read past the end of \(A\) and wrote past the end of \(C\), and the GPU stopped the kernel. A smaller overhang can stay inside memory that the program owns. In that case, the kernel finishes, and the error shows only in the values of \(C\). In Section 16.5.6, we make the same change in Rust, where the outcome is different.
16.4.3 Counting the fetches
The kernel is correct, but it reads far more from global memory than it needs to. Consider the value \(a_{01} = 2\), which lies in row 0 of \(A\). All 4 entries of row 0 of \(C\), namely \(c_{00}\), \(c_{01}\), \(c_{02}\) and \(c_{03}\), are computed from row 0 of \(A\), so 4 threads need \(a_{01}\). In the direct kernel, each of these 4 threads fetches \(a_{01}\) from global memory on its own, as shown in Figure 16.12.
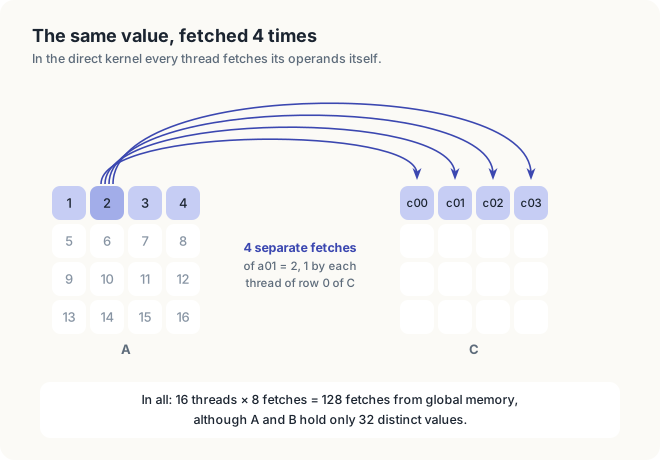
The same holds for every value. Each entry of \(A\) is fetched by the 4 threads that compute its row of \(C\), and each entry of \(B\) is fetched by the 4 threads that compute its column of \(C\). For example, \(b_{21} = 1\) is fetched by the threads that compute \(c_{01}\), \(c_{11}\), \(c_{21}\) and \(c_{31}\). In total, 16 threads each fetch 4 values of \(A\) and 4 values of \(B\), which makes 128 fetches, although the 2 matrices hold only 32 distinct values.
In general, the kernel runs one thread for each of the \(MN\) entries of \(C\), and each thread makes \(2K\) fetches, \(K\) from its row of \(A\) and \(K\) from its column of \(B\). The direct kernel therefore performs \(MN \cdot 2K = 2MNK\) fetches, which is 1 fetch for every FLOP. In our example, \(MN = 16\) threads each make \(2K = 8\) fetches, which gives the 128 fetches counted above. Each entry of \(A\) is fetched \(N\) times, once by each of the \(N\) threads of its row of \(C\), and each entry of \(B\) is fetched \(M\) times.
For realistic sizes, these numbers become large. For 2 matrices of 1,024 × 1,024 floats of 4 bytes each, the kernel makes \(2 \cdot 1{,}024^3 = 2.1 \times 10^9\) fetches, or 8.6 GB of traffic, to read only 8.4 MB of input. Every value is fetched 1,024 times, and each fetch that reaches global memory costs hundreds of cycles. The ratio of work to traffic is 2 FLOP for every 2 floats fetched, that is, 1 FLOP per float. Recall from Section 9.1.3 that a GPU needs about 100 FLOP per float fetched from memory to keep its arithmetic units busy, namely 94 on the Orin NX and 119 on the Thor.
Key observation The 4 threads computing row 0 of \(C\) all need the same value \(a_{01}\). If these threads belong to the same block, one of them can copy \(a_{01}\) into shared memory, and the other 3 can take it from there.
In Chapter 17, we turn this observation into the tiled kernel. In the rest of this chapter, we implement the direct kernel and measure how much its repeated fetches cost.
Exercises
16.10 Which threads need \(b_{21}\)? How many times does the direct kernel fetch it?
16.11 For \(M = N = K = 2{,}048\), how many times does the direct kernel fetch each entry of
\(A\), and how many bytes does it fetch in all?
16.12 For \(M = 3\), \(K = 3\), \(N = 3\) and blocks of 2 × 2 threads, how many threads
does the grid hold, and how many of them return at line 4?
16.5 Implementation
We now turn the direct kernel into code. Both languages express the same procedure, and they differ mainly in what the compiler checks. In each listing below, the Rust version is shown in the first tab and the C++ version in the second.
16.5.1 The kernel
In cuda-oxide, a kernel is an ordinary Rust function marked #[kernel], placed inside a module
marked #[cuda_module]. The compiler turns the module into GPU code, and for each kernel, it
generates host-side methods that prepare and launch it. In CUDA C++, a kernel is a function
marked __global__. The following code shows the kernel matmul in both languages.
mod kernels {
// ...
/// C (m x n) = A (m x k) B (k x n), all row-major. 1 thread computes 1 entry of C.
/// The width of `c` is bound on the host with `RowWidth`.
#[kernel]
#[launch_bounds(256)]
#[launch_contract(
domain = 2,
coordinates = u32,
requires = (a.len() >= m * k, b.len() >= k * n, c.len() >= m * n)
)]
pub fn matmul<T>(
m: u32,
n: u32,
k: u32,
a: &[T],
b: &[T],
mut c: DisjointSlice<T, Runtime2DIndex>,
) where
T: Copy + Default + Add<Output = T> + Mul<Output = T>,
{
let row = thread::index_2d_row();
let col = thread::index_2d_col();
let (m, n, k) = (m as usize, n as usize, k as usize);
if row < m
&& col < n
&& let Some(idx) = thread::index_2d_runtime(&c)
&& let Some(out) = c.get_mut(idx)
{
let mut sum = T::default();
let mut inner = 0;
#[unroll(4)]
while inner < k {
sum = sum + a[row * k + inner] * b[inner * n + col];
inner += 1;
}
*out = sum;
}
}
// ...
}// C (m x n) = A (m x k) B (k x n), all row-major. 1 thread computes 1 entry of C.
template <typename T>
__global__ void matmul(int m, int n, int k, const T* a, const T* b, T* c)
{
int row = blockIdx.y * blockDim.y + threadIdx.y;
int col = blockIdx.x * blockDim.x + threadIdx.x;
if (row >= m || col >= n) {
return;
}
T sum = 0;
for (int inner = 0; inner < k; ++inner) {
sum += a[row * k + inner] * b[inner * n + col];
}
c[row * n + col] = sum;
}
Both kernels follow Direct-Kernel almost line for
line. In Rust, index_2d_row() and index_2d_col() compute lines 1 and 2 of the pseudocode, and in C++,
the 2 expressions with blockIdx compute the same lines. The
test of row and col corresponds to lines 3 to 5, and the loop over inner corresponds to lines 7
to 9. Every index follows Definition 16.2. The expression a[row * k + inner] is
\(a_{\mathsf{row}, \mathsf{inner}}\) in a matrix of row width \(k\), and b[inner * n + col] is
\(b_{\mathsf{inner}, \mathsf{col}}\) in a matrix of row width \(n\). For example, for thread \((1, 0)\) of
block \((0, 1)\) with \(\mathsf{inner} = 0\), these are a[1 * 4 + 0], which is a[4] and holds 5, and
b[0 * 4 + 2], which is b[2] and holds 2.
The Rust kernel receives the sizes as u32, which is the type of a launch argument, and converts
them to usize once, so that all index arithmetic uses 1 type. Its loop is a while loop marked
#[unroll(4)]. Recall from Section 9.7 that cuda-oxide unrolls a while loop marked #[unroll],
but does not unroll a for loop over a range.
16.5.2 The output slice
The two kernels differ in how they write \(C\). The C++ kernel receives a raw pointer T* c and
stores to c[row * n + col]. Nothing in the language prevents 2 threads from storing to the same
address, or a thread from storing past the end of the matrix. In Rust, a kernel that took
&mut [T] would allow every thread to write anywhere in \(C\), and nothing would prevent 2
threads from writing the same element at the same time.
Definition 16.8 Data race. A data race occurs when 2 threads access the same memory location, at least one of them writes it, and nothing orders the 2 accesses. The value that results depends on the timing of the threads.
Example. If thread \((0, 0)\) and thread \((0, 1)\) both stored their sums to \(c_{00}\), the entry would hold 11 or 13, depending on which store came last.
For this reason, cuda-oxide gives the output the type DisjointSlice<T, IndexSpace>. A thread
can write an element of such a slice only through a witness. A witness is a value of type
ThreadIndex that names the element the thread owns; it is computed from the thread’s own
coordinates, and only the thread itself can obtain it. The second type parameter, the index
space, states how coordinates are turned into an element. The kernel matmul uses the index
space Runtime2DIndex, which works in 3 steps. First, the host binds the row width \(n\) to the
buffer with RowWidth::new(&mut c, n). Second, in the kernel, thread::index_2d_runtime(&c)
returns a witness that holds the thread’s row and column, or None if the column is not less
than the bound width. Third, c.get_mut(idx) returns a mutable reference to element
\(\mathsf{row} \cdot n + \mathsf{col}\), or None if that element lies past the end of c.
For example, with \(n = 4\), thread \((1, 0)\) of block \((0, 1)\) receives a witness for
row 1 and column 2, and get_mut gives it element \(1 \cdot 4 + 2 = 6\) of c, which is
\(c_{12}\).
The argument of Section 16.4.2 that no 2 threads write the same entry is now carried by the
types. Any 2 threads have different coordinates. For a fixed width \(n\) and columns less than
\(n\), different coordinates (row, col) give different elements
\(\mathsf{row} \cdot n + \mathsf{col}\), so 2 threads never hold the same element. As a result,
the kernel needs no unsafe block.
A second index space, Index2D<W>, makes the row width part of the type. The following code shows
the kernel matmul_fixed, which uses it to multiply matrices of FIXED × FIXED = 1,024 × 1,024
floats, together with the C++ template matmulFixed<W>, which multiplies \(W \times W\)
matrices.
mod kernels {
// ...
/// The same product for FIXED x FIXED matrices: the width is part of the type of `c`.
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (16, 16, 1))]
pub fn matmul_fixed(a: &[f32], b: &[f32], mut c: DisjointSlice<f32, Index2D<FIXED>>) {
let row = thread::index_2d_row();
let col = thread::index_2d_col();
if let Some(idx) = thread::index_2d::<FIXED>()
&& let Some(out) = c.get_mut(idx)
{
let mut sum = 0.0;
let mut inner = 0;
#[unroll(4)]
while inner < FIXED {
sum += a[row * FIXED + inner] * b[inner * FIXED + col];
inner += 1;
}
*out = sum;
}
}
}// The same product for W x W matrices, with the width W fixed at compile time.
template <int W>
__global__ void matmulFixed(const float* a, const float* b, float* c)
{
int row = blockIdx.y * blockDim.y + threadIdx.y;
int col = blockIdx.x * blockDim.x + threadIdx.x;
if (row >= W || col >= W) {
return;
}
float sum = 0.0f;
for (int inner = 0; inner < W; ++inner) {
sum += a[row * W + inner] * b[inner * W + col];
}
c[row * W + col] = sum;
}
In the Rust kernel, thread::index_2d::<FIXED>() computes
\(\mathsf{row} \cdot 1{,}024 + \mathsf{col}\) and returns it as a witness of type
ThreadIndex<Index2D<1024>>. The method get_mut of a DisjointSlice<f32, Index2D<1024>>
accepts only a witness of this type. A witness made for another width has another type, and
passing it to this slice is a compile error. The C++ template matmulFixed<W> also has the width
as a compile-time constant, but it does not have the check, because the index expression is
written by hand, and a wrong width in it still compiles. In both languages, the price of a
compile-time width is 1 compiled kernel per matrix size.
16.5.3 The launch contract
The attribute #[launch_contract] states the conditions under which a launch of the kernel is
correct, and cuda-oxide checks them on the host before the kernel starts. The contract of matmul
has three parts. The setting domain = 2 declares a 2-dimensional launch with \(z = 1\), which the
2-dimensional index space requires. The setting coordinates = u32 requires every coordinate of
the launch to fit in 32 bits. The attribute #[launch_bounds(256)], which accompanies the
contract, limits a block to 256 threads, so that the same kernel serves both the blocks of 2 × 2
threads of our example and the blocks of 16 × 16 threads of the measurements. Finally, the
requires clause adds 3 relations between the sizes and the lengths of the buffers. The relation
a.len() >= m * k, for example, states that the buffer a holds at least the \(MK\) values of
an \(M \times K\) matrix. The following code shows the contract in front of the Rust kernel, and
the C++ function violated, which tests the same 3 relations.
#[kernel]
#[launch_bounds(256)]
#[launch_contract(
domain = 2,
coordinates = u32,
requires = (a.len() >= m * k, b.len() >= k * n, c.len() >= m * n)
)]
pub fn matmul<T>(
m: u32,
n: u32,
k: u32,
a: &[T],
b: &[T],
mut c: DisjointSlice<T, Runtime2DIndex>,
) where
T: Copy + Default + Add<Output = T> + Mul<Output = T>,
{
// ...
}// The relation of the Rust launch contract that a launch of matmul
// would violate, or nullptr if there is none.
const char* violated(int m, int n, int k, size_t aLen, size_t bLen, size_t cLen)
{
if (aLen < size_t(m) * k) {
return "aLen >= m * k";
}
if (bLen < size_t(k) * n) {
return "bLen >= k * n";
}
if (cLen < size_t(m) * n) {
return "cLen >= m * n";
}
return nullptr;
}
In C++, we write the 3 relations ourselves, in the host function violated, and call it before a
launch. In this way, the C++ program rejects the same launches as the launch contract does in Rust.
In Rust, the host prepares a launch once with module.prepare_matmul::<T>(config), which checks
the grid and block shapes against the contract and against the limits of the GPU. It then
launches the kernel with module.matmul(stream, &prepared, m, n, k, &a, &b, width), which
evaluates the 3 relations with the actual lengths and sizes. To show the check at work, the
program deliberately launches matmul once with buffers of 256 × 256 floats and \(k = 512\).
The buffer a then holds \(256 \cdot 256 = 65{,}536\) values, while an \(m \times k\) matrix
needs \(256 \cdot 512 = 131{,}072\). The relation \(a.\text{len}() \ge mk\) therefore becomes
\(65{,}536 \ge 131{,}072\), which is false, and no kernel runs. The program prints the
following line.
k = 2 n refused before launch: matmul: size requirement `a.len() >= m * k` violated: left-hand side is 65536, right-hand side is 131072
The C++ launch matmul<T><<<grid, block>>>(m, n, k, a, b, c) has no such check. With the same
mistake, each thread would read row row of a matrix twice as wide as a, and the threads of the
lower half of the grid would read beyond the end of a.
The following code shows how the host computes the launch configuration and launches the kernel for an \(n \times n\) product in each language.
/// A grid of side x side blocks that covers an m x n matrix C.
fn config(m: usize, n: usize, side: u32) -> LaunchConfig2D {
let grid = ((n as u32).div_ceil(side), (m as u32).div_ceil(side));
LaunchConfig2D::new(grid, (side, side), 0)
}
fn run_generic<T>(
module: &Module,
stream: &Arc<CudaStream>,
name: &str,
n: usize,
) -> Result<bool, Error>
where
T: DeviceCopy + Copy + Default + Add<Output = T> + Mul<Output = T>,
T: From<f32> + Into<f64>,
{
// ...
let side = n as u32;
let prepared = module.prepare_matmul::<T>(config(n, n, 16))?;
let mut launch = || {
let width = RowWidth::new(&mut c, side);
Ok(module.matmul(stream, &prepared, side, side, side, &a, &b, width)?)
};
let ms = time_ms(stream, runs_for(n), &mut launch)?;
// ...
}// A grid of side x side blocks that covers an m x n matrix C.
dim3 gridFor(int m, int n, int side)
{
return dim3((n + side - 1) / side, (m + side - 1) / side);
}
template <typename T>
bool runGeneric(const char* name, int n)
{
dim3 grid = gridFor(n, n, 16);
dim3 block(16, 16);
auto launch = [=](const T* a, const T* b, T* c) {
matmul<T><<<grid, block>>>(n, n, n, a, b, c);
};
return runSize<T>(name, n, launch);
}
The function config computes the grid of Section 16.3.2, with \(\lceil n / \mathsf{side} \rceil\) blocks
along \(x\) and \(\lceil m / \mathsf{side} \rceil\) blocks along \(y\), where \(\mathsf{side}\) is the number of threads along each side of a block. The method div_ceil performs
the division rounded up. For example, config(1000, 1000, 16) gives a grid of 63 × 63 blocks. The
C++ function gridFor computes the same grid with the expression \((n + \mathsf{side} - 1) / \mathsf{side}\). The Rust
closure creates a new RowWidth for every launch, because a RowWidth holds the mutable borrow
of c for the duration of 1 launch. The function time_ms launches the kernel once without
timing it, and then it averages runs launches between 2 synchronizations of the stream.
16.5.4 One kernel for f32 and f64
Both kernels are written once for any element type. In C++, template <typename T> accepts any
type, and the compiler reports an error only if the body of the kernel uses an operation that the
type lacks. In Rust, the kernel states in a trait bound which operations it needs from \(T\).
The following code shows the signature of matmul in each language, with the bound in Rust and
the template header in C++.
pub fn matmul<T>(
m: u32,
n: u32,
k: u32,
a: &[T],
b: &[T],
mut c: DisjointSlice<T, Runtime2DIndex>,
) where
T: Copy + Default + Add<Output = T> + Mul<Output = T>,
{
// ...
}template <typename T>
__global__ void matmul(int m, int n, int k, const T* a, const T* b, T* c)
{
// ...
}
The bound lists exactly the operations that the kernel performs, namely copying values
(Copy), creating the initial 0 with T::default() (Default), adding (Add), and multiplying
(Mul). A type that lacks one of them is refused at the call, and the error message names the
missing trait. cuda-oxide compiles 1 GPU function for each type with which the host prepares the
kernel, here prepare_matmul::<f32> and prepare_matmul::<f64>. The 2 versions perform the same
number of operations. However, an f64 occupies 8 bytes instead of 4, and a GPU has separate
units for 64-bit arithmetic, whose number differs widely between GPU models.
16.5.5 Exact verification
Both programs fill \(A\) and \(B\) with integers in \([-5, 5]\) from the same linear congruential generator. Every product of 2 such integers is then at most 25 in magnitude, and every partial sum is at most \(25K\) in magnitude, which is \(102{,}400\) for \(K = 4{,}096\). Single-precision floating point represents every integer up to \(2^{24} = 16{,}777{,}216\) exactly. Therefore, each multiply-add is exact, the GPU and the CPU must produce identical results in whatever order they add the products, and any difference signals a bug. The programs compare 64 sampled entries of \(C\) with a product computed on the CPU, and they require all 64 to be equal. They also run the 4 × 4 example with blocks of 2 × 2 threads, print \(C\), and compare it with the product computed by hand in Section 16.1.
16.5.6 Removing the guard in Rust
In Section 16.4.2, we removed lines 3 to 5 from the C++ kernel, and the kernel faulted. In the
Rust kernel, the guard is the condition row < m && col < n in front of the 2 let patterns. We
removed this condition and ran the kernel on matrices of 1,000 × 1,000, comparing all 1,000,000
entries with the CPU. The program printed the following line.
no guard, n = 1000: 0 of 1000000 entries wrong
The result is correct. A thread past the last column receives None from index_2d_runtime, a
thread past the last row receives None from get_mut, and in both cases, the thread skips the
loop and the write. The test of the witness therefore acts as a second guard. The explicit guard
is nevertheless still needed, because the width bound to c and the length of c are chosen by
the host, and nothing forces them to equal \(n\) and \(mn\). If the host bound a larger
buffer, a thread in row \(m\) would receive an element of c and would then read row \(m\) of
a, which does not exist. That read is bounds-checked, so the kernel would stop with an error
rather than read another buffer. The guard, however, ties the reads to the sizes of a and b,
and it prevents the kernel from failing at all.
Exercises
16.13 Change the Rust launch to blocks of 32 × 8 threads. Which lines must change, and does the
contract accept the new shape?
16.14 Write matmul::<i32> launches for the 4 × 4 example. Is the result exact? Which trait
bound does i32 satisfy that a type such as bool does not?
16.15 In the C++ kernel, exchange blockIdx.x and blockIdx.y in the computation of row and
col but not in the grid. For which matrix shapes is the result still correct?
16.6 Measurements
16.6.1 Platform and method
The measurements come from an integrated GPU, a Jetson Orin NX 16 GB, with 8 SMs, a memory bandwidth of 102 GB/s, and an FP32 peak of 2,400 GFLOP/s at 1.173 GHz. Each program first runs the GPU for 0.5 s so that its clocks reach their sustained values. It then launches each kernel once without timing it, and finally it averages up to 50 launches, fewer for the large sizes. Each program ran 3 times. The tables show the quietest run, and repeated runs differed by up to 10%.
16.6.2 Results
The Rust program prints the following output.
$ cargo oxide run
C = A B on the 4 x 4 example, a grid of 2 x 2 blocks of 2 x 2 threads
11 13 8 8
27 29 24 24
43 45 40 40
59 61 56 56
equal to the product computed by hand: yes
C = A B, n x n, 1 thread per entry of C, blocks of 16 x 16 threads
n type ms GFLOP/s fetched GB/s exact
512 f32 1.469 182.7 730.8 64 of 64
1024 f32 15.659 137.1 548.6 64 of 64
2048 f32 124.013 138.5 554.1 64 of 64
4096 f32 997.150 137.8 551.3 64 of 64
1024 f32 fixed 11.071 194.0 775.9 64 of 64
512 f64 7.641 35.1 281.0 64 of 64
1024 f64 61.076 35.2 281.3 64 of 64
2048 f64 488.370 35.2 281.4 64 of 64
k = 2 n refused before launch: matmul: size requirement `a.len() >= m * k` violated: left-hand side is 65536, right-hand side is 131072
PASSED
The first lines reproduce the product of Section 16.1, with \(c_{00} = 11\) and \(c_{01} = 13\). The C++ program prints the same example and the same table. The following table shows the times of the two programs side by side.
| n | type | C++ time | C++ rate | Rust time | Rust rate | requested fetches (C++) |
|---|---|---|---|---|---|---|
| 512 | f32 | 1.465 ms | 183.2 GFLOP/s | 1.469 ms | 182.7 GFLOP/s | 732.9 GB/s |
| 1,024 | f32 | 11.803 ms | 181.9 GFLOP/s | 15.659 ms | 137.1 GFLOP/s | 727.8 GB/s |
| 2,048 | f32 | 93.828 ms | 183.1 GFLOP/s | 124.013 ms | 138.5 GFLOP/s | 732.4 GB/s |
| 4,096 | f32 | 743.091 ms | 185.0 GFLOP/s | 997.150 ms | 137.8 GFLOP/s | 739.8 GB/s |
| 1,024 | f32, fixed width | 11.493 ms | 186.9 GFLOP/s | 11.071 ms | 194.0 GFLOP/s | 747.4 GB/s |
| 512 | f64 | 7.588 ms | 35.4 GFLOP/s | 7.641 ms | 35.1 GFLOP/s | 283.0 GB/s |
| 1,024 | f64 | 61.045 ms | 35.2 GFLOP/s | 61.076 ms | 35.2 GFLOP/s | 281.4 GB/s |
| 2,048 | f64 | 487.566 ms | 35.2 GFLOP/s | 488.370 ms | 35.2 GFLOP/s | 281.9 GB/s |
The rate counts \(2n^3\) FLOP for each product. For example, for \(n = 4{,}096\), the kernel performs \(2 \cdot 4{,}096^3 = 1.37 \times 10^{11}\) FLOP in the time shown. The column fetched GB/s divides the bytes that the kernel requests, \(2n^3\) values of 4 or 8 bytes each, by the time. All 64 sampled entries were exact in every run, in single and in double precision.
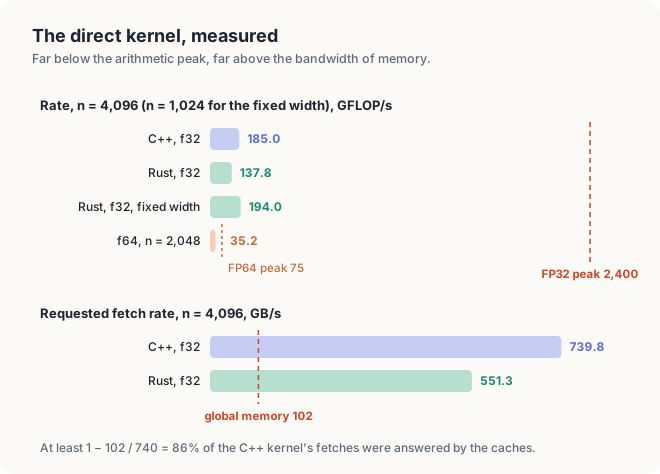
16.6.3 Why the rate is far below the peak
The C++ kernel ran at 185.0 GFLOP/s for \(n = 4{,}096\), which is 7.7% of the FP32 peak of 2,400 GFLOP/s. In other words, the arithmetic units were idle more than 92% of the time. The reason is the one we found in Section 16.4.3, where we saw that the kernel fetches 1 float for every FLOP. If every fetch went to global memory, the 102 GB/s of the measured GPU would deliver \(102 / 4 = 25.5 \times 10^9\) floats per second, and the kernel could therefore perform at most 25.5 GFLOP/s.
The measured rate is 7.3 times this limit, and the fetch column of the table explains how. The kernel requested \(2 \cdot 4{,}096^3 \cdot 4\) bytes, or 550 GB, in 0.743 s, which is 739.8 GB/s, 7.3 times what global memory can deliver. Since global memory delivers at most 102 GB/s, at least \(1 - 102/740 = 86\%\) of the requested fetches must have been answered by the L1 and L2 caches. The repeated fetches of Figure 16.12 happen close together in time. The 16 threads of a warp that share a row of \(C\) request the same value of \(A\) in the same instruction, and the hardware delivers that value once to all of them. In addition, neighboring blocks request the same rows and columns shortly after one another. The caches therefore recover much of the reuse, but only because the requests happen to be close in time, and the kernel spends the remaining time waiting for memory. The kernel is thus limited by how fast the memory system delivers operands, not by the arithmetic.
The f64 kernel ran at 35.2 GFLOP/s. The measured GPU reports a ratio of 32 between its FP32 and
FP64 rates, so its FP64 peak is \(2{,}400 / 32 = 75\) GFLOP/s, and the f64 kernel reached 47%
of that peak, compared with 7.7% for f32. Its operands are twice as large, and it requested
282 GB/s, but on this GPU, the small number of FP64 units, not the memory, sets its speed. On a
data-center GPU with an FP32:FP64 ratio of 2, the f64 kernel would be limited by memory, like
the f32 kernel.
The two languages agree at 512 × 512 and in double precision. From 1,024 × 1,024 upwards, however,
the generic Rust kernel, whose sizes are known only at run time, ran at 138 GFLOP/s, compared with
182 to 185 GFLOP/s in C++. The Rust kernel with the width in its type ran at 194.0 GFLOP/s, the
fastest of all. Both Rust kernels read the same values in the same order, and they differ only in
what the compiler knows. When \(n\) and \(k\) are constants, the loop has a fixed trip count,
which is a multiple of 4, and the addresses of consecutive reads of b lie a constant 4,096 bytes
apart. When the sizes are known only at run time, the compiler must handle a possible remainder of
the unrolled loop and recompute every address. A width in the type costs 1 compiled kernel per
matrix size, and in Chapter 17, we recover more speed for every size by tiling.
The measured rates also show which factors do not matter. The block shape of 16 × 16 threads keeps the reads of a warp contiguous, and the rates are almost the same at every size from 512 to 4,096. Once the matrices exceed the caches, every size waits for memory in the same proportion. The remedy is therefore to fetch less often from global memory, which is what the key observation of Section 16.4.3 proposes.
16.7 The complete programs
The following code shows the complete Rust program and the complete C++ program.
//! Chapter 16: matrix multiplication in Rust, 1 thread per entry of C.
//!
//! cargo oxide run
use std::ops::{Add, Mul};
use std::sync::Arc;
use std::time::Instant;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, DeviceCopy, LaunchConfig2D};
use cuda_device::thread::{Index2D, Runtime2DIndex};
use cuda_device::{DisjointSlice, cuda_module, kernel, thread};
use cuda_device::{launch_bounds, launch_contract};
use cuda_host::RowWidth;
const FIXED: usize = 1024; // the width of C in the kernel with a compile-time width
type Error = Box<dyn std::error::Error>;
type Module = kernels::LoadedModule;
#[cuda_module]
mod kernels {
use super::*;
/// C (m x n) = A (m x k) B (k x n), all row-major. 1 thread computes 1 entry of C.
/// The width of `c` is bound on the host with `RowWidth`.
#[kernel]
#[launch_bounds(256)]
#[launch_contract(
domain = 2,
coordinates = u32,
requires = (a.len() >= m * k, b.len() >= k * n, c.len() >= m * n)
)]
pub fn matmul<T>(
m: u32,
n: u32,
k: u32,
a: &[T],
b: &[T],
mut c: DisjointSlice<T, Runtime2DIndex>,
) where
T: Copy + Default + Add<Output = T> + Mul<Output = T>,
{
let row = thread::index_2d_row();
let col = thread::index_2d_col();
let (m, n, k) = (m as usize, n as usize, k as usize);
if row < m
&& col < n
&& let Some(idx) = thread::index_2d_runtime(&c)
&& let Some(out) = c.get_mut(idx)
{
let mut sum = T::default();
let mut inner = 0;
#[unroll(4)]
while inner < k {
sum = sum + a[row * k + inner] * b[inner * n + col];
inner += 1;
}
*out = sum;
}
}
/// The same product for FIXED x FIXED matrices: the width is part of the type of `c`.
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (16, 16, 1))]
pub fn matmul_fixed(a: &[f32], b: &[f32], mut c: DisjointSlice<f32, Index2D<FIXED>>) {
let row = thread::index_2d_row();
let col = thread::index_2d_col();
if let Some(idx) = thread::index_2d::<FIXED>()
&& let Some(out) = c.get_mut(idx)
{
let mut sum = 0.0;
let mut inner = 0;
#[unroll(4)]
while inner < FIXED {
sum += a[row * FIXED + inner] * b[inner * FIXED + col];
inner += 1;
}
*out = sum;
}
}
}
/// Average time of `runs` launches in milliseconds, after 1 launch that is not timed.
fn time_ms<F>(stream: &CudaStream, runs: u32, mut launch: F) -> Result<f64, Error>
where
F: FnMut() -> Result<(), Error>,
{
launch()?;
stream.synchronize()?;
let start = Instant::now();
for _ in 0..runs {
launch()?;
}
stream.synchronize()?;
Ok(start.elapsed().as_secs_f64() * 1e3 / runs as f64)
}
/// Integers in [-5, 5] from a small linear congruential generator: every partial sum
/// of a product with k <= 4096 is an integer below 2^24, so f32 results are exact.
fn integers<T: From<f32>>(len: usize, state: &mut u32) -> Vec<T> {
let mut values = Vec::with_capacity(len);
for _ in 0..len {
*state = state.wrapping_mul(1_664_525).wrapping_add(1_013_904_223);
let x = ((*state >> 8) % 11) as f32 - 5.0;
values.push(T::from(x));
}
values
}
/// The number of 64 sampled entries of C that equal the exact product.
fn exact_entries<T: Copy + Into<f64>>(a: &[T], b: &[T], c: &[T], n: usize) -> usize {
let mut exact = 0;
for s in 0..64 {
let i = s * 977 % n;
let j = (s * 1231 + 7) % n;
let mut sum = 0.0;
for p in 0..n {
sum += a[i * n + p].into() * b[p * n + j].into();
}
let got: f64 = c[i * n + j].into();
if got == sum {
exact += 1;
}
}
exact
}
/// Launches that keep n^3 x runs near 2^33, so each size runs for a similar time.
fn runs_for(n: usize) -> u32 {
((1usize << 33) / (n * n * n)).clamp(1, 50) as u32
}
/// A grid of side x side blocks that covers an m x n matrix C.
fn config(m: usize, n: usize, side: u32) -> LaunchConfig2D {
let grid = ((n as u32).div_ceil(side), (m as u32).div_ceil(side));
LaunchConfig2D::new(grid, (side, side), 0)
}
/// The 4 x 4 example: blocks of 2 x 2 threads, printed, and compared with the hand result.
fn run_example(module: &Module, stream: &Arc<CudaStream>) -> Result<bool, Error> {
let a_int = [1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12, 13, 14, 15, 16];
let b_int = [1, 0, 2, 1, 0, 1, 1, 2, 2, 1, 0, 1, 1, 2, 1, 0];
let want = [11, 13, 8, 8, 27, 29, 24, 24, 43, 45, 40, 40, 59, 61, 56, 56];
let a_host: Vec<f32> = a_int.iter().map(|&x| x as f32).collect();
let b_host: Vec<f32> = b_int.iter().map(|&x| x as f32).collect();
let a = DeviceBuffer::from_host(stream, &a_host)?;
let b = DeviceBuffer::from_host(stream, &b_host)?;
let mut c = DeviceBuffer::<f32>::zeroed(stream, 16)?;
let prepared = module.prepare_matmul::<f32>(config(4, 4, 2))?;
let width = RowWidth::new(&mut c, 4);
module.matmul(stream, &prepared, 4, 4, 4, &a, &b, width)?;
let result = c.to_host_vec(stream)?;
println!("C = A B on the 4 x 4 example, a grid of 2 x 2 blocks of 2 x 2 threads");
for row in result.chunks(4) {
println!(" {:4} {:4} {:4} {:4}", row[0], row[1], row[2], row[3]);
}
let same = result.iter().zip(want).all(|(&got, w)| got == w as f32);
let answer = if same { "yes" } else { "no" };
println!("equal to the product computed by hand: {answer}\n");
Ok(same)
}
/// Print 1 line of the table for an n x n product of type T that took `ms` milliseconds.
fn report<T>(name: &str, n: usize, ms: f64, exact: usize) {
let flop = 2.0 * (n * n * n) as f64;
let gflops = flop / ms / 1e6;
let fetched = flop * size_of::<T>() as f64 / ms / 1e6;
println!(" {n:5} {name:<10} {ms:9.3} {gflops:9.1} {fetched:10.1} {exact:6} of 64");
}
/// Time matmul::<T> on n x n matrices, print a line, and return true if the check passed.
fn run_generic<T>(
module: &Module,
stream: &Arc<CudaStream>,
name: &str,
n: usize,
) -> Result<bool, Error>
where
T: DeviceCopy + Copy + Default + Add<Output = T> + Mul<Output = T>,
T: From<f32> + Into<f64>,
{
let mut state = 1;
let a_host: Vec<T> = integers(n * n, &mut state);
let b_host: Vec<T> = integers(n * n, &mut state);
let a = DeviceBuffer::from_host(stream, &a_host)?;
let b = DeviceBuffer::from_host(stream, &b_host)?;
let mut c = DeviceBuffer::<T>::zeroed(stream, n * n)?;
let side = n as u32;
let prepared = module.prepare_matmul::<T>(config(n, n, 16))?;
let mut launch = || {
let width = RowWidth::new(&mut c, side);
Ok(module.matmul(stream, &prepared, side, side, side, &a, &b, width)?)
};
let ms = time_ms(stream, runs_for(n), &mut launch)?;
let exact = exact_entries(&a_host, &b_host, &c.to_host_vec(stream)?, n);
report::<T>(name, n, ms, exact);
Ok(exact == 64)
}
/// The same for matmul_fixed, whose size is FIXED x FIXED.
fn run_fixed(module: &Module, stream: &Arc<CudaStream>) -> Result<bool, Error> {
let n = FIXED;
let mut state = 1;
let a_host: Vec<f32> = integers(n * n, &mut state);
let b_host: Vec<f32> = integers(n * n, &mut state);
let a = DeviceBuffer::from_host(stream, &a_host)?;
let b = DeviceBuffer::from_host(stream, &b_host)?;
let mut c = DeviceBuffer::<f32>::zeroed(stream, n * n)?;
let prepared = module.prepare_matmul_fixed(config(n, n, 16))?;
let mut launch = || Ok(module.matmul_fixed(stream, &prepared, &a, &b, &mut c)?);
let ms = time_ms(stream, runs_for(n), &mut launch)?;
let exact = exact_entries(&a_host, &b_host, &c.to_host_vec(stream)?, n);
report::<f32>("f32 fixed", n, ms, exact);
Ok(exact == 64)
}
/// A launch that claims k = 2 n for buffers of n x n: the contract refuses it.
fn launch_too_long_k(
module: &Module,
stream: &Arc<CudaStream>,
n: usize,
) -> Result<(), Error> {
let a = DeviceBuffer::<f32>::zeroed(stream, n * n)?;
let b = DeviceBuffer::<f32>::zeroed(stream, n * n)?;
let mut c = DeviceBuffer::<f32>::zeroed(stream, n * n)?;
let side = n as u32;
let prepared = module.prepare_matmul::<f32>(config(n, n, 16))?;
let width = RowWidth::new(&mut c, side);
module.matmul(stream, &prepared, side, side, 2 * side, &a, &b, width)?;
Ok(())
}
/// About 0.5 s of 1024 x 1024 products: the GPU raises its clocks under sustained load.
fn warm_up(module: &Module, stream: &Arc<CudaStream>) -> Result<(), Error> {
let n = 1024;
let a = DeviceBuffer::<f32>::zeroed(stream, n * n)?;
let b = DeviceBuffer::<f32>::zeroed(stream, n * n)?;
let mut c = DeviceBuffer::<f32>::zeroed(stream, n * n)?;
let side = n as u32;
let prepared = module.prepare_matmul::<f32>(config(n, n, 16))?;
let start = Instant::now();
while start.elapsed().as_millis() < 500 {
let width = RowWidth::new(&mut c, side);
module.matmul(stream, &prepared, side, side, side, &a, &b, width)?;
stream.synchronize()?;
}
Ok(())
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let mut passed = run_example(&module, &stream)?;
warm_up(&module, &stream)?;
println!("C = A B, n x n, 1 thread per entry of C, blocks of 16 x 16 threads");
println!(" n type ms GFLOP/s fetched GB/s exact");
for n in [512, 1024, 2048, 4096] {
passed &= run_generic::<f32>(&module, &stream, "f32", n)?;
}
passed &= run_fixed(&module, &stream)?;
for n in [512, 1024, 2048] {
passed &= run_generic::<f64>(&module, &stream, "f64", n)?;
}
match launch_too_long_k(&module, &stream, 256) {
Err(error) => println!("k = 2 n refused before launch: {error}"),
Ok(()) => passed = false,
}
println!("{}", if passed { "PASSED" } else { "FAILED" });
Ok(())
}// Chapter 16: matrix multiplication, 1 thread per entry of C.
// Build: nvcc -O3 -arch=native matmul_naive.cu -o matmul_naive
#include <chrono>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cuda_runtime.h>
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
// C (m x n) = A (m x k) B (k x n), all row-major. 1 thread computes 1 entry of C.
template <typename T>
__global__ void matmul(int m, int n, int k, const T* a, const T* b, T* c)
{
int row = blockIdx.y * blockDim.y + threadIdx.y;
int col = blockIdx.x * blockDim.x + threadIdx.x;
if (row >= m || col >= n) {
return;
}
T sum = 0;
for (int inner = 0; inner < k; ++inner) {
sum += a[row * k + inner] * b[inner * n + col];
}
c[row * n + col] = sum;
}
// The same product for W x W matrices, with the width W fixed at compile time.
template <int W>
__global__ void matmulFixed(const float* a, const float* b, float* c)
{
int row = blockIdx.y * blockDim.y + threadIdx.y;
int col = blockIdx.x * blockDim.x + threadIdx.x;
if (row >= W || col >= W) {
return;
}
float sum = 0.0f;
for (int inner = 0; inner < W; ++inner) {
sum += a[row * W + inner] * b[inner * W + col];
}
c[row * W + col] = sum;
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// Average time of `runs` launches in milliseconds, after 1 launch that is not timed.
template <typename F>
double timeMs(F launch, int runs)
{
launch();
check(cudaDeviceSynchronize());
double start = nowMs();
for (int r = 0; r < runs; ++r) {
launch();
}
check(cudaGetLastError());
check(cudaDeviceSynchronize());
return (nowMs() - start) / runs;
}
// Integers in [-5, 5] from a small linear congruential generator: every partial sum
// of a product with k <= 4096 is an integer below 2^24, so float results are exact.
template <typename T>
std::vector<T> integers(size_t len, unsigned* state)
{
std::vector<T> values(len);
for (size_t i = 0; i < len; ++i) {
*state = *state * 1664525u + 1013904223u;
values[i] = T(int((*state >> 8) % 11) - 5);
}
return values;
}
// The number of 64 sampled entries of C that equal the exact product.
template <typename T>
int exactEntries(const std::vector<T>& a, const std::vector<T>& b,
const std::vector<T>& c, int n)
{
int exact = 0;
for (int s = 0; s < 64; ++s) {
int i = s * 977 % n;
int j = (s * 1231 + 7) % n;
double sum = 0.0;
for (int p = 0; p < n; ++p) {
sum += double(a[i * n + p]) * double(b[p * n + j]);
}
exact += double(c[i * n + j]) == sum;
}
return exact;
}
// Launches that keep n^3 x runs near 2^33, so each size runs for a similar time.
int runsFor(int n)
{
double runs = double(1ull << 33) / (double(n) * n * n);
return runs < 1 ? 1 : (runs > 50 ? 50 : int(runs));
}
// A grid of side x side blocks that covers an m x n matrix C.
dim3 gridFor(int m, int n, int side)
{
return dim3((n + side - 1) / side, (m + side - 1) / side);
}
// The 4 x 4 example with blocks of 2 x 2 threads, compared with the hand result.
bool runExample()
{
std::vector<float> a{1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12, 13, 14, 15, 16};
std::vector<float> b{1, 0, 2, 1, 0, 1, 1, 2, 2, 1, 0, 1, 1, 2, 1, 0};
std::vector<float> want{11, 13, 8, 8, 27, 29, 24, 24, 43, 45, 40, 40, 59, 61, 56, 56};
std::vector<float> c(16);
float *a_gpu, *b_gpu, *c_gpu;
check(cudaMalloc(&a_gpu, 16 * sizeof(float)));
check(cudaMalloc(&b_gpu, 16 * sizeof(float)));
check(cudaMalloc(&c_gpu, 16 * sizeof(float)));
check(cudaMemcpy(a_gpu, a.data(), 16 * sizeof(float), cudaMemcpyHostToDevice));
check(cudaMemcpy(b_gpu, b.data(), 16 * sizeof(float), cudaMemcpyHostToDevice));
matmul<float><<<gridFor(4, 4, 2), dim3(2, 2)>>>(4, 4, 4, a_gpu, b_gpu, c_gpu);
check(cudaGetLastError());
check(cudaMemcpy(c.data(), c_gpu, 16 * sizeof(float), cudaMemcpyDeviceToHost));
check(cudaFree(a_gpu));
check(cudaFree(b_gpu));
check(cudaFree(c_gpu));
std::printf("C = A B on the 4 x 4 example, a grid of 2 x 2 blocks of 2 x 2 threads\n");
for (int i = 0; i < 4; ++i) {
const float* row = &c[i * 4];
std::printf(" %4.0f %4.0f %4.0f %4.0f\n", row[0], row[1], row[2], row[3]);
}
bool same = c == want;
std::printf("equal to the product computed by hand: %s\n\n", same ? "yes" : "no");
return same;
}
// Time 1 kernel on n x n matrices, print 1 line of the table, and return true if exact.
template <typename T, typename F>
bool runSize(const char* name, int n, F launch)
{
unsigned state = 1;
std::vector<T> a = integers<T>(size_t(n) * n, &state);
std::vector<T> b = integers<T>(size_t(n) * n, &state);
std::vector<T> c(size_t(n) * n);
size_t bytes = size_t(n) * n * sizeof(T);
T *a_gpu, *b_gpu, *c_gpu;
check(cudaMalloc(&a_gpu, bytes));
check(cudaMalloc(&b_gpu, bytes));
check(cudaMalloc(&c_gpu, bytes));
check(cudaMemcpy(a_gpu, a.data(), bytes, cudaMemcpyHostToDevice));
check(cudaMemcpy(b_gpu, b.data(), bytes, cudaMemcpyHostToDevice));
double ms = timeMs([&] { launch(a_gpu, b_gpu, c_gpu); }, runsFor(n));
check(cudaMemcpy(c.data(), c_gpu, bytes, cudaMemcpyDeviceToHost));
check(cudaFree(a_gpu));
check(cudaFree(b_gpu));
check(cudaFree(c_gpu));
double flop = 2.0 * n * n * double(n);
double gflops = flop / ms / 1e6;
double fetched = flop * sizeof(T) / ms / 1e6;
int exact = exactEntries(a, b, c, n);
std::printf(" %5d %-10s %9.3f %9.1f", n, name, ms, gflops);
std::printf(" %10.1f %6d of 64\n", fetched, exact);
return exact == 64;
}
template <typename T>
bool runGeneric(const char* name, int n)
{
dim3 grid = gridFor(n, n, 16);
dim3 block(16, 16);
auto launch = [=](const T* a, const T* b, T* c) {
matmul<T><<<grid, block>>>(n, n, n, a, b, c);
};
return runSize<T>(name, n, launch);
}
bool runFixed()
{
const int n = 1024;
dim3 grid = gridFor(n, n, 16);
dim3 block(16, 16);
auto launch = [=](const float* a, const float* b, float* c) {
matmulFixed<n><<<grid, block>>>(a, b, c);
};
return runSize<float>("f32 fixed", n, launch);
}
// About 0.5 s of 1024 x 1024 products: the GPU raises its clocks under sustained load.
void warmUp()
{
const int n = 1024;
size_t bytes = size_t(n) * n * sizeof(float);
float *a_gpu, *b_gpu, *c_gpu;
check(cudaMalloc(&a_gpu, bytes));
check(cudaMalloc(&b_gpu, bytes));
check(cudaMalloc(&c_gpu, bytes));
check(cudaMemset(a_gpu, 0, bytes));
check(cudaMemset(b_gpu, 0, bytes));
double start = nowMs();
while (nowMs() - start < 500.0) {
matmul<float><<<gridFor(n, n, 16), dim3(16, 16)>>>(n, n, n, a_gpu, b_gpu, c_gpu);
check(cudaDeviceSynchronize());
}
check(cudaFree(a_gpu));
check(cudaFree(b_gpu));
check(cudaFree(c_gpu));
}
// The relation of the Rust launch contract that a launch of matmul
// would violate, or nullptr if there is none.
const char* violated(int m, int n, int k, size_t aLen, size_t bLen, size_t cLen)
{
if (aLen < size_t(m) * k) {
return "aLen >= m * k";
}
if (bLen < size_t(k) * n) {
return "bLen >= k * n";
}
if (cLen < size_t(m) * n) {
return "cLen >= m * n";
}
return nullptr;
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %d SMs\n\n", prop.name, prop.multiProcessorCount);
bool passed = runExample();
warmUp();
std::printf("C = A B, n x n, 1 thread per entry of C, blocks of 16 x 16 threads\n");
std::printf(" n type ms GFLOP/s fetched GB/s exact\n");
for (int n : {512, 1024, 2048, 4096}) {
passed &= runGeneric<float>("f32", n);
}
passed &= runFixed();
for (int n : {512, 1024, 2048}) {
passed &= runGeneric<double>("f64", n);
}
// A launch that claims k = 2 n for buffers of 256 x 256: the check refuses it.
size_t len = 256 * 256;
const char* broken = violated(256, 256, 512, len, len, len);
bool refused = broken != nullptr;
if (refused) {
std::printf("k = 2 n refused before launch: %s is false\n", broken);
}
passed &= refused;
std::printf("%s\n", passed ? "PASSED" : "FAILED");
return passed ? 0 : 1;
}
To build and run the Rust program, we run cargo oxide run in its directory. To build and run
the C++ program, we run
nvcc -O3 -arch=native matmul_naive.cu -o matmul_naive && ./matmul_naive.
Common mistakes
- Taking the row from \(x\). The result is still correct, but the 32 threads of a warp then walk down a column of \(B\), whose entries lie \(N\) floats apart, and the kernel runs several times slower (Section 9.3).
- Rounding the grid down. A grid of
n / 16blocks leaves the last \(n \bmod 16\) rows and columns of \(C\) unwritten. For example, with \(n = 1{,}000\), it leaves 8 rows and 8 columns unwritten. The size of the grid must be rounded up, withdiv_ceilor with \((n + 15) / 16\). - Dropping the guard in C++. Threads of the edge blocks then read and write outside the matrices. With \(n = 1{,}000\), the kernel stopped with an illegal memory access.
- Binding the wrong row width. With
RowWidth::new(&mut c, k)instead ofRowWidth::new(&mut c, n), every thread writes the element of a grid of width \(k\). The writes stay disjoint, so the program is safe, but the result is wrong unless \(k = n\). - Mixing up the 3 sizes. \(A\) has row width \(K\), and \(B\) and \(C\) have row width \(N\). Square test matrices hide a mistake here, so a rectangular product should be tested as well.
- Comparing random floats exactly. With random real inputs, the order of the additions changes the rounding. Small integers, as used here, give exact results; otherwise, the results must be compared with a tolerance.
Summary
- The product \(C = AB\) of an \(M \times K\) and a \(K \times N\) matrix has the entries \(c_{ij} = \sum_s a_{is} b_{sj}\), and it costs \(MNK\) multiply-adds, or \(2MNK\) FLOP. Our 4 × 4 example needs 64 multiply-adds, and \(c_{00} = 11\) and \(c_{01} = 13\).
- In row-major order, entry \((r, c)\) of a matrix of row width \(W\) is stored at location \(rW + c\).
- A kernel runs as many threads. The threads are grouped in blocks of up to 1,024 threads, each of which runs on 1 SM and shares shared memory, and the blocks form a grid. Along each axis, a thread finds its entry from \(\mathsf{blockIdx} \cdot \mathsf{blockDim} + \mathsf{threadIdx}\).
- Registers are fast and private to a thread, shared memory is fast and belongs to a block, and global memory is large and shared by all threads, but slow.
- The direct kernel gives each thread 1 entry of \(C\). It is correct, but it fetches every value of \(A\) \(N\) times and every value of \(B\) \(M\) times, which makes \(2MNK\) fetches, 1 per FLOP.
- In Rust,
DisjointSlicewithRuntime2DIndexorIndex2D<W>lets each thread write only its own entry withoutunsafe, and the launch contract refuses buffers that are too small for the sizes. - On the measured GPU, the kernel ran at about 7% of the FP32 peak. The caches answered most of its repeated fetches, and the rest of the time went to waiting for memory.
In Chapter 17, we let the threads of a block share the values they fetch, through shared memory, and we derive the tiled kernel from the key observation of Section 16.4.3.
Exercises
- Compute \(c_{32}\) of the example by hand, and identify the thread of Figure 16.5 that computes it.
- For \(n = 1{,}000\) and blocks of 16 × 16 threads, how many threads does the grid contain, and what fraction of them fail the guard?
- Extend the Rust host program to rectangular matrices and check the product for \(M = 300\), \(K = 500\), \(N = 700\).
- Explain why the
f64results of this chapter are exact. Would they stay exact for integers in \([-1{,}000, 1{,}000]\) and \(K = 4{,}096\)? And thef32results? - Using the FP32:FP64 ratio of your GPU, predict the rate of
matmul::<f64>if it were limited by arithmetic, and compare with your measurement. - Remove
#[unroll(4)]frommatmuland measure again. What changes? - Write a kernel that computes \(C = A^{\mathsf T} B\) without forming \(A^{\mathsf T}\). Which index expression changes, and how does the access pattern of a warp change?
- Suppose a cache holds every value that a block fetches. How many fetches does block \((0, 0)\) of Figure 16.5 then make from global memory, and how does that compare with the 32 fetches it requests?
Sources and further reading
- A. Pathak, An Introduction to Tiled Parallel Programming, Simplified, 2026: the worked example, the direct kernel and its fetch count.
- T. H. Cormen, C. E. Leiserson, R. L. Rivest and C. Stein, Introduction to Algorithms, 4th ed., MIT Press, 2022: the pseudocode conventions.
- NVIDIA, CUDA C++ Programming Guide, “Thread Hierarchy” and “Memory Hierarchy”: https://docs.nvidia.com/cuda/cuda-c-programming-guide/
- cuda-oxide, rev b7fe543,
cuda-devicecrate:DisjointSlice,Index2D,Runtime2DIndexand the thread index functions;cuda-macros:#[launch_contract]: https://github.com/NVlabs/cuda-oxide - Chapter 9 of this book, for the same kernel in CUDA C++ and the effect of the block shape.
Chapter 17: Tiled Matrix Multiplication
A GPU can perform arithmetic far faster than it can read operands from its global memory. In the direct kernel of Chapter 16, every thread read both of its operands from global memory for every multiply-add it performed, so the kernel spent most of its time waiting for memory rather than computing. Tiling is the standard technique for reducing this traffic. The threads of a block first copy a small piece of each input matrix into the fast on-chip shared memory, and then every thread of the block takes its operands from that copy. A value that would otherwise be read from global memory by many threads is then read from global memory only once per block.
In this chapter, we develop the tiled kernel step by step, using the same pair of 4 × 4 matrices as in Chapter 16, so that every number can be checked by hand. We first determine which values one block needs and how often the direct kernel reads them. We then split each dot product into phases, let the threads of a block load the pieces they need into shared memory together, and count the reads from global memory again. After that, we remove each of the kernel’s 2 barriers in turn and follow the wrong values that appear, and we prove that the complete kernel is correct. Finally, we implement the kernel in Rust and in CUDA C++, measure it, and explain why the measured speedup is much smaller than the reduction in reads.
This chapter covers
- the values 1 block of the direct kernel needs, and how often it fetches them
- splitting a dot product into phases, and tiles in shared memory
- the barrier, and the tiled algorithm with its 2 barriers
- the fetches of the tiled kernel: \(2MNK/T\) instead of \(2MNK\)
- each barrier removed, with the wrong values 7 and 15 on the example
- a proof of correctness by a loop invariant, and matrices of any size
- shared memory in Rust (
SharedArray,DynamicSharedArray,unsafewith// SAFETY:) and in CUDA C++ (__shared__arrays sized by a template parameter) - measured speeds, and why the speedup is not \(T\)
The code of the chapter is in
code/oxide/ch17_matmul_tiled/
for Rust and in
code/cuda/ch17_matmul_tiled/
for C++. We use the notation of Chapter 16: \(A\) is \(M \times K\), \(B\) is
\(K \times N\), \(C = AB\), all stored in row-major order, and \([a, b)\) is the range of
integers from \(a\) to \(b - 1\).
17.1 Values needed by 1 block
Recall from Section 16.4.3 that the 4 threads computing row 0 of \(C\) all read the same value \(a_{01}\) from global memory, each on its own. Our goal is to let such threads share a single copy of the value. Since only threads of the same block can share data, we start by asking which values one block needs. We take block \((0, 0)\) of the grid in Figure 16.5. Its 4 threads compute the top-left 2 × 2 square of \(C\), that is, \(c_{00} = 11\), \(c_{01} = 13\), \(c_{10} = 27\) and \(c_{11} = 29\). An entry \(c_{ij}\) needs row \(i\) of \(A\) and column \(j\) of \(B\), so together the 4 threads need rows 0 and 1 of \(A\) and columns 0 and 1 of \(B\). These are 8 values from each matrix, 16 values in all, as shown in Figure 17.1.
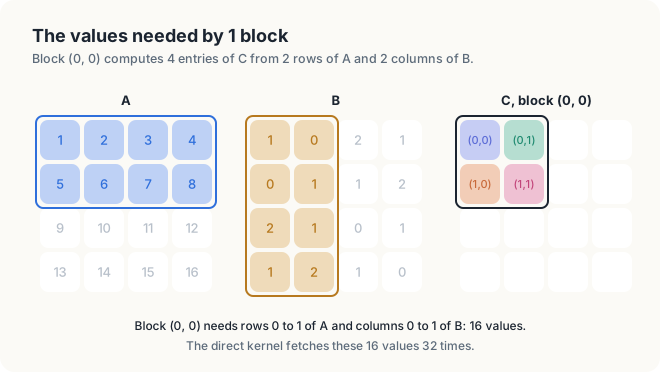
Let us count how often the direct kernel reads these 16 values. Thread \((0, 0)\) reads the 4 values of row 0 of \(A\) and the 4 values of column 0 of \(B\). Thread \((0, 1)\) reads the same row 0 of \(A\) again, together with column 1 of \(B\). In the same way, each of the 4 threads makes 8 reads, so the block makes 32 reads in total, and every one of the 16 values is read twice. If the block instead copied each of the 16 values into shared memory once, and its threads then took their operands from that copy, the block would read global memory only 16 times, half as often.
This plan has one difficulty. Shared memory is small: a block can use at most 48 KB of it by default, and a streaming multiprocessor (SM) has between 48 KB and 228 KB in total, shared by all the blocks that it runs. In our example, the rows are only 4 values long, but in a real problem a row of \(A\) holds thousands of values. For example, with \(K = 4{,}096\), a block of 16 × 16 threads needs 16 rows of \(A\) and 16 columns of \(B\), which hold \(2 \cdot 16 \cdot 4{,}096 = 131{,}072\) floats, or 512 KB. Such a strip of rows and columns does not fit into shared memory, so the block cannot copy everything it needs at once. In the next section, we see that it does not have to.
17.2 Splitting the sum
The key to the solution is that a thread does not need its whole row and column at the same time. The entry \(c_{00}\) is a sum of 4 products, and the terms of a sum may be added in any grouping. Figure 17.2 groups the 4 terms of \(c_{00}\) in 2 pairs. The first pair uses the first 2 values of row 0 of \(A\) and the first 2 values of column 0 of \(B\), and adds up to \(1 \cdot 1 + 2 \cdot 0 = 1\). The second pair uses the last 2 values of each, and adds up to \(3 \cdot 2 + 4 \cdot 1 = 10\). Together the 2 pairs give \(1 + 10 = 11\), which is \(c_{00}\).
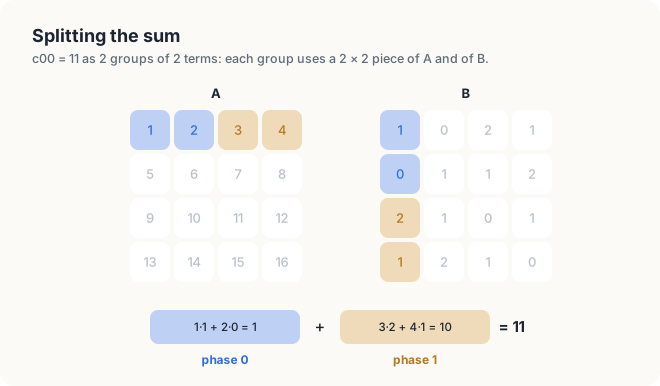
Now consider all 4 threads of the block. For its first pair of terms, every thread needs only columns 0 and 1 of rows 0 and 1 of \(A\), which form a 2 × 2 piece of \(A\), and rows 0 and 1 of columns 0 and 1 of \(B\), which form a 2 × 2 piece of \(B\). For its second pair, every thread needs the 2 × 2 pieces next to these: columns 2 and 3 of \(A\), and rows 2 and 3 of \(B\). The block can therefore work in 2 rounds. In each round, it copies 1 small piece of \(A\) and 1 small piece of \(B\) into shared memory, and every thread adds the matching pair of terms to its sum. At any moment, the block holds only 2 pieces of 4 values each in shared memory, however long the rows are.
Definition 17.1 Tile and phase. A tile is a square piece of \(A\) or \(B\), of \(T\) rows and \(T\) columns, that a block holds in shared memory. The number \(T\) is called the tile width. A phase is 1 round of the tiled kernel: the block copies 1 tile of \(A\) and 1 tile of \(B\) into shared memory, and every thread adds \(T\) products to its sum.
Example. With \(T = 2\), block \((0, 0)\) runs 2 phases. In phase 0, it uses the tile of \(A\) in rows 0 and 1 and columns 0 and 1; in phase 1, the tile of \(A\) in rows 0 and 1 and columns 2 and 3.
We can now state the grouping in general. We number the phases 0, 1, 2 and so on, and we write \(\mathsf{phase}\) for the number of a phase. Each phase handles \(T\) consecutive terms of each sum, so phase 0 handles the terms with \(s = 0, \ldots, T - 1\), phase 1 the terms with \(s = T, \ldots, 2T - 1\), and in general, the phase with number \(\mathsf{phase}\) handles the \(T\) terms that begin at \(s = \mathsf{phase} \cdot T\). The product \(\mathsf{phase} \cdot T\) is therefore the position at which the phase begins. In our example, with \(T = 2\), phase 0 begins at \(s = 0\) and phase 1 at \(s = 1 \cdot 2 = 2\). We write the position of a term within its phase as \(\mathsf{offset}\), which runs from 0 to \(T - 1\), so that every index \(s\) can be written as \(s = \mathsf{phase} \cdot T + \mathsf{offset}\). For example, the term with \(s = 3\) is the term with \(\mathsf{offset} = 1\) in phase 1, since \(3 = 1 \cdot 2 + 1\). With this notation, the definition of the matrix product in Definition 16.1 becomes a sum over the phases of a sum within each phase:
\[ c_{ij} = \sum_{\mathsf{phase} \in [0, \lceil K/T \rceil)} \; \underbrace{\sum_{\mathsf{offset} \in [0, T)} a_{i,\, \mathsf{phase} \cdot T + \mathsf{offset}}\; b_{\mathsf{phase} \cdot T + \mathsf{offset},\, j}}_{\text{one phase}}. \]
| Symbol | Meaning | In the example |
|---|---|---|
| \(T\) | tile width: rows and columns of a tile, terms added per phase | 2 |
| \(\mathsf{phase}\) | number of the phase | 0 or 1 |
| \(\mathsf{phase} \cdot T\) | index \(s\) at which the phase begins | 0 in phase 0, 2 in phase 1 |
| \(\mathsf{offset}\) | position of a term inside its phase | 0 or 1 |
| \(\lceil K/T \rceil\) | number of phases, \(K/T\) rounded up | \(4/2 = 2\) |
| \(a_{i,\, \mathsf{phase} \cdot T + \mathsf{offset}}\) | value of \(A\) in row \(i\), column \(\mathsf{phase} \cdot T + \mathsf{offset}\) | \(a_{0,3} = 4\) for \(i = 0\), \(\mathsf{phase} = 1\), \(\mathsf{offset} = 1\) |
The number of phases is \(\lceil K/T \rceil\), the quotient \(K/T\) rounded up, because when \(K\) is not a multiple of \(T\), the last phase is only partly filled. In that case, we treat the entries beyond the edge of a matrix as 0, so that the missing terms add nothing to the sum. Note also how the tiles move. From 1 phase to the next, the tile of \(A\) moves \(T\) columns to the right along the rows of the block, and the tile of \(B\) moves \(T\) rows down along its columns. Each thread still uses its entire row of \(A\) and column of \(B\); it receives them 1 tile at a time.
17.3 Loading a tile together
Next, we decide which thread copies which value of a tile. A tile holds \(T \times T = T^2\) values, and a block of the tiled kernel has \(T \times T = T^2\) threads, so the work divides evenly. We let each thread copy exactly 1 value of the tile of \(A\) and 1 value of the tile of \(B\). The natural choice is to let every thread copy the value that belongs at its own position in the tile. Recall from Chapter 16 that thread \((\mathsf{threadIdx{.}y}, \mathsf{threadIdx{.}x})\) is the thread in row \(\mathsf{threadIdx{.}y}\) and column \(\mathsf{threadIdx{.}x}\) of its block, and that it computes the entry of \(C\) in row \(\mathsf{row}\) and column \(\mathsf{col}\). We call the 2 tiles in shared memory tileA and tileB. In the phase with number \(\mathsf{phase}\), thread \((\mathsf{threadIdx{.}y}, \mathsf{threadIdx{.}x})\) performs the 2 copies
\[ \mathsf{tileA}[\mathsf{threadIdx{.}y}][\mathsf{threadIdx{.}x}] = a_{\mathsf{row},\; \mathsf{phase} \cdot T + \mathsf{threadIdx{.}x}}, \qquad \mathsf{tileB}[\mathsf{threadIdx{.}y}][\mathsf{threadIdx{.}x}] = b_{\mathsf{phase} \cdot T + \mathsf{threadIdx{.}y},\; \mathsf{col}}. \]
The first copy reads from the thread’s own row of \(A\), at column \(\mathsf{phase} \cdot T + \mathsf{threadIdx{.}x}\): the tile of this phase begins at column \(\mathsf{phase} \cdot T\), and the thread takes the value \(\mathsf{threadIdx{.}x}\) places further along. The second copy reads from the thread’s own column of \(B\), at row \(\mathsf{phase} \cdot T + \mathsf{threadIdx{.}y}\), that is, \(\mathsf{threadIdx{.}y}\) places below the first row of the tile. For example, in phase 1, thread \((0, 1)\) of block \((0, 0)\) has \(\mathsf{row} = 0\) and \(\mathsf{col} = 1\), and copies \(a_{0,\, 2 + 1} = a_{03} = 4\) into tileA[0][1] and \(b_{2 + 0,\, 1} = b_{21} = 1\) into tileB[0][1].
| Symbol | Meaning | Thread \((0, 1)\), phase 1 |
|---|---|---|
| \(\mathsf{threadIdx{.}y}, \mathsf{threadIdx{.}x}\) | row and column of the thread within its block | 0, 1 |
| \(\mathsf{row}, \mathsf{col}\) | row and column of the entry of \(C\) the thread computes | 0, 1 |
| \(\mathsf{phase} \cdot T + \mathsf{threadIdx{.}x}\) | column of \(A\) the thread copies | \(1 \cdot 2 + 1 = 3\) |
| \(\mathsf{phase} \cdot T + \mathsf{threadIdx{.}y}\) | row of \(B\) the thread copies | \(1 \cdot 2 + 0 = 2\) |
As \((\mathsf{threadIdx{.}y}, \mathsf{threadIdx{.}x})\) runs over all threads of the block, these copies fill every position of both tiles exactly once, so no value is copied twice and none is missed. Note also that the threads with the same \(\mathsf{threadIdx{.}y}\) copy \(T\) neighboring values of the same row of \(A\), which lie next to each other in memory, so their reads can be combined into few memory transactions. In Figure 17.3, we follow block \((0, 0)\) through both phases. Each color belongs to 1 thread and marks the values that the thread copies as well as the sum that it accumulates.
Let us follow thread \((0, 0)\). In phase 0, it copies \(a_{00} = 1\) and \(b_{00} = 1\), while the other 3 threads of the block copy the remaining 6 values of the 2 tiles. Once both tiles are complete, the thread multiplies row 0 of tileA by column 0 of tileB and obtains \(1 \cdot 1 + 2 \cdot 0 = 1\). In phase 1, the tiles hold the next 2 pieces of \(A\) and \(B\), and the thread adds \(3 \cdot 2 + 4 \cdot 1 = 10\), which brings its sum to \(c_{00} = 11\). Thread \((0, 1)\) performs the same steps with column 1 of each tile of \(B\). It obtains \(1 \cdot 0 + 2 \cdot 1 = 2\) in phase 0, and \(2 + 3 \cdot 1 + 4 \cdot 2 = 13\) after phase 1, which is \(c_{01}\).
We can now see where the saving comes from. Consider thread \((0, 1)\) in phase 0, shown in Figure 17.4. It uses 4 values from shared memory, but it copied only 2 of them, \(a_{01}\) and \(b_{01}\); the other 2 were copied by its neighbors. In general, each value of tileA is used by the \(T\) threads in its row of the block, and each value of tileB by the \(T\) threads in its column. Every value that the block reads from global memory is therefore used \(T\) times.
Exercises
17.1 Carry out both phases of block \((0, 1)\), which computes \(c_{02}\), \(c_{03}\),
\(c_{12}\) and \(c_{13}\). Which values does thread \((1, 0)\) copy in each phase?
17.2 With \(T = 4\), the whole example is a single block. How many phases does it run, and which
values does thread \((2, 3)\) copy?
17.3 In the phase with number \(\mathsf{phase}\), which thread of block \((\mathsf{blockIdx{.}y}, \mathsf{blockIdx{.}x})\) copies \(a_{i, s}\)? Express \(\mathsf{threadIdx{.}y}\)
and \(\mathsf{threadIdx{.}x}\) in terms of \(i\), \(s\), \(\mathsf{blockIdx{.}y}\), \(\mathsf{phase}\) and \(T\).
17.4 The algorithm
17.4.1 The barrier
In Section 17.3, we let every thread copy 1 value of each tile and then compute with values that other threads had copied. In Figure 17.4, for example, thread \((0, 1)\) uses \(\mathsf{tileA}[0][0] = 1\), which thread \((0, 0)\) copied, and \(\mathsf{tileB}[1][1] = 1\), which thread \((1, 1)\) copied. This is correct only if thread \((0, 1)\) reads these 2 slots after its neighbors have stored their values in them. The threads of a block, however, do not move in lockstep. One thread may run ahead while another falls behind, because their warps are scheduled independently and their memory reads finish at different times. From its own progress alone, thread \((0, 1)\) therefore cannot tell whether thread \((1, 1)\) has already stored its value. When threads exchange data through shared memory, they need a common point in the program at which all of them wait for one another, so that each thread knows that the work of every other thread before that point is finished. Such a point is called a barrier.
Definition 17.2 Barrier. A barrier is a point in a kernel
that no thread of a block may pass until every thread of the block has reached it. The writes to
shared memory that a thread made before the barrier are visible to every thread of the block after
it. In cuda-oxide, a barrier is thread::sync_threads(), and in CUDA C++, it is __syncthreads().
Example. In Figure 17.5, thread 3 arrives first and waits; thread 1 arrives last, and then all 4 threads continue together.
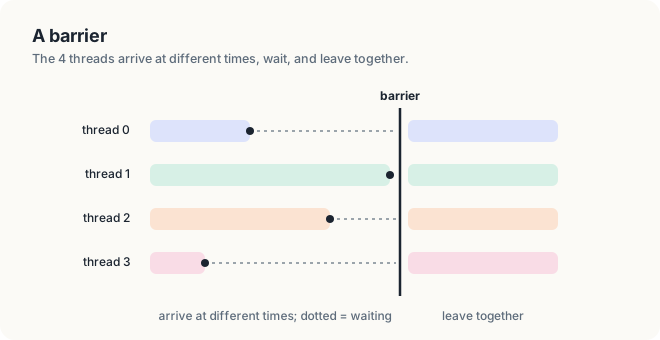
Note that a barrier costs time. In Figure 17.5, the threads that arrive early do no work between their arrival and the arrival of thread 1, so the block as a whole advances at the pace of its slowest thread. We will return to this cost in Section 17.8.2.
17.4.2 The tiled kernel
We now have all the pieces of the tiled kernel. In every phase, each thread performs the same 4 steps, shown in Figure 17.6. It first copies its 1 value of each tile. It then waits at a barrier until the whole block has finished copying. Next, it adds the \(T\) products of the phase to its sum, and finally, it waits at a second barrier until the whole block has finished reading the tiles. The phase then begins again with the next pair of tiles. In Section 17.6, we explain why each of the 2 barriers is needed.
Every thread executes the following procedure. The arrays tileA and tileB live in shared memory, and each block has its own pair of them.
Tiled-Kernel(\(A, B, C, M, K, N\))
- \(\mathsf{row} = \mathsf{blockIdx{.}y} \cdot T + \mathsf{threadIdx{.}y}\)
- \(\mathsf{col} = \mathsf{blockIdx{.}x} \cdot T + \mathsf{threadIdx{.}x}\)
- \(\mathsf{sum} = 0\)
- for \(\mathsf{phase} \in [0, \lceil K/T \rceil)\) {
- \(\mathsf{aCol} = \mathsf{phase} \cdot T + \mathsf{threadIdx{.}x}\)
- \(\mathsf{bRow} = \mathsf{phase} \cdot T + \mathsf{threadIdx{.}y}\)
- \(\mathsf{tileA}[\mathsf{threadIdx{.}y}][\mathsf{threadIdx{.}x}] = a_{\mathsf{row},\, \mathsf{aCol}}\) if \(\mathsf{row} \in [0, M)\) and \(\mathsf{aCol} \in [0, K)\), else 0
- \(\mathsf{tileB}[\mathsf{threadIdx{.}y}][\mathsf{threadIdx{.}x}] = b_{\mathsf{bRow},\, \mathsf{col}}\) if \(\mathsf{bRow} \in [0, K)\) and \(\mathsf{col} \in [0, N)\), else 0
- Barrier() // wait until both tiles are full
- for \(\mathsf{offset} \in [0, T)\) {
- \(\mathsf{sum} = \mathsf{sum} + \mathsf{tileA}[\mathsf{threadIdx{.}y}][\mathsf{offset}] \cdot \mathsf{tileB}[\mathsf{offset}][\mathsf{threadIdx{.}x}]\)
- }
- Barrier() // wait until every thread has read the tiles
- }
- if \(\mathsf{row} \in [0, M)\) and \(\mathsf{col} \in [0, N)\) {
- \(c_{\mathsf{row}, \mathsf{col}} = \mathsf{sum}\)
- }
Lines 1 and 2 compute the row and column of the entry of \(C\) that the thread computes, as in Direct-Kernel. A block of the tiled kernel has \(T \times T\) threads, so \(\mathsf{blockDim{.}x} = \mathsf{blockDim{.}y} = T\). For thread \((0, 1)\) of block \((0, 0)\) with \(T = 2\), \(\mathsf{threadIdx{.}y} = 0\) and \(\mathsf{threadIdx{.}x} = 1\), so the 2 lines give \(\mathsf{row} = 0 \cdot 2 + 0 = 0\) and \(\mathsf{col} = 0 \cdot 2 + 1 = 1\). Line 3 sets the sum to 0, and line 4 starts the loop over the \(\lceil K/T \rceil\) phases, of which there are 2 in our example. Lines 5 and 6 name the 2 positions that the thread copies in this phase, the column \(\mathsf{aCol}\) of \(A\) and the row \(\mathsf{bRow}\) of \(B\). For thread \((0, 1)\) in phase 1, they are \(1 \cdot 2 + 1 = 3\) and \(1 \cdot 2 + 0 = 2\). Lines 7 and 8 are the joint copy of Section 17.3. Lines 10 to 12 add 1 phase of the sum, that is, the inner sum over \(\mathsf{offset}\) of the formula in Section 17.2. In phase 0, for thread \((0, 1)\), they compute \(\mathsf{tileA}[0][0] \cdot \mathsf{tileB}[0][1] + \mathsf{tileA}[0][1] \cdot \mathsf{tileB}[1][1] = 1 \cdot 0 + 2 \cdot 1 = 2\). Lines 9 and 13 are the 2 barriers. The conditions in lines 7 and 8, which store 0 in place of a value outside the matrix, handle matrices whose size is not a multiple of \(T\); we treat both the barriers and these zeros in Section 17.6. Finally, lines 15 to 17 store the result. They replace the early return of the direct kernel, for a reason that we give in Section 17.6.5.
17.5 Counting the fetches again
We can now count how often the tiled kernel reads global memory, in the same way as we counted the reads of the direct kernel in Section 17.1. As in Chapter 16, we call each read of a value from global memory a fetch. In each phase, every thread fetches 2 values, 1 for each tile, in lines 7 and 8. Block \((0, 0)\) has 4 threads and runs 2 phases, so it makes \(4 \cdot 2 \cdot 2 = 16\) fetches. This is half of the 32 fetches that the direct kernel makes for the same block, and it equals the number of different values that the block needs, so the block now fetches each of these values exactly once. The other 3 blocks behave in the same way, and over the whole grid we count \(4 \cdot 16 = 64\) fetches instead of 128 (Figure 17.7).
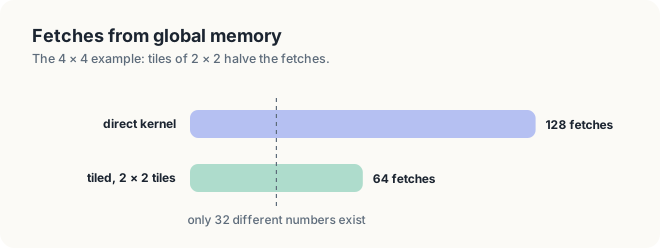
The dashed line in Figure 17.7 marks the 32 different values of \(A\) and \(B\), which is the least that any kernel must fetch. The tiled kernel still fetches each value twice, because 2 blocks need it. For example, \(a_{00}\) is fetched by block \((0, 0)\) and again by block \((0, 1)\), which computes the right half of the same 2 rows of \(C\).
In general, a block has \(T^2\) threads, each of which fetches 2 values per phase, so a block makes \(2T^2\) fetches per phase. When \(T\) divides every dimension, the grid has \((M/T)(N/T)\) blocks, because each block covers a \(T \times T\) square of the \(M \times N\) matrix \(C\), and each block runs \(K/T\) phases. The total number of fetches is therefore
\[ \frac{M}{T} \cdot \frac{N}{T} \cdot \frac{K}{T} \cdot 2T^2 = \frac{2MNK}{T}. \]
| Symbol | Meaning | In the example |
|---|---|---|
| \(M, N\) | rows and columns of \(C\) | 4, 4 |
| \(K\) | columns of \(A\) and rows of \(B\), the length of each dot product | 4 |
| \(T\) | tile width | 2 |
| \((M/T)(N/T)\) | number of blocks in the grid | \(2 \cdot 2 = 4\) |
| \(K/T\) | number of phases each block runs | 2 |
| \(2T^2\) | fetches of 1 block in 1 phase | 8 |
| \(2MNK/T\) | fetches of the whole kernel | \(2 \cdot 4 \cdot 4 \cdot 4 / 2 = 64\) |
Recall that the direct kernel makes \(2MNK\) fetches, 2 for each of its \(MNK\) multiply-adds, which in our example is \(2 \cdot 64 = 128\). Tiling therefore divides the traffic to global memory by exactly \(T\). Equivalently, each value of \(A\) is fetched \(N/T\) times instead of \(N\) times, once by each of the \(N/T\) blocks that compute its rows of \(C\), and each value of \(B\) is fetched \(M/T\) times instead of \(M\) times. With \(T = 16\), the product of 2 matrices of 1,024 × 1,024 moves 0.54 GB instead of 8.6 GB. In the units of Chapter 9, the kernel performs \(T\) FLOP per float fetched from global memory, 16 instead of 1.
Since a larger tile saves more fetches, it is natural to ask how large \(T\) can be. There are 2 limits. A block holds at most 1,024 threads, and a block of the tiled kernel has \(T^2\) threads, so \(T \le 32\). The 2 tiles hold \(2T^2\) values of 4 bytes each, which is 2 KB of shared memory for \(T = 16\) and 8 KB for \(T = 32\), well within the 48 KB that a block may use. The number of threads in a block, not the size of shared memory, therefore limits \(T\). In Section 17.8, we will see that the largest \(T\) is nevertheless not the fastest.
Exercises
17.4 With \(T = 4\), the example is 1 block. How many fetches does it make, and how often is each
value fetched?
17.5 Let \(M = N = K = 100\) and \(T = 16\). How many phases does each block run, and what
fraction of the values copied in the last phase are zeros?
17.6 For \(M = N = K = 4{,}096\) and \(T = 32\), how many bytes does the tiled kernel fetch
from global memory?
17.6 Correctness
In Section 17.4, we placed 2 barriers in every phase without explaining why both are needed. The threads of a block run at different speeds, yet they read and write the same slots of shared memory. Without coordination, 2 things can go wrong. A thread can read a slot before the thread responsible for it has filled it, or a thread can overwrite a slot that another thread has not yet finished reading. In this section, we remove the barriers of Tiled-Kernel one at a time and follow each error on our example. We then prove that the kernel with both barriers is correct, and we extend it to matrices of any size.
17.6.1 The first barrier: copy before computing
Suppose that we delete line 9, the first barrier. Consider phase 1 of block \((0, 0)\). Thread \((0, 0)\) finishes its copies early and goes on to line 11, where it computes \(\mathsf{tileA}[0][0] \cdot \mathsf{tileB}[0][0] + \mathsf{tileA}[0][1] \cdot \mathsf{tileB}[1][0]\). The slot \(\mathsf{tileB}[1][0]\) belongs to thread \((1, 0)\), which in phase 1 is to fill it with \(b_{30} = 1\). Thread \((1, 0)\), however, is running late, and it has not yet stored this value when thread \((0, 0)\) reads the slot (Figure 17.8).
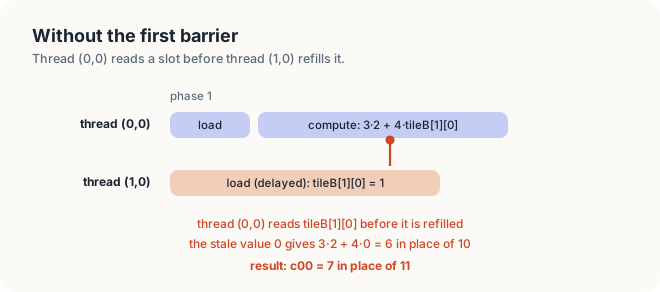
The slot therefore still holds the value that thread \((1, 0)\) stored in phase 0, which is \(b_{10} = 0\). Thread \((0, 0)\) adds \(3 \cdot 2 + 4 \cdot 0 = 6\) instead of \(3 \cdot 2 + 4 \cdot 1 = 10\), and its sum becomes \(c_{00} = 1 + 6 = 7\) instead of 11. Line 9 prevents this error, because no thread may start computing until every thread of the block has finished copying.
17.6.2 The second barrier: compute before the next copy
Now we restore line 9 and delete line 13, the second barrier, instead. This time, the error occurs at the end of a phase rather than at its start. In phase 0, thread \((1, 1)\) finishes its multiply-adds early and moves on to phase 1, where its first task is to store \(b_{31} = 2\) in \(\mathsf{tileB}[1][1]\). Thread \((0, 1)\), however, is still in phase 0, and it still needs the old value of that slot, \(b_{11} = 1\) (Figure 17.9).
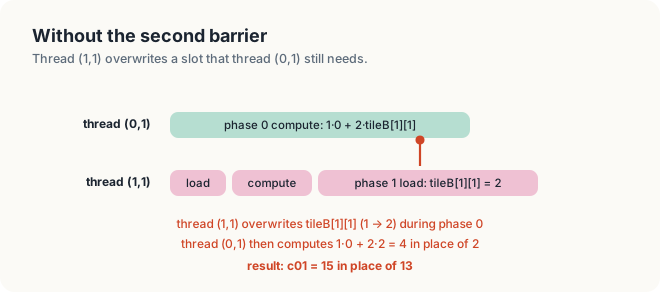
Thread \((0, 1)\) reads the new value and computes \(1 \cdot 0 + 2 \cdot 2 = 4\) instead of \(1 \cdot 0 + 2 \cdot 1 = 2\) in phase 0. Phase 1 then adds the correct \(3 \cdot 1 + 4 \cdot 2 = 11\), so this time we get \(c_{01} = 4 + 11 = 15\) instead of 13. Line 13 prevents this error, because no thread may overwrite a tile until every thread of the block has finished reading it. With both barriers in place, every phase follows the same orderly schedule, shown in Figure 17.10. The threads copy, wait for the slowest of them, compute, and wait again before the next copy.
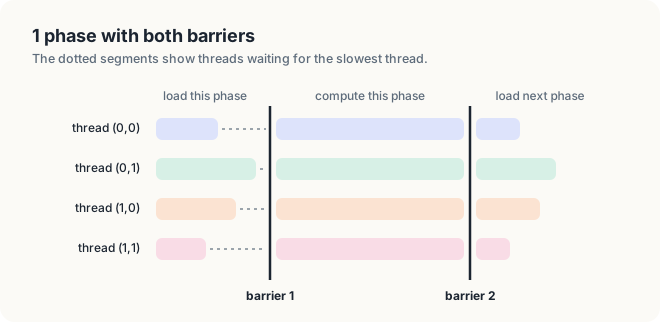
The two errors are of different kinds. The first barrier orders a write of a slot before a read of the same slot. Here, the reading thread needs the value that the writing thread produces, and such an ordering is called a read-after-write dependence. In Section 17.6.1, thread \((0, 0)\) had to read \(\mathsf{tileB}[1][0]\) after thread \((1, 0)\) had written it. The second barrier orders a read of a slot before the next write of the same slot. Here, the writing thread needs nothing from the reading thread, and the conflict exists only because both use the same slot in consecutive phases. Such an ordering is called a write-after-read dependence. In Section 17.6.2, thread \((1, 1)\) had to write \(\mathsf{tileB}[1][1]\) only after thread \((0, 1)\) had read it. Both errors are data races in the sense of Definition 16.8.
17.6.3 The broken kernels on the GPU
Figures 17.8 and 17.9 show what can happen, but whether it actually happens depends on the timing
of the threads. To find out, we built the Rust kernel twice more, once without each barrier. We ran
each broken kernel 3 times on the 4 × 4 example with \(T = 2\) and 5 times on matrices of
512 × 512 with \(T = 16\), and we compared every entry of the result with a product computed on
the CPU. On the example, all 6 runs printed equal to the product computed by hand: yes. At
512 × 512, the kernel without the first barrier printed the following lines.
without barrier 1, n = 512, T = 16: 260406 of 262144 entries wrong
without barrier 1, n = 512, T = 16: 260433 of 262144 entries wrong
without barrier 1, n = 512, T = 16: 260452 of 262144 entries wrong
without barrier 1, n = 512, T = 16: 260531 of 262144 entries wrong
without barrier 1, n = 512, T = 16: 260351 of 262144 entries wrong
The kernel without the second barrier printed the following lines.
without barrier 2, n = 512, T = 16: 24255 of 262144 entries wrong
without barrier 2, n = 512, T = 16: 24704 of 262144 entries wrong
without barrier 2, n = 512, T = 16: 27347 of 262144 entries wrong
without barrier 2, n = 512, T = 16: 25287 of 262144 entries wrong
without barrier 2, n = 512, T = 16: 23913 of 262144 entries wrong
On the 4 × 4 example, both broken kernels happened to give the right product in every run. A block of 2 × 2 threads consists of 4 threads of a single warp, and the hardware issued their loads and their multiply-adds together, so no thread ran ahead of another. A missing barrier therefore does not guarantee a wrong result; it only allows one. At 512 × 512, each block has 256 threads in 8 warps, which the SM schedules independently, and the errors appeared at once. Without the first barrier, 99.3% of the entries were wrong, because almost every dot product met at least 1 slot that its writer had not yet filled. Without the second barrier, about 9.5% were wrong. This error is rarer, because it requires 1 warp to finish a whole phase while another warp of the same block is still in it. In both cases, the count changed from run to run, since it depends on the order in which the warps happen to run. The CUDA C++ kernels behaved in the same way, with 260,014 to 260,438 and 23,424 to 25,694 wrong entries. Neither program reported an error, and both compiled without a warning, because a missing barrier breaks no rule that a compiler checks.
17.6.4 The proof
The experiments of Section 17.6.3 show that the kernel fails without its barriers, but tests on a few matrices cannot show that it is correct with them. For that, we need a proof. The idea is to follow the variable sum of 1 thread as it grows, phase by phase. Figure 17.11 shows this for thread \((0, 0)\) with \(T = 2\). Before phase 0, sum is 0. Before phase 1, it holds the first 2 terms of \(c_{00}\), \(1 \cdot 1 + 2 \cdot 0 = 1\), and after phase 1, it holds all 4 terms, which add up to 11. In general, before the phase with number \(\mathsf{phase}\), sum holds exactly the first \(\mathsf{phase} \cdot T\) terms of the thread’s entry of \(C\). A statement that holds every time a loop begins a new iteration is called a loop invariant, and we prove the theorem by showing that this statement is one.
![Row 0 of A, 1 2 3 4, and column 0 of B, 1 0 2 1, drawn as 2 rows of cells: the first 2 cells of each in blue (phase 0), the last 2 in amber (phase 1). Below, 3 bars show how much of the dot product sum covers: at the start of phase 0 no terms, sum = 0; at the start of phase 1 the terms s in [0, 2), sum = 1 times 1 plus 2 times 0 = 1; at the end of the loop, the terms s in [0, 4), sum = 1 + 3 times 2 + 4 times 1 = 11 = c00.](figures/ch17-invariant.svg)
Theorem 17.1 When Tiled-Kernel finishes, every entry of \(C\) equals the corresponding entry of \(AB\).
Proof. Fix a thread with \(\mathsf{row} \in [0, M)\) and \(\mathsf{col} \in [0, N)\), and treat entries beyond the edge of a matrix as 0. We show that the loop of lines 4 to 14 maintains the invariant
\[ \text{at the start of the phase with number } \mathsf{phase}, \qquad \mathsf{sum} = \sum_{s \in [0,\, \mathsf{phase} \cdot T)} a_{\mathsf{row}, s}\; b_{s, \mathsf{col}}. \]
| Symbol | Meaning | Thread \((0, 0)\), start of phase 1 |
|---|---|---|
| \(\mathsf{phase}\) | phase about to begin | 1 |
| \(\mathsf{phase} \cdot T\) | number of terms already added | \(1 \cdot 2 = 2\) |
| \(s \in [0, \mathsf{phase} \cdot T)\) | indices of the terms already added | 0 and 1 |
| \(a_{\mathsf{row}, s}\, b_{s, \mathsf{col}}\) | term \(s\) of the dot product | \(1 \cdot 1\) and \(2 \cdot 0\) |
| \(\mathsf{sum}\) | value of the variable | 1 |
Initialization. Before phase 0, \(\mathsf{sum} = 0\), which is the empty sum.
Maintenance. Assume that the invariant holds at the start of the phase with number \(\mathsf{phase}\). In lines 7 and 8, the threads of the block fill both tiles completely (Section 17.3). Because of the barrier in line 9, every one of these stores is complete and visible before any thread reaches line 11; this excludes the error of Section 17.6.1. Hence \(\mathsf{tileA}[\mathsf{threadIdx{.}y}][\mathsf{offset}] = a_{\mathsf{row}, \mathsf{phase} \cdot T + \mathsf{offset}}\) and \(\mathsf{tileB}[\mathsf{offset}][\mathsf{threadIdx{.}x}] = b_{\mathsf{phase} \cdot T + \mathsf{offset}, \mathsf{col}}\) for every \(\mathsf{offset} \in [0, T)\), and lines 10 to 12 add exactly the terms with \(s \in [\mathsf{phase} \cdot T, \mathsf{phase} \cdot T + T)\). For thread \((0, 0)\) in phase 1, these are the terms with \(s = 2\) and \(s = 3\), which add \(3 \cdot 2 + 4 \cdot 1 = 10\). Because of the barrier in line 13, no thread overwrites a tile for the next phase while another thread is still reading it in this one; this excludes the error of Section 17.6.2. Therefore, the invariant holds at the start of the phase with number \(\mathsf{phase} + 1\).
Termination. The loop ends with \(\mathsf{phase} = \lceil K/T \rceil\), so \(\mathsf{phase} \cdot T \ge K\). All terms with \(s \ge K\) are 0, hence \(\mathsf{sum} = c_{\mathsf{row}, \mathsf{col}}\), and line 16 stores it.
The proof uses each barrier exactly once, in the maintenance step, and each use excludes 1 of the two errors of Sections 17.6.1 and 17.6.2. The proof covers only the threads that have an entry of \(C\). A thread outside \(C\) stores nothing, so there is no result of its own to prove correct. It still takes part in lines 7 to 13, however, and in the next section, we show why it must.
17.6.5 Matrices of any size
So far, we have assumed that \(T\) divides every dimension of the matrices. Nothing in the algorithm requires this, and in this section, we see how the kernel handles the other cases. Take \(C\) of size 3 × 3 with \(T = 2\). A single block covers only a 2 × 2 square, so we still need 2 × 2 = 4 blocks to cover \(C\). Together they have 16 threads, but \(C\) has only 9 entries, so the blocks stick out past the edge of \(C\), and 7 of their 16 threads have no entry to compute. If also \(K = 3\), the matrix \(A\) has only 3 columns, and in phase 1, the tile of \(A\), which covers columns 2 and 3, reaches for a column that does not exist (Figure 17.12).
Lines 7 and 8 handle a missing value by storing 0 in its place, and a product with 0 adds nothing to the sum. In Figure 17.12, the right column of tileA in phase 1 would hold column 3 of \(A\); both of its slots hold 0, so the term with \(s = 3\), which does not exist, contributes nothing.
Threads with no entry need more care, and they explain the only structural difference between the direct kernel and the tiled kernel. In the direct kernel, such a thread returns at once. In the tiled kernel, it must not return, because a barrier releases the block only when every thread has arrived. A thread that has returned never arrives, so the rest of the block would wait forever, or, on some GPUs, continue with an undefined result. Instead, these threads stay in the loop, copy zeros, wait at every barrier together with the other threads, and skip only the final store in lines 15 to 17. For example, thread \((1, 1)\) of block \((1, 1)\) has \(\mathsf{row} = 3\) and \(\mathsf{col} = 3\), outside the 3 × 3 matrix \(C\). In both phases, it copies 0 into both tiles, since row 3 of \(A\) and column 3 of \(B\) do not exist, and it waits at all 4 barriers. At line 15, the condition \(\mathsf{row} \in [0, M)\) is false, so it stores nothing. Both programs check 3 shapes of this kind, comparing every entry: the 3 × 3 product with \(T = 2\), a 128 × 64 by 64 × 96 product, and a 1,000 × 1,000 product with \(T = 16\).
Rule Every thread of a block must reach every barrier. Never place a barrier where some threads of the block can skip it.
Exercises
17.7 Without line 9, thread \((1, 1)\) might read \(\mathsf{tileA}[1][0]\) in phase 1 before
the slot is refilled. Which value would it use, and what would \(c_{11}\) become?
17.8 Explain why the proof of Theorem 17.1 breaks when a thread returns early, even though that
thread writes no entry of \(C\).
17.9 Without line 13, could \(c_{00}\) become wrong in our example? Which thread would have to
run ahead, and which slot would it overwrite?
17.7 Implementation
We now turn Tiled-Kernel into code, in Rust and in CUDA C++. The main new element in both languages is shared memory, so we begin with the declaration of the 2 tiles.
17.7.1 Shared arrays
In CUDA C++, an array in shared memory is a local array declared with the qualifier __shared__.
Its length must be known at compile time, and a template parameter satisfies this requirement.
The kernel matmulTiled<T> therefore declares 2 tiles of T × T floats, and the compiler builds
1 kernel for each value of T that the program uses.
In cuda-oxide, a fixed-size array in shared memory is a static mut of type
SharedArray<f32, N> declared inside the kernel, where N must be known at compile time; we use
one in Chapter 18 for comparison. This form does not work for a kernel that is generic over the
tile width. A static declared inside a function is a separate item of the program, with exactly
1 instance, and Rust does not allow its type to mention a generic parameter of the function that
contains it. For example, SharedArray<f32, { T * T }> inside fn matmul_tiled<const T: usize> is
refused with error E0401. A kernel that is generic over the tile width therefore takes its tiles
from dynamic shared memory. This is a single region per block, whose size in bytes the host
passes in the launch configuration. The call DynamicSharedArray::<f32>::get() returns a raw
pointer of type *mut f32 to the start of the region, and the call
DynamicSharedArray::<f32>::offset(bytes) returns a pointer that lies bytes bytes further on.
The following code declares the 2 tiles in each language.
mod kernels {
// ...
pub fn matmul_tiled<const T: usize>(
m: u32,
n: u32,
k: u32,
a: &[f32],
b: &[f32],
mut c: DisjointSlice<f32, Runtime2DIndex>,
) {
let tile_a: *mut f32 = DynamicSharedArray::<f32>::get();
let tile_b: *mut f32 = DynamicSharedArray::<f32>::offset(T * T * 4);
// ...
}
}// The same product with T x T tiles in shared memory. A block of T x T threads computes
// a T x T square of C in ceil(k / T) phases.
template <int T>
__global__ void matmulTiled(int m, int n, int k, const float* a, const float* b, float* c)
{
__shared__ float tile_a[T][T];
__shared__ float tile_b[T][T];
// ...
}
In Rust, tileA starts at byte 0 of the region and tileB at byte \(4T^2\), immediately after
the \(T^2\) floats of tileA, each of which takes 4 bytes. With \(T = 2\), for example,
tileA occupies bytes 0 to 15 and tileB bytes 16 to 31, so the region must hold 32 bytes. Both
programs store a tile as a flat array of \(T^2\) values in row-major order (Figure 17.13). In
C++, the compiler lays out the 2-dimensional array tile_a[threadIdx.y][threadIdx.x] in this way, while the Rust
kernel computes the index \(\mathsf{threadIdx{.}y} \cdot T + \mathsf{threadIdx{.}x}\) of Definition 16.2 itself. In our example, slot
\((1, 0)\) of a 2 × 2 tile is at index \(1 \cdot 2 + 0 = 2\).
17.7.2 The tiled kernel
Before reading the code, we trace where the data of 1 thread travel (Figure 17.14). In each phase, the thread copies 2 values from global memory into shared memory. From shared memory, it then reads \(2T\) values, \(T\) from a row of tileA and \(T\) from a column of tileB, which feed its \(T\) multiply-adds. Its sum stays in a register throughout, and at the end, a single store writes it into \(C\). In our example with \(T = 2\), thread \((0, 1)\) copies 2 values and reads 4 values in each phase, as in Figure 17.4.
The following code is the loop over the phases, lines 4 to 14 of the pseudocode, together with the initialization of the sum in line 3.
mod kernels {
// ...
pub fn matmul_tiled<const T: usize>(
m: u32,
n: u32,
k: u32,
a: &[f32],
b: &[f32],
mut c: DisjointSlice<f32, Runtime2DIndex>,
) {
// ...
let mut sum = 0.0;
let mut phase = 0;
while phase < k.div_ceil(T) {
let a_col = phase * T + thread_x;
let b_row = phase * T + thread_y;
let a_value = if row < m && a_col < k { a[row * k + a_col] } else { 0.0 };
let b_value = if b_row < k && col < n { b[b_row * n + col] } else { 0.0 };
// SAFETY: tiled_config::<T> launches T x T threads with 2 T^2 floats
// of shared memory, so slot thread_y * T + thread_x lies in each tile
// and belongs to this thread alone; the barrier below completes these writes
// before any thread reads them.
unsafe {
*tile_a.add(thread_y * T + thread_x) = a_value;
*tile_b.add(thread_y * T + thread_x) = b_value;
}
thread::sync_threads();
let mut offset = 0;
#[unroll]
while offset < T {
let a_slot = thread_y * T + offset;
let b_slot = offset * T + thread_x;
// SAFETY: between the 2 barriers no thread writes either tile.
sum += unsafe { *tile_a.add(a_slot) * *tile_b.add(b_slot) };
offset += 1;
}
thread::sync_threads();
phase += 1;
}
// ...
}
}// The same product with T x T tiles in shared memory. A block of T x T threads computes
// a T x T square of C in ceil(k / T) phases.
template <int T>
__global__ void matmulTiled(int m, int n, int k, const float* a, const float* b, float* c)
{
// ...
float sum = 0.0f;
int phases = (k + T - 1) / T;
for (int phase = 0; phase < phases; ++phase) {
int a_col = phase * T + threadIdx.x;
int b_row = phase * T + threadIdx.y;
float a_value = row < m && a_col < k ? a[row * k + a_col] : 0.0f;
float b_value = b_row < k && col < n ? b[b_row * n + col] : 0.0f;
tile_a[threadIdx.y][threadIdx.x] = a_value;
tile_b[threadIdx.y][threadIdx.x] = b_value;
__syncthreads();
for (int offset = 0; offset < T; ++offset) {
sum += tile_a[threadIdx.y][offset] * tile_b[offset][threadIdx.x];
}
__syncthreads();
}
// ...
}
The variable phase counts the phases of line 4. In Rust, the bound of the loop, k.div_ceil(T), is
\(\lceil K/T \rceil\), the quotient \(K/T\) rounded up; in C++, the same bound is computed as
(k + T - 1) / T and stored in phases. The variables a_col and b_row are the indices
\(\mathsf{phase} \cdot T + \mathsf{threadIdx{.}x}\) and \(\mathsf{phase} \cdot T + \mathsf{threadIdx{.}y}\) of lines 7 and 8, that is, the column of \(A\) and the row of
\(B\) that the thread copies. For thread \((0, 1)\) in phase 1 with \(T = 2\), they are
\(1 \cdot 2 + 1 = 3\) and \(1 \cdot 2 + 0 = 2\), as in Section 17.3. When an index lies past
the edge of a matrix, the conditional expression yields 0 instead of reading memory. The first
call to the barrier, thread::sync_threads() in Rust and __syncthreads() in C++, is line 9. It
lies outside every if, so every thread reaches it, as the Rule of Section 17.6.5 requires.
In Rust, the copy is split into two halves. The reads a[row * k + a_col] and b[b_row * n + col]
are ordinary slice reads, bounds-checked like every slice access in safe Rust. The stores through
the raw pointers tile_a and tile_b are different. The compiler cannot check how many threads
write a slot of shared memory, or when, so every access to shared memory must stand in an
unsafe block. Each unsafe block carries a // SAFETY: comment, which is the Rust convention for
stating why the block is sound. The 2 comments of the kernel summarize Section 17.6. The first
states that every thread writes only its own slot, which lies inside the tile because the block
has \(T \times T\) threads, and that the barrier completes these writes before any thread reads
them. The second states that no thread writes either tile between the 2 barriers. In C++, the same
stores need no marking. The argument for their correctness is the same, but the language does not
ask for it.
The inner loop is lines 10 to 12 of the pseudocode. In Rust, thread_x and thread_y hold
\(\mathsf{threadIdx{.}x}\) and \(\mathsf{threadIdx{.}y}\). The slot a_slot, which is
thread_y * T + offset, is the flat index of
\(\mathsf{tileA}[\mathsf{threadIdx{.}y}][\mathsf{offset}]\), so as offset runs from 0 to \(T - 1\), the thread walks along
its own row of tileA. Likewise, b_slot, which is offset * T + thread_x, is the flat index of
\(\mathsf{tileB}[\mathsf{offset}][\mathsf{threadIdx{.}x}]\), and the thread walks down its own column of tileB. For thread
\((0, 1)\) with \(T = 2\), the flat indices are 0 and 1 in tileA and 1 and 3 in tileB. The
Rust loop is a while loop marked #[unroll]. Inside each specialization of the generic kernel,
T is a constant, so the loop has a fixed count, and the compiler replaces it by \(T\) copies of
its body. The C++ compiler unrolls the for loop over a template constant by itself. The second
barrier, line 13, again lies outside every if.
The following code stores the result, lines 15 to 17 of the pseudocode.
mod kernels {
// ...
pub fn matmul_tiled<const T: usize>(
m: u32,
n: u32,
k: u32,
a: &[f32],
b: &[f32],
mut c: DisjointSlice<f32, Runtime2DIndex>,
) {
// ...
if row < m
&& col < n
&& let Some(idx) = thread::index_2d_runtime(&c)
&& let Some(out) = c.get_mut(idx)
{
*out = sum;
}
}
}// The same product with T x T tiles in shared memory. A block of T x T threads computes
// a T x T square of C in ceil(k / T) phases.
template <int T>
__global__ void matmulTiled(int m, int n, int k, const float* a, const float* b, float* c)
{
// ...
if (row < m && col < n) {
c[row * n + col] = sum;
}
}
The final store goes through DisjointSlice exactly as in the direct kernel, guarded by the
condition row < m && col < n. Unlike the direct kernel, however, the tiled kernel has no early
return. A thread outside \(C\) reaches this point only after it has taken part in every phase,
and only then does it skip the store.
17.7.3 The launch
The launch configuration must match T in 3 respects. The block must have \(T \times T\)
threads, so that every slot of a tile has exactly 1 thread to fill it. The grid must have enough
blocks to cover \(C\). In Rust, the dynamic shared memory must also hold the 2 tiles, which take
\(2T^2 \cdot 4\) bytes. The following code builds this configuration and launches the kernel. In
Rust, the function tiled_config computes the configuration and the method Problem::tiled
launches the kernel with it; in C++, the function launchTiled does both.
/// The launch of matmul_tiled::<T> for an m x n matrix C: T x T threads per block,
/// enough blocks to cover C, and 2 tiles of T x T floats in dynamic shared memory.
fn tiled_config<const T: usize>(m: usize, n: usize) -> LaunchConfig2D {
let side = T as u32;
let grid = ((n as u32).div_ceil(side), (m as u32).div_ceil(side));
let shared = (2 * T * T * size_of::<f32>()) as u32;
LaunchConfig2D::new(grid, (side, side), shared)
}
impl Problem {
// ...
/// Launch matmul_tiled::<T> on this problem.
fn tiled<const T: usize>(
&mut self,
module: &Module,
stream: &Arc<CudaStream>,
) -> Result<(), Error> {
let prepared = module.prepare_matmul_tiled::<T>(tiled_config::<T>(self.m, self.n))?;
let (m, n, k) = (self.m as u32, self.n as u32, self.k as u32);
let width = RowWidth::new(&mut self.c, n);
module.matmul_tiled::<T>(stream, &prepared, m, n, k, &self.a, &self.b, width)?;
Ok(())
}
// ...
}template <int T>
void launchTiled(const Product& p)
{
dim3 grid((p.n + T - 1) / T, (p.m + T - 1) / T);
matmulTiled<T><<<grid, dim3(T, T)>>>(p.m, p.n, p.k, p.a, p.b, p.c);
}
For \(T = 16\) and \(M = N = 1{,}000\), tiled_config returns a grid of 63 × 63 blocks, since
\(\lceil 1{,}000/16 \rceil = 63\), with 16 × 16 threads per block and
\(2 \cdot 16^2 \cdot 4 = 2{,}048\) bytes of dynamic shared memory. The launch contract of the
Rust kernel checks what it can. The setting dynamic_shared_range = (32, 8192) accepts amounts
from the 32 bytes of \(T = 2\) up to the 8,192 bytes of \(T = 32\), and the attribute
#[launch_bounds(1024)] limits a block to 1,024 threads. The requires clause checks the lengths
of the buffers, as in Chapter 16. An exact block shape such as block = (16, 16, 1), however, must
be written as literal numbers, so it cannot depend on T, and the contract therefore cannot check
that the block is \(T \times T\). This condition moves into the program instead. The function
tiled_config::<T> derives the block, the grid and the shared memory from T in 1 place, and the
SAFETY comment of the copy names it.
Exercises
17.10 Set T to 32. Predict the effect on fetches from global memory and on shared memory per
block.
17.11 Launch matmul_tiled::<16> with blocks of 8 × 8 threads and 2,048 bytes of dynamic shared
memory. Does the contract accept the launch? Which part of the SAFETY argument fails, and which
entries of \(C\) are wrong?
17.12 Each thread of the tiled kernel performs 2 arithmetic operations for every 2 values it reads
from shared memory. Design a variant in which each thread computes several entries of \(C\), so
that every value read from shared memory is used more than once.
17.8 Measurements
17.8.1 Results
The measurements come from the GPU of Chapter 16, which has 8 SMs, a memory bandwidth of 102 GB/s and an FP32 peak of 2,400 GFLOP/s, and we use the method of Section 16.6.1. Both programs time the direct kernel and the tiled kernel with \(T = 8\), 16 and 32, on square matrices from 512 × 512 to 4,096 × 4,096. The Rust program prints the following output.
$ cargo oxide run
C = A B on the 4 x 4 example, tiles of 2 x 2, 2 phases
11 13 8 8
27 29 24 24
43 45 40 40
59 61 56 56
equal to the product computed by hand: yes
Sizes that are not multiples of the tile width
m = 3, k = 3, n = 3, T = 2: 9 of 9 entries exact
m = 128, k = 64, n = 96, T = 16: 12288 of 12288 entries exact
m = 1000, k = 1000, n = 1000, T = 16: 1000000 of 1000000 entries exact
C = A B, n x n; fetched: the modelled reads from global memory
n kernel ms GFLOP/s fetched MiB fetch GB/s exact
512 direct 1.462 183.6 1024.0 734.3 64 of 64
512 T = 8 1.918 140.0 128.0 70.0 64 of 64
512 T = 16 0.946 283.6 64.0 70.9 64 of 64
512 T = 32 1.133 237.0 32.0 29.6 64 of 64
1024 direct 15.561 138.0 8192.0 552.0 64 of 64
1024 T = 8 15.368 139.7 1024.0 69.9 64 of 64
1024 T = 16 8.192 262.1 512.0 65.5 64 of 64
1024 T = 32 9.816 218.8 256.0 27.3 64 of 64
2048 direct 125.589 136.8 65536.0 547.2 64 of 64
2048 T = 8 123.308 139.3 8192.0 69.7 64 of 64
2048 T = 16 66.321 259.0 4096.0 64.8 64 of 64
2048 T = 32 80.277 214.0 2048.0 26.8 64 of 64
4096 direct 996.270 138.0 524288.0 551.8 64 of 64
4096 T = 8 1004.860 136.8 65536.0 68.4 64 of 64
4096 T = 16 531.679 258.5 32768.0 64.6 64 of 64
4096 T = 32 668.652 205.5 16384.0 25.7 64 of 64
PASSED
The first part of the output repeats the 4 × 4 example and the 3 shapes of Section 17.6.5. In the table that follows, the column fetched MiB is the model of Section 17.5, \(2n^3/T\) values of 4 bytes, where \(n\) is the size of the matrices and \(T = 1\) for the direct kernel. For example, at \(n = 512\) with \(T = 16\), the model gives \(2 \cdot 512^3 / 16 = 16{,}777{,}216\) values, or 64 MiB. The column fetch GB/s divides this amount by the time, so it is the rate at which the kernel requests data from global memory, whether or not a cache answers the request. The C++ program prints the same lines. The following table compares the two languages at the smallest and the largest size.
| n | kernel | modeled fetches | C++ time | C++ rate | Rust time | Rust rate |
|---|---|---|---|---|---|---|
| 512 | direct | 1,024 MiB | 1.495 ms | 179.5 GFLOP/s | 1.462 ms | 183.6 GFLOP/s |
| 512 | \(T = 8\) | 128 MiB | 1.809 ms | 148.4 GFLOP/s | 1.918 ms | 140.0 GFLOP/s |
| 512 | \(T = 16\) | 64 MiB | 0.976 ms | 275.2 GFLOP/s | 0.946 ms | 283.6 GFLOP/s |
| 512 | \(T = 32\) | 32 MiB | 1.079 ms | 248.7 GFLOP/s | 1.133 ms | 237.0 GFLOP/s |
| 4,096 | direct | 524,288 MiB | 744.953 ms | 184.5 GFLOP/s | 996.270 ms | 138.0 GFLOP/s |
| 4,096 | \(T = 8\) | 65,536 MiB | 982.887 ms | 139.8 GFLOP/s | 1,004.860 ms | 136.8 GFLOP/s |
| 4,096 | \(T = 16\) | 32,768 MiB | 505.159 ms | 272.1 GFLOP/s | 531.679 ms | 258.5 GFLOP/s |
| 4,096 | \(T = 32\) | 16,384 MiB | 637.641 ms | 215.5 GFLOP/s | 668.652 ms | 205.5 GFLOP/s |
With \(T = 16\), the tiled kernel made, in the model of Section 17.5, 16 times fewer fetches than the direct kernel. In C++, it ran 1.53 times as fast as the direct kernel at 512 × 512 (1.495 ms against 0.976 ms) and 1.47 times as fast at 4,096 × 4,096. In Rust, the factors are 1.55 and 1.87. The second Rust factor is larger because the generic Rust direct kernel is slower at large sizes (Section 16.6.3). The Rust and C++ tiled kernels agree within 6% at every size. All checked entries were exact, including those of the 3 shapes that are not multiples of the tile width. Figure 17.15 shows the rates at \(n = 4{,}096\) against two limits, which we explain in the next section.
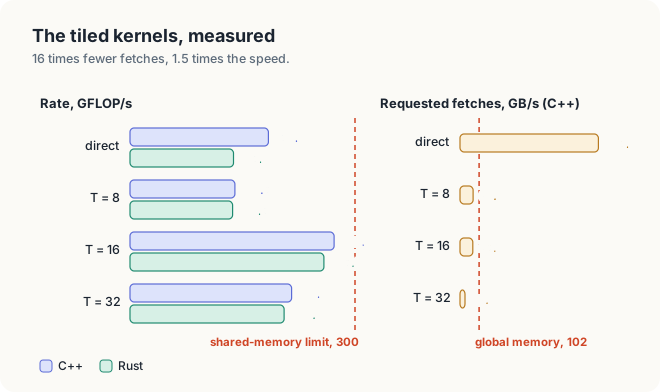
17.8.2 Why the speedup is 1.5, not 16
Tiling reduced the fetches by a factor of 16, yet the kernel became only about 1.5 times as fast. The reason is that our model in Section 17.5 counted fetches as if every fetch went all the way to global memory. In Section 16.6.3, we saw that this is not true for the direct kernel. It requested 738 GB/s, which is 7.2 times what global memory can deliver, so at least 86% of its fetches were answered by the L1 and L2 caches. Tiling removes 15 of every 16 requested fetches, but most of the fetches that it removes were already cheap. In effect, the hardware caches had already recovered part of the reuse that tiling makes explicit.
The difference between the two approaches is control. A value stays in a cache only by chance, and the chance shrinks as the matrices grow beyond the size of the cache. A value in shared memory stays there for exactly 1 phase, by construction, at every matrix size. The tiled kernel with \(T = 16\) requested 68 GB/s from global memory, two-thirds of the 102 GB/s available, so global memory is no longer what limits it.
What limits the tiled kernel now is shared memory. Each execution of line 11 performs 1 multiply-add and reads 2 values from shared memory, \(\mathsf{tileA}[\mathsf{threadIdx{.}y}][\mathsf{offset}]\) and \(\mathsf{tileB}[\mathsf{offset}][\mathsf{threadIdx{.}x}]\). The shared memory of an SM serves 1 read instruction of a warp per cycle, that is, 32 values of 4 bytes, or 128 bytes per cycle, provided that the 32 addresses fall in different banks or coincide. The 128 FP32 units of the SM, on the other hand, can perform 128 multiply-adds per cycle. Let us count for 1 warp. Its 32 multiply-adds need 2 read instructions, 1 for each tile, and therefore 2 cycles of shared memory. The SM thus completes at most \(32 / 2 = 16\) multiply-adds per cycle, 1/8 of the 128 that its units could perform. On the measured GPU, that limit is \(2{,}400 / 8 = 300\) GFLOP/s. The C++ kernel with \(T = 16\) reached 272 to 275 GFLOP/s at every size, 91% of the limit, and the Rust kernel reached 259 to 284 GFLOP/s. A larger tile reduces the fetches from global memory, but it does not change this ratio, because every multiply-add of the tiled kernel still costs 2 reads of shared memory.
The other 2 tile widths are slower, each for a reason of its own. To explain the first reason, we need 1 more definition. A block of 32 × 32 = 1,024 threads leaves no room for a second block on an SM of the measured GPU, which holds at most 1,536 threads.
Definition 17.3 Occupancy. The occupancy of a kernel is the number of threads resident on an SM divided by the largest number the SM can hold.
Example. With \(T = 32\), each SM of the measured GPU runs 1 block of 1,024 threads out of 1,536, an occupancy of 67%; with \(T = 16\), it runs 6 blocks of 256 threads, an occupancy of 100%.
With \(T = 32\), the SM therefore runs a single block, and when the threads of that block wait at a barrier, the SM has no other block to run, so it idles. This kernel ran at 216 GFLOP/s, although it fetched half as much as the kernel with \(T = 16\). With \(T = 8\), a block has only 64 threads, and each thread performs only 8 multiply-adds between 2 barriers, so the copy and the barriers take a larger share of each phase. Moreover, an SM holds at most 16 blocks, which with \(T = 8\) is only 1,024 threads. This kernel ran at 140 GFLOP/s, slower than the direct kernel in C++.
The speedup differs between GPUs, because it depends on how well the caches serve the direct kernel. On a Jetson AGX Thor, Rust kernels for the same two algorithms with \(T = 16\) took 1.158 ms and 0.285 ms for 512 × 512 matrices, a speedup of 4.06 (Pathak, 2026). On that GPU, the direct kernel requested 927 GB/s, 3.4 times the 273 GB/s of the Thor’s memory, so the caches answered at least 70% of its fetches, against 86% on the measured GPU, and tiling had more to gain. The tiled kernel ran at 941.5 GFLOP/s, 93% of the Thor’s shared-memory limit of \(8{,}100 / 8 = 1{,}012\) GFLOP/s. On both GPUs, the tiled kernel ends near the same limit, 1/8 of the arithmetic peak, and we remove this limit in Chapter 18.
17.9 The complete programs
The following listings are the complete programs of this chapter, in Rust and in CUDA C++.
//! Chapter 17: tiled matrix multiplication in shared memory, against the direct kernel.
//!
//! cargo oxide run
use std::sync::Arc;
use std::time::Instant;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, LaunchConfig2D};
use cuda_device::thread::Runtime2DIndex;
use cuda_device::{DisjointSlice, DynamicSharedArray, cuda_module, kernel, thread};
use cuda_device::{launch_bounds, launch_contract};
use cuda_host::RowWidth;
type Error = Box<dyn std::error::Error>;
type Module = kernels::LoadedModule;
#[cuda_module]
mod kernels {
use super::*;
/// C (m x n) = A (m x k) B (k x n), all row-major. 1 thread computes 1 entry of C and
/// fetches all its operands from global memory.
#[kernel]
#[launch_bounds(256)]
#[launch_contract(
domain = 2,
coordinates = u32,
requires = (a.len() >= m * k, b.len() >= k * n, c.len() >= m * n)
)]
pub fn matmul_direct(
m: u32,
n: u32,
k: u32,
a: &[f32],
b: &[f32],
mut c: DisjointSlice<f32, Runtime2DIndex>,
) {
let row = thread::index_2d_row();
let col = thread::index_2d_col();
let (m, n, k) = (m as usize, n as usize, k as usize);
if row < m
&& col < n
&& let Some(idx) = thread::index_2d_runtime(&c)
&& let Some(out) = c.get_mut(idx)
{
let mut sum = 0.0;
let mut inner = 0;
#[unroll(4)]
while inner < k {
sum += a[row * k + inner] * b[inner * n + col];
inner += 1;
}
*out = sum;
}
}
/// The same product with T x T tiles in shared memory. A block of T x T threads
/// computes a T x T square of C in ceil(k / T) phases.
#[kernel]
#[launch_bounds(1024)]
#[launch_contract(
domain = 2,
coordinates = u32,
dynamic_shared_range = (32, 8192),
requires = (a.len() >= m * k, b.len() >= k * n, c.len() >= m * n)
)]
pub fn matmul_tiled<const T: usize>(
m: u32,
n: u32,
k: u32,
a: &[f32],
b: &[f32],
mut c: DisjointSlice<f32, Runtime2DIndex>,
) {
let tile_a: *mut f32 = DynamicSharedArray::<f32>::get();
let tile_b: *mut f32 = DynamicSharedArray::<f32>::offset(T * T * 4);
let thread_x = thread::threadIdx_x() as usize;
let thread_y = thread::threadIdx_y() as usize;
let row = thread::index_2d_row();
let col = thread::index_2d_col();
let (m, n, k) = (m as usize, n as usize, k as usize);
let mut sum = 0.0;
let mut phase = 0;
while phase < k.div_ceil(T) {
let a_col = phase * T + thread_x;
let b_row = phase * T + thread_y;
let a_value = if row < m && a_col < k { a[row * k + a_col] } else { 0.0 };
let b_value = if b_row < k && col < n { b[b_row * n + col] } else { 0.0 };
// SAFETY: tiled_config::<T> launches T x T threads with 2 T^2 floats
// of shared memory, so slot thread_y * T + thread_x lies in each tile
// and belongs to this thread alone; the barrier below completes these writes
// before any thread reads them.
unsafe {
*tile_a.add(thread_y * T + thread_x) = a_value;
*tile_b.add(thread_y * T + thread_x) = b_value;
}
thread::sync_threads();
let mut offset = 0;
#[unroll]
while offset < T {
let a_slot = thread_y * T + offset;
let b_slot = offset * T + thread_x;
// SAFETY: between the 2 barriers no thread writes either tile.
sum += unsafe { *tile_a.add(a_slot) * *tile_b.add(b_slot) };
offset += 1;
}
thread::sync_threads();
phase += 1;
}
if row < m
&& col < n
&& let Some(idx) = thread::index_2d_runtime(&c)
&& let Some(out) = c.get_mut(idx)
{
*out = sum;
}
}
}
/// The launch of matmul_tiled::<T> for an m x n matrix C: T x T threads per block,
/// enough blocks to cover C, and 2 tiles of T x T floats in dynamic shared memory.
fn tiled_config<const T: usize>(m: usize, n: usize) -> LaunchConfig2D {
let side = T as u32;
let grid = ((n as u32).div_ceil(side), (m as u32).div_ceil(side));
let shared = (2 * T * T * size_of::<f32>()) as u32;
LaunchConfig2D::new(grid, (side, side), shared)
}
/// The launch of matmul_direct: blocks of 16 x 16 threads that cover C.
fn direct_config(m: usize, n: usize) -> LaunchConfig2D {
let grid = ((n as u32).div_ceil(16), (m as u32).div_ceil(16));
LaunchConfig2D::new(grid, (16, 16), 0)
}
/// Average time of `runs` launches in milliseconds, after 1 launch that is not timed.
fn time_ms<F>(stream: &CudaStream, runs: u32, mut launch: F) -> Result<f64, Error>
where
F: FnMut() -> Result<(), Error>,
{
launch()?;
stream.synchronize()?;
let start = Instant::now();
for _ in 0..runs {
launch()?;
}
stream.synchronize()?;
Ok(start.elapsed().as_secs_f64() * 1e3 / runs as f64)
}
/// Integers in [-5, 5] from a small linear congruential generator: every partial sum
/// of a product with k <= 4096 is an integer below 2^24, so f32 results are exact.
fn integers(len: usize, state: &mut u32) -> Vec<f32> {
let mut values = Vec::with_capacity(len);
for _ in 0..len {
*state = state.wrapping_mul(1_664_525).wrapping_add(1_013_904_223);
values.push(((*state >> 8) % 11) as f32 - 5.0);
}
values
}
/// An m x k by k x n product: the inputs on the host and all 3 matrices on the device.
struct Problem {
m: usize,
n: usize,
k: usize,
a_host: Vec<f32>,
b_host: Vec<f32>,
a: DeviceBuffer<f32>,
b: DeviceBuffer<f32>,
c: DeviceBuffer<f32>,
}
impl Problem {
fn new(stream: &Arc<CudaStream>, m: usize, n: usize, k: usize) -> Result<Self, Error> {
let mut state = if m == n && n == k { 1 } else { 7 };
let a_host = integers(m * k, &mut state);
let b_host = integers(k * n, &mut state);
let a = DeviceBuffer::from_host(stream, &a_host)?;
let b = DeviceBuffer::from_host(stream, &b_host)?;
let c = DeviceBuffer::<f32>::zeroed(stream, m * n)?;
Ok(Problem { m, n, k, a_host, b_host, a, b, c })
}
/// Launch matmul_direct on this problem.
fn direct(&mut self, module: &Module, stream: &Arc<CudaStream>) -> Result<(), Error> {
let prepared = module.prepare_matmul_direct(direct_config(self.m, self.n))?;
let (m, n, k) = (self.m as u32, self.n as u32, self.k as u32);
let width = RowWidth::new(&mut self.c, n);
module.matmul_direct(stream, &prepared, m, n, k, &self.a, &self.b, width)?;
Ok(())
}
/// Launch matmul_tiled::<T> on this problem.
fn tiled<const T: usize>(
&mut self,
module: &Module,
stream: &Arc<CudaStream>,
) -> Result<(), Error> {
let prepared = module.prepare_matmul_tiled::<T>(tiled_config::<T>(self.m, self.n))?;
let (m, n, k) = (self.m as u32, self.n as u32, self.k as u32);
let width = RowWidth::new(&mut self.c, n);
module.matmul_tiled::<T>(stream, &prepared, m, n, k, &self.a, &self.b, width)?;
Ok(())
}
/// The number of `samples` entries of C (all of them if C is smaller) that are exact.
fn exact_entries(&self, stream: &CudaStream, samples: usize) -> Result<usize, Error> {
let (m, n, k) = (self.m, self.n, self.k);
let c = self.c.to_host_vec(stream)?;
let count = samples.min(m * n);
let mut exact = 0;
for sample in 0..count {
let row = if count == m * n { sample / n } else { sample * 977 % m };
let col = if count == m * n { sample % n } else { (sample * 1231 + 7) % n };
let mut sum = 0.0;
for inner in 0..k {
let a_value = self.a_host[row * k + inner] as f64;
let b_value = self.b_host[inner * n + col] as f64;
sum += a_value * b_value;
}
if c[row * n + col] as f64 == sum {
exact += 1;
}
}
Ok(exact)
}
}
/// The 4 x 4 example with T = 2: 4 blocks of 2 x 2 threads, 2 phases each.
fn run_example(module: &Module, stream: &Arc<CudaStream>) -> Result<bool, Error> {
let a_int = [1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12, 13, 14, 15, 16];
let b_int = [1, 0, 2, 1, 0, 1, 1, 2, 2, 1, 0, 1, 1, 2, 1, 0];
let want = [11, 13, 8, 8, 27, 29, 24, 24, 43, 45, 40, 40, 59, 61, 56, 56];
let mut p = Problem::new(stream, 4, 4, 4)?;
p.a_host = a_int.iter().map(|&x| x as f32).collect();
p.b_host = b_int.iter().map(|&x| x as f32).collect();
p.a = DeviceBuffer::from_host(stream, &p.a_host)?;
p.b = DeviceBuffer::from_host(stream, &p.b_host)?;
p.tiled::<2>(module, stream)?;
let c = p.c.to_host_vec(stream)?;
println!("C = A B on the 4 x 4 example, tiles of 2 x 2, 2 phases");
for row in c.chunks(4) {
println!(" {:4} {:4} {:4} {:4}", row[0], row[1], row[2], row[3]);
}
let same = c.iter().zip(want).all(|(&got, w)| got == w as f32);
let answer = if same { "yes" } else { "no" };
println!("equal to the product computed by hand: {answer}\n");
Ok(same)
}
/// Sizes that are not multiples of T: every entry of C is checked.
fn run_shape<const T: usize>(
module: &Module,
stream: &Arc<CudaStream>,
(m, n, k): (usize, usize, usize),
) -> Result<bool, Error> {
let mut p = Problem::new(stream, m, n, k)?;
p.tiled::<T>(module, stream)?;
let exact = p.exact_entries(stream, m * n)?;
let all = m * n;
print!(" m = {m:4}, k = {k:4}, n = {n:4}, T = {T:2}:");
println!(" {exact:7} of {all:7} entries exact");
Ok(exact == all)
}
/// Time 1 kernel on n x n matrices and print 1 line of the table. `tile` is 1 for the
/// direct kernel, which fetches every operand from global memory.
fn run_timed<F>(
stream: &Arc<CudaStream>,
name: &str,
n: usize,
tile: usize,
launch: F,
) -> Result<bool, Error>
where
F: Fn(&mut Problem) -> Result<(), Error>,
{
let mut p = Problem::new(stream, n, n, n)?;
let cube = (n * n * n) as f64;
let runs = (1e11 / (cube * 4.0)) as u32 + 2;
let ms = time_ms(stream, runs.min(50), || launch(&mut p))?;
let exact = p.exact_entries(stream, 64)?;
let gflops = 2.0 * cube / ms / 1e6;
let fetched = 2.0 * cube / tile as f64 * 4.0;
let mib = fetched / (1 << 20) as f64;
let rate = fetched / ms / 1e6;
print!(" {n:5} {name:<10} {ms:9.3} {gflops:9.1} {mib:12.1} {rate:11.1}");
println!(" {exact:6} of 64");
Ok(exact == 64)
}
/// About 0.5 s of 1024 x 1024 products: the GPU raises its clocks under sustained load.
fn warm_up(module: &Module, stream: &Arc<CudaStream>) -> Result<(), Error> {
let mut p = Problem::new(stream, 1024, 1024, 1024)?;
let start = Instant::now();
while start.elapsed().as_millis() < 500 {
p.tiled::<16>(module, stream)?;
stream.synchronize()?;
}
Ok(())
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let (module, stream) = (&module, &stream);
let mut passed = run_example(module, stream)?;
println!("Sizes that are not multiples of the tile width");
passed &= run_shape::<2>(module, stream, (3, 3, 3))?;
passed &= run_shape::<16>(module, stream, (128, 96, 64))?;
passed &= run_shape::<16>(module, stream, (1000, 1000, 1000))?;
println!();
warm_up(module, stream)?;
println!("C = A B, n x n; fetched: the modelled reads from global memory");
print!(" n kernel ms GFLOP/s");
println!(" fetched MiB fetch GB/s exact");
for n in [512, 1024, 2048, 4096] {
passed &= run_timed(stream, "direct", n, 1, |p| p.direct(module, stream))?;
passed &= run_timed(stream, "T = 8", n, 8, |p| p.tiled::<8>(module, stream))?;
passed &= run_timed(stream, "T = 16", n, 16, |p| p.tiled::<16>(module, stream))?;
passed &= run_timed(stream, "T = 32", n, 32, |p| p.tiled::<32>(module, stream))?;
}
println!("{}", if passed { "PASSED" } else { "FAILED" });
Ok(())
}// Chapter 17: tiled matrix multiplication in shared memory, against the direct kernel.
// Build: nvcc -O3 -arch=native matmul_tiled.cu -o matmul_tiled
#include <chrono>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cuda_runtime.h>
using Matrix = std::vector<float>;
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
// C (m x n) = A (m x k) B (k x n), all row-major. 1 thread computes 1 entry of C and
// fetches all its operands from global memory.
__global__ void matmulDirect(int m, int n, int k, const float* a, const float* b, float* c)
{
int row = blockIdx.y * blockDim.y + threadIdx.y;
int col = blockIdx.x * blockDim.x + threadIdx.x;
if (row >= m || col >= n) {
return;
}
float sum = 0.0f;
for (int inner = 0; inner < k; ++inner) {
sum += a[row * k + inner] * b[inner * n + col];
}
c[row * n + col] = sum;
}
// The same product with T x T tiles in shared memory. A block of T x T threads computes
// a T x T square of C in ceil(k / T) phases.
template <int T>
__global__ void matmulTiled(int m, int n, int k, const float* a, const float* b, float* c)
{
__shared__ float tile_a[T][T];
__shared__ float tile_b[T][T];
int row = blockIdx.y * T + threadIdx.y;
int col = blockIdx.x * T + threadIdx.x;
float sum = 0.0f;
int phases = (k + T - 1) / T;
for (int phase = 0; phase < phases; ++phase) {
int a_col = phase * T + threadIdx.x;
int b_row = phase * T + threadIdx.y;
float a_value = row < m && a_col < k ? a[row * k + a_col] : 0.0f;
float b_value = b_row < k && col < n ? b[b_row * n + col] : 0.0f;
tile_a[threadIdx.y][threadIdx.x] = a_value;
tile_b[threadIdx.y][threadIdx.x] = b_value;
__syncthreads();
for (int offset = 0; offset < T; ++offset) {
sum += tile_a[threadIdx.y][offset] * tile_b[offset][threadIdx.x];
}
__syncthreads();
}
if (row < m && col < n) {
c[row * n + col] = sum;
}
}
// A product on the device: the 3 buffers and their sizes.
struct Product {
int m, n, k;
float *a, *b, *c;
};
template <int T>
void launchTiled(const Product& p)
{
dim3 grid((p.n + T - 1) / T, (p.m + T - 1) / T);
matmulTiled<T><<<grid, dim3(T, T)>>>(p.m, p.n, p.k, p.a, p.b, p.c);
}
void launchDirect(const Product& p)
{
dim3 grid((p.n + 15) / 16, (p.m + 15) / 16);
matmulDirect<<<grid, dim3(16, 16)>>>(p.m, p.n, p.k, p.a, p.b, p.c);
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// Average time of `runs` launches in milliseconds, after 1 launch that is not timed.
template <typename F>
double timeMs(F launch, int runs)
{
launch();
check(cudaDeviceSynchronize());
double start = nowMs();
for (int r = 0; r < runs; ++r) {
launch();
}
check(cudaGetLastError());
check(cudaDeviceSynchronize());
return (nowMs() - start) / runs;
}
// Integers in [-5, 5] from a small linear congruential generator: every partial sum
// of a product with k <= 4096 is an integer below 2^24, so float results are exact.
Matrix integers(size_t len, unsigned* state)
{
Matrix values(len);
for (size_t i = 0; i < len; ++i) {
*state = *state * 1664525u + 1013904223u;
values[i] = float(int((*state >> 8) % 11) - 5);
}
return values;
}
// The number of `samples` entries of C (all of them if C is smaller) that are exact.
int exactEntries(const Matrix& a, const Matrix& b, const Matrix& c,
int m, int n, int k, int samples)
{
int count = m * n < samples ? m * n : samples;
int exact = 0;
for (int sample = 0; sample < count; ++sample) {
int row = count == m * n ? sample / n : sample * 977 % m;
int col = count == m * n ? sample % n : (sample * 1231 + 7) % n;
double sum = 0.0;
for (int inner = 0; inner < k; ++inner) {
sum += double(a[row * k + inner]) * double(b[inner * n + col]);
}
exact += double(c[row * n + col]) == sum;
}
return exact;
}
// Host and device copies of A, B and C for an m x k by k x n product.
struct Problem {
Matrix a, b, c;
Product gpu;
};
Problem makeProblem(int m, int n, int k, unsigned seed)
{
Problem p;
p.a = integers(size_t(m) * k, &seed);
p.b = integers(size_t(k) * n, &seed);
p.c.resize(size_t(m) * n);
p.gpu = {m, n, k, nullptr, nullptr, nullptr};
check(cudaMalloc(&p.gpu.a, p.a.size() * sizeof(float)));
check(cudaMalloc(&p.gpu.b, p.b.size() * sizeof(float)));
check(cudaMalloc(&p.gpu.c, p.c.size() * sizeof(float)));
check(cudaMemcpy(p.gpu.a, p.a.data(), p.a.size() * 4, cudaMemcpyHostToDevice));
check(cudaMemcpy(p.gpu.b, p.b.data(), p.b.size() * 4, cudaMemcpyHostToDevice));
return p;
}
// Copy C back, free the device buffers, and count the exact entries.
int finish(Problem& p, int samples)
{
check(cudaMemcpy(p.c.data(), p.gpu.c, p.c.size() * 4, cudaMemcpyDeviceToHost));
check(cudaFree(p.gpu.a));
check(cudaFree(p.gpu.b));
check(cudaFree(p.gpu.c));
return exactEntries(p.a, p.b, p.c, p.gpu.m, p.gpu.n, p.gpu.k, samples);
}
// The 4 x 4 example with T = 2: 4 blocks of 2 x 2 threads, 2 phases each.
bool runExample()
{
Matrix a{1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12, 13, 14, 15, 16};
Matrix b{1, 0, 2, 1, 0, 1, 1, 2, 2, 1, 0, 1, 1, 2, 1, 0};
Matrix want{11, 13, 8, 8, 27, 29, 24, 24, 43, 45, 40, 40, 59, 61, 56, 56};
Matrix c(16);
Product p = {4, 4, 4, nullptr, nullptr, nullptr};
check(cudaMalloc(&p.a, 64));
check(cudaMalloc(&p.b, 64));
check(cudaMalloc(&p.c, 64));
check(cudaMemcpy(p.a, a.data(), 64, cudaMemcpyHostToDevice));
check(cudaMemcpy(p.b, b.data(), 64, cudaMemcpyHostToDevice));
launchTiled<2>(p);
check(cudaGetLastError());
check(cudaMemcpy(c.data(), p.c, 64, cudaMemcpyDeviceToHost));
check(cudaFree(p.a));
check(cudaFree(p.b));
check(cudaFree(p.c));
std::printf("C = A B on the 4 x 4 example, tiles of 2 x 2, 2 phases\n");
for (int i = 0; i < 4; ++i) {
const float* row = &c[i * 4];
std::printf(" %4.0f %4.0f %4.0f %4.0f\n", row[0], row[1], row[2], row[3]);
}
bool same = c == want;
std::printf("equal to the product computed by hand: %s\n\n", same ? "yes" : "no");
return same;
}
// Sizes that are not multiples of T: every entry of C is checked.
template <int T>
bool runShape(int m, int n, int k)
{
Problem p = makeProblem(m, n, k, 7);
launchTiled<T>(p.gpu);
check(cudaGetLastError());
int exact = finish(p, m * n);
std::printf(" m = %4d, k = %4d, n = %4d, T = %2d:", m, k, n, T);
std::printf(" %7d of %7d entries exact\n", exact, m * n);
return exact == m * n;
}
// Time 1 kernel on n x n matrices and print 1 line of the table.
template <typename F>
bool runTimed(const char* name, int n, int tile, F launch)
{
Problem p = makeProblem(n, n, n, 1);
double cube = double(n) * n * n;
int runs = cube * 4 > 1e11 ? 2 : int(1e11 / (cube * 4)) + 2;
double ms = timeMs([&] { launch(p.gpu); }, runs < 50 ? runs : 50);
int exact = finish(p, 64);
double gflops = 2.0 * cube / ms / 1e6;
double fetched = 2.0 * cube / tile * 4.0;
double mib = fetched / (1 << 20);
double rate = fetched / ms / 1e6;
std::printf(" %5d %-10s %9.3f %9.1f %12.1f %11.1f", n, name, ms, gflops, mib, rate);
std::printf(" %6d of 64\n", exact);
return exact == 64;
}
// About 0.5 s of 1024 x 1024 products: the GPU raises its clocks under sustained load.
void warmUp()
{
Problem p = makeProblem(1024, 1024, 1024, 1);
double start = nowMs();
while (nowMs() - start < 500.0) {
launchTiled<16>(p.gpu);
check(cudaDeviceSynchronize());
}
finish(p, 1);
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %d SMs\n\n", prop.name, prop.multiProcessorCount);
bool passed = runExample();
std::printf("Sizes that are not multiples of the tile width\n");
passed &= runShape<2>(3, 3, 3);
passed &= runShape<16>(128, 96, 64);
passed &= runShape<16>(1000, 1000, 1000);
std::printf("\n");
warmUp();
std::printf("C = A B, n x n; fetched: the modelled reads from global memory\n");
std::printf(" n kernel ms GFLOP/s");
std::printf(" fetched MiB fetch GB/s exact\n");
for (int n : {512, 1024, 2048, 4096}) {
passed &= runTimed("direct", n, 1, launchDirect);
passed &= runTimed("T = 8", n, 8, launchTiled<8>);
passed &= runTimed("T = 16", n, 16, launchTiled<16>);
passed &= runTimed("T = 32", n, 32, launchTiled<32>);
}
std::printf("%s\n", passed ? "PASSED" : "FAILED");
return passed ? 0 : 1;
}
The Rust program is built and run with cargo oxide run in its directory, and the C++ program
with nvcc -O3 -arch=native matmul_tiled.cu -o matmul_tiled && ./matmul_tiled.
Common mistakes
- Omitting a barrier. Without the first barrier, threads read slots before they are filled. Without the second, a fast thread overwrites a tile that a slow thread is still reading. Neither mistake produces an error or a compiler warning (Section 17.6.3).
- Returning early from a tiled kernel. A thread outside \(C\) must still copy zeros and reach every barrier; only its final store is skipped.
- Forgetting the zeros. Without the
else 0of lines 7 and 8, a tile at the edge holds values of the previous phase or of another matrix, and the last phase adds them to the sum. - A block shape that does not match the tile. With fewer than \(T \times T\) threads, part of
each tile is never filled; with more, threads write past the end of the tile. In Rust, the shape
is best derived from
Tin 1 function. - Assuming that shared-memory indices are checked. An index through the pointers of
DynamicSharedArray, or into a C++__shared__array, is not compared with any length. - Choosing the largest tile. \(T = 32\) fetches half as much as \(T = 16\), but it ran slower, because a block of 1,024 threads fills an SM on its own (Section 17.8.2).
Summary
- A block of \(T \times T\) threads needs \(T\) rows of \(A\) and \(T\) columns of \(B\), and the direct kernel fetches each of these values \(T\) times.
- Splitting each dot product into phases of \(T\) terms lets the block copy 1 tile of \(A\) and 1 tile of \(B\) into shared memory per phase, 1 value per thread, after which every thread adds \(T\) terms from the copy.
- The tiled kernel fetches \(2MNK/T\) values instead of \(2MNK\), that is, it performs \(T\) FLOP per float fetched instead of 1.
- The first barrier orders the copy before the reads (without it, \(c_{00} = 7\)), and the second orders the reads before the next copy (without it, \(c_{01} = 15\)). A loop invariant proves the kernel correct, and the proof uses each barrier once.
- Zeros outside the matrices, together with threads that stay in the loop, handle matrices of any size. Every thread of a block must reach every barrier.
- In Rust, shared memory is
unsafeto access, and each access states its argument in a// SAFETY:comment; a tile sized by a generic parameter lives in dynamic shared memory. In C++, a__shared__array can be sized by a template parameter. - On the measured GPU, tiles of 16 × 16 ran about 1.5 times as fast as the direct kernel, not 16 times. The caches had already absorbed most of the direct kernel’s repeated fetches, and the tiled kernel is limited by its 2 shared-memory reads per multiply-add.
In Chapter 18, we remove the second limit by letting each thread compute several entries of \(C\) and keep their sums in registers, so that each value read from shared memory is used several times.
Exercises
- For \(T = 16\) and \(M = N = K = 4{,}096\), how many floats does 1 block copy from global memory over the whole kernel, and how many FLOP does it perform? Check that the ratio is 16.
- Thread \((7, 12)\) of block \((3, 5)\) with \(T = 16\): which slot of each tile does it write, and which entries of \(A\) and \(B\) does it copy in phase 2?
- Remove the second barrier from the Rust kernel and run it 5 times on your GPU at 512 × 512. Record the number of wrong entries each time, and explain why the number varies.
- Change the phase sum to compute
a_slotasoffset * T + thread_yinstead ofthread_y * T + offset, without changing the copy. Which entries of the 4 × 4 example are still correct, and why? - Add \(T = 4\) to the program. Predict its fetches and its shared-memory limit, and compare with the measured rate.
- Draw the timeline of Figure 17.8 for thread \((1, 1)\) instead of \((0, 0)\). Which entry becomes wrong, and what value does it take?
- Rewrite
tiled_config::<T>to return an error whenT * Texceeds 1,024 threads, and call it for \(T = 64\).
Sources and further reading
- A. Pathak, An Introduction to Tiled Parallel Programming, Simplified, 2026: the derivation of the tiled kernel on the 4 × 4 example, the 2 broken kernels, the proof, and the measurements on a Jetson AGX Thor quoted in Section 17.8.
- T. H. Cormen, C. E. Leiserson, R. L. Rivest and C. Stein, Introduction to Algorithms, 4th ed., MIT Press, 2022: loop invariants.
- NVIDIA, CUDA C++ Programming Guide, “Shared Memory” and
__syncthreads(): https://docs.nvidia.com/cuda/cuda-c-programming-guide/ - cuda-oxide, rev b7fe543,
crates/cuda-device/src/shared.rs:SharedArrayandDynamicSharedArray;cuda-macros:dynamic_shared_rangeand#[launch_bounds]. - The Rust Reference, “Static items”, and
rustc --explain E0401. - V. Volkov and J. Demmel, “Benchmarking GPUs to Tune Dense Linear Algebra”, SC08, 2008.
- Chapter 9 of this book, for the same algorithm in CUDA C++ and the comparison with cuBLAS.
Chapter 18: Register Tiling, Several Entries per Thread
Recall that in Chapter 17, the tiled kernel read each value from global memory 16 times less often than the direct kernel of Chapter 16, and yet, on the GPU measured in that chapter, it ran only about 1.5 times as fast. In Section 17.8.2, we found the reason. Every multiply-add of the tiled kernel reads 2 values from shared memory, and shared memory cannot deliver values as fast as the arithmetic units consume them. As a result, the tiled kernel reaches only about 1/8 of the arithmetic peak on every GPU, whatever its tile width.
In this chapter, we remove this limit with the same idea that removed the first one, applied 1 level closer to the arithmetic units. In Chapter 17, the threads of a block shared each value fetched from global memory by keeping it in shared memory. Here, a single thread reuses each value read from shared memory by keeping it in a register and using it for several entries of \(C\). We start from the observation of Exercise 17.12, that each thread of the tiled kernel performs 2 FLOP for every 2 values it reads from shared memory, and we work again with the 4 × 4 matrices of Chapter 16. We first let 1 thread compute 2 entries of \(C\), and then a 2 × 2 group of entries. We will see that the inner loop of the kernel then becomes a sum of outer products, in which every value read from shared memory is used several times. We then count the reads per multiply-add in general, derive the kernel in pseudocode, and prove it correct. Finally, we implement the kernel in Rust and in CUDA C++, and we measure it against the tiled kernel of Chapter 17 and the C++ kernels of Chapter 9.
This chapter covers
- the shared-memory reads of the tiled kernel, counted on the example
- One thread computing a 2 × 1 and then a 2 × 2 block of \(C\)
- the inner loop as a sum of outer products
- reads per multiply-add, \((T_M + T_N) / (T_M T_N)\), and registers as the third level of storage
- the register-tiled kernel in pseudocode, and its loop invariant
- the kernel in Rust (const generics,
#[unroll],RuntimeRowMajorTiles) and in CUDA C++ (templates,#pragma unroll) - measured speeds for thread tiles from 1 × 1 to 8 × 8, and what limits each
The code of the chapter is in
code/oxide/ch18_matmul_register_tiled/
for Rust and in
code/cuda/ch18_matmul_register_tiled/
for C++. In Chapter 9, we built a kernel in which each thread computes a 4 × 4 patch of \(C\),
in C++ and in Rust. In this chapter, we derive that kernel step by step from the tiled kernel, and
we generalize the shape of its patch. We keep the notation of Chapters 16 and 17: \(A\) is
\(M \times K\), \(B\) is \(K \times N\), and \(C = AB\); \(T\) is the tile width of the
tiled kernel, \(t\) the number of a phase, \(tT\) the index \(s\) at which phase \(t\)
begins, and tileA and tileB are the 2 tiles that a block holds in shared memory.
18.1 The reads of the tiled kernel
18.1.1 1 thread in 1 phase
To see where the reads of shared memory go, we return to block \((0, 0)\) of Chapter 17, with tile width \(T = 2\), in phase 0. Recall from Figure 17.3 that in this phase, the 2 tiles in shared memory hold \(\mathsf{tileA} = \begin{pmatrix} 1 & 2 \\ 5 & 6 \end{pmatrix}\) and \(\mathsf{tileB} = \begin{pmatrix} 1 & 0 \\ 0 & 1 \end{pmatrix}\), that is, columns 0 and 1 of rows 0 and 1 of \(A\), and rows 0 and 1 of columns 0 and 1 of \(B\). Thread \((0, 0)\) computes \(c_{00}\), so in this phase it multiplies row 0 of tileA by column 0 of tileB. It does so by running line 11 of Tiled-Kernel twice, once for each position \(\mathsf{offset}\) of a term within the phase. For \(\mathsf{offset} = 0\), it reads \(\mathsf{tileA}[0][0] = 1\) and \(\mathsf{tileB}[0][0] = 1\) from shared memory and adds \(1 \cdot 1\) to its sum. For \(\mathsf{offset} = 1\), it reads \(\mathsf{tileA}[0][1] = 2\) and \(\mathsf{tileB}[1][0] = 0\) and adds \(2 \cdot 0\) (Figure 18.1). In this phase, the thread therefore makes 4 reads from shared memory for 2 multiply-adds. Since a multiply-add counts as 2 floating-point operations, this is 4 reads for 4 FLOP.
Now consider the whole block. Each of its 4 threads makes 4 reads, so the block makes 16 reads from shared memory for 8 multiply-adds in the phase. Many of these reads fetch a value that another thread of the block also fetches. Thread \((0, 1)\) computes \(c_{01}\), so it reads row 0 of tileA as well, the same 2 values, 1 and 2, that thread \((0, 0)\) read a moment earlier. In the same way, thread \((1, 0)\) computes \(c_{10}\) and reads column 0 of tileB again. In general, every value of tileA is read by the \(T\) threads in its row of the block, and every value of tileB by the \(T\) threads in its column. This is the same waste that we found for global memory in Section 16.4.3, now 1 level closer to the arithmetic units.
18.1.2 What the reads cost
In Section 17.8.2, we turned this count of reads into a limit on speed. Recall the two facts on which the limit rests. The shared memory of an SM serves 1 read instruction of a warp per cycle, which delivers 32 values, and in the same cycle, the 128 FP32 units of the SM could perform 128 multiply-adds. When every multiply-add needs 2 reads, the 32 values delivered in a cycle feed only 16 multiply-adds, so the SM completes at most 16 multiply-adds per cycle, 1/8 of its peak. On the GPU of Chapter 17, this limit is 300 GFLOP/s, and the tiled kernel reached 272 GFLOP/s. In general, a kernel that makes fewer reads per multiply-add has a proportionally higher limit: with 1 read per multiply-add, the 32 values of a cycle feed 32 multiply-adds, and the limit doubles to 600 GFLOP/s. Note that a larger tile does not help, because the ratio of 2 reads per multiply-add does not depend on \(T\). Therefore, only a kernel that performs more multiply-adds for each value it reads from shared memory can run faster.
Exercises
18.1 In phase 1 of block \((0, 0)\), which values does thread \((1, 1)\) read from shared memory,
and which of them does another thread of the block also read?
18.2 With \(T = 16\), how many reads from shared memory does 1 block make in 1 phase, and how many
distinct values do the 2 tiles hold?
18.2 Several entries per thread
18.2.1 A 2 × 1 block of C
The waste arises because 2 threads read the same value, and each of them uses it only once. If 1 thread computed both of the entries that need the value, it could read the value once and use it twice. Let us try this with the smallest possible change, and let 1 thread compute 2 entries of \(C\) instead of 1, namely \(c_{00}\) and \(c_{10}\), the top 2 entries of column 0. In this chapter, we call such a rectangle of entries of \(C\) a block of \(C\); it should not be confused with a block of threads.
Both entries use column 0 of \(B\): \(c_{00}\) is row 0 of \(A\) times column 0 of \(B\), and \(c_{10}\) is row 1 of \(A\) times the same column. Consider the first term of each sum, the term with \(\mathsf{offset} = 0\). For \(c_{00}\), the thread needs \(a_{00} = 1\); for \(c_{10}\), it needs \(a_{10} = 5\); and for both, it needs \(b_{00} = 1\). The thread reads these 3 values from shared memory once, keeps them in registers, and performs 2 multiply-adds. It adds \(1 \cdot 1 = 1\) to the sum of \(c_{00}\), and \(5 \cdot 1 = 5\) to the sum of \(c_{10}\) (Figure 18.2).
In the tiled kernel, the same 2 multiply-adds were performed by 2 threads, \((0, 0)\) and \((1, 0)\), and took 4 reads, because each of the 2 threads read \(b_{00}\) on its own. Now they are performed by 1 thread with 3 reads, which is \(3/2 = 1.5\) reads per multiply-add instead of 2. The saving comes from the value of \(B\) that the 2 entries share. It is read once and used twice from a register.
18.2.2 A 2 × 2 block of C
The 2 × 1 block shares only the values of \(B\). If the thread also computes the entries of a second column, it can share the values of \(A\) as well. Let 1 thread compute \(c_{00}\), \(c_{01}\), \(c_{10}\) and \(c_{11}\), the 4 entries that the whole block \((0, 0)\) computed in Chapter 17. Let us list what these 4 entries need for 1 value of \(\mathsf{offset}\). The 2 entries in row 0 need \(a_{0, \mathsf{offset}}\), and the 2 entries in row 1 need \(a_{1, \mathsf{offset}}\); these are 2 values from column \(\mathsf{offset}\) of \(A\). The 2 entries in column 0 need \(b_{\mathsf{offset}, 0}\), and the 2 entries in column 1 need \(b_{\mathsf{offset}, 1}\); these are 2 values from row \(\mathsf{offset}\) of \(B\). Each of the 4 entries needs the product of 1 of the 2 values of \(A\) with 1 of the 2 values of \(B\); for example, \(c_{01}\) needs \(a_{0, \mathsf{offset}} b_{\mathsf{offset}, 1}\). Conversely, each value of \(A\) meets each value of \(B\) in exactly 1 of the 4 entries.
For \(\mathsf{offset} = 0\), the thread therefore reads \((a_{00}, a_{10}) = (1, 5)\) from \(A\) and \((b_{00}, b_{01}) = (1, 0)\) from \(B\), and it forms all 4 products of a value of the first pair with a value of the second (Figure 18.3). If we write the 2 values of \(A\) as a column and the 2 values of \(B\) as a row, the 4 products form a 2 × 2 matrix, whose entry in row \(i\) and column \(j\) is the \(i\)-th value of the column times the \(j\)-th value of the row:
\[ \begin{pmatrix} 1 \\ 5 \end{pmatrix} \begin{pmatrix} 1 & 0 \end{pmatrix} = \begin{pmatrix} 1 \cdot 1 & 1 \cdot 0 \\ 5 \cdot 1 & 5 \cdot 0 \end{pmatrix} = \begin{pmatrix} 1 & 0 \\ 5 & 0 \end{pmatrix}. \]
The entry in row 0 and column 0, \(1 \cdot 1 = 1\), is the first term of \(c_{00}\); the entry in row 1 and column 0, \(5 \cdot 1 = 5\), is the first term of \(c_{10}\); and in the same way, the 2 zeros are the first terms of \(c_{01}\) and \(c_{11}\).
This step costs 4 reads for 4 multiply-adds, which is 1 read per multiply-add, half the cost in the tiled kernel. Every value read is used twice, once for each entry in its row or column of the block. The product of a column with a row that we have just formed has a name.
Definition 18.1 Outer product. The outer product of a column vector \(x\) of length \(p\) and a row vector \(y\) of length \(q\) is the \(p \times q\) matrix \(xy\) with entries \(x_i y_j\). It contains every product of an entry of \(x\) with an entry of \(y\): \(pq\) products from \(p + q\) values.
Example. The outer product of \((1, 5)\) and \((1, 0)\) is \(\begin{pmatrix} 1 & 0 \\ 5 & 0 \end{pmatrix}\), the 4 products of Figure 18.3.
In our example, \(x = (1, 5)\) has length \(p = 2\), \(y = (1, 0)\) has length \(q = 2\), and the outer product holds \(pq = 4\) products made from \(p + q = 4\) values. The name distinguishes it from the inner product, or dot product, of 2 vectors of equal length, which is a single number. Recall that each entry of \(C\) is an inner product of a row of \(A\) with a column of \(B\); the outer product, in contrast, combines a column of \(A\) with a row of \(B\).
18.2.3 The outer-product form
For \(\mathsf{offset} = 0\), the outer product gives the first term of each of the 4 sums. The remaining terms come from the remaining positions. For now, we ignore the division into phases, so the position of a term is its index \(s\), which runs over all \(K = 4\) terms of the sums. For \(s = 1\), the thread reads \((2, 6)\) from column 1 of \(A\) and \((0, 1)\) from row 1 of \(B\); for \(s = 2\), it reads \((3, 7)\) and \((2, 1)\); and for \(s = 3\), it reads \((4, 8)\) and \((1, 2)\). Each pair gives 1 outer product, and the sum of the 4 outer products is the 2 × 2 block of \(C\) (Figure 18.4):
\[ \begin{pmatrix} 1 & 0 \\ 5 & 0 \end{pmatrix} + \begin{pmatrix} 0 & 2 \\ 0 & 6 \end{pmatrix} + \begin{pmatrix} 6 & 3 \\ 14 & 7 \end{pmatrix} + \begin{pmatrix} 4 & 8 \\ 8 & 16 \end{pmatrix} = \begin{pmatrix} 11 & 13 \\ 27 & 29 \end{pmatrix}. \]
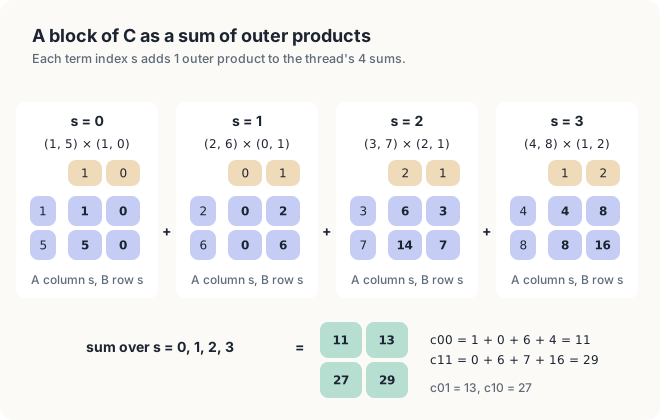
Let us check 1 entry. The top-left entries of the 4 outer products add up to \(1 + 0 + 6 + 4 = 11\), which is \(c_{00}\). These are the same 4 products as in Figure 16.1, \(1 \cdot 1\), \(2 \cdot 0\), \(3 \cdot 2\) and \(4 \cdot 1\), added in the same order; only the bookkeeping has changed. In the tiled kernel, each thread ran the loop over the terms inside its single entry, so it completed the sum of 1 entry term by term. In the new form, the loop over the terms is the outer loop, and inside it the thread touches every entry of its block once, adding 1 term to each.
We now write this form in general. Let 1 thread compute a block of \(C\) with \(T_M\) rows and \(T_N\) columns. The subscripts recall that the rows of \(C\) are counted by \(M\) and its columns by \(N\). In the 2 × 1 example of Section 18.2.1, \(T_M = 2\) and \(T_N = 1\); in the 2 × 2 example, \(T_M = T_N = 2\). Let the block start at row \(i_0\) and column \(j_0\) of \(C\), so that its top-left entry is \(c_{i_0 j_0}\); in the 2 × 2 example, \(i_0 = j_0 = 0\). Within the block, we number the rows \(i = 0, \ldots, T_M - 1\) and the columns \(j = 0, \ldots, T_N - 1\), so that entry \((i, j)\) of the block is the entry of \(C\) in row \(i_0 + i\) and column \(j_0 + j\). As in Definition 16.1, we write \(s\) for the index of a term. The \(T_M T_N\) entries that the thread computes are then
\[ c_{i_0 + i,\; j_0 + j} = \sum_{s \in [0, K)} a_{i_0 + i,\, s}\; b_{s,\, j_0 + j}, \qquad i \in [0, T_M),\ j \in [0, T_N). \]
| Symbol | Meaning | In the 2 × 2 example |
|---|---|---|
| \(T_M\) | rows of the block of \(C\) that 1 thread computes | 2 |
| \(T_N\) | columns of the block of \(C\) that 1 thread computes | 2 |
| \(i_0, j_0\) | row and column of \(C\) at which the thread’s block begins | 0, 0 |
| \(i, j\) | row and column of an entry within the block | 0 or 1 each |
| \(s\) | index of a term of the sum | 0 to 3 |
| \(a_{i_0 + i,\, s}\) | value of \(A\) in row \(i_0 + i\), column \(s\) | \(a_{12} = 7\) for \(i = 1\), \(s = 2\) |
| \(b_{s,\, j_0 + j}\) | value of \(B\) in row \(s\), column \(j_0 + j\) | \(b_{21} = 1\) for \(s = 2\), \(j = 1\) |
In the outer-product form, the thread performs 1 step for each value of \(s\). The step reads the \(T_M\) values \(a_{i_0 + i, s}\), which form the part of column \(s\) of \(A\) that lies in the rows of the block, and the \(T_N\) values \(b_{s, j_0 + j}\), which form the part of row \(s\) of \(B\) that lies in the columns of the block. It then adds their outer product to its \(T_M T_N\) sums. For example, in the step for \(s = 2\), our thread reads \(a_{02} = 3\) and \(a_{12} = 7\) from column 2 of \(A\), and \(b_{20} = 2\) and \(b_{21} = 1\) from row 2 of \(B\), and it adds the third outer product of Figure 18.4 to its 4 sums.
18.2.4 Counting the reads
Let us now count the reads of 1 step in general. The step reads \(T_M\) values of \(A\) and \(T_N\) values of \(B\), so it makes \(T_M + T_N\) reads, and it performs 1 multiply-add for every entry of the block, \(T_M T_N\) multiply-adds in all. The number of reads per multiply-add is therefore
\[ \frac{T_M + T_N}{T_M T_N}. \]
| Symbol | Meaning | In the 2 × 2 example |
|---|---|---|
| \(T_M + T_N\) | values read from shared memory in 1 step | \(2 + 2 = 4\) |
| \(T_M T_N\) | multiply-adds in 1 step, 1 per entry of the block | \(2 \cdot 2 = 4\) |
| \((T_M + T_N)/(T_M T_N)\) | reads per multiply-add | \(4/4 = 1\) |
For the 1 × 1 block, which is the tiled kernel, the ratio is \(2/1 = 2\). For a 2 × 1 block, it is \(3/2 = 1.5\); for 2 × 2, it is \(4/4 = 1\); for 4 × 4, it is \(8/16 = 0.5\); and for 8 × 8, it is \(16/64 = 0.25\) (Figure 18.5). In general, for a square block whose side is \(T_M = T_N = R\), the ratio is \(2R/R^2 = 2/R\). It therefore falls in proportion to the side of the block, just as in Chapter 17, the fetches from global memory fell in proportion to \(T\). The saving has a price, however. The thread must keep its \(T_M T_N\) sums for the whole kernel, and in addition the \(T_M + T_N\) values of the current step. For a 4 × 4 block, these are 16 sums and 8 values.
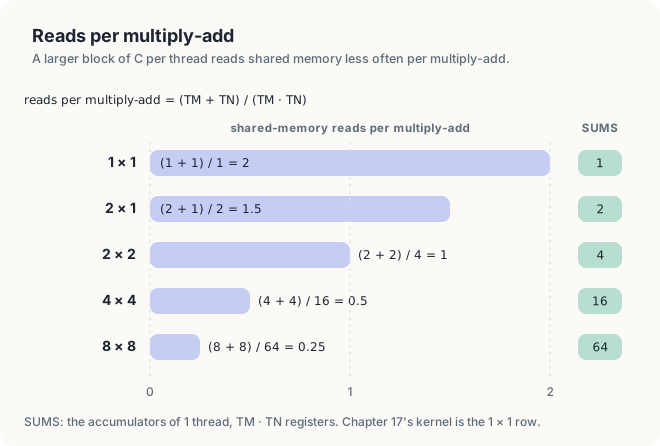
Key observation A thread that computes a \(T_M \times T_N\) block of \(C\) can read \(T_M\) values of \(A\) and \(T_N\) values of \(B\) once per step, keep them in registers, and use each of them \(T_N\) or \(T_M\) times. Its reads from shared memory per multiply-add fall from 2 to \((T_M + T_N) / (T_M T_N)\).
Exercises
18.3 Compute the outer products for the 2 × 2 block of \(C\) in rows 2 and 3 and columns 0 and 1,
and check that they sum to \(\begin{pmatrix} 43 & 45 \\ 59 & 61 \end{pmatrix}\).
18.4 For a thread tile of 4 × 2, how many reads and how many multiply-adds does 1 step take? Which
is better for a fixed number of 8 sums, 4 × 2 or 8 × 1?
18.5 Show that for a fixed number \(P = T_M T_N\) of sums, the reads per multiply-add are smallest
when \(T_M = T_N\).
18.3 Registers as the third level
The sums and the values of the current step in Section 18.2 must be kept close to the arithmetic units, and the place for them is the registers. Recall that in Chapter 16, we described three kinds of storage: global memory, shared memory and registers. The direct kernel took its operands from global memory, the tiled kernel took them from shared memory, and the new kernel takes most of them from registers.
Definition 18.2 Register tile. A register tile, or thread tile, is a \(T_M \times T_N\) block of \(C\) that 1 thread computes, with its \(T_M T_N\) sums held in registers for the whole kernel. Register tiling is the technique of giving each thread a register tile and computing it as a sum of outer products.
Example. With \(T_M = T_N = 2\), thread \((0, 0)\) of our example holds the 4 sums of \(c_{00}\), \(c_{01}\), \(c_{10}\) and \(c_{11}\) in 4 registers.
In the 2 × 1 example of Section 18.2.1, the register tile has \(T_M = 2\) rows and \(T_N = 1\) column, and it holds the 2 sums of \(c_{00}\) and \(c_{10}\). In the rest of the chapter, we describe a register tile by its shape, \(T_M \times T_N\), so that a 4 × 4 register tile is a thread that keeps 16 sums.
Registers are the fastest storage of the GPU, but each SM has a fixed number of them: 65,536 registers of 4 bytes on both measured GPUs. These registers are divided among all the threads resident on the SM, and a single thread may use at most 255 of them. Therefore, a kernel that uses more registers per thread fits fewer threads on an SM, which lowers its occupancy (Definition 17.3). For example, a thread with a 4 × 4 register tile needs 16 registers for its sums and 8 for the values of the current step, plus registers for addresses and loop counters.
Figure 18.6 shows the 3 levels with the numbers of a kernel in which each thread computes a 4 × 4 register tile, as in Chapter 9. A block of 256 threads, arranged as 16 × 16, then computes a square of \(16 \cdot 4 = 64\) rows and 64 columns of \(C\). Each phase of this kernel covers 16 terms of each sum. In each phase, the block copies from global memory into shared memory a piece of \(A\) with 64 rows and 16 columns and a piece of \(B\) with 16 rows and 64 columns. These are 2,048 floats, or 8 per thread. In each of the 16 steps of a phase, a thread then reads 8 floats from shared memory and performs 16 multiply-adds on registers.
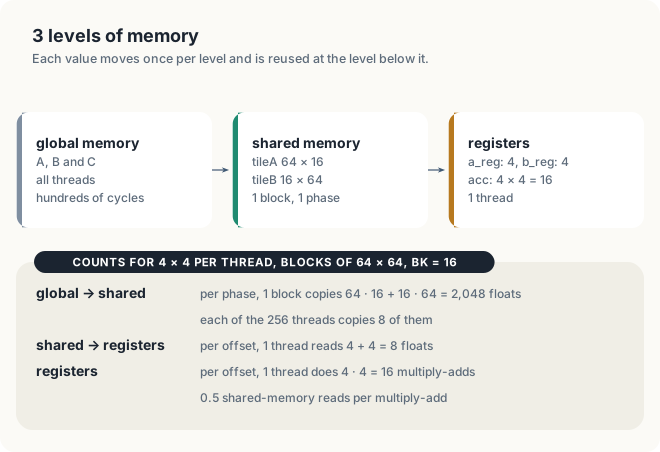
The savings of the 2 levels of tiling multiply. To see this, we need names for the sizes of the part of \(C\) that a block computes, since these are no longer tied to a single tile width \(T\). We write \(B_M\) for the number of rows of \(C\) that a block computes, \(B_N\) for the number of its columns, and \(B_K\) for the number of terms of each sum that a phase covers. The letter \(B\) stands for block, and the subscript again names the dimension: \(B_K\) counts along the dimension \(K\) that \(A\) and \(B\) share. In the configuration of Figure 18.6, \(B_M = B_N = 64\) and \(B_K = 16\). In each phase, the block copies the \(B_M \times B_K\) piece of \(A\) and the \(B_K \times B_N\) piece of \(B\), which are \(B_M B_K + B_K B_N\) values, and it performs \(B_M B_N B_K\) multiply-adds. There are \(M/B_M\) rows and \(N/B_N\) columns of blocks, and each block runs \(K/B_K\) phases, so over the whole product the blocks fetch
\[ \frac{M}{B_M} \cdot \frac{N}{B_N} \cdot \frac{K}{B_K} \cdot (B_M B_K + B_K B_N) = MNK \left( \frac{1}{B_N} + \frac{1}{B_M} \right) \]
values from global memory.
| Symbol | Meaning | In Figure 18.6 |
|---|---|---|
| \(B_M\) | rows of \(C\) that 1 block computes | 64 |
| \(B_N\) | columns of \(C\) that 1 block computes | 64 |
| \(B_K\) | terms of each sum covered by 1 phase | 16 |
| \((M/B_M) \cdot (N/B_N)\) | number of blocks | \(64 \cdot 64 = 4{,}096\) for \(M = N = 4{,}096\) |
| \(K/B_K\) | number of phases of each block | \(4{,}096/16 = 256\) for \(K = 4{,}096\) |
| \(B_M B_K + B_K B_N\) | values that a block copies in 1 phase | \(1{,}024 + 1{,}024 = 2{,}048\) |
For \(B_M = B_N = 64\), the count is \(MNK (1/64 + 1/64) = 2MNK/64\). Recall from Section 17.5 that the tiled kernel with \(T = 16\) fetches \(2MNK/16\) values, so the new kernel fetches 4 times fewer. In our 4 × 4 example, with \(B_M = B_N = 4\) and \(B_K = 2\), the formula gives \(4 \cdot 4 \cdot 4 \cdot (1/4 + 1/4) = 32\), which means that each of the 32 values of \(A\) and \(B\) is fetched exactly once. The number of fetches from global memory depends only on the block’s part of \(C\), \(B_M \times B_N\), whereas the number of reads from shared memory per multiply-add, \((T_M + T_N)/(T_M T_N)\), depends only on the thread tile. The 2 can therefore be chosen independently. In other words, global memory sees the block tile, shared memory sees the thread tile, and the arithmetic units see registers.
Exercises
18.6 For \(B_M = B_N = 128\), \(B_K = 8\) and 8 × 8 per thread, how many threads does a block
have, how many floats does each copy per phase, and how many FLOP per float does the kernel perform
on values fetched from global memory?
18.7 At 110 registers per thread, how many blocks of 256 threads fit in the 65,536 registers of an
SM? What occupancy does that give on an SM that holds 1,536 threads?
18.4 The algorithm
18.4.1 Assigning the work to threads
We now assign the entries of \(C\) and the values of the tiles to the threads of a block. A block computes \(B_M \times B_N\) entries, and each of its threads computes \(T_M \times T_N\) of them, so the block needs \((B_M / T_M) \cdot (B_N / T_N)\) threads, arranged as \(B_M/T_M\) rows and \(B_N/T_N\) columns. For the configuration of Figure 18.6, these are \(64/4 = 16\) rows and 16 columns of threads, 256 threads in all. Thread \((\mathsf{threadIdx{.}y}, \mathsf{threadIdx{.}x})\) of block \((\mathsf{blockIdx{.}y}, \mathsf{blockIdx{.}x})\) owns the \(T_M \times T_N\) block of \(C\) whose top-left entry lies in row \(\mathsf{blockIdx{.}y} \cdot B_M + \mathsf{threadIdx{.}y} \cdot T_M\) and column \(\mathsf{blockIdx{.}x} \cdot B_N + \mathsf{threadIdx{.}x} \cdot T_N\). The first term, \(\mathsf{blockIdx{.}y} \cdot B_M\), is the first row of the block’s part of \(C\), and the second term, \(\mathsf{threadIdx{.}y} \cdot T_M\), is the number of rows owned by the \(\mathsf{threadIdx{.}y}\) rows of threads above the thread in its block; the column is found in the same way.
In our example, we take \(B_M = B_N = 4\), \(B_K = 2\) and \(T_M = T_N = 2\). A single block of 2 × 2 threads then covers all of \(C\), and each thread owns a 2 × 2 block of it (Figure 18.7). For instance, thread \((1, 0)\) of block \((0, 0)\) owns the block that begins in row \(0 \cdot 4 + 1 \cdot 2 = 2\) and column \(0 \cdot 4 + 0 \cdot 2 = 0\), that is, the entries \(c_{20} = 43\), \(c_{21} = 45\), \(c_{30} = 59\) and \(c_{31} = 61\). Thread \((0, 0)\) alone now computes the 4 entries that the 4 threads of block \((0, 0)\) computed in Chapter 17.
| Symbol | Meaning | Thread \((1, 0)\) of the example |
|---|---|---|
| \(\mathsf{blockIdx{.}y}, \mathsf{blockIdx{.}x}\) | row and column of the block in the grid | 0, 0 |
| \(\mathsf{threadIdx{.}y}, \mathsf{threadIdx{.}x}\) | row and column of the thread within its block | 1, 0 |
| \(\mathsf{blockIdx{.}y} \cdot B_M + \mathsf{threadIdx{.}y} \cdot T_M\) | first row of the thread’s block of \(C\) | \(0 \cdot 4 + 1 \cdot 2 = 2\) |
| \(\mathsf{blockIdx{.}x} \cdot B_N + \mathsf{threadIdx{.}x} \cdot T_N\) | first column of the thread’s block of \(C\) | \(0 \cdot 4 + 0 \cdot 2 = 0\) |
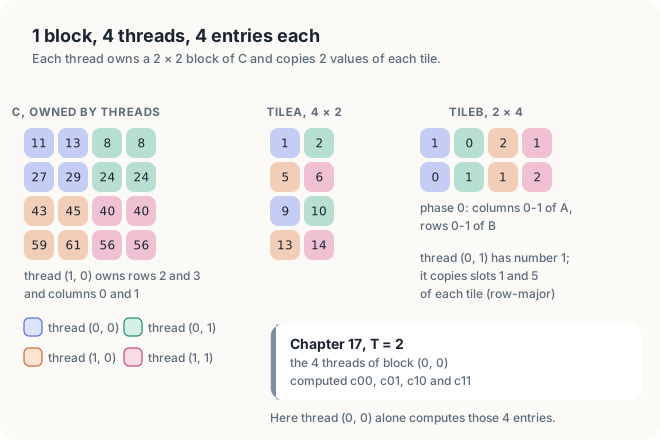
The tiles are no longer square. In the phase with number \(\mathsf{phase}\), the block needs the piece of \(A\) that lies in its own \(B_M\) rows and in the \(B_K\) columns \([\mathsf{phase} \cdot B_K, \mathsf{phase} \cdot B_K + B_K)\), and the piece of \(B\) that lies in the \(B_K\) rows \([\mathsf{phase} \cdot B_K, \mathsf{phase} \cdot B_K + B_K)\) and in its own \(B_N\) columns. As in Chapter 17, the product \(\mathsf{phase} \cdot B_K\) is the index \(s\) at which the phase begins; in the example, with \(B_K = 2\), phase 1 begins at column 2 of \(A\) and row 2 of \(B\). In the example, tileA therefore has 4 rows and 2 columns, and tileB has 2 rows and 4 columns. Both hold 8 values, and the block has only 4 threads, so each thread must copy 2 values of each tile.
In Chapter 17, each thread copied the value at its own position in the tile, but this rule no longer works when a tile has more values than the block has threads. Instead, we number the threads of a block in row-major order, \(\mathsf{threadNumber} = \mathsf{threadIdx{.}y} \cdot (B_N/T_N) + \mathsf{threadIdx{.}x}\), and we write \(\mathsf{threads}\) for the number of threads. We also number the slots of each tile in row-major order, 0, 1, 2, and so on, and we write \(\mathsf{element}\) for the number of a slot. Thread \(\mathsf{threadNumber}\) then copies the slots \(\mathsf{element} = \mathsf{threadNumber}\), \(\mathsf{threadNumber} + \mathsf{threads}\), \(\mathsf{threadNumber} + 2 \cdot \mathsf{threads}\), and so forth, up to the end of the tile. Slot \(\mathsf{element}\) of tileA, whose rows have \(B_K\) slots, lies in row \(\lfloor \mathsf{element}/B_K \rfloor\) and column \(\mathsf{element} \bmod B_K\) of the tile. In the example, \(\mathsf{threads} = 4\), and thread \((0, 1)\) has \(\mathsf{threadNumber} = 0 \cdot 2 + 1 = 1\), so it copies slots 1 and 5 of each tile. Slot 5 of tileA lies in row \(\lfloor 5/2 \rfloor = 2\) and column \(5 \bmod 2 = 1\), so in phase 0, the thread copies \(a_{21} = 10\) into it.
| Symbol | Meaning | Thread \((0, 1)\) of the example |
|---|---|---|
| \(\mathsf{threads}\) | number of threads in a block, \((B_M/T_M)(B_N/T_N)\) | \(2 \cdot 2 = 4\) |
| \(\mathsf{threadNumber}\) | number of the thread, \(\mathsf{threadIdx{.}y} \cdot (B_N/T_N) + \mathsf{threadIdx{.}x}\) | \(0 \cdot 2 + 1 = 1\) |
| \(\mathsf{element}\) | number of a slot of a tile, in row-major order | 1 and 5 |
| \(\lfloor \mathsf{element}/B_K \rfloor\) | row of slot \(\mathsf{element}\) in tileA | \(\lfloor 5/2 \rfloor = 2\) |
| \(\mathsf{element} \bmod B_K\) | column of slot \(\mathsf{element}\) in tileA | \(5 \bmod 2 = 1\) |
With this numbering, consecutive threads copy consecutive values of a row, which lie next to each other in global memory, so the reads of a warp can be combined into few memory transactions. For the scheme to cover each tile exactly once, \(\mathsf{threads}\) must divide the sizes of both tiles, \(B_M B_K\) and \(B_K B_N\). In the example, \(\mathsf{threads} = 4\) divides 8, and all our configurations satisfy this condition.
18.4.2 The kernel
Every thread executes the following procedure. As in Chapter 17, the arrays tileA and tileB live in shared memory, 1 pair per block, whereas acc, aReg and bReg are small arrays that belong to the thread and are kept in its registers.
Register-Tiled-Kernel(\(A, B, C, M, K, N\))
- \(\mathsf{threads} = (B_M/T_M) \cdot (B_N/T_N)\)
- \(\mathsf{threadNumber} = \mathsf{threadIdx{.}y} \cdot (B_N/T_N) + \mathsf{threadIdx{.}x}\)
- \(\mathsf{blockRow} = \mathsf{blockIdx{.}y} \cdot B_M\)
- \(\mathsf{blockCol} = \mathsf{blockIdx{.}x} \cdot B_N\)
- \(\mathsf{acc}[\mathsf{localRow}][\mathsf{localCol}] = 0\) for all \(\mathsf{localRow} \in [0, T_M)\), \(\mathsf{localCol} \in [0, T_N)\)
- for \(\mathsf{phase} \in [0, \lceil K/B_K \rceil)\) {
- for \(\mathsf{element} \in \{\mathsf{threadNumber}, \mathsf{threadNumber} + \mathsf{threads}, \ldots\} \cap [0, B_M B_K)\) {
- \(\mathsf{tileRow} = \lfloor \mathsf{element} / B_K \rfloor\)
- \(\mathsf{tileCol} = \mathsf{element} \bmod B_K\)
- \(\mathsf{tileA}[\mathsf{tileRow}][\mathsf{tileCol}] = a_{\mathsf{blockRow} + \mathsf{tileRow},\, \mathsf{phase} \cdot B_K + \mathsf{tileCol}}\), or 0 outside \(A\)
- }
- for \(\mathsf{element} \in \{\mathsf{threadNumber}, \mathsf{threadNumber} + \mathsf{threads}, \ldots\} \cap [0, B_K B_N)\) {
- \(\mathsf{tileRow} = \lfloor \mathsf{element} / B_N \rfloor\)
- \(\mathsf{tileCol} = \mathsf{element} \bmod B_N\)
- \(\mathsf{tileB}[\mathsf{tileRow}][\mathsf{tileCol}] = b_{\mathsf{phase} \cdot B_K + \mathsf{tileRow},\, \mathsf{blockCol} + \mathsf{tileCol}}\), or 0 outside \(B\)
- }
- Barrier()
- for \(\mathsf{offset} \in [0, B_K)\) {
- \(\mathsf{aReg}[\mathsf{localRow}] = \mathsf{tileA}[\mathsf{threadIdx{.}y} \cdot T_M + \mathsf{localRow}][\mathsf{offset}]\) for all \(\mathsf{localRow}\)
- \(\mathsf{bReg}[\mathsf{localCol}] = \mathsf{tileB}[\mathsf{offset}][\mathsf{threadIdx{.}x} \cdot T_N + \mathsf{localCol}]\) for all \(\mathsf{localCol}\)
- \(\mathsf{acc}[\mathsf{localRow}][\mathsf{localCol}] \mathrel{+}= \mathsf{aReg}[\mathsf{localRow}] \cdot \mathsf{bReg}[\mathsf{localCol}]\) for all pairs
- }
- Barrier()
- }
- for \(\mathsf{localRow} \in [0, T_M)\), \(\mathsf{localCol} \in [0, T_N)\) {
- \(\mathsf{row} = \mathsf{blockRow} + \mathsf{threadIdx{.}y} \cdot T_M + \mathsf{localRow}\)
- \(\mathsf{col} = \mathsf{blockCol} + \mathsf{threadIdx{.}x} \cdot T_N + \mathsf{localCol}\)
- if \(\mathsf{row} \in [0, M)\) and \(\mathsf{col} \in [0, N)\) {
- \(c_{\mathsf{row}, \mathsf{col}} = \mathsf{acc}[\mathsf{localRow}][\mathsf{localCol}]\)
- }
- }
The procedure has the shape of Tiled-Kernel. Lines 1 and 2 compute the number of threads in a block, \(\mathsf{threads}\), and the number of this thread within its block, \(\mathsf{threadNumber}\). Lines 3 and 4 compute the first row \(\mathsf{blockRow}\) and the first column \(\mathsf{blockCol}\) of the block’s part of \(C\); in the example, \(\mathsf{blockRow} = \mathsf{blockCol} = 0\). Line 5 sets the thread’s \(T_M T_N\) sums to 0. Lines 7 to 16 are the joint copy of Section 18.4.1, now several values per thread. Lines 8 and 9 find the row \(\mathsf{tileRow}\) and the column \(\mathsf{tileCol}\) of slot \(\mathsf{element}\) in tileA, and line 10 copies into it the value of \(A\) in row \(\mathsf{blockRow} + \mathsf{tileRow}\) and column \(\mathsf{phase} \cdot B_K + \mathsf{tileCol}\), that is, the value at the same position within the piece of \(A\) that the current phase needs. Lines 13 to 15 do the same for tileB, whose rows have \(B_N\) slots. Lines 17 and 23 are the 2 barriers.
Lines 18 to 22 replace the inner loop of Tiled-Kernel. Line 19 reads the \(T_M\) values of column \(\mathsf{offset}\) of tileA that lie in the thread’s own rows. For example, thread \((1, 0)\) owns rows 2 and 3, so for \(\mathsf{offset} = 0\) in phase 0, it reads \(\mathsf{tileA}[2][0] = a_{20} = 9\) and \(\mathsf{tileA}[3][0] = a_{30} = 13\). Line 20 reads, in the same way, the \(T_N\) values of row \(\mathsf{offset}\) of tileB that lie in the thread’s own columns. Line 21 then adds the outer product of these values to the sums, \(T_M T_N\) multiply-adds that use registers only. Finally, lines 25 to 31 store the \(T_M T_N\) results. As in Chapter 17, every thread stays in the loop until the end and reaches every barrier, and only the stores are guarded.
In Figure 18.8, we follow the procedure for thread \((0, 0)\) of the example. In phase 0, tileA holds columns 0 and 1 of \(A\), and tileB holds rows 0 and 1 of \(B\). For \(\mathsf{offset} = 0\), the thread reads aReg = (1, 5) and bReg = (1, 0) and adds their outer product; for \(\mathsf{offset} = 1\), it reads (2, 6) and (0, 1). After phase 0, its sums are \(\begin{pmatrix} 1 & 2 \\ 5 & 6 \end{pmatrix}\), the same 4 values that the 4 threads of Chapter 17 held after phase 0 (Figure 17.3). Phase 1 adds \(\begin{pmatrix} 10 & 11 \\ 22 & 23 \end{pmatrix}\), and the thread ends with \(c_{00} = 11\), \(c_{01} = 13\), \(c_{10} = 27\) and \(c_{11} = 29\).
Exercises
18.8 Run phase 0 of the example for thread \((1, 1)\). Which values does it copy into each tile,
which values does it read for \(\mathsf{offset} = 0\), and what are its 4 sums after the phase?
18.9 With \(B_M = B_N = 64\), \(B_K = 16\) and \(T_M = T_N = 4\), which slots of tileA does
thread \(\mathsf{threadNumber} = 37\) copy, and from which rows and columns of \(A\) in the phase with number \(\mathsf{phase}\)?
18.5 Correctness
The register-tiled kernel changes which thread computes which entry, but it does not change the order of the terms in any entry. Its proof is therefore the proof of Theorem 17.1, with the invariant written for every sum of a thread.
Theorem 18.1 When Register-Tiled-Kernel finishes, every entry of \(C\) equals the corresponding entry of \(AB\), provided the block has \(\mathsf{threads}\) threads and \(\mathsf{threads}\) divides \(B_M B_K\) and \(B_K B_N\).
Proof. Fix a thread and a pair \(\mathsf{localRow} \in [0, T_M)\), \(\mathsf{localCol} \in [0, T_N)\), let \(\mathsf{row} = \mathsf{blockRow} + \mathsf{threadIdx{.}y} \cdot T_M + \mathsf{localRow}\) and \(\mathsf{col} = \mathsf{blockCol} + \mathsf{threadIdx{.}x} \cdot T_N + \mathsf{localCol}\), and treat entries beyond the edge of a matrix as 0. We show that the loop of lines 6 to 24 maintains the invariant
\[ \text{at the start of the phase with number } \mathsf{phase}, \qquad \mathsf{acc}[\mathsf{localRow}][\mathsf{localCol}] = \sum_{s \in [0,\, \mathsf{phase} \cdot B_K)} a_{\mathsf{row}, s}\; b_{s, \mathsf{col}}. \]
In words, at the start of each phase, every sum of the thread holds the terms of its entry that precede the phase. For example, for thread \((0, 1)\) of the example with \(\mathsf{localRow} = 1\) and \(\mathsf{localCol} = 0\), we have \(\mathsf{row} = 0 + 0 \cdot 2 + 1 = 1\) and \(\mathsf{col} = 0 + 1 \cdot 2 + 0 = 2\), and at the start of phase 1, the invariant states that \(\mathsf{acc}[1][0] = a_{10} b_{02} + a_{11} b_{12} = 5 \cdot 2 + 6 \cdot 1 = 16\).
| Symbol | Meaning | Thread \((0, 1)\), \(\mathsf{localRow} = 1\), \(\mathsf{localCol} = 0\), phase 1 |
|---|---|---|
| \(\mathsf{row}, \mathsf{col}\) | row and column of \(C\) of the sum \(\mathsf{acc}[\mathsf{localRow}][\mathsf{localCol}]\) | 1, 2 |
| \(\mathsf{phase} \cdot B_K\) | number of terms added before the phase | \(1 \cdot 2 = 2\) |
| \(\mathsf{acc}[\mathsf{localRow}][\mathsf{localCol}]\) | the thread’s sum for entry \((\mathsf{localRow}, \mathsf{localCol})\) of its block | 16 |
Initialization. Line 5 sets every sum to 0, the empty sum.
Maintenance. In lines 7 to 16, thread \(\mathsf{threadNumber}\) writes slots \(\mathsf{threadNumber}\), \(\mathsf{threadNumber} + \mathsf{threads}, \ldots\) of each tile. Because \(\mathsf{threads}\) divides the size of each tile, the \(\mathsf{threads}\) threads write every slot exactly once, and the barrier of line 17 makes every write visible before any thread reaches line 19. Hence, \(\mathsf{tileA}[\mathsf{threadIdx{.}y} \cdot T_M + \mathsf{localRow}][\mathsf{offset}] = a_{\mathsf{row},\, \mathsf{phase} \cdot B_K + \mathsf{offset}}\) and \(\mathsf{tileB}[\mathsf{offset}][\mathsf{threadIdx{.}x} \cdot T_N + \mathsf{localCol}] = b_{\mathsf{phase} \cdot B_K + \mathsf{offset},\, \mathsf{col}}\) for every \(\mathsf{offset} \in [0, B_K)\), and over the \(B_K\) passes of lines 18 to 22, line 21 adds exactly the terms with \(s \in [\mathsf{phase} \cdot B_K, \mathsf{phase} \cdot B_K + B_K)\) to \(\mathsf{acc}[\mathsf{localRow}][\mathsf{localCol}]\). Because of the barrier of line 23, no thread overwrites a tile for the next phase while another thread still reads it in this one. Therefore, the invariant holds at the start of the phase with number \(\mathsf{phase} + 1\).
Termination. The loop ends with \(\mathsf{phase} = \lceil K/B_K \rceil\), so \(\mathsf{phase} \cdot B_K \ge K\), and \(\mathsf{acc}[\mathsf{localRow}][\mathsf{localCol}] = c_{\mathsf{row}, \mathsf{col}}\). Lines 28 to 30 store it if \((\mathsf{row}, \mathsf{col})\) lies in \(C\). Distinct threads and distinct \((\mathsf{localRow}, \mathsf{localCol})\) give distinct \((\mathsf{row}, \mathsf{col})\), so every entry of \(C\) is stored exactly once.
The 2 barriers play the same roles as in Chapter 17, and removing either of them produces the same errors as in Sections 17.6.1 and 17.6.2. The only new condition is the one on \(\mathsf{threads}\). If the block had fewer threads than \(\mathsf{threads}\), some slots of each tile would never be written, and the sums would add values left over from an earlier phase. If \(\mathsf{threads}\) did not divide the size of a tile, the last pass of the copy loop would run past the end of the tile. For this reason, the Rust host function that builds the launch derives the block shape from the 5 constants, so that the caller cannot break the condition. The same function also checks a second condition of the Rust implementation, which we describe in Section 18.6.4.
Rule The number of threads in a block must be the number the kernel was derived for. Compute the block shape from the tile sizes, in 1 place.
Exercises
18.10 Which line of the proof fails if the block has \(\mathsf{threads}/2\) threads? Which entries of the example
would then be wrong?
18.11 Write the invariant of Theorem 18.1 for thread \((1, 0)\) of the example at the start of
phase 1, with numbers.
18.6 Implementation
18.6.1 The tile sizes as compile-time constants
The kernel has 5 sizes, \(B_M\), \(B_N\), \(B_K\), \(T_M\) and \(T_N\), and all 5 must be known when the kernel is compiled. The reason is that the sums of a thread can stay in registers only if the compiler knows how many there are and can give each of them a register of its own. A register has a fixed name, chosen at compile time, and no instruction selects a register by an index that is computed while the kernel runs. In C++, the 5 sizes are therefore template parameters, and in Rust, they are const generic parameters. In both languages, the compiler produces 1 compiled kernel for each combination of sizes that the program uses. The following code shows the beginning of the kernel: its 5 sizes, the tiles in shared memory, the thread’s numbers, and the array of sums.
mod kernels {
// ...
pub fn matmul_register<
const BM: usize,
const BN: usize,
const BK: usize,
const TM: usize,
const TN: usize,
>(
m: u32,
n: u32,
k: u32,
a: &[f32],
b: &[f32],
mut c: DisjointSlice<f32, RuntimeRowMajorTiles<TM, TN>>,
) {
let tile_a: *mut f32 = DynamicSharedArray::<f32>::get();
let tile_b: *mut f32 = DynamicSharedArray::<f32>::offset(BM * (BK + 1) * 4);
let threads = (BM / TM) * (BN / TN);
let thread_x = thread::threadIdx_x() as usize;
let thread_y = thread::threadIdx_y() as usize;
let thread_number = thread_y * (BN / TN) + thread_x;
let block_row = thread::blockIdx_y() as usize * BM;
let block_col = thread::blockIdx_x() as usize * BN;
let (m, n, k) = (m as usize, n as usize, k as usize);
let mut acc = [[0.0f32; TN]; TM];
// ...
}
}// C (m x n) = A (m x k) B (k x n), all row-major. A block computes a BM x BN tile of C
// in phases of BK; thread (threadIdx.y, threadIdx.x) computes the TM x TN block of that
// tile that starts at row threadIdx.y * TM and column threadIdx.x * TN, and keeps its
// TM * TN sums in registers.
template <int BM, int BN, int BK, int TM, int TN>
__global__ void __launch_bounds__((BM / TM) * (BN / TN))
matmulRegister(int m, int n, int k, const float* a, const float* b, float* c)
{
const int threads = (BM / TM) * (BN / TN);
__shared__ float tile_a[BM][BK + 1]; // 1 column of padding against bank conflicts
__shared__ float tile_b[BK][BN];
int thread_number = threadIdx.y * (BN / TN) + threadIdx.x;
int block_row = blockIdx.y * BM;
int block_col = blockIdx.x * BN;
float acc[TM][TN] = {};
float a_reg[TM];
float b_reg[TN];
// ...
}
The register tile is the array acc of TM × TN floats, [[0.0f32; TN]; TM] in Rust and
float acc[TM][TN] = {} in C++. A Rust array type may use a const generic parameter as its length,
as here, but not an expression such as TM * TN; the 2-dimensional array needs no such expression.
The tiles in shared memory follow Chapter 17. C++ declares 2 __shared__ arrays sized by the
template parameters, whereas Rust, which cannot size a static by a generic parameter, takes both
tiles from 1 region of dynamic shared memory.
Note that tileA has 1 column of padding, so each of its rows holds \(B_K + 1\) values. The padding prevents a conflict between the reads of line 19. A warp of a 16 × 16 block consists of 2 rows of 16 threads, and in line 19, the 2 rows of threads read rows of tileA that are \(T_M\) rows apart. Without padding, these rows are \(T_M B_K\) values apart, which is 64 values for a 4 × 4 register tile with \(B_K = 16\). Since shared memory has 32 banks and 64 is a multiple of 32, the 2 values fall in the same bank, and the 2 reads are served one after the other (Section 9.5.3). With the padding, the 2 values are \(T_M (B_K + 1) = 68\) values apart, which places them in different banks.
18.6.2 The copy and the outer product
The following code performs the copy of lines 7 to 17 of the pseudocode.
mod kernels {
// ...
pub fn matmul_register<
const BM: usize,
const BN: usize,
const BK: usize,
const TM: usize,
const TN: usize,
>(
m: u32,
n: u32,
k: u32,
a: &[f32],
b: &[f32],
mut c: DisjointSlice<f32, RuntimeRowMajorTiles<TM, TN>>,
) {
// ...
while t < k.div_ceil(BK) {
let mut pass = 0;
#[unroll]
while pass < BM * BK / threads {
let element = pass * threads + thread_number;
let (tile_row, tile_col) = (element / BK, element % BK);
let (a_row, a_col) = (block_row + tile_row, phase * BK + tile_col);
let value = if a_row < m && a_col < k { a[a_row * k + a_col] } else { 0.0 };
// SAFETY: regtile_config launches `threads` threads, so each slot of tile A
// has 1 writer; the slot lies inside the BM x (BK + 1) tile.
unsafe { *tile_a.add(tile_row * (BK + 1) + tile_col) = value };
pass += 1;
}
let mut pass = 0;
#[unroll]
while pass < BK * BN / threads {
let element = pass * threads + thread_number;
let (b_row, b_col) = (phase * BK + element / BN, block_col + element % BN);
let value = if b_row < k && b_col < n { b[b_row * n + b_col] } else { 0.0 };
// SAFETY: as for tile A, with BK x BN slots.
unsafe { *tile_b.add(element) = value };
pass += 1;
}
thread::sync_threads();
// ...
}
// ...
}
}// C (m x n) = A (m x k) B (k x n), all row-major. A block computes a BM x BN tile of C
// in phases of BK; thread (ty, tx) computes the TM x TN block of that tile that starts
// at row ty * TM and column tx * TN, and keeps its TM * TN sums in registers.
template <int BM, int BN, int BK, int TM, int TN>
__global__ void __launch_bounds__((BM / TM) * (BN / TN))
matmulRegister(int m, int n, int k, const float* a, const float* b, float* c)
{
// ...
for (int t = 0; t < phases; ++t) {
#pragma unroll
for (int pass = 0; pass < BM * BK / threads; ++pass) {
int element = pass * threads + thread_number;
int tile_row = element / BK;
int tile_col = element % BK;
int a_row = block_row + tile_row;
int a_col = phase * BK + tile_col;
float value = a_row < m && a_col < k ? a[a_row * k + a_col] : 0.0f;
tile_a[tile_row][tile_col] = value;
}
#pragma unroll
for (int pass = 0; pass < BK * BN / threads; ++pass) {
int element = pass * threads + thread_number;
int tile_row = element / BN;
int tile_col = element % BN;
int b_row = phase * BK + tile_row;
int b_col = block_col + tile_col;
float value = b_row < k && b_col < n ? b[b_row * n + b_col] : 0.0f;
tile_b[tile_row][tile_col] = value;
}
__syncthreads();
// ...
}
// ...
}
In the pass with number \(\mathsf{pass}\) of a copy loop, the thread copies slot \(\mathsf{element} = \mathsf{pass} \cdot \mathsf{threads} + \mathsf{threadNumber}\), so the
passes \(\mathsf{pass} = 0, 1, \ldots\) visit exactly the slots \(\mathsf{threadNumber}\), \(\mathsf{threadNumber} + \mathsf{threads}\),
and so forth, of Section 18.4.1. The loops over pass are therefore the loops of lines 7 and 12,
written with a fixed count: \(B_M B_K / \mathsf{threads}\) passes for tileA and \(B_K B_N / \mathsf{threads}\) passes for
tileB, which are \(64 \cdot 16 / 256 = 4\) passes each for the 4 × 4 configuration. With a
fixed count, the compiler can unroll the loop and issue all the loads from global memory of a phase
before the first store to shared memory, so that their waiting times overlap. A loop that runs
element from thread_number in steps of threads while \(\mathsf{element} < B_M B_K\), the
literal form of line 7, does the same work. However, its count is unknown to the compiler, and on
the measured GPU, it ran the 2 × 2 configuration at 380 GFLOP/s, against 580 GFLOP/s with the fixed count.
The following code performs the steps of lines 18 to 22 of the pseudocode, the reads into registers and the outer product.
mod kernels {
// ...
pub fn matmul_register<
const BM: usize,
const BN: usize,
const BK: usize,
const TM: usize,
const TN: usize,
>(
m: u32,
n: u32,
k: u32,
a: &[f32],
b: &[f32],
mut c: DisjointSlice<f32, RuntimeRowMajorTiles<TM, TN>>,
) {
// ...
while t < k.div_ceil(BK) {
// ...
let mut offset = 0;
#[unroll]
while offset < BK {
let mut a_reg = [0.0f32; TM];
let mut b_reg = [0.0f32; TN];
let mut local_row = 0;
#[unroll]
while local_row < TM {
let slot = (thread_y * TM + local_row) * (BK + 1) + offset;
// SAFETY: between the 2 barriers no thread writes either tile.
a_reg[local_row] = unsafe { *tile_a.add(slot) };
local_row += 1;
}
let mut local_col = 0;
#[unroll]
while local_col < TN {
let slot = offset * BN + thread_x * TN + local_col;
// SAFETY: between the 2 barriers no thread writes either tile.
b_reg[local_col] = unsafe { *tile_b.add(slot) };
local_col += 1;
}
let mut local_row = 0;
#[unroll]
while local_row < TM {
let mut local_col = 0;
#[unroll]
while local_col < TN {
acc[local_row][local_col] += a_reg[local_row] * b_reg[local_col];
local_col += 1;
}
local_row += 1;
}
offset += 1;
}
thread::sync_threads();
// ...
}
// ...
}
}// C (m x n) = A (m x k) B (k x n), all row-major. A block computes a BM x BN tile of C
// in phases of BK; thread (ty, tx) computes the TM x TN block of that tile that starts
// at row ty * TM and column tx * TN, and keeps its TM * TN sums in registers.
template <int BM, int BN, int BK, int TM, int TN>
__global__ void __launch_bounds__((BM / TM) * (BN / TN))
matmulRegister(int m, int n, int k, const float* a, const float* b, float* c)
{
// ...
for (int t = 0; t < phases; ++t) {
// ...
#pragma unroll
for (int offset = 0; offset < BK; ++offset) {
#pragma unroll
for (int local_row = 0; local_row < TM; ++local_row) {
a_reg[local_row] = tile_a[threadIdx.y * TM + local_row][offset];
}
#pragma unroll
for (int local_col = 0; local_col < TN; ++local_col) {
b_reg[local_col] = tile_b[offset][threadIdx.x * TN + local_col];
}
#pragma unroll
for (int local_row = 0; local_row < TM; ++local_row) {
#pragma unroll
for (int local_col = 0; local_col < TN; ++local_col) {
acc[local_row][local_col] += a_reg[local_row] * b_reg[local_col];
}
}
}
__syncthreads();
}
// ...
}
Every loop in this code has a count that is fixed by the constants, and every one of them must be
unrolled. When the loops over local_row and local_col are unrolled, they become \(T_M T_N\) separate
multiply-adds with constant indices, and each of acc[local_row][local_col], a_reg[local_row] and
b_reg[local_col] names 1 register. If a loop is not unrolled, its index is computed at run time, and the compiler must then
keep acc in local memory, a per-thread area of global memory. In C++, #pragma unroll asks the
compiler to unroll the next loop. nvcc unrolls loops with constant bounds of this size on its own,
so the pragma mainly states the intent. In cuda-oxide, #[unroll] on a while loop does the same,
and there it is required: cuda-oxide at the revision used here does not unroll a for loop over a
range, and in Section 9.7, we measured the 4 × 4 kernel 33% slower with for loops.
18.6.3 Writing the register tile
We let each thread write \(T_M T_N\) entries of \(C\), not 1. In C++, the store of lines 25 to 31 is
a pair of loops with a guard. In Rust, the index space Runtime2DIndex of a DisjointSlice gives
each thread a single element. Recall that in Chapter 9, we therefore wrote the 4 × 4 patch through
get_unchecked_mut, an unsafe call whose SAFETY comment argued that the patches of different
threads do not overlap. cuda-oxide has an index space for this case, RuntimeRowMajorTiles<TM, TN>,
in which thread \((y, x)\) of the grid owns rows \([y T_M, y T_M + T_M)\) and columns
\([x T_N, x T_N + T_N)\) of a matrix whose row width the host binds with RowWidth, exactly as in
Chapter 16. For example, with \(T_M = T_N = 2\), thread \((1, 0)\) of the grid owns rows 2 and 3
and columns 0 and 1. The following code stores the register tile, lines 25 to 31 of the
pseudocode.
mod kernels {
// ...
pub fn matmul_register<
const BM: usize,
const BN: usize,
const BK: usize,
const TM: usize,
const TN: usize,
>(
m: u32,
n: u32,
k: u32,
a: &[f32],
b: &[f32],
mut c: DisjointSlice<f32, RuntimeRowMajorTiles<TM, TN>>,
) {
// ...
if let Some(mut tile) = c.tile_2d32_rt(thread::coord_2d_u32(lc)) {
let mut local_row = 0;
#[unroll]
while local_row < TM {
let mut local_col = 0;
#[unroll]
while local_col < TN {
if let Some(row_in_tile) = LocalIndex32::new(local_row as u32)
&& let Some(col_in_tile) = LocalIndex32::new(local_col as u32)
{
tile.at(row_in_tile, col_in_tile).write(acc[local_row][local_col]);
}
local_col += 1;
}
local_row += 1;
}
}
}
}// C (m x n) = A (m x k) B (k x n), all row-major. A block computes a BM x BN tile of C
// in phases of BK; thread (ty, tx) computes the TM x TN block of that tile that starts
// at row ty * TM and column tx * TN, and keeps its TM * TN sums in registers.
template <int BM, int BN, int BK, int TM, int TN>
__global__ void __launch_bounds__((BM / TM) * (BN / TN))
matmulRegister(int m, int n, int k, const float* a, const float* b, float* c)
{
// ...
#pragma unroll
for (int local_row = 0; local_row < TM; ++local_row) {
#pragma unroll
for (int local_col = 0; local_col < TN; ++local_col) {
int row = block_row + threadIdx.y * TM + local_row;
int col = block_col + threadIdx.x * TN + local_col;
if (row < m && col < n) {
c[row * n + col] = acc[local_row][local_col];
}
}
}
}
In the Rust code, thread::coord_2d_u32(lc) returns the thread’s coordinates in the grid, row
\(\mathsf{blockIdx{.}y} \cdot (B_M/T_M) + \mathsf{threadIdx{.}y}\) and column \(\mathsf{blockIdx{.}x} \cdot (B_N/T_N) + \mathsf{threadIdx{.}x}\). It is available only in a
kernel whose contract declares domain = 2, coordinates = u32 and whose
#[kernel(launch_context = lc)] names the launch context; both attributes stand above the kernel
in the complete program of Section 18.8. Before it creates any pointer,
c.tile_2d32_rt(...) checks that the whole \(T_M \times T_N\) rectangle of this thread lies
inside a single row band of the slice, and it returns a tile view, or None if the rectangle does
not fit. LocalIndex32::new(local_row) turns local_row into an index that is known to be below TM,
and tile.at(row_in_tile, col_in_tile).write(...) stores the value without a further check. Distinct grid coordinates give
disjoint rectangles, so the write needs no unsafe. Note also that multiplying the grid
coordinates by the tile sizes gives exactly the ownership of Section 18.4.1: the row
\((\mathsf{blockIdx{.}y} \cdot (B_M/T_M) + \mathsf{threadIdx{.}y}) \cdot T_M\) equals \(\mathsf{blockIdx{.}y} \cdot B_M + \mathsf{threadIdx{.}y} \cdot T_M\).
18.6.4 The launch
The following functions compute the grid, the block and, in Rust, the dynamic shared memory from the 5 constants, and launch the kernel.
/// The launch of matmul_register for an m x n matrix C: (BN / TN) x (BM / TM) threads
/// per block, enough blocks to cover C, and tiles of BM x (BK + 1) and BK x BN floats.
/// Every thread's TM x TN block must lie wholly inside C or wholly outside it.
fn regtile_config<
const BM: usize,
const BN: usize,
const BK: usize,
const TM: usize,
const TN: usize,
>(
m: usize,
n: usize,
) -> Result<LaunchConfig2D, Error> {
if m % TM != 0 || n % TN != 0 {
let message = format!("{m} x {n} is not a multiple of the thread tile {TM} x {TN}");
return Err(message.into());
}
let grid = ((n as u32).div_ceil(BN as u32), (m as u32).div_ceil(BM as u32));
let block = ((BN / TN) as u32, (BM / TM) as u32);
let shared = ((BM * (BK + 1) + BK * BN) * size_of::<f32>()) as u32;
Ok(LaunchConfig2D::new(grid, block, shared))
}template <int BM, int BN, int BK, int TM, int TN>
void launch(const Product& p)
{
dim3 grid((p.n + BN - 1) / BN, (p.m + BM - 1) / BM);
dim3 block(BN / TN, BM / TM);
matmulRegister<BM, BN, BK, TM, TN><<<grid, block>>>(p.m, p.n, p.k, p.a, p.b, p.c);
}
Both functions derive the grid and the block from the constants, as the Rule of Section 18.5 asks:
\(B_N/T_N\) threads along \(x\), \(B_M/T_M\) threads along \(y\), and enough blocks to cover
\(C\). The Rust function also computes the dynamic shared memory,
\((B_M (B_K + 1) + B_K B_N) \cdot 4\) bytes, which is
\((64 \cdot 17 + 16 \cdot 64) \cdot 4 = 8{,}448\) bytes for the 4 × 4 configuration, inside the
range of 64 to 16,384 bytes that the contract accepts. In addition, it returns an error unless
\(T_M\) divides \(m\) and \(T_N\) divides \(n\). The reason is that tile_2d32_rt returns a
tile only when the whole rectangle fits, so a thread whose register tile crossed the edge of \(C\)
would write nothing, and its entries inside \(C\) would stay 0. The check turns that silent error
into a refused launch. The C++ store, in contrast, has a guard for each entry and handles partial
tiles, at the cost of a comparison per store. Both programs check every entry of a 1,000 × 1,000
product with the 4 × 4 configuration, whose 64 × 64 blocks overhang \(C\) by 24 rows and 24
columns.
Exercises
18.12 Add the configuration \(B_M = 64\), \(B_N = 32\), \(B_K = 16\), \(T_M = 4\),
\(T_N = 2\) to both programs. How many threads does a block have, and how many values does each
copy per tile per phase?
18.13 Remove #[unroll] from the loops over local_row and local_col in the Rust kernel, run the 4 × 4
configuration, and explain the change in speed.
18.14 Launch the Rust kernel for a 1,002 × 1,002 product with the 4 × 4 configuration. What does
regtile_config return, and why?
18.7 Measurements
18.7.1 Results
The measurements come from the GPU of Chapters 16 and 17 (8 SMs, 102 GB/s, 2,400 GFLOP/s), and we use the same method. Both programs first run the 4 × 4 example with 1 block of 2 × 2 threads, then check the 1,000 × 1,000 product, and finally time 6 kernels on square matrices of size 1,024, 2,048 and 4,096. The 6 kernels are the tiled kernel of Chapter 17 with \(T = 16\), and the register-tiled kernel with thread tiles of 1 × 1, 2 × 1, 2 × 2, 4 × 4 and 8 × 8, all with 256 threads per block.
The Rust program prints the following output.
$ cargo oxide run
C = A B on the 4 x 4 example, 1 block of 2 x 2 threads, 2 x 2 entries per thread
11 13 8 8
27 29 24 24
43 45 40 40
59 61 56 56
equal to the product computed by hand: yes
m = 1000, k = 1000, n = 1000, 4 x 4 per thread: 1000000 of 1000000 entries exact
C = A B, n x n, 256 threads per block
n thread block ms GFLOP/s reads/FMA fetched MiB exact
1024 Ch. 17 16 x 16 7.888 272.2 2.00 512.0 64 of 64
1024 1 x 1 16 x 16 9.657 222.4 2.00 512.0 64 of 64
1024 2 x 1 32 x 16 5.559 386.3 1.50 384.0 64 of 64
1024 2 x 2 32 x 32 3.792 566.2 1.00 256.0 64 of 64
1024 4 x 4 64 x 64 2.541 845.1 0.50 128.0 64 of 64
1024 8 x 8 128 x 128 2.821 761.2 0.25 64.0 64 of 64
2048 Ch. 17 16 x 16 62.312 275.7 2.00 4096.0 64 of 64
2048 1 x 1 16 x 16 78.145 219.8 2.00 4096.0 64 of 64
2048 2 x 1 32 x 16 43.445 395.4 1.50 3072.0 64 of 64
2048 2 x 2 32 x 32 30.245 568.0 1.00 2048.0 64 of 64
2048 4 x 4 64 x 64 19.861 865.0 0.50 1024.0 64 of 64
2048 8 x 8 128 x 128 21.330 805.4 0.25 512.0 64 of 64
4096 Ch. 17 16 x 16 500.956 274.4 2.00 32768.0 64 of 64
4096 1 x 1 16 x 16 626.368 219.4 2.00 32768.0 64 of 64
4096 2 x 1 32 x 16 352.620 389.8 1.50 24576.0 64 of 64
4096 2 x 2 32 x 32 241.749 568.5 1.00 16384.0 64 of 64
4096 4 x 4 64 x 64 156.975 875.5 0.50 8192.0 64 of 64
4096 8 x 8 128 x 128 166.083 827.5 0.25 4096.0 64 of 64
PASSED
The column reads/FMA is \((T_M + T_N)/(T_M T_N)\), and the column fetched MiB is the model of Section 18.3, \(n^3 (1/B_M + 1/B_N)\) values of 4 bytes each. The C++ program prints the same lines. The following table compares the two programs at \(n = 4{,}096\). It also lists the shared-memory limit of Section 18.1.2 for each kernel, \(300 \cdot 2 / r\) GFLOP/s for \(r\) reads per multiply-add, and the number of registers per thread that nvcc reports for each C++ kernel.
| Kernel | Reads per multiply-add | Limit | C++ rate | Rust rate | C++ registers |
|---|---|---|---|---|---|
| Chapter 17, \(T = 16\) | 2 | 300 GFLOP/s | 271.9 GFLOP/s | 274.4 GFLOP/s | 38 |
| 1 × 1, 16 × 16 block | 2 | 300 GFLOP/s | 220.4 GFLOP/s | 219.4 GFLOP/s | 37 |
| 2 × 1, 32 × 16 block | 1.5 | 400 GFLOP/s | 391.5 GFLOP/s | 389.8 GFLOP/s | 40 |
| 2 × 2, 32 × 32 block | 1 | 600 GFLOP/s | 583.5 GFLOP/s | 568.5 GFLOP/s | 40 |
| 4 × 4, 64 × 64 block | 0.5 | 1,200 GFLOP/s | 1,009.9 GFLOP/s | 875.5 GFLOP/s | 72 |
| 8 × 8, 128 × 128 block | 0.25 | 2,400 GFLOP/s | 773.1 GFLOP/s | 827.5 GFLOP/s | 138 |
18.7.2 Comparison with the model
Up to the 2 × 2 register tile, the model of Section 18.1.2 predicts the measurements well. Halving the reads per multiply-add from 2 to 1 doubled the rate, and each configuration ran within 3% to 5% of its limit: in C++, 391.5 of 400 GFLOP/s for 2 × 1 and 583.5 of 600 GFLOP/s for 2 × 2, with Rust within 3% of C++. The 1 × 1 configuration performs the same arithmetic as the tiled kernel of Chapter 17 and fetches the same values, but it ran at 220 GFLOP/s instead of 272. The two kernels differ only in their copy code, which in the general kernel computes each slot from the slot number \(\mathsf{element}\).
The 4 × 4 register tile reached 1,009.9 GFLOP/s in C++, which is 42% of the FP32 peak and 3.7 times the rate of the tiled kernel of Chapter 17, but only 84% of its limit of 1,200 GFLOP/s. At this point, 2 other limits become visible. The first is global memory. A block performs 64 FLOP for every float that it fetches, so at 102 GB/s, or 25.5 billion floats per second, the kernel can perform at most \(25.5 \cdot 64 = 1{,}632\) GFLOP/s. The second is occupancy. With 72 registers per thread, a block of 256 threads needs \(72 \cdot 256 = 18{,}432\) registers, so the 65,536 registers of an SM hold \(65{,}536 / 18{,}432 = 3.6\), that is, 3 blocks. These are 768 threads, an occupancy of 50%. With half as many warps to switch between, the SM hides less of the time that each warp spends waiting for shared memory and at the barriers.
The 8 × 8 register tile reads shared memory least, 0.25 times per multiply-add, but in C++, it ran slower than the 4 × 4 tile. Its 64 sums and 16 operands took 138 registers per thread, so only \(65{,}536 / (138 \cdot 256) = 1.9\), that is, 1 block of 256 threads fits on an SM, an occupancy of 17%. When that block waits at a barrier, the SM has nothing else to run. The Rust compiler allocated registers differently: its 8 × 8 kernel ran at 827.5 GFLOP/s, faster than the C++ one, whereas its 4 × 4 kernel, at 875.5 GFLOP/s, was slower. In general, larger register tiles help only as long as the registers they need leave enough threads on each SM.
These results agree with those of Chapter 9, where we measured a 4 × 4 patch kernel of the same
shape on the same GPU at 901.4 GFLOP/s in C++, at 931.9 GFLOP/s with __launch_bounds__ asking for
4 blocks per SM, and at 844.9 GFLOP/s in Rust. Our C++ kernel is 8% faster than the best of those,
in part because of the fixed-count copy loops of Section 18.6.2. cuBLAS ran the same product at
1,495.3 GFLOP/s, 62% of the peak. The techniques that it adds are listed in Section 9.8; among them
are wider loads from shared memory and copying the next tiles while computing on the current ones.
From the direct kernel of Chapter 16 to the 4 × 4 register tile, the time of the 4,096 × 4,096 product fell from 743 ms to 136 ms in C++, a speedup of 5.5. Each step removed 1 measured limit: tiling removed the dependence on global memory, and register tiling removed the dependence on shared memory.
18.8 The complete programs
//! Chapter 18: register tiling, a TM x TN block of C per thread.
//!
//! cargo oxide run
use std::sync::Arc;
use std::time::Instant;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, LaunchConfig2D};
use cuda_device::thread::Runtime2DIndex;
use cuda_device::{DisjointSlice, DynamicSharedArray, SharedArray};
use cuda_device::{LocalIndex32, RuntimeRowMajorTiles};
use cuda_device::{cuda_module, kernel, launch_bounds, launch_contract, thread};
use cuda_host::RowWidth;
type Error = Box<dyn std::error::Error>;
type Module = kernels::LoadedModule;
#[cuda_module]
mod kernels {
use super::*;
/// The tiled kernel of Chapter 17 with T = 16, for comparison: a block of 16 x 16
/// threads computes a 16 x 16 square of C, with 2 tiles in static shared memory.
#[kernel]
#[launch_contract(
domain = 2,
coordinates = u32,
block = (16, 16, 1),
requires = (a.len() >= m * k, b.len() >= k * n, c.len() >= m * n)
)]
pub fn matmul_tiled(
m: u32,
n: u32,
k: u32,
a: &[f32],
b: &[f32],
mut c: DisjointSlice<f32, Runtime2DIndex>,
) {
static mut TILE_A: SharedArray<f32, 256> = SharedArray::UNINIT;
static mut TILE_B: SharedArray<f32, 256> = SharedArray::UNINIT;
let thread_x = thread::threadIdx_x() as usize;
let thread_y = thread::threadIdx_y() as usize;
let row = thread::index_2d_row();
let col = thread::index_2d_col();
let (m, n, k) = (m as usize, n as usize, k as usize);
let mut sum = 0.0;
let mut phase = 0;
while phase < k.div_ceil(16) {
let (a_col, b_row) = (phase * 16 + thread_x, phase * 16 + thread_y);
let a_value = if row < m && a_col < k { a[row * k + a_col] } else { 0.0 };
let b_value = if b_row < k && col < n { b[b_row * n + col] } else { 0.0 };
// SAFETY: the contract fixes the block at 16 x 16, so slot
// thread_y * 16 + thread_x is below 256 and is this thread's alone.
unsafe {
TILE_A[thread_y * 16 + thread_x] = a_value;
TILE_B[thread_y * 16 + thread_x] = b_value;
}
thread::sync_threads();
let mut offset = 0;
#[unroll]
while offset < 16 {
let (a_slot, b_slot) = (thread_y * 16 + offset, offset * 16 + thread_x);
// SAFETY: between the 2 barriers no thread writes either tile.
sum += unsafe { TILE_A[a_slot] * TILE_B[b_slot] };
offset += 1;
}
thread::sync_threads();
phase += 1;
}
if row < m
&& col < n
&& let Some(idx) = thread::index_2d_runtime(&c)
&& let Some(out) = c.get_mut(idx)
{
*out = sum;
}
}
/// C (m x n) = A (m x k) B (k x n), all row-major. A block computes a BM x BN tile of
/// C in phases of BK; thread (threadIdx.y, threadIdx.x) computes the TM x TN block of
/// that tile that starts at row threadIdx.y * TM and column threadIdx.x * TN, and keeps
/// its TM * TN sums in registers.
#[kernel(launch_context = lc)]
#[launch_bounds(256)]
#[launch_contract(
domain = 2,
coordinates = u32,
dynamic_shared_range = (64, 16384),
requires = (a.len() >= m * k, b.len() >= k * n, c.len() >= m * n)
)]
pub fn matmul_register<
const BM: usize,
const BN: usize,
const BK: usize,
const TM: usize,
const TN: usize,
>(
m: u32,
n: u32,
k: u32,
a: &[f32],
b: &[f32],
mut c: DisjointSlice<f32, RuntimeRowMajorTiles<TM, TN>>,
) {
let tile_a: *mut f32 = DynamicSharedArray::<f32>::get();
let tile_b: *mut f32 = DynamicSharedArray::<f32>::offset(BM * (BK + 1) * 4);
let threads = (BM / TM) * (BN / TN);
let thread_x = thread::threadIdx_x() as usize;
let thread_y = thread::threadIdx_y() as usize;
let thread_number = thread_y * (BN / TN) + thread_x;
let block_row = thread::blockIdx_y() as usize * BM;
let block_col = thread::blockIdx_x() as usize * BN;
let (m, n, k) = (m as usize, n as usize, k as usize);
let mut acc = [[0.0f32; TN]; TM];
let mut phase = 0;
while phase < k.div_ceil(BK) {
let mut pass = 0;
#[unroll]
while pass < BM * BK / threads {
let element = pass * threads + thread_number;
let (tile_row, tile_col) = (element / BK, element % BK);
let (a_row, a_col) = (block_row + tile_row, phase * BK + tile_col);
let value = if a_row < m && a_col < k { a[a_row * k + a_col] } else { 0.0 };
// SAFETY: regtile_config launches `threads` threads, so each slot of tile A
// has 1 writer; the slot lies inside the BM x (BK + 1) tile.
unsafe { *tile_a.add(tile_row * (BK + 1) + tile_col) = value };
pass += 1;
}
let mut pass = 0;
#[unroll]
while pass < BK * BN / threads {
let element = pass * threads + thread_number;
let (b_row, b_col) = (phase * BK + element / BN, block_col + element % BN);
let value = if b_row < k && b_col < n { b[b_row * n + b_col] } else { 0.0 };
// SAFETY: as for tile A, with BK x BN slots.
unsafe { *tile_b.add(element) = value };
pass += 1;
}
thread::sync_threads();
let mut offset = 0;
#[unroll]
while offset < BK {
let mut a_reg = [0.0f32; TM];
let mut b_reg = [0.0f32; TN];
let mut local_row = 0;
#[unroll]
while local_row < TM {
let slot = (thread_y * TM + local_row) * (BK + 1) + offset;
// SAFETY: between the 2 barriers no thread writes either tile.
a_reg[local_row] = unsafe { *tile_a.add(slot) };
local_row += 1;
}
let mut local_col = 0;
#[unroll]
while local_col < TN {
let slot = offset * BN + thread_x * TN + local_col;
// SAFETY: between the 2 barriers no thread writes either tile.
b_reg[local_col] = unsafe { *tile_b.add(slot) };
local_col += 1;
}
let mut local_row = 0;
#[unroll]
while local_row < TM {
let mut local_col = 0;
#[unroll]
while local_col < TN {
acc[local_row][local_col] += a_reg[local_row] * b_reg[local_col];
local_col += 1;
}
local_row += 1;
}
offset += 1;
}
thread::sync_threads();
phase += 1;
}
if let Some(mut tile) = c.tile_2d32_rt(thread::coord_2d_u32(lc)) {
let mut local_row = 0;
#[unroll]
while local_row < TM {
let mut local_col = 0;
#[unroll]
while local_col < TN {
if let Some(row_in_tile) = LocalIndex32::new(local_row as u32)
&& let Some(col_in_tile) = LocalIndex32::new(local_col as u32)
{
tile.at(row_in_tile, col_in_tile).write(acc[local_row][local_col]);
}
local_col += 1;
}
local_row += 1;
}
}
}
}
/// The launch of matmul_register for an m x n matrix C: (BN / TN) x (BM / TM) threads
/// per block, enough blocks to cover C, and tiles of BM x (BK + 1) and BK x BN floats.
/// Every thread's TM x TN block must lie wholly inside C or wholly outside it.
fn regtile_config<
const BM: usize,
const BN: usize,
const BK: usize,
const TM: usize,
const TN: usize,
>(
m: usize,
n: usize,
) -> Result<LaunchConfig2D, Error> {
if m % TM != 0 || n % TN != 0 {
let message = format!("{m} x {n} is not a multiple of the thread tile {TM} x {TN}");
return Err(message.into());
}
let grid = ((n as u32).div_ceil(BN as u32), (m as u32).div_ceil(BM as u32));
let block = ((BN / TN) as u32, (BM / TM) as u32);
let shared = ((BM * (BK + 1) + BK * BN) * size_of::<f32>()) as u32;
Ok(LaunchConfig2D::new(grid, block, shared))
}
/// Average time of `runs` launches in milliseconds, after 1 launch that is not timed.
fn time_ms<F>(stream: &CudaStream, runs: u32, mut launch: F) -> Result<f64, Error>
where
F: FnMut() -> Result<(), Error>,
{
launch()?;
stream.synchronize()?;
let start = Instant::now();
for _ in 0..runs {
launch()?;
}
stream.synchronize()?;
Ok(start.elapsed().as_secs_f64() * 1e3 / runs as f64)
}
/// Integers in [-5, 5] from a small linear congruential generator: every partial sum
/// of a product with k <= 4096 is an integer below 2^24, so f32 results are exact.
fn integers(len: usize, state: &mut u32) -> Vec<f32> {
let mut values = Vec::with_capacity(len);
for _ in 0..len {
*state = state.wrapping_mul(1_664_525).wrapping_add(1_013_904_223);
values.push(((*state >> 8) % 11) as f32 - 5.0);
}
values
}
/// An m x k by k x n product: the inputs on the host and all 3 matrices on the device.
struct Problem {
m: usize,
n: usize,
k: usize,
a_host: Vec<f32>,
b_host: Vec<f32>,
a: DeviceBuffer<f32>,
b: DeviceBuffer<f32>,
c: DeviceBuffer<f32>,
}
impl Problem {
fn new(stream: &Arc<CudaStream>, m: usize, n: usize, k: usize) -> Result<Self, Error> {
let mut state = if m == n && n == k { 1 } else { 7 };
let a_host = integers(m * k, &mut state);
let b_host = integers(k * n, &mut state);
let a = DeviceBuffer::from_host(stream, &a_host)?;
let b = DeviceBuffer::from_host(stream, &b_host)?;
let c = DeviceBuffer::<f32>::zeroed(stream, m * n)?;
Ok(Problem { m, n, k, a_host, b_host, a, b, c })
}
/// Launch matmul_register::<BM, BN, BK, TM, TN> on this problem.
fn run<
const BM: usize,
const BN: usize,
const BK: usize,
const TM: usize,
const TN: usize,
>(
&mut self,
module: &Module,
stream: &Arc<CudaStream>,
) -> Result<(), Error> {
let config = regtile_config::<BM, BN, BK, TM, TN>(self.m, self.n)?;
let ready = module.prepare_matmul_register::<BM, BN, BK, TM, TN>(config)?;
let (m, n, k) = (self.m as u32, self.n as u32, self.k as u32);
let w = RowWidth::new(&mut self.c, n);
let (a, b) = (&self.a, &self.b);
module.matmul_register::<BM, BN, BK, TM, TN>(stream, &ready, m, n, k, a, b, w)?;
Ok(())
}
/// Launch matmul_tiled, the kernel of Chapter 17, on this problem.
fn tiled16(&mut self, module: &Module, stream: &Arc<CudaStream>) -> Result<(), Error> {
let side = 16;
let grid = ((self.n as u32).div_ceil(side), (self.m as u32).div_ceil(side));
let config = LaunchConfig2D::new(grid, (side, side), 0);
let ready = module.prepare_matmul_tiled(config)?;
let (m, n, k) = (self.m as u32, self.n as u32, self.k as u32);
let w = RowWidth::new(&mut self.c, n);
module.matmul_tiled(stream, &ready, m, n, k, &self.a, &self.b, w)?;
Ok(())
}
/// The number of `samples` entries of C (all of them if C is smaller) that are exact.
fn exact_entries(&self, stream: &CudaStream, samples: usize) -> Result<usize, Error> {
let (m, n, k) = (self.m, self.n, self.k);
let c = self.c.to_host_vec(stream)?;
let count = samples.min(m * n);
let mut exact = 0;
for sample in 0..count {
let row = if count == m * n { sample / n } else { sample * 977 % m };
let col = if count == m * n { sample % n } else { (sample * 1231 + 7) % n };
let mut sum = 0.0;
for inner in 0..k {
let a_value = self.a_host[row * k + inner] as f64;
let b_value = self.b_host[inner * n + col] as f64;
sum += a_value * b_value;
}
if c[row * n + col] as f64 == sum {
exact += 1;
}
}
Ok(exact)
}
}
/// The 4 x 4 example: 1 block of 2 x 2 threads, each thread a 2 x 2 block of C.
fn run_example(module: &Module, stream: &Arc<CudaStream>) -> Result<bool, Error> {
let a_int = [1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12, 13, 14, 15, 16];
let b_int = [1, 0, 2, 1, 0, 1, 1, 2, 2, 1, 0, 1, 1, 2, 1, 0];
let want = [11, 13, 8, 8, 27, 29, 24, 24, 43, 45, 40, 40, 59, 61, 56, 56];
let mut p = Problem::new(stream, 4, 4, 4)?;
p.a_host = a_int.iter().map(|&x| x as f32).collect();
p.b_host = b_int.iter().map(|&x| x as f32).collect();
p.a = DeviceBuffer::from_host(stream, &p.a_host)?;
p.b = DeviceBuffer::from_host(stream, &p.b_host)?;
p.run::<4, 4, 2, 2, 2>(module, stream)?;
let c = p.c.to_host_vec(stream)?;
print!("C = A B on the 4 x 4 example, 1 block of 2 x 2 threads,");
println!(" 2 x 2 entries per thread");
for row in c.chunks(4) {
println!(" {:4} {:4} {:4} {:4}", row[0], row[1], row[2], row[3]);
}
let same = c.iter().zip(want).all(|(&got, w)| got == w as f32);
let answer = if same { "yes" } else { "no" };
println!("equal to the product computed by hand: {answer}\n");
Ok(same)
}
/// A shape that is not a multiple of any block tile: every entry of C is checked.
fn run_shape(module: &Module, stream: &Arc<CudaStream>) -> Result<bool, Error> {
let (m, n, k) = (1000, 1000, 1000);
let mut p = Problem::new(stream, m, n, k)?;
p.run::<64, 64, 16, 4, 4>(module, stream)?;
let exact = p.exact_entries(stream, m * n)?;
let all = m * n;
print!(" m = {m:4}, k = {k:4}, n = {n:4}, 4 x 4 per thread:");
println!(" {exact:7} of {all:7} entries exact\n");
Ok(exact == all)
}
/// Time 1 kernel on n x n matrices and print 1 line of the table. The kernel computes
/// bm x bn tiles of C, tm x tn entries per thread.
fn run_timed<F>(
stream: &Arc<CudaStream>,
n: usize,
name: &str,
(bm, bn, tm, tn): (usize, usize, usize, usize),
launch: F,
) -> Result<bool, Error>
where
F: Fn(&mut Problem) -> Result<(), Error>,
{
let mut p = Problem::new(stream, n, n, n)?;
let cube = (n * n * n) as f64;
let runs = (1e11 / (cube * 4.0)) as u32 + 2;
let ms = time_ms(stream, runs.min(50), || launch(&mut p))?;
let exact = p.exact_entries(stream, 64)?;
let gflops = 2.0 * cube / ms / 1e6;
let reads = (tm + tn) as f64 / (tm * tn) as f64;
let fetched = cube * (1.0 / bm as f64 + 1.0 / bn as f64) * 4.0 / (1 << 20) as f64;
print!(" {n:5} {name:<9} {bm:3} x {bn:3} {ms:9.3} {gflops:9.1}");
println!(" {reads:10.2} {fetched:12.1} {exact:6} of 64");
Ok(exact == 64)
}
/// run_timed for matmul_register::<BM, BN, BK, TM, TN>.
fn run_config<
const BM: usize,
const BN: usize,
const BK: usize,
const TM: usize,
const TN: usize,
>(
module: &Module,
stream: &Arc<CudaStream>,
n: usize,
name: &str,
) -> Result<bool, Error> {
let shape = (BM, BN, TM, TN);
run_timed(stream, n, name, shape, |p| p.run::<BM, BN, BK, TM, TN>(module, stream))
}
/// About 0.5 s of 1024 x 1024 products: the GPU raises its clocks under sustained load.
fn warm_up(module: &Module, stream: &Arc<CudaStream>) -> Result<(), Error> {
let mut p = Problem::new(stream, 1024, 1024, 1024)?;
let start = Instant::now();
while start.elapsed().as_millis() < 500 {
p.run::<64, 64, 16, 4, 4>(module, stream)?;
stream.synchronize()?;
}
Ok(())
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let (module, stream) = (&module, &stream);
let mut passed = run_example(module, stream)?;
passed &= run_shape(module, stream)?;
warm_up(module, stream)?;
println!("C = A B, n x n, 256 threads per block");
print!(" n thread block ms GFLOP/s");
println!(" reads/FMA fetched MiB exact");
for n in [1024, 2048, 4096] {
let tiled = |p: &mut Problem| p.tiled16(module, stream);
passed &= run_timed(stream, n, "Ch. 17", (16, 16, 1, 1), tiled)?;
passed &= run_config::<16, 16, 16, 1, 1>(module, stream, n, "1 x 1")?;
passed &= run_config::<32, 16, 16, 2, 1>(module, stream, n, "2 x 1")?;
passed &= run_config::<32, 32, 16, 2, 2>(module, stream, n, "2 x 2")?;
passed &= run_config::<64, 64, 16, 4, 4>(module, stream, n, "4 x 4")?;
passed &= run_config::<128, 128, 8, 8, 8>(module, stream, n, "8 x 8")?;
}
println!("{}", if passed { "PASSED" } else { "FAILED" });
Ok(())
}// Chapter 18: register tiling, a TM x TN block of C per thread.
// Build: nvcc -O3 -arch=native matmul_register_tiled.cu -o matmul_register_tiled
#include <chrono>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cuda_runtime.h>
using Matrix = std::vector<float>;
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
// C (m x n) = A (m x k) B (k x n), all row-major. A block computes a BM x BN tile of C
// in phases of BK; thread (threadIdx.y, threadIdx.x) computes the TM x TN block of that
// tile that starts at row threadIdx.y * TM and column threadIdx.x * TN, and keeps its
// TM * TN sums in registers.
template <int BM, int BN, int BK, int TM, int TN>
__global__ void __launch_bounds__((BM / TM) * (BN / TN))
matmulRegister(int m, int n, int k, const float* a, const float* b, float* c)
{
const int threads = (BM / TM) * (BN / TN);
__shared__ float tile_a[BM][BK + 1]; // 1 column of padding against bank conflicts
__shared__ float tile_b[BK][BN];
int thread_number = threadIdx.y * (BN / TN) + threadIdx.x;
int block_row = blockIdx.y * BM;
int block_col = blockIdx.x * BN;
float acc[TM][TN] = {};
float a_reg[TM];
float b_reg[TN];
int phases = (k + BK - 1) / BK;
for (int phase = 0; phase < phases; ++phase) {
#pragma unroll
for (int pass = 0; pass < BM * BK / threads; ++pass) {
int element = pass * threads + thread_number;
int tile_row = element / BK;
int tile_col = element % BK;
int a_row = block_row + tile_row;
int a_col = phase * BK + tile_col;
float value = a_row < m && a_col < k ? a[a_row * k + a_col] : 0.0f;
tile_a[tile_row][tile_col] = value;
}
#pragma unroll
for (int pass = 0; pass < BK * BN / threads; ++pass) {
int element = pass * threads + thread_number;
int tile_row = element / BN;
int tile_col = element % BN;
int b_row = phase * BK + tile_row;
int b_col = block_col + tile_col;
float value = b_row < k && b_col < n ? b[b_row * n + b_col] : 0.0f;
tile_b[tile_row][tile_col] = value;
}
__syncthreads();
#pragma unroll
for (int offset = 0; offset < BK; ++offset) {
#pragma unroll
for (int local_row = 0; local_row < TM; ++local_row) {
a_reg[local_row] = tile_a[threadIdx.y * TM + local_row][offset];
}
#pragma unroll
for (int local_col = 0; local_col < TN; ++local_col) {
b_reg[local_col] = tile_b[offset][threadIdx.x * TN + local_col];
}
#pragma unroll
for (int local_row = 0; local_row < TM; ++local_row) {
#pragma unroll
for (int local_col = 0; local_col < TN; ++local_col) {
acc[local_row][local_col] += a_reg[local_row] * b_reg[local_col];
}
}
}
__syncthreads();
}
#pragma unroll
for (int local_row = 0; local_row < TM; ++local_row) {
#pragma unroll
for (int local_col = 0; local_col < TN; ++local_col) {
int row = block_row + threadIdx.y * TM + local_row;
int col = block_col + threadIdx.x * TN + local_col;
if (row < m && col < n) {
c[row * n + col] = acc[local_row][local_col];
}
}
}
}
// The tiled kernel of Chapter 17, for comparison: a block of T x T threads computes
// a T x T square of C in ceil(k / T) phases, with T x T tiles in shared memory.
template <int T>
__global__ void matmulTiled(int m, int n, int k, const float* a, const float* b, float* c)
{
__shared__ float tile_a[T][T];
__shared__ float tile_b[T][T];
int row = blockIdx.y * T + threadIdx.y;
int col = blockIdx.x * T + threadIdx.x;
float sum = 0.0f;
int phases = (k + T - 1) / T;
for (int phase = 0; phase < phases; ++phase) {
int a_col = phase * T + threadIdx.x;
int b_row = phase * T + threadIdx.y;
float a_value = row < m && a_col < k ? a[row * k + a_col] : 0.0f;
float b_value = b_row < k && col < n ? b[b_row * n + col] : 0.0f;
tile_a[threadIdx.y][threadIdx.x] = a_value;
tile_b[threadIdx.y][threadIdx.x] = b_value;
__syncthreads();
for (int offset = 0; offset < T; ++offset) {
sum += tile_a[threadIdx.y][offset] * tile_b[offset][threadIdx.x];
}
__syncthreads();
}
if (row < m && col < n) {
c[row * n + col] = sum;
}
}
// A product on the device: the 3 buffers and their sizes.
struct Product {
int m, n, k;
float *a, *b, *c;
};
template <int BM, int BN, int BK, int TM, int TN>
void launch(const Product& p)
{
dim3 grid((p.n + BN - 1) / BN, (p.m + BM - 1) / BM);
dim3 block(BN / TN, BM / TM);
matmulRegister<BM, BN, BK, TM, TN><<<grid, block>>>(p.m, p.n, p.k, p.a, p.b, p.c);
}
void launchTiled16(const Product& p)
{
dim3 grid((p.n + 15) / 16, (p.m + 15) / 16);
matmulTiled<16><<<grid, dim3(16, 16)>>>(p.m, p.n, p.k, p.a, p.b, p.c);
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// Average time of `runs` launches in milliseconds, after 1 launch that is not timed.
template <typename F>
double timeMs(F launch, int runs)
{
launch();
check(cudaDeviceSynchronize());
double start = nowMs();
for (int r = 0; r < runs; ++r) {
launch();
}
check(cudaGetLastError());
check(cudaDeviceSynchronize());
return (nowMs() - start) / runs;
}
// Integers in [-5, 5] from a small linear congruential generator: every partial sum
// of a product with k <= 4096 is an integer below 2^24, so float results are exact.
Matrix integers(size_t len, unsigned* state)
{
Matrix values(len);
for (size_t i = 0; i < len; ++i) {
*state = *state * 1664525u + 1013904223u;
values[i] = float(int((*state >> 8) % 11) - 5);
}
return values;
}
// The number of `samples` entries of C (all of them if C is smaller) that are exact.
int exactEntries(const Matrix& a, const Matrix& b, const Matrix& c,
int m, int n, int k, int samples)
{
int count = m * n < samples ? m * n : samples;
int exact = 0;
for (int sample = 0; sample < count; ++sample) {
int row = count == m * n ? sample / n : sample * 977 % m;
int col = count == m * n ? sample % n : (sample * 1231 + 7) % n;
double sum = 0.0;
for (int inner = 0; inner < k; ++inner) {
sum += double(a[row * k + inner]) * double(b[inner * n + col]);
}
exact += double(c[row * n + col]) == sum;
}
return exact;
}
// Host and device copies of A, B and C for an m x k by k x n product.
struct Problem {
Matrix a, b, c;
Product gpu;
};
Problem makeProblem(int m, int n, int k, unsigned seed)
{
Problem p;
p.a = integers(size_t(m) * k, &seed);
p.b = integers(size_t(k) * n, &seed);
p.c.resize(size_t(m) * n);
p.gpu = {m, n, k, nullptr, nullptr, nullptr};
check(cudaMalloc(&p.gpu.a, p.a.size() * sizeof(float)));
check(cudaMalloc(&p.gpu.b, p.b.size() * sizeof(float)));
check(cudaMalloc(&p.gpu.c, p.c.size() * sizeof(float)));
check(cudaMemcpy(p.gpu.a, p.a.data(), p.a.size() * 4, cudaMemcpyHostToDevice));
check(cudaMemcpy(p.gpu.b, p.b.data(), p.b.size() * 4, cudaMemcpyHostToDevice));
return p;
}
// Copy C back, free the device buffers, and count the exact entries.
int finish(Problem& p, int samples)
{
check(cudaMemcpy(p.c.data(), p.gpu.c, p.c.size() * 4, cudaMemcpyDeviceToHost));
check(cudaFree(p.gpu.a));
check(cudaFree(p.gpu.b));
check(cudaFree(p.gpu.c));
return exactEntries(p.a, p.b, p.c, p.gpu.m, p.gpu.n, p.gpu.k, samples);
}
// The 4 x 4 example: 1 block of 2 x 2 threads, each thread a 2 x 2 block of C.
bool runExample()
{
Matrix a{1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12, 13, 14, 15, 16};
Matrix b{1, 0, 2, 1, 0, 1, 1, 2, 2, 1, 0, 1, 1, 2, 1, 0};
Matrix want{11, 13, 8, 8, 27, 29, 24, 24, 43, 45, 40, 40, 59, 61, 56, 56};
Matrix c(16);
Product p = {4, 4, 4, nullptr, nullptr, nullptr};
check(cudaMalloc(&p.a, 64));
check(cudaMalloc(&p.b, 64));
check(cudaMalloc(&p.c, 64));
check(cudaMemcpy(p.a, a.data(), 64, cudaMemcpyHostToDevice));
check(cudaMemcpy(p.b, b.data(), 64, cudaMemcpyHostToDevice));
launch<4, 4, 2, 2, 2>(p);
check(cudaGetLastError());
check(cudaMemcpy(c.data(), p.c, 64, cudaMemcpyDeviceToHost));
check(cudaFree(p.a));
check(cudaFree(p.b));
check(cudaFree(p.c));
std::printf("C = A B on the 4 x 4 example, 1 block of 2 x 2 threads,");
std::printf(" 2 x 2 entries per thread\n");
for (int i = 0; i < 4; ++i) {
const float* row = &c[i * 4];
std::printf(" %4.0f %4.0f %4.0f %4.0f\n", row[0], row[1], row[2], row[3]);
}
bool same = c == want;
std::printf("equal to the product computed by hand: %s\n\n", same ? "yes" : "no");
return same;
}
// A shape that is not a multiple of any tile: every entry of C is checked.
bool runShape(int m, int n, int k)
{
Problem p = makeProblem(m, n, k, 7);
launch<64, 64, 16, 4, 4>(p.gpu);
check(cudaGetLastError());
int exact = finish(p, m * n);
std::printf(" m = %4d, k = %4d, n = %4d, 4 x 4 per thread:", m, k, n);
std::printf(" %7d of %7d entries exact\n\n", exact, m * n);
return exact == m * n;
}
// Time 1 kernel on n x n matrices and print 1 line of the table. The kernel computes
// bm x bn tiles of C, tm x tn entries per thread.
template <typename F>
bool runTimed(int n, const char* name, int bm, int bn, int tm, int tn, F launch)
{
Problem p = makeProblem(n, n, n, 1);
double cube = double(n) * n * n;
int runs = cube * 4 > 1e11 ? 2 : int(1e11 / (cube * 4)) + 2;
double ms = timeMs([&] { launch(p.gpu); }, runs < 50 ? runs : 50);
int exact = finish(p, 64);
double gflops = 2.0 * cube / ms / 1e6;
double reads = double(tm + tn) / (tm * tn);
double fetched = cube * (1.0 / bm + 1.0 / bn) * 4.0 / (1 << 20);
std::printf(" %5d %-9s %3d x %3d %9.3f %9.1f", n, name, bm, bn, ms, gflops);
std::printf(" %10.2f %12.1f %6d of 64\n", reads, fetched, exact);
return exact == 64;
}
template <int BM, int BN, int BK, int TM, int TN>
bool runConfig(int n, const char* name)
{
return runTimed(n, name, BM, BN, TM, TN, launch<BM, BN, BK, TM, TN>);
}
// About 0.5 s of 1024 x 1024 products: the GPU raises its clocks under sustained load.
void warmUp()
{
Problem p = makeProblem(1024, 1024, 1024, 1);
double start = nowMs();
while (nowMs() - start < 500.0) {
launch<64, 64, 16, 4, 4>(p.gpu);
check(cudaDeviceSynchronize());
}
finish(p, 1);
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %d SMs\n\n", prop.name, prop.multiProcessorCount);
bool passed = runExample();
passed &= runShape(1000, 1000, 1000);
warmUp();
std::printf("C = A B, n x n, 256 threads per block\n");
std::printf(" n thread block ms GFLOP/s");
std::printf(" reads/FMA fetched MiB exact\n");
for (int n : {1024, 2048, 4096}) {
passed &= runTimed(n, "Ch. 17", 16, 16, 1, 1, launchTiled16);
passed &= runConfig<16, 16, 16, 1, 1>(n, "1 x 1");
passed &= runConfig<32, 16, 16, 2, 1>(n, "2 x 1");
passed &= runConfig<32, 32, 16, 2, 2>(n, "2 x 2");
passed &= runConfig<64, 64, 16, 4, 4>(n, "4 x 4");
passed &= runConfig<128, 128, 8, 8, 8>(n, "8 x 8");
}
std::printf("%s\n", passed ? "PASSED" : "FAILED");
return passed ? 0 : 1;
}
To build and run the Rust program, we use cargo oxide run in its directory, and for the C++
program,
nvcc -O3 -arch=native matmul_register_tiled.cu -o matmul_register_tiled && ./matmul_register_tiled.
Common mistakes
- Loops that are not unrolled. If the loops over the register tile are not unrolled,
accmoves to local memory, and every multiply-add becomes a load and a store. In cuda-oxide, these loops must bewhileloops with#[unroll]. - Too large a register tile. 64 sums per thread need more than 100 registers, so fewer blocks fit on an SM; on the measured GPU, the 8 × 8 tile ran slower than the 4 × 4 tile.
- A block shape that does not match the constants. The copy loop assumes exactly \((B_M/T_M)(B_N/T_N)\) threads, so the block shape should be derived from the constants in 1 function.
- Copy loops with a run-time count. A copy loop whose count the compiler cannot see is not unrolled, and the loads of a phase wait one after another.
- Forgetting the padding of tileA. Without it, the threads of a warp read tileA in the same bank, and the reads are served one after another.
- Partial thread tiles in Rust.
tile_2d32_rtwrites only whole tiles, so a matrix size that is not a multiple of the thread tile must be refused or padded.
Summary
- Each multiply-add of the tiled kernel reads 2 values from shared memory, which limits it to 1/8 of the arithmetic peak.
- A thread that computes a \(T_M \times T_N\) block of \(C\) reads \(T_M\) values of \(A\) and \(T_N\) values of \(B\) per step and adds their outer product to its sums. In the example, 4 outer products give \(\begin{pmatrix} 11 & 13 \\ 27 & 29 \end{pmatrix}\).
- The reads per multiply-add fall to \((T_M + T_N)/(T_M T_N)\): 1.5, 1, 0.5 and 0.25 for 2 × 1, 2 × 2, 4 × 4 and 8 × 8. The sums live in registers, the third level of storage.
- A block computes a \(B_M \times B_N\) part of \(C\) in phases of \(B_K\) terms, and it fetches \(MNK(1/B_M + 1/B_N)\) values from global memory.
- The proof of Chapter 17 carries over, with the invariant written for every sum; the block must have exactly the number of threads that the copy assumes.
- The 5 sizes are template parameters in C++ and const generic parameters in Rust, and every loop
over the register tile is unrolled. In Rust,
RuntimeRowMajorTileslets each thread write its whole tile withoutunsafe. - On the measured GPU, the rate followed the shared-memory limit up to the 2 × 2 tile (583.5 of 600 GFLOP/s). The 4 × 4 tile reached 1,009.9 GFLOP/s in C++ and 875.5 GFLOP/s in Rust, 3.7 and 3.2 times the rate of the tiled kernel. The 8 × 8 tile was slower in both languages, because its registers leave few blocks on each SM (1 in C++).
In Chapter 19, we turn to stencil computations, in which each output depends on a small neighborhood of the input, and we apply the same staging in shared memory to a grid with borders.
Exercises
- Compute, for the example with \(T_M = T_N = 2\), the number of reads from shared memory and the number of multiply-adds of the whole kernel, and compare with the tiled kernel of Chapter 17.
- For \(B_M = B_N = 64\), \(B_K = 16\), \(T_M = T_N = 4\) and \(n = 4{,}096\), compute the bytes fetched from global memory and the FLOP per float fetched.
- Extend both programs with a 4 × 8 thread tile (\(B_M = 64\), \(B_N = 128\), \(B_K = 8\)). Predict its reads per multiply-add and its shared-memory limit, and measure it.
- Store tileA transposed, as \(B_K \times B_M\), so that line 19 reads \(T_M\) consecutive values. Which loads into shared memory now conflict, and is the kernel faster?
- Replace the Rust store through
RuntimeRowMajorTilesbyget_unchecked_mutas in Chapter 9, and write theSAFETYcomment that the new code needs. - With the register counts of Section 18.7.2, compute the occupancy of each configuration on an SM that holds 1,536 threads and 65,536 registers.
- The 8 × 8 configuration uses \(B_K = 8\). Predict the effect of \(B_K = 16\) on shared memory per block and on the number of barriers, and measure it.
Sources and further reading
- A. Pathak, An Introduction to Tiled Parallel Programming, Simplified, 2026: the tiled kernel and its Exercise 7.2, from which we start in this chapter.
- V. Volkov and J. Demmel, “Benchmarking GPUs to Tune Dense Linear Algebra”, SC08, 2008: register blocking of matrix products on GPUs.
- S. Boehm, “How to Optimize a CUDA Matmul Kernel for cuBLAS-like Performance”, 2022.
- NVIDIA, CUDA C++ Programming Guide, “Shared Memory” (banks) and
#pragma unroll: https://docs.nvidia.com/cuda/cuda-c-programming-guide/ - cuda-oxide, rev b7fe543,
crates/cuda-device/src/view.rs:RuntimeRowMajorTiles,tile_2d32_rtandLocalIndex32;crates/cuda-device/src/thread.rs:coord_2d_u32. - Chapter 9 of this book, for the 4 × 4 patch kernel in C++ and Rust, occupancy and
__launch_bounds__, and the comparison with cuBLAS.
Stencils
A stencil computation updates every cell of a grid from a fixed pattern of its neighbors. The temperature of a heated plate, the potential between charged conductors, the blur of an image and the step of a fluid simulation are all stencil computations. In the next 2 chapters, we study the most common one, the 5-point stencil of the Laplace equation, iterated with Jacobi’s method. We use a single plate of 6 × 6 cells throughout, so that every value can be checked by hand.
The idea that connects the 2 chapters is the separation of old values from new ones. Every update of a Jacobi step reads only values of the previous step. All updates of a step are therefore independent of one another, and a GPU may run them at the same time, but only if no update overwrites a value that another update still has to read. In Chapter 19, we enforce this separation between steps with 2 buffers in global memory. In Chapter 20, we enforce it within a block with a tile in shared memory and a barrier, and, for temporal blocking, with 2 tiles used in turn.
In Chapter 19, Stencils and Jacobi Iteration, we derive the 5-point stencil from the Laplace
equation, work 2 Jacobi steps by hand, show the exact wrong value that an update in place
produces, and prove with a loop invariant that 2 buffers used in turn compute Jacobi iteration. We
then write the kernel with 1 thread per cell, in Rust with DisjointSlice and in C++ with
__restrict__, measure how fast the iteration converges, and show from its arithmetic intensity
why the step is limited by memory bandwidth.
In Chapter 20, Tiled Stencils with Halo Cells, we count how often the direct kernel reads each value, define the tile and its halo, compare 2 ways of loading the halo, and show the wrong values that appear without the barrier and without the halo. We then count the loads per result as a function of the tile size, measure why the tile gains little on GPUs whose caches already capture the reuse, and measure temporal blocking, which performs several steps on each tile.
In both chapters, we build on Chapter 7 for sectors, coalescing and shared memory, and on Chapter 5 for barriers and race conditions. We also apply the method of the tiled matrix product of Chapters 9 and 17, which stages data in shared memory, to a computation with far less reuse per value.
Chapter 19: Stencils and Jacobi Iteration
The temperature inside a heated plate, the electric potential between charged conductors and the pressure of a fluid at rest are all described by the same partial differential equation, the Laplace equation. A computer solves this equation on a grid of points. The value at each point is computed again and again from the values of its 4 neighbors, until the values stop changing. A computation in which every point of a grid is updated from a fixed pattern of neighbors is called a stencil computation. Stencils are among the most common workloads of a GPU, because all points of a grid can be updated at the same time.
In this chapter, we derive the parallel algorithm for 1 stencil, the 5-point stencil of the Laplace equation, together with its standard solver, Jacobi iteration. We work on a single 6 × 6 plate from the first section to the last. We first compute its steps by hand and show why an update in place produces a different answer. We then prove that 2 buffers used in turn compute Jacobi iteration exactly, and we count the memory traffic that determines the speed of the kernel. Both implementations, in Rust and in CUDA C++, check themselves against the values that we work out by hand.
This chapter covers
- the Laplace equation on a grid, and the 5-point stencil derived from it
- Jacobi iteration, worked by hand on a 6 × 6 plate
- why an update in place computes a different method, and the exact wrong value it produces
- Two buffers used in turn, and a proof that they compute Jacobi iteration
- One thread per cell, in Rust with
DisjointSliceand in C++ with__restrict__ - how fast the iteration converges, measured and predicted
- arithmetic intensity, and why a stencil is limited by memory bandwidth
The code of the chapter is in
code/oxide/ch19_stencil/
for Rust and in
code/cuda/ch19_stencil/
for C++.
19.1 The problem
19.1.1 A heated plate
We use the same example throughout the chapter. It is a square plate whose 4 edges are held at fixed temperatures, the top edge at 100 degrees and the other 3 edges at 0 degrees. Heat flows into the plate through the hot edge and out of it through the cold ones. After enough time, the temperature at every point stops changing, and we want to know this final temperature at every point of the plate.
A computer cannot store a temperature for each of the infinitely many points of the plate, so we replace the plate by a grid of 6 × 6 cells and keep 1 temperature per cell. The rows and the columns are numbered from 0 to 5, as shown in Figure 19.1. The cells on the edge of the grid have known temperatures, and the 16 cells inside them are the unknowns that we want to compute.
Definition 19.1 Grid, boundary cell, interior cell. A grid of \(W \times H\) cells holds one value per cell; cell \((r, c)\) lies in row \(r \in [0, H)\) and column \(c \in [0, W)\). A boundary cell lies in the first or last row or column; its value is given by the problem and never changes. Every other cell is an interior cell, and its value is unknown.
Example. Our plate has \(W = H = 6\): 36 cells, of which 20 are boundary cells and \(4 \times 4 = 16\) are interior cells, in rows 1 to 4 and columns 1 to 4.
Here \(W\) is the width of the grid, that is, the number of cells in a row, and \(H\) is its height, the number of cells in a column. As in the earlier chapters, \([a, b)\) denotes the integers from \(a\) to \(b - 1\), so \(r \in [0, 6)\) means that the row number \(r\) is one of 0, 1, 2, 3, 4 and 5.
The grid is stored in row-major order: the 6 cells of row 0 come first, followed by the 6 cells of row 1, then those of row 2, until row 5 ends the array. Before cell \((r, c)\) there are \(r\) complete rows of \(W\) cells each, followed by \(c\) cells of its own row, so cell \((r, c)\) is element \(rW + c\) of the array. For example, cell (2, 3) of our plate is element \(2 \cdot 6 + 3 = 15\). It follows that the 2 neighbors of a cell in the same row are 1 element away from it, at elements 14 and 16 in this example, while the 2 neighbors in the same column are \(W\) elements away, at elements \(15 - 6 = 9\) and \(15 + 6 = 21\).
19.1.2 The rule for the final temperature
Physics gives a simple rule that the final temperatures obey. At every interior cell, the temperature is the mean of the temperatures of its 4 neighbors:
\[ u_{r,c} = \frac{1}{4} \left( u_{r-1,c} + u_{r+1,c} + u_{r,c-1} + u_{r,c+1} \right). \]
| Symbol | Meaning | In the example, cell (1, 1) |
|---|---|---|
| \(u_{r,c}\) | final temperature of the cell in row \(r\), column \(c\) | \(u_{1,1} = 45.45\) |
| \(u_{r-1,c}\), \(u_{r+1,c}\) | temperatures of the cells above and below | 100 and 22.35 |
| \(u_{r,c-1}\), \(u_{r,c+1}\) | temperatures of the cells to the left and right | 0 and 59.47 |
| \(\frac{1}{4}\) | weight of each neighbor; 4 weights of 1/4 form a mean | 0.25 |
The reason for the rule is that heat flows from warm to cold. If a cell were warmer than the mean of its neighbors, it would lose more heat to them than it receives, and its temperature would still be falling. If it were colder, it would still be rising. Only when every cell equals the mean of its neighbors does the temperature stop changing. We can check the rule on the answer. In Section 19.2, we compute the final temperatures of our plate, and there cell (1, 1) holds 45.45, while its neighbors hold 100 above, 22.35 below, 0 to the left and 59.47 to the right. Their mean is \((100 + 22.35 + 0 + 59.47) / 4 = 181.82 / 4 = 45.45\), which is the value of the cell itself, as Figure 19.2 shows.
The rule is the discrete form of the Laplace equation. Let \(u(x, y)\) denote the temperature at the point \((x, y)\) of the plate. The Laplace equation states that the sum of the second derivatives of \(u\) along \(x\) and along \(y\) is 0 at every point inside the plate:
\[ \frac{\partial^2 u}{\partial x^2} + \frac{\partial^2 u}{\partial y^2} = 0. \]
| Symbol | Meaning | On the grid |
|---|---|---|
| \(u(x, y)\) | temperature at the point \((x, y)\) | \(u_{r,c}\), with \(x\) along the columns and \(y\) along the rows |
| \(\partial^2 u / \partial x^2\) | second derivative of \(u\) along \(x\): how fast the slope changes from left to right | a difference of the cells left and right |
| \(\partial^2 u / \partial y^2\) | the same along \(y\), from top to bottom | a difference of the cells above and below |
A grid has no derivatives, only values at cells, so we approximate each second derivative by a difference of neighboring values. Let \(h\) be the spacing between the centers of 2 neighboring cells. The second derivative along \(x\) at cell \((r, c)\) is approximated by the finite difference
\[ \frac{\partial^2 u}{\partial x^2} \approx \frac{u_{r,c+1} - 2u_{r,c} + u_{r,c-1}}{h^2}, \]
and the second derivative along \(y\) by the same expression with the cells above and below. The numerator compares the cell with its 2 neighbors in the row. It is 0 when the 3 values lie on a straight line, and it measures how far they bend away from one when they do not. We can test the approximation on a function whose second derivative we know. For \(f(x) = x^2\), whose second derivative is 2 everywhere, the difference at \(x = 1\) with \(h = 1\) uses \(f(2) = 4\), \(f(1) = 1\) and \(f(0) = 0\), and gives \((4 - 2 \cdot 1 + 0) / 1^2 = 2\), which is exact.
Substituting both differences into the Laplace equation gives
\[ \frac{u_{r,c+1} - 2u_{r,c} + u_{r,c-1}}{h^2} + \frac{u_{r+1,c} - 2u_{r,c} + u_{r-1,c}}{h^2} = 0. \]
Multiplying by \(h^2\) removes the spacing, and moving the 4 terms \(-2u_{r,c}\) to the right gives \(u_{r-1,c} + u_{r+1,c} + u_{r,c-1} + u_{r,c+1} = 4u_{r,c}\). Dividing by 4 gives the rule above. Note that the spacing \(h\) has canceled, so the rule is the same however finely we cut the plate.
Definition 19.2 Stencil. A stencil is a fixed pattern of neighbors, with a weight for each, from which a new value of a cell is computed. A stencil computation applies the same stencil to every interior cell of a grid. The 5-point stencil uses a cell and its 4 neighbors in the same row and column, with weight 1/4 on each neighbor and 0 on the cell itself.
Example. Applied to cell (1, 1) of the final plate, the 5-point stencil gives 45.45 (Figure 19.2).
The rule gives 1 equation for each of the 16 interior cells, and each equation contains up to 4 unknowns. For cell (1, 1), whose upper and left neighbors are boundary cells with the known values 100 and 0, the equation reads \(u_{1,1} = (100 + u_{2,1} + 0 + u_{1,2}) / 4\). A system of 16 equations can be solved by elimination, as in a first course in linear algebra. A grid of 4096 × 4096 cells, however, has 16.7 million interior cells, and elimination on a system of that size needs far more memory and time than the iterative method of the next section.
Exercises
19.1 Write the equation of the rule for cell (2, 3) of the plate. Which of its neighbors are
boundary cells?
19.2 At which element of the array is cell (4, 1) stored, in row-major order with \(W = 6\)?
19.3 Apply the finite difference to \(f(x) = x^3\) at \(x = 1\) with \(h = 1\) and with
\(h = 0.5\), and compare both with the exact second derivative, 6.
19.2 The sequential algorithm
19.2.1 Jacobi iteration
We do not know the final temperatures, but we do know a property that they have. Each interior value is the mean of its neighbors. Jacobi iteration turns this property into a procedure. It starts from a guess and replaces every interior value by the mean of its neighbors, again and again. If the guess is wrong, the replacement moves each value toward the mean of its neighbors, and after many repetitions the values settle at the point where the replacement no longer changes them, which is exactly the final state.
Definition 19.3 Jacobi iteration. Let \(u^{(0)}\) be a grid whose boundary cells hold the given values and whose interior cells hold a guess. Jacobi iteration computes the grids \(u^{(1)}, u^{(2)}, \ldots\), where each step keeps the boundary cells and sets every interior cell to
\[ u^{(k+1)}_{r,c} = \frac{1}{4} \left( u^{(k)}_{r-1,c} + u^{(k)}_{r+1,c} + u^{(k)}_{r,c-1} + u^{(k)}_{r,c+1} \right). \]
The right-hand side uses only values of step \(k\).
Example. We start from 0 in every interior cell. After step 1, the 4 cells of row 1 hold 25; all other interior cells still hold 0.
The superscript in parentheses is the number of the step, not a power. Thus \(u^{(0)}\) is the starting grid, \(u^{(1)}\) the grid after 1 step, and \(u^{(k)}_{r,c}\) the value of cell \((r, c)\) after \(k\) steps.
| Symbol | Meaning | In the example |
|---|---|---|
| \(k\) | number of steps already performed | \(k = 0\) when step 1 is computed |
| \(u^{(k)}\) | grid after \(k\) steps; the old grid that the step reads | \(u^{(0)}\): 100 on top, 0 inside |
| \(u^{(k+1)}_{r,c}\) | new value of cell \((r, c)\), written by the step | \(u^{(1)}_{1,1} = 25\) |
| \(u^{(k)}_{r-1,c}\) | old value of the cell above | \(u^{(0)}_{0,1} = 100\) |
The method is named after Carl Gustav Jacob Jacobi. Let us carry out its first 2 steps by hand, starting from 0 in every interior cell. Before step 1, each of the 4 cells of row 1 has the hot boundary cell above it and 3 neighbors at 0, so it becomes \((100 + 0 + 0 + 0) / 4 = 25\). Each cell of rows 2 to 4 has only neighbors at 0, and it stays at 0.
In step 2, every cell again reads the values that the grid held before the step, which are now the values of step 1. Cell (1, 1) has 100 above it, 0 below, 0 to its left and 25 to its right, so it becomes \(125 / 4 = 31.25\). Cell (1, 2) has 25 on both sides and becomes \((100 + 0 + 25 + 25) / 4 = 37.5\). Each cell of row 2 has 25 above it and 0 elsewhere, so it becomes \(25 / 4 = 6.25\). After 2 steps, heat has therefore moved 2 rows into the plate, 1 row per step, because a cell learns only about its direct neighbors in each step. Figure 19.3 shows the 2 steps, together with the plate after 100 steps, when the values agree with the final temperatures to 2 decimal places.
19.2.2 The algorithm
We now write 1 step as a procedure that reads the grid \(u\) and writes the grid \(v\), and the iteration as a loop around that procedure. We write algorithms in the style of Cormen, Leiserson, Rivest and Stein, with procedure names in small capitals, numbered lines, and the half-open range \([a, b)\) for the integers \(a, a + 1, \ldots, b - 1\). In both procedures, \(u\) is the old grid, \(v\) is the new grid, \(W\) and \(H\) are the width and height of Definition 19.1, and \(K\) is the number of steps to perform.
Jacobi-Step(\(u, v, W, H\))
- for \(\mathsf{row} \in [1, H - 1)\) {
- for \(\mathsf{col} \in [1, W - 1)\) {
- \(v_{\mathsf{row},\mathsf{col}} = (u_{\mathsf{row}-1,\mathsf{col}} + u_{\mathsf{row}+1,\mathsf{col}} + u_{\mathsf{row},\mathsf{col}-1} + u_{\mathsf{row},\mathsf{col}+1}) / 4\)
- }
- }
Jacobi(\(u, W, H, K\))
- \(v = u\) // both grids hold the boundary
- for \(\mathsf{step} \in [0, K)\) {
- Jacobi-Step(\(u, v, W, H\))
- exchange the names \(u\) and \(v\) // u is the newest grid
- }
- return \(u\)
Lines 1 and 2 of Jacobi-Step visit the interior cells only. On our plate, \(\mathsf{row}\) and \(\mathsf{col}\) run over \([1, 5)\), that is, over 1, 2, 3 and 4, so the boundary cells of \(v\) are never written. For this reason, line 1 of Jacobi copies the whole starting grid into \(v\), so that \(v\) holds the boundary values as well. Line 4 exchanges the names after each step, so that the grid written last becomes the grid that the next step reads. After step 1, for example, the name \(u\) refers to the grid that holds 25 in row 1, and step 2 reads that grid.
19.2.3 Counting the work
Line 3 of Jacobi-Step executes once for each interior cell. There are \(W - 2\) interior cells in a row and \(H - 2\) in a column, so line 3 executes \((W - 2)(H - 2)\) times per step, which is \(4 \cdot 4 = 16\) times on our plate. Each execution reads 4 values, performs 3 additions and 1 multiplication by 1/4, which are 4 floating-point operations, and writes 1 value. On our plate, a step therefore performs 16 updates, with 64 reads, 64 operations and 16 writes. On a grid of 4096 × 4096 cells, a step performs 16.7 million updates, and in Section 19.7, we will see that such a grid needs millions of steps. A CPU performs these updates one after another. In the next section, we ask which of them may run at the same time.
Exercises
19.4 Carry out step 3 of the plate by hand, starting from the values of step 2 in Figure 19.3.
19.5 How many reads, writes and floating-point operations does Jacobi perform for \(K = 100\)
steps on the plate?
19.6 Why does line 1 of Jacobi copy the whole grid and not only the boundary?
19.3 Updating in place
19.3.1 1 grid in place of 2
Jacobi keeps 2 grids, which doubles the memory it needs. A natural question is whether 1 grid would be enough, with line 3 writing the new value of a cell into the same grid that it reads from. Let us run step 1 in this way on our plate, visiting the cells row by row, in the order of the loops of Jacobi-Step.
Cell (1, 1) is visited first and becomes \((100 + 0 + 0 + 0) / 4 = 25\), as before. Cell (1, 2) is visited next. Its left neighbor is cell (1, 1), which now holds the new value 25 rather than the old value 0, so cell (1, 2) becomes \((100 + 0 + 25 + 0) / 4 = 31.25\) instead of 25. The error then spreads to later cells. Cell (1, 3) reads 31.25 on its left and becomes 32.81, and cell (2, 1), whose upper neighbor already holds 25, becomes 6.25 instead of 0, as shown in Figure 19.4.
On a CPU, the update in place gives another well-defined method, called Gauss-Seidel iteration, which also converges. On a GPU, however, it gives no well-defined method at all, because the cells are updated by different threads. The thread of cell (1, 2) may read its left neighbor before or after the thread of cell (1, 1) writes it, and the order is decided by how the hardware schedules the 2 threads. The result can be 25, 31.25, or a mixture of both across the grid, and it can change from run to run. We run this variant in Section 19.5.
19.3.2 Which updates are independent
Recall the formula of Definition 19.3. Its right-hand side uses only values of step \(k\), and its left-hand side writes only values of step \(k + 1\). No update of a step therefore uses the result of another update of the same step. In step 2 of our plate, for example, cell (1, 2) needs the value of cell (1, 1) after step 1, which is 25, and not the value 31.25 that cell (1, 1) receives in step 2.
Key observation The 16 updates of a Jacobi step read only the grid of the previous step, so no update depends on another and all 16 can run at the same time, provided that no update overwrites a value of the previous step that another update still has to read.
The condition at the end of the observation is met by keeping the 2 grids of Jacobi apart. Every update reads from one grid and writes into the other, and the next step exchanges their roles. This arrangement has a name.
Definition 19.4 Ping-pong buffers. Ping-pong buffering keeps 2 buffers of the same size. Each step reads 1 buffer and writes the other, and after each step the 2 exchange roles, so that the buffer written last is the one read next.
Example. Step 1 of the plate reads buffer \(\mathsf{current}\) and writes buffer \(\mathsf{next}\); step 2 reads \(\mathsf{next}\) and writes \(\mathsf{current}\); step 3 reads \(\mathsf{current}\) again.
Exercises
19.7 Finish step 1 in place for row 1 and row 2 of the plate, visiting the cells row by row. Which
of the 16 values differ from Jacobi’s?
19.8 Suppose the cells of a step in place were visited column by column instead. Which value would
cell (1, 2) receive in step 1?
19.4 The parallel algorithm
19.4.1 Threads and blocks
A GPU runs 1 function many times at once. The terms below were introduced in Chapters 3 and 13. We restate them here because we use them throughout the rest of the chapter.
Definition 19.5 Kernel, thread, block, grid of blocks, warp. A kernel is a function that the GPU runs many times at once; each run is a thread, with its own position and its own variables. Threads are grouped into blocks of up to 1,024 threads that run on the same streaming multiprocessor (SM), share a fast on-chip memory and can wait for one another. The blocks of 1 launch form a grid of blocks. The SM issues instructions for 32 threads of a block at a time; such a group is a warp.
Example. For the plate, the program launches 1 block of 32 × 8 threads. Its 256 threads form 8 warps, 1 per row of the block.
The word “grid” now has 2 meanings, the grid of cells and the grid of blocks. In the rest of the chapter, we say “grid” for the cells and “the blocks of a launch” for the other meaning.
We give each cell its own thread. A thread finds its cell from 3 values that the GPU supplies: the position of its block among the blocks of the launch (\(\mathsf{blockIdx}\)), its position inside the block (\(\mathsf{threadIdx}\)), and the size of a block (\(\mathsf{blockDim}\)). We use blocks of 32 × 8 threads, so \(\mathsf{blockDim{.}x} = 32\) and \(\mathsf{blockDim{.}y} = 8\) that is, 32 threads along a row and 8 rows of threads. The thread at position (\(\mathsf{threadIdx{.}x}\), \(\mathsf{threadIdx{.}y}\)) of block (\(\mathsf{blockIdx{.}x}\), \(\mathsf{blockIdx{.}y}\)) then owns the cell
\[ \mathsf{row} = \mathsf{blockIdx{.}y} \cdot \mathsf{blockDim{.}y} + \mathsf{threadIdx{.}y}, \qquad \mathsf{col} = \mathsf{blockIdx{.}x} \cdot \mathsf{blockDim{.}x} + \mathsf{threadIdx{.}x}. \]
| Symbol | Meaning | Example: thread (4, 2) of block (1, 0) |
|---|---|---|
| \(\mathsf{blockDim{.}x}, \mathsf{blockDim{.}y}\) | width and height of a block in threads | 32, 8 |
| \(\mathsf{blockIdx{.}x}\), \(\mathsf{blockIdx{.}y}\) | column and row of the block among the blocks | 1, 0 |
| \(\mathsf{threadIdx{.}x}\), \(\mathsf{threadIdx{.}y}\) | column and row of the thread inside its block | 4, 2 |
| \(\mathsf{row}\) | row of the cell the thread owns | \(0 \cdot 8 + 2 = 2\) |
| \(\mathsf{col}\) | column of the cell the thread owns | \(1 \cdot 32 + 4 = 36\) |
The formula has a simple reading. Along a row, the blocks to the left of block \(\mathsf{blockIdx{.}x}\) cover \(\mathsf{blockIdx{.}x} \cdot \mathsf{blockDim{.}x}\) columns, and the thread lies \(\mathsf{threadIdx{.}x}\) columns further on. In the example of the table, block 1 has 1 block of 32 columns to its left, so its thread 4 owns column 36. The rows are counted in the same way.
A grid of \(W \times H\) cells needs \(\lceil W / \mathsf{blockDim{.}x} \rceil \times \lceil H / \mathsf{blockDim{.}y} \rceil\) blocks, where \(\lceil x \rceil\) denotes \(x\) rounded up to the next integer, so that a partly filled block at the edge is still counted. A grid of 4096 × 4096 cells needs \(4096 / 32 = 128\) blocks along a row and \(4096 / 8 = 512\) along a column. For the plate, \(\lceil 6 / 32 \rceil = \lceil 6 / 8 \rceil = 1\), so 1 block suffices. The threads of that block with \(\mathsf{col} \ge 6\) or \(\mathsf{row} \ge 6\) have no cell, and of the 36 threads that do have a cell, the 20 on the boundary have nothing to compute.
We choose blocks that are 32 threads wide because the 32 threads of a warp then lie along 1 row of the grid. When they read their neighbors, they read 32 neighboring values, 128 bytes, at the same time, and the hardware can serve such a read efficiently.
Definition 19.6 Coalesced access. Global memory moves data in sectors of 32 bytes (Chapter 7). A warp’s access is coalesced when its 32 threads read neighboring addresses, so that the 32 values arrive in as few sectors as possible.
Example. A warp reading 32 neighboring floats of a row, 128 bytes, needs 4 sectors when the row segment starts at a multiple of 32 bytes. A warp reading 32 floats of a column needs 32 sectors.
19.4.2 The kernel
Every thread executes the following procedure. The 2 grids \(u\) and \(v\) are 2 different buffers in global memory, the large memory of the GPU that every thread can read and write.
Jacobi-Kernel(\(u, v, W, H\))
- \(\mathsf{row} = \mathsf{blockIdx{.}y} \cdot \mathsf{blockDim{.}y} + \mathsf{threadIdx{.}y}\)
- \(\mathsf{col} = \mathsf{blockIdx{.}x} \cdot \mathsf{blockDim{.}x} + \mathsf{threadIdx{.}x}\)
- if \(\mathsf{row} \in [1, H - 1)\) and \(\mathsf{col} \in [1, W - 1)\) { // interior cells only
- \(v_{\mathsf{row},\mathsf{col}} = (u_{\mathsf{row}-1,\mathsf{col}} + u_{\mathsf{row}+1,\mathsf{col}} + u_{\mathsf{row},\mathsf{col}-1} + u_{\mathsf{row},\mathsf{col}+1}) / 4\)
- }
Jacobi-GPU(\(u, W, H, K\))
- copy \(u\) into 2 device buffers \(\mathsf{current}\) and \(\mathsf{next}\) // both hold the boundary
- for \(\mathsf{step} \in [0, K)\) {
- launch Jacobi-Kernel(\(\mathsf{current}, \mathsf{next}, W, H\)) on \(\lceil W/\mathsf{blockDim{.}x} \rceil \times \lceil H/\mathsf{blockDim{.}y} \rceil\) blocks
- exchange the names \(\mathsf{current}\) and \(\mathsf{next}\)
- }
- copy \(\mathsf{current}\) to the host
Jacobi-Kernel is the body of Jacobi-Step with its 2 loops removed. The position of the thread, computed in lines 1 and 2, plays the role of the loop variables \(\mathsf{row}\) and \(\mathsf{col}\). Line 3 lets only the threads of interior cells continue, and line 4 is line 3 of Jacobi-Step. Jacobi-GPU is Jacobi with the call of Jacobi-Step replaced by a launch of the kernel, and \(\mathsf{current}\) and \(\mathsf{next}\) are the 2 buffers on the device. Launches issued one after another on the same stream run in that order, so each launch starts only after every thread of the previous launch has written its value. The loop of the CPU is thus replaced by threads within a step, while the steps themselves still run one after another.
19.4.3 The work of 1 thread
Figure 19.5 follows the thread of cell (2, 2) through step 2. The thread reads 4 values from buffer \(\mathsf{current}\), which holds the grid after step 1, namely 25 above, 0 below, 0 to the left and 0 to the right. It then writes \(25 / 4 = 6.25\) into cell (2, 2) of buffer \(\mathsf{next}\). In total, the thread makes 4 reads from global memory and 1 write, and none of the values that it reads was written in the same step.
Over the whole step, the 16 interior threads of the plate read 64 values and write 16. A grid of 4096 × 4096 cells has 16.7 million interior threads per step, which read 67 million values, or 268 MB, and write 16.7 million values, or 67 MB. In Section 19.8, we will see that most of those reads never reach the memory chips.
Exercises
19.9 Which cell does thread (5, 3) of block (2, 1) own with blocks of 32 × 8 threads?
19.10 How many blocks of 32 × 8 threads cover a grid of 1000 × 1000 cells, and how many of their
threads have no cell?
19.11 Follow the thread of cell (1, 2) through step 2, as Figure 19.5 does for cell (2, 2).
19.5 Correctness
The kernel is correct only if the buffers are used as Jacobi-GPU prescribes. In this section, we break the prescription in two ways and run each broken variant. We then prove that the correct program computes Jacobi iteration exactly.
19.5.1 1 buffer for both arguments
Suppose that we launch the kernel with the same buffer as \(u\) and as \(v\). This is the
update in place of Section 19.3. In C++, the launch
jacobi<<<blocks, block>>>(current, current, width, height)
compiles without a warning. We ran it for 10 steps on the 4096 × 4096 plate, 3 times, and compared
each result with the result of 10 correct steps. The program printed the following counts.
in place, 4096 x 4096, run 1: 28420 of 16777216 cells differ from Jacobi after 10 steps
in place, 4096 x 4096, run 2: 28330 of 16777216 cells differ from Jacobi after 10 steps
in place, 4096 x 4096, run 3: 28464 of 16777216 cells differ from Jacobi after 10 steps
The number of wrong cells changes from run to run, as we predicted in Section 19.3. On the 6 × 6 plate, the same launch printed the correct values of Figure 19.3. There, all 36 cells belong to 1 block, and in our runs every thread of the block read its neighbors before any of them wrote. Nothing in the hardware guarantees that order, however. A test on a small grid therefore cannot show the error. The error appears where 1 block reads cells that another block, running earlier or later, writes.
In Rust, the same mistake does not compile. The kernel takes the old grid as &[f32] and the new
one as a DisjointSlice, which the launch builds from a &mut borrow of a buffer. Passing the
same buffer as both arguments borrows it as shared and as mutable at the same time, which the
borrow checker rejects with the following message.
error[E0502]: cannot borrow `current` as mutable because it is also borrowed as immutable
--> src/main.rs:154:64
|
154 | module.jacobi(&stream, &small, ¤t, RowWidth::new(&mut current, width as u32))?;
| ------ -------- ^^^^^^^^^^^^ mutable borrow occurs here
| | |
| | immutable borrow occurs here
| immutable borrow later used by call
19.5.2 A buffer without the boundary
The compiler can check that the 2 arguments are different buffers, but it cannot check what a buffer holds. Suppose that line 1 of Jacobi-GPU copies the plate into \(\mathsf{current}\) only, and that \(\mathsf{next}\) is created filled with 0. The kernel never writes a boundary cell, so the top row of \(\mathsf{next}\) stays at 0. Step 1 is unaffected, because it reads \(\mathsf{current}\). Step 2, however, reads \(\mathsf{next}\), whose top edge is cold, and cell (1, 1) becomes \((0 + 0 + 0 + 25) / 4 = 6.25\) instead of 31.25, as shown in Figure 19.6. We ran this variant, and it printed the following grids.
zeroed second buffer, after step 2
100.00 100.00 100.00 100.00 100.00 100.00
0.00 6.25 12.50 12.50 6.25 0.00
0.00 6.25 6.25 6.25 6.25 0.00
0.00 0.00 0.00 0.00 0.00 0.00
0.00 0.00 0.00 0.00 0.00 0.00
0.00 0.00 0.00 0.00 0.00 0.00
zeroed second buffer, after step 200
100.00 100.00 100.00 100.00 100.00 100.00
0.00 11.55 21.76 21.76 11.55 0.00
0.00 13.88 17.55 17.55 13.88 0.00
0.00 4.79 8.45 8.45 4.79 0.00
0.00 2.45 3.58 3.58 2.45 0.00
0.00 0.00 0.00 0.00 0.00 0.00
The grid printed after step 2 shows 100 in its top row. The program printed buffer \(\mathsf{current}\), which holds the boundary, while the step itself had read the cold top row of \(\mathsf{next}\). The iteration still converges, but to the answer of a different problem, in which the top edge is hot only in every second step. After 200 steps, cell (2, 2) holds 17.55, whereas the correct value is 32.95. No error is reported, and only a comparison with known values exposes the mistake.
19.5.3 A proof of correctness
We can now prove that the correct program computes Jacobi iteration. The proof follows the 2 buffers at the start of each pass through the loop of Jacobi-GPU, as shown in Figure 19.7.
Theorem 19.1 When Jacobi-GPU finishes, buffer \(\mathsf{current}\) holds the grid \(u^{(K)}\) of Definition 19.3, in every cell.
Proof. We show that the loop of lines 2 to 5 maintains the following invariant: at the start of pass \(k\), (i) buffer \(\mathsf{current}\) holds \(u^{(k)}\) in every cell, and (ii) every boundary cell of \(\mathsf{next}\) holds its given value.
Initialization. Before pass 0, line 1 has copied the starting grid \(u = u^{(0)}\) into both buffers. Both parts of the invariant therefore hold.
Maintenance. Assume that the invariant holds at the start of pass \(k\). The launch in line 3 reads only \(\mathsf{current}\) and writes only interior cells of \(\mathsf{next}\), and \(\mathsf{current}\) and \(\mathsf{next}\) are different buffers, so no thread reads a value that another thread of the launch writes. Every thread therefore reads values of \(u^{(k)}\), and line 4 of Jacobi-Kernel stores \(u^{(k+1)}_{r,c}\) into each interior cell of \(\mathsf{next}\). The boundary cells of \(\mathsf{next}\) are not written, so they still hold the given values, which are also the boundary values of \(u^{(k+1)}\). Hence, \(\mathsf{next}\) holds \(u^{(k+1)}\) in every cell. Buffer \(\mathsf{current}\) was not written, so its boundary cells still hold the given values. Line 4 exchanges the names, after which (i) and (ii) hold for pass \(k + 1\). The next launch starts only after this one has finished, because launches on 1 stream run in order.
Termination. The loop ends after \(K\) passes, so \(\mathsf{current}\) holds \(u^{(K)}\), and line 6 copies it to the host.
Each broken variant of this section violates 1 step of the proof. The launch with 1 buffer violates the condition that \(\mathsf{current}\) and \(\mathsf{next}\) are different buffers in the maintenance step. The zeroed buffer violates part (ii) of the invariant at initialization, and the proof then fails at the first exchange, when \(\mathsf{next}\) becomes the buffer that the next step reads.
Rule A Jacobi step reads 1 buffer and writes the other, never the same one, and both buffers hold the boundary values before the first step.
Exercises
19.12 In the zeroed-buffer variant, compute cell (1, 2) after step 2 by hand and compare it with
the output above.
19.13 Suppose the kernel also wrote the boundary cells, copying them from \(u\) to \(v\). Would
the zeroed second buffer still give a wrong answer? Which part of the invariant would the proof no
longer need?
19.14 The output above shows the in-place launch with 3 different results. Why can a block of the
4096 × 4096 grid read a value that another block has already overwritten, while the single block of
the 6 × 6 plate did not?
19.6 Implementation
19.6.1 The kernel
Listing 19.1 shows the kernel in both languages. We let each thread compute its position, which is lines 1
and 2 of Jacobi-Kernel, keep only interior cells, which is line 3, and store the mean of its 4
neighbors, which is line 4. In the flat array, the cell itself is element
center = row * width + col.
Its neighbors above and below are \(W\) elements away, at center - width and center + width, and
those to the left and right are at center - 1 and center + 1. For cell (2, 2) of the plate,
center is
\(2 \cdot 6 + 2 = 14\), and the 4 neighbors are elements 8, 20, 13 and 15. Both versions add the
4 values in the same order and multiply by 0.25 last, as the CPU reference of the programs does,
so that the GPU and the CPU round identically.
Listing 19.1 One Jacobi step, one thread per cell.
mod kernels {
// ...
/// 1 Jacobi step: each interior cell of `new` gets the mean of 4 neighbors in `old`.
#[kernel]
#[launch_contract(domain = 2, block = (32, 8, 1))]
pub fn jacobi(old: &[f32], mut new: DisjointSlice<f32, Runtime2DIndex>) {
let width = new.row_width() as usize;
let height = new.len() / width;
if let Some(idx) = thread::index_2d_runtime(&new) {
let (row, col) = (idx.row(), idx.col());
let interior = row >= 1 && row + 1 < height && col >= 1 && col + 1 < width;
if interior {
let center = row * width + col;
let (above, below) = (old[center - width], old[center + width]);
let (left, right) = (old[center - 1], old[center + 1]);
let sum = above + below + left + right;
if let Some(cell) = new.get_mut(idx) {
*cell = 0.25 * sum;
}
}
}
}
// ...
}// 1 Jacobi step: each interior cell of `next` gets the mean of its 4 neighbors in `old`.
__global__ void jacobi(const float* __restrict__ old, float* __restrict__ next,
int width, int height)
{
int row = blockIdx.y * blockDim.y + threadIdx.y;
int col = blockIdx.x * blockDim.x + threadIdx.x;
bool interior = row >= 1 && row + 1 < height && col >= 1 && col + 1 < width;
if (interior) {
int center = row * width + col;
float above = old[center - width];
float below = old[center + width];
float sum = above + below + old[center - 1] + old[center + 1];
next[center] = 0.25f * sum;
}
}
The two versions differ in how they state that the 2 grids do not overlap. The C++ kernel receives 2
raw pointers and marks them __restrict__, which is a promise to the compiler that no element is
reached through both pointers. The compiler does not check this promise. The Rust kernel receives
the old grid as a shared slice, &[f32], and the new grid as a
DisjointSlice<f32, Runtime2DIndex>, a slice that each thread may write only at its own position.
The Rust kernel obtains that position in 3 steps. First, the host attaches the row width to the
buffer with RowWidth::new, and on the device, row_width() returns it. Second,
thread::index_2d_runtime(&new) returns the thread’s (row, column) position as an index that only
this thread holds. Third, get_mut turns that index into element row * width + col, checks it
against the length of the slice, and returns a mutable reference to the element. Since no 2
threads hold the same index, no 2 threads can write the same element, and the write needs no
unsafe block. This is the same guarantee that the borrow checker enforced on the host in
Section 19.5.1, where it rejected 1 buffer passed as both arguments.
19.6.2 The host loop
Listing 19.2 implements Jacobi-GPU for the plate, that is, lines 1 to 5 of the pseudocode. It fills both buffers from the same host grid, launches 100 steps, exchanges the 2 buffers after each step, and prints the grid after steps 1, 2 and 100.
Listing 19.2 100 steps on the 6 × 6 plate, with the 2 buffers exchanged after each step.
fn main() -> Result<(), Error> {
// ...
// 1. The 6 x 6 plate of the text, small enough to check by hand.
let (width, height) = (6, 6);
let start = initial_grid(width, height);
let mut current = DeviceBuffer::from_host(&stream, &start)?;
let mut next = DeviceBuffer::from_host(&stream, &start)?;
let small = module.prepare_jacobi(grid_2d(width, height))?;
println!("1. 6 x 6 plate, top edge at {HOT}");
let mut changes = Vec::new();
for step in 1..=100 {
module.jacobi(&stream, &small, ¤t, RowWidth::new(&mut next, width as u32))?;
std::mem::swap(&mut current, &mut next);
let (new, old) = (current.to_host_vec(&stream)?, next.to_host_vec(&stream)?);
changes.push(rms_change(&new, &old));
if step <= 2 || step == 100 {
print_grid(&format!("after step {step}"), &new, width);
}
}
// ...
}int main()
{
// ...
// 1. The 6 x 6 plate of the text, small enough to check by hand.
int width = 6;
int height = 6;
Grid start = initialGrid(width, height);
float* current;
float* next;
std::tie(current, next) = deviceGrids(start);
std::printf("1. 6 x 6 plate, top edge at %.0f\n", HOT);
std::vector<double> changes;
for (int step = 1; step <= 100; ++step) {
jacobi<<<blocksFor(width, height), block>>>(current, next, width, height);
std::swap(current, next);
Grid newer = toHost(current, width, height);
Grid older = toHost(next, width, height);
changes.push_back(rmsChange(newer, older));
if (step <= 2 || step == 100) {
char label[32];
std::snprintf(label, sizeof label, "after step %d", step);
printGrid(label, newer, width);
}
}
// ...
}
Both buffers are filled from the same host grid start, which is line 1 of Jacobi-GPU and
establishes part (ii) of the invariant. The exchange of line 4 moves no grid data. In C++,
std::swap(current, next) exchanges 2 pointers of 8 bytes each. In Rust, std::mem::swap(&mut current, &mut next)
exchanges 2 DeviceBuffer values, which are small handles of 40 bytes that hold the device address,
the length and a reference to the context, while the grids themselves stay where they are in
device memory. For comparison, a step on a 4096 × 4096 grid moves at least 134 MB, whereas the
exchange moves 80 bytes of host memory.
19.6.3 Running the example
Both programs print the same values. The Rust program prints the following output.
$ cargo oxide run
GPU: Orin, 8 SMs
1. 6 x 6 plate, top edge at 100
after step 1
100.00 100.00 100.00 100.00 100.00 100.00
0.00 25.00 25.00 25.00 25.00 0.00
0.00 0.00 0.00 0.00 0.00 0.00
0.00 0.00 0.00 0.00 0.00 0.00
0.00 0.00 0.00 0.00 0.00 0.00
0.00 0.00 0.00 0.00 0.00 0.00
after step 2
100.00 100.00 100.00 100.00 100.00 100.00
0.00 31.25 37.50 37.50 31.25 0.00
0.00 6.25 6.25 6.25 6.25 0.00
0.00 0.00 0.00 0.00 0.00 0.00
0.00 0.00 0.00 0.00 0.00 0.00
0.00 0.00 0.00 0.00 0.00 0.00
after step 100
100.00 100.00 100.00 100.00 100.00 100.00
0.00 45.45 59.47 59.47 45.45 0.00
0.00 22.35 32.95 32.95 22.35 0.00
0.00 10.98 17.05 17.05 10.98 0.00
0.00 4.55 7.20 7.20 4.55 0.00
0.00 0.00 0.00 0.00 0.00 0.00
Every value of steps 1 and 2 agrees with the values that we computed by hand in Section 19.2.1.
The program also runs the same 100 steps on the CPU with the function cpu_step, and it reports
same bits as the CPU after 100 steps: true. The 2 computations therefore agree in every bit of
every cell. This is possible because each cell is computed by the same 3 additions in the same
order, followed by the same multiplication, and IEEE 754 single-precision arithmetic rounds such a
sequence identically on both processors.
Exercises
19.15 Change the programs to print the grid after step 3 and compare it with your answer to
Exercise 19.4.
19.16 The Rust launch passes ¤t and RowWidth::new(&mut next, ...). Explain why the borrow checker
accepts this call but rejects the one of Section 19.5.1.
19.7 Convergence
19.7.1 Measuring the change
After 100 steps, the plate agrees with the final temperatures to 2 decimal places. In general, however, the final temperatures are not known in advance, so a solver must decide by itself when to stop. It does so by measuring how much a step still changes the grid. When a step hardly changes any value, the grid is close to the state in which every cell equals the mean of its neighbors.
Definition 19.7 RMS change. The root-mean-square (RMS) change of a step from grid \(u\) to grid \(v\) of \(N\) cells is
\[ \Delta = \sqrt{\frac{1}{N} \sum_{i \in [0, N)} (v_i - u_i)^2 }. \]
Example. Step 1 of the plate changes 4 of the 36 cells by 25 each: \(\Delta = \sqrt{4 \cdot 625 / 36} = 8.33\) degrees.
| Symbol | Meaning | Step 1 of the plate |
|---|---|---|
| \(N\) | number of cells of the grid | 36 |
| \(i\) | position of a cell in the flat array | 0 to 35 |
| \(u_i\), \(v_i\) | value of cell \(i\) before and after the step | 0 and 25 for the 4 cells of row 1 |
| \((v_i - u_i)^2\) | square of the change of cell \(i\) | 625 for those 4 cells, 0 for the rest |
| \(\Delta\) | square root of the mean of the squares: a typical change per cell | 8.33 |
The squares make every change count as positive, so that a rise in 1 cell cannot cancel a fall in another, and the square root at the end returns the result to degrees.
Both programs copy the 2 buffers to the host after every step of the plate and compute the RMS change there. A 6 × 6 grid occupies only 144 bytes, so the copy costs microseconds. The programs print the change and its ratio to the change of the step before, as follows.
RMS change per step, and its ratio to the step before
step 1 8.33e+00
step 2 3.90e+00 ratio 0.4677
step 3 2.52e+00 ratio 0.6478
step 4 1.82e+00 ratio 0.7192
step 10 4.48e-01 ratio 0.8075
step 20 5.38e-02 ratio 0.8090
step 40 7.75e-04 ratio 0.8086
After the first few steps, the change shrinks by the same factor in every step, 0.809.
19.7.2 The rate of convergence
This factor can be predicted. Let the error of a grid be its difference from the final temperatures, cell by cell. A Jacobi step leaves the final temperatures unchanged, since each of them already equals the mean of its neighbors. A step therefore applies the same averaging to the error that it applies to the grid, and the error after a step is the mean of the neighboring errors before it. An error pattern that varies quickly from cell to cell, for example \(+1\) and \(-1\) in alternating cells, is averaged away in a few steps, because neighboring values cancel. The pattern that survives longest is the smoothest one that is 0 on the boundary, a single bump that is largest in the middle of the plate. On a grid whose cells are numbered 0 to \(n\) along each side, this pattern is
\[ e_{r,c} = \sin\frac{\pi r}{n} \, \sin\frac{\pi c}{n}. \]
| Symbol | Meaning | On the 6 × 6 plate |
|---|---|---|
| \(n\) | number of the last row and column; the boundary lies at 0 and \(n\) | 5 |
| \(e_{r,c}\) | error of cell \((r, c)\) in the slowest pattern | 0 on the boundary, largest in the center |
| \(\sin(\pi r / n)\) | a half wave along the rows, 0 at \(r = 0\) and at \(r = n\) | \(\sin(\pi/5) = 0.588\) at \(r = 1\) |
Let us apply 1 step to this pattern. The 2 neighbors of cell \((r, c)\) in its column hold \(\sin(\pi(r - 1)/n)\) and \(\sin(\pi(r + 1)/n)\), each multiplied by the same column factor \(\sin(\pi c / n)\). By the identity \(\sin(x - y) + \sin(x + y) = 2 \sin x \cos y\), their sum is \(2\cos(\pi/n)\) times the value of the cell, and the same holds for the 2 neighbors in its row. The sum of the 4 neighbors is therefore \(4\cos(\pi/n)\) times the value of the cell, their mean is \(\cos(\pi/n)\) times that value, and 1 step multiplies the whole pattern by
\[ \rho = \cos\frac{\pi}{n}. \]
Our plate has \(n = 5\), and \(\cos(\pi/5) = 0.8090\), which is the ratio that the programs measured from step 10 on. The early ratios are smaller, because the rougher error patterns, which shrink faster, have not yet died out.
The same programs then iterate a 64 × 64 plate, for which \(n = 63\), until the RMS change of a step falls below \(10^{-6}\) degrees. They measure the change every 1,000 steps and print the following values.
2. 64 x 64 plate until the RMS change per step is below 1e-6
step 1000 RMS change 7.49e-03
step 2000 RMS change 2.06e-03
step 3000 RMS change 5.95e-04
step 4000 RMS change 1.71e-04
step 5000 RMS change 4.95e-05
step 6000 RMS change 1.44e-05
step 7000 RMS change 4.57e-06
step 8000 RMS change 1.79e-06
step 9000 RMS change 5.59e-07
largest difference from the CPU after 9000 steps: 0.00e+00
The prediction is \(\rho = \cos(\pi/63) = 0.998757\) per step, so 1,000 steps multiply the change by \(0.998757^{1000} = 0.288\). The measured ratios between consecutive lines are \(2.06 / 7.49 = 0.275\), \(0.595 / 2.06 = 0.289\), \(0.171 / 0.595 = 0.287\) and \(0.0495 / 0.171 = 0.289\), in close agreement with the prediction, as Figure 19.8 shows. After step 7,000, the ratio drifts upward, to 0.39 and 0.31, because the changes have become smaller than the rounding error of single-precision values near 50, which is about \(4 \times 10^{-6}\) degrees.
The prediction also gives the cost of the method on a large grid. When \(\rho\) is close to 1, each step removes only the small fraction \(1 - \rho\) of the remaining error, so reducing the error by a factor of \(e = 2.718\) takes about \(1 / (1 - \rho)\) steps. For large \(n\), \(1 - \cos(\pi/n)\) is close to \(\pi^2 / (2n^2)\), so this number of steps is about \(2n^2/\pi^2\). It is 5 for our plate, about 800 for \(n = 63\), and about 3.4 million for a grid of 4096 × 4096 cells. The number of steps grows with the square of the width, so large solvers use Jacobi steps as one part of faster methods, such as multigrid, which apply a few Jacobi steps on a series of coarser grids. A fast Jacobi step is the building block of those methods, and in the rest of this chapter and in the next, we measure how fast a step can be.
Exercises
19.17 Predict \(\rho\) and the factor per 1,000 steps for a 128 × 128 plate. Change the programs
and compare.
19.18 About how many steps reduce the error of the 64 × 64 plate by a factor of 1,000?
19.8 Memory traffic and measurements
19.8.1 Arithmetic intensity
Each update performs 4 floating-point operations (FLOP). To judge whether this is much or little, we compare it with the number of bytes that the update must move. Every old value must be read at least once, and every new value must be written once. The least that any step can move is therefore 1 read and 1 write of 4 bytes per cell, 8 bytes in total.
Definition 19.8 Arithmetic intensity, memory-bound. The arithmetic intensity of a computation is the number of floating-point operations it performs per byte it moves to or from memory. A kernel is memory-bound on a GPU when its arithmetic intensity lies below the GPU’s ridge point, its peak arithmetic rate divided by its memory bandwidth (Chapter 2); its speed is then set by the bytes it moves, not by the operations it performs.
Example. A Jacobi step performs 4 FLOP per cell and moves at least 8 bytes per cell, so its arithmetic intensity is at most \(4 / 8 = 0.5\) FLOP per byte.
The ridge point is the arithmetic intensity at which a kernel would keep both the arithmetic units and the memory fully busy. The ridge points of the GPUs compared in Chapter 2 range from about 10 FLOP per byte for the A100 to about 114 FLOP per byte for the DGX Spark. The Jetson Orin NX lies at about 24, and the Jetson AGX Thor at about 30, as Figure 19.9 shows. A Jacobi step lies below every one of them by a factor of 20 or more, so it is memory-bound on every GPU of the table. Its speed is therefore best measured by its effective bandwidth, the 8 bytes per cell that a step must move divided by the time of the step. Since a copy of the grid moves the same 8 bytes per cell, a step can be no faster than a copy.
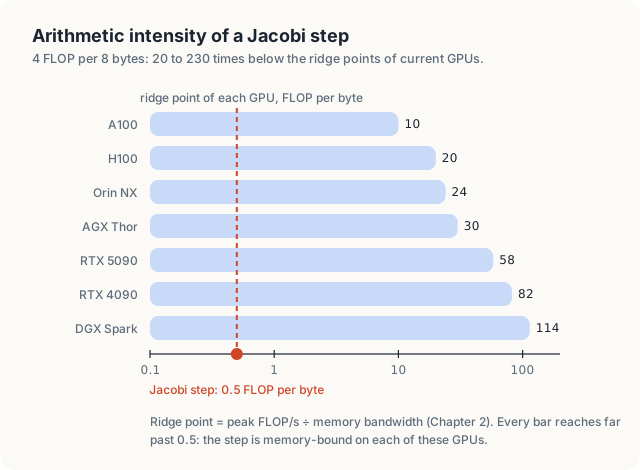
19.8.2 Measurements
The measurements come from a Jetson Orin NX, an integrated GPU with 8 SMs and 102 GB/s of memory bandwidth. Both programs time a step on a 4096 × 4096 grid, which occupies 64 MiB per buffer. This is far larger than the 2 MiB L2 cache of the measured GPU, so the grid must come from memory. Each program first runs the kernel for 0.4 s, because these GPUs raise their clock frequency only under sustained load, and then averages 50 calls. Repeated runs differ by 10 to 20%. On the measured GPU, the C++ program printed
3. 4096 x 4096 plate, 8 bytes per cell per step (1 read, 1 write)
copy kernel 1.756 ms 76.4 GB/s
jacobi 1.966 ms 68.3 GB/s
PASSED
and the Rust program printed
3. 4096 x 4096 plate, 8 bytes per cell per step (1 read, 1 write)
copy kernel 1.784 ms 75.2 GB/s
jacobi 2.322 ms 57.8 GB/s
PASSED
The following table and Figure 19.10 collect these numbers. The last column gives the effective bandwidth of each kernel as a share of the bandwidth of the copy.
| Kernel | Time per step | Effective bandwidth | Share of the copy |
|---|---|---|---|
| copy, C++ | 1.756 ms | 76.4 GB/s | 100% |
| Jacobi step, C++ | 1.966 ms | 68.3 GB/s | 89% |
| Jacobi step, Rust | 2.322 ms | 57.8 GB/s | 76% |
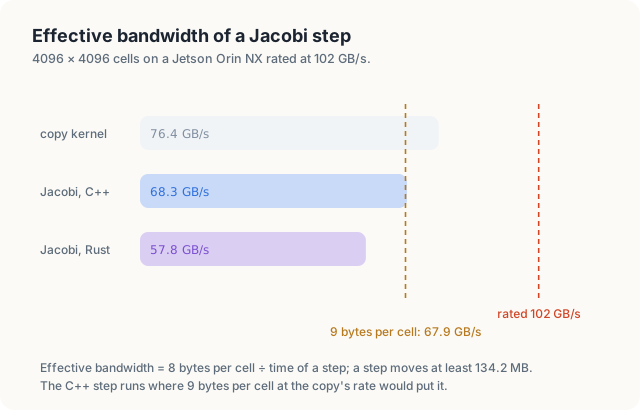
19.8.3 Why the step runs at 89% of a copy
The copy reaches 76.4 GB/s, which is 75% of the rated 102 GB/s. In Chapter 7, we saw that no kernel reaches the rated figure, so the copy, not the rating, is the ceiling for a step. The C++ step reaches 89% of the copy. This is more than we should expect at first sight. If every one of its 4 reads per cell went to memory, a step would move 16 bytes of reads and 4 bytes of writes, 20 bytes per cell, and it would take at least \(20 / 8 = 2.5\) times as long as the copy, that is, 4.4 ms. It took 1.97 ms.
Let us compute what that time would require. Requesting 20 bytes for each of the 16.7 million cells in 1.966 ms is a rate of \(20 \cdot 16.7 \times 10^6 / 1.966 \times 10^{-3}\) = 171 GB/s, which is 1.7 times the 102 GB/s that the memory can deliver at all. At most 102 of every 171 requested bytes can therefore have come from memory, and at least \(1 - 102/171 = 40\%\) of them must have come from the L1 and L2 caches, the on-chip memories that keep recently read values.
The caches find those values because neighboring threads read neighboring rows, as Figure 19.11 shows. The 32 threads of a warp read 3 row segments of the old grid: the row above, their own row with 1 extra cell at each end, and the row below. The 8 warps of a block cover 8 consecutive rows, so the row above warp 1 is the row of warp 0, and the row below warp 1 is the row of warp 2. A block of 32 × 8 threads therefore needs only 10 different row segments of the old grid, its own 8 rows and 1 more on each side. If each segment is read from memory once, a block reads \(10 / 8 = 1.25\) old values per cell and writes 1, which is 9 bytes per cell instead of 8. At the copy’s rate, 9 bytes per cell take \(1.756 \cdot 9 / 8 = 1.98\) ms, which agrees with the measured 1.966 ms.
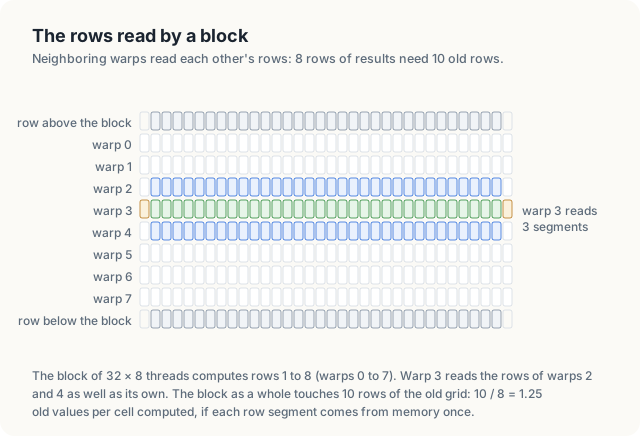
The step is thus close to the best it can be. It moves about 9 bytes per cell where 8 are needed, and its speed follows from that count. In Chapter 20, we ask whether a block can do better by copying its 10 rows into shared memory itself.
19.8.4 Why the Rust step is slower
The Rust kernel runs at 57.8 GB/s, 85% of the speed of the C++ kernel, although it reads and writes
the same cells. Its memory traffic is the same, but its integer work is not. The C++ kernel computes
positions in 32-bit int. The Rust kernel computes them in 64-bit usize, derives the height with
a 64-bit division, new.len() / width, and checks each index against the length of its slice. To
separate these costs, we changed only the C++ kernel, so that it used 64-bit positions and the same
division of the length by the width. It then ran at 58.9 GB/s, the speed of the Rust kernel. A
memory-bound kernel is therefore not free of arithmetic. With only 4 floating-point operations per
cell, the integer instructions that compute positions and check bounds make up most of the kernel,
and a 64-bit division, which the GPU performs as a sequence of many instructions, delays the loads.
Exercises
19.19 Rewrite the Rust kernel so that it computes positions in u32 and receives the height as an
argument, then measure it. How close does it come to the C++ kernel?
19.20 Change the block shape of both programs to 16 × 16 and predict, with the row count of
Section 19.8.3, how many old values a block reads per cell. Then measure.
19.9 The complete programs
Listing 19.3 The complete Rust program. code/oxide/ch19_stencil/src/main.rs
//! Chapter 19: Jacobi iteration for the Laplace equation, 1 thread per cell.
//!
//! cargo oxide run
use std::sync::Arc;
use std::time::Instant;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, LaunchConfig1D, LaunchConfig2D};
use cuda_device::thread::Runtime2DIndex;
use cuda_device::{DisjointSlice, cuda_module, kernel, launch_contract, thread};
use cuda_host::RowWidth;
const BLOCK_WIDTH: usize = 32; // 1 warp along a row of the grid
const BLOCK_HEIGHT: usize = 8; // 8 warps, 256 threads
const HOT: f32 = 100.0; // the top edge; the other edges are held at 0
type Error = Box<dyn std::error::Error>;
#[cuda_module]
mod kernels {
use super::*;
/// 1 Jacobi step: each interior cell of `new` gets the mean of 4 neighbors in `old`.
#[kernel]
#[launch_contract(domain = 2, block = (32, 8, 1))]
pub fn jacobi(old: &[f32], mut new: DisjointSlice<f32, Runtime2DIndex>) {
let width = new.row_width() as usize;
let height = new.len() / width;
if let Some(idx) = thread::index_2d_runtime(&new) {
let (row, col) = (idx.row(), idx.col());
let interior = row >= 1 && row + 1 < height && col >= 1 && col + 1 < width;
if interior {
let center = row * width + col;
let (above, below) = (old[center - width], old[center + width]);
let (left, right) = (old[center - 1], old[center + 1]);
let sum = above + below + left + right;
if let Some(cell) = new.get_mut(idx) {
*cell = 0.25 * sum;
}
}
}
}
/// A copy: 1 read and 1 write per cell, the least traffic a step can have.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn copy(input: &[f32], mut out: DisjointSlice<f32>) {
let idx = thread::index_1d();
let index = idx.get();
if let Some(out_cell) = out.get_mut(idx) {
*out_cell = input[index];
}
}
}
/// A plate of `width` x `height` cells: the top row at HOT, every other cell at 0.
fn initial_grid(width: usize, height: usize) -> Vec<f32> {
let mut grid = vec![0.0; width * height];
grid[..width].fill(HOT);
grid
}
/// 1 Jacobi step on the CPU, the reference for the GPU kernel.
fn cpu_step(old: &[f32], new: &mut [f32], width: usize) {
let height = old.len() / width;
for row in 1..height - 1 {
for col in 1..width - 1 {
let center = row * width + col;
let (above, below) = (old[center - width], old[center + width]);
let (left, right) = (old[center - 1], old[center + 1]);
let sum = above + below + left + right;
new[center] = 0.25 * sum;
}
}
}
/// The root-mean-square difference between 2 grids, over all cells.
fn rms_change(new: &[f32], old: &[f32]) -> f64 {
let squares: f64 = new
.iter()
.zip(old)
.map(|(new_value, old_value)| f64::from(new_value - old_value).powi(2))
.sum();
(squares / new.len() as f64).sqrt()
}
/// A number in the style of C's %.2e, so that both programs print the same text.
fn sci(v: f64) -> String {
let exponent = if v == 0.0 { 0 } else { v.abs().log10().floor() as i32 };
format!("{:.2}e{exponent:+03}", v / 10f64.powi(exponent))
}
fn print_grid(label: &str, grid: &[f32], width: usize) {
println!(" {label}");
for row in grid.chunks(width) {
let cells: Vec<String> = row.iter().map(|v| format!("{v:7.2}")).collect();
println!(" {}", cells.join(" "));
}
}
/// Enough 32 x 8 blocks to cover a grid of `width` x `height` cells, 1 thread per cell.
fn grid_2d(width: usize, height: usize) -> LaunchConfig2D {
let blocks_x = width.div_ceil(BLOCK_WIDTH) as u32;
let blocks_y = height.div_ceil(BLOCK_HEIGHT) as u32;
LaunchConfig2D::new((blocks_x, blocks_y), (BLOCK_WIDTH as u32, BLOCK_HEIGHT as u32), 0)
}
/// Average time of `runs` calls of `launch`, in milliseconds, after 0.4 s of warm-up.
fn time_ms(
stream: &Arc<CudaStream>,
runs: u32,
mut launch: impl FnMut() -> Result<(), Error>,
) -> Result<f64, Error> {
let warm = Instant::now();
while warm.elapsed().as_secs_f64() < 0.4 {
launch()?;
stream.synchronize()?;
}
let start = Instant::now();
for _ in 0..runs {
launch()?;
}
stream.synchronize()?;
Ok(start.elapsed().as_secs_f64() * 1e3 / runs as f64)
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let name = ctx.device_name()?;
let sms = ctx.multiprocessor_count()?;
println!("GPU: {name}, {sms} SMs");
// 1. The 6 x 6 plate of the text, small enough to check by hand.
let (width, height) = (6, 6);
let start = initial_grid(width, height);
let mut current = DeviceBuffer::from_host(&stream, &start)?;
let mut next = DeviceBuffer::from_host(&stream, &start)?;
let small = module.prepare_jacobi(grid_2d(width, height))?;
println!("1. 6 x 6 plate, top edge at {HOT}");
let mut changes = Vec::new();
for step in 1..=100 {
module.jacobi(&stream, &small, ¤t, RowWidth::new(&mut next, width as u32))?;
std::mem::swap(&mut current, &mut next);
let (new, old) = (current.to_host_vec(&stream)?, next.to_host_vec(&stream)?);
changes.push(rms_change(&new, &old));
if step <= 2 || step == 100 {
print_grid(&format!("after step {step}"), &new, width);
}
}
println!(" RMS change per step, and its ratio to the step before");
println!(" step {:3} {:>9}", 1, sci(changes[0]));
for step in [2, 3, 4, 10, 20, 40] {
let ratio = changes[step - 1] / changes[step - 2];
println!(" step {step:3} {:>9} ratio {ratio:.4}", sci(changes[step - 1]));
}
let mut cpu_a = start.clone();
let mut cpu_b = start.clone();
for _ in 0..100 {
cpu_step(&cpu_a, &mut cpu_b, width);
std::mem::swap(&mut cpu_a, &mut cpu_b);
}
let small_same = current.to_host_vec(&stream)? == cpu_a;
println!(" same bits as the CPU after 100 steps: {small_same}");
// 2. A 64 x 64 plate, iterated until the RMS change per step is below 1e-6.
let (width, height) = (64, 64);
let start = initial_grid(width, height);
let mut current = DeviceBuffer::from_host(&stream, &start)?;
let mut next = DeviceBuffer::from_host(&stream, &start)?;
let step = module.prepare_jacobi(grid_2d(width, height))?;
println!("2. 64 x 64 plate until the RMS change per step is below 1e-6");
let mut steps = 0;
loop {
module.jacobi(&stream, &step, ¤t, RowWidth::new(&mut next, width as u32))?;
std::mem::swap(&mut current, &mut next);
steps += 1;
if steps % 1000 == 0 {
let (new, old) = (current.to_host_vec(&stream)?, next.to_host_vec(&stream)?);
let rms = rms_change(&new, &old);
println!(" step {steps:5} RMS change {}", sci(rms));
if rms < 1e-6 {
break;
}
}
}
let field = current.to_host_vec(&stream)?;
let mut cpu_a = start.clone();
let mut cpu_b = start.clone();
for _ in 0..steps {
cpu_step(&cpu_a, &mut cpu_b, width);
std::mem::swap(&mut cpu_a, &mut cpu_b);
}
let differences = field.iter().zip(&cpu_a).map(|(gpu, cpu)| (gpu - cpu).abs());
let diff = differences.fold(0.0, f32::max);
let shown = sci(f64::from(diff));
println!(" largest difference from the CPU after {steps} steps: {shown}");
// 3. A 4096 x 4096 plate: time per step and effective bandwidth.
let (width, height) = (4096, 4096);
let cells = width * height;
let start = initial_grid(width, height);
let mut current = DeviceBuffer::from_host(&stream, &start)?;
let mut next = DeviceBuffer::from_host(&stream, &start)?;
let big = module.prepare_jacobi(grid_2d(width, height))?;
let copy = module.prepare_copy(LaunchConfig1D::new((cells / 256) as u32, 256, 0))?;
let copy_once = || Ok(module.copy(&stream, ©, ¤t, &mut next)?);
let ms_copy = time_ms(&stream, 50, copy_once)?;
let ms_jacobi = time_ms(&stream, 50, || {
module.jacobi(&stream, &big, ¤t, RowWidth::new(&mut next, width as u32))?;
module.jacobi(&stream, &big, &next, RowWidth::new(&mut current, width as u32))?;
Ok(())
})? / 2.0;
let gb = |ms: f64| (2 * cells * 4) as f64 / 1e9 / (ms / 1e3);
println!("3. 4096 x 4096 plate, 8 bytes per cell per step (1 read, 1 write)");
println!(" copy kernel {ms_copy:6.3} ms {:6.1} GB/s", gb(ms_copy));
println!(" jacobi {ms_jacobi:6.3} ms {:6.1} GB/s", gb(ms_jacobi));
let passed = small_same && diff == 0.0;
println!("{}", if passed { "PASSED" } else { "FAILED" });
Ok(())
}// Chapter 19: Jacobi iteration for the Laplace equation, 1 thread per cell.
// Build: nvcc -O3 -arch=native stencil.cu -o stencil
#include <chrono>
#include <cmath>
#include <cstdio>
#include <cstdlib>
#include <tuple>
#include <utility>
#include <vector>
#include <cuda_runtime.h>
using Grid = std::vector<float>;
const int BLOCK_WIDTH = 32; // 1 warp along a row of the grid
const int BLOCK_HEIGHT = 8; // 8 warps, 256 threads
const float HOT = 100.0f; // the top edge; the others are held at 0
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
// 1 Jacobi step: each interior cell of `next` gets the mean of its 4 neighbors in `old`.
__global__ void jacobi(const float* __restrict__ old, float* __restrict__ next,
int width, int height)
{
int row = blockIdx.y * blockDim.y + threadIdx.y;
int col = blockIdx.x * blockDim.x + threadIdx.x;
bool interior = row >= 1 && row + 1 < height && col >= 1 && col + 1 < width;
if (interior) {
int center = row * width + col;
float above = old[center - width];
float below = old[center + width];
float sum = above + below + old[center - 1] + old[center + 1];
next[center] = 0.25f * sum;
}
}
// A copy: 1 read and 1 write per cell, the least traffic a step can have.
__global__ void copy(const float* __restrict__ in, float* __restrict__ out, int n)
{
int index = blockIdx.x * blockDim.x + threadIdx.x;
if (index < n) {
out[index] = in[index];
}
}
// A plate of width x height cells: the top row at HOT, every other cell at 0.
Grid initialGrid(int width, int height)
{
Grid grid(size_t(width) * height, 0.0f);
for (int col = 0; col < width; ++col) {
grid[col] = HOT;
}
return grid;
}
// 1 Jacobi step on the CPU, the reference for the GPU kernel.
void cpuStep(const Grid& old, Grid& next, int width, int height)
{
for (int row = 1; row + 1 < height; ++row) {
for (int col = 1; col + 1 < width; ++col) {
int center = row * width + col;
float above = old[center - width];
float below = old[center + width];
float sum = above + below + old[center - 1] + old[center + 1];
next[center] = 0.25f * sum;
}
}
}
// The root-mean-square difference between 2 grids, over all cells.
double rmsChange(const Grid& next, const Grid& old)
{
double squares = 0.0;
for (size_t i = 0; i < next.size(); ++i) {
double change = next[i] - old[i];
squares += change * change;
}
return std::sqrt(squares / next.size());
}
void printGrid(const char* label, const Grid& grid, int width)
{
std::printf(" %s\n", label);
for (size_t i = 0; i < grid.size(); ++i) {
const char* gap = i % width == 0 ? " " : " ";
const char* end = i % width == size_t(width - 1) ? "\n" : "";
std::printf("%s%7.2f%s", gap, grid[i], end);
}
}
Grid toHost(const float* device, int width, int height)
{
Grid grid(size_t(width) * height);
size_t bytes = grid.size() * sizeof(float);
check(cudaMemcpy(grid.data(), device, bytes, cudaMemcpyDeviceToHost));
return grid;
}
// 2 device grids, both filled with the initial plate (boundary included).
std::pair<float*, float*> deviceGrids(const Grid& start)
{
size_t bytes = start.size() * sizeof(float);
float *a, *b;
check(cudaMalloc(&a, bytes));
check(cudaMalloc(&b, bytes));
check(cudaMemcpy(a, start.data(), bytes, cudaMemcpyHostToDevice));
check(cudaMemcpy(b, start.data(), bytes, cudaMemcpyHostToDevice));
return {a, b};
}
// Enough 32 x 8 blocks to cover a grid of width x height cells, 1 thread per cell.
dim3 blocksFor(int width, int height)
{
int columns = (width + BLOCK_WIDTH - 1) / BLOCK_WIDTH;
int rows = (height + BLOCK_HEIGHT - 1) / BLOCK_HEIGHT;
return dim3(columns, rows);
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// Average time of `runs` calls of `launch`, in milliseconds, after 0.4 s of warm-up.
template <typename F>
double timeMs(F launch, int runs)
{
double warm = nowMs();
while (nowMs() - warm < 400.0) {
launch();
check(cudaDeviceSynchronize());
}
double t0 = nowMs();
for (int run = 0; run < runs; ++run) {
launch();
}
check(cudaGetLastError());
check(cudaDeviceSynchronize());
return (nowMs() - t0) / runs;
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %d SMs\n", prop.name, prop.multiProcessorCount);
dim3 block(BLOCK_WIDTH, BLOCK_HEIGHT);
// 1. The 6 x 6 plate of the text, small enough to check by hand.
int width = 6;
int height = 6;
Grid start = initialGrid(width, height);
float* current;
float* next;
std::tie(current, next) = deviceGrids(start);
std::printf("1. 6 x 6 plate, top edge at %.0f\n", HOT);
std::vector<double> changes;
for (int step = 1; step <= 100; ++step) {
jacobi<<<blocksFor(width, height), block>>>(current, next, width, height);
std::swap(current, next);
Grid newer = toHost(current, width, height);
Grid older = toHost(next, width, height);
changes.push_back(rmsChange(newer, older));
if (step <= 2 || step == 100) {
char label[32];
std::snprintf(label, sizeof label, "after step %d", step);
printGrid(label, newer, width);
}
}
std::printf(" RMS change per step, and its ratio to the step before\n");
std::printf(" step %3d %9.2e\n", 1, changes[0]);
for (int step : {2, 3, 4, 10, 20, 40}) {
double ratio = changes[step - 1] / changes[step - 2];
std::printf(" step %3d %9.2e ratio %.4f\n", step, changes[step - 1], ratio);
}
Grid cpuA = start;
Grid cpuB = start;
for (int step = 0; step < 100; ++step) {
cpuStep(cpuA, cpuB, width, height);
std::swap(cpuA, cpuB);
}
bool smallSame = toHost(current, width, height) == cpuA;
const char* answer = smallSame ? "true" : "false";
std::printf(" same bits as the CPU after 100 steps: %s\n", answer);
check(cudaFree(current));
check(cudaFree(next));
// 2. A 64 x 64 plate, iterated until the RMS change per step is below 1e-6.
width = 64;
height = 64;
start = initialGrid(width, height);
std::tie(current, next) = deviceGrids(start);
std::printf("2. 64 x 64 plate until the RMS change per step is below 1e-6\n");
int steps = 0;
while (true) {
jacobi<<<blocksFor(width, height), block>>>(current, next, width, height);
std::swap(current, next);
steps += 1;
if (steps % 1000 == 0) {
Grid newer = toHost(current, width, height);
Grid older = toHost(next, width, height);
double rms = rmsChange(newer, older);
std::printf(" step %5d RMS change %.2e\n", steps, rms);
if (rms < 1e-6) {
break;
}
}
}
Grid field = toHost(current, width, height);
cpuA = start;
cpuB = start;
for (int step = 0; step < steps; ++step) {
cpuStep(cpuA, cpuB, width, height);
std::swap(cpuA, cpuB);
}
float diff = 0.0f;
for (size_t i = 0; i < field.size(); ++i) {
diff = std::fmax(diff, std::fabs(field[i] - cpuA[i]));
}
std::printf(" largest difference from the CPU after %d steps: %.2e\n", steps, diff);
check(cudaFree(current));
check(cudaFree(next));
// 3. A 4096 x 4096 plate: time per step and effective bandwidth.
width = 4096;
height = 4096;
int cells = width * height;
start = initialGrid(width, height);
std::tie(current, next) = deviceGrids(start);
auto copyStep = [&] { copy<<<cells / 256, 256>>>(current, next, cells); };
auto twoSteps = [&] {
jacobi<<<blocksFor(width, height), block>>>(current, next, width, height);
jacobi<<<blocksFor(width, height), block>>>(next, current, width, height);
};
double msCopy = timeMs(copyStep, 50);
double msJacobi = timeMs(twoSteps, 50) / 2.0;
auto gb = [&](double ms) { return 2.0 * cells * 4 / 1e9 / (ms / 1e3); };
std::printf("3. 4096 x 4096 plate, 8 bytes per cell per step (1 read, 1 write)\n");
std::printf(" copy kernel %6.3f ms %6.1f GB/s\n", msCopy, gb(msCopy));
std::printf(" jacobi %6.3f ms %6.1f GB/s\n", msJacobi, gb(msJacobi));
check(cudaFree(current));
check(cudaFree(next));
bool passed = smallSame && diff == 0.0f;
std::printf("%s\n", passed ? "PASSED" : "FAILED");
return passed ? 0 : 1;
}
Common mistakes
- Updating the grid in place. Threads then read neighbors that other threads have already replaced, and the result depends on their timing. On a small grid inside 1 block, the error may not appear at all (Section 19.5.1). Use 2 buffers; in Rust, the safe launch path rejects the same buffer as both arguments.
- Leaving the boundary out of 1 buffer. The kernel never writes boundary cells, so both buffers must hold them before the first step. The mistake converges to a wrong answer without any error (Section 19.5.2).
- Copying the new grid back into the old one after every step. Exchanging the 2 names moves 80 bytes of host memory, whereas a copy moves the whole grid.
- Checking convergence after every step on a large grid. Each check waits for the GPU and moves data to the host. Check every few hundred or few thousand steps.
- Expecting Jacobi iteration to converge quickly on a large grid. The number of steps needed grows with the square of the width; use Jacobi steps inside a faster method such as multigrid.
- Judging a stencil kernel by its FLOP rate. At 0.5 FLOP per byte, the kernel is memory-bound; compare its effective bandwidth with that of a copy.
Summary
- The Laplace equation, written with finite differences, says that in the final state every interior cell equals the mean of its 4 neighbors. This is the 5-point stencil.
- Jacobi iteration replaces every interior value by the mean of its old neighbors. On the 6 × 6 plate, step 1 gives 25 in row 1, step 2 gives 31.25, 37.5 and 6.25, and 100 steps reach the final temperatures to 2 decimal places.
- An update in place computes a different value, 31.25 instead of 25 at cell (1, 2) in step 1. On a GPU, it gives results that change from run to run: 28,420, 28,330 and 28,464 wrong cells in 3 runs on a 4096 × 4096 grid.
- Ping-pong buffers keep the steps apart. Theorem 19.1 proves that they compute Jacobi iteration exactly, provided that both buffers hold the boundary and the 2 arguments of a launch differ.
- Rust states this condition in types: the old grid is
&[f32], the new one aDisjointSlice, and the borrow checker rejects 1 buffer passed as both. C++ states it with__restrict__, which is not checked. - The RMS change falls by \(\cos(\pi/n)\) per step: 0.809 on the 6 × 6 plate and 0.288 per 1,000 steps on a 64 × 64 plate, as measured.
- A step performs 0.5 FLOP per byte and is memory-bound on every GPU. The C++ step reached 68.3 GB/s, 89% of a copy, because the caches already reduce its reads to about 1.25 per cell.
Exercises
- Change the boundary of the plate so that the top edge is at 100 and the left edge at 50. Predict the mean of the 4 center cells at the final state from the symmetry of the problem, and check it with the programs.
- A 9-point stencil also uses the 4 diagonal neighbors. How many reads per cell does it request, and how many old rows does a block of 32 × 8 threads touch? Predict its effective bandwidth from the measurements of Section 19.8.
- Write a kernel that computes the RMS change on the GPU with a block reduction (Chapter 15) and use it for the 64 × 64 plate. Measure how often the loop can afford to check.
- Modify the in-place variant so that it runs on the 6 × 6 plate with blocks of 1 × 1 threads. Does the result now differ from Jacobi’s? Explain from the order in which blocks run.
- Explain why Theorem 19.1 needs the sentence “launches on 1 stream run in order”. Construct a program with 2 streams in which the proof fails.
Sources and further reading
- R. J. LeVeque, Finite Difference Methods for Ordinary and Partial Differential Equations, SIAM, 2007. Chapters 2 and 3 derive the 5-point Laplacian and its error; chapter 4 analyzes Jacobi iteration and its convergence factor.
- Y. Saad, Iterative Methods for Sparse Linear Systems, 2nd edition, SIAM, 2003. Jacobi and Gauss-Seidel iteration and their convergence.
- W. L. Briggs, V. E. Henson and S. F. McCormick, A Multigrid Tutorial, 2nd edition, SIAM, 2000. How Jacobi steps on coarser grids remove smooth errors quickly.
- T. H. Cormen, C. E. Leiserson, R. L. Rivest and C. Stein, Introduction to Algorithms, 4th edition, MIT Press, 2022. The pseudocode conventions and loop invariants used here.
- A. Pathak, An Introduction to Tiled Parallel Programming, Simplified, 2026. The same method of presentation applied to the matrix product.
- NVlabs, cuda-oxide, rev
b7fe543:cuda-device/src/disjoint.rsdocumentsRuntime2DIndex,index_2d_runtimeand whyget_muton a slice of run-time width is safe.
Chapter 20: Tiled Stencils with Halo Cells
Recall that in the Jacobi kernel of Chapter 19, every thread reads its 4 neighbors from global memory, so every value of the grid is read by up to 4 different threads. In Chapter 17, we removed exactly this kind of repetition from the matrix product. The threads of a block copied a piece of the input into shared memory once, and then every thread read its operands from that copy. A stencil can be tiled in the same way, with 1 complication: the cells that a block computes need neighbors that belong to other blocks.
In this chapter, we derive the tiled stencil kernel on the 6 × 6 plate of Chapter 19. We first count how often the direct kernel reads each value. We then define the tile and its halo, compare 2 ways of loading the halo, and break the kernel twice, once without its barrier and once without its halo, to show the exact wrong values that appear. After that, we count the memory traffic as a function of the tile size and measure the result. The measurement holds a lesson of its own. On GPUs whose caches already capture the reuse, the tile saves little traffic and costs instructions. Finally, we study temporal blocking, which performs several steps on each tile and so obtains more reuse, and we measure it as well.
This chapter covers
- how many times the direct kernel reads each value of the grid
- tiles, halo cells, and the 2 standard ways of loading a halo
- the barrier between loading and computing, and the wrong values without it
- a missing halo and the wrong values it produces
- a proof that the tiled kernel computes the same grid as the direct one
- loads per result as a function of the tile size, \((T + 2)^2 / T^2\)
- why tiling a 5-point stencil gains little on GPUs with large caches
- temporal blocking: several steps per load, and how its halo grows
The code of the chapter is in
code/oxide/ch20_stencil_tiled/
for Rust and in
code/cuda/ch20_stencil_tiled/
for C++. We use the notation of Chapter 19: \(u\) is the old grid that a step reads, \(v\) the
new grid that it writes, \(W\) and \(H\) are the width and height of the grid, and \([a, b)\)
is the range of integers from \(a\) to \(b - 1\).
20.1 Counting the reads
20.1.1 The plate and the direct kernel
We use the plate of Chapter 19, which has 6 × 6 cells, with the top edge held at 100 and the other edges at 0. Consider step 2, which reads the grid after step 1 and writes the grid of step 2. In the grid after step 1, row 1 holds 25 and every other interior cell holds 0. Recall that in the direct kernel of Chapter 19, the thread of each interior cell \((r, c)\) reads the 4 values \(u_{r-1,c}\), \(u_{r+1,c}\), \(u_{r,c-1}\) and \(u_{r,c+1}\) from global memory, which are the values above, below, to the left and to the right of the cell, and writes their mean. For example, the thread of cell (2, 2) reads 25, 0, 0 and 0 and writes 6.25.
20.1.2 Each value is read by its neighbors
So far, we have counted the reads of 1 thread. To find the repetition, we now count the other way round and ask, for 1 value of the old grid, how many threads read it. The value \(u_{2,2}\) is a neighbor of the cells (1, 2), (3, 2), (2, 1) and (2, 3). All 4 of them are interior cells, so 4 threads read \(u_{2,2}\), and each of them fetches it from global memory on its own, as shown in Figure 20.1. A value next to the boundary is read fewer times, because some of its neighbors are boundary cells, which have no thread that computes them. Thus \(u_{1,1}\) is read by 2 threads, \(u_{1,2}\) by 3, and a boundary value such as \(u_{0,2} = 100\) by 1.
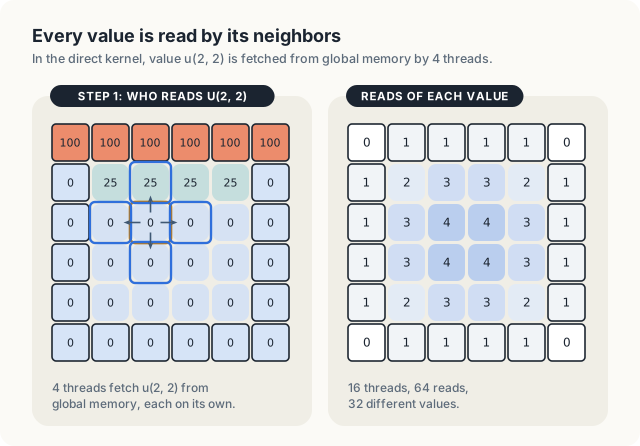
Let us add up these counts over the whole plate. The 4 center values are read 4 times each, and the 8 other values along the edges of the interior are read 3 times each. The 4 corners of the interior are read 2 times each, and the 16 boundary values next to the interior are read once each. In total, the step makes \(16 + 24 + 8 + 16 = 64\) reads of 32 different values. On a large grid, nearly every value lies far from the boundary, so the direct kernel fetches nearly every value 4 times. A step on a 4096 × 4096 grid thus requests 67 million values, or 268 MB, to read 16.7 million different values, or 67 MB.
Key observation The 4 threads that read \(u_{2,2}\) compute 4 neighboring cells. If those threads belong to the same block, one of them can copy \(u_{2,2}\) into shared memory, and the other 3 can read it from there.
In Chapter 19, we found that the caches already serve many of these repeated reads. The tile makes the reuse explicit instead of leaving it to the caches, and we measure the difference between the 2 in Section 20.7.
Exercises
20.1 How many threads read \(u_{3,1}\) in a step of the plate? Which ones?
20.2 For a grid of \(W \times H\) cells, how many reads does a step of the direct kernel make,
and how many different values does it read?
20.2 Tiles and halos
20.2.1 The cells a block needs
To turn the observation into an algorithm, we divide the plate among blocks. For the worked example, we use blocks of \(2 \times 2\) threads with one thread per cell, so the 6 × 6 cells need \(3 \times 3 = 9\) blocks. The programs use blocks of 32 × 8 threads, and everything below carries over to them. We follow block (1, 1), which computes the 4 center cells (2, 2), (2, 3), (3, 2) and (3, 3), as shown in Figure 20.2.
To compute its 4 cells, block (1, 1) needs their neighbors. Some of these neighbors are the block’s own cells; cell (2, 2), for example, has cells (2, 3) and (3, 2) as neighbors. The others lie directly above, below, to the left and to the right of the block’s square, such as cell (1, 2) above cell (2, 2), and they belong to the 4 neighboring blocks. The block copies all of these values into shared memory once. The simplest arrangement copies the whole square of rows 1 to 4 and columns 1 to 4, which holds 16 values. Of these, the 4 corner values (1, 1), (1, 4), (4, 1) and (4, 4) are copied but never read, because a 5-point stencil does not use diagonal neighbors.
Definition 20.1 Shared memory. Shared memory is a memory on each SM that belongs to 1 block. Every thread of the block can read and write it, no other thread can, it responds within a few cycles, and values enter it only when the threads of the block store them there.
Example. The block of 32 × 8 threads in our programs keeps a tile of 34 × 10 floats, 1,360 bytes, in shared memory.
Definition 20.2 Tile and halo. A block that computes a \(\mathsf{blockDim{.}y} \times \mathsf{blockDim{.}x}\) square of cells keeps a tile in shared memory: the \((\mathsf{blockDim{.}y} + 2) \times (\mathsf{blockDim{.}x} + 2)\) square of old values made of its own cells and a ring of cells 1 cell wide around them. The cells of the ring are the halo of the block. Halo cells are read by the block but computed by its neighbors.
Example. Block (1, 1) of the plate has \(\mathsf{blockDim{.}x} = \mathsf{blockDim{.}y} = 2\). Its tile covers rows 1 to 4 and columns 1 to 4: 4 own cells and 12 halo cells, of which 4 are corners that the 5-point stencil does not read.
Here \(\mathsf{blockDim{.}x}\) is the number of cells that a block computes along a row, and \(\mathsf{blockDim{.}y}\) the number along a column. The ring adds 1 cell on each of the two sides, which explains the 2 in \(\mathsf{blockDim{.}x} + 2\) and \(\mathsf{blockDim{.}y} + 2\). For the blocks of our programs, \(\mathsf{blockDim{.}x} = 32\) and \(\mathsf{blockDim{.}y} = 8\), so the tile is \(34 \times 10\), the size given in the example of Definition 20.1.
Next, we need to know where each cell sits inside the tile. Let \((\mathsf{top}, \mathsf{left})\) be the first cell of the block, that is, its upper-left own cell. The tile starts 1 row above and 1 column to the left of this cell, at cell \((\mathsf{top} - 1, \mathsf{left} - 1)\). The block’s cell \((\mathsf{row}, \mathsf{col})\) therefore lies at tile position
\[ (row - top + 1,\; col - left + 1). \]
| Symbol | Meaning | Block (1, 1), cell (2, 2) |
|---|---|---|
| \(\mathsf{top}, \mathsf{left}\) | row and column of the block’s first own cell | 2, 2 |
| \(\mathsf{row}, \mathsf{col}\) | row and column of a cell of the grid | 2, 2 |
| \(\mathsf{row} - \mathsf{top} + 1\) | row of the cell inside the tile | \(2 - 2 + 1 = 1\) |
| \(\mathsf{col} - \mathsf{left} + 1\) | column of the cell inside the tile | \(2 - 2 + 1 = 1\) |
The 4 neighbors of the cell lie 1 position above, below, to the left and to the right of it in the tile. In block (1, 1), cell (2, 2) thus sits at tile position (1, 1), and its upper neighbor, cell (1, 2), sits at tile position \((1 - 2 + 1, 2 - 2 + 1) = (0, 1)\).
20.2.2 Computing from the tile
Figure 20.3 shows the tile of block (1, 1) in step 2. It holds the old values of rows 1 to 4 of the plate. Its top row is row 1 of the plate and holds 25, and its other rows hold 0. The thread of cell (2, 2) reads its 4 neighbors from the tile positions (0, 1), (2, 1), (1, 0) and (1, 2). It obtains 25, 0, 0 and 0, which are the same values that it read from global memory in the direct kernel, and it writes 6.25.
Exercises
20.3 Which cells does the tile of block (0, 1) cover? Which of its slots lie outside the plate?
20.4 At which tile position does cell (3, 3) of block (1, 1) sit, and from which positions does
it read its neighbors?
20.3 Loading the halo
20.3.1 More slots than threads
We call each position of the tile a slot. In the tiled matrix product of Chapter 17, a tile had exactly as many slots as the block had threads, so each thread copied 1 value. A stencil tile has more. A block of \(\mathsf{blockDim{.}x} \times \mathsf{blockDim{.}y}\) threads must fill \((\mathsf{blockDim{.}x} + 2)(\mathsf{blockDim{.}y} + 2)\) slots. Block (1, 1) of our example has 4 threads and 16 slots, and a block of 32 × 8 threads has 256 threads and \(34 \times 10 = 340\) slots. There are 2 standard ways to close this gap, which are shown in Figure 20.4.
Extra threads. In the first way, the block is given one thread per slot, that is, \((\mathsf{blockDim{.}x} + 2) \times (\mathsf{blockDim{.}y} + 2)\) threads. We let every thread load the slot at its own position, and after the barrier, only the \(\mathsf{blockDim{.}x} \times \mathsf{blockDim{.}y}\) inner threads compute a cell. For block (1, 1), this means 16 threads, of which 12 only load. In the programs, it means 34 × 10 = 340 threads, of which 256 compute. The loading is a single statement per thread, but 84 of the 340 threads are idle while the others compute.
A loading loop. In the second way, the block keeps one thread per computed cell, and each thread loads several slots. Recall that \((\mathsf{threadIdx{.}y}, \mathsf{threadIdx{.}x})\) gives the row and column of a thread within its block. Thread \((\mathsf{threadIdx{.}y}, \mathsf{threadIdx{.}x})\) starts at slot \((\mathsf{threadIdx{.}y}, \mathsf{threadIdx{.}x})\) and moves down the tile in strides of \(\mathsf{blockDim{.}y}\) rows and across it in strides of \(\mathsf{blockDim{.}x}\) columns, loading every slot that it lands on, as long as the slot lies in the tile. Its rows are therefore \(\mathsf{threadIdx{.}y}, \mathsf{threadIdx{.}y} + \mathsf{blockDim{.}y}, \mathsf{threadIdx{.}y} + 2 \cdot \mathsf{blockDim{.}y}, \ldots\), and its columns are \(\mathsf{threadIdx{.}x}, \mathsf{threadIdx{.}x} + \mathsf{blockDim{.}x}, \mathsf{threadIdx{.}x} + 2 \cdot \mathsf{blockDim{.}x}, \ldots\). In the notation of modular arithmetic, these are the slots with
\[ \mathsf{slotRow} \equiv \mathsf{threadIdx{.}y} \pmod{\mathsf{blockDim{.}y}}, \qquad \mathsf{slotCol} \equiv \mathsf{threadIdx{.}x} \pmod{\mathsf{blockDim{.}x}}. \]
| Symbol | Meaning | Thread (0, 0) of block (1, 1) |
|---|---|---|
| \(\mathsf{threadIdx{.}y}, \mathsf{threadIdx{.}x}\) | row and column of the thread within its block | 0, 0 |
| \((\mathsf{slotRow}, \mathsf{slotCol})\) | row and column of a slot of the tile | (0, 0), (0, 2), (2, 0), (2, 2) |
| \(\mathsf{slotRow} \equiv \mathsf{threadIdx{.}y} \pmod{\mathsf{blockDim{.}y}}\) | \(\mathsf{slotRow}\) leaves the remainder \(\mathsf{threadIdx{.}y}\) when divided by \(\mathsf{blockDim{.}y}\) | \(\mathsf{slotRow} = 0\) or \(2\), with \(\mathsf{blockDim{.}y} = 2\) |
| \(\mathsf{slotCol} \equiv \mathsf{threadIdx{.}x} \pmod{\mathsf{blockDim{.}x}}\) | \(\mathsf{slotCol}\) leaves the remainder \(\mathsf{threadIdx{.}x}\) when divided by \(\mathsf{blockDim{.}x}\) | \(\mathsf{slotCol} = 0\) or \(2\), with \(\mathsf{blockDim{.}x} = 2\) |
In block (1, 1), thread (0, 0) therefore loads the slots (0, 0), (0, 2), (2, 0) and (2, 2), and in the same way each of the 4 threads loads 4 slots. With 32 × 8 threads and a tile of 34 × 10 slots, the counts are less even. The row \(\mathsf{slotRow}\) takes the value \(\mathsf{threadIdx{.}y}\), and also \(\mathsf{threadIdx{.}y} + 8\) when \(\mathsf{threadIdx{.}y} < 2\), since the tile has only 10 rows. The column \(\mathsf{slotCol}\) takes the value \(\mathsf{threadIdx{.}x}\), and also \(\mathsf{threadIdx{.}x} + 32\) when \(\mathsf{threadIdx{.}x} < 2\), since the tile has only 34 columns. As a result, 180 threads load 1 slot, 72 threads load 2 slots, and 4 threads load 4 slots, which accounts for all \(180 + 144 + 16 = 340\) slots. We let every thread compute a cell, but a few threads load more slots than the rest.
Both ways give every slot exactly 1 loading thread, which is what the correctness proof of Section 20.5 needs. They differ in cost, and we measure both in Section 20.7.
20.3.2 Slots outside the grid
A block on the edge of the grid has slots that lie outside the grid. Block (0, 0) of the plate, for example, computes the cells (0, 0) to (1, 1), and its tile covers rows −1 to 2 and columns −1 to 2. The loader stores 0 in a slot outside the grid instead of reading it from memory. No thread ever reads such a slot, because only interior cells are computed, and every neighbor of an interior cell lies inside the grid.
Exercises
20.5 With the loading loop and blocks of 32 × 8 threads, which slots does thread (1, 0) load? And
thread (5, 20)?
20.6 For blocks of 16 × 16 threads, how many slots does the tile have, and how many threads load
2 slots with the loading loop?
20.4 The tiled algorithm
20.4.1 The barrier
The threads of a block do not move in lockstep. A thread may finish its own loads early and start to compute while another thread is still loading a slot that the first thread needs. In block (1, 1), for example, the thread of cell (2, 2) needs tile position (0, 1), which another thread loads. The block therefore needs a point in the kernel at which all of its threads meet before any of them continues.
Definition 20.3 Barrier. A barrier is a point in a kernel
that no thread of a block may pass until every thread of the block has reached it. In CUDA C++, a
barrier is __syncthreads(); in cuda-oxide, it is thread::sync_threads(). Writes to shared memory
made before the barrier are visible to every thread of the block after it.
Example. In the tiled kernel, the thread of cell (2, 2) waits at the barrier until the thread that loads tile position (0, 1) has stored 25 there.
20.4.2 The kernel
Every thread executes the following procedure, which is written with the loading loop. With extra threads, lines 3 to 7 become a single load, and the condition of line 13 also requires an inner thread.
Tiled-Jacobi-Kernel(\(u, v, W, H\))
- \(\mathsf{top} = \mathsf{blockIdx{.}y} \cdot \mathsf{blockDim{.}y}\)
- \(\mathsf{left} = \mathsf{blockIdx{.}x} \cdot \mathsf{blockDim{.}x}\)
- for \(\mathsf{slotRow} \in [\mathsf{threadIdx{.}y}, \mathsf{blockDim{.}y} + 2)\) stride \(\mathsf{blockDim{.}y}\) {
- for \(\mathsf{slotCol} \in [\mathsf{threadIdx{.}x}, \mathsf{blockDim{.}x} + 2)\) stride \(\mathsf{blockDim{.}x}\) {
- \(\mathsf{tile}[\mathsf{slotRow}][\mathsf{slotCol}] = u_{\mathsf{top}+\mathsf{slotRow}-1,\, \mathsf{left}+\mathsf{slotCol}-1}\) if that cell is in the grid, else 0
- }
- }
- Barrier() // wait until the whole tile is loaded
- \(\mathsf{row} = \mathsf{top} + \mathsf{threadIdx{.}y}\)
- \(\mathsf{col} = \mathsf{left} + \mathsf{threadIdx{.}x}\)
- \(\mathsf{centerRow} = \mathsf{threadIdx{.}y} + 1\) // the slot of the cell itself
- \(\mathsf{centerCol} = \mathsf{threadIdx{.}x} + 1\)
- if \(\mathsf{row} \in [1, H - 1)\) and \(\mathsf{col} \in [1, W - 1)\) {
- \(\mathsf{up} = \mathsf{tile}[\mathsf{centerRow} - 1][\mathsf{centerCol}]\)
- \(\mathsf{down} = \mathsf{tile}[\mathsf{centerRow} + 1][\mathsf{centerCol}]\)
- \(\mathsf{toLeft} = \mathsf{tile}[\mathsf{centerRow}][\mathsf{centerCol} - 1]\)
- \(\mathsf{toRight} = \mathsf{tile}[\mathsf{centerRow}][\mathsf{centerCol} + 1]\)
- \(v_{\mathsf{row},\mathsf{col}} = (\mathsf{up} + \mathsf{down} + \mathsf{toLeft} + \mathsf{toRight}) / 4\)
- }
Lines 1 and 2 compute the first own cell \((\mathsf{top}, \mathsf{left})\) of the block. For block (1, 1) of the plate, with blocks of 2 × 2 threads, they give \(\mathsf{top} = 1 \cdot 2 = 2\) and \(\mathsf{left} = 1 \cdot 2 = 2\). Lines 3 to 7 are the loading loop of Section 20.3.1. In line 5, slot \((\mathsf{slotRow}, \mathsf{slotCol})\) receives the cell \((\mathsf{top} + \mathsf{slotRow} - 1, \mathsf{left} + \mathsf{slotCol} - 1)\), because the tile begins 1 row above and 1 column to the left of the first own cell. For example, thread (0, 1) of block (1, 1) loads slot (0, 1) with the cell \((2 + 0 - 1, 2 + 1 - 1) = (1, 2)\), whose value in step 2 is 25. Line 8 is the barrier.
Lines 9 to 19 are Jacobi-Kernel of Chapter 19, with each read from \(u\) replaced by a read from the tile. Lines 9 and 10 compute the cell \((\mathsf{row}, \mathsf{col})\) of the thread, and lines 11 and 12 compute the slot \((\mathsf{centerRow}, \mathsf{centerCol})\) at which that cell sits in the tile, 1 row and 1 column past the thread’s own position. Lines 14 to 17 read the 4 neighbors around that slot, and line 18 writes their mean. For thread (0, 0) of block (1, 1), these are the positions (0, 1), (2, 1), (1, 0) and (1, 2) of Figure 20.3. Note that the barrier in line 8 lies outside every condition, so every thread of the block reaches it, including the threads whose cell is on the boundary or outside the grid. The host loop is unchanged from Chapter 19, with 2 buffers, 1 launch per step, and an exchange of the names after each launch.
Each block thus runs through 3 phases, in which it loads the tile, waits at the barrier, and computes its cells from the tile, as shown in Figure 20.5.
20.4.3 Counting the loads again
We can now count how much the tile saves. In the direct kernel, the 4 threads of block (1, 1) make \(4 \cdot 4 = 16\) reads from global memory, 4 per thread. With the tile, the block makes 16 loads, 1 per slot. For a 2 × 2 block, the tile therefore saves nothing, since \((2 + 2)^2 = 16 = 4 \cdot 2^2\). The halo is as large as the block itself in this case. As the block grows, however, its own cells grow with the square of its width, while the halo grows only with its perimeter, so the saving grows with the block.
In general, a block of \(T \times T\) threads makes \(4T^2\) reads in the direct kernel, 4 for each of its \(T^2\) threads, and \((T + 2)^2\) loads with a tile, 1 for each slot. The tile therefore divides the number of reads by
\[ \frac{4T^2}{(T + 2)^2}. \]
| Symbol | Meaning | \(T = 2\) | \(T = 16\) |
|---|---|---|---|
| \(T\) | width and height of the block, in threads | 2 | 16 |
| \(4T^2\) | reads of the direct kernel per block | 16 | 1,024 |
| \((T + 2)^2\) | loads of the tiled kernel per block | 16 | 324 |
| \(4T^2 / (T + 2)^2\) | factor by which the tile reduces the reads | 1 | 3.2 |
The factor is 1 for \(T = 2\), 1.8 for \(T = 4\), 2.6 for \(T = 8\) and 3.2 for \(T = 16\). It approaches 4, the number of reads per cell of the direct kernel, as the block grows. A block of 32 × 8 threads makes \(4 \cdot 256 = 1{,}024\) reads in the direct kernel and 340 loads with a tile, which is 3 times fewer.
It is often more useful to count the loads per computed cell, which we call the loads per result. A tile of a \(\mathsf{blockDim{.}x} \times \mathsf{blockDim{.}y}\) block loads \((\mathsf{blockDim{.}x} + 2)(\mathsf{blockDim{.}y} + 2)\) values for \(\mathsf{blockDim{.}x} \cdot \mathsf{blockDim{.}y}\) results, so it loads \((\mathsf{blockDim{.}x} + 2)(\mathsf{blockDim{.}y} + 2) / (\mathsf{blockDim{.}x} \cdot \mathsf{blockDim{.}y})\) values per result, as plotted in Figure 20.6. For the 32 × 8 block of the programs, this is \(340 / 256 = 1.33\). A value of 1 would mean that every value is loaded exactly once. The part above 1 is the halo overhead, which comes from the halo cells that 2 or more neighboring blocks each load for themselves. The following table gives both numbers for several block shapes.
| Block | Tile | Loads per result | Halo overhead |
|---|---|---|---|
| 2 × 2 | 4 × 4 | 16 / 4 = 4.00 | 300% |
| 4 × 4 | 6 × 6 | 36 / 16 = 2.25 | 125% |
| 8 × 8 | 10 × 10 | 100 / 64 = 1.56 | 56% |
| 16 × 16 | 18 × 18 | 324 / 256 = 1.27 | 27% |
| 32 × 8 | 34 × 10 | 340 / 256 = 1.33 | 33% |
| 32 × 32 | 34 × 34 | 1,156 / 1,024 = 1.13 | 13% |
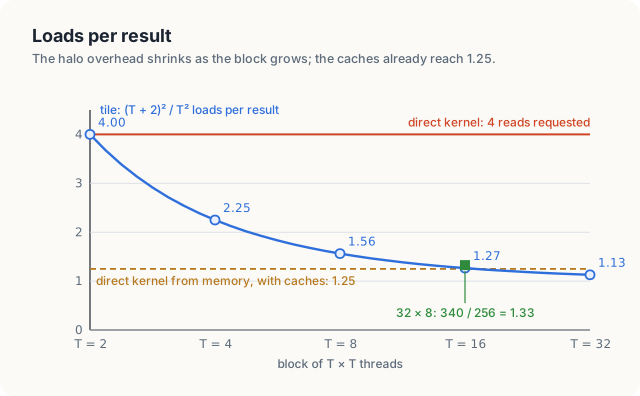
The largest block in the table would have the smallest overhead, but a block holds at most 1,024 threads. The extra-threads scheme therefore cannot serve a block that computes 32 × 32 cells, because its tile has 34 × 34 = 1,156 slots and would need 1,156 threads. Shared memory, on the other hand, is not the limit, since the 34 × 10 tile of the programs takes only 1,360 bytes. The 32 × 8 block that the programs use costs 1.33 loads per result, which is 3 times fewer than the 4 that the direct kernel requests.
Exercises
20.7 Compute the loads per result for blocks of 64 × 4 and 16 × 16 threads, both of 256 threads.
Which shape loads fewer halo cells per result?
20.8 A 2-D stencil of radius 2 reads the 2 nearest cells in each direction. How wide is its halo,
and how many loads per result does a 32 × 8 block make?
20.5 Correctness
Compared with the direct kernel, the tiled kernel adds 2 places where it can go wrong, the barrier and the halo. In this section, we remove each of them in turn, show the wrong value that the removal produces on the plate, and run the broken variant.
20.5.1 Without the barrier
Suppose that we delete line 8. In block (1, 1), loaded with the loop, the thread of cell (2, 2) is thread (0, 0). It needs tile position (0, 1), which holds the halo cell (1, 2) and is loaded by thread (0, 1). If thread (0, 0) finishes its own loads early and thread (0, 1) runs late, thread (0, 0) reads position (0, 1) before 25 has been stored there. The slot then holds whatever an earlier block left in that part of shared memory. If it holds 0, cell (2, 2) becomes \((0 + 0 + 0 + 0) / 4 = 0\) instead of 6.25, as shown in Figure 20.7.
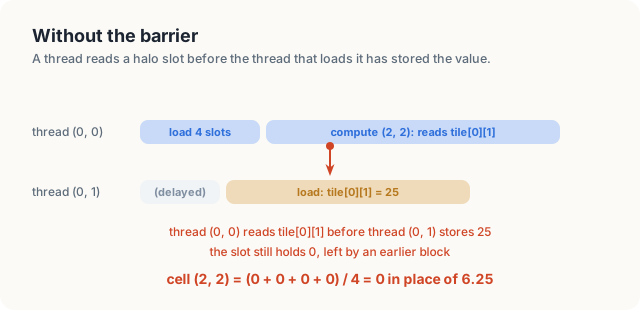
We ran the kernel of the programs, with 32 × 8 threads and the loading loop, without its barrier. It performed 1 step on the 4096 × 4096 plate after 200 correct steps, and we repeated this 3 times and compared each result with the result of the direct kernel. The program printed the following counts.
loop loader without barrier, 4096 x 4096, run 1: 126302 cells differ after 1 step
loop loader without barrier, 4096 x 4096, run 2: 124849 cells differ after 1 step
loop loader without barrier, 4096 x 4096, run 3: 124322 cells differ after 1 step
The count changes from run to run, because it depends on the timing of the threads. On the 6 × 6 plate with 2 × 2 blocks, the extra-threads kernel without its barrier gave the correct values in our runs. There, the 16 threads of each block belong to 1 warp, and they happened to finish their loads together. The error appears when the threads of a block span several warps, as they do in every block of practical size.
20.5.2 Without the halo
Suppose next that the loader copies only the block’s own cells, so that the halo slots stay at 0. In block (1, 1), cell (2, 2) then reads 0 above instead of 25, and it becomes 0 instead of 6.25. Cell (1, 1) belongs to block (0, 0), and its right neighbor (1, 2) belongs to block (0, 1). The halo slot of block (0, 0) that should hold cell (1, 2) therefore holds 0, and cell (1, 1) becomes \((100 + 0 + 0 + 0) / 4 = 25\) instead of 31.25. We ran this variant with 2 × 2 blocks on the plate, and it printed the following grid.
2 x 2 blocks, halo filled with 0, after step 2
100.00 100.00 100.00 100.00 100.00 100.00
0.00 25.00 31.25 31.25 25.00 0.00
0.00 0.00 0.00 0.00 0.00 0.00
0.00 0.00 0.00 0.00 0.00 0.00
0.00 0.00 0.00 0.00 0.00 0.00
0.00 0.00 0.00 0.00 0.00 0.00
In this grid, 8 of the 16 interior cells are wrong. Row 1 reads 25, 31.25, 31.25 and 25 instead of 31.25, 37.5, 37.5 and 31.25, and row 2 reads 0 instead of 6.25, as Figure 20.8 shows. Step 1 was still correct, because in step 1 every halo value that a computed cell reads is 0 in the correct grid as well. A test of 1 step would therefore have passed.
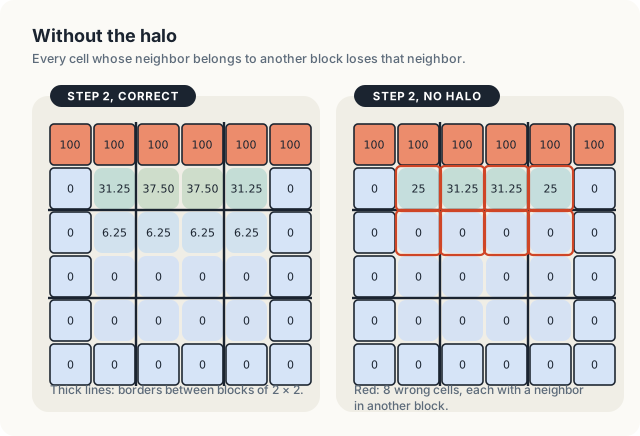
20.5.3 A proof of correctness
Having seen how each part of the kernel fails when it is removed, we now prove that the complete kernel computes exactly what the direct kernel computes.
Theorem 20.1 Launched on 2 different buffers \(u\) and \(v\), Tiled-Jacobi-Kernel writes the same value into every cell of \(v\) as Jacobi-Kernel of Chapter 19.
Proof. Fix a block with first cell \((\mathsf{top}, \mathsf{left})\). We show three facts.
Every slot is loaded once, with the old value. The loops of lines 3 to 7 let thread \((\mathsf{threadIdx{.}y}, \mathsf{threadIdx{.}x})\) store slot \((\mathsf{slotRow}, \mathsf{slotCol})\) exactly when \(\mathsf{slotRow} \equiv \mathsf{threadIdx{.}y} \pmod{\mathsf{blockDim{.}y}}\) and \(\mathsf{slotCol} \equiv \mathsf{threadIdx{.}x} \pmod{\mathsf{blockDim{.}x}}\). Each slot \((\mathsf{slotRow}, \mathsf{slotCol})\) of the \((\mathsf{blockDim{.}y} + 2) \times (\mathsf{blockDim{.}x} + 2)\) tile has exactly 1 such thread, namely \((\mathsf{slotRow} \bmod \mathsf{blockDim{.}y}, \mathsf{slotCol} \bmod \mathsf{blockDim{.}x})\). For example, with \(\mathsf{blockDim{.}x} = \mathsf{blockDim{.}y} = 2\), slot (2, 3) is stored by thread \((2 \bmod 2, 3 \bmod 2) = (0, 1)\). That thread stores \(u_{\mathsf{top}+\mathsf{slotRow}-1,\,\mathsf{left}+\mathsf{slotCol}-1}\) if the cell is in the grid. No thread of the launch writes \(u\), because \(u\) and \(v\) are different buffers, so the stored value is the old value.
Every load finishes before any read. The barrier of line 8 lies outside every condition, so every thread of the block reaches it. No thread passes it before all threads have finished lines 3 to 7, and their stores are then visible to the whole block. The tile is not written after line 8.
The reads are the right ones. Let \((\mathsf{row}, \mathsf{col}) = (\mathsf{top} + \mathsf{threadIdx{.}y}, \mathsf{left} + \mathsf{threadIdx{.}x})\) be an interior cell. Tile position \((\mathsf{threadIdx{.}y}, \mathsf{threadIdx{.}x} + 1)\) holds the cell \((\mathsf{top} + \mathsf{threadIdx{.}y} - 1, \mathsf{left} + \mathsf{threadIdx{.}x}) = (\mathsf{row} - 1, \mathsf{col})\), the upper neighbor; in the same way, \((\mathsf{threadIdx{.}y} + 2, \mathsf{threadIdx{.}x} + 1)\), \((\mathsf{threadIdx{.}y} + 1, \mathsf{threadIdx{.}x})\) and \((\mathsf{threadIdx{.}y} + 1, \mathsf{threadIdx{.}x} + 2)\) hold the lower, left and right neighbors. All 4 lie in the grid, because \((\mathsf{row}, \mathsf{col})\) is interior, so their slots hold old values and not the 0 of line 5. Line 18 therefore adds the same 4 values, in the same order, as line 4 of Jacobi-Kernel and writes the same result. Cells that are not interior are written by neither kernel.
Each broken variant of this section breaks 1 fact of the proof. Without the barrier, the second fact fails. Without the halo, the first fact fails for every halo slot, and the third fact then reads 0 where it needs a neighbor. Since the tiled kernel writes what the direct kernel writes, Theorem 19.1 carries over unchanged, and with 2 buffers used in turn, the tiled kernel computes Jacobi iteration.
Rule Every thread of the block must reach the barrier between loading the tile and reading it, and the tile must hold every cell that any thread of the block reads, the halo included.
Exercises
20.9 In the variant without the halo, compute cell (2, 1) after step 2 by hand.
20.10 Suppose the loading loop used slot_col < BLOCK_WIDTH + 1 instead of
slot_col < TILE_WIDTH. Which slots would stay
empty, and which cells of block (1, 1) of the plate would be wrong in step 2?
20.11 Why must a thread whose cell lies outside the grid still execute line 8?
20.6 Implementation
20.6.1 The kernel with a loading loop
Listing 20.1 implements Tiled-Jacobi-Kernel with blocks of 32 × 8 threads and a 34 × 10 tile. The
2 while loops in Rust and the 2 for loops in C++ are lines 3 to 7 of the pseudocode. The test
of line 5, whether a cell lies in the grid, is written differently in the two languages. Rust uses
wrapping_sub on unsigned positions. For the first block, top + slot_row - 1 is −1, which
wrapping_sub turns into the largest usize, so the test cell_row < height fails and the slot
receives 0. The C++ version computes signed positions and tests cell_row >= 0 as well. In both
languages, the barrier, thread::sync_threads() in Rust and __syncthreads() in C++, lies
outside every if.
Listing 20.1 One Jacobi step from a tile, loaded with a loop.
mod kernels {
// ...
/// 1 Jacobi step from a 34 x 10 tile; 32 x 8 threads load it, some 2 or 4 cells each.
#[kernel]
#[launch_contract(domain = 2, block = (32, 8, 1))]
pub fn jacobi_tiled(old: &[f32], mut new: DisjointSlice<f32, Runtime2DIndex>) {
const AREA: usize = TILE_WIDTH * TILE_HEIGHT;
static mut TILE: SharedArray<f32, AREA> = SharedArray::UNINIT;
let width = new.row_width() as usize;
let height = new.len() / width;
let thread_x = thread::threadIdx_x() as usize;
let thread_y = thread::threadIdx_y() as usize;
let top = thread::blockIdx_y() as usize * BLOCK_HEIGHT;
let left = thread::blockIdx_x() as usize * BLOCK_WIDTH;
let mut slot_row = thread_y;
while slot_row < TILE_HEIGHT {
let mut slot_col = thread_x;
while slot_col < TILE_WIDTH {
let cell_row = (top + slot_row).wrapping_sub(1);
let cell_col = (left + slot_col).wrapping_sub(1);
let inside = cell_row < height && cell_col < width;
let value = if inside { old[cell_row * width + cell_col] } else { 0.0 };
// SAFETY: slot (slot_row, slot_col) is written by 1 thread alone,
// the thread (slot_row mod 8, slot_col mod 32).
unsafe { TILE[slot_row * TILE_WIDTH + slot_col] = value };
slot_col += BLOCK_WIDTH;
}
slot_row += BLOCK_HEIGHT;
}
thread::sync_threads();
if let Some(idx) = thread::index_2d_runtime(&new) {
let (row, col) = (idx.row(), idx.col());
let interior = row >= 1 && row + 1 < height && col >= 1 && col + 1 < width;
if interior {
let center = (thread_y + 1) * TILE_WIDTH + thread_x + 1;
// SAFETY: after the barrier no thread writes the tile.
let up = unsafe { TILE[center - TILE_WIDTH] };
// SAFETY: as above.
let down = unsafe { TILE[center + TILE_WIDTH] };
// SAFETY: as above.
let (to_left, to_right) = unsafe { (TILE[center - 1], TILE[center + 1]) };
let sum = up + down + to_left + to_right;
if let Some(cell) = new.get_mut(idx) {
*cell = 0.25 * sum;
}
}
}
}
// ...
}// 1 Jacobi step from a 34 x 10 tile; 32 x 8 threads load it, some 2 or 4 cells each.
__global__ void jacobiTiled(const float* __restrict__ old, float* __restrict__ next,
int width, int height)
{
__shared__ float tile[TILE_HEIGHT][TILE_WIDTH];
int top = blockIdx.y * BLOCK_HEIGHT;
int left = blockIdx.x * BLOCK_WIDTH;
for (int slot_row = threadIdx.y; slot_row < TILE_HEIGHT; slot_row += BLOCK_HEIGHT) {
for (int slot_col = threadIdx.x; slot_col < TILE_WIDTH; slot_col += BLOCK_WIDTH) {
int cell_row = top + slot_row - 1;
int cell_col = left + slot_col - 1;
bool row_inside = cell_row >= 0 && cell_row < height;
bool col_inside = cell_col >= 0 && cell_col < width;
int cell = cell_row * width + cell_col;
tile[slot_row][slot_col] = row_inside && col_inside ? old[cell] : 0.0f;
}
}
__syncthreads();
int row = top + threadIdx.y;
int col = left + threadIdx.x;
bool interior = row >= 1 && row + 1 < height && col >= 1 && col + 1 < width;
if (interior) {
int center_row = threadIdx.y + 1;
int center_col = threadIdx.x + 1;
float up = tile[center_row - 1][center_col];
float down = tile[center_row + 1][center_col];
float to_left = tile[center_row][center_col - 1];
float to_right = tile[center_row][center_col + 1];
next[row * width + col] = 0.25f * (up + down + to_left + to_right);
}
}
The tile is declared differently in the two languages. In C++, __shared__ float tile[TILE_HEIGHT][TILE_WIDTH] is a
2-D array, and tile[center_row - 1][center_col] reads it like any other array. In Rust, the tile
is a static mut TILE: SharedArray<f32, AREA>, a flat array of 340 floats with 1 copy per
block, and slot \((\mathsf{slotRow}, \mathsf{slotCol})\) is element
slot_row * TILE_WIDTH + slot_col. Every access to it is unsafe, because the
compiler cannot check how the threads of a block share a static. Each unsafe block therefore
carries a // SAFETY: comment that states why it is sound, and the 2 comments are the first 2
facts of the proof of Theorem 20.1: each slot has 1 writer, and after the barrier the tile is only
read. The final write needs no unsafe block. As in Chapter 19, the thread writes its own cell
through get_mut of the DisjointSlice.
20.6.2 The kernel with extra threads
Listing 20.2 performs the same step with 34 × 10 threads per block, one thread per slot. Each thread loads 1 slot, all threads wait at the barrier, and only the 32 × 8 inner threads compute a cell.
Listing 20.2 One Jacobi step from a tile, loaded by one thread per slot.
mod kernels {
// ...
/// 1 Jacobi step from a 34 x 10 tile; 34 x 10 threads load 1 cell each, 32 x 8 compute.
#[kernel]
#[launch_contract(domain = 2, block = (34, 10, 1))]
pub fn jacobi_halo_threads(old: &[f32], mut new: DisjointSlice<f32, Runtime2DIndex>) {
const AREA: usize = TILE_WIDTH * TILE_HEIGHT;
static mut TILE: SharedArray<f32, AREA> = SharedArray::UNINIT;
let width = new.row_width() as usize;
let height = new.len() / width;
let slot_col = thread::threadIdx_x() as usize;
let slot_row = thread::threadIdx_y() as usize;
let row = (thread::blockIdx_y() as usize * BLOCK_HEIGHT + slot_row).wrapping_sub(1);
let col = (thread::blockIdx_x() as usize * BLOCK_WIDTH + slot_col).wrapping_sub(1);
let slot = slot_row * TILE_WIDTH + slot_col;
let value = if row < height && col < width { old[row * width + col] } else { 0.0 };
// SAFETY: the slot belongs to this thread alone.
unsafe { TILE[slot] = value };
thread::sync_threads();
let inner_row = slot_row >= 1 && slot_row <= BLOCK_HEIGHT;
let inner_col = slot_col >= 1 && slot_col <= BLOCK_WIDTH;
let interior = row >= 1 && row + 1 < height && col >= 1 && col + 1 < width;
if inner_row && inner_col && interior {
// SAFETY: after the barrier no thread writes the tile.
let (up, down) = unsafe { (TILE[slot - TILE_WIDTH], TILE[slot + TILE_WIDTH]) };
// SAFETY: as above.
let (to_left, to_right) = unsafe { (TILE[slot - 1], TILE[slot + 1]) };
let sum = up + down + to_left + to_right;
// SAFETY: the inner threads of the blocks cover each cell of the grid once,
// so no other thread writes cell (row, col), which lies inside `new`.
unsafe { *new.get_unchecked_mut(row * width + col) = 0.25 * sum };
}
}
// ...
}// 1 Jacobi step from a 34 x 10 tile; 34 x 10 threads load 1 cell each, 32 x 8 compute.
__global__ void jacobiHaloThreads(const float* __restrict__ old, float* __restrict__ next,
int width, int height)
{
__shared__ float tile[TILE_HEIGHT][TILE_WIDTH];
int slot_row = threadIdx.y;
int slot_col = threadIdx.x;
int row = blockIdx.y * BLOCK_HEIGHT + slot_row - 1;
int col = blockIdx.x * BLOCK_WIDTH + slot_col - 1;
bool inside = row >= 0 && row < height && col >= 0 && col < width;
tile[slot_row][slot_col] = inside ? old[row * width + col] : 0.0f;
__syncthreads();
bool inner_row = slot_row >= 1 && slot_row <= BLOCK_HEIGHT;
bool inner_col = slot_col >= 1 && slot_col <= BLOCK_WIDTH;
bool interior = row >= 1 && row + 1 < height && col >= 1 && col + 1 < width;
if (inner_row && inner_col && interior) {
float up = tile[slot_row - 1][slot_col];
float down = tile[slot_row + 1][slot_col];
float to_left = tile[slot_row][slot_col - 1];
float to_right = tile[slot_row][slot_col + 1];
next[row * width + col] = 0.25f * (up + down + to_left + to_right);
}
}
In this kernel, the thread at position \((\mathsf{threadIdx{.}y}, \mathsf{threadIdx{.}x})\) of the block no longer owns cell
\((\mathsf{top} + \mathsf{threadIdx{.}y}, \mathsf{left} + \mathsf{threadIdx{.}x})\). Instead, it owns slot \((\mathsf{threadIdx{.}y}, \mathsf{threadIdx{.}x})\), which holds cell
\((\mathsf{top} + \mathsf{threadIdx{.}y} - 1, \mathsf{left} + \mathsf{threadIdx{.}x} - 1)\). Thread (0, 0), for example, owns the corner slot of the halo,
and thread (1, 1) owns the block’s first own cell \((\mathsf{top}, \mathsf{left})\). The launch contract of the
Rust kernel states the new block shape, block = (34, 10, 1). Because the thread’s position is no
longer its cell, index_2d_runtime and get_mut no longer apply, and the Rust kernel writes with
get_unchecked_mut(row * width + col). Its // SAFETY: comment gives the argument that the type
system gave before: the inner threads of the blocks cover each cell exactly once, so no 2 threads
write the same element. The C++ kernel writes next[row * width + col] and relies on the same
argument without stating it.
20.6.3 The 6 × 6 plate
Both programs run each tiled kernel on the plate and compare its result, bit for bit, with the result of the direct kernel. The Rust program prints the following output.
$ cargo oxide run
GPU: Orin, 8 SMs
1. 6 x 6 plate, top edge at 100
after step 2, tiled
100.00 100.00 100.00 100.00 100.00 100.00
0.00 31.25 37.50 37.50 31.25 0.00
0.00 6.25 6.25 6.25 6.25 0.00
0.00 0.00 0.00 0.00 0.00 0.00
0.00 0.00 0.00 0.00 0.00 0.00
0.00 0.00 0.00 0.00 0.00 0.00
loop loader same bits as the plain kernel after 4 steps: true
extra threads same bits as the plain kernel after 4 steps: true
4 steps per load same bits as the plain kernel after 4 steps: true
The grid after step 2 agrees with the values of Chapter 19, and all 3 tiled kernels agree with the
direct kernel in every bit. The third kernel, 4 steps per load, is the subject of Section 20.8.
Exercises
20.12 Rewrite the loading loop of Listing 20.1 as a single loop over the slot number
\(k = \mathsf{threadIdx{.}y} \cdot 32 + \mathsf{threadIdx{.}x}, k + 256, \ldots\), with \(\mathsf{slotRow} = k / 34\) and \(\mathsf{slotCol} = k \bmod 34\). Which
threads now load 2 slots? Measure the two versions.
20.13 In the Rust extra-threads kernel, which fact of the proof of Theorem 20.1 does the
// SAFETY: comment of the final write rely on?
20.7 Measurements
20.7.1 Results
The measurements come from a Jetson Orin NX, an integrated GPU with 8 SMs and 102 GB/s of memory bandwidth. Both programs time each kernel on a 4096 × 4096 plate after 0.4 s of warm-up and average 50 launches. They report the effective bandwidth of Chapter 19, that is, 8 bytes per cell per step divided by the time of a step. Repeated runs differ by 10 to 20%. On the measured GPU, the C++ program printed the following results.
2. 4096 x 4096 plate, 8 bytes per cell per step (1 read, 1 write)
copy kernel 1.752 ms 76.6 GB/s
plain 1.966 ms 68.3 GB/s
loop loader 3.089 ms 43.4 GB/s
extra threads 2.931 ms 45.8 GB/s
4 steps per load 2.112 ms 63.5 GB/s
loop loader same bits as the plain kernel after 8 steps: true
extra threads same bits as the plain kernel after 8 steps: true
4 steps per load same bits as the plain kernel after 8 steps: true
PASSED
The following table collects these results together with those of the Rust program, and adds the number of global loads per result of each kernel.
| Kernel | Global loads per result | C++ | Rust |
|---|---|---|---|
| copy | 1 | 76.6 GB/s | 75.0 GB/s |
| direct (plain) | 4 requested, about 1.25 from memory | 68.3 GB/s | 58.0 GB/s |
| tiled, loading loop | 1.33 | 43.4 GB/s | 34.6 GB/s |
| tiled, extra threads | 1.33 | 45.8 GB/s | 39.2 GB/s |
| 4 steps per load (Section 20.8) | 0.44 per step | 63.5 GB/s | 54.3 GB/s |
The tiled kernels load 3 times fewer values than the direct kernel requests, yet they run at 64% and 67% of its speed in C++, and at 60% and 68% in Rust. In other words, the tile made the kernel slower, not faster. The Rust kernels are slower than the C++ kernels throughout, for the reason measured in Section 19.8.4: they compute positions in 64-bit integers and derive the height with a division.
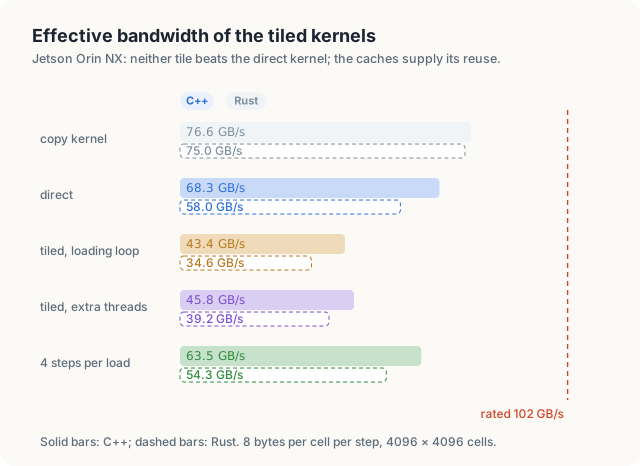
20.7.2 Why the tile gains nothing here
Recall from Section 19.8.3 that the direct kernel already moves only about 9 bytes per cell from memory, namely 1.25 reads and 1 write, and that it runs within 12% of a copy. The 4 reads per cell that the direct kernel requests are mostly answered by the L1 and L2 caches, which keep the rows that neighboring warps share (Figure 19.11). The tile loads 1.33 values per result, 340 cells for 256 results, and with the write, this amounts to \(4 \cdot 1.33 + 4 = 9.3\) bytes per cell. The direct kernel already moves this much or less. A tile can remove only the traffic that reaches memory, and in this case, the caches have already removed it.
Two further measurements support this explanation. First, we bypassed the L1 cache in the direct
kernel by reading each neighbor with the C++ intrinsic __ldcg, which reads through the L2 cache
only. The kernel then ran at 61.4 to 63.7 GB/s, which is 7 to 10% slower. The L2 cache alone thus
captures most of the reuse, since the 2 MiB L2 of the measured GPU holds the few rows that the
blocks running at the same time share. Second, the tile is not free. The tiled kernels compute a
tile position for every slot, store the value to shared memory and read it back, and wait at a
barrier. During the wait, a warp that has finished its loads issues no instructions. When we
deleted the barrier from the loop loader, which gives wrong results, its time fell from 3.10 ms to
2.83 ms, so the barrier alone costs about 9%. The remaining difference from the direct kernel is
instructions. The loading loop runs 1 or 2 iterations per thread with a test at each, and the
extra-threads kernel keeps 84 of its 340 threads idle while the others compute.
The result depends on the GPU. On a GPU whose caches are small compared with the number of threads in flight, or that does not cache global loads in L1, the 4 reads per cell of the direct kernel reach memory, and the tile’s 1.33 loads per result reduce the traffic 3-fold. On the measured GPU, the caches capture the reuse of a 5-point stencil, and the tile only adds work. A stencil with more reuse per value leaves more for the tile to capture. Examples are a 3-D stencil of radius 4, which reads 25 values per result, and a kernel that performs several steps on 1 tile. We measure the second in the next section.
Exercises
20.14 The extra-threads kernel launches 340 threads per block. How many warps is that, and how many
threads of its last warp have no slot?
20.15 Estimate the time of the tiled kernel from its traffic alone, 9.3 bytes per cell at the
copy’s rate. How much of the measured 3.089 ms is not explained by traffic?
20.8 Temporal blocking
20.8.1 Several steps per load
In Section 20.7, we saw that a single step reuses each value too little for the tile to pay. We can increase the reuse by letting a block perform more than 1 step on the values that it has loaded. The tile holds a block’s cells and their neighbors, which is exactly what 1 step of the block’s cells needs. If the tile had 1 more ring of halo, it would hold everything needed to compute 2 steps of the block’s cells. The first step would be computed on the block’s cells and on the inner ring of the halo, and the second step on the block’s cells alone, from the values of the first. In general, \(K\) steps need a halo \(K\) cells wide, because each step can compute correct values only 1 ring further in than the step before.
Definition 20.4 Temporal blocking. In temporal blocking, a block loads a tile with a halo \(K\) cells wide, performs \(K\) steps on it in shared memory, and writes only its own cells after the last step. After the step with number \(\mathsf{step}\), the values are correct on the tile without its outer \(\mathsf{step}\) rings.
Example. Our programs use a tile of 32 × 32 threads with \(K = 4\). The tile holds a 24 × 24 square of the block’s own cells and a halo 4 cells wide; after steps 1, 2, 3 and 4 the correct region is 30 × 30, 28 × 28, 26 × 26 and 24 × 24.
In this section, \(K\) is the number of steps per load and \(\mathsf{step}\) the number of the step inside the tile, from 1 to \(K\). In the example, the 32 × 32 tile loses 1 ring on each of its 4 sides in every step, so its correct region shrinks by 2 cells in each direction per step, from 32 to 30, 28, 26 and finally \(32 - 2 \cdot 4 = 24\) cells. The block’s own cells are the \(24 \times 24\) square that remains after 4 steps.
The steps inside the tile need 2 buffers, for the same reason as in Chapter 19: a step must not overwrite a value that another thread of the same step still has to read. The kernel therefore keeps 2 tiles in shared memory and uses them in turn, with a barrier between steps. This is ping-pong buffering in shared memory. Figure 20.10 shows the 2 tiles and the correct region that shrinks from step to step.
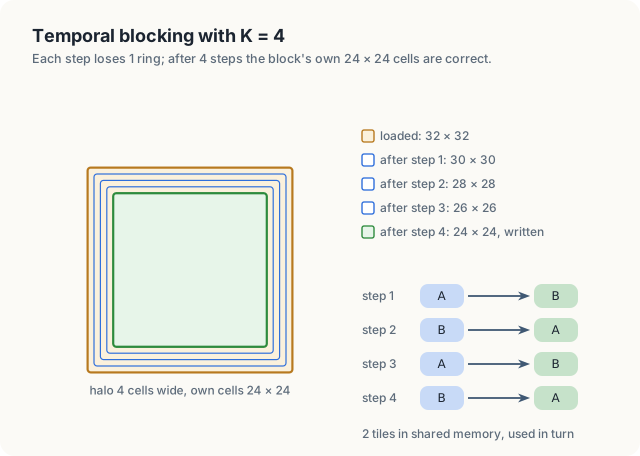
Every thread executes the following procedure. Each of the 32 × 32 threads owns 1 slot of the tile, and \(A\) and \(B\) are the 2 tiles in shared memory.
Temporal-Jacobi-Kernel(\(u, v, W, H\))
- \((\mathsf{row}, \mathsf{col})\) = cell of this thread, \(K\) cells before the block's first own cell
- \(A[\mathsf{threadIdx{.}y}][\mathsf{threadIdx{.}x}] = u_{\mathsf{row},\mathsf{col}}\) if \((\mathsf{row}, \mathsf{col})\) is in the grid, else 0
- Barrier()
- for \(\mathsf{step} \in [1, K]\) { // src = A, dst = B for odd steps, the reverse for even steps
- if \(\mathsf{threadIdx{.}x}, \mathsf{threadIdx{.}y} \in [\mathsf{step}, 32 - \mathsf{step})\) {
- \(\mathsf{dst}[\mathsf{threadIdx{.}y}][\mathsf{threadIdx{.}x}]\) = mean of the 4 neighbors in \(\mathsf{src}\) if \((\mathsf{row}, \mathsf{col})\) is interior, else \(\mathsf{src}[\mathsf{threadIdx{.}y}][\mathsf{threadIdx{.}x}]\)
- }
- Barrier()
- }
- if \(\mathsf{threadIdx{.}x}, \mathsf{threadIdx{.}y} \in [K, 32 - K)\) and \((\mathsf{row}, \mathsf{col})\) is interior {
- \(v_{\mathsf{row},\mathsf{col}}\) = the tile written in step \(K\), at \([\mathsf{threadIdx{.}y}][\mathsf{threadIdx{.}x}]\)
- }
Line 1 places the tile \(K\) cells above and to the left of the block’s own cells, so that the halo of width \(K\) surrounds them. Line 2 loads the whole tile, 1 slot per thread, and line 3 waits until the tile is complete. In the step with number \(\mathsf{step}\), line 5 lets only the threads whose slot lies at least \(\mathsf{step}\) positions from every edge of the tile compute. In step 1, for example, these are the positions 1 to 30 in each direction, which form the 30 × 30 region of Definition 20.4. Line 6 reads from the tile written in the previous step, called \(\mathsf{src}\), and writes into the other tile, called \(\mathsf{dst}\). Line 8 is the barrier between steps. Finally, lines 10 to 12 write the block’s own cells, the positions \([K, 32 - K)\), from the tile written in step \(K\).
Theorem 20.2 Launched on 2 different buffers holding the grid \(u^{(k)}\) and its boundary, Temporal-Jacobi-Kernel writes \(u^{(k+K)}\) into every interior cell of \(v\).
Proof. We show that the loop of lines 4 to 9 maintains the invariant: at the start of the pass for step \(\mathsf{step}\), for every position \((\mathsf{threadIdx{.}y}, \mathsf{threadIdx{.}x})\) with \(\mathsf{threadIdx{.}x}, \mathsf{threadIdx{.}y} \in [\mathsf{step} - 1, 33 - \mathsf{step})\) whose cell lies in the grid, the tile \(\mathsf{src}\) holds \(u^{(k+\mathsf{step}-1)}\) of that cell.
Initialization. At \(\mathsf{step} = 1\) the region is the whole tile, and line 2 stored \(u^{(k)}\) in every position whose cell is in the grid; the barrier of line 3 makes the stores visible.
Maintenance. Let \((\mathsf{threadIdx{.}y}, \mathsf{threadIdx{.}x})\) lie in \([\mathsf{step}, 32 - \mathsf{step})\) with its cell in the grid. If the cell is interior, its 4 neighbors lie at positions in \([\mathsf{step} - 1, 33 - \mathsf{step})\) and in the grid, so by the invariant line 6 reads 4 values of \(u^{(k+\mathsf{step}-1)}\) and stores \(u^{(k+\mathsf{step})}\). If the cell is a boundary cell, line 6 copies its value, which is the same in every step. The 2 tiles are different arrays, so no thread writes a value that another reads in the same pass, and the barrier of line 8 completes every store before the next pass reads them. The roles of the tiles exchange, and the invariant holds for \(\mathsf{step} + 1\) on the region \([\mathsf{step}, 32 - \mathsf{step})\).
Termination. After pass \(K\), the tile written last holds \(u^{(k+K)}\) on \([K, 32 - K)\), the block’s own cells, and lines 10 to 12 write them. The own squares of the blocks cover the grid without overlap.
20.8.2 Traffic and work
We now count what temporal blocking saves and what it costs. A launch loads a 32 × 32 tile, 1,024 values, and writes \((32 - 2K)^2\) cells, and it does so for \(K\) steps at once. Per kept cell, the block therefore reads \(1024 / (32 - 2K)^2\) values and writes 1 value, each of 4 bytes, and this traffic is shared among \(K\) steps. The traffic per cell and step is
\[ \frac{4}{K} \left( \frac{1024}{(32 - 2K)^2} + 1 \right) \text{ bytes}. \]
| Symbol | Meaning | \(K = 4\) |
|---|---|---|
| \(K\) | steps per load | 4 |
| \(32 - 2K\) | width of the block’s own square | 24 |
| \(1024 / (32 - 2K)^2\) | values loaded per kept cell | \(1024 / 576 = 1.78\) |
| \(+ 1\) | the 1 value written per kept cell | 1 |
| \(4 / K\) | 4 bytes per value, shared among \(K\) steps | 1 |
For \(K = 4\), the traffic is \(1 \cdot (1.78 + 1) = 2.78\) bytes per cell and step, against about 9 bytes for the direct kernel. The price of this saving is work. In every step, all 1,024 threads of the block run the loop and wait at the barrier, although only \((32 - 2K)^2\) cells per block are kept. Per kept cell and step, a launch therefore runs \(1024 / (32 - 2K)^2\) thread-steps, where a thread-step is 1 pass of 1 thread through the loop. For \(K = 4\), this is 1.78 thread-steps. We measured the C++ kernel for several values of \(K\) in 1 run, in which the direct kernel reached 65.0 GB/s. The following table gives the results.
| \(K\) | Own cells per block | Bytes per cell and step | Thread-steps per cell and step | Measured |
|---|---|---|---|---|
| 1 | 30 × 30 | 8.55 | 1.14 | 30.3 GB/s |
| 2 | 28 × 28 | 4.61 | 1.31 | 48.4 GB/s |
| 4 | 24 × 24 | 2.78 | 1.78 | 62.4 GB/s |
| 6 | 20 × 20 | 2.37 | 2.56 | 57.1 GB/s |
| 8 | 16 × 16 | 2.50 | 4.00 | 43.7 GB/s |
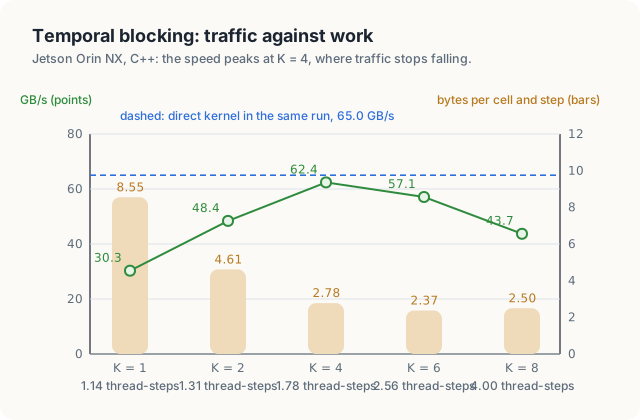
From \(K = 1\) to \(K = 4\), the traffic falls by a factor of 3, and the speed doubles. Beyond \(K = 4\), the traffic hardly changes, while the work per cell grows from 1.78 to 4 thread-steps, and the speed falls again. The time of the kernel now follows its work rather than its traffic. At its best, with \(K = 4\), the temporal kernel reached 62.4 GB/s in this run, 96% of the direct kernel’s 65.0 GB/s, while moving a third of the bytes. In the run of Section 20.7, the two kernels reached 63.5 and 68.3 GB/s, a ratio of 93%. On the measured GPU, with 8 SMs, a 5-point step costs about as much in instructions as in memory traffic once the caches have done their part, so neither tiling nor temporal blocking beats the direct kernel. On a GPU with more arithmetic per byte of bandwidth, such as those with ridge points of 60 to 110 FLOP per byte in Chapter 2, the same reduction of traffic leaves more room for the extra work. Temporal blocking is used on such GPUs, and for stencils with more work per cell.
Exercises
20.16 Derive the traffic formula of Section 20.8.2. What is its limit for large tiles and fixed
\(K\)?
20.17 With 1,024 threads per block and 8 KiB of shared memory per block, how many blocks of the
temporal kernel fit on an SM with 1,536 threads and 100 KiB of shared memory? What limits the
number?
20.18 Design a temporal kernel in which each thread computes 2 cells of a 64 × 32 tile, so that
fewer threads idle in the outer rings. Predict its thread-steps per cell for \(K = 4\).
20.9 The complete programs
Listing 20.3 The complete programs. code/oxide/ch20_stencil_tiled/src/main.rs code/cuda/ch20_stencil_tiled/stencil_tiled.cu
//! Chapter 20: tiled Jacobi steps with halo cells in shared memory, in Rust.
//!
//! cargo oxide run
use std::sync::Arc;
use std::time::Instant;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, LaunchConfig1D, LaunchConfig2D};
use cuda_device::thread::Runtime2DIndex;
use cuda_device::{DisjointSlice, SharedArray, cuda_module, kernel, launch_contract, thread};
use cuda_host::RowWidth;
const BLOCK_WIDTH: usize = 32; // cells computed by a block, across
const BLOCK_HEIGHT: usize = 8; // cells computed by a block, down
const TILE_WIDTH: usize = BLOCK_WIDTH + 2; // the block's cells and a 1-cell halo
const TILE_HEIGHT: usize = BLOCK_HEIGHT + 2;
const TEMPORAL_TILE: usize = 32; // temporal blocking: a 32 x 32 tile, 1 thread per cell
const STEPS: usize = 4; // temporal blocking: Jacobi steps per load
const OWN_WIDTH: usize = TEMPORAL_TILE - 2 * STEPS; // temporal blocking: cells written
const HOT: f32 = 100.0; // the top edge; the other edges are held at 0
type Error = Box<dyn std::error::Error>;
#[cuda_module]
mod kernels {
use super::*;
/// 1 Jacobi step, 1 thread per cell, every neighbor read from global memory.
#[kernel]
#[launch_contract(domain = 2, block = (32, 8, 1))]
pub fn jacobi(old: &[f32], mut new: DisjointSlice<f32, Runtime2DIndex>) {
let width = new.row_width() as usize;
let height = new.len() / width;
if let Some(idx) = thread::index_2d_runtime(&new) {
let (row, col) = (idx.row(), idx.col());
let interior = row >= 1 && row + 1 < height && col >= 1 && col + 1 < width;
if interior {
let center = row * width + col;
let (up, down) = (old[center - width], old[center + width]);
let (to_left, to_right) = (old[center - 1], old[center + 1]);
let sum = up + down + to_left + to_right;
if let Some(cell) = new.get_mut(idx) {
*cell = 0.25 * sum;
}
}
}
}
/// 1 Jacobi step from a 34 x 10 tile; 32 x 8 threads load it, some 2 or 4 cells each.
#[kernel]
#[launch_contract(domain = 2, block = (32, 8, 1))]
pub fn jacobi_tiled(old: &[f32], mut new: DisjointSlice<f32, Runtime2DIndex>) {
const AREA: usize = TILE_WIDTH * TILE_HEIGHT;
static mut TILE: SharedArray<f32, AREA> = SharedArray::UNINIT;
let width = new.row_width() as usize;
let height = new.len() / width;
let thread_x = thread::threadIdx_x() as usize;
let thread_y = thread::threadIdx_y() as usize;
let top = thread::blockIdx_y() as usize * BLOCK_HEIGHT;
let left = thread::blockIdx_x() as usize * BLOCK_WIDTH;
let mut slot_row = thread_y;
while slot_row < TILE_HEIGHT {
let mut slot_col = thread_x;
while slot_col < TILE_WIDTH {
let cell_row = (top + slot_row).wrapping_sub(1);
let cell_col = (left + slot_col).wrapping_sub(1);
let inside = cell_row < height && cell_col < width;
let value = if inside { old[cell_row * width + cell_col] } else { 0.0 };
// SAFETY: slot (slot_row, slot_col) is written by 1 thread alone,
// the thread (slot_row mod 8, slot_col mod 32).
unsafe { TILE[slot_row * TILE_WIDTH + slot_col] = value };
slot_col += BLOCK_WIDTH;
}
slot_row += BLOCK_HEIGHT;
}
thread::sync_threads();
if let Some(idx) = thread::index_2d_runtime(&new) {
let (row, col) = (idx.row(), idx.col());
let interior = row >= 1 && row + 1 < height && col >= 1 && col + 1 < width;
if interior {
let center = (thread_y + 1) * TILE_WIDTH + thread_x + 1;
// SAFETY: after the barrier no thread writes the tile.
let up = unsafe { TILE[center - TILE_WIDTH] };
// SAFETY: as above.
let down = unsafe { TILE[center + TILE_WIDTH] };
// SAFETY: as above.
let (to_left, to_right) = unsafe { (TILE[center - 1], TILE[center + 1]) };
let sum = up + down + to_left + to_right;
if let Some(cell) = new.get_mut(idx) {
*cell = 0.25 * sum;
}
}
}
}
/// 1 Jacobi step from a 34 x 10 tile; 34 x 10 threads load 1 cell each, 32 x 8 compute.
#[kernel]
#[launch_contract(domain = 2, block = (34, 10, 1))]
pub fn jacobi_halo_threads(old: &[f32], mut new: DisjointSlice<f32, Runtime2DIndex>) {
const AREA: usize = TILE_WIDTH * TILE_HEIGHT;
static mut TILE: SharedArray<f32, AREA> = SharedArray::UNINIT;
let width = new.row_width() as usize;
let height = new.len() / width;
let slot_col = thread::threadIdx_x() as usize;
let slot_row = thread::threadIdx_y() as usize;
let row = (thread::blockIdx_y() as usize * BLOCK_HEIGHT + slot_row).wrapping_sub(1);
let col = (thread::blockIdx_x() as usize * BLOCK_WIDTH + slot_col).wrapping_sub(1);
let slot = slot_row * TILE_WIDTH + slot_col;
let value = if row < height && col < width { old[row * width + col] } else { 0.0 };
// SAFETY: the slot belongs to this thread alone.
unsafe { TILE[slot] = value };
thread::sync_threads();
let inner_row = slot_row >= 1 && slot_row <= BLOCK_HEIGHT;
let inner_col = slot_col >= 1 && slot_col <= BLOCK_WIDTH;
let interior = row >= 1 && row + 1 < height && col >= 1 && col + 1 < width;
if inner_row && inner_col && interior {
// SAFETY: after the barrier no thread writes the tile.
let (up, down) = unsafe { (TILE[slot - TILE_WIDTH], TILE[slot + TILE_WIDTH]) };
// SAFETY: as above.
let (to_left, to_right) = unsafe { (TILE[slot - 1], TILE[slot + 1]) };
let sum = up + down + to_left + to_right;
// SAFETY: the inner threads of the blocks cover each cell of the grid once,
// so no other thread writes cell (row, col), which lies inside `new`.
unsafe { *new.get_unchecked_mut(row * width + col) = 0.25 * sum };
}
}
/// STEPS Jacobi steps from 1 load: a 32 x 32 tile, ping-pong in shared memory.
#[kernel]
#[launch_contract(domain = 2, block = (32, 32, 1))]
pub fn jacobi_temporal(old: &[f32], mut new: DisjointSlice<f32, Runtime2DIndex>) {
const AREA: usize = TEMPORAL_TILE * TEMPORAL_TILE;
static mut TILES: SharedArray<f32, { 2 * AREA }> = SharedArray::UNINIT;
let width = new.row_width() as usize;
let height = new.len() / width;
let slot_col = thread::threadIdx_x() as usize;
let slot_row = thread::threadIdx_y() as usize;
let first_row = thread::blockIdx_y() as usize * OWN_WIDTH;
let first_col = thread::blockIdx_x() as usize * OWN_WIDTH;
let row = (first_row + slot_row).wrapping_sub(STEPS);
let col = (first_col + slot_col).wrapping_sub(STEPS);
let slot = slot_row * TEMPORAL_TILE + slot_col;
let inside = row < height && col < width;
let interior = row >= 1 && row + 1 < height && col >= 1 && col + 1 < width;
let value = if inside { old[row * width + col] } else { 0.0 };
// SAFETY: this slot of the first tile belongs to this thread alone.
unsafe { TILES[slot] = value };
thread::sync_threads();
let mut step = 1;
#[unroll]
while step <= STEPS {
let src = (step - 1) % 2 * AREA + slot;
let dst = step % 2 * AREA + slot;
let last = TEMPORAL_TILE - step;
let valid_row = slot_row >= step && slot_row < last;
let valid_col = slot_col >= step && slot_col < last;
if valid_row && valid_col {
// SAFETY: in this step the tile at src is only read, slot dst belongs to
// this thread alone, and the barrier below separates the steps.
unsafe {
let up = TILES[src - TEMPORAL_TILE];
let down = TILES[src + TEMPORAL_TILE];
let (to_left, to_right) = (TILES[src - 1], TILES[src + 1]);
let sum = up + down + to_left + to_right;
TILES[dst] = if interior { 0.25 * sum } else { TILES[src] };
}
}
thread::sync_threads();
step += 1;
}
let end = TEMPORAL_TILE - STEPS;
let owned_row = slot_row >= STEPS && slot_row < end;
let owned_col = slot_col >= STEPS && slot_col < end;
if owned_row && owned_col && interior {
let last = STEPS % 2 * AREA + slot;
// SAFETY: the owned squares of the blocks cover each cell of the grid once,
// so no other thread writes cell (row, col), which lies inside `new`.
unsafe { *new.get_unchecked_mut(row * width + col) = TILES[last] };
}
}
/// A copy: 1 read and 1 write per cell, the least traffic a step can have.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn copy(input: &[f32], mut out: DisjointSlice<f32>) {
let idx = thread::index_1d();
let index = idx.get();
if let Some(out_cell) = out.get_mut(idx) {
*out_cell = input[index];
}
}
}
/// The 4 ways to advance the plate: 1 step per launch, or STEPS steps per launch.
#[derive(Clone, Copy, PartialEq)]
enum Kind {
Plain,
Tiled,
HaloThreads,
Temporal,
}
impl Kind {
fn steps_per_launch(self) -> usize {
if self == Kind::Temporal { STEPS } else { 1 }
}
}
type Buffer = DeviceBuffer<f32>;
/// The 4 kernels prepared for a plate of `width` x `height` cells, as 1 launch function.
fn stepper<'a>(
module: &'a kernels::LoadedModule,
stream: &'a Arc<CudaStream>,
width: usize,
height: usize,
) -> Result<impl Fn(Kind, &Buffer, &mut Buffer) -> Result<(), Error> + 'a, Error> {
let block_columns = width.div_ceil(BLOCK_WIDTH) as u32;
let block_rows = height.div_ceil(BLOCK_HEIGHT) as u32;
let blocks = (block_columns, block_rows);
let squares = (width.div_ceil(OWN_WIDTH) as u32, height.div_ceil(OWN_WIDTH) as u32);
let block = (BLOCK_WIDTH as u32, BLOCK_HEIGHT as u32);
let tile_block = (TILE_WIDTH as u32, TILE_HEIGHT as u32);
let square = (TEMPORAL_TILE as u32, TEMPORAL_TILE as u32);
let one_per_cell = LaunchConfig2D::new(blocks, block, 0);
let one_per_tile_cell = LaunchConfig2D::new(blocks, tile_block, 0);
let several_steps = LaunchConfig2D::new(squares, square, 0);
let plain = module.prepare_jacobi(one_per_cell)?;
let tiled = module.prepare_jacobi_tiled(one_per_cell)?;
let halo = module.prepare_jacobi_halo_threads(one_per_tile_cell)?;
let temporal = module.prepare_jacobi_temporal(several_steps)?;
Ok(move |kind: Kind, old: &Buffer, new: &mut Buffer| {
let new = RowWidth::new(new, width as u32);
match kind {
Kind::Plain => module.jacobi(stream, &plain, old, new)?,
Kind::Tiled => module.jacobi_tiled(stream, &tiled, old, new)?,
Kind::HaloThreads => module.jacobi_halo_threads(stream, &halo, old, new)?,
Kind::Temporal => module.jacobi_temporal(stream, &temporal, old, new)?,
}
Ok(())
})
}
/// The plate after `steps` Jacobi steps of `kind`, starting from `start`.
fn run(
stream: &Arc<CudaStream>,
launch: &impl Fn(Kind, &Buffer, &mut Buffer) -> Result<(), Error>,
kind: Kind,
start: &[f32],
steps: usize,
) -> Result<Vec<f32>, Error> {
let mut current = DeviceBuffer::from_host(stream, start)?;
let mut next = DeviceBuffer::from_host(stream, start)?;
for _ in 0..steps / kind.steps_per_launch() {
launch(kind, ¤t, &mut next)?;
std::mem::swap(&mut current, &mut next);
}
Ok(current.to_host_vec(stream)?)
}
/// A plate of `width` x `height` cells: the top row at HOT, every other cell at 0.
fn initial_grid(width: usize, height: usize) -> Vec<f32> {
let mut grid = vec![0.0; width * height];
grid[..width].fill(HOT);
grid
}
fn print_grid(label: &str, grid: &[f32], width: usize) {
println!(" {label}");
for row in grid.chunks(width) {
let cells: Vec<String> = row.iter().map(|value| format!("{value:7.2}")).collect();
println!(" {}", cells.join(" "));
}
}
/// Average time of `runs` calls of `launch`, in milliseconds, after 0.4 s of warm-up.
fn time_ms(
stream: &Arc<CudaStream>,
runs: u32,
mut launch: impl FnMut() -> Result<(), Error>,
) -> Result<f64, Error> {
let warm = Instant::now();
while warm.elapsed().as_secs_f64() < 0.4 {
launch()?;
stream.synchronize()?;
}
let start = Instant::now();
for _ in 0..runs {
launch()?;
}
stream.synchronize()?;
Ok(start.elapsed().as_secs_f64() * 1e3 / runs as f64)
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let name = ctx.device_name()?;
let sms = ctx.multiprocessor_count()?;
println!("GPU: {name}, {sms} SMs");
let kinds = [Kind::Tiled, Kind::HaloThreads, Kind::Temporal];
let names = ["loop loader", "extra threads", "4 steps per load"];
// 1. The 6 x 6 plate of the text: every tiled kernel against the plain kernel.
let (width, height) = (6, 6);
let start = initial_grid(width, height);
let small = stepper(&module, &stream, width, height)?;
println!("1. 6 x 6 plate, top edge at {HOT}");
let after_two = run(&stream, &small, Kind::Tiled, &start, 2)?;
print_grid("after step 2, tiled", &after_two, width);
let mut small_same = true;
let reference = run(&stream, &small, Kind::Plain, &start, 4)?;
for (kind, name) in kinds.iter().zip(names) {
let same = run(&stream, &small, *kind, &start, 4)? == reference;
println!(" {name:24} same bits as the plain kernel after 4 steps: {same}");
small_same &= same;
}
// 2. A 4096 x 4096 plate: time per step and effective bandwidth.
let (width, height) = (4096, 4096);
let cells = width * height;
let start = initial_grid(width, height);
let big = stepper(&module, &stream, width, height)?;
let mut current = DeviceBuffer::from_host(&stream, &start)?;
let mut next = DeviceBuffer::from_host(&stream, &start)?;
let copy = module.prepare_copy(LaunchConfig1D::new((cells / 256) as u32, 256, 0))?;
let gb = |ms: f64| (2 * cells * 4) as f64 / 1e9 / (ms / 1e3);
println!("2. 4096 x 4096 plate, 8 bytes per cell per step (1 read, 1 write)");
let copy_once = || Ok(module.copy(&stream, ©, ¤t, &mut next)?);
let ms = time_ms(&stream, 50, copy_once)?;
println!(" {:24} {ms:6.3} ms {:6.1} GB/s", "copy kernel", gb(ms));
let all_kinds = [Kind::Plain, Kind::Tiled, Kind::HaloThreads, Kind::Temporal];
let all_names = ["plain", names[0], names[1], names[2]];
for (kind, name) in all_kinds.iter().zip(all_names) {
let two_launches = time_ms(&stream, 50, || {
big(*kind, ¤t, &mut next)?;
big(*kind, &next, &mut current)
})?;
let ms = two_launches / (2 * kind.steps_per_launch()) as f64;
println!(" {name:24} {ms:6.3} ms {:6.1} GB/s", gb(ms));
}
let mut big_same = true;
let reference = run(&stream, &big, Kind::Plain, &start, 8)?;
for (kind, name) in kinds.iter().zip(names) {
let same = run(&stream, &big, *kind, &start, 8)? == reference;
println!(" {name:24} same bits as the plain kernel after 8 steps: {same}");
big_same &= same;
}
let passed = small_same && big_same;
println!("{}", if passed { "PASSED" } else { "FAILED" });
Ok(())
}// Chapter 20: tiled Jacobi steps with halo cells in shared memory.
// Build: nvcc -O3 -arch=native stencil_tiled.cu -o stencil_tiled
#include <chrono>
#include <cstdio>
#include <cstdlib>
#include <utility>
#include <vector>
#include <cuda_runtime.h>
using Grid = std::vector<float>;
const int BLOCK_WIDTH = 32; // cells computed by a block, across
const int BLOCK_HEIGHT = 8; // cells computed by a block, down
const int TILE_WIDTH = BLOCK_WIDTH + 2; // the block's cells and the halo
const int TILE_HEIGHT = BLOCK_HEIGHT + 2;
const int TEMPORAL_TILE = 32; // temporal blocking: a 32 x 32 tile
const int STEPS = 4; // temporal blocking: Jacobi steps per load
const int OWN_WIDTH = TEMPORAL_TILE - 2 * STEPS; // temporal blocking: cells written
const float HOT = 100.0f; // the top edge; the others are held at 0
enum Kind { PLAIN, TILED, HALO_THREADS, TEMPORAL };
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
// 1 Jacobi step, 1 thread per cell, every neighbor read from global memory.
__global__ void jacobi(const float* __restrict__ old, float* __restrict__ next,
int width, int height)
{
int row = blockIdx.y * BLOCK_HEIGHT + threadIdx.y;
int col = blockIdx.x * BLOCK_WIDTH + threadIdx.x;
bool interior = row >= 1 && row + 1 < height && col >= 1 && col + 1 < width;
if (interior) {
int center = row * width + col;
float up = old[center - width];
float down = old[center + width];
float sum = up + down + old[center - 1] + old[center + 1];
next[center] = 0.25f * sum;
}
}
// 1 Jacobi step from a 34 x 10 tile; 32 x 8 threads load it, some 2 or 4 cells each.
__global__ void jacobiTiled(const float* __restrict__ old, float* __restrict__ next,
int width, int height)
{
__shared__ float tile[TILE_HEIGHT][TILE_WIDTH];
int top = blockIdx.y * BLOCK_HEIGHT;
int left = blockIdx.x * BLOCK_WIDTH;
for (int slot_row = threadIdx.y; slot_row < TILE_HEIGHT; slot_row += BLOCK_HEIGHT) {
for (int slot_col = threadIdx.x; slot_col < TILE_WIDTH; slot_col += BLOCK_WIDTH) {
int cell_row = top + slot_row - 1;
int cell_col = left + slot_col - 1;
bool row_inside = cell_row >= 0 && cell_row < height;
bool col_inside = cell_col >= 0 && cell_col < width;
int cell = cell_row * width + cell_col;
tile[slot_row][slot_col] = row_inside && col_inside ? old[cell] : 0.0f;
}
}
__syncthreads();
int row = top + threadIdx.y;
int col = left + threadIdx.x;
bool interior = row >= 1 && row + 1 < height && col >= 1 && col + 1 < width;
if (interior) {
int center_row = threadIdx.y + 1;
int center_col = threadIdx.x + 1;
float up = tile[center_row - 1][center_col];
float down = tile[center_row + 1][center_col];
float to_left = tile[center_row][center_col - 1];
float to_right = tile[center_row][center_col + 1];
next[row * width + col] = 0.25f * (up + down + to_left + to_right);
}
}
// 1 Jacobi step from a 34 x 10 tile; 34 x 10 threads load 1 cell each, 32 x 8 compute.
__global__ void jacobiHaloThreads(const float* __restrict__ old, float* __restrict__ next,
int width, int height)
{
__shared__ float tile[TILE_HEIGHT][TILE_WIDTH];
int slot_row = threadIdx.y;
int slot_col = threadIdx.x;
int row = blockIdx.y * BLOCK_HEIGHT + slot_row - 1;
int col = blockIdx.x * BLOCK_WIDTH + slot_col - 1;
bool inside = row >= 0 && row < height && col >= 0 && col < width;
tile[slot_row][slot_col] = inside ? old[row * width + col] : 0.0f;
__syncthreads();
bool inner_row = slot_row >= 1 && slot_row <= BLOCK_HEIGHT;
bool inner_col = slot_col >= 1 && slot_col <= BLOCK_WIDTH;
bool interior = row >= 1 && row + 1 < height && col >= 1 && col + 1 < width;
if (inner_row && inner_col && interior) {
float up = tile[slot_row - 1][slot_col];
float down = tile[slot_row + 1][slot_col];
float to_left = tile[slot_row][slot_col - 1];
float to_right = tile[slot_row][slot_col + 1];
next[row * width + col] = 0.25f * (up + down + to_left + to_right);
}
}
// STEPS Jacobi steps from 1 load: a 32 x 32 tile, ping-pong in shared memory.
__global__ void jacobiTemporal(const float* __restrict__ old, float* __restrict__ next,
int width, int height)
{
__shared__ float tiles[2][TEMPORAL_TILE][TEMPORAL_TILE];
int slot_row = threadIdx.y;
int slot_col = threadIdx.x;
int row = blockIdx.y * OWN_WIDTH + slot_row - STEPS;
int col = blockIdx.x * OWN_WIDTH + slot_col - STEPS;
bool inside = row >= 0 && row < height && col >= 0 && col < width;
bool interior = row >= 1 && row + 1 < height && col >= 1 && col + 1 < width;
tiles[0][slot_row][slot_col] = inside ? old[row * width + col] : 0.0f;
__syncthreads();
#pragma unroll
for (int step = 1; step <= STEPS; ++step) {
int src = (step - 1) % 2;
int dst = step % 2;
int last = TEMPORAL_TILE - step;
bool valid_row = slot_row >= step && slot_row < last;
bool valid_col = slot_col >= step && slot_col < last;
if (valid_row && valid_col) {
float up = tiles[src][slot_row - 1][slot_col];
float down = tiles[src][slot_row + 1][slot_col];
float to_left = tiles[src][slot_row][slot_col - 1];
float to_right = tiles[src][slot_row][slot_col + 1];
float mean = 0.25f * (up + down + to_left + to_right);
float same = tiles[src][slot_row][slot_col];
tiles[dst][slot_row][slot_col] = interior ? mean : same;
}
__syncthreads();
}
int end = TEMPORAL_TILE - STEPS;
bool owned = slot_col >= STEPS && slot_col < end && slot_row >= STEPS && slot_row < end;
if (owned && interior) {
next[row * width + col] = tiles[STEPS % 2][slot_row][slot_col];
}
}
// A copy: 1 read and 1 write per cell, the least traffic a step can have.
__global__ void copy(const float* __restrict__ in, float* __restrict__ out, int n)
{
int index = blockIdx.x * blockDim.x + threadIdx.x;
if (index < n) {
out[index] = in[index];
}
}
int stepsPerLaunch(Kind kind)
{
return kind == TEMPORAL ? STEPS : 1;
}
// 1 launch of `kind` on a plate of width x height cells, reading `old`, writing `next`.
void launch(Kind kind, const float* old, float* next, int width, int height)
{
int block_columns = (width + BLOCK_WIDTH - 1) / BLOCK_WIDTH;
int block_rows = (height + BLOCK_HEIGHT - 1) / BLOCK_HEIGHT;
dim3 blocks(block_columns, block_rows);
dim3 squares((width + OWN_WIDTH - 1) / OWN_WIDTH, (height + OWN_WIDTH - 1) / OWN_WIDTH);
dim3 block(BLOCK_WIDTH, BLOCK_HEIGHT);
dim3 tile_block(TILE_WIDTH, TILE_HEIGHT);
dim3 square(TEMPORAL_TILE, TEMPORAL_TILE);
switch (kind) {
case PLAIN:
jacobi<<<blocks, block>>>(old, next, width, height);
break;
case TILED:
jacobiTiled<<<blocks, block>>>(old, next, width, height);
break;
case HALO_THREADS:
jacobiHaloThreads<<<blocks, tile_block>>>(old, next, width, height);
break;
case TEMPORAL:
jacobiTemporal<<<squares, square>>>(old, next, width, height);
break;
}
}
// A plate of width x height cells: the top row at HOT, every other cell at 0.
Grid initialGrid(int width, int height)
{
Grid grid(size_t(width) * height, 0.0f);
for (int col = 0; col < width; ++col) {
grid[col] = HOT;
}
return grid;
}
// The plate after `steps` Jacobi steps of `kind`, starting from `start`.
Grid run(Kind kind, const Grid& start, int width, int height, int steps)
{
size_t bytes = start.size() * sizeof(float);
float *current, *next;
check(cudaMalloc(¤t, bytes));
check(cudaMalloc(&next, bytes));
check(cudaMemcpy(current, start.data(), bytes, cudaMemcpyHostToDevice));
check(cudaMemcpy(next, start.data(), bytes, cudaMemcpyHostToDevice));
for (int launches = 0; launches < steps / stepsPerLaunch(kind); ++launches) {
launch(kind, current, next, width, height);
std::swap(current, next);
}
check(cudaGetLastError());
Grid result(start.size());
check(cudaMemcpy(result.data(), current, bytes, cudaMemcpyDeviceToHost));
check(cudaFree(current));
check(cudaFree(next));
return result;
}
void printGrid(const char* label, const Grid& grid, int width)
{
std::printf(" %s\n", label);
for (size_t i = 0; i < grid.size(); ++i) {
const char* gap = i % width == 0 ? " " : " ";
const char* end = i % width == size_t(width - 1) ? "\n" : "";
std::printf("%s%7.2f%s", gap, grid[i], end);
}
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// Average time of `runs` calls of `launch`, in milliseconds, after 0.4 s of warm-up.
template <typename F>
double timeMs(F launch, int runs)
{
double warm = nowMs();
while (nowMs() - warm < 400.0) {
launch();
check(cudaDeviceSynchronize());
}
double t0 = nowMs();
for (int timed = 0; timed < runs; ++timed) {
launch();
}
check(cudaGetLastError());
check(cudaDeviceSynchronize());
return (nowMs() - t0) / runs;
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %d SMs\n", prop.name, prop.multiProcessorCount);
Kind kinds[] = {TILED, HALO_THREADS, TEMPORAL};
const char* names[] = {"loop loader", "extra threads", "4 steps per load"};
// 1. The 6 x 6 plate of the text: every tiled kernel against the plain kernel.
int width = 6;
int height = 6;
Grid start = initialGrid(width, height);
std::printf("1. 6 x 6 plate, top edge at %.0f\n", HOT);
printGrid("after step 2, tiled", run(TILED, start, width, height, 2), width);
bool smallSame = true;
Grid reference = run(PLAIN, start, width, height, 4);
for (int index = 0; index < 3; ++index) {
bool same = run(kinds[index], start, width, height, 4) == reference;
std::printf(" %-24s same bits as the plain kernel", names[index]);
std::printf(" after 4 steps: %s\n", same ? "true" : "false");
smallSame = smallSame && same;
}
// 2. A 4096 x 4096 plate: time per step and effective bandwidth.
width = 4096;
height = 4096;
int cells = width * height;
start = initialGrid(width, height);
size_t bytes = start.size() * sizeof(float);
float *current, *next;
check(cudaMalloc(¤t, bytes));
check(cudaMalloc(&next, bytes));
check(cudaMemcpy(current, start.data(), bytes, cudaMemcpyHostToDevice));
check(cudaMemcpy(next, start.data(), bytes, cudaMemcpyHostToDevice));
auto gb = [&](double ms) { return 2.0 * cells * 4 / 1e9 / (ms / 1e3); };
std::printf("2. 4096 x 4096 plate, 8 bytes per cell per step (1 read, 1 write)\n");
double ms = timeMs([&] { copy<<<cells / 256, 256>>>(current, next, cells); }, 50);
std::printf(" %-24s %6.3f ms %6.1f GB/s\n", "copy kernel", ms, gb(ms));
Kind allKinds[] = {PLAIN, TILED, HALO_THREADS, TEMPORAL};
const char* allNames[] = {"plain", names[0], names[1], names[2]};
for (int index = 0; index < 4; ++index) {
Kind kind = allKinds[index];
auto twoLaunches = [&] {
launch(kind, current, next, width, height);
launch(kind, next, current, width, height);
};
ms = timeMs(twoLaunches, 50) / (2 * stepsPerLaunch(kind));
std::printf(" %-24s %6.3f ms %6.1f GB/s\n", allNames[index], ms, gb(ms));
}
check(cudaFree(current));
check(cudaFree(next));
bool bigSame = true;
reference = run(PLAIN, start, width, height, 8);
for (int index = 0; index < 3; ++index) {
bool same = run(kinds[index], start, width, height, 8) == reference;
std::printf(" %-24s same bits as the plain kernel", names[index]);
std::printf(" after 8 steps: %s\n", same ? "true" : "false");
bigSame = bigSame && same;
}
bool passed = smallSame && bigSame;
std::printf("%s\n", passed ? "PASSED" : "FAILED");
return passed ? 0 : 1;
}
Common mistakes
- Leaving out the barrier between loading and computing. Threads then read slots that other threads have not filled; on small tests inside 1 warp, the error may not appear (Section 20.5.1).
- Placing the barrier inside a condition. A thread whose cell is on the boundary or outside the grid must still reach the barrier.
- Loading only the block’s own cells. The cells on the edge of the block then lose the neighbors that belong to other blocks. Step 1 of the plate is still correct, so test more than 1 step (Section 20.5.2).
- Reading outside the grid while loading the halo. Blocks on the edge of the grid have slots outside it; store 0 there and never read it.
- Expecting a tile to beat the caches. Measure the direct kernel first. A 5-point stencil reuses each value only 4 times, and the L1 and L2 caches already capture most of that reuse.
- Growing the halo of temporal blocking without counting the work. Each extra step removes a ring of results; past a few steps, the idle threads cost more than the saved traffic.
Summary
- In the direct kernel, each value of the grid is read by up to 4 threads: on the 6 × 6 plate, 16 threads make 64 reads of 32 values.
- A block copies a tile into shared memory, made of its own cells and a halo 1 cell wide. Block (1, 1) of the plate loads a 4 × 4 tile, 4 own cells and 12 halo cells, and computes cell (2, 2) = 6.25 from it.
- The halo is loaded either by extra threads, 1 per slot, or by a loop in which some threads load 2 or more slots.
- Without the barrier, a thread reads a slot before it is filled: 124,322 to 126,302 wrong cells per step on a 4096 × 4096 grid. Without the halo, row 1 of the plate becomes 25, 31.25, 31.25, 25 in step 2.
- Theorem 20.1 shows that the tiled kernel writes exactly what the direct kernel writes, given 1 loader per slot, the barrier, and a tile that covers every neighbor.
- A tile of \(T \times T\) costs \((T + 2)^2 / T^2\) loads per result: 1.33 for 32 × 8, against 4 requested by the direct kernel.
- On the measured GPU, the caches already reduce the direct kernel to about 1.25 loads per cell, so the tiled kernels ran slower, at 43.4 and 45.8 GB/s against 68.3 GB/s.
- Temporal blocking with \(K = 4\) steps per load cuts the traffic to 2.78 bytes per cell and step and reached 63.5 GB/s, 93% of the direct kernel; beyond \(K = 4\), the extra work outweighs the saved traffic.
Exercises
- Draw the tile of block (0, 2) of the plate with 2 × 2 blocks in step 2, and compute its 4 cells from the tile.
- A 9-point stencil also reads the 4 diagonal neighbors. Which slots of the tile become necessary, and how does the reuse per value change?
- Implement a 3-D 7-point stencil on a 256 × 256 × 256 grid, directly and with a tile of 32 × 8 cells in each of 3 consecutive planes. Count the loads per result of both and measure them.
- Change the tiled kernel so that each thread computes 2 cells in the same column. How does the ratio of halo to own cells change, and what happens to the speed?
- Extend Theorem 20.2 to a tile that is not square, of \(\mathsf{blockDim{.}x} \times \mathsf{blockDim{.}y}\) threads.
Sources and further reading
- A. Pathak, An Introduction to Tiled Parallel Programming, Simplified, 2026. Tiles, the 2 barriers, and a loop-invariant proof for the matrix product.
- T. H. Cormen, C. E. Leiserson, R. L. Rivest and C. Stein, Introduction to Algorithms, 4th edition, MIT Press, 2022. Pseudocode conventions and loop invariants.
- P. Micikevicius, “3D Finite Difference Computation on GPUs using CUDA”, Proceedings of the 2nd Workshop on General Purpose Processing on Graphics Processing Units, 2009. Tiles with halos for high-order 3-D stencils.
- A. Nguyen, N. Satish, J. Chhugani, C. Kim and P. Dubey, “3.5-D Blocking Optimization for Stencil Computations on Modern CPUs and GPUs”, Proceedings of SC10, 2010. Spatial and temporal blocking of stencils.
- NVIDIA, CUDA C++ Programming Guide: shared memory,
__syncthreads(), and the caching of global loads.
Scan-Based Algorithms
In the next 2 chapters, we treat algorithms whose output positions are not known in advance. A stream compaction keeps some of the elements of an array and packs them together at the front of another array. How far an element moves depends on how many elements before it were kept. A radix sort moves every key to a place that depends on 2 numbers: how many keys have a smaller digit, and how many keys before it have the same digit. In both cases, each element could compute its output position on its own, if it knew a count of the elements before it.
Such a count is a scan. For example, the exclusive scan of an array of 0s and 1s gives every element the number of 1s before it, and the exclusive scan of a histogram gives every bin the number of elements in the bins before it. At first sight, a scan seems to need a strict order, since every running total is built from the one before it. Because addition is associative, however, the totals can be built by combining partial sums in a tree, in a number of steps that grows only with the logarithm of the length of the array. The idea that connects the 2 chapters is therefore to turn each data-dependent position into a count, and each count into a scan.
In Chapter 21, Scan and Stream Compaction, we derive 2 parallel scans from the sequential loop, on 1 example of 8 values. The Hillis-Steele scan doubles the length of the ranges it sums at every step. The Blelloch scan builds a tree of partial sums and then passes the sums down the tree. We show what each barrier and the second buffer prevent, prove the Hillis-Steele scan correct, and extend both scans to arrays of many blocks. Finally, we build stream compaction on the scan, first in 3 passes and then with warp votes.
In Chapter 22, Radix Sort and Histograms, we sort 8 keys of 3 bits by a sequence of stable passes. A pass on 1 bit consists of 2 stream compactions. A pass on a digit of several bits needs the count of every digit, which is a histogram, and the exclusive scan of that histogram gives each digit its start in the output. We count with atomic operations, measure their contention, remove most of it with private bins in shared memory, and prove that a sort by stable passes is correct.
In both chapters, we build on Chapter 8, where we developed a fast scan and a histogram in CUDA C++ and in Rust, and on Chapter 15, where we built the tree of a reduction. We implement every algorithm in Rust with cuda-oxide and in CUDA C++, and we reuse the rules for barriers and shared memory that we established for the tiled matrix multiplication.
Chapter 21: Scan and Stream Compaction
A scan turns a list of numbers into the list of its running totals. It is one of the most widely used building blocks of parallel programs, because a running total answers the question “how many elements come before this one?”, and the answer to that question decides where each element is written when a program packs, sorts or distributes data. The sequential algorithm for a scan is a single loop, and every iteration of that loop needs the result of the iteration before it. At first sight, therefore, a scan looks like the opposite of a parallel computation.
In this chapter, we derive 2 parallel scans from the sequential loop, using one example of 8 small integers throughout, so that every number can be checked by hand. The first, the Hillis-Steele scan, takes the fewest steps. The second, the Blelloch scan, performs no more additions than necessary, up to a factor of 2. We then show why each barrier of these algorithms is needed, by removing it and following the wrong values that appear, and we prove 1 of the 2 scans correct. After that, we extend both scans to arrays of any length, and we use the scan for stream compaction, the removal of unwanted elements from an array. Finally, we implement every algorithm in Rust with cuda-oxide and in CUDA C++, and we measure it.
This chapter covers
- inclusive and exclusive scans, worked by hand on 8 values
- the dependence chain of the sequential scan, and how associativity breaks it
- the Hillis-Steele and Blelloch scans, their work and their steps
- the barrier and the second buffer of a scan, broken one at a time, and a proof of correctness
- the scan of an array of many blocks
- stream compaction with a scan, and with warp votes
- measured times on 16,777,216 values, and why they differ
The code of the chapter is in
code/oxide/ch21_scan_compaction/
for Rust and in
code/cuda/ch21_scan_compaction/
for C++. In Section 8.7, we already built a fast scan from warp shuffles. In this chapter, we
derive the scan from the beginning, and we reuse the kernel of Chapter 8 as the third of our
measured methods.
21.1 The problem
21.1.1 A worked example
Throughout the chapter, we use the same 8 values, which we call \(x\):
\[ x = (3,\ 1,\ 7,\ 0,\ 4,\ 1,\ 6,\ 3). \]
We number the positions from 0, so that \(x_0 = 3\) is the first value, \(x_1 = 1\) the second, and \(x_7 = 3\) the last. The running totals of these values are found by walking along the list and adding each value to the total so far. The first total is 3. Adding 1 gives 4, adding 7 gives 11, and adding 0 leaves the total at 11. In the same way, the remaining 4 values give the totals 15, 16, 22 and 25. The last total, 25, is the sum of all 8 values.
There are two ways to line up these totals with the input. In the first, the total at position \(i\) includes the value \(x_i\) itself, so that position 4 holds \(3 + 1 + 7 + 0 + 4 = 15\). In the second, the total at position \(i\) stops just before \(x_i\), so that position 4 holds \(3 + 1 + 7 + 0 = 11\). In the second form, position 0 has no values before it and holds the empty sum, 0. Figure 21.1 shows both forms.
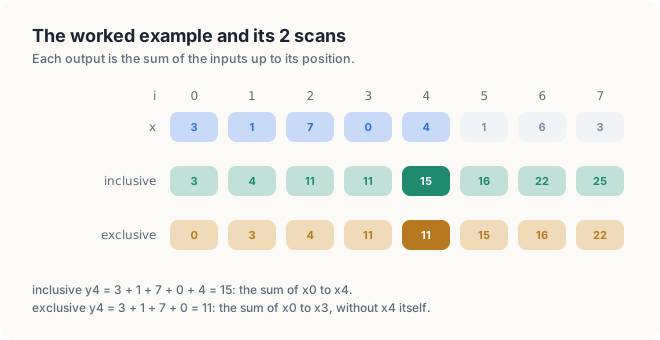
We will return to 2 of these totals several times, \(y_2 = 11\) at position 2 and \(y_6 = 22\) at position 6. In particular, in Section 21.6, we will see 2 faulty kernels that produce 8 and 14 in place of \(y_2 = 11\).
21.1.2 Definitions
We write ranges of integers as in the rest of the book: \([a, b)\) is the set of integers
\(a, a + 1, \ldots, b - 1\), like a..b in Rust. For example, \([0, 8)\) is the set of the 8
positions 0 to 7 of our example. Indices start at 0.
Definition 21.1 Inclusive scan. The inclusive scan of an array \(x\) of \(n\) values is the array \(y\) of \(n\) values with
\[ y_i = x_0 + x_1 + \cdots + x_i, \qquad i \in [0, n). \]
Example. For our 8 values, \(y = (3, 4, 11, 11, 15, 16, 22, 25)\).
| Symbol | Meaning | In the example |
|---|---|---|
| \(n\) | number of values in the array | 8 |
| \(i\) | a position in the array, from 0 to \(n - 1\) | 4 |
| \(x_i\) | the input value at position \(i\) | \(x_4 = 4\) |
| \(y_i\) | the sum of the inputs at positions 0 to \(i\), \(x_i\) included | \(y_4 = 15\) |
Definition 21.2 Exclusive scan. The exclusive scan of \(x\) is the array \(e\) with \(e_0 = 0\) and
\[ e_i = x_0 + x_1 + \cdots + x_{i-1}, \qquad i \in [1, n). \]
Example. For our 8 values, \(e = (0, 3, 4, 11, 11, 15, 16, 22)\).
The value \(e_i\) is the sum of the inputs that come strictly before position \(i\). In our example, \(e_4 = x_0 + x_1 + x_2 + x_3 = 3 + 1 + 7 + 0 = 11\), and \(e_0 = 0\), because no input comes before position 0.
The 2 scans differ by exactly 1 term at every position, namely \(x_i\), so each of them is obtained from the other with 1 operation per element:
\[ e_i = y_i - x_i, \qquad y_i = e_i + x_i. \]
At position 4, for example, \(e_4 = 15 - 4 = 11\) and \(y_4 = 11 + 4 = 15\). Scans are also called prefix sums, because \(y_i\) is the sum of the prefix of the array that ends at position \(i\). The same definitions apply to operators other than addition, such as the maximum. In this chapter, we use addition throughout, as do the applications of this chapter and of Chapter 22.
The exclusive scan has a direct use, which motivates much of this part of the book. Suppose that some of the values are to be copied, in their original order, to the front of another array. We write 1 for every value that is copied and 0 for every other value. The exclusive scan of these 1s and 0s at position \(i\) is then the number of copied values before position \(i\), and that number is exactly the position in the output array to which value \(i\) must be copied. In Section 21.8, we build stream compaction on this fact, and in Chapter 22, we build a radix sort on it.
Exercises
21.1 Compute the inclusive and the exclusive scan of \((2, 0, 5, 1, 1, 3, 0, 4)\).
21.2 The maximum is also an operator for a scan. Compute the inclusive max-scan of our 8 values.
What does \(y_i\) mean for this operator?
21.3 Show that the last value of the inclusive scan equals the last value of the exclusive scan
plus the last input. Which value of our example does this give?
21.2 The sequential algorithm
21.2.1 The loop
On a CPU, Definition 21.1 becomes a single loop. The first total is the first input, and each iteration of the loop adds the next input to the previous total.
Sequential-Scan(\(x, y, n\))
- \(y_0 = x_0\)
- for \(i \in [1, n)\) {
- \(y_i = y_{i-1} + x_i\) // 1 addition, needs line 3 of the previous iteration
- }
In our example, the iteration with \(i = 4\) computes \(y_4 = y_3 + x_4 = 11 + 4 = 15\). Line 3 executes once for each \(i\) from 1 to \(n - 1\), that is, \(n - 1\) times, so the loop performs \(n - 1\) additions, 7 for our example. No algorithm can do with fewer additions, because each of the inputs \(x_1\) to \(x_7\) has to enter the final total through at least 1 addition.
21.2.2 The dependence chain
On a parallel machine, the number of additions is not the main cost. The main cost is the order in which the additions must happen. Consider the iteration that computes \(y_4 = 15\). It adds \(x_4 = 4\) to \(y_3 = 11\), and so it cannot start until \(y_3\) is known. The value \(y_3\), in turn, needs \(y_2\), which needs \(y_1\). Figure 21.2 draws these dependences. Every addition waits for the one before it, and the 7 additions form a single chain.
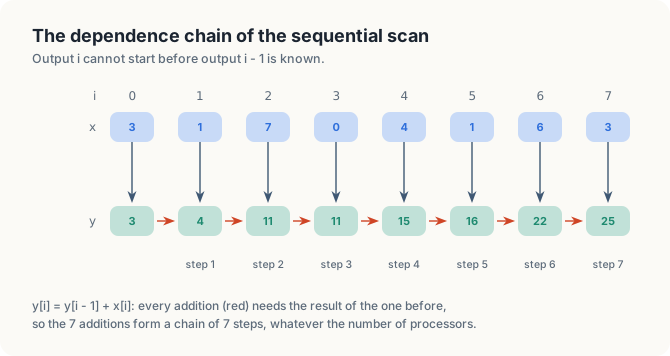
To compare algorithms by both of these costs, we give them names.
Definition 21.3 Work and steps. The work of an algorithm is the number of operations it performs. Its steps are the length of its longest chain of operations in which each needs the result of the one before. A machine with enough processors can execute an algorithm in as many rounds as it has steps, but not in fewer.
Example. Sequential-Scan of our 8 values does a work of 7 additions in 7 steps.
A GPU executes thousands of threads at once, and it is fast only when it has work for all of them. Sequential-Scan, however, offers only 1 addition per step. For an array of 1,024 values, it needs 1,023 steps, each of which waits for the one before, and during each step every other thread of the GPU is idle. To make use of the GPU, we therefore need an algorithm whose number of steps grows much more slowly than \(n\).
Exercises
21.4 How many additions and how many steps does Sequential-Scan need for \(n = 2^{20}\)?
21.5 The sum of all \(n\) values is the last output of the scan. In Chapter 15, we computed a sum in
\(\log_2 n\) steps. Why does the tree of a sum not give all \(n\) outputs of a scan?
21.3 Breaking the chain
21.3.1 1 thread per output
Recall that a kernel is a function that the GPU runs many times at once, and that each of these runs is a thread, with its own index and its own variables. The most direct parallel scan gives each output its own thread, and lets thread \(i\) add up the inputs \(x_0\) to \(x_i\) on its own.
Direct-Scan(\(x, y, n\))
- \(i\) = the index of this thread // 1 thread per output
- \(sum = 0\)
- for \(j \in [0, i]\) {
- \(sum = sum + x_j\) // \(i + 1\) reads of \(x\)
- }
- \(y_i = sum\)
In this kernel, no thread waits for another, so the threads may run in any order. Consider, however, thread 7. It reads all 8 values and performs 8 additions in a chain, which is exactly the chain of Sequential-Scan, so the number of steps has not changed. The work, on the other hand, has grown. Thread \(i\) reads \(i + 1\) values, so the 8 threads together read \(1 + 2 + \cdots + 8 = 36\) values. For \(n\) values, the kernel reads \(n(n + 1)/2\) of them, which for 1,024 values amounts to 524,800 reads of only 1,024 different numbers.
The waste is easy to see in the example. Thread 3 computes the sum \(3 + 1 + 7 + 0 = 11\) of the first 4 values, and threads 4, 5, 6 and 7 each compute the same sum again from the beginning. In general, each thread rebuilds a total that another thread already holds.
21.3.2 Regrouping a sum
Thread 7 needs \(y_7 = 3 + 1 + 7 + 0 + 4 + 1 + 6 + 3\). Since the result of an addition does not depend on how its terms are grouped, we may write
\[ y_7 = \underbrace{(3 + 1 + 7 + 0)}_{11} + \underbrace{(4 + 1 + 6 + 3)}_{14} = 25. \]
The left group is the sum of the values at positions 0 to 3, and the right group is the sum of the values at positions 4 to 7. Each group can itself be split into 2 pairs, which gives the 4 pair sums \(3 + 1 = 4\), \(7 + 0 = 7\), \(4 + 1 = 5\) and \(6 + 3 = 9\). These 4 additions do not depend on one another, so they can be performed at the same time. Figure 21.3 draws the result. It contains the same 7 additions as the chain of Figure 21.2, arranged as a tree of 3 levels instead of a chain of 7.

The property of addition that allows this regrouping has a name, and we will use it repeatedly.
Definition 21.4 Associative operator. An operator \(\oplus\) is associative if \((a \oplus b) \oplus c = a \oplus (b \oplus c)\) for all \(a\), \(b\), \(c\). The result of combining a list with an associative operator then depends only on the order of the list, not on how its terms are grouped.
Example. Integer addition is associative: \((3 + 1) + 7 = 3 + (1 + 7) = 11\).
Each node of the tree in Figure 21.3 holds the sum of the inputs over a range of consecutive positions. We need a short name for such a sum.
Definition 21.5 Range sum. For \(a \le b\), the range sum \(S[a..b]\) is \(x_a + x_{a+1} + \cdots + x_b\), the sum of the inputs at positions \(a\) to \(b\), both included. Because addition is associative, for every \(m\) with \(a \le m < b\),
\[ S[a..b] = S[a..m] + S[m+1..b]. \]
Example. \(S[0..7] = S[0..3] + S[4..7] = 11 + 14 = 25\), and \(y_i = S[0..i]\).
| Symbol | Meaning | In the example |
|---|---|---|
| \(a\) | first position of the range | 0 |
| \(b\) | last position of the range, included | 7 |
| \(m\) | last position of the left part; the right part begins at \(m + 1\) | 3 |
| \(S[a..m]\) | sum of the left part, positions \(a\) to \(m\) | \(S[0..3] = 11\) |
| \(S[m+1..b]\) | sum of the right part, positions \(m + 1\) to \(b\) | \(S[4..7] = 14\) |
In words, the sum over a range is the sum over its left part plus the sum over its right part, wherever we cut the range. Note also that the inclusive scan is a range sum that always starts at position 0: \(y_i = S[0..i]\), so that, for example, \(y_4 = S[0..4] = 15\).
Integer addition is exactly associative, which is why every program of this chapter can check its result against the CPU value by value. Floating-point addition is associative only approximately, because every addition rounds its result. In Section 8.2, we measured how much a regrouped float sum changes.
We can now state the idea on which the first parallel scan is built.
Key observation A thread that knows the range sums of 2 adjacent ranges obtains the range sum of their union with 1 addition. If, at every step, every thread doubles the length of the range it knows by adding the range sum held by another thread, then after \(\log_2 n\) steps every thread \(i\) holds \(S[0..i] = y_i\).
For our 8 values, \(\log_2 8 = 3\), so 3 steps suffice: the ranges grow from length 1 to length 2, then 4, then 8.
Exercises
21.6 Draw the tree of Figure 21.3 for \(y_5\). Which range sums of the figure can it reuse?
21.7 How many reads does Direct-Scan perform for \(n = 4{,}096\)? How many steps does it need?
21.4 The Hillis-Steele scan
21.4.1 Doubling the ranges
We now turn the key observation into an algorithm. Each position \(i\) keeps 1 value. At the start, this value is the input \(x_i\), which is the range sum \(S[i..i]\) of the range of length 1 that ends at \(i\).
In the first step, every position \(i \ge 1\) adds the value of position \(i - 1\), its left neighbor. For example, position 7 adds \(S[6..6] = 6\) to its own \(S[7..7] = 3\), and then holds \(S[6..7] = 9\). After this step, every position holds the sum of a range of length 2 that ends at it.
In the second step, every position \(i \ge 2\) adds the value of position \(i - 2\), which is the sum of the 2 values just before its own pair. Position 7 adds \(S[4..5] = 5\) and then holds \(S[4..7] = 14\), the sum of a range of length 4.
In the third step, every position \(i \ge 4\) adds the value of position \(i - 4\). Position 7 adds \(S[0..3] = 11\) and then holds \(S[0..7] = 25\), which is \(y_7\).
We call the distance between a position and the position whose value it adds the offset of the step, and write it \(\mathsf{distance}\). In our example, the offsets are \(\mathsf{distance} = 1\), 2 and 4. A position whose index is smaller than the offset has no partner, because position \(i - \mathsf{distance}\) would be negative. Such a position already holds the sum of a range that starts at position 0, so its value is final, and it keeps it. Figure 21.4 shows all 3 steps on our values, with the range that each cell sums written under the cell.
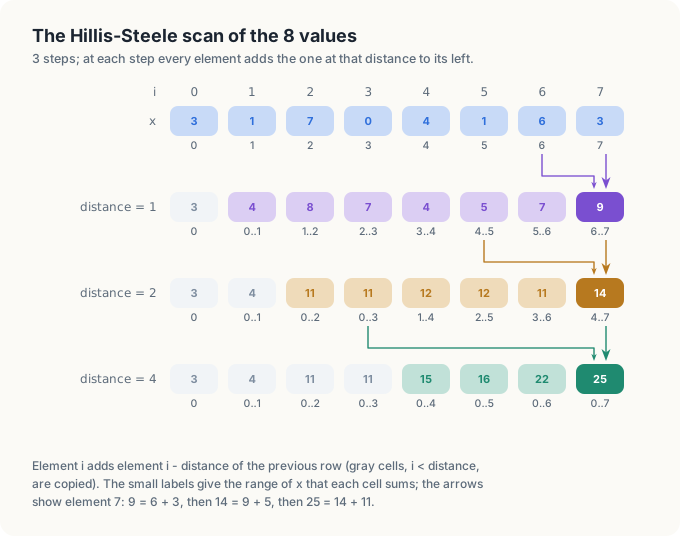
After the step with offset 4, the range of every cell in the last row starts at position 0, so the last row is the inclusive scan. This algorithm is due to Hillis and Steele, and it is called the Hillis-Steele scan.
21.4.2 Blocks, shared memory and the barrier
Every step reads the values that the previous step wrote, and those values were written by other threads. The threads therefore need a memory that all of them can read and write, and a way to wait for each other between steps. The GPU provides both, but only among the threads of 1 block.
Definition 21.6 Block and shared memory. A block is a group of up to 1,024 threads that run on the same streaming multiprocessor (SM) of the GPU. Shared memory is a small memory of each SM, a few cycles away, that every thread of a block can read and write and that no thread of another block can access.
Example. We scan our 8 values with 1 block of 8 threads, thread \(i\) for position \(i\), and keep the values in shared memory.
Definition 21.7 Barrier. A barrier is a point in a kernel that
no thread of a block may pass until every thread of the block has reached it. In cuda-oxide, a
barrier is written thread::sync_threads(), and in CUDA C++, __syncthreads().
Example. With a barrier at the end of each step, no thread starts the step with offset 2 until all 8 threads have finished the step with offset 1.
A second difficulty remains. A step reads the values of the previous step and writes new ones. If the new values overwrite the old ones in the same array, a thread may read a value that its neighbor has already replaced with the new value of the current step. We avoid this with 2 arrays. Every step reads 1 array and writes the other, and the next step exchanges their roles.
Definition 21.8 Double buffer. A double buffer is a pair of arrays \(\mathsf{current}\) and \(\mathsf{next}\) in which each step of an algorithm reads only \(\mathsf{current}\) and writes only \(\mathsf{next}\), after which the 2 names are exchanged.
Example. In the step with offset 1, thread 2 reads \(\mathsf{current}[2] = 7\) and \(\mathsf{current}[1] = 1\) and writes \(\mathsf{next}[2] = 8\); \(\mathsf{current}[1]\) keeps the value 1 until the step is over, whatever thread 1 does.
21.4.3 The algorithm
Every thread of the block executes the following procedure. The arrays \(\mathsf{current}\) and \(\mathsf{next}\) are stored in shared memory, and \(\mathsf{distance}\) is the offset of the current step.
Hillis-Steele-Scan(\(x, y, n\))
- \(i\) = the index of this thread in the block // 1 thread per value, \(n\) threads
- \(\mathsf{current}[i] = x_i\)
- Barrier() // every value is in \(\mathsf{current}\)
- for \(\mathsf{distance} = 1, 2, 4, \ldots\) while \(\mathsf{distance} < n\) {
- if \(i \ge \mathsf{distance}\): \(\mathsf{next}[i] = \mathsf{current}[i] + \mathsf{current}[i - \mathsf{distance}]\) // reads only \(\mathsf{current}\), writes only \(\mathsf{next}\)
- else: \(\mathsf{next}[i] = \mathsf{current}[i]\)
- Barrier() // the step is complete
- exchange the names \(\mathsf{current}\) and \(\mathsf{next}\)
- }
- \(y_i = \mathsf{current}[i]\)
Line 2 copies the input into shared memory, and the barrier in line 3 makes sure that every value is there before any thread reads the value of a neighbor. Lines 5 and 6 perform 1 step of Figure 21.4. For example, in the step with \(\mathsf{distance} = 2\), thread 6 executes line 5 and computes \(\mathsf{next}[6] = \mathsf{current}[6] + \mathsf{current}[4] = 7 + 4 = 11\), while thread 1 has \(i < \mathsf{distance}\) and executes line 6, which copies \(\mathsf{current}[1] = 4\) unchanged. Line 7 is the barrier that ends the step, and line 8 makes the array written in this step the input of the next step. In Section 21.6, we remove line 7 and then line 8, and we show the wrong values that each removal produces.
21.4.4 Counting the work
In the step with offset \(\mathsf{distance}\), the threads with \(i \ge \mathsf{distance}\) perform 1 addition each, and there are \(n - \mathsf{distance}\) such threads. In our example, the 3 steps therefore perform \(8 - 1 = 7\), \(8 - 2 = 6\) and \(8 - 4 = 4\) additions, \(7 + 6 + 4 = 17\) in all, in 3 steps, whereas the sequential loop performs 7 additions in 7 steps. In general, when \(n\) is a power of 2, the offsets are \(\mathsf{distance} = 2^k\) for \(k = 0, 1, \ldots, \log_2 n - 1\), that is, \(1, 2, \ldots, n/2\). There are \(\log_2 n\) steps, and the work is
\[ \sum_{k=0}^{\log_2 n - 1} (n - 2^k) = n \log_2 n - (n - 1). \]
| Symbol | Meaning | In the example |
|---|---|---|
| \(k\) | number of the step, starting from 0 | 0, 1 or 2 |
| \(2^k\) | the offset \(\mathsf{distance}\) of step \(k\) | 1, 2 or 4 |
| \(n - 2^k\) | additions in step \(k\), 1 per thread with \(i \ge \mathsf{distance}\) | 7, 6 or 4 |
| \(\log_2 n\) | number of steps | \(\log_2 8 = 3\) |
The right-hand side follows because the \(\log_2 n\) terms \(n\) add up to \(n \log_2 n\), and the offsets \(1 + 2 + \cdots + n/2\) add up to \(n - 1\). For our example, this gives \(8 \cdot 3 - 7 = 17\), as counted above. For a block of 1,024 values, the scan takes 10 steps and 11 barriers, and it performs \(1{,}024 \cdot 10 - 1{,}023 = 9{,}217\) additions, where the sequential loop performs 1,023. The Hillis-Steele scan thus pays for its small number of steps with about \(\log_2 n\) times the work of the sequential loop.
Exercises
21.8 Carry out Hillis-Steele-Scan on \((2, 0, 5, 1, 1, 3, 0, 4)\) and write the range under
each cell, as in Figure 21.4.
21.9 How many additions does Hillis-Steele-Scan perform for \(n = 16\), and how many of them
does the sequential loop need?
21.10 In which step does position 5 reach its final value? What does it do in the remaining
steps?
21.5 The Blelloch scan
21.5.1 Work efficiency
An algorithm is work-efficient if it performs, up to a constant factor, no more operations than the best sequential algorithm. The Hillis-Steele scan is not work-efficient: on 1,024 values, it performs 9,217 additions, 9 times the 1,023 additions of the sequential loop. A GPU block can absorb some extra work, since many of its threads would otherwise wait. The extra additions, however, still occupy the arithmetic units and, more importantly, shared memory, which line 5 reads twice and writes once for every addition. In 1990, Blelloch described a scan that performs \(2(n - 1)\) additions in \(2 \log_2 n\) steps. For our 8 values, these are 14 additions in 6 steps. The scan works in 2 phases on a single array, which we now describe in turn.
21.5.2 The up-sweep
The first phase builds the tree of Figure 21.3 in place, in the array itself. As before, we call the distance between the 2 positions that are added \(\mathsf{distance}\). At distance 1, every odd position \(\mathsf{right}\) adds the value of position \(\mathsf{right} - 1\), so that positions 1, 3, 5 and 7 receive the pair sums 4, 7, 5 and 9. At distance 2, positions 3 and 7 add the values of positions 1 and 5, and receive \(7 + 4 = 11\) and \(9 + 5 = 14\). At distance 4, position 7 adds the value of position 3 and receives \(14 + 11 = 25\). Figure 21.5 shows the 3 levels.
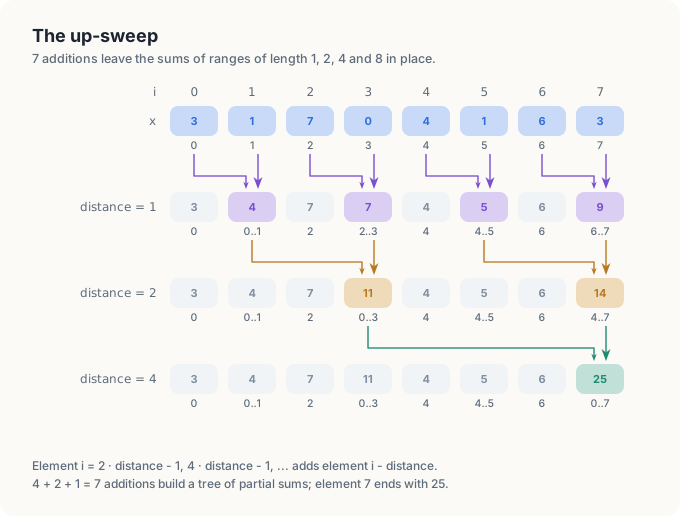
At each level, the number of additions halves. The up-sweep performs \(4 + 2 + 1 = 7\) additions, and \(n - 1\) in general, the same number as the sequential loop. It leaves the array holding a mixture of results, however. Position 7 holds the total, 25, and position 3 holds \(S[0..3] = 11\), which is \(y_3\). Position 5, on the other hand, holds \(S[4..5] = 5\), which is neither \(y_5 = 16\) nor \(e_5 = 15\). The second phase must complete such totals.
Key observation After the up-sweep, every position in the right half of the array needs, to complete its total, the sum of the whole left half, and that sum, \(S[0..3] = 11\), already sits at position 3. The same holds inside each half and each quarter. Every node of the tree needs the sum of everything to its left. For a left child that sum is its parent’s, and for a right child it is its parent’s plus the total of its left sibling. Passing these sums down the tree takes 1 addition per node, \(n - 1\) in all.
For example, position 5 holds \(S[4..5] = 5\) and lies in the right half. To obtain its exclusive total \(e_5 = S[0..4]\), it lacks the sum of the left half, 11, which sits at position 3, and the value \(x_4 = 4\), which sits at position 4: \(e_5 = 11 + 4 = 15\).
21.5.3 The down-sweep
The second phase starts by setting the last position, the root of the tree, to 0, since nothing lies to the left of the whole array. Then, from the root downwards, the down-sweep visits every pair \((\mathsf{right} - \mathsf{distance}, \mathsf{right})\) of the up-sweep again, in the reverse order of the levels. At each pair, the left position receives the value of the right position, which is the sum of everything to the left of the pair. The right position receives that same value plus the old value of the left position, which is the total of its left sibling. Figure 21.6 shows the 3 levels on our values.
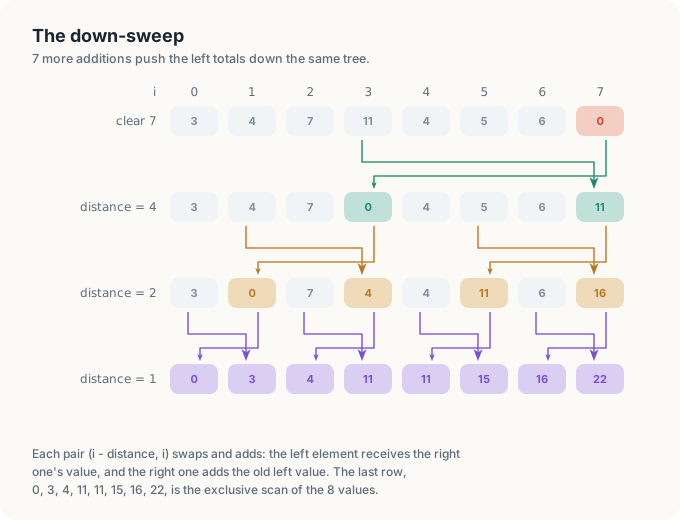
Let us follow position 5 through the down-sweep. At distance 2, the pair (5, 7) holds the values (5, 11). Position 5 receives 11, the sum of everything to the left of the pair, and position 7 receives \(11 + 5 = 16\). At distance 1, the pair (4, 5) holds (4, 11). Position 4 receives 11, and position 5 receives \(11 + 4 = 15\), which is \(e_5\). The last row is the exclusive scan \((0, 3, 4, 11, 11, 15, 16, 22)\), and adding \(x_i\) to each position gives the inclusive scan.
21.5.4 The algorithm
A block of \(n/2\) threads scans \(n\) values, 2 per thread, in 1 array \(\mathsf{cells}\) in shared memory. At each level, every pair is handled by 1 thread. At a given distance, thread \(\mathsf{threadIdx{.}x}\) handles the pair whose right position is
\[ \mathsf{right} = (2 \cdot \mathsf{threadIdx{.}x} + 2) \cdot \mathsf{distance} - 1, \]
and only the first \(n/(2 \cdot \mathsf{distance})\) threads have a pair.
| Symbol | Meaning | In the example, \(\mathsf{distance} = 2\) |
|---|---|---|
| \(\mathsf{threadIdx{.}x}\) | index of the thread in the block, from 0 to \(n/2 - 1\) | 0 to 3 |
| \(\mathsf{distance}\) | distance between the 2 positions of a pair | 2 |
| \(\mathsf{right}\) | right position of the pair of thread \(\mathsf{threadIdx{.}x}\) | 3 for \(\mathsf{threadIdx{.}x} = 0\), 7 for \(\mathsf{threadIdx{.}x} = 1\) |
| \(\mathsf{right} - \mathsf{distance}\) | left position of the pair | 1 for \(\mathsf{threadIdx{.}x} = 0\), 5 for \(\mathsf{threadIdx{.}x} = 1\) |
| \(n/(2 \cdot \mathsf{distance})\) | number of pairs, and of threads with a pair | \(8/4 = 2\) |
The right positions of the pairs at a given distance are spaced \(2 \cdot \mathsf{distance}\) apart, starting at \(2 \cdot \mathsf{distance} - 1\), and the formula numbers them in that order. At distance 2, for instance, thread 0 handles the pair (1, 3) and thread 1 the pair (5, 7), while threads 2 and 3 have no pair, since \(n/(2 \cdot \mathsf{distance}) = 2\).
Blelloch-Scan(\(x, y, n\))
- \(\mathsf{first} = 2 \cdot \mathsf{threadIdx{.}x}\) // this thread owns positions first and first + 1; \(n/2\) threads
- \(\mathsf{cells}[\mathsf{first}] = x_{\mathsf{first}}\), \(\mathsf{cells}[\mathsf{first} + 1] = x_{\mathsf{first}+1}\)
- for \(\mathsf{distance} = 1, 2, 4, \ldots\) while \(\mathsf{distance} < n\) { // up-sweep
- Barrier()
- if \(\mathsf{threadIdx{.}x} < n/(2 \cdot \mathsf{distance})\) {
- \(\mathsf{right} = (2 \cdot \mathsf{threadIdx{.}x} + 2) \cdot \mathsf{distance} - 1\)
- \(\mathsf{cells}[\mathsf{right}] = \mathsf{cells}[\mathsf{right}] + \mathsf{cells}[\mathsf{right} - \mathsf{distance}]\)
- }
- }
- Barrier()
- if \(\mathsf{threadIdx{.}x} = 0\): \(\mathsf{cells}[n - 1] = 0\) // the root: nothing to its left
- for \(\mathsf{distance} = n/2, n/4, \ldots, 1\) { // down-sweep
- Barrier()
- if \(\mathsf{threadIdx{.}x} < n/(2 \cdot \mathsf{distance})\) {
- \(\mathsf{right} = (2 \cdot \mathsf{threadIdx{.}x} + 2) \cdot \mathsf{distance} - 1\)
- \(\mathsf{left} = \mathsf{right} - \mathsf{distance}\)
- \((\mathsf{cells}[\mathsf{left}],\ \mathsf{cells}[\mathsf{right}]) = (\mathsf{cells}[\mathsf{right}],\ \mathsf{cells}[\mathsf{right}] + \mathsf{cells}[\mathsf{left}])\) // swap and add
- }
- }
- Barrier()
- \(y_{\mathsf{first}} = \mathsf{cells}[\mathsf{first}]\), \(y_{\mathsf{first}+1} = \mathsf{cells}[\mathsf{first}+1]\) // the exclusive scan
Lines 3 to 9 are the up-sweep of Figure 21.5, and lines 12 to 19 are the down-sweep of Figure 21.6. Within 1 level, the pairs of different threads do not overlap, so no 2 threads touch the same position between 2 barriers. Line 17 assigns both positions at once from their old values. In code, this means that the old left value must be kept in a register before the left position is overwritten.
21.5.5 Comparing the 3 scans
The up-sweep performs \(n - 1\) additions, and so does the down-sweep, so the Blelloch scan performs \(2(n - 1)\) additions in total. This is 14 for our example and 2,046 for 1,024 values, twice the work of the sequential loop and about 1/4.5 of the work of the Hillis-Steele scan. The Blelloch scan pays for this saving with steps. It has \(2 \log_2 n\) levels, 20 for 1,024 values, and 21 barriers. Figure 21.7 compares the three algorithms.
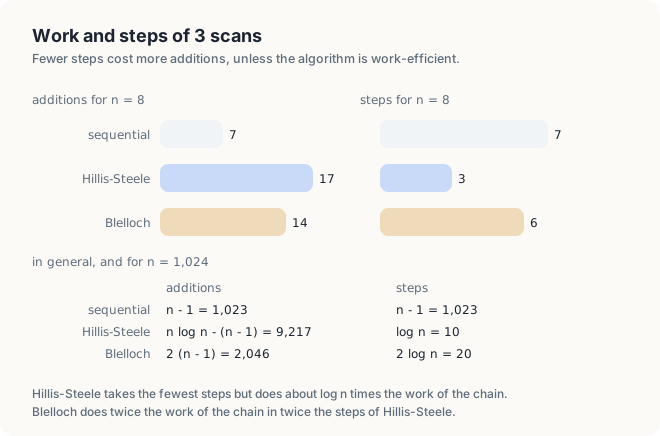
Figure 21.7 alone does not tell us which of the 2 parallel scans is faster on a GPU. The answer depends on what a step, an addition and a barrier cost on the hardware, and we measure both scans in Section 21.11.
Exercises
21.11 Carry out the up-sweep and the down-sweep on \((2, 0, 5, 1, 1, 3, 0, 4)\).
21.12 At distance 2 of the up-sweep, which threads have a pair, and which positions
do they read and write?
21.13 Why must line 11 set \(\mathsf{cells}[n-1]\) to 0 rather than leave the total there? What would the
last row of Figure 21.6 be without it?
21.6 Correctness
The threads of a block run at different speeds, and they read and write the same slots of shared memory. Without coordination, 2 things can go wrong. A thread can read a slot before the step that fills it is over, or it can read a slot that the current step has already changed. In this section, we remove line 7 of Hillis-Steele-Scan, and then line 8, and we follow each error as it happens on our example.
21.6.1 The barrier at the end of a step
Suppose that we delete line 7, the barrier that ends each step. In the step with offset 1, thread 2 computes \(\mathsf{next}[2] = \mathsf{current}[2] + \mathsf{current}[1] = 7 + 1 = 8\) and moves on to the step with offset 2. In that step, the names have been exchanged, so thread 2 reads the array that was \(\mathsf{next}\) in the previous step, and it needs the value at position 0. Thread 0, however, is running late and has not yet written \(\mathsf{next}[0] = \mathsf{current}[0] = 3\), as Figure 21.8 shows.
The slot still holds whatever it held before the kernel started, and thread 2 computes its new value as \(8 + \mathsf{next}[0]\) from that content. On the GPU we measured, the slot held 0, so the result is \(y_2 = 8\) instead of 11. We removed the barrier from the C++ program and ran it, and it printed the following lines.
$ ./nobarrier # line 7 deleted
scans of 3 1 7 0 4 1 6 3
Hillis-Steele 3 4 8 7 7 6 14 9
Position 2 holds 8, the value predicted by Figure 21.8. The 5 positions after it are wrong as well, because each of them read at least 1 slot too early. The output was the same in 3 runs, and the program reported FAILED for the array of 16,777,216 values. Line 7 prevents this error, since no thread may start a step until every thread has finished the previous one.
21.6.2 The second buffer
Now we restore line 7 and delete line 8 instead, so that every step reads and writes the same array, and line 5 becomes \(\mathsf{current}[i] = \mathsf{current}[i] + \mathsf{current}[i - \mathsf{distance}]\). In the step with offset 1, thread 1 computes \(\mathsf{current}[1] = \mathsf{current}[1] + \mathsf{current}[0] = 1 + 3 = 4\). Thread 2 is late, and when it reads \(\mathsf{current}[1]\), it finds the new value 4 instead of the old value 1, as Figure 21.9 shows.
Thread 2 therefore computes \(\mathsf{current}[2] = 7 + 4 = 11\) instead of 8, and its range now counts \(x_0\) twice. After the step with offset 2, it holds \(11 + 3 = 14\), and we get \(y_2 = 14\) instead of 11. We deleted line 8 from the C++ program and ran it 3 times. The 8 values came out right every time, as in the following output.
$ ./inplace # line 8 deleted
scans of 3 1 7 0 4 1 6 3
Hillis-Steele 3 4 11 11 15 16 22 25
The scan of 16,777,216 values, however, failed in all 3 runs. We added to the program a count of the wrong values and the position of the first one, and the 3 runs printed the following lines.
Hillis-Steele: 16768480 of 16777216 values wrong, first at 8288 (tile 8, position 96)
Hillis-Steele: 16766720 of 16777216 values wrong, first at 6848 (tile 6, position 704)
Hillis-Steele: 16764032 of 16777216 values wrong, first at 6848 (tile 6, position 704)
In almost every tile, every thread read \(\mathsf{current}[i - \mathsf{distance}]\) before the thread that owns that slot had updated it, and the tile was scanned correctly. A single block, scanned on its own 1,000 times in a separate test, never went wrong. In a few of the 16,384 tiles, however, 1 warp updated its values before another warp had read them, as in Figure 21.9, and the wrong total of that tile reached every later value through the tile offsets of Section 21.7. Nothing in the hardware or in CUDA fixes the order of 2 warps inside a step, so a test on a small input cannot show that this kernel is correct. Only an argument about every possible order can, and for the in-place kernel, that argument fails at Figure 21.9.
21.6.3 A proof of correctness
With lines 7 and 8 in place, we can prove that Hillis-Steele-Scan computes the inclusive scan. The idea is to watch the value \(\mathsf{current}[i]\) of 1 thread grow step by step, as in Figure 21.10. At the start of the step with offset \(\mathsf{distance}\), this value is the sum of the last \(\mathsf{distance}\) inputs up to and including position \(i\), or of all inputs from position 0 if there are fewer than \(\mathsf{distance}\) of them. We call this range of inputs the window of thread \(i\). For thread 6, the window has length 1, 2 and 4 at the start of the 3 steps, and it then covers all 7 inputs \(x_0\) to \(x_6\).
The window of \(\mathsf{distance}\) inputs that ends at position \(i\) begins at position \(i - \mathsf{distance} + 1\), but never before position 0. We write its first position as
\[ \ell(i, \mathsf{distance}) = \max(0,\ i - \mathsf{distance} + 1). \]
| Symbol | Meaning | Thread 6 |
|---|---|---|
| \(i\) | position of the thread, and last position of its window | 6 |
| \(\mathsf{distance}\) | offset of the step, and length of the window when it fits | 1, 2, 4, then 8 |
| \(\ell(i, \mathsf{distance})\) | first position of the window | 6, 5, 3, then \(\max(0, -1) = 0\) |
For example, at the start of the step with offset 4, thread 6 holds \(S[\ell(6, 4)..6] = S[3..6] = 0 + 4 + 1 + 6 = 11\), as in Figure 21.10.
Theorem 21.1 When Hillis-Steele-Scan finishes, \(y_i = S[0..i]\) for every \(i \in [0, n)\).
Proof. Write \(\ell(i, \mathsf{distance}) = \max(0, i - \mathsf{distance} + 1)\) for the first position of the window. We show that the loop of lines 4 to 9 maintains the invariant
\[ \mathsf{current}[i] = S[\ell(i, \mathsf{distance})\,..\,i] \quad \text{for every } i \in [0, n), \text{ at the start of the iteration with offset } d. \]
Initialization. Before the first iteration, \(\mathsf{distance} = 1\), and line 2 stored \(\mathsf{current}[i] = x_i = S[i..i]\). The barrier in line 3 makes all \(n\) stores complete before any thread reads \(\mathsf{current}\).
Maintenance. Assume that the invariant holds at the start of the iteration with offset \(\mathsf{distance}\). In lines 5 and 6, each thread reads only \(\mathsf{current}\) and writes only its own slot of \(\mathsf{next}\), so every value it reads is a value from the start of the iteration; this excludes the error of Section 21.6.2. If \(i \ge \mathsf{distance}\), thread \(i\) writes \(S[\ell(i, \mathsf{distance})..i] + S[\ell(i - \mathsf{distance}, \mathsf{distance})..i - \mathsf{distance}]\). The second range ends at \(i - \mathsf{distance}\), 1 position before the first range begins, and it starts at \(\ell(i, 2 \cdot \mathsf{distance})\), so by Definition 21.5 the sum is \(S[\ell(i, 2 \cdot \mathsf{distance})..i]\). If \(i < \mathsf{distance}\), then \(\ell(i, \mathsf{distance}) = \ell(i, 2 \cdot \mathsf{distance}) = 0\), and thread \(i\) copies \(S[0..i]\) unchanged. The barrier in line 7 completes every write to \(\mathsf{next}\) before any thread passes it; this excludes the error of Section 21.6.1. After line 8 exchanges the names, \(\mathsf{current}[i] = S[\ell(i, 2 \cdot \mathsf{distance})..i]\) at the start of the iteration with offset \(2 \cdot \mathsf{distance}\).
Termination. The loop ends with the first offset \(\mathsf{distance} \ge n\). Then \(i - \mathsf{distance} + 1 \le 0\) for every \(i < n\), so \(\ell(i, \mathsf{distance}) = 0\) and \(\mathsf{current}[i] = S[0..i]\), and line 10 stores this value.
The maintenance step can be checked on thread 6 in the step with offset 2. At the start of the step, thread 6 holds \(S[5..6] = 7\), and thread 4 holds \(S[3..4] = 4\). The second range ends at position 4, just before the first begins, so thread 6 writes \(S[3..6] = 7 + 4 = 11\), which is the window of length 4 that the invariant requires at the start of the step with offset 4.
The proof uses each of the 3 barriers and the double buffer exactly once, and it uses no fact about the speed of the threads. The same argument, applied level by level, shows that the Blelloch scan is correct; Exercise 21.16 asks for its invariant. Note, finally, that a barrier works only if every thread of the block reaches it. In both scans, the threads without a partner in a step do not leave the loop. They copy their value, or do nothing, and then wait at the barrier with the others.
Rule Every thread of a block must reach every barrier. Never place a barrier where some threads of the block can skip it, and never let a step read a slot that the same step writes.
Exercises
21.14 Without line 7, could thread 7 read a wrong value in the step with offset 4? Give a
schedule in which it does, and the value of \(y_7\) it produces.
21.15 Explain why the proof of Theorem 21.1 breaks if a thread with \(i < \mathsf{distance}\) leaves the loop
early, even though its value no longer changes.
21.16 State an invariant for the up-sweep of Blelloch-Scan: what does \(s[i]\) hold after the
level with distance \(\mathsf{distance}\)?
21.7 Scanning more than 1 block
21.7.1 Tiles
A block holds at most 1,024 threads, and its threads cooperate only through its own shared memory and its own barriers. The arrays that we want to scan, on the other hand, hold millions of values. We therefore cut the array into tiles of 1,024 values, 1 tile per block, and every block scans its tile on its own. The result is correct inside each tile, but every tile has started its totals from 0, whereas the true total at the first value of a tile must include every value of the earlier tiles.
Figure 21.11 shows how this is repaired, on our 8 values cut into 2 tiles of 4. Tile 0, \((3, 1, 7, 0)\), scans to \((3, 4, 11, 11)\), and tile 1, \((4, 1, 6, 3)\), scans to \((4, 5, 11, 14)\). The last value of each tile scan is the total of the tile, 11 and 14. The inclusive scan of these totals, \((11, 25)\), says that the values before tile 1 add up to 11. Adding 11 to every value of tile 1 gives \((15, 16, 22, 25)\), and the whole scan is then correct.
21.7.2 The algorithm
The scan of the tile totals is itself a scan, of an array 1,024 times shorter than the input, so the procedure can call itself. For example, 16,777,216 values form 16,384 tiles, whose 16,384 totals form 16 tiles, whose 16 totals fit in a single tile. In the following procedure, \(\mathsf{tiles}\) is the number of tiles, \(\mathsf{totals}_{\mathsf{tile}}\) is the total of tile \(\mathsf{tile}\), and \(\mathsf{offsets}\) is the inclusive scan of the totals, so that \(\mathsf{offsets}_{\mathsf{tile}-1}\) is the sum of all values before tile \(\mathsf{tile}\). In our example, \(\mathsf{tiles} = 2\), \(\mathsf{totals} = (11, 14)\), \(\mathsf{offsets} = (11, 25)\), and tile 1 receives \(\mathsf{offsets}_0 = 11\).
Scan(\(x, y, n\))
- \(\mathsf{tiles} = \lceil n / 1024 \rceil\) // the number of tiles
- launch 1 block per tile: scan the tile of \(x\) into \(y\), write its total to \(\mathsf{totals}_{\mathsf{tile}}\)
- if \(\mathsf{tiles} > 1\) {
- Scan(\(\mathsf{totals}, \mathsf{offsets}, \mathsf{tiles}\)) // the tile totals, recursively
- launch 1 block per tile: add \(\mathsf{offsets}_{\mathsf{tile}-1}\) to every value of tile \(\mathsf{tile} \ge 1\)
- }
The 2 launches of lines 2 and 5 take the place of a barrier across blocks, which the GPU does not provide. A kernel launch starts only after the previous launch on the same stream has finished, so line 5 reads totals that are complete.
21.7.3 Counting the traffic
Any scan must read every input value once and write every output once. For values of 4 bytes, this is 8 bytes per value, if nothing else is stored. Scan moves more than this. Line 2 reads the input and writes the tile scans, and line 5 reads the tile scans again and writes them again, so Scan moves 16 bytes per value, plus 1 total per 1,024 values. On 16,777,216 values, the minimum is 134 MB, and Scan moves 268 MB. A scan that passes the total of each tile directly to the next block while the kernel runs, called a single-pass scan, avoids the second pass; in Chapter 11, we measured one from the CUB library.
Exercises
21.17 Carry out Figure 21.11 with 4 tiles of 2 values. What are the tile totals, their scan, and
the offsets?
21.18 How many levels of recursion does Scan need for \(n = 2^{30}\), and how many tiles does
each level have?
21.8 Stream compaction
21.8.1 The problem
Stream compaction takes an array and a condition, and writes the values that satisfy the condition to the front of an output array, in their input order. It appears wherever a computation produces many candidates and keeps a few of them, for example particles that are still inside a simulation, rays that hit a surface, or detections above a threshold. In our example, we keep the values with \(x \ge 3\). These are 3, 7, 4, 6 and 3, at positions 0, 2, 4, 6 and 7, and the output is \((3, 7, 4, 6, 3)\).
On a CPU, compaction is a single loop with a counter \(\mathsf{count}\) of the values written so far.
Sequential-Compact(\(x, \mathsf{out}, n\))
- \(\mathsf{count} = 0\) // values written so far
- for \(i \in [0, n)\) {
- if \(x_i \ge 3\) {
- \(\mathsf{out}_{\mathsf{count}} = x_i\)
- \(\mathsf{count} = \mathsf{count} + 1\)
- }
- }
- return \(\mathsf{count}\) // the number of kept values
The counter \(\mathsf{count}\) forms a chain like the one of Figure 21.2, because the position of a kept value depends on every earlier decision. For example, when line 4 writes \(x_4 = 4\), the counter holds \(\mathsf{count} = 2\), because 2 values, at positions 0 and 2, were kept before it.
Key observation When line 4 writes \(x_i\), the counter \(\mathsf{count}\) equals the number of kept values before position \(i\). With a flag \(f_i\) that is 1 for a kept value and 0 otherwise, that number is the exclusive scan of the flags at \(i\). A parallel scan gives every kept value its output position at once.
Definition 21.9 Flags and scatter. The flag of a value is 1 if the value is kept and 0 if it is removed. A scatter is a write in which each thread writes its value to a position computed from data, rather than to its own index.
Example. The flags of our values for \(x \ge 3\) are \((1, 0, 1, 0, 1, 0, 1, 1)\); their exclusive scan is \((0, 1, 1, 2, 2, 3, 3, 4)\), and \(x_4 = 4\) is scattered to position 2.
21.8.2 The algorithm
The parallel algorithm computes the flags, scans them, and scatters every kept value to its position. In the following procedure, \(f_i\) is the flag of value \(i\) and \(s_i\) is the inclusive scan of the flags, the number of kept values at positions 0 to \(i\).
Parallel-Compact(\(x, \mathsf{out}, n\))
- for every \(i \in [0, n)\) in parallel: \(f_i = 1\) if \(x_i \ge 3\), else 0 // kernel 1
- \(s\) = the inclusive scan of \(f\) // Scan of Section 21.7
- for every \(i \in [0, n)\) in parallel: if \(f_i = 1\): \(\mathsf{out}_{s_i - 1} = x_i\) // kernel 2, a scatter
- return \(s_{n-1}\)
Line 3 uses \(s_i - 1\), the inclusive scan minus the flag 1 of a kept value, which is the exclusive scan at \(i\). For example, \(x_4 = 4\) has \(f_4 = 1\) and \(s_4 = 3\), since 3 values among positions 0 to 4 are kept, and it is written to position \(3 - 1 = 2\). Figure 21.12 follows the algorithm on our values. The 5 kept values read their positions 0, 1, 2, 3 and 4 from the exclusive scan, and the count of kept values is the last inclusive value, \(s_7 = 5\).
Theorem 21.2 Parallel-Compact writes every kept value exactly once, to a distinct position in \([0, c)\), where \(c\) is the number of kept values, and the output keeps the input order.
Proof. Let \(e_i = s_i - f_i\) be the exclusive scan. Take 2 kept values at positions \(i < j\). The kept values before \(j\) include those before \(i\) and \(i\) itself, so \(e_j \ge e_i + 1\): the positions are distinct and increase with the input position, which is the input order. The first kept value has \(e = 0\), and the last has \(e = c - 1\), since \(c - 1\) kept values precede it. Every position therefore lies in \([0, c)\).
In our example, \(c = 5\), and the kept values at positions 2 and 4 receive \(e_2 = 1\) and \(e_4 = 2\). Since the value at position 2 is itself kept, \(e_4\) is at least \(e_2 + 1\).
The proof also describes the mistake to avoid. If line 3 used the inclusive scan \(s_i\) as the position, every value would land 1 position too far to the right. We made this change in the C++ program, and it printed the following lines.
$ ./inclusive # out[s_i] in place of out[s_i - 1]
compaction of 3 1 7 0 4 1 6 3, keep x >= 3
flags 1 0 1 0 1 0 1 1
exclusive 0 1 1 2 2 3 3 4
output 0 3 7 4 6
Position 0 keeps whatever the output buffer held, and the last kept value, 3, goes to position 5, which the program does not read. No error is reported, because position 5 lies inside the buffer of 8 values, and the writes are distinct and in bounds, only wrong. Only the comparison with the CPU result detects the mistake.
Exercises
21.19 Compact \((2, 0, 5, 1, 1, 3, 0, 4)\) with the condition \(x \ge 1\): give the flags,
their exclusive scan and the output.
21.20 Change Parallel-Compact so that it writes the removed values, in order, after the kept
ones. Which position does a removed value at index \(i\) receive?
21.9 Compaction with warp votes
21.9.1 Bytes moved per value
Compaction performs almost no arithmetic, so its time is set by the bytes that it moves between the SMs and global memory. We count them per input value of 4 bytes, when half of the values are kept. Kernel 1 reads the value and writes the flag, which is 8 bytes. The scan reads and writes the flags twice, which is 16 bytes, as we counted in Section 21.7.3. Kernel 2 reads the flag, the scan and the value, which is 12 bytes, and writes half a value on average, 2 bytes, for 14 bytes in all. In total, Parallel-Compact moves \(8 + 16 + 14 = 38\) bytes per value. The least that any compaction must move is 1 read of each value and 1 write of each kept value, which is \(4 + 2 = 6\) bytes, as Figure 21.13 shows.
Most of the 38 bytes are spent on storing the flags and their scan and on reading them back. A method that computes the flags and the positions inside each block, while it reads the values, never has to store them in global memory. The tool for this is the warp vote, which we now introduce.
21.9.2 Warps and ballots
Definition 21.10 Warp and lane. A warp is a group of 32 threads of a block that the SM executes together, 1 instruction for all 32 at a time. Threads \(32 \cdot \mathsf{warp}\) to \(32 \cdot \mathsf{warp} + 31\) of a block form warp \(\mathsf{warp}\). The position of a thread inside its warp, 0 to 31, is its lane.
Example. A block of 256 threads has 8 warps; thread 70 is lane 6 of warp 2.
In the example of Definition 21.10, warp 2 consists of threads \(32 \cdot 2 = 64\) to \(64 + 31 = 95\), and thread 70 lies \(70 - 64 = 6\) places after the first of them. In general, thread \(\mathsf{threadIdx{.}x}\) belongs to warp \(\lfloor \mathsf{threadIdx{.}x} / 32 \rfloor\), and its lane is \(\mathsf{threadIdx{.}x} \bmod 32\).
Definition 21.11 Ballot and population count. A ballot is an instruction that all 32 lanes of a warp execute together, each with a condition; it returns to every lane the same 32-bit word, whose bit \(\mathsf{step}\) is 1 if the condition of lane \(\mathsf{step}\) is true. The population count of a word, popcount for short, is the number of its bits that are 1.
Example. For 8 lanes holding our values, the ballot of \(x \ge 3\) has the bits \((1, 0, 1, 0, 1, 0, 1, 1)\) for lanes 0 to 7, and its popcount is 5.
A ballot thus hands every lane the flags of the whole warp in 1 instruction, and every lane can compute its own exclusive scan from it. Lane \(\mathsf{step}\) needs the number of kept values in the lanes below it, that is, the number of 1 bits among bits 0 to \(\mathsf{step} - 1\) of the ballot. The word \(2^\mathsf{step} - 1\) has exactly these \(\mathsf{step}\) bits set to 1 and all others set to 0. For \(\mathsf{step} = 4\), for example, \(2^4 - 1 = 15\), which is 1111 in binary. Combining the ballot with this mask by a bitwise AND keeps only the bits of the lanes below lane \(\mathsf{step}\), and the popcount of the result is the exclusive scan of lane \(\mathsf{step}\). Figure 21.14 does this for lane 4 of a warp drawn with 8 lanes. The bits of lanes 0 to 3 are \((1, 0, 1, 0)\), their popcount is 2, and \(x_4 = 4\) therefore goes to position 2, as in Figure 21.12.
21.9.3 The algorithm
The method runs two kernels on tiles of 1,024 values, with 1 block of 256 threads per tile, and each thread handles 4 values. The first kernel counts the kept values of every tile. Scan then turns the 16,384 counts into the position of the first kept value of each tile. The second kernel reads the values again and places every kept value after the kept values of the earlier tiles, of the earlier steps of its own tile, of the earlier warps of the step, and of the earlier lanes of its warp.
In the following procedure, \(\mathsf{blockIdx{.}x}\) is the number of the block, which is also the number of its tile, \(\mathsf{threadIdx{.}x}\) is the index of the thread in the block, \(\mathsf{warp}\) is its warp, and \(\mathsf{lane}\) is its lane. The block processes its tile in 4 steps \(\mathsf{step} = 0, 1, 2, 3\) of 256 values each. The shared array \(\mathsf{counts}\) holds the count of kept values of each of the 8 warps in the current step, and \(\mathsf{next}\) is the output position at which the kept values of the current step begin.
Compact-Votes(\(x, \mathsf{out}, n\))
- \(\mathsf{next}\) = the scanned count of tiles \(0\) to \(\mathsf{blockIdx{.}x} - 1\) // 0 for \(\mathsf{blockIdx{.}x} = 0\)
- for \(\mathsf{step} \in [0, 4)\) {
- \(i = 1024 \cdot \mathsf{blockIdx{.}x} + 256 \cdot \mathsf{step} + \mathsf{threadIdx{.}x}\), \(\mathsf{keep} = (i < n\) and \(x_i \ge 3)\)
- \(\mathsf{votes}\) = Ballot(\(\mathsf{keep}\))
- lane 0 of warp \(\mathsf{warp}\): \(\mathsf{counts}[\mathsf{warp}]\) = Popc(\(\mathsf{votes}\)) // \(\mathsf{counts}\) in shared memory
- Barrier()
- \(\mathsf{before} = \mathsf{counts}[0] + \cdots + \mathsf{counts}[\mathsf{warp} - 1]\), \(\mathsf{total} = \mathsf{counts}[0] + \cdots + \mathsf{counts}[7]\)
- if \(\mathsf{keep}\): \(\mathsf{out}[\mathsf{next} + \mathsf{before} + \)Popc\((\mathsf{votes} \wedge (2^{lane} - 1))] = x_i\)
- \(\mathsf{next} = \mathsf{next} + \mathsf{total}\)
- Barrier() // \(\mathsf{counts}\) is read before the next step writes it
- }
| Symbol | Meaning | Thread 70 of block 1, step 2 |
|---|---|---|
| \(\mathsf{blockIdx{.}x}\) | number of the block and of its tile | 1 |
| \(\mathsf{step}\) | step within the tile, 256 values per step | 2 |
| \(\mathsf{threadIdx{.}x}\) | index of the thread in the block | 70 |
| \(i = 1024 \cdot \mathsf{blockIdx{.}x} + 256 \cdot \mathsf{step} + \mathsf{threadIdx{.}x}\) | index of the value the thread handles | \(1{,}024 + 512 + 70 = 1{,}606\) |
| \(\mathsf{warp}\), \(\mathsf{lane}\) | warp of the thread and its lane in the warp | 2 and 6 |
| \(\mathsf{before}\) | kept values in warps 0 to \(\mathsf{warp} - 1\) of this step | \(\mathsf{counts}[0] + \mathsf{counts}[1]\) |
| \(\mathsf{total}\) | kept values in all 8 warps of this step | \(\mathsf{counts}[0] + \cdots + \mathsf{counts}[7]\) |
The index \(i\) in line 3 is built from three parts. The tile of block \(\mathsf{blockIdx{.}x}\) begins at value \(1024 \cdot \mathsf{blockIdx{.}x}\), step \(\mathsf{step}\) begins \(256 \cdot \mathsf{step}\) values later, and thread \(\mathsf{threadIdx{.}x}\) takes the value \(\mathsf{threadIdx{.}x}\) places after that. Line 8 then adds 4 counts to find the output position of a kept value: the kept values of the earlier tiles and earlier steps, which are in \(\mathsf{next}\), those of the earlier warps of the step, which are in \(\mathsf{before}\), and those of the earlier lanes of the warp, which are the popcount of the ballot under the mask \(2^{lane} - 1\).
The order of the positions is therefore the order of the input. Value \(1024 \cdot \mathsf{blockIdx{.}x} + 256 \cdot \mathsf{step} + \mathsf{threadIdx{.}x}\) is processed in step \(\mathsf{step}\), by warp \(\lfloor \mathsf{threadIdx{.}x} / 32 \rfloor\), in lane \(\mathsf{threadIdx{.}x} \bmod 32\). Line 8 orders the kept values first by tile, then by step, then by warp, and then by lane, which is the order of their indices. The argument of Theorem 21.2 then applies unchanged. The first kernel, Count-Kept, consists of lines 2 to 6, with \(\mathsf{next}\) replaced by a running count, followed by the sum of the 8 warp counts.
With half of the values kept, this method reads the values twice and writes the kept values once, which is \(4 + 4 + 2 = 10\) bytes per value, and the scan of 1 count per 1,024 values adds almost nothing. Figure 21.13 compares the two methods.
Exercises
21.21 For a warp of 32 lanes in which lanes 3, 4, 10 and 31 keep their values, give the ballot
as a binary number and the position of lane 10.
21.22 Why does line 3 compute the condition \(i < n\) instead of skipping line 4 for the lanes
beyond the end of the array?
21.10 Implementation
21.10.1 The Hillis-Steele kernel
We now turn the algorithms into code. The following listing implements Hillis-Steele-Scan for tiles of 1,024 values and blocks of 1,024 threads; each block scans 1 tile and writes the total of its tile.
Listing 21.1 The Hillis-Steele scan of 1 tile.
mod kernels {
// ...
/// Hillis-Steele: 1,024 threads, 1 element each, 2 buffers in shared memory.
#[kernel]
#[launch_contract(domain = 1, block = (1024, 1, 1))]
pub fn scan_hillis_steele(
x: &[u32],
mut y: DisjointSlice<u32>,
mut sums: DisjointSlice<u32>,
) {
static mut BUF: SharedArray<u32, 2048> = SharedArray::UNINIT;
let idx = thread::index_1d();
let index = idx.get();
let thread_idx = thread::threadIdx_x() as usize;
// SAFETY: each thread writes only its own slot thread_idx, before the barrier.
unsafe { BUF[thread_idx] = if index < x.len() { x[index] } else { 0 } };
thread::sync_threads();
let mut src = 0;
let mut step = 0usize;
#[unroll]
while step < 10 {
let distance = 1 << step; // 1, 2, 4, ..., 512
let dst = TILE - src;
// SAFETY: a step reads only buffer src and writes only this thread's slot of
// buffer dst; the barrier ends the step before the next one reads buffer dst.
unsafe {
let mut value = BUF[src + thread_idx];
if thread_idx >= distance {
value += BUF[src + thread_idx - distance];
}
BUF[dst + thread_idx] = value;
}
thread::sync_threads();
src = dst;
step += 1;
}
// SAFETY: after the last barrier the buffers are only read.
let total = unsafe { BUF[src + thread_idx] };
if let Some(out) = y.get_mut(idx) {
*out = total;
}
if thread_idx == TILE - 1 {
let block = thread::blockIdx_x() as usize;
// SAFETY: only the last thread of each block writes, at its own block number.
unsafe { *sums.get_unchecked_mut(block) = total };
}
}
// ...
}// Hillis-Steele: 1,024 threads, 1 element each, 2 buffers in shared memory.
__global__ void scanHillisSteele(const unsigned* x, unsigned* y, unsigned* sums, int n)
{
__shared__ unsigned buf[2 * TILE];
int index = blockIdx.x * TILE + threadIdx.x;
buf[threadIdx.x] = index < n ? x[index] : 0;
__syncthreads();
int src = 0;
for (int distance = 1; distance < TILE; distance *= 2) {
int dst = TILE - src;
unsigned value = buf[src + threadIdx.x];
if (threadIdx.x >= distance) {
value += buf[src + threadIdx.x - distance];
}
buf[dst + threadIdx.x] = value;
__syncthreads(); // the step is complete before any read
src = dst;
}
if (index < n) {
y[index] = buf[src + threadIdx.x];
}
if (threadIdx.x == TILE - 1) {
sums[blockIdx.x] = buf[src + threadIdx.x];
}
}
The load into the first buffer is line 2 of the pseudocode, and the first barrier is line 3. The
loop over step is lines 4 to 9, with \(\mathsf{distance} = 2^{\mathsf{step}}\), so that steps 0, 1
and 2 have the distances 1, 2 and 4. The 2 buffers \(\mathsf{current}\) and \(\mathsf{next}\) are the two halves of 1 shared array of 2,048
values, and src and dst are the offsets of these halves, 0 or 1,024. The assignment
src = dst at the end of the loop is line 8, the exchange of the names. The barrier inside the
loop is line 7, and it stands outside every if, so every thread reaches it. Finally, the last
thread of the block also writes the total of the tile to sums, for line 2 of Scan.
The two languages differ in 3 places. First, shared memory in cuda-oxide is a static mut of type
SharedArray<u32, 2048>, whose length is part of its type, whereas C++ declares a __shared__
array. Every access to the shared array is unsafe in Rust, because the compiler cannot see the
barriers that make the accesses safe, so each unsafe block carries a // SAFETY: comment that
states the argument of Section 21.6.3. Second, the output y has the type DisjointSlice<u32>,
which can be written only through get_mut(idx), with the index that thread::index_1d() returned
to this thread. With one thread per value, the type itself proves that no 2 threads write the same
element, and the write needs no unsafe. The total, which is written at the block number rather
than at the thread index, uses get_unchecked_mut with its own safety comment. Third, the loop
runs over a counter step rather than over distance. For a loop that doubles distance, the cuda-oxide
compiler did not unroll the loop and reported “no recognized induction variable”. A counter that
grows by 1 is recognized, and distance is computed from it.
21.10.2 The Blelloch kernel
The following listing implements Blelloch-Scan for blocks of 512 threads, each of which handles 2 of the 1,024 values of a tile. The kernel converts the exclusive result of line 21 into the inclusive scan by adding the 2 inputs, which each thread kept in registers. Thread 0 also saves the total from \(\mathsf{cells}[1023]\) before line 11 replaces it with 0.
Listing 21.2 The Blelloch scan of 1 tile.
mod kernels {
// ...
/// Blelloch: 512 threads, 2 elements each, 1 buffer; an up-sweep, then a down-sweep.
#[kernel]
#[launch_contract(domain = 1, block = (512, 1, 1))]
pub fn scan_blelloch(
x: &[u32],
mut y: DisjointSlice<u32>,
mut sums: DisjointSlice<u32>,
) {
static mut CELLS: SharedArray<u32, 1024> = SharedArray::UNINIT;
let thread_idx = thread::threadIdx_x() as usize;
let block = thread::blockIdx_x() as usize;
let index = block * TILE + 2 * thread_idx;
let first = if index < x.len() { x[index] } else { 0 };
let second = if index + 1 < x.len() { x[index + 1] } else { 0 };
// SAFETY: each thread writes only its own 2 slots, before a barrier.
unsafe {
CELLS[2 * thread_idx] = first;
CELLS[2 * thread_idx + 1] = second;
}
let mut step = 0usize;
#[unroll]
while step < 10 {
let distance = 1 << step; // up-sweep: 1, 2, 4, ..., 512
thread::sync_threads();
if thread_idx < TILE / (2 * distance) {
let right = (2 * thread_idx + 2) * distance - 1;
// SAFETY: at each distance, the pairs (right - distance, right) of
// different threads are disjoint, and the barriers separate the levels.
unsafe { CELLS[right] += CELLS[right - distance] };
}
step += 1;
}
thread::sync_threads();
if thread_idx == 0 {
// SAFETY: thread 0 alone touches slot TILE - 1 between 2 barriers.
unsafe {
*sums.get_unchecked_mut(block) = CELLS[TILE - 1];
CELLS[TILE - 1] = 0;
}
}
let mut step = 0usize;
#[unroll]
while step < 10 {
let distance = 512 >> step; // down-sweep: 512, 256, ..., 1
thread::sync_threads();
if thread_idx < TILE / (2 * distance) {
let right = (2 * thread_idx + 2) * distance - 1;
// SAFETY: as in the up-sweep, each pair belongs to 1 thread per level.
unsafe {
let left = CELLS[right - distance];
CELLS[right - distance] = CELLS[right];
CELLS[right] += left;
}
}
step += 1;
}
thread::sync_threads();
// SAFETY: after the last barrier CELLS is only read; each thread alone writes its 2
// elements of y, and both lie below y.len() when the test passes.
unsafe {
if index < y.len() {
*y.get_unchecked_mut(index) = CELLS[2 * thread_idx] + first;
}
if index + 1 < y.len() {
*y.get_unchecked_mut(index + 1) = CELLS[2 * thread_idx + 1] + second;
}
}
}
// ...
}// Blelloch: 512 threads, 2 elements each, 1 buffer; an up-sweep, then a down-sweep.
__global__ void scanBlelloch(const unsigned* x, unsigned* y, unsigned* sums, int n)
{
__shared__ unsigned cells[TILE];
int index = blockIdx.x * TILE + 2 * threadIdx.x;
unsigned first = index < n ? x[index] : 0;
unsigned second = index + 1 < n ? x[index + 1] : 0;
cells[2 * threadIdx.x] = first;
cells[2 * threadIdx.x + 1] = second;
for (int distance = 1; distance < TILE; distance *= 2) {
__syncthreads();
if (threadIdx.x < TILE / (2 * distance)) {
int right = (2 * threadIdx.x + 2) * distance - 1;
cells[right] += cells[right - distance];
}
}
__syncthreads();
if (threadIdx.x == 0) {
sums[blockIdx.x] = cells[TILE - 1];
cells[TILE - 1] = 0;
}
for (int distance = TILE / 2; distance >= 1; distance /= 2) {
__syncthreads();
if (threadIdx.x < TILE / (2 * distance)) {
int right = (2 * threadIdx.x + 2) * distance - 1;
unsigned left = cells[right - distance];
cells[right - distance] = cells[right];
cells[right] += left;
}
}
__syncthreads();
if (index < n) {
y[index] = cells[2 * threadIdx.x] + first; // exclusive plus own: inclusive
}
if (index + 1 < n) {
y[index + 1] = cells[2 * threadIdx.x + 1] + second;
}
}
The loops of the up-sweep and the down-sweep are lines 3 to 9 and lines 12 to 19 of the
pseudocode, with right = (2 * thread_idx + 2) * distance - 1 as in line 6. The swap-and-add of line 17 keeps the old
left value in the register left before it overwrites the left position. We let each thread write 2
elements of y, at \(\mathsf{first}\) and \(\mathsf{first} + 1\), which are not the index of the
thread, so the Rust kernel writes them through get_unchecked_mut, and the safety comment states
that the 2 positions belong to that thread alone.
21.10.3 The scan of many tiles
The following listing implements Scan of Section 21.7.2 on the host. The first function launches the kernel that scans every tile, and the second function is the recursive procedure itself. The 3 tile kernels have the same interface, so the functions take the method as a parameter.
Listing 21.3 The scan of an array of any length.
/// Scans every tile of 1,024 elements on its own and writes the tile totals.
fn scan_tiles(
module: &Module,
stream: &Arc<CudaStream>,
method: Method,
x: &DeviceBuffer<u32>,
y: &mut DeviceBuffer<u32>,
sums: &mut DeviceBuffer<u32>,
) -> Result<(), Error> {
let tiles = x.len().div_ceil(TILE) as u32;
match method {
Method::HillisSteele => {
let grid = LaunchConfig1D::new(tiles, 1024, 0);
let config = module.prepare_scan_hillis_steele(grid)?;
module.scan_hillis_steele(stream, &config, x, y, sums)?;
}
Method::Blelloch => {
let grid = LaunchConfig1D::new(tiles, 512, 0);
let config = module.prepare_scan_blelloch(grid)?;
module.scan_blelloch(stream, &config, x, y, sums)?;
}
Method::Warps => {
let grid = LaunchConfig1D::new(tiles, 256, 0);
let config = module.prepare_scan_warps(grid)?;
module.scan_warps(stream, &config, x, y, sums)?;
}
}
Ok(())
}
/// Inclusive scan: the tiles, then the tile totals (by the same function), then offsets.
fn scan(
module: &Module,
stream: &Arc<CudaStream>,
method: Method,
x: &DeviceBuffer<u32>,
y: &mut DeviceBuffer<u32>,
levels: &mut [(DeviceBuffer<u32>, DeviceBuffer<u32>)],
) -> Result<(), Error> {
let tiles = x.len().div_ceil(TILE) as u32;
let ((totals, scanned), rest) = levels.split_first_mut().ok_or("no level left")?;
scan_tiles(module, stream, method, x, y, totals)?;
if tiles > 1 {
scan(module, stream, method, totals, scanned, rest)?;
let config = module.prepare_add_offsets(LaunchConfig1D::new(tiles, 256, 0))?;
module.add_offsets(stream, &config, y, scanned)?;
}
Ok(())
}// Scans every tile of 1,024 elements on its own and writes the tile totals.
void scanTiles(Method method, const unsigned* x, unsigned* y, unsigned* sums, int n)
{
int tiles = (n + TILE - 1) / TILE;
if (method == HILLIS_STEELE) {
scanHillisSteele<<<tiles, TILE>>>(x, y, sums, n);
} else if (method == BLELLOCH) {
scanBlelloch<<<tiles, TILE / 2>>>(x, y, sums, n);
} else {
scanWarps<<<tiles, 256>>>(x, y, sums, n);
}
}
// Inclusive scan of n elements: the tiles, then the tile totals (in place), then offsets.
void scan(Method method, const unsigned* x, unsigned* y, int n, unsigned* scratch)
{
int tiles = (n + TILE - 1) / TILE;
scanTiles(method, x, y, scratch, n);
if (tiles > 1) {
scan(method, scratch, scratch, tiles, scratch + tiles);
addOffsets<<<tiles, 256>>>(y, scratch, n);
}
}
The C++ function scans the tile totals in place, in scratch, which holds every level of the
recursion one after another. A Rust function, however, cannot borrow 1 buffer as both its input
&[u32] and its output DisjointSlice<u32>. The Rust version therefore gives each level its own
pair of buffers, totals and scanned, which scan_levels allocates once before any timing
starts, and it hands the remaining levels to the recursive call with split_first_mut. Both
versions launch the three kernels on 1 stream, so each launch starts after the previous one has
finished.
21.10.4 The compaction kernels
The following listing implements line 3 of Parallel-Compact, the scatter, in which every thread whose flag is 1 writes its value to the position given by the scan.
Listing 21.4 The scatter of a compaction.
mod kernels {
// ...
/// Writes each kept element at its exclusive scan: the inclusive scan minus its flag 1.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scatter_kept(
x: &[u32],
flags: &[u32],
scanned: &[u32],
mut out: DisjointSlice<u32>,
) {
let index = thread::index_1d().get();
if index < x.len() && flags[index] == 1 {
let at = (scanned[index] - 1) as usize;
// SAFETY: the kept elements receive the distinct positions 0 to count - 1,
// and out holds x.len() >= count elements.
unsafe { *out.get_unchecked_mut(at) = x[index] };
}
}
// ...
}// Writes each kept element at its exclusive scan, the inclusive scan minus its flag of 1.
__global__ void scatterKept(const unsigned* x, const unsigned* flags,
const unsigned* scanned, unsigned* out, int n)
{
int index = blockIdx.x * blockDim.x + threadIdx.x;
if (index < n && flags[index] == 1) {
out[scanned[index] - 1] = x[index];
}
}
Thread \(i\) writes element \(s_i - 1\) of the output, a position computed from the contents of
the scan buffer. No type can express a property of the contents of a buffer, so DisjointSlice
cannot prove that the positions are distinct, and the write uses get_unchecked_mut. Its safety
comment is Theorem 21.2: the kept values receive the distinct positions 0 to \(c - 1\), and the
output holds \(n \ge c\) elements. This argument depends on the scan being complete when the
scatter runs, which the single stream guarantees.
The next listing implements Compact-Votes. Each block processes its tile in 4 steps, and in each step, it computes the output positions with a ballot and the counts of its 8 warps.
Listing 21.5 Compaction with warp votes.
mod kernels {
// ...
/// Writes the kept elements of each tile in order, after those of the earlier tiles.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn compact_votes(
x: &[u32],
threshold: u32,
scanned: &[u32],
mut out: DisjointSlice<u32>,
) {
static mut WARPS: SharedArray<u32, 8> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
let lane = warp::lane_id();
let warp = tid / 32;
let block = thread::blockIdx_x() as usize;
let below = (1u32 << lane) - 1; // the lanes to the left of this one
let mut next = if block > 0 { scanned[block - 1] } else { 0 };
let mut step = 0;
#[unroll]
while step < 4 {
let index = block * TILE + step * 256 + tid;
let keep = index < x.len() && x[index] >= threshold;
let votes = warp::ballot(keep);
if lane == 0 {
// SAFETY: lane 0 of each warp writes its own slot, before the barrier.
unsafe { WARPS[warp] = votes.count_ones() };
}
thread::sync_threads();
let mut before = 0;
let mut total = 0;
let mut other = 0;
#[unroll]
while other < 8 {
// SAFETY: between the 2 barriers the slots are only read.
let count = unsafe { WARPS[other] };
before += if other < warp { count } else { 0 };
total += count;
other += 1;
}
if keep {
let at = (next + before + (votes & below).count_ones()) as usize;
// SAFETY: the kept elements receive the distinct positions 0 to count - 1,
// in input order, and out holds x.len() >= count elements.
unsafe { *out.get_unchecked_mut(at) = x[index] };
}
next += total;
thread::sync_threads();
step += 1;
}
}
}// Writes the kept elements of each tile in order, after those of the earlier tiles.
__global__ void compactVotes(const unsigned* x, unsigned threshold,
const unsigned* scanned, unsigned* out, int n)
{
__shared__ unsigned warps[8];
int lane = threadIdx.x % 32;
int warp = threadIdx.x / 32;
unsigned below = (1u << lane) - 1; // the lanes to the left of this one
unsigned next = blockIdx.x > 0 ? scanned[blockIdx.x - 1] : 0;
for (int step = 0; step < 4; ++step) {
int index = blockIdx.x * TILE + step * 256 + threadIdx.x;
bool keep = index < n && x[index] >= threshold;
unsigned votes = __ballot_sync(0xffffffff, keep);
if (lane == 0) {
warps[warp] = __popc(votes);
}
__syncthreads();
unsigned before = 0;
unsigned total = 0;
for (int other = 0; other < 8; ++other) {
before += other < warp ? warps[other] : 0;
total += warps[other];
}
if (keep) {
out[next + before + __popc(votes & below)] = x[index];
}
next += total;
__syncthreads();
}
}
The call warp::ballot(keep) in Rust and the call __ballot_sync(0xffffffff, keep) in C++ are
line 4 of Compact-Votes, and count_ones() and __popc compute the popcount. The variable
below is the mask \(2^{lane} - 1\) of line 8. Every lane calls the ballot, including the lanes
whose index lies beyond the end of the array, because a ballot needs all 32 lanes of the warp;
those lanes vote false. The shared array \(\mathsf{counts}\) is named WARPS in Rust and warps in C++, and
the 2 barriers that protect it are lines 6 and 10.
Exercises
21.23 In Listing 21.1, y.get_mut(idx) returns None for some threads of the last block.
Which threads, for \(n = 3{,}000\)?
21.24 Rewrite the Blelloch kernel for blocks of 1,024 threads and tiles of 2,048 values. What
must change in scan_tiles?
21.11 Measurements
21.11.1 Platform and method
The measurements come from a Jetson Orin NX 16 GB, an integrated GPU with 8 SMs (sm_87) and 102 GB/s of memory bandwidth. The programs scan 16,777,216 values of 4 bytes, 64 MiB in all, drawn from \([0, 4)\), and they compact 16,777,216 values drawn from \([0, 100)\) at 3 thresholds. Every result is compared value by value with the result computed on the CPU. Each time is the average of 20 runs after 0.4 s of warm-up; between runs of the same program, times varied by up to 10%.
21.11.2 Results
The C++ program printed the following output.
$ ./scan_compaction
...
inclusive scans of 16777216 values, average of 20 runs
method blocks/SM tiles ms GB/s whole ms GB/s
Hillis-Steele 1 5.540 24.2 7.118 18.9
Blelloch 3 4.722 28.4 6.328 21.2
warp shuffles 6 1.750 76.7 3.404 39.4
compaction of 16777216 values in [0, 100), average of 20 runs
keep x >= kept 3 passes ms GB/s warp votes ms GB/s
90 1676698 7.74 9.5 2.28 32.3
50 8387729 8.05 12.5 2.41 41.8
10 15100473 8.46 15.1 2.66 47.9
PASSED
The column “tiles” times line 2 of Scan alone, in which every block scans its tile of 1,024 values and writes its total. The column “whole” times the complete scan of Section 21.7. The GB/s columns divide the bytes that the job needs by the time. These bytes are 1 read of every input and 1 write of every output, which for the scans is \(2 \times 4 \times 16{,}777{,}216 = 134.2\) MB. The column “blocks/SM” gives the number of blocks of each kernel that fit on 1 SM at the same time; the program asks the CUDA runtime for it. The Rust program measured 5.65, 4.74 and 1.76 ms for the tiles and 7.23, 6.35 and 3.46 ms for the whole scans, within 3% of the C++ times, and compaction times within 2% of the C++ times. Figure 21.15 draws the C++ times.
21.11.3 Why the work-efficient scan is not 4.5 times faster
The Blelloch scan performs 2,046 additions per tile and the Hillis-Steele scan 9,217, yet the Blelloch scan is only 1.17 times as fast, 4.72 ms against 5.54 ms. Both take 2.7 to 3.2 times as long as the scan of Chapter 8, which runs at 76.7 GB/s, 75% of the 102 GB/s of the memory. All 3 kernels read and write the same 134.2 MB, so the difference must lie inside the SMs. The difference is explained by three costs, which we take in turn.
The first cost is the barrier. Removing line 7 from the Hillis-Steele kernel, as in Section 21.6.1, gives wrong results, but it lets us measure what the 10 barriers of the loop cost. The broken kernel scanned the tiles in 4.03 ms instead of 5.54 ms, so 27% of the time of the Hillis-Steele scan is spent waiting at barriers.
The second cost is the small number of blocks on an SM. A thread that waits, at a barrier or for a value from global memory, does no work, and the SM hides that wait only if other threads are ready to run in the meantime. The following definition gives this quantity a name.
Definition 21.12 Occupancy. The occupancy of a kernel is the number of its threads, or warps, that an SM holds at the same time, often given as a fraction of the most the SM can hold.
Example. An SM of the measured GPU holds at most 1,536 threads. A block of 1,024 threads leaves room for no second block: one block per SM, 2/3 of the maximum.
The Hillis-Steele kernel runs one block per SM. While that block waits at one of its 11 barriers, or for its tile to arrive from global memory, the SM has nothing else to run. The Blelloch kernel uses blocks of 512 threads and runs 3 of them per SM. Its 22 barriers are twice as many, but while 1 block waits, the 2 others can work. The warp-shuffle kernel runs 6 blocks of 256 threads per SM and waits at only 2 barriers per tile.
The third cost is shared memory. The Hillis-Steele kernel reads 2 values and writes 1 in each of its 10 steps, about 31 accesses to shared memory per value. The Blelloch kernel reads 2 values and writes 1 for every pair of the up-sweep, and writes 2 for every pair of the down-sweep, about 9 accesses per value in all. The warp-shuffle kernel scans 4 values per thread in registers and exchanges values between the lanes of a warp with shuffles, which do not use shared memory at all; it writes only 1 total per warp to shared memory.
We can now see why Figure 21.7 does not predict the measured times. The work in that figure counts additions, and in a GPU block, an addition is the cheapest part of a step. What a step costs is set by its barrier, its accesses to shared memory, and the occupancy that decides whether those waits overlap with other work. The scan of Chapter 8 was designed around these three costs, and it is the scan that the compaction uses.
The whole scan adds 1.58 to 1.65 ms to each tile scan. This is the second pass of Section 21.7.3, which reads and writes all 16,777,216 values again: 134.2 MB in 1.65 ms is 81 GB/s.
21.11.4 Why the warp votes are 3.3 times faster, not 3.8
With half of the values kept, the 3-pass compaction took 8.05 ms and the warp votes took 2.41 ms, a ratio of 3.3. In Section 21.9.1, we predicted the ratio of the bytes moved, \(38 / 10 = 3.8\). Dividing the bytes that each method moves by its time gives the rate at which it used the memory. For the 3 passes, this is \(38 \times 16{,}777{,}216 = 637.5\) MB in 8.05 ms, or 79.2 GB/s, and for the warp votes, it is \(10 \times 16{,}777{,}216 = 167.8\) MB in 2.41 ms, or 69.6 GB/s. Both methods therefore run close to the rate of the memory, and the warp votes are faster because they move fewer bytes. They run at a slightly lower rate because each tile waits at 8 barriers and reads its values twice, in 2 separate kernels, so each kernel has less work with which to overlap its waits.
The time of the 3-pass method hardly changes with the fraction of kept values, from 7.74 to 8.46 ms, because 24 of its 38 bytes, those of the flags and the scan, do not depend on that fraction. The warp votes write more as more values are kept, and their time grows from 2.28 to 2.66 ms.
Exercises
21.25 Compute, from the table, the time per tile of the Blelloch kernel on 1 SM, and the number
of cycles per barrier at a clock of 1 GHz.
21.26 Predict the time of the 3-pass compaction with 90% of the values kept from the byte count,
and compare with the measured value.
21.12 The complete programs
The following listing contains the complete programs of this chapter, in Rust and in CUDA C++. Each program runs the small example, scans and compacts 16,777,216 values with every method, checks every result against the CPU, and prints the times.
Listing 21.6 The complete programs. code/oxide/ch21_scan_compaction/src/main.rs and code/cuda/ch21_scan_compaction/scan_compaction.cu
//! Chapter 21: 3 inclusive scans of a tile (Hillis-Steele, Blelloch, warp shuffles),
//! the scan of a long array, and stream compaction by a scan and by warp votes.
//!
//! cargo oxide run
use std::sync::Arc;
use std::time::{Duration, Instant};
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, LaunchConfig1D};
use cuda_device::{DisjointSlice, SharedArray, cuda_module, device, kernel, launch_contract};
use cuda_device::{thread, warp};
const TILE: usize = 1024; // elements scanned by 1 block
const N: usize = 16 << 20; // elements in the measured runs
type Error = Box<dyn std::error::Error>;
type Levels = Vec<(DeviceBuffer<u32>, DeviceBuffer<u32>)>;
type Module = kernels::LoadedModule;
#[derive(Clone, Copy)]
enum Method {
HillisSteele,
Blelloch,
Warps,
}
const METHODS: [(Method, &str); 3] = [
(Method::HillisSteele, "Hillis-Steele"),
(Method::Blelloch, "Blelloch"),
(Method::Warps, "warp shuffles"),
];
#[cuda_module]
mod kernels {
use super::*;
/// Hillis-Steele: 1,024 threads, 1 element each, 2 buffers in shared memory.
#[kernel]
#[launch_contract(domain = 1, block = (1024, 1, 1))]
pub fn scan_hillis_steele(
x: &[u32],
mut y: DisjointSlice<u32>,
mut sums: DisjointSlice<u32>,
) {
static mut BUF: SharedArray<u32, 2048> = SharedArray::UNINIT;
let idx = thread::index_1d();
let index = idx.get();
let thread_idx = thread::threadIdx_x() as usize;
// SAFETY: each thread writes only its own slot thread_idx, before the barrier.
unsafe { BUF[thread_idx] = if index < x.len() { x[index] } else { 0 } };
thread::sync_threads();
let mut src = 0;
let mut step = 0usize;
#[unroll]
while step < 10 {
let distance = 1 << step; // 1, 2, 4, ..., 512
let dst = TILE - src;
// SAFETY: a step reads only buffer src and writes only this thread's slot of
// buffer dst; the barrier ends the step before the next one reads buffer dst.
unsafe {
let mut value = BUF[src + thread_idx];
if thread_idx >= distance {
value += BUF[src + thread_idx - distance];
}
BUF[dst + thread_idx] = value;
}
thread::sync_threads();
src = dst;
step += 1;
}
// SAFETY: after the last barrier the buffers are only read.
let total = unsafe { BUF[src + thread_idx] };
if let Some(out) = y.get_mut(idx) {
*out = total;
}
if thread_idx == TILE - 1 {
let block = thread::blockIdx_x() as usize;
// SAFETY: only the last thread of each block writes, at its own block number.
unsafe { *sums.get_unchecked_mut(block) = total };
}
}
/// Blelloch: 512 threads, 2 elements each, 1 buffer; an up-sweep, then a down-sweep.
#[kernel]
#[launch_contract(domain = 1, block = (512, 1, 1))]
pub fn scan_blelloch(
x: &[u32],
mut y: DisjointSlice<u32>,
mut sums: DisjointSlice<u32>,
) {
static mut CELLS: SharedArray<u32, 1024> = SharedArray::UNINIT;
let thread_idx = thread::threadIdx_x() as usize;
let block = thread::blockIdx_x() as usize;
let index = block * TILE + 2 * thread_idx;
let first = if index < x.len() { x[index] } else { 0 };
let second = if index + 1 < x.len() { x[index + 1] } else { 0 };
// SAFETY: each thread writes only its own 2 slots, before a barrier.
unsafe {
CELLS[2 * thread_idx] = first;
CELLS[2 * thread_idx + 1] = second;
}
let mut step = 0usize;
#[unroll]
while step < 10 {
let distance = 1 << step; // up-sweep: 1, 2, 4, ..., 512
thread::sync_threads();
if thread_idx < TILE / (2 * distance) {
let right = (2 * thread_idx + 2) * distance - 1;
// SAFETY: at each distance, the pairs (right - distance, right) of
// different threads are disjoint, and the barriers separate the levels.
unsafe { CELLS[right] += CELLS[right - distance] };
}
step += 1;
}
thread::sync_threads();
if thread_idx == 0 {
// SAFETY: thread 0 alone touches slot TILE - 1 between 2 barriers.
unsafe {
*sums.get_unchecked_mut(block) = CELLS[TILE - 1];
CELLS[TILE - 1] = 0;
}
}
let mut step = 0usize;
#[unroll]
while step < 10 {
let distance = 512 >> step; // down-sweep: 512, 256, ..., 1
thread::sync_threads();
if thread_idx < TILE / (2 * distance) {
let right = (2 * thread_idx + 2) * distance - 1;
// SAFETY: as in the up-sweep, each pair belongs to 1 thread per level.
unsafe {
let left = CELLS[right - distance];
CELLS[right - distance] = CELLS[right];
CELLS[right] += left;
}
}
step += 1;
}
thread::sync_threads();
// SAFETY: after the last barrier CELLS is only read; each thread alone writes its 2
// elements of y, and both lie below y.len() when the test passes.
unsafe {
if index < y.len() {
*y.get_unchecked_mut(index) = CELLS[2 * thread_idx] + first;
}
if index + 1 < y.len() {
*y.get_unchecked_mut(index + 1) = CELLS[2 * thread_idx + 1] + second;
}
}
}
/// The inclusive scan of 1 value per lane across a warp (Section 8.7.2).
#[device]
fn warp_scan(mut value: u32) -> u32 {
let lane = warp::lane_id();
let mut step = 0u32;
#[unroll]
while step < 5 {
let offset = 1 << step; // 1, 2, 4, 8, 16
let left = warp::shuffle_up_sync(u32::MAX, value, offset);
if lane >= offset {
value += left;
}
step += 1;
}
value
}
/// The scan of Chapter 8: 256 threads, 4 elements each, warp shuffles and 2 barriers.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scan_warps(
x: &[u32],
mut y: DisjointSlice<u32>,
mut sums: DisjointSlice<u32>,
) {
static mut WARPS: SharedArray<u32, 8> = SharedArray::UNINIT;
let first = thread::index_1d().get() * 4;
let lane = warp::lane_id() as usize;
let warp = thread::threadIdx_x() as usize / 32;
let mut prefix = [0u32; 4];
let mut own = 0;
let mut element = 0;
#[unroll]
while element < 4 {
if first + element < x.len() {
own += x[first + element];
}
prefix[element] = own;
element += 1;
}
let warp_prefix = warp_scan(own);
if lane == 31 {
// SAFETY: lane 31 of each warp writes its own slot, before the barrier.
unsafe { WARPS[warp] = warp_prefix };
}
thread::sync_threads();
if warp == 0 {
// SAFETY: only warp 0 touches the slots between the 2 barriers.
let warp_total = if lane < 8 { unsafe { WARPS[lane] } } else { 0 };
let scanned_total = warp_scan(warp_total);
if lane < 8 {
unsafe { WARPS[lane] = scanned_total };
}
}
thread::sync_threads();
// SAFETY: after the second barrier the slots are only read.
let earlier_warps = if warp > 0 { unsafe { WARPS[warp - 1] } } else { 0 };
let before = warp_prefix - own + earlier_warps;
let mut element = 0;
#[unroll]
while element < 4 {
if first + element < y.len() {
// SAFETY: each thread alone writes its own 4 elements.
unsafe { *y.get_unchecked_mut(first + element) = before + prefix[element] };
}
element += 1;
}
if thread::threadIdx_x() == 255 {
let block = thread::blockIdx_x() as usize;
// SAFETY: only the last thread of each block writes, at its own block number.
unsafe { *sums.get_unchecked_mut(block) = before + prefix[3] };
}
}
/// Adds to every element of tile b the total of tiles 0 to b - 1.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn add_offsets(mut y: DisjointSlice<u32>, scanned: &[u32]) {
let block = thread::blockIdx_x() as usize;
let tid = thread::threadIdx_x() as usize;
if block > 0 {
let offset = scanned[block - 1];
let mut step = 0;
#[unroll]
while step < 4 {
let index = block * TILE + step * 256 + tid;
if index < y.len() {
// SAFETY: element g is this thread's alone and lies below y.len().
unsafe { *y.get_unchecked_mut(index) += offset };
}
step += 1;
}
}
}
/// flags[i] = 1 if x[i] is kept, 0 if it is removed.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn keep_flags(x: &[u32], threshold: u32, mut flags: DisjointSlice<u32>) {
let idx = thread::index_1d();
let index = idx.get();
if let Some(flag) = flags.get_mut(idx) {
*flag = (x[index] >= threshold) as u32;
}
}
/// Writes each kept element at its exclusive scan: the inclusive scan minus its flag 1.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scatter_kept(
x: &[u32],
flags: &[u32],
scanned: &[u32],
mut out: DisjointSlice<u32>,
) {
let index = thread::index_1d().get();
if index < x.len() && flags[index] == 1 {
let at = (scanned[index] - 1) as usize;
// SAFETY: the kept elements receive the distinct positions 0 to count - 1,
// and out holds x.len() >= count elements.
unsafe { *out.get_unchecked_mut(at) = x[index] };
}
}
/// The number of kept elements in each tile of 1,024, counted with warp votes.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn count_kept(x: &[u32], threshold: u32, mut counts: DisjointSlice<u32>) {
static mut WARPS: SharedArray<u32, 8> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
let base = thread::blockIdx_x() as usize * TILE;
let mut count = 0;
let mut step = 0;
#[unroll]
while step < 4 {
let index = base + step * 256 + tid;
let keep = index < x.len() && x[index] >= threshold;
count += warp::ballot(keep).count_ones();
step += 1;
}
if warp::lane_id() == 0 {
// SAFETY: lane 0 of each warp writes its own slot, before the barrier.
unsafe { WARPS[tid / 32] = count };
}
thread::sync_threads();
if tid == 0 {
let mut total = 0;
let mut other = 0;
#[unroll]
while other < 8 {
// SAFETY: after the barrier the slots are only read.
total += unsafe { WARPS[other] };
other += 1;
}
let block = thread::blockIdx_x() as usize;
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *counts.get_unchecked_mut(block) = total };
}
}
/// Writes the kept elements of each tile in order, after those of the earlier tiles.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn compact_votes(
x: &[u32],
threshold: u32,
scanned: &[u32],
mut out: DisjointSlice<u32>,
) {
static mut WARPS: SharedArray<u32, 8> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
let lane = warp::lane_id();
let warp = tid / 32;
let block = thread::blockIdx_x() as usize;
let below = (1u32 << lane) - 1; // the lanes to the left of this one
let mut next = if block > 0 { scanned[block - 1] } else { 0 };
let mut step = 0;
#[unroll]
while step < 4 {
let index = block * TILE + step * 256 + tid;
let keep = index < x.len() && x[index] >= threshold;
let votes = warp::ballot(keep);
if lane == 0 {
// SAFETY: lane 0 of each warp writes its own slot, before the barrier.
unsafe { WARPS[warp] = votes.count_ones() };
}
thread::sync_threads();
let mut before = 0;
let mut total = 0;
let mut other = 0;
#[unroll]
while other < 8 {
// SAFETY: between the 2 barriers the slots are only read.
let count = unsafe { WARPS[other] };
before += if other < warp { count } else { 0 };
total += count;
other += 1;
}
if keep {
let at = (next + before + (votes & below).count_ones()) as usize;
// SAFETY: the kept elements receive the distinct positions 0 to count - 1,
// in input order, and out holds x.len() >= count elements.
unsafe { *out.get_unchecked_mut(at) = x[index] };
}
next += total;
thread::sync_threads();
step += 1;
}
}
}
/// Runs `launch` for 0.4 s so that the clocks rise, then averages 20 runs, in ms.
fn time_ms(
stream: &Arc<CudaStream>,
mut launch: impl FnMut() -> Result<(), Error>,
) -> Result<f64, Error> {
let warm = Instant::now();
while warm.elapsed() < Duration::from_millis(400) {
launch()?;
stream.synchronize()?;
}
let start = Instant::now();
for _ in 0..20 {
launch()?;
}
stream.synchronize()?;
Ok(start.elapsed().as_secs_f64() * 1e3 / 20.0)
}
/// Numbers below `limit` from a small linear congruential generator.
fn random_below(n: usize, limit: u32, seed: u32) -> Vec<u32> {
let mut state = seed;
(0..n)
.map(|_| {
state = state.wrapping_mul(1_664_525).wrapping_add(1_013_904_223);
(state >> 8) % limit
})
.collect()
}
/// Buffers for the tile totals and their scan, per level: n / 1,024, / 1,024 again, ... 1.
fn scan_levels(stream: &Arc<CudaStream>, mut n: usize) -> Result<Levels, Error> {
let mut levels = Vec::new();
while n > 1 {
n = n.div_ceil(TILE);
let totals = DeviceBuffer::<u32>::zeroed(stream, n)?;
let scanned = DeviceBuffer::<u32>::zeroed(stream, n)?;
levels.push((totals, scanned));
}
Ok(levels)
}
/// Scans every tile of 1,024 elements on its own and writes the tile totals.
fn scan_tiles(
module: &Module,
stream: &Arc<CudaStream>,
method: Method,
x: &DeviceBuffer<u32>,
y: &mut DeviceBuffer<u32>,
sums: &mut DeviceBuffer<u32>,
) -> Result<(), Error> {
let tiles = x.len().div_ceil(TILE) as u32;
match method {
Method::HillisSteele => {
let grid = LaunchConfig1D::new(tiles, 1024, 0);
let config = module.prepare_scan_hillis_steele(grid)?;
module.scan_hillis_steele(stream, &config, x, y, sums)?;
}
Method::Blelloch => {
let grid = LaunchConfig1D::new(tiles, 512, 0);
let config = module.prepare_scan_blelloch(grid)?;
module.scan_blelloch(stream, &config, x, y, sums)?;
}
Method::Warps => {
let grid = LaunchConfig1D::new(tiles, 256, 0);
let config = module.prepare_scan_warps(grid)?;
module.scan_warps(stream, &config, x, y, sums)?;
}
}
Ok(())
}
/// Inclusive scan: the tiles, then the tile totals (by the same function), then offsets.
fn scan(
module: &Module,
stream: &Arc<CudaStream>,
method: Method,
x: &DeviceBuffer<u32>,
y: &mut DeviceBuffer<u32>,
levels: &mut [(DeviceBuffer<u32>, DeviceBuffer<u32>)],
) -> Result<(), Error> {
let tiles = x.len().div_ceil(TILE) as u32;
let ((totals, scanned), rest) = levels.split_first_mut().ok_or("no level left")?;
scan_tiles(module, stream, method, x, y, totals)?;
if tiles > 1 {
scan(module, stream, method, totals, scanned, rest)?;
let config = module.prepare_add_offsets(LaunchConfig1D::new(tiles, 256, 0))?;
module.add_offsets(stream, &config, y, scanned)?;
}
Ok(())
}
fn print(name: &str, values: &[u32]) {
let cells: Vec<String> = values.iter().map(|v| v.to_string()).collect();
println!(" {name:13} {}", cells.join(" "));
}
/// The worked example of the chapter: 8 values, 3 scans and 1 compaction.
fn small_example(module: &Module, stream: &Arc<CudaStream>) -> Result<bool, Error> {
let values = [3u32, 1, 7, 0, 4, 1, 6, 3];
let x = DeviceBuffer::from_host(stream, &values)?;
let mut y = DeviceBuffer::<u32>::zeroed(stream, 8)?;
let mut levels = scan_levels(stream, 8)?;
let mut ok = true;
println!("scans of 3 1 7 0 4 1 6 3");
for (method, name) in METHODS {
scan(module, stream, method, &x, &mut y, &mut levels)?;
let result = y.to_host_vec(stream)?;
print(name, &result);
ok &= result == [3, 4, 11, 11, 15, 16, 22, 25];
}
let one = LaunchConfig1D::new(1, 256, 0);
let mut flags = DeviceBuffer::<u32>::zeroed(stream, 8)?;
let mut out = DeviceBuffer::<u32>::zeroed(stream, 8)?;
module.keep_flags(stream, &module.prepare_keep_flags(one)?, &x, 3, &mut flags)?;
scan(module, stream, Method::HillisSteele, &flags, &mut y, &mut levels)?;
let scatter = module.prepare_scatter_kept(one)?;
module.scatter_kept(stream, &scatter, &x, &flags, &y, &mut out)?;
let f = flags.to_host_vec(stream)?;
let s = y.to_host_vec(stream)?;
let exclusive: Vec<u32> = s.iter().zip(&f).map(|(s, f)| s - f).collect();
let kept = out.to_host_vec(stream)?[..s[7] as usize].to_vec();
println!("compaction of 3 1 7 0 4 1 6 3, keep x >= 3");
print("flags", &f);
print("exclusive", &exclusive);
print("output", &kept);
Ok(ok && kept == [3, 7, 4, 6, 3])
}
/// The 3 scans of N values: tiles alone, and the whole array, checked against the CPU.
fn scans(module: &Module, stream: &Arc<CudaStream>) -> Result<bool, Error> {
let host = random_below(N, 4, 1);
let expected: Vec<u32> = host
.iter()
.scan(0u32, |run, &v| {
*run += v;
Some(*run)
})
.collect();
let x = DeviceBuffer::from_host(stream, &host)?;
let mut y = DeviceBuffer::<u32>::zeroed(stream, N)?;
let mut levels = scan_levels(stream, N)?;
let gb = 2.0 * N as f64 * 4.0 / 1e9;
let mut ok = true;
println!("inclusive scans of {N} values, average of 20 runs");
println!(" method tiles ms GB/s whole ms GB/s");
for (method, name) in METHODS {
let (totals, _) = levels.first_mut().ok_or("no level")?;
let one_level = || scan_tiles(module, stream, method, &x, &mut y, totals);
let tiles = time_ms(stream, one_level)?;
let all_levels = || scan(module, stream, method, &x, &mut y, &mut levels);
let whole = time_ms(stream, all_levels)?;
ok &= y.to_host_vec(stream)? == expected;
let (tiles_gb, whole_gb) = (gb / (tiles / 1e3), gb / (whole / 1e3));
println!(" {name:14} {tiles:9.3} {tiles_gb:6.1} {whole:10.3} {whole_gb:6.1}");
}
Ok(ok)
}
/// Compaction of N values in [0, 100) at 3 thresholds, by 3 passes and by warp votes.
fn compaction(module: &Module, stream: &Arc<CudaStream>) -> Result<bool, Error> {
let host = random_below(N, 100, 2);
let x = DeviceBuffer::from_host(stream, &host)?;
let mut flags = DeviceBuffer::<u32>::zeroed(stream, N)?;
let mut scanned = DeviceBuffer::<u32>::zeroed(stream, N)?;
let mut levels = scan_levels(stream, N)?;
let tiles = N.div_ceil(TILE);
let mut counts = DeviceBuffer::<u32>::zeroed(stream, tiles)?;
let mut tile_scan = DeviceBuffer::<u32>::zeroed(stream, tiles)?;
let mut tile_levels = scan_levels(stream, tiles)?;
let every = LaunchConfig1D::new(N.div_ceil(256) as u32, 256, 0);
let per_tile = LaunchConfig1D::new(tiles as u32, 256, 0);
let flag_cfg = module.prepare_keep_flags(every)?;
let scatter_cfg = module.prepare_scatter_kept(every)?;
let count_cfg = module.prepare_count_kept(per_tile)?;
let votes_cfg = module.prepare_compact_votes(per_tile)?;
let mut ok = true;
println!("compaction of {N} values in [0, 100), average of 20 runs");
println!(" keep x >= kept 3 passes ms GB/s warp votes ms GB/s");
for threshold in [90u32, 50, 10] {
let expected: Vec<u32> = host.iter().copied().filter(|&v| v >= threshold).collect();
let kept = expected.len();
let gb = (4 * N + 4 * kept) as f64 / 1e9;
let mut out = DeviceBuffer::<u32>::zeroed(stream, N)?;
let three = || -> Result<(), Error> {
module.keep_flags(stream, &flag_cfg, &x, threshold, &mut flags)?;
scan(module, stream, Method::Warps, &flags, &mut scanned, &mut levels)?;
module.scatter_kept(stream, &scatter_cfg, &x, &flags, &scanned, &mut out)?;
Ok(())
};
let three_ms = time_ms(stream, three)?;
ok &= out.to_host_vec(stream)?[..kept] == expected[..];
out = DeviceBuffer::<u32>::zeroed(stream, N)?;
let votes = || -> Result<(), Error> {
module.count_kept(stream, &count_cfg, &x, threshold, &mut counts)?;
scan(module, stream, Method::Warps, &counts, &mut tile_scan, &mut tile_levels)?;
module.compact_votes(stream, &votes_cfg, &x, threshold, &tile_scan, &mut out)?;
Ok(())
};
let votes_ms = time_ms(stream, votes)?;
ok &= out.to_host_vec(stream)?[..kept] == expected[..];
let (three_gb, votes_gb) = (gb / (three_ms / 1e3), gb / (votes_ms / 1e3));
print!(" {threshold:9} {kept:9} {three_ms:13.2} {three_gb:6.1}");
println!(" {votes_ms:15.2} {votes_gb:6.1}");
}
Ok(ok)
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let mut passed = small_example(&module, &stream)?;
passed &= scans(&module, &stream)?;
passed &= compaction(&module, &stream)?;
println!("{}", if passed { "PASSED" } else { "FAILED" });
Ok(())
}// Chapter 21: 3 inclusive scans of a tile (Hillis-Steele, Blelloch, warp shuffles),
// the scan of a long array, and stream compaction by a scan and by warp votes.
// Build: nvcc -O3 -arch=native scan_compaction.cu -o scan_compaction
#include <chrono>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cuda_runtime.h>
const int TILE = 1024; // elements scanned by 1 block
const int N = 16 << 20; // elements in the measured runs
enum Method { HILLIS_STEELE, BLELLOCH, WARPS };
const char* NAMES[] = {"Hillis-Steele", "Blelloch", "warp shuffles"};
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// Runs `launch` for 0.4 s so that the clocks rise, then averages 20 runs, in ms.
template <typename F>
double timeMs(F launch)
{
double warm = nowMs();
while (nowMs() - warm < 400) {
launch();
check(cudaDeviceSynchronize());
}
double t0 = nowMs();
for (int timed = 0; timed < 20; ++timed) {
launch();
}
check(cudaGetLastError());
check(cudaDeviceSynchronize());
return (nowMs() - t0) / 20;
}
// Hillis-Steele: 1,024 threads, 1 element each, 2 buffers in shared memory.
__global__ void scanHillisSteele(const unsigned* x, unsigned* y, unsigned* sums, int n)
{
__shared__ unsigned buf[2 * TILE];
int index = blockIdx.x * TILE + threadIdx.x;
buf[threadIdx.x] = index < n ? x[index] : 0;
__syncthreads();
int src = 0;
for (int distance = 1; distance < TILE; distance *= 2) {
int dst = TILE - src;
unsigned value = buf[src + threadIdx.x];
if (threadIdx.x >= distance) {
value += buf[src + threadIdx.x - distance];
}
buf[dst + threadIdx.x] = value;
__syncthreads(); // the step is complete before any read
src = dst;
}
if (index < n) {
y[index] = buf[src + threadIdx.x];
}
if (threadIdx.x == TILE - 1) {
sums[blockIdx.x] = buf[src + threadIdx.x];
}
}
// Blelloch: 512 threads, 2 elements each, 1 buffer; an up-sweep, then a down-sweep.
__global__ void scanBlelloch(const unsigned* x, unsigned* y, unsigned* sums, int n)
{
__shared__ unsigned cells[TILE];
int index = blockIdx.x * TILE + 2 * threadIdx.x;
unsigned first = index < n ? x[index] : 0;
unsigned second = index + 1 < n ? x[index + 1] : 0;
cells[2 * threadIdx.x] = first;
cells[2 * threadIdx.x + 1] = second;
for (int distance = 1; distance < TILE; distance *= 2) {
__syncthreads();
if (threadIdx.x < TILE / (2 * distance)) {
int right = (2 * threadIdx.x + 2) * distance - 1;
cells[right] += cells[right - distance];
}
}
__syncthreads();
if (threadIdx.x == 0) {
sums[blockIdx.x] = cells[TILE - 1];
cells[TILE - 1] = 0;
}
for (int distance = TILE / 2; distance >= 1; distance /= 2) {
__syncthreads();
if (threadIdx.x < TILE / (2 * distance)) {
int right = (2 * threadIdx.x + 2) * distance - 1;
unsigned left = cells[right - distance];
cells[right - distance] = cells[right];
cells[right] += left;
}
}
__syncthreads();
if (index < n) {
y[index] = cells[2 * threadIdx.x] + first; // exclusive plus own: inclusive
}
if (index + 1 < n) {
y[index + 1] = cells[2 * threadIdx.x + 1] + second;
}
}
// The scan of Chapter 8: 256 threads, 4 elements each, warp shuffles and 2 barriers.
__device__ unsigned warpScan(unsigned value)
{
int lane = threadIdx.x % 32;
for (int offset = 1; offset < 32; offset *= 2) {
unsigned left = __shfl_up_sync(0xffffffff, value, offset);
if (lane >= offset) {
value += left;
}
}
return value;
}
__global__ void scanWarps(const unsigned* x, unsigned* y, unsigned* sums, int n)
{
__shared__ unsigned warps[8];
int first = blockIdx.x * TILE + 4 * threadIdx.x;
int lane = threadIdx.x % 32;
int warp = threadIdx.x / 32;
unsigned prefix[4];
unsigned own = 0;
for (int element = 0; element < 4; ++element) {
own += first + element < n ? x[first + element] : 0;
prefix[element] = own;
}
unsigned warpPrefix = warpScan(own);
if (lane == 31) {
warps[warp] = warpPrefix;
}
__syncthreads();
if (warp == 0) {
unsigned scannedTotal = warpScan(lane < 8 ? warps[lane] : 0);
if (lane < 8) {
warps[lane] = scannedTotal;
}
}
__syncthreads();
unsigned before = warpPrefix - own + (warp > 0 ? warps[warp - 1] : 0);
for (int element = 0; element < 4; ++element) {
if (first + element < n) {
y[first + element] = before + prefix[element];
}
}
if (threadIdx.x == 255) {
sums[blockIdx.x] = before + prefix[3];
}
}
// Adds to every element of a tile the total of the tiles before it.
__global__ void addOffsets(unsigned* y, const unsigned* scanned, int n)
{
if (blockIdx.x == 0) {
return;
}
unsigned offset = scanned[blockIdx.x - 1];
for (int step = 0; step < 4; ++step) {
int index = blockIdx.x * TILE + step * 256 + threadIdx.x;
if (index < n) {
y[index] += offset;
}
}
}
// Scans every tile of 1,024 elements on its own and writes the tile totals.
void scanTiles(Method method, const unsigned* x, unsigned* y, unsigned* sums, int n)
{
int tiles = (n + TILE - 1) / TILE;
if (method == HILLIS_STEELE) {
scanHillisSteele<<<tiles, TILE>>>(x, y, sums, n);
} else if (method == BLELLOCH) {
scanBlelloch<<<tiles, TILE / 2>>>(x, y, sums, n);
} else {
scanWarps<<<tiles, 256>>>(x, y, sums, n);
}
}
// Inclusive scan of n elements: the tiles, then the tile totals (in place), then offsets.
void scan(Method method, const unsigned* x, unsigned* y, int n, unsigned* scratch)
{
int tiles = (n + TILE - 1) / TILE;
scanTiles(method, x, y, scratch, n);
if (tiles > 1) {
scan(method, scratch, scratch, tiles, scratch + tiles);
addOffsets<<<tiles, 256>>>(y, scratch, n);
}
}
// flags[index] = 1 if x[index] is kept.
__global__ void keepFlags(const unsigned* x, unsigned threshold, unsigned* flags, int n)
{
int index = blockIdx.x * blockDim.x + threadIdx.x;
if (index < n) {
flags[index] = x[index] >= threshold;
}
}
// Writes each kept element at its exclusive scan, the inclusive scan minus its flag of 1.
__global__ void scatterKept(const unsigned* x, const unsigned* flags,
const unsigned* scanned, unsigned* out, int n)
{
int index = blockIdx.x * blockDim.x + threadIdx.x;
if (index < n && flags[index] == 1) {
out[scanned[index] - 1] = x[index];
}
}
// The number of kept elements in each tile of 1,024, counted with warp votes.
__global__ void countKept(const unsigned* x, unsigned threshold, unsigned* counts, int n)
{
__shared__ unsigned warps[8];
int base = blockIdx.x * TILE;
unsigned count = 0;
for (int step = 0; step < 4; ++step) {
int index = base + step * 256 + threadIdx.x;
bool keep = index < n && x[index] >= threshold;
count += __popc(__ballot_sync(0xffffffff, keep));
}
if (threadIdx.x % 32 == 0) {
warps[threadIdx.x / 32] = count;
}
__syncthreads();
if (threadIdx.x == 0) {
unsigned total = 0;
for (int other = 0; other < 8; ++other) {
total += warps[other];
}
counts[blockIdx.x] = total;
}
}
// Writes the kept elements of each tile in order, after those of the earlier tiles.
__global__ void compactVotes(const unsigned* x, unsigned threshold,
const unsigned* scanned, unsigned* out, int n)
{
__shared__ unsigned warps[8];
int lane = threadIdx.x % 32;
int warp = threadIdx.x / 32;
unsigned below = (1u << lane) - 1; // the lanes to the left of this one
unsigned next = blockIdx.x > 0 ? scanned[blockIdx.x - 1] : 0;
for (int step = 0; step < 4; ++step) {
int index = blockIdx.x * TILE + step * 256 + threadIdx.x;
bool keep = index < n && x[index] >= threshold;
unsigned votes = __ballot_sync(0xffffffff, keep);
if (lane == 0) {
warps[warp] = __popc(votes);
}
__syncthreads();
unsigned before = 0;
unsigned total = 0;
for (int other = 0; other < 8; ++other) {
before += other < warp ? warps[other] : 0;
total += warps[other];
}
if (keep) {
out[next + before + __popc(votes & below)] = x[index];
}
next += total;
__syncthreads();
}
}
// Numbers from a small linear congruential generator.
std::vector<unsigned> randomBelow(int n, unsigned limit, unsigned seed)
{
std::vector<unsigned> v(n);
unsigned state = seed;
for (int i = 0; i < n; ++i) {
state = state * 1664525u + 1013904223u;
v[i] = (state >> 8) % limit;
}
return v;
}
void print(const char* name, const std::vector<unsigned>& v, int count)
{
std::printf(" %-13s", name);
for (int i = 0; i < count; ++i) {
std::printf(" %u", v[i]);
}
std::printf("\n");
}
std::vector<unsigned> toHost(const unsigned* d, int n)
{
std::vector<unsigned> h(n);
check(cudaMemcpy(h.data(), d, n * sizeof(unsigned), cudaMemcpyDeviceToHost));
return h;
}
// The worked example of the chapter: 8 values, 3 scans and 1 compaction.
bool smallExample(unsigned* scratch)
{
std::vector<unsigned> x = {3, 1, 7, 0, 4, 1, 6, 3};
std::vector<unsigned> inclusive = {3, 4, 11, 11, 15, 16, 22, 25};
unsigned *dx, *dy, *flags, *out;
check(cudaMalloc(&dx, 8 * sizeof(unsigned)));
check(cudaMalloc(&dy, 8 * sizeof(unsigned)));
check(cudaMalloc(&flags, 8 * sizeof(unsigned)));
check(cudaMalloc(&out, 8 * sizeof(unsigned)));
check(cudaMemcpy(dx, x.data(), 8 * sizeof(unsigned), cudaMemcpyHostToDevice));
bool ok = true;
std::printf("scans of 3 1 7 0 4 1 6 3\n");
for (Method m : {HILLIS_STEELE, BLELLOCH, WARPS}) {
scan(m, dx, dy, 8, scratch);
std::vector<unsigned> y = toHost(dy, 8);
print(NAMES[m], y, 8);
ok = ok && y == inclusive;
}
keepFlags<<<1, 256>>>(dx, 3, flags, 8);
scan(HILLIS_STEELE, flags, dy, 8, scratch);
scatterKept<<<1, 256>>>(dx, flags, dy, out, 8);
std::vector<unsigned> f = toHost(flags, 8);
std::vector<unsigned> s = toHost(dy, 8);
std::vector<unsigned> e(8);
for (int i = 0; i < 8; ++i) {
e[i] = s[i] - f[i];
}
std::vector<unsigned> kept = toHost(out, s[7]);
std::printf("compaction of 3 1 7 0 4 1 6 3, keep x >= 3\n");
print("flags", f, 8);
print("exclusive", e, 8);
print("output", kept, s[7]);
ok = ok && kept == std::vector<unsigned>({3, 7, 4, 6, 3});
check(cudaFree(dx));
check(cudaFree(dy));
check(cudaFree(flags));
check(cudaFree(out));
return ok;
}
// The 3 scans of N values: tiles alone, and the whole array, checked against the CPU.
bool scans(const unsigned* dx, unsigned* dy, unsigned* scratch,
const std::vector<unsigned>& x)
{
std::vector<unsigned> expected(N);
unsigned run = 0;
for (int i = 0; i < N; ++i) {
run += x[i];
expected[i] = run;
}
double gb = 2.0 * N * sizeof(unsigned) / 1e9;
int perSm[3]; // blocks that fit on 1 SM at once
auto fit = cudaOccupancyMaxActiveBlocksPerMultiprocessor<decltype(&scanWarps)>;
check(fit(&perSm[HILLIS_STEELE], scanHillisSteele, TILE, 0));
check(fit(&perSm[BLELLOCH], scanBlelloch, TILE / 2, 0));
check(fit(&perSm[WARPS], scanWarps, 256, 0));
bool ok = true;
std::printf("inclusive scans of %d values, average of 20 runs\n", N);
std::printf(" method blocks/SM tiles ms GB/s whole ms GB/s\n");
for (Method m : {HILLIS_STEELE, BLELLOCH, WARPS}) {
double tiles = timeMs([&] { scanTiles(m, dx, dy, scratch, N); });
double whole = timeMs([&] { scan(m, dx, dy, N, scratch); });
ok = ok && toHost(dy, N) == expected;
std::printf(" %-14s %10d %10.3f %6.1f %10.3f %6.1f\n", NAMES[m], perSm[m],
tiles, gb / (tiles / 1e3), whole, gb / (whole / 1e3));
}
return ok;
}
// Compaction of N values in [0, 100) at 3 thresholds, by 3 passes and by warp votes.
bool compaction(const unsigned* dx, unsigned* scratch, const std::vector<unsigned>& x)
{
int tiles = (N + TILE - 1) / TILE;
unsigned *flags, *scanned, *out, *counts;
check(cudaMalloc(&flags, N * sizeof(unsigned)));
check(cudaMalloc(&scanned, N * sizeof(unsigned)));
check(cudaMalloc(&out, N * sizeof(unsigned)));
check(cudaMalloc(&counts, tiles * sizeof(unsigned)));
int blocks = (N + 255) / 256;
bool ok = true;
std::printf("compaction of %d values in [0, 100), average of 20 runs\n", N);
std::printf(" keep x >= kept 3 passes ms GB/s warp votes ms GB/s\n");
for (unsigned threshold : {90u, 50u, 10u}) {
std::vector<unsigned> expected;
for (unsigned v : x) {
if (v >= threshold) {
expected.push_back(v);
}
}
int kept = expected.size();
double gb = (4.0 * N + 4.0 * kept) / 1e9;
auto three = [&] {
keepFlags<<<blocks, 256>>>(dx, threshold, flags, N);
scan(WARPS, flags, scanned, N, scratch);
scatterKept<<<blocks, 256>>>(dx, flags, scanned, out, N);
};
check(cudaMemset(out, 0, N * sizeof(unsigned)));
double threeMs = timeMs(three);
ok = ok && toHost(out, kept) == expected;
auto votes = [&] {
countKept<<<tiles, 256>>>(dx, threshold, counts, N);
scan(WARPS, counts, counts, tiles, scratch);
compactVotes<<<tiles, 256>>>(dx, threshold, counts, out, N);
};
check(cudaMemset(out, 0, N * sizeof(unsigned)));
double votesMs = timeMs(votes);
ok = ok && toHost(out, kept) == expected;
std::printf(" %9u %9d %13.2f %6.1f %15.2f %6.1f\n", threshold, kept,
threeMs, gb / (threeMs / 1e3), votesMs, gb / (votesMs / 1e3));
}
check(cudaFree(flags));
check(cudaFree(scanned));
check(cudaFree(out));
check(cudaFree(counts));
return ok;
}
int main()
{
unsigned *dx, *dy, *scratch;
check(cudaMalloc(&dx, N * sizeof(unsigned)));
check(cudaMalloc(&dy, N * sizeof(unsigned)));
check(cudaMalloc(&scratch, N / 512 * sizeof(unsigned)));
bool ok = smallExample(scratch);
std::vector<unsigned> x = randomBelow(N, 4, 1);
check(cudaMemcpy(dx, x.data(), N * sizeof(unsigned), cudaMemcpyHostToDevice));
ok = scans(dx, dy, scratch, x) && ok;
x = randomBelow(N, 100, 2);
check(cudaMemcpy(dx, x.data(), N * sizeof(unsigned), cudaMemcpyHostToDevice));
ok = compaction(dx, scratch, x) && ok;
check(cudaFree(dx));
check(cudaFree(dy));
check(cudaFree(scratch));
std::printf("%s\n", ok ? "PASSED" : "FAILED");
return ok ? 0 : 1;
}
Common mistakes
- A missing barrier between steps. A thread starts the next step and reads a slot that a slower thread has not written yet (Section 21.6.1). Every step that reads the values of other threads must end with a barrier that every thread reaches.
- Scanning in place. A step that reads and writes the same array lets a thread read a value of the current step. The test passed on 8 values and failed on 16,777,216 (Section 21.6.2). Use 2 buffers, or keep the value to be added in a register and separate the read from the write with a barrier.
- Leaving the loop early. A thread whose value is final must still reach the barriers of the remaining steps, or the block waits for it forever.
- The inclusive scan as an output position. Every kept value lands 1 position too far, in bounds, and no error is reported. The position is the exclusive scan, \(s_i - f_i\).
- A ballot inside a branch. A ballot needs every lane of the warp. Compute the condition for every lane, with the bounds test inside it, and call the ballot unconditionally.
- Assuming that blocks see each other’s results. The blocks of 1 launch cannot wait for each other, so the scan of many tiles crosses blocks only through a second launch.
Summary
- The inclusive scan holds at position \(i\) the sum of the inputs 0 to \(i\), and the exclusive scan stops before \(i\). The sequential scan performs \(n - 1\) additions in a chain of \(n - 1\) steps.
- Because addition is associative, a range sum is the sum of 2 adjacent range sums. Doubling the ranges gives the Hillis-Steele scan, with \(\log_2 n\) steps and \(n \log_2 n - (n - 1)\) additions. Building a tree and then descending it gives the Blelloch scan, with \(2 \log_2 n\) steps and \(2(n - 1)\) additions.
- A step must not start before the previous one has ended, and it must not read what it writes. These two requirements are met by 1 barrier and 1 double buffer, both of which are used in the proof of Theorem 21.1.
- An array of many blocks is scanned in tiles. We scan the tiles, scan their totals, and add the offsets.
- Stream compaction is a scan of flags followed by a scatter to the exclusive scan. Warp votes compute the same positions inside each block and reduce the traffic from 38 to 10 bytes per value.
In Chapter 22, we use the exclusive scan as the core of a radix sort, and we combine it with a histogram.
Exercises
- Run Hillis-Steele-Scan by hand on 16 values \(1, 2, \ldots, 16\), and check the last row against \(y_i = (i + 1)(i + 2)/2\).
- Prove that the up-sweep of Blelloch-Scan leaves \(S[i - 2 \cdot \mathsf{distance} + 1..i]\) at every position \(i = 2 \cdot \mathsf{distance} - 1, 4 \cdot \mathsf{distance} - 1, \ldots\) after the level with distance \(\mathsf{distance}\).
- A segmented scan restarts the running total at every position where a second array holds 1. Write the sequential algorithm, and show how Hillis-Steele-Scan can carry the segment flags.
- Change
scan_hillis_steeleto keep 1 buffer and a register, as suggested in Common mistakes, with 2 barriers per step. Measure it against Listing 21.1. - Estimate the bytes per value of the 3-pass compaction when 10% of the values are kept, taking into account that memory is read in sectors of 32 bytes, and compare with the measured times.
- Write a kernel that removes adjacent duplicates from a sorted array. Which flag does it compute?
Sources and further reading
- W. D. Hillis and G. L. Steele, Jr., “Data Parallel Algorithms”, Communications of the ACM 29(12), 1986.
- G. E. Blelloch, “Prefix Sums and Their Applications”, Technical Report CMU-CS-90-190, Carnegie Mellon University, 1990.
- T. H. Cormen, C. E. Leiserson, R. L. Rivest and C. Stein, Introduction to Algorithms, 4th ed., MIT Press, 2022: loop invariants and the pseudocode conventions of this chapter.
- A. Pathak, “An Introduction to Tiled Parallel Programming, Simplified”, 2026: the worked-example and proof style of this part of the book.
- D. Merrill and M. Garland, “Single-pass Parallel Prefix Scan with Decoupled Look-back”, NVIDIA Technical Report NVR-2016-002, 2016.
- NVIDIA, CUDA C++ Programming Guide, “Warp Vote Functions” and “Synchronization Functions”.
- cuda-oxide, documentation of
DisjointSliceandSharedArray, cratecuda-device, revision b7fe543.
Chapter 22: Radix Sort and Histograms
Sorting puts a list of keys in increasing order. Most sorting algorithms compare keys 2 at a time, and the order of the comparisons depends on the keys, which makes these algorithms awkward to run on thousands of threads. A radix sort compares nothing. It sorts integer keys by their digits, 1 digit per pass, and in each pass, every key computes its output position from 2 counts: the number of keys that have a smaller digit, and the number of keys before it that have the same digit. Both counts come from the scan of Chapter 21, and the first one also comes from a histogram, the count of the keys with each digit value.
In this chapter, we derive a radix sort on 8 keys of 3 bits, small enough that every pass can be checked by hand. We start with passes on 1 bit, each of which consists of 2 stream compactions, and we show why every pass must keep keys with equal digits in their input order. We then count keys with atomic operations, measure what happens when many threads count into the same bin, and remove most of that contention with private bins in shared memory. Finally, we use a histogram and an exclusive scan to compute the positions of a pass on a digit of 4 bits, and we measure a sort that runs 6.5 times as fast as the sort by single bits.
This chapter covers
- radix sort, least significant digit first, worked by hand on 8 keys of 3 bits
- a split on 1 bit as 2 compactions, and why each pass must be stable
- a proof that a sort by stable passes is correct
- histograms with atomic operations, contention, private bins and warp aggregation
- a pass on a digit of several bits from a histogram, an exclusive scan and ranks
- measured histograms and sorts of 16,777,216 keys
The code of the chapter is in
code/oxide/ch22_radix_sort_histogram/
for Rust and in
code/cuda/ch22_radix_sort_histogram/
for C++. The programs use the warp-shuffle scan of Chapter 21 (Section 21.10.3) without change. In
Chapters 5 and 8, we measured histograms of bytes in C++ and in Rust, and we cite those results
where we reuse them.
22.1 The problem
22.1.1 A worked example
Throughout the chapter, we sort the same 8 keys, which we call \(K\):
\[ K = (5,\ 2,\ 7,\ 2,\ 0,\ 6,\ 3,\ 5). \]
As in Chapter 21, we number the positions from 0, so that \(K_0 = 5\) is the first key and \(K_7 = 5\) the last. Every key is below 8, so it fits in 3 bits. For example, 5 is 101 in binary, 2 is 010, and 7 is 111. The sorted list is \((0, 2, 2, 3, 5, 5, 6, 7)\). Figure 22.1 shows the keys with their bits, and the sorted keys with the position from which each one came. The key 2 occurs twice, at positions 1 and 3, and so does the key 5, at positions 0 and 7. We follow both pairs through the chapter.
22.1.2 Definitions
A radix sort works on the bits of a key, so we first state precisely how a bit, and a group of bits, is read from a key.
Definition 22.1 Key, bit and digit. A key is an unsigned integer of \(B\) bits. Bit \(b\) of key \(k\) is \(\lfloor k / 2^b \rfloor \bmod 2\), and bit 0 is the least significant. A digit of \(r\) bits at shift \(s\) is \(\lfloor k / 2^s \rfloor \bmod 2^r\), the bits \(s\) to \(s + r - 1\) read as a number.
Example. \(B = 3\). The key 6 = 110 has bit 0 equal to 0 and bit 2 equal to 1; its digit of 2 bits at shift 0 is 10, that is 2.
Dividing a key by \(2^b\) and rounding down removes its lowest \(b\) bits, and taking the remainder modulo 2 then keeps only the lowest of the remaining bits, which is bit \(b\) of the original key. For the key 6 and \(b = 2\), we get \(\lfloor 6 / 4 \rfloor = 1\) and \(1 \bmod 2 = 1\). A digit is read in the same way, except that the remainder modulo \(2^r\) keeps the lowest \(r\) bits instead of 1.
| Symbol | Meaning | Key 6 = 110 |
|---|---|---|
| \(B\) | number of bits of every key | 3 |
| \(b\) | number of a bit, 0 for the least significant | 2 |
| \(\lfloor k / 2^b \rfloor \bmod 2\) | bit \(b\) of key \(k\) | \(\lfloor 6/4 \rfloor \bmod 2 = 1\) |
| \(r\) | number of bits of a digit | 2 |
| \(s\) | shift: the number of the lowest bit of the digit | 0 |
| \(\lfloor k / 2^s \rfloor \bmod 2^r\) | the digit of \(r\) bits at shift \(s\) | \(6 \bmod 4 = 2\) |
The second definition names the property on which the whole chapter depends.
Definition 22.2 Stable. A rearrangement of a list by some property of its keys is stable if any 2 keys with equal property keep the relative order they had in the input.
Example. Sorting \(K\) by value is stable if the 2 from position 1 comes before the 2 from position 3, as in Figure 22.1.
Stability is invisible when the keys are plain numbers, because 2 equal numbers look the same. It becomes visible when each key carries a payload, such as the index of a record. As we show in Section 22.4, stability is also required inside the radix sort itself.
Exercises
22.1 Write the keys \((6, 1, 4, 4, 7, 0, 3, 1)\) in binary, and give their digits of 2 bits at
shift 0.
22.2 How many bits do keys below 1,000 need? How many digits of 4 bits?
22.2 Sorting by 1 bit at a time
22.2.1 The sequential algorithm
A radix sort processes the bits from the least significant to the most significant. In each pass, it reads the keys in their current order and splits them into 2 lists: first the keys whose current bit is 0, and then the keys whose current bit is 1, each list in the order in which the keys were read. In the following procedure, \(\mathsf{zeros}\) is the list of keys whose bit is 0, and \(\mathsf{ones}\) is the list of keys whose bit is 1.
Radix-Sort-Bits(\(K, n, B\))
- for \(\mathsf{bitIndex} \in [0, B)\) { // 1 pass per bit, bit 0 first
- \(\mathsf{zeros}\) = empty list, \(\mathsf{ones}\) = empty list
- for \(i \in [0, n)\) {
- if bit \(\mathsf{bitIndex}\) of \(K_i\) is 0: append \(K_i\) to \(\mathsf{zeros}\)
- else: append \(K_i\) to \(\mathsf{ones}\)
- }
- \(K\) = \(\mathsf{zeros}\) followed by \(\mathsf{ones}\) // the split on bit \(\mathsf{bitIndex}\)
- }
Lines 3 to 7 form 1 pass, which we call the split on bit \(\mathsf{bitIndex}\). Figure 22.2 shows the 3 passes on our keys. After the split on bit 0, the even keys \((2, 2, 0, 6)\) come before the odd keys \((5, 7, 3, 5)\). After the split on bit 1, the keys are ordered by their 2 lowest bits. First comes 0, whose 2 lowest bits are 00, then 5 and 5 (01), then 2, 2 and 6 (10), and finally 7 and 3 (11). After the split on bit 2, the keys are sorted.
Line 4 or line 5 executes once per key and pass, that is, \(nB\) times: \(8 \cdot 3 = 24\) times for our example, and \(32n\) times for keys of 32 bits. The work therefore grows linearly with \(n\), and no 2 keys are ever compared.
22.2.2 Why the least significant bit comes first
The last pass decides the order by the most significant bit, and the order established by every earlier pass must survive it. It survives because each split keeps the order of the keys within each of its 2 lists. Consider the 2 keys 2 and 3 after the pass on bit 1 in Figure 22.2. The key 2 = 010 comes before 3 = 011, because the pass on bit 0 put the even keys first. The pass on bit 2 sees the same bit, 0, in both keys, and so it keeps 2 before 3. The following theorem states this argument in general.
Theorem 22.1 If every pass of Radix-Sort-Bits is a stable split, then after the pass on bit \(\mathsf{bitIndex}\), the keys are in increasing order of \(k \bmod 2^{\mathsf{bitIndex}+1}\), their bits 0 to \(\mathsf{bitIndex}\), and keys with equal bits 0 to \(\mathsf{bitIndex}\) are in input order. In particular, after the pass on bit \(B - 1\) the keys are sorted, and the sort is stable.
The quantity \(k \bmod 2^{\mathsf{bitIndex}+1}\) is the number formed by the lowest \(\mathsf{bitIndex} + 1\) bits of the key, bits 0 to \(\mathsf{bitIndex}\), which are exactly the bits that the passes so far have looked at. After the pass on bit 1, for example, it is \(k \bmod 4\), the 2 lowest bits. In the order of Figure 22.2 after that pass, \((0, 5, 5, 2, 2, 6, 7, 3)\), these values are \((0, 1, 1, 2, 2, 2, 3, 3)\), which are indeed in increasing order.
Proof. We show that the loop of lines 1 to 8 maintains the statement as an invariant, writing \(v_{\mathsf{bitIndex}}(k) = k \bmod 2^{\mathsf{bitIndex}+1}\).
Initialization. Before the first pass, take \(\mathsf{bitIndex} = -1\): \(v_{-1}(k) = 0\) for every key, and the keys are in input order.
Maintenance. Assume the statement holds after the pass on bit \(\mathsf{bitIndex} - 1\), and take 2 keys \(k\) and \(k’\). If their bits \(\mathsf{bitIndex}\) differ, the split on bit \(\mathsf{bitIndex}\) puts the key with bit 0 first. Bit \(\mathsf{bitIndex}\) is the most significant of bits 0 to \(\mathsf{bitIndex}\), so that key has the smaller \(v_{\mathsf{bitIndex}}\), and the order is correct. If their bits \(\mathsf{bitIndex}\) are equal, the split is stable and keeps the order of the previous pass, which is the order of \(v_{\mathsf{bitIndex}-1}\), with input order among equal values. Since \(v_{\mathsf{bitIndex}}(k) - v_{\mathsf{bitIndex}}(k’) = v_{\mathsf{bitIndex}-1}(k) - v_{\mathsf{bitIndex}-1}(k’)\) when bit \(\mathsf{bitIndex}\) is equal, that order is the order of \(v_{\mathsf{bitIndex}}\), with input order among equal values.
Termination. After the pass on bit \(B - 1\), \(v_{B-1}(k) = k\) for every key of \(B\) bits, so the keys are sorted, and equal keys are in input order.
| Symbol | Meaning | Keys 2 and 3, \(\mathsf{bitIndex} = 2\) |
|---|---|---|
| \(v_{\mathsf{bitIndex}}(k)\) | the lowest \(\mathsf{bitIndex} + 1\) bits of \(k\), read as a number | \(v_2(2) = 2\), \(v_2(3) = 3\) |
| \(v_{\mathsf{bitIndex}-1}(k)\) | the same before the pass on bit \(\mathsf{bitIndex}\) | \(v_1(2) = 2\), \(v_1(3) = 3\) |
The case of equal bits can be checked on the keys 2 and 3 in the pass on bit 2. Both have bit 2 equal to 0, so their difference does not change: \(v_2(3) - v_2(2) = 3 - 2 = 1\), which equals \(v_1(3) - v_1(2)\). The order of the previous pass, 2 before 3, is therefore also the correct order after this pass. The proof uses stability in exactly this 1 place, the case of equal bits. In Section 22.4, we show what happens to our keys when that case fails.
Exercises
22.3 Sort \((6, 1, 4, 4, 7, 0, 3, 1)\) with Radix-Sort-Bits, writing the keys after each pass.
22.4 Sort \(K\) with the most significant bit first, by the same splits. Where does the result
differ from the sorted list, and why?
22.3 A split is 2 compactions
22.3.1 Positions from a scan
A split on the GPU cannot append keys to lists, because the threads would have to agree on the order of the appends. Instead, every key computes its own output position, as in the stream compaction of Section 21.8. The keys whose bit \(\mathsf{bitIndex}\) is 0 form 1 compaction. Their flag is \(z_i = 1\) when bit \(\mathsf{bitIndex}\) of key \(i\) is 0, and key \(i\) goes to position \(e_i\), the exclusive scan of these flags. The keys whose bit is 1 form a second compaction, written after the keys of the first one. We write \(\mathsf{zeros}\) for the number of keys whose bit is 0.
The second compaction needs no second scan. Of the \(i\) keys before position \(i\), \(e_i\) have bit 0, so the remaining \(i - e_i\) have bit 1. A key with bit 1 must therefore come after all \(\mathsf{zeros}\) keys with bit 0 and after the \(i - e_i\) keys with bit 1 that precede it, and so it goes to position
\[ \mathsf{zeros} + i - e_i. \]
| Symbol | Meaning | Key 7 at position 2, bit 0 |
|---|---|---|
| \(i\) | input position of the key | 2 |
| \(z_i\) | 1 if bit \(\mathsf{bitIndex}\) of the key is 0, else 0 | 0 |
| \(e_i\) | keys with bit 0 before position \(i\): the exclusive scan of \(z\) | 1 |
| \(i - e_i\) | keys with bit 1 before position \(i\) | 1 |
| \(\mathsf{zeros}\) | number of keys with bit 0 in the whole list | 4 |
Figure 22.3 works out the split on bit 0 of our keys. The flags of the keys with bit 0 are \((0, 1, 0, 1, 1, 1, 0, 0)\), their exclusive scan is \((0, 0, 1, 1, 2, 3, 4, 4)\), and \(\mathsf{zeros} = 4\). The key 5 at position 0 has bit 1 and goes to \(4 + 0 - 0 = 4\). The key 7 at position 2 also has bit 1 and goes to \(4 + 2 - 1 = 5\). The key 2 at position 3 has bit 0 and goes to \(e_3 = 1\).
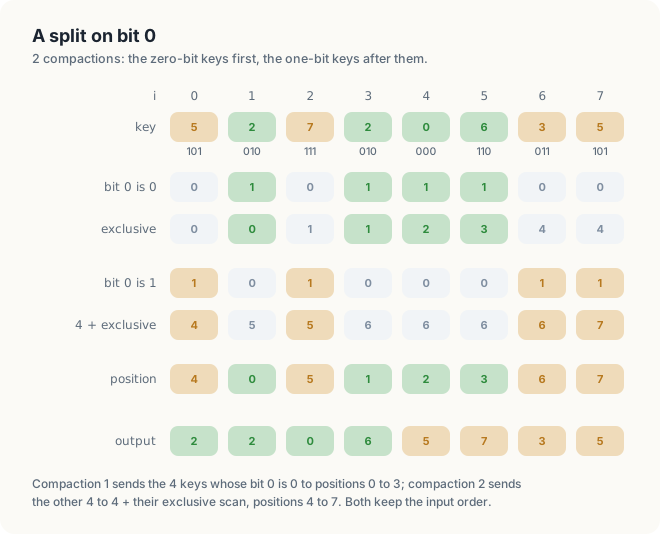
Key observation 1 exclusive scan of the zero flags places both groups of a split: a key with bit 0 goes to \(e_i\), and a key with bit 1 goes to \(\mathsf{zeros} + i - e_i\), where \(\mathsf{zeros}\) is the number of keys with bit 0. Each group is a stream compaction, so the split inherits the stability of compaction.
22.3.2 The algorithm
In the following procedure, \(s\) is the inclusive scan of the flags, from which line 5 recovers the exclusive scan \(e_i\), and line 3 reads \(\mathsf{zeros}\) as the last inclusive value.
Parallel-Split(\(K, \mathsf{out}, n, \mathsf{bitIndex}\))
- for every \(i \in [0, n)\) in parallel: \(z_i = 1\) if bit \(\mathsf{bitIndex}\) of \(K_i\) is 0, else 0
- \(s\) = the inclusive scan of \(z\) // Scan of Section 21.7
- \(\mathsf{zeros} = s_{n-1}\) // the keys with bit 0
- for every \(i \in [0, n)\) in parallel {
- \(e_i = s_i - z_i\) // the exclusive scan
- if \(z_i = 1\): \(\mathsf{out}_{e_i} = K_i\)
- else: \(\mathsf{out}_{\mathsf{zeros} + i - e_i} = K_i\)
- }
Theorem 22.2 Parallel-Split writes every key exactly once, the positions form a permutation of \([0, n)\), and the split is stable.
Proof. By Theorem 21.2, the keys with bit 0 receive the distinct positions \([0, \mathsf{zeros})\) in input order. A key with bit 1 at position \(i\) receives \(\mathsf{zeros}\) plus the number of keys with bit 1 before it. For 2 such keys at \(i < j\), that number grows by at least 1. These positions are therefore distinct, increase with the input position, and run from \(\mathsf{zeros}\) to \(\mathsf{zeros} + (n - \mathsf{zeros}) - 1 = n - 1\). The 2 ranges \([0, \mathsf{zeros})\) and \([\mathsf{zeros}, n)\) do not overlap and together hold \(n\) positions.
In our example, the 4 keys with bit 1 receive the positions 4, 5, 6 and 7, in the order of their input positions 0, 2, 6 and 7, and the 4 keys with bit 0 receive the positions 0 to 3. A pass of Parallel-Split moves every key once, as the sequential split does. In addition, the parallel split writes the flags, scans them and reads them back, and we count the cost of this extra traffic in Section 22.5.
Exercises
22.5 Carry out Parallel-Split on bit 1 of \((2, 2, 0, 6, 5, 7, 3, 5)\), the output of Figure
22.3, and check the result against Figure 22.2.
22.6 Why does line 7 not need the inclusive scan of the flags of the bit-1 keys?
22.4 Stability
22.4.1 An unstable split
Suppose that a split puts the keys with bit 0 first, as it must, but writes the keys with bit 1 in some other order, for example in reverse. On its own bit, this is still a correct split. We apply it to bit 1 of the keys after the first pass, \((2, 2, 0, 6, 5, 7, 3, 5)\). The keys whose bit 1 is 0 are \((0, 5, 5)\), and they stay in order. The keys whose bit 1 is 1 are \((2, 2, 6, 7, 3)\), and they come out reversed, as \((3, 7, 6, 2, 2)\). The pass on bit 2, which is stable again, then gives \((0, 3, 2, 2, 5, 5, 7, 6)\), as Figure 22.4 shows.
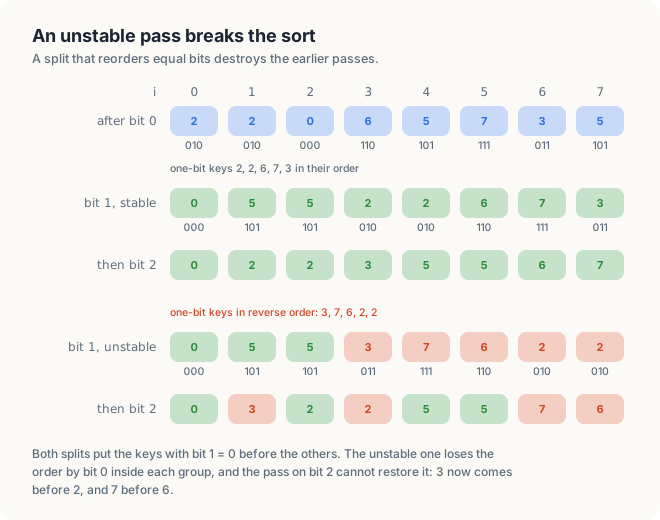
The keys 3 = 011 and 2 = 010 have the same bits 1 and 2, and only bit 0 tells them apart. The first pass had put 2 before 3. The unstable pass reversed them, and the last pass, which saw equal bits, kept the reversed order. As a result, 3 now precedes 2, and 7 precedes 6, which differ in the same way. This is the case of equal bits in the proof of Theorem 22.1, and it is the only place where the proof needs stability.
A split that hands out output positions in the order in which the threads arrive, for example by incrementing a shared counter, produces such an order. We run a split of this kind on the GPU in Section 22.8.
Rule Every pass of a least-significant-digit radix sort must be stable. A pass that places equal digits in any other order than the input order destroys the work of the passes before it.
Exercises
22.7 Which positions of the final result are wrong if the first pass, on bit 0, is the unstable
one and the other 2 are stable?
22.8 Does the last pass of a radix sort need to be stable when the keys carry no payload? Give a
reason.
22.5 The cost of 1-bit passes
A sort of 32-bit keys by Parallel-Split takes 32 passes. Each pass is memory-bound. It performs a few operations per key and moves several bytes per key, so its time is set by the bytes it moves. We count these bytes per key of 4 bytes. Line 1 reads the key and writes the flag, which is 8 bytes. The scan of Section 21.7 reads and writes the flags twice, which is 16 bytes. Lines 4 to 8 read the key, the flag and the scan, and write the key, which is another 16 bytes. A pass therefore moves \(8 + 16 + 16 = 40\) bytes per key, and the sort moves \(32 \times 40 = 1{,}280\) bytes per key, or 21.5 GB to sort 16,777,216 keys of 64 MiB in all.
The way to reduce this traffic is to reduce the number of passes. With a digit of \(r\) bits, a sort of 32-bit keys takes \(32 / r\) passes, so that with \(r = 4\), it needs 8 passes instead of 32. A pass on a digit of \(r\) bits, however, splits the keys into \(2^r\) groups rather than 2, and 1 scan of 1 flag no longer gives every group its start. Every key needs to know how many keys have each smaller digit, so the keys must be counted by digit. That count is a histogram, the subject of the next section.
22.6 Histograms
22.6.1 Counting by value
Definition 22.3 Histogram. The histogram of a list of keys over \(R\) bins is the array \(h\) of \(R\) counts in which \(h_{\mathsf{bin}}\) is the number of keys whose digit, or value, is \(\mathsf{bin}\).
Example. The histogram of \(K\) by value, over 8 bins, is \(h = (1, 0, 2, 1, 0, 2, 1, 1)\): 1 key 0, no key 1, 2 keys 2, and so on.
Each count of a histogram is called a bin. In the example, bin 2 holds \(h_2 = 2\), because the key 2 occurs twice, at positions 1 and 3. The sequential algorithm reads every key once and adds 1 to its bin.
Histogram(\(K, h, n, R\))
- for \(\mathsf{bin} \in [0, R)\): \(h_{\mathsf{bin}} = 0\)
- for \(i \in [0, n)\) {
- \(h_{K_i} = h_{K_i} + 1\) // a read, an addition and a write
- }
In line 3, the key \(K_i\) itself serves as the index of the bin. For \(i = 1\), for example, \(K_1 = 2\), and line 3 adds 1 to \(h_2\).
22.6.2 1 thread per key, and atomic additions
The direct parallel version gives every key its own thread, and each thread executes line 3 for its key. Line 3, however, consists of 3 operations. It reads the bin, adds 1, and writes the bin back. In our example, threads 1 and 3 hold the same key, 2. If both read \(h_2 = 0\) before either of them writes, both write 1, and 1 of the 2 counts is lost. The GPU offers an operation that cannot be split in this way.
Definition 22.4 Atomic operation. An atomic operation reads a
memory location, modifies the value and writes it back as 1 indivisible step. No other thread can
access the location between the read and the write. When several threads apply atomic operations
to the same location, the hardware performs them one after the other, in an order it chooses, and
every one of them takes effect. In CUDA C++, the atomic addition is atomicAdd(&h[v], 1); in
cuda-oxide, it is the method fetch_add of an atomic type such as DeviceAtomicU32.
Example. Threads 1 and 3 each apply an atomic addition of 1 to \(h_2\). Whatever their order, \(h_2\) ends at 2.
Atomic operations make the histogram correct, but they introduce a new cost when many threads update the same bin.
Definition 22.5 Contention. Contention is the waiting that occurs when several threads apply atomic operations to the same location at about the same time: since the operations are performed one after the other, each waits for those before it.
Example. Bins 2 and 5 each receive 2 requests from our 8 threads, and 1 of the 2 requests waits for the other (Figure 22.5).
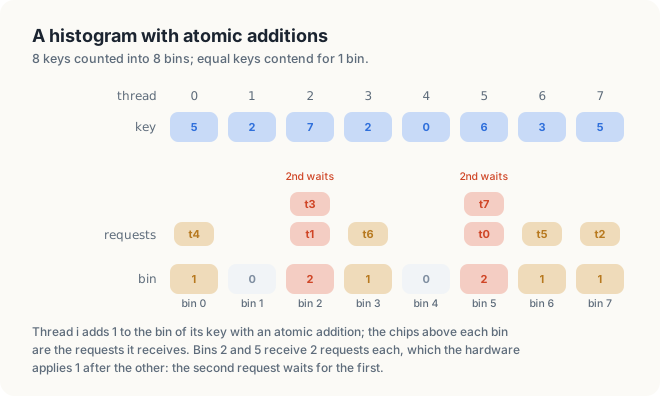
Atomic operations on global memory are performed in the L2 cache, which all SMs share, and the requests to 1 address are queued there. In Section 5.5.2, we measured this queue. A histogram of 64 MiB of bytes into 256 global bins took 33.40 ms for random bytes and 134.65 ms for bytes that were all 7, 4 times as long, because every request went to the same address. A radix pass with digits of 4 bits has only 16 bins, so even random keys send 1/16 of all requests to each address.
22.6.3 Private bins
The solution is to let fewer threads share a bin. Each block counts its keys into its own copy of the bins in shared memory, where only the threads of that block compete, and where an atomic operation completes within the SM. When the block has counted all of its keys, it adds each of its bins to the corresponding global bin once, as Figure 22.6 shows.
Definition 22.6 Privatization. Privatization gives each block, or each warp, a private copy of a shared result, lets it update only its copy, and merges the copies into the shared result at the end.
Example. Block 0 counts the keys 5, 2, 7, 2 into the private bins \((0, 0, 2, 0, 0, 1, 0, 1)\), block 1 counts 0, 6, 3, 5 into \((1, 0, 0, 1, 0, 1, 1, 0)\), and their sum is the histogram.
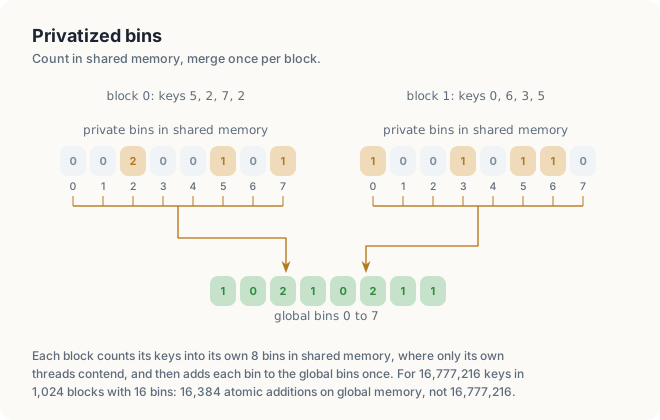
In the following procedure, \(\mathsf{privateBins}\) is the array of \(R\) private bins in shared memory.
Histogram-Private(\(K, h, n, R\))
- if \(\mathsf{threadIdx{.}x} < R\): \(\mathsf{privateBins}[\mathsf{threadIdx{.}x}] = 0\) // \(\mathsf{privateBins}\) in shared memory
- Barrier() // every private bin is 0
- for \(i = \mathsf{blockIdx{.}x} \cdot \mathsf{blockDim{.}x} + \mathsf{threadIdx{.}x}\); \(i < n\); \(i = i + \mathsf{gridDim{.}x} \cdot \mathsf{blockDim{.}x}\) {
- Atomic-Add(\(\mathsf{privateBins}[\mathsf{digit}(K_i)]\), 1)
- }
- Barrier() // every key of the block is counted
- if \(\mathsf{threadIdx{.}x} < R\): Atomic-Add(\(h_{\mathsf{threadIdx{.}x}}\), \(\mathsf{privateBins}[\mathsf{threadIdx{.}x}]\)) // the merge
| Symbol | Meaning | Example: \(\mathsf{gridDim{.}x} = 2\), \(\mathsf{blockDim{.}x} = 2\), \(n = 8\) |
|---|---|---|
| \(\mathsf{gridDim{.}x}\), \(\mathsf{blockDim{.}x}\) | number of blocks, and threads per block | 2 and 2 |
| \(\mathsf{gridDim{.}x} \cdot \mathsf{blockDim{.}x}\) | number of threads in the grid, the stride of the loop | 4 |
| \(bT + \mathsf{threadIdx{.}x}\) | the first key of thread \(\mathsf{threadIdx{.}x}\) of block \(\mathsf{blockIdx{.}x}\) | 3 for \(\mathsf{blockIdx{.}x} = 1\), \(\mathsf{threadIdx{.}x} = 1\) |
| \(R\) | number of bins | 8 |
Line 3 is a grid-stride loop. The \(\mathsf{gridDim{.}x} \cdot \mathsf{blockDim{.}x}\) threads of the grid take the keys in rounds, so that in each round, neighboring threads read neighboring keys. In the small grid of the table, thread 1 of block 1 starts at key \(1 \cdot 2 + 1 = 3\) and then moves on to key \(3 + 4 = 7\), while the 4 threads together read keys 0 to 3 in the first round and keys 4 to 7 in the second. The 2 barriers separate 3 phases. Without the first barrier, a thread could count into a bin that another thread has not yet set to 0. Without the second barrier, thread \(\mathsf{threadIdx{.}x}\) could merge bin \(\mathsf{threadIdx{.}x}\) before the other threads have finished counting into it.
With private bins, the number of atomic operations on global memory falls from 1 per key to \(R\) per block. With \(\mathsf{gridDim{.}x} = 1{,}024\) blocks and \(R = 16\) bins, a histogram of 16,777,216 keys makes \(1{,}024 \cdot 16 = 16{,}384\) atomic additions on global memory instead of 16,777,216, which is 1,024 times fewer.
22.6.4 Warp aggregation
Inside a block, some contention remains. When the 32 lanes of a warp hold the same digit, 32 atomic operations on 1 bin in shared memory are performed one after the other. The lanes can, however, combine their counts first, with the following instruction.
Definition 22.7 Match. A match is an instruction that all 32
lanes of a warp execute together, each with a value; it returns to every lane a 32-bit word
whose bit \(k\) is 1 if lane \(k\) holds the same value. In C++, it is
__match_any_sync(mask, v); in cuda-oxide, warp::match_any_sync(mask, v).
Example. For 8 lanes holding the digits \((1, 2, 3, 2, 0, 2, 3, 1)\), lane 5 receives the bits of lanes 1, 3 and 5, the lanes with digit 2.
With a match, the lowest lane of each group of lanes with equal digits adds the popcount of its word, which is the size of the group, with 1 atomic operation, and the other lanes of the group add nothing. In the example of Definition 22.7, lane 1 adds 3 to the bin of digit 2, and lanes 3 and 5 add nothing. A warp then makes at most 1 atomic operation per distinct digit, instead of 32. This technique is called warp aggregation. It costs a match instruction for every key, and in Section 22.10, we measure whether it pays for itself.
Exercises
22.9 Compute the histogram of \((6, 1, 4, 4, 7, 0, 3, 1)\) over 8 bins. Which bins receive more
than 1 request?
22.10 For 16,777,216 keys, 1,024 blocks and 256 bins, how many atomic operations does
Histogram-Private make on global memory, and how many on shared memory?
22.11 What does the merge of line 7 compute if the second barrier is removed and 1 thread of the
block is delayed?
22.7 A pass on a digit of several bits
22.7.1 The positions from a histogram
We now sort by digits of 2 bits. Our keys have 3 bits, so a first pass on the digit at shift 0, the 2 low bits, followed by a second pass on bit 2, sorts them. The digits of the first pass are \((1, 2, 3, 2, 0, 2, 3, 1)\). For example, the key 5 = 101 has the 2 low bits 01, so its digit is 1. The histogram of these digits over 4 bins is \((1, 2, 3, 2)\): 1 key with digit 0, 2 with digit 1, 3 with digit 2 and 2 with digit 3.
In the output of the pass, the key with digit 0 comes first, at position 0. The 2 keys with digit 1 follow at positions 1 and 2, the 3 keys with digit 2 at positions 3, 4 and 5, and the 2 keys with digit 3 at positions 6 and 7. The start of each digit, \((0, 1, 3, 6)\), is therefore the exclusive scan of the histogram. Within a digit, the keys keep their input order. The first key with digit 2, the 2 at position 1, goes to position 3, the second, the 2 at position 3, goes to position 4, and the third, the 6 at position 5, goes to position 5. The number of keys with the same digit that come before a key has its own name.
Definition 22.8 Rank. The rank of a key in a pass is the number of keys before it, in input order, that have the same digit.
Example. In the pass on the 2 low bits, the 6 at position 5 has digit 2, and 2 keys with digit 2 come before it, at positions 1 and 3: its rank is 2.
Key observation The exclusive scan of the digit histogram gives the start of every digit in the output, and a key goes to the start of its digit plus its rank. The split of Section 22.3 is the case of 1 bit: 2 bins, a start of 0 for digit 0 and \(Z\) for digit 1, and ranks \(e_i\) and \(i - e_i\).
For the 6 at position 5, the start of digit 2 is 3 and its rank is 2, so it goes to position \(3 + 2 = 5\). Figure 22.7 carries out the whole pass. The output, \((0, 5, 5, 2, 2, 6, 7, 3)\), is the output of the 2 splits on bits 0 and 1 in Figure 22.2, as it must be, since 1 stable pass on 2 bits sorts by those 2 bits, as 2 stable passes on 1 bit do.
On a CPU, this pass is the counting sort, which consists of 3 loops over the keys and the bins. In the following procedure, \(s\) is the shift and \(r\) the number of bits of the digit, as in Definition 22.1, and \(\mathsf{start}[\mathsf{digit}]\) is the next free output position for a key with digit \(\mathsf{digit}\).
Counting-Pass(\(K, \mathsf{out}, n, s, r\))
- \(h\) = the histogram of the digits \(\lfloor K_i / 2^s \rfloor \bmod 2^r\) over \(2^r\) bins
- \(\mathsf{start}\) = the exclusive scan of \(h\)
- for \(i \in [0, n)\) { // in input order
- \(\mathsf{digit}\) = the digit of \(K_i\)
- \(\mathsf{out}_{start[\mathsf{digit}]} = K_i\)
- \(\mathsf{start}[\mathsf{digit}] = \mathsf{start}[\mathsf{digit}] + 1\) // the next key with digit \(\mathsf{digit}\)
- }
In line 5, \(\mathsf{start}[\mathsf{digit}]\) has grown by 1 for every earlier key with digit \(\mathsf{digit}\), so it equals the start of \(\mathsf{digit}\) plus the rank of the key. For the 6 at position 5, \(\mathsf{start}[2]\) began at 3 and grew by 1 for each of the 2 keys at positions 1 and 3, so it equals 5. Line 6 forms a chain like the counter of Sequential-Compact, because the rank of each key depends on all the keys before it.
22.7.2 Many tiles
On the GPU, the keys are cut into tiles of 1,024 keys, 1 block per tile, as in Section 21.7. A block can count the digits of its own tile and rank its own keys. The position of a key, however, also depends on the keys with smaller digits in every tile, and on the keys with the same digit in earlier tiles. Both of these numbers come from 1 scan, provided that the counts of all tiles are laid out digit by digit. The table holds first the count of digit 0 in tile 0, in tile 1, and so on, then the counts of digit 1 in every tile, and so on. With \(m\) tiles, the count of digit \(\mathsf{digit}\) in tile \(b\) is entry \(dm + b\) of the table. The exclusive scan of this table at entry \((\mathsf{digit}, b)\) is the number of keys with a smaller digit anywhere, plus the number of keys with digit \(\mathsf{digit}\) in the tiles before \(b\), which is exactly the start of digit \(\mathsf{digit}\) in tile \(b\).
Figure 22.8 shows the table for our keys, cut into 2 tiles of 4. Tile 0 holds the digits \((1, 2, 3, 2)\), and tile 1 holds \((0, 2, 3, 1)\). With \(m = 2\), the count of digit 1 in tile 1 is entry \(1 \cdot 2 + 1 = 3\) of the table. The scan of the table places digit 1 of tile 1 at position 2, after the key 0 of tile 1 and the key 5 of tile 0. The keys of tile 1 then land at positions 0, 5, 7 and 2, the same positions as in Figure 22.7.
Inside a tile, the rank of a key is the number of keys with the same digit before it in the tile. A block processes its tile in 4 steps of 256 keys. Within a step, the match of Definition 22.7 gives each lane the lanes of its warp that hold the same digit. Keeping only the bits of the lanes below it, and counting them, gives the rank of the key within the warp, just as the ballot gave the position within the warp in Section 21.9 (Figure 22.9). The counts of the earlier warps of the step, and of the earlier steps of the tile, complete the rank.
22.7.3 The algorithm
A pass on the digit of \(r = 4\) bits at shift \(s\) has three parts. The first kernel counts the digits of every tile with private bins, as in lines 1 to 6 of Histogram-Private but without a grid-stride loop, and writes its 16 counts into column \(\mathsf{blockIdx{.}x}\) of the table \(c\). Scan then computes the inclusive scan of the table, which has \(16 \cdot \mathsf{tiles}\) entries for \(\mathsf{tiles}\) tiles. The second kernel moves the keys.
In the following procedure, \(c\) is the table of counts and \(s\) its inclusive scan, so that \(s_j - c_j\) is the exclusive scan at entry \(j\). In line 1, thread \(\mathsf{threadIdx{.}x} < 16\) stands for digit \(\mathsf{threadIdx{.}x}\), and the entry \(\mathsf{entry} = \mathsf{threadIdx{.}x} \cdot \mathsf{tiles} + \mathsf{blockIdx{.}x}\) is the count of that digit in tile \(\mathsf{blockIdx{.}x}\). The shared array \(\mathsf{start}\) holds, for each digit, the output position of the next key with that digit, and the shared array \(\mathsf{warpCounts}\) holds, for each warp \(\mathsf{warp}\) and digit \(\mathsf{digit}\), the number of keys with digit \(\mathsf{digit}\) in warp \(\mathsf{warp}\) in the current step.
Scatter-Digits(\(K, \mathsf{out}, c, s\))
- if \(\mathsf{threadIdx{.}x} < 16\): \(\mathsf{start}[\mathsf{threadIdx{.}x}] = s_{\mathsf{entry}} - c_{\mathsf{entry}}\) // the exclusive scan of the table
- for \(\mathsf{step} \in [0, 4)\) { // 4 steps of 256 keys, in order
- set \(\mathsf{warpCounts}[\cdot][\cdot]\) to 0; Barrier()
- \(i = 1024 \cdot \mathsf{blockIdx{.}x} + 256 \cdot \mathsf{step} + \mathsf{threadIdx{.}x}\), \(\mathsf{digit}\) = the digit of \(K_i\)
- \(\mathsf{peers}\) = Match(\(\mathsf{digit}\)), \(\mathsf{rank}\) = Popc(\(\mathsf{peers} \wedge (2^{\mathsf{lane}} - 1)\))
- if \(\mathsf{rank} = 0\): \(\mathsf{warpCounts}[\mathsf{warp}][\mathsf{digit}]\) = Popc(\(\mathsf{peers}\)) // 1 lane per digit and warp
- Barrier()
- \(\mathsf{out}[\mathsf{start}[\mathsf{digit}] + \sum_{\mathsf{other} < \mathsf{warp}} \mathsf{warpCounts}[\mathsf{other}][\mathsf{digit}] + \mathsf{rank}] = K_i\)
- Barrier()
- if \(\mathsf{threadIdx{.}x} < 16\): \(\mathsf{start}[\mathsf{threadIdx{.}x}] \mathrel{+}= \sum_{\mathsf{warp}=0}^{7} \mathsf{warpCounts}[\mathsf{warp}][\mathsf{threadIdx{.}x}]\)
- Barrier()
- }
| Symbol | Meaning | Lane 5 in the 8-lane example |
|---|---|---|
| \(\mathsf{digit}\) | digit of the key of this thread | 2 |
| \(\mathsf{peers}\) | lanes of the warp with the same digit, from the match | lanes 1, 3 and 5 |
| \(2^{\mathsf{lane}} - 1\) | mask of the lanes below lane \(\mathsf{lane}\) | lanes 0 to 4 |
| \(\mathsf{rank}\) | lanes below this one with the same digit | 2 (lanes 1 and 3) |
| \(\mathsf{warpCounts}[\mathsf{warp}][\mathsf{digit}]\) | keys with digit \(\mathsf{digit}\) in warp \(\mathsf{warp}\), written by the lane with rank 0 | 3, written by lane 1 |
| \(\mathsf{start}[\mathsf{digit}]\) | output position of the next key with digit \(\mathsf{digit}\) in this tile | 3 in the 1-tile example |
Line 8 corresponds to line 5 of Counting-Pass, with the rank assembled from three parts. The first part is the number of keys with the same digit in the earlier steps of the tile, which line 10 has added to \(\mathsf{start}[\mathsf{digit}]\). The second part is the number of such keys in the earlier warps of the step, and the third part is the number in the earlier lanes of the warp. In the 8-lane example, taken as a single tile and a single warp, lane 5 writes its key 6 to position \(\mathsf{start}[2] + \mathsf{rank} = 3 + 2 = 5\).
Each of the 4 barriers separates a write to the shared arrays from the reads that need it. The barrier of line 3 completes the clearing of \(\mathsf{warpCounts}\) before any lane writes a count, and line 7 completes the counts before any thread sums them. Line 9 completes every read of \(\mathsf{start}\) before line 10 changes it, and line 11 completes the change before the next step reads \(\mathsf{start}\).
22.7.4 Counting the bytes
A pass reads every key twice, once in the counting kernel and once in the scatter, and writes it once, which is 12 bytes per key. The table holds 16 counts per 1,024 keys, so its scan moves less than 1 byte per key. A sort of 32-bit keys by 8 passes of 4 bits therefore moves about \(8 \times 12 = 96\) bytes per key, against 1,280 bytes for 32 passes of 1 bit, which is 13 times less.
Exercises
22.12 Carry out Counting-Pass on the digit of 2 bits at shift 1 of \(K\). What are the
histogram, the starts and the output?
22.13 Build the table of Figure 22.8 for 4 tiles of 2 keys, and give its exclusive scan.
22.14 How many bytes per key does a sort by 4 passes of 8 bits move, if the scan of the table is
counted too? (A tile has 256 counts.)
22.8 Correctness
Theorem 22.3 A pass of Scatter-Digits writes every key of the input exactly once, the positions form a permutation of \([0, n)\), and keys with equal digits keep their input order.
Proof. Let \(c(\mathsf{digit}, \mathsf{blockIdx{.}x})\) be the number of keys with digit \(\mathsf{digit}\) in tile \(\mathsf{blockIdx{.}x}\), and \(S(\mathsf{digit}, \mathsf{blockIdx{.}x})\) the exclusive scan of the table at entry \((\mathsf{digit}, \mathsf{blockIdx{.}x})\): the number of keys with a digit below \(\mathsf{digit}\), plus the keys with digit \(\mathsf{digit}\) in tiles before \(\mathsf{blockIdx{.}x}\). We show that the keys with digit \(\mathsf{digit}\) of tile \(\mathsf{blockIdx{.}x}\) receive the positions \(S(\mathsf{digit}, \mathsf{blockIdx{.}x})\) to \(S(\mathsf{digit}, \mathsf{blockIdx{.}x}) + c(\mathsf{digit}, \mathsf{blockIdx{.}x}) - 1\), in input order. The step \(\mathsf{step}\), the warp \(\mathsf{warp}\) and the lane \(\mathsf{lane}\) of a key order the keys of a tile as their indices do, since the index is \(1024 \cdot \mathsf{blockIdx{.}x} + 256 \cdot \mathsf{step} + 32 \cdot \mathsf{warp} + \mathsf{lane}\). In line 8, the position of a key is \(S(\mathsf{digit}, \mathsf{blockIdx{.}x})\) plus 3 counts of keys with digit \(\mathsf{digit}\): those in the earlier steps (added to \(\mathsf{start}[\mathsf{digit}]\) by line 10 of each earlier step), those in the earlier warps of the step, and those in the earlier lanes of the warp. Together they are exactly the keys with digit \(\mathsf{digit}\) before it in the tile. These numbers are \(0, 1, \ldots, c(\mathsf{digit}, \mathsf{blockIdx{.}x}) - 1\) in input order. The ranges for different \((\mathsf{digit}, \mathsf{blockIdx{.}x})\) follow each other in the order of the table, without gap or overlap, and the last ends at \(n - 1\).
| Symbol | Meaning | Digit 1, tile 1 of Figure 22.8 |
|---|---|---|
| \(c(\mathsf{digit}, \mathsf{blockIdx{.}x})\) | keys with digit \(\mathsf{digit}\) in tile \(\mathsf{blockIdx{.}x}\) | 1 (the key 5) |
| \(S(\mathsf{digit}, \mathsf{blockIdx{.}x})\) | start of digit \(\mathsf{digit}\) in tile \(\mathsf{blockIdx{.}x}\): the exclusive scan of the table | 2 |
| \(S(\mathsf{digit}, \mathsf{blockIdx{.}x})\) to \(S(\mathsf{digit}, \mathsf{blockIdx{.}x}) + c(\mathsf{digit}, \mathsf{blockIdx{.}x}) - 1\) | the positions of these keys | 2 to 2 |
Rank and stability are the same thing here. The rank counts the keys that come before a key in input order, so a pass that places keys by rank is stable by construction, and a pass that places them by any other count is not. To see the difference on the GPU, we replaced the position of line 8 by an atomic increment of \(\mathsf{start}[\mathsf{digit}]\), and removed line 10. The increment hands every key the next free position of its digit, in the order in which the threads arrive. We ran the C++ program with this change, and it printed the following lines.
$ ./unstable # out[atomicAdd(&start[d], 1)] = key
radix sort of 5 2 7 2 0 6 3 5
...
4-bit pass 0 2 2 3 5 5 6 7
...
method 1 run 1: 5618124 neighbours out of order, 15278248 keys misplaced
method 1 run 2: 5627284 neighbours out of order, 15294346 keys misplaced
method 1 run 3: 5638523 neighbours out of order, 15291387 keys misplaced
FAILED
On the 8 keys, the result was correct, because the 8 lanes of 1 warp happened to obtain their positions in lane order. On 16,777,216 keys, 15.3 million keys ended in the wrong place, 5.6 million neighbors were out of order, and the counts differed from run to run. Every pass still grouped the keys correctly by its own digit. Only the order inside the groups was lost, and with it the work of the earlier passes, as in Figure 22.4.
Exercises
22.15 In Scatter-Digits, which wrong position can a key receive if the barrier of line 9 is
removed? Describe a schedule.
22.16 Prove that \(S(\mathsf{digit}, \mathsf{blockIdx{.}x}) + c(\mathsf{digit}, \mathsf{blockIdx{.}x}) = S(\mathsf{digit}, \mathsf{blockIdx{.}x} + 1)\) for \(\mathsf{blockIdx{.}x} < \mathsf{tiles} - 1\), and
\(S(\mathsf{digit}, \mathsf{tiles} - 1) + c(\mathsf{digit}, \mathsf{tiles} - 1) = S(\mathsf{digit} + 1, 0)\).
22.9 Implementation
22.9.1 The histograms
The following listing implements Histogram-Private for digits of 4 bits. Each block clears its 16 private bins, counts its keys into them with a grid-stride loop, and merges them into the global bins.
Listing 22.1 A histogram of 4-bit digits with private bins.
mod kernels {
// ...
/// 2. Each block counts into private bins in shared memory and merges them once.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn hist_shared(keys: &[u32], shift: u32, bins: &[DeviceAtomicU32]) {
static mut LOCAL: SharedArray<u32, RADIX> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
if tid < RADIX {
// SAFETY: threads 0 to 15 each zero their own bin, before the barrier.
unsafe { LOCAL[tid] = 0 };
}
thread::sync_threads();
// SAFETY: between the 2 barriers every access to LOCAL is atomic.
let local = unsafe { (*&raw mut LOCAL).as_mut_ptr() };
let stride = (thread::gridDim_x() * 256) as usize;
let mut index = thread::index_1d().get();
while index < keys.len() {
let digit = digit_of(keys[index], shift);
// SAFETY: d < RADIX, and LOCAL holds RADIX bins.
unsafe { shared_bin(local, digit) }.fetch_add(1, AtomicOrdering::Relaxed);
index += stride;
}
thread::sync_threads();
if tid < RADIX {
// SAFETY: after the barrier no thread writes LOCAL again.
let count = unsafe { LOCAL[tid] };
bins[tid].fetch_add(count, AtomicOrdering::Relaxed);
}
}
// ...
}// 2. Each block counts into private bins in shared memory and merges them once.
__global__ void histShared(const unsigned* keys, int shift, unsigned* bins, int n)
{
__shared__ unsigned local[RADIX];
if (threadIdx.x < RADIX) {
local[threadIdx.x] = 0;
}
__syncthreads();
int stride = gridDim.x * blockDim.x;
for (int index = blockIdx.x * blockDim.x + threadIdx.x; index < n; index += stride) {
atomicAdd(&local[digitOf(keys[index], shift)], 1u);
}
__syncthreads();
if (threadIdx.x < RADIX) {
atomicAdd(&bins[threadIdx.x], local[threadIdx.x]);
}
}
The bins in shared memory are a SharedArray<u32, RADIX> in Rust and a __shared__ array in
C++. CUDA C++ applies atomicAdd to any address. cuda-oxide, on the other hand, gives atomics their
own types, with the scope of the threads that may share them in the name. The type
DeviceAtomicU32 is used for global memory, which every thread of the grid can reach, and
BlockAtomicU32 for shared memory, which only the threads of the block can reach. The global bins
arrive as a slice &[DeviceAtomicU32], which the host creates by reinterpreting a buffer of u32
with cast_elem. A shared bin is viewed as a BlockAtomicU32 with BlockAtomicU32::from_ptr,
which the helper shared_bin wraps. The pointer comes from the SharedArray, so the call is
unsafe, and its safety comment states that the digit is below 16.
The next listing implements the same histogram with warp aggregation. The lanes of a warp that hold the same digit find each other with a match, and only the lowest of them adds the count of the group to the private bin.
Listing 22.2 The same histogram with warp aggregation.
mod kernels {
// ...
/// 3. As 2, but the lanes of a warp with equal digits add their count with 1 atomic.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn hist_aggregated(keys: &[u32], shift: u32, bins: &[DeviceAtomicU32]) {
static mut LOCAL: SharedArray<u32, RADIX> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
if tid < RADIX {
// SAFETY: threads 0 to 15 each zero their own bin, before the barrier.
unsafe { LOCAL[tid] = 0 };
}
thread::sync_threads();
// SAFETY: between the 2 barriers every access to LOCAL is atomic.
let local = unsafe { (*&raw mut LOCAL).as_mut_ptr() };
let lane = warp::lane_id();
let stride = (thread::gridDim_x() * 256) as usize;
let mut base = thread::blockIdx_x() as usize * 256;
while base < keys.len() {
let index = base + tid;
let inside = index < keys.len();
let digit = if inside { digit_of(keys[index], shift) } else { RADIX };
let peers = warp::match_any_sync(u32::MAX, digit as u32);
let leader = peers.trailing_zeros();
if lane == leader && digit < RADIX {
// SAFETY: d < RADIX, and LOCAL holds RADIX bins.
let bin = unsafe { shared_bin(local, digit) };
bin.fetch_add(peers.count_ones(), AtomicOrdering::Relaxed);
}
base += stride;
}
thread::sync_threads();
if tid < RADIX {
// SAFETY: after the barrier no thread writes LOCAL again.
let count = unsafe { LOCAL[tid] };
bins[tid].fetch_add(count, AtomicOrdering::Relaxed);
}
}
// ...
}// 3. As 2, but the lanes of a warp with equal digits add their count with 1 atomic.
__global__ void histAggregated(const unsigned* keys, int shift, unsigned* bins, int n)
{
__shared__ unsigned local[RADIX];
if (threadIdx.x < RADIX) {
local[threadIdx.x] = 0;
}
__syncthreads();
int lane = threadIdx.x % 32;
int stride = gridDim.x * blockDim.x;
for (int base = blockIdx.x * blockDim.x; base < n; base += stride) {
int index = base + threadIdx.x;
unsigned digit = index < n ? digitOf(keys[index], shift) : RADIX;
unsigned peers = __match_any_sync(FULL, digit);
int leader = __ffs(peers) - 1;
if (lane == leader && digit < RADIX) {
atomicAdd(&local[digit], __popc(peers));
}
}
__syncthreads();
if (threadIdx.x < RADIX) {
atomicAdd(&bins[threadIdx.x], local[threadIdx.x]);
}
}
The loop runs over base, the first key of the round of the block, rather than over the key
itself, so that all 32 lanes of every warp execute the match together, including the lanes past
the end of the array. Those lanes match on the value 16, which no digit has, and add nothing. The
variable leader is the lowest lane of the group, the position of the lowest 1 bit of peers.
22.9.2 The split
The following listing implements lines 4 to 8 of Parallel-Split, in which every key computes its position from the scan of the zero flags and writes itself there. The flags and the scan are the kernels of Chapter 21.
Listing 22.3 The scatter of a split on 1 bit.
mod kernels {
// ...
/// Zero-bit keys go to their exclusive scan, one-bit keys after all zero-bit keys.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn split_scatter(
keys: &[u32],
flags: &[u32],
scanned: &[u32],
mut out: DisjointSlice<u32>,
) {
let index = thread::index_1d().get();
if index < keys.len() {
let zeros = scanned[keys.len() - 1] as usize;
let upto = scanned[index] as usize; // zero-bit keys among 0 to i
let at = if flags[index] == 1 { upto - 1 } else { zeros + index - upto };
// SAFETY: zero-bit keys receive 0 to zeros - 1 and one-bit keys zeros to
// n - 1, each position once: a permutation of 0 to n - 1.
unsafe { *out.get_unchecked_mut(at) = keys[index] };
}
}
// ...
}// Zero-bit keys go to their exclusive scan, one-bit keys after all zero-bit keys.
__global__ void splitScatter(const unsigned* keys, const unsigned* flags,
const unsigned* scanned, unsigned* out, int n)
{
int index = blockIdx.x * blockDim.x + threadIdx.x;
if (index < n) {
unsigned zeros = scanned[n - 1];
unsigned upto = scanned[index]; // zero-bit keys among 0 to index
unsigned at = flags[index] == 1 ? upto - 1 : zeros + index - upto;
out[at] = keys[index];
}
}
The variable zeros is \(Z\), and upto is the inclusive scan \(s_i\), so that upto - 1 is
\(e_i\) for a key with bit 0, and zeros + i - upto is \(Z + i - e_i\) for a key with bit 1,
whose flag is 0. We let every thread read scanned[n - 1], the number of keys with bit 0, and the cache
serves all but the first of these reads. The Rust write uses get_unchecked_mut, and its safety
comment is Theorem 22.2: the positions form a permutation of \([0, n)\).
22.9.3 The pass on a 4-bit digit
A pass on a 4-bit digit takes 3 listings. The following listing implements the first kernel of the pass, which counts the digits of each tile in private bins and writes the 16 counts into the table, digit by digit.
Listing 22.4 The digit counts of every tile, digit by digit.
mod kernels {
// ...
/// The 4-bit pass, step 1: the digit histogram of every tile, stored digit by digit:
/// counts[digit * tiles + tile] is the number of keys with that digit in that tile.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn digit_counts(keys: &[u32], shift: u32, mut counts: DisjointSlice<u32>) {
static mut LOCAL: SharedArray<u32, RADIX> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
let block = thread::blockIdx_x() as usize;
if tid < RADIX {
// SAFETY: threads 0 to 15 each zero their own bin, before the barrier.
unsafe { LOCAL[tid] = 0 };
}
thread::sync_threads();
// SAFETY: between the 2 barriers every access to LOCAL is atomic.
let local = unsafe { (*&raw mut LOCAL).as_mut_ptr() };
let mut step = 0;
#[unroll]
while step < 4 {
let index = block * TILE + step * 256 + tid;
if index < keys.len() {
let digit = digit_of(keys[index], shift);
// SAFETY: d < RADIX, and LOCAL holds RADIX bins.
unsafe { shared_bin(local, digit) }.fetch_add(1, AtomicOrdering::Relaxed);
}
step += 1;
}
thread::sync_threads();
if tid < RADIX {
let tiles = thread::gridDim_x() as usize;
// SAFETY: thread d of block b alone writes entry d * tiles + b, and the
// table holds RADIX * tiles entries.
unsafe { *counts.get_unchecked_mut(tid * tiles + block) = LOCAL[tid] };
}
}
// ...
}// The 4-bit pass, step 1: the digit histogram of every tile, stored digit by digit:
// counts[digit * tiles + tile] is the number of keys with that digit in that tile.
__global__ void digitCounts(const unsigned* keys, int shift, unsigned* counts, int n)
{
__shared__ unsigned local[RADIX];
if (threadIdx.x < RADIX) {
local[threadIdx.x] = 0;
}
__syncthreads();
for (int step = 0; step < 4; ++step) {
int index = blockIdx.x * TILE + step * 256 + threadIdx.x;
if (index < n) {
atomicAdd(&local[digitOf(keys[index], shift)], 1u);
}
}
__syncthreads();
if (threadIdx.x < RADIX) {
counts[threadIdx.x * gridDim.x + blockIdx.x] = local[threadIdx.x];
}
}
The final write stores the count of digit \(d\) of block \(b\) at entry
tid * tiles + block, which is entry \(dm + b\) of the table of Section 22.7.2. The next listing
implements Scatter-Digits, which moves every key to the start of its digit in its tile plus its
rank.
Listing 22.5 The scatter of a pass on a 4-bit digit.
mod kernels {
// ...
/// The 4-bit pass, step 3: every key goes to the start of its digit in its tile, plus
/// the keys with the same digit before it in the tile. 4 steps of 256 keys, in order.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scatter_digits(
keys: &[u32],
shift: u32,
counts: &[u32],
scanned: &[u32],
mut out: DisjointSlice<u32>,
) {
static mut START: SharedArray<u32, RADIX> = SharedArray::UNINIT;
// The count of digit d in warp w, at slot w * RADIX + d.
static mut WARP_COUNTS: SharedArray<u32, 128> = SharedArray::UNINIT;
let thread_idx = thread::threadIdx_x() as usize;
let block = thread::blockIdx_x() as usize;
let lane = warp::lane_id();
let warp = thread_idx / 32;
let below = (1u32 << lane) - 1;
if thread_idx < RADIX {
let entry = thread_idx * thread::gridDim_x() as usize + block;
// SAFETY: thread t alone writes START[t], before the first barrier.
unsafe { START[thread_idx] = scanned[entry] - counts[entry] };
}
let mut step = 0;
#[unroll]
while step < 4 {
if thread_idx < 8 * RADIX {
// SAFETY: thread t alone writes slot t, between 2 barriers.
unsafe { WARP_COUNTS[thread_idx] = 0 };
}
thread::sync_threads();
let index = block * TILE + step * 256 + thread_idx;
let key = if index < keys.len() { keys[index] } else { 0 };
let digit = if index < keys.len() { digit_of(key, shift) } else { RADIX };
let peers = warp::match_any_sync(u32::MAX, digit as u32);
let rank = (peers & below).count_ones();
if rank == 0 && digit < RADIX {
// SAFETY: 1 lane per digit and warp writes slot warp * 16 + d.
unsafe { WARP_COUNTS[warp * RADIX + digit] = peers.count_ones() };
}
thread::sync_threads();
if digit < RADIX {
let mut before = 0;
let mut other = 0;
while other < warp {
// SAFETY: between the 2 barriers the slots are only read.
before += unsafe { WARP_COUNTS[other * RADIX + digit] };
other += 1;
}
// SAFETY: START is only read between these barriers.
let at = (unsafe { START[digit] } + before + rank) as usize;
// SAFETY: the keys of each digit receive distinct consecutive positions
// after the keys of the smaller digits and of the earlier tiles: the
// positions of all keys form a permutation of 0 to n - 1.
unsafe { *out.get_unchecked_mut(at) = key };
}
thread::sync_threads();
if thread_idx < RADIX {
let mut other = 0;
#[unroll]
while other < 8 {
// SAFETY: thread t alone updates START[t]; the slots are only read.
unsafe { START[thread_idx] += WARP_COUNTS[other * RADIX + thread_idx] };
other += 1;
}
}
thread::sync_threads();
step += 1;
}
}
}// The 4-bit pass, step 3: every key goes to the start of its digit in its tile, plus
// the keys with the same digit before it in the tile. 4 steps of 256 keys, in order.
__global__ void scatterDigits(const unsigned* keys, int shift, const unsigned* counts,
const unsigned* scanned, unsigned* out, int n)
{
__shared__ unsigned start[RADIX];
__shared__ unsigned warpCounts[8 * RADIX]; // [warp][digit]
int lane = threadIdx.x % 32;
int warp = threadIdx.x / 32;
unsigned below = (1u << lane) - 1;
if (threadIdx.x < RADIX) {
int entry = threadIdx.x * gridDim.x + blockIdx.x;
start[threadIdx.x] = scanned[entry] - counts[entry]; // the exclusive scan
}
for (int step = 0; step < 4; ++step) {
if (threadIdx.x < 8 * RADIX) {
warpCounts[threadIdx.x] = 0;
}
__syncthreads();
int index = blockIdx.x * TILE + step * 256 + threadIdx.x;
unsigned key = index < n ? keys[index] : 0;
unsigned digit = index < n ? digitOf(key, shift) : RADIX;
unsigned peers = __match_any_sync(FULL, digit);
unsigned rank = __popc(peers & below);
if (rank == 0 && digit < RADIX) {
warpCounts[warp * RADIX + digit] = __popc(peers);
}
__syncthreads();
if (digit < RADIX) {
unsigned before = 0;
for (int other = 0; other < warp; ++other) {
before += warpCounts[other * RADIX + digit];
}
out[start[digit] + before + rank] = key;
}
__syncthreads();
if (threadIdx.x < RADIX) {
for (int other = 0; other < 8; ++other) {
start[threadIdx.x] += warpCounts[other * RADIX + threadIdx.x];
}
}
__syncthreads();
}
}
The shared arrays start and warpCounts (START and WARP_COUNTS in Rust) are the arrays
\(\mathsf{start}\) and \(wc\) of the pseudocode, and the 4 calls to the barrier are lines 3, 7, 9 and
11. The rank is popc(peers & below), where below has 1 bits for the lanes below this one. A
lane past the end of the array gets the digit 16, matches only with other such lanes, and writes
nothing, but it still reaches every barrier. The Rust write uses get_unchecked_mut, and its
safety comment is Theorem 22.3.
The last listing runs the 8 passes on the host. Each pass launches the two kernels and the scan of the table between them.
Listing 22.6 8 passes of 4 bits on the host.
/// 1 pass on the 4-bit digit at `shift`, from `keys` into `buffers.spare`.
fn digit_pass(
module: &Module,
stream: &Arc<CudaStream>,
keys: &DeviceBuffer<u32>,
shift: u32,
buffers: &mut SortBuffers,
) -> Result<(), Error> {
let tiles = LaunchConfig1D::new(keys.len().div_ceil(TILE) as u32, 256, 0);
let count = module.prepare_digit_counts(tiles)?;
module.digit_counts(stream, &count, keys, shift, &mut buffers.counts)?;
let levels = &mut buffers.count_levels;
scan(module, stream, &buffers.counts, &mut buffers.positions, levels)?;
let scatter = module.prepare_scatter_digits(tiles)?;
let (counts, positions) = (&buffers.counts, &buffers.positions);
let out = &mut buffers.spare;
module.scatter_digits(stream, &scatter, keys, shift, counts, positions, out)?;
Ok(())
}
/// 8 passes of 4 bits, digit 0 first. The result ends in `keys`.
fn sort_digits(
module: &Module,
stream: &Arc<CudaStream>,
keys: &mut DeviceBuffer<u32>,
buffers: &mut SortBuffers,
) -> Result<(), Error> {
for shift in (0..32).step_by(4) {
digit_pass(module, stream, keys, shift, buffers)?;
std::mem::swap(keys, &mut buffers.spare);
}
Ok(())
}// 8 passes of 4 bits: digit histograms per tile, 1 scan of the table, a stable scatter.
void sortDigits(unsigned*& keys, Buffers& buffers, int n)
{
int tiles = (n + TILE - 1) / TILE;
unsigned* counts = buffers.flags;
unsigned* scanned = buffers.scanned;
for (int shift = 0; shift < 32; shift += 4) {
digitCounts<<<tiles, 256>>>(keys, shift, counts, n);
scan(counts, scanned, RADIX * tiles, buffers.scratch);
scatterDigits<<<tiles, 256>>>(keys, shift, counts, scanned, buffers.spare, n);
std::swap(keys, buffers.spare);
}
}
The 3 launches of a pass run on 1 stream, so the scatter reads a complete scan. Each pass writes
the keys into a second buffer, and the host then exchanges the 2 buffers, with std::mem::swap of
the 2 DeviceBuffer values in Rust and with std::swap of the 2 pointers in C++, without moving
any data on the GPU. After 8 passes, which is an even number, the sorted keys are back in the first
buffer.
Exercises
22.17 Change digit_counts and scatter_digits for digits of 8 bits. Which shared arrays grow,
and how large is the table for 16,777,216 keys?
22.18 Why does hist_aggregated compare lane with leader instead of testing rank == 0 as
scatter_digits does? Are the 2 tests equivalent?
22.10 Measurements
22.10.1 Platform and method
The measurements come from a Jetson Orin NX 16 GB, an integrated GPU with 8 SMs (sm_87) and 102 GB/s of memory bandwidth. The histograms count the low 4 bits of 16,777,216 keys of 4 bytes, 64 MiB in all, with 1,024 blocks of 256 threads, both on random keys and on keys that are all 7. Each histogram time is the average of 20 runs after 0.4 s of warm-up. The sorts take 16,777,216 random keys of 32 bits, and each sort time is the best of 3 runs after 1 run of warm-up. Every histogram is compared bin by bin, and every sort key by key, with the result computed on the CPU. Between runs, times varied by up to 10%.
The C++ program printed the following output.
$ ./radix_sort_histogram
radix sort of 5 2 7 2 0 6 3 5
split bit 0 2 2 0 6 5 7 3 5
split bit 1 0 5 5 2 2 6 7 3
split bit 2 0 2 2 3 5 5 6 7
histogram 1 0 2 1 0 2 1 1
digit starts 0 1 1 3 4 4 6 7
4-bit pass 0 2 2 3 5 5 6 7
histograms of the low 4 bits of 16777216 keys, average of 20 runs
keys global ms GB/s shared ms GB/s warp-aggregated ms GB/s
random 3.23 20.8 1.02 66.1 1.91 35.1
all 7 15.15 4.4 1.01 66.2 1.31 51.2
radix sorts of 16777216 random 32-bit keys, best of 3 runs
32 passes of 1 bit 262.26 ms 64.0 Mkeys/s
8 passes of 4 bits 40.13 ms 418.1 Mkeys/s
1 pass of 4 bits: counts 1.15 ms, scan 0.04 ms, scatter 3.83 ms
PASSED
The first 4 lines repeat Figure 22.2, and the histogram line is the histogram of Definition 22.3. Because the keys have only 3 bits, 1 pass on the digit of 4 bits at shift 0 sorts them. The digit starts \((0, 1, 1, 3, 4, 4, 6, 7)\) are the exclusive scan of the histogram, and the pass is a counting sort of the whole keys. The Rust program printed the same small example and times within 5% of these: 3.24, 1.00 and 2.00 ms for the random keys, 15.24, 1.01 and 1.28 ms for the keys that are all 7, and 255.32 ms and 39.89 ms for the 2 sorts.
22.10.2 Contention, measured
Figure 22.10 draws the histogram times. With global bins, the keys that are all 7 took 15.15 ms, and the random keys took 3.23 ms, 4.7 times less. In Section 5.5.2, we measured a factor of 4 for bytes in 256 global bins. With all keys equal, every one of the 16,777,216 atomic additions went to 1 address, and the L2 cache performed them one after the other, at a rate of \(16{,}777{,}216 / 15.15\ \text{ms} = 1.11\) billion per second. Spreading them over 16 addresses raised the rate only to 5.19 billion per second.
With private bins, the 2 inputs took the same time, 1.02 and 1.01 ms, and both read the keys at 66 GB/s, 65% of the memory bandwidth. The 1,024 blocks merged 16,384 counts into global memory instead of 16,777,216, and the contention in shared memory, where every key of the second input also went to 1 bin, no longer set the time. In Section 8.8, we found the same for bytes: once the bins were private, the speed of the histogram was set by its loads.
Warp aggregation made the histogram slower, 1.91 ms against 1.02 ms on random keys, and 1.31 ms against 1.01 ms on equal keys. Every key paid for the match instruction, and the atomic operations that it saved were not the limit. On random keys, it saved few of them in any case. The 32 random digits of a warp, drawn from 16 values, take on average \(16 (1 - (15/16)^{32}) = 14.0\) distinct values, because each of the 16 digits is missing from the warp with probability \((15/16)^{32}\). A warp therefore still made about 14 atomic additions instead of 32. Aggregation pays when many lanes of a warp update the same location in global memory, and private bins had already removed that case.
22.10.3 Why the 4-bit sort is 6.5 times faster, not 13
The 32 passes of 1 bit took 262.26 ms. By Section 22.5, they move 1,280 bytes per key, 21.5 GB for 16,777,216 keys, so they used the memory at 81.9 GB/s, 80% of its bandwidth. The sort by single bits is therefore limited by its traffic. The 8 passes of 4 bits move 96 bytes per key, 13.3 times less, but they took 40.13 ms, only 6.5 times less (Figure 22.11), and so they used the memory at only 40.1 GB/s.
The last line of the output locates the difference. In 1 pass, counting the digits took 1.15 ms, reading 67.1 MB at 58.4 GB/s, and the scan of the table of 262,144 counts took 0.04 ms. The scatter took 3.83 ms, reading and writing 134.2 MB at only 35.0 GB/s, so the scatter is the slow part. In a step, the 32 keys of a warp go to about 14 different places, 1 per distinct digit, as computed above. A store instruction of the warp then becomes about 14 separate writes of a few bytes each, whereas the copy of 32 consecutive keys is 4 writes of 32 bytes, and the memory system handles each of those writes as a separate request. The scatter also waits at 16 barriers per tile. The splits of the 1-bit sort scatter too, but every warp writes to at most 2 places, and their writes are nearly as regular as a copy.
The library sort that we measured in Chapter 11, cub::DeviceRadixSort, sorted 16,777,216 keys in
8.96 ms on the same GPU, 4.5 times faster than our 4-bit sort. It uses digits of 8 bits, and
therefore 4 passes instead of 8 (Section 11.2.4). It ranks and reorders the keys of each tile in
shared memory, so that the writes of a warp go to few places, and it computes the digit starts with
a single-pass scan (Adinets and Merrill, 2022). Exercise 5 at the end of the chapter takes the
first of those steps.
22.11 The complete programs
The following listing contains the complete programs of this chapter, in Rust and in CUDA C++. Each program runs the small example, measures the 3 histograms and the 2 sorts on 16,777,216 keys, checks every result against the CPU, and prints the times.
Listing 22.7 The complete programs. code/oxide/ch22_radix_sort_histogram/src/main.rs and code/cuda/ch22_radix_sort_histogram/radix_sort_histogram.cu
//! Chapter 22: histograms of 4-bit digits with atomics, a radix sort by 1-bit splits,
//! and a radix sort by 4-bit digits whose offsets come from a histogram and a scan.
//!
//! cargo oxide run
use std::sync::Arc;
use std::time::{Duration, Instant};
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, LaunchConfig1D};
use cuda_device::atomic::{AtomicOrdering, BlockAtomicU32, DeviceAtomicU32};
use cuda_device::{DisjointSlice, SharedArray, cuda_module, device, kernel, launch_contract};
use cuda_device::{thread, warp};
const TILE: usize = 1024; // keys per block in the scan and the sort
const N: usize = 16 << 20; // keys in the measured runs
const RADIX: usize = 16; // digit values of a 4-bit pass
const GRID: u32 = 1024; // blocks of the histogram kernels
type Error = Box<dyn std::error::Error>;
type Levels = Vec<(DeviceBuffer<u32>, DeviceBuffer<u32>)>;
type Bins = DeviceBuffer<DeviceAtomicU32>;
type Module = kernels::LoadedModule;
#[cuda_module]
mod kernels {
use super::*;
#[device]
fn digit_of(key: u32, shift: u32) -> usize {
((key >> shift) as usize) & (RADIX - 1)
}
/// Bin `d` of a block's private bins in shared memory, viewed as an atomic.
///
/// # Safety
/// `local` must point to the block's bins and `d` must be below RADIX.
#[device]
unsafe fn shared_bin<'a>(local: *mut u32, d: usize) -> &'a BlockAtomicU32 {
unsafe { BlockAtomicU32::from_ptr(local.add(d)) }
}
/// 1. Every count is an atomic addition on 1 of 16 bins in global memory.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn hist_global(keys: &[u32], shift: u32, bins: &[DeviceAtomicU32]) {
let stride = (thread::gridDim_x() * 256) as usize;
let mut index = thread::index_1d().get();
while index < keys.len() {
bins[digit_of(keys[index], shift)].fetch_add(1, AtomicOrdering::Relaxed);
index += stride;
}
}
/// 2. Each block counts into private bins in shared memory and merges them once.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn hist_shared(keys: &[u32], shift: u32, bins: &[DeviceAtomicU32]) {
static mut LOCAL: SharedArray<u32, RADIX> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
if tid < RADIX {
// SAFETY: threads 0 to 15 each zero their own bin, before the barrier.
unsafe { LOCAL[tid] = 0 };
}
thread::sync_threads();
// SAFETY: between the 2 barriers every access to LOCAL is atomic.
let local = unsafe { (*&raw mut LOCAL).as_mut_ptr() };
let stride = (thread::gridDim_x() * 256) as usize;
let mut index = thread::index_1d().get();
while index < keys.len() {
let digit = digit_of(keys[index], shift);
// SAFETY: d < RADIX, and LOCAL holds RADIX bins.
unsafe { shared_bin(local, digit) }.fetch_add(1, AtomicOrdering::Relaxed);
index += stride;
}
thread::sync_threads();
if tid < RADIX {
// SAFETY: after the barrier no thread writes LOCAL again.
let count = unsafe { LOCAL[tid] };
bins[tid].fetch_add(count, AtomicOrdering::Relaxed);
}
}
/// 3. As 2, but the lanes of a warp with equal digits add their count with 1 atomic.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn hist_aggregated(keys: &[u32], shift: u32, bins: &[DeviceAtomicU32]) {
static mut LOCAL: SharedArray<u32, RADIX> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
if tid < RADIX {
// SAFETY: threads 0 to 15 each zero their own bin, before the barrier.
unsafe { LOCAL[tid] = 0 };
}
thread::sync_threads();
// SAFETY: between the 2 barriers every access to LOCAL is atomic.
let local = unsafe { (*&raw mut LOCAL).as_mut_ptr() };
let lane = warp::lane_id();
let stride = (thread::gridDim_x() * 256) as usize;
let mut base = thread::blockIdx_x() as usize * 256;
while base < keys.len() {
let index = base + tid;
let inside = index < keys.len();
let digit = if inside { digit_of(keys[index], shift) } else { RADIX };
let peers = warp::match_any_sync(u32::MAX, digit as u32);
let leader = peers.trailing_zeros();
if lane == leader && digit < RADIX {
// SAFETY: d < RADIX, and LOCAL holds RADIX bins.
let bin = unsafe { shared_bin(local, digit) };
bin.fetch_add(peers.count_ones(), AtomicOrdering::Relaxed);
}
base += stride;
}
thread::sync_threads();
if tid < RADIX {
// SAFETY: after the barrier no thread writes LOCAL again.
let count = unsafe { LOCAL[tid] };
bins[tid].fetch_add(count, AtomicOrdering::Relaxed);
}
}
/// The inclusive scan of 1 value per lane across a warp.
#[device]
fn warp_scan(mut value: u32) -> u32 {
let lane = warp::lane_id();
let mut step = 0u32;
#[unroll]
while step < 5 {
let offset = 1 << step; // 1, 2, 4, 8, 16
let left = warp::shuffle_up_sync(u32::MAX, value, offset);
if lane >= offset {
value += left;
}
step += 1;
}
value
}
/// The scan of Chapter 21: 256 threads, 4 elements each, warp shuffles and 2 barriers.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scan_warps(
x: &[u32],
mut y: DisjointSlice<u32>,
mut sums: DisjointSlice<u32>,
) {
static mut WARPS: SharedArray<u32, 8> = SharedArray::UNINIT;
let first = thread::index_1d().get() * 4;
let lane = warp::lane_id() as usize;
let warp = thread::threadIdx_x() as usize / 32;
let mut prefix = [0u32; 4];
let mut own = 0;
let mut element = 0;
#[unroll]
while element < 4 {
if first + element < x.len() {
own += x[first + element];
}
prefix[element] = own;
element += 1;
}
let warp_prefix = warp_scan(own);
if lane == 31 {
// SAFETY: lane 31 of each warp writes its own slot, before the barrier.
unsafe { WARPS[warp] = warp_prefix };
}
thread::sync_threads();
if warp == 0 {
// SAFETY: only warp 0 touches the slots between the 2 barriers.
let warp_total = if lane < 8 { unsafe { WARPS[lane] } } else { 0 };
let scanned_total = warp_scan(warp_total);
if lane < 8 {
unsafe { WARPS[lane] = scanned_total };
}
}
thread::sync_threads();
// SAFETY: after the second barrier the slots are only read.
let earlier_warps = if warp > 0 { unsafe { WARPS[warp - 1] } } else { 0 };
let before = warp_prefix - own + earlier_warps;
let mut element = 0;
#[unroll]
while element < 4 {
if first + element < y.len() {
// SAFETY: thread t alone writes elements 4t to 4t + 3.
unsafe { *y.get_unchecked_mut(first + element) = before + prefix[element] };
}
element += 1;
}
if thread::threadIdx_x() == 255 {
let block = thread::blockIdx_x() as usize;
// SAFETY: only the last thread of each block writes, at its own block number.
unsafe { *sums.get_unchecked_mut(block) = before + prefix[3] };
}
}
/// Adds to every element of tile b the total of tiles 0 to b - 1.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn add_offsets(mut y: DisjointSlice<u32>, scanned: &[u32]) {
let block = thread::blockIdx_x() as usize;
let tid = thread::threadIdx_x() as usize;
if block > 0 {
let offset = scanned[block - 1];
let mut step = 0;
#[unroll]
while step < 4 {
let index = block * TILE + step * 256 + tid;
if index < y.len() {
// SAFETY: element g is this thread's alone and lies below y.len().
unsafe { *y.get_unchecked_mut(index) += offset };
}
step += 1;
}
}
}
/// The split on 1 bit: flags[i] = 1 if the bit of keys[i] is 0.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn zero_flags(keys: &[u32], bit: u32, mut flags: DisjointSlice<u32>) {
let idx = thread::index_1d();
let index = idx.get();
if let Some(flag) = flags.get_mut(idx) {
*flag = 1 - ((keys[index] >> bit) & 1);
}
}
/// Zero-bit keys go to their exclusive scan, one-bit keys after all zero-bit keys.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn split_scatter(
keys: &[u32],
flags: &[u32],
scanned: &[u32],
mut out: DisjointSlice<u32>,
) {
let index = thread::index_1d().get();
if index < keys.len() {
let zeros = scanned[keys.len() - 1] as usize;
let upto = scanned[index] as usize; // zero-bit keys among 0 to i
let at = if flags[index] == 1 { upto - 1 } else { zeros + index - upto };
// SAFETY: zero-bit keys receive 0 to zeros - 1 and one-bit keys zeros to
// n - 1, each position once: a permutation of 0 to n - 1.
unsafe { *out.get_unchecked_mut(at) = keys[index] };
}
}
/// The 4-bit pass, step 1: the digit histogram of every tile, stored digit by digit:
/// counts[digit * tiles + tile] is the number of keys with that digit in that tile.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn digit_counts(keys: &[u32], shift: u32, mut counts: DisjointSlice<u32>) {
static mut LOCAL: SharedArray<u32, RADIX> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
let block = thread::blockIdx_x() as usize;
if tid < RADIX {
// SAFETY: threads 0 to 15 each zero their own bin, before the barrier.
unsafe { LOCAL[tid] = 0 };
}
thread::sync_threads();
// SAFETY: between the 2 barriers every access to LOCAL is atomic.
let local = unsafe { (*&raw mut LOCAL).as_mut_ptr() };
let mut step = 0;
#[unroll]
while step < 4 {
let index = block * TILE + step * 256 + tid;
if index < keys.len() {
let digit = digit_of(keys[index], shift);
// SAFETY: d < RADIX, and LOCAL holds RADIX bins.
unsafe { shared_bin(local, digit) }.fetch_add(1, AtomicOrdering::Relaxed);
}
step += 1;
}
thread::sync_threads();
if tid < RADIX {
let tiles = thread::gridDim_x() as usize;
// SAFETY: thread d of block b alone writes entry d * tiles + b, and the
// table holds RADIX * tiles entries.
unsafe { *counts.get_unchecked_mut(tid * tiles + block) = LOCAL[tid] };
}
}
/// The 4-bit pass, step 3: every key goes to the start of its digit in its tile, plus
/// the keys with the same digit before it in the tile. 4 steps of 256 keys, in order.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scatter_digits(
keys: &[u32],
shift: u32,
counts: &[u32],
scanned: &[u32],
mut out: DisjointSlice<u32>,
) {
static mut START: SharedArray<u32, RADIX> = SharedArray::UNINIT;
// The count of digit d in warp w, at slot w * RADIX + d.
static mut WARP_COUNTS: SharedArray<u32, 128> = SharedArray::UNINIT;
let thread_idx = thread::threadIdx_x() as usize;
let block = thread::blockIdx_x() as usize;
let lane = warp::lane_id();
let warp = thread_idx / 32;
let below = (1u32 << lane) - 1;
if thread_idx < RADIX {
let entry = thread_idx * thread::gridDim_x() as usize + block;
// SAFETY: thread t alone writes START[t], before the first barrier.
unsafe { START[thread_idx] = scanned[entry] - counts[entry] };
}
let mut step = 0;
#[unroll]
while step < 4 {
if thread_idx < 8 * RADIX {
// SAFETY: thread t alone writes slot t, between 2 barriers.
unsafe { WARP_COUNTS[thread_idx] = 0 };
}
thread::sync_threads();
let index = block * TILE + step * 256 + thread_idx;
let key = if index < keys.len() { keys[index] } else { 0 };
let digit = if index < keys.len() { digit_of(key, shift) } else { RADIX };
let peers = warp::match_any_sync(u32::MAX, digit as u32);
let rank = (peers & below).count_ones();
if rank == 0 && digit < RADIX {
// SAFETY: 1 lane per digit and warp writes slot warp * 16 + d.
unsafe { WARP_COUNTS[warp * RADIX + digit] = peers.count_ones() };
}
thread::sync_threads();
if digit < RADIX {
let mut before = 0;
let mut other = 0;
while other < warp {
// SAFETY: between the 2 barriers the slots are only read.
before += unsafe { WARP_COUNTS[other * RADIX + digit] };
other += 1;
}
// SAFETY: START is only read between these barriers.
let at = (unsafe { START[digit] } + before + rank) as usize;
// SAFETY: the keys of each digit receive distinct consecutive positions
// after the keys of the smaller digits and of the earlier tiles: the
// positions of all keys form a permutation of 0 to n - 1.
unsafe { *out.get_unchecked_mut(at) = key };
}
thread::sync_threads();
if thread_idx < RADIX {
let mut other = 0;
#[unroll]
while other < 8 {
// SAFETY: thread t alone updates START[t]; the slots are only read.
unsafe { START[thread_idx] += WARP_COUNTS[other * RADIX + thread_idx] };
other += 1;
}
}
thread::sync_threads();
step += 1;
}
}
}
/// Runs `launch` for 0.4 s so that the clocks rise, then averages 20 runs, in ms.
fn time_ms(
stream: &Arc<CudaStream>,
mut launch: impl FnMut() -> Result<(), Error>,
) -> Result<f64, Error> {
let warm = Instant::now();
while warm.elapsed() < Duration::from_millis(400) {
launch()?;
stream.synchronize()?;
}
let start = Instant::now();
for _ in 0..20 {
launch()?;
}
stream.synchronize()?;
Ok(start.elapsed().as_secs_f64() * 1e3 / 20.0)
}
/// Numbers from a small linear congruential generator.
fn random(n: usize, seed: u32) -> Vec<u32> {
let mut state = seed;
(0..n)
.map(|_| {
state = state.wrapping_mul(1_664_525).wrapping_add(1_013_904_223);
state
})
.collect()
}
/// Buffers for the tile totals and their scan, per level: n / 1,024, / 1,024 again, ... 1.
fn scan_levels(stream: &Arc<CudaStream>, mut n: usize) -> Result<Levels, Error> {
let mut levels = Vec::new();
while n > 1 {
n = n.div_ceil(TILE);
let totals = DeviceBuffer::<u32>::zeroed(stream, n)?;
let scanned = DeviceBuffer::<u32>::zeroed(stream, n)?;
levels.push((totals, scanned));
}
Ok(levels)
}
/// Inclusive scan: the tiles, then the tile totals (by the same function), then offsets.
fn scan(
module: &Module,
stream: &Arc<CudaStream>,
x: &DeviceBuffer<u32>,
y: &mut DeviceBuffer<u32>,
levels: &mut [(DeviceBuffer<u32>, DeviceBuffer<u32>)],
) -> Result<(), Error> {
let tiles = x.len().div_ceil(TILE) as u32;
let config = LaunchConfig1D::new(tiles, 256, 0);
let ((totals, scanned), rest) = levels.split_first_mut().ok_or("no level left")?;
module.scan_warps(stream, &module.prepare_scan_warps(config)?, x, y, totals)?;
if tiles > 1 {
scan(module, stream, totals, scanned, rest)?;
module.add_offsets(stream, &module.prepare_add_offsets(config)?, y, scanned)?;
}
Ok(())
}
/// The buffers that a radix sort of n keys needs besides the keys themselves.
struct SortBuffers {
spare: DeviceBuffer<u32>, // the other half of each pass
flags: DeviceBuffer<u32>, // 1 per key
scanned: DeviceBuffer<u32>, // 1 per key
levels: Levels, // the scan of the flags
counts: DeviceBuffer<u32>, // RADIX per tile
positions: DeviceBuffer<u32>, // the scan of the counts
count_levels: Levels,
}
impl SortBuffers {
fn new(stream: &Arc<CudaStream>, n: usize) -> Result<Self, Error> {
let table = RADIX * n.div_ceil(TILE);
Ok(SortBuffers {
spare: DeviceBuffer::<u32>::zeroed(stream, n)?,
flags: DeviceBuffer::<u32>::zeroed(stream, n)?,
scanned: DeviceBuffer::<u32>::zeroed(stream, n)?,
levels: scan_levels(stream, n)?,
counts: DeviceBuffer::<u32>::zeroed(stream, table)?,
positions: DeviceBuffer::<u32>::zeroed(stream, table)?,
count_levels: scan_levels(stream, table)?,
})
}
}
/// 1 stable split on `bit`, from `keys` into `buffers.spare`.
fn split(
module: &Module,
stream: &Arc<CudaStream>,
keys: &DeviceBuffer<u32>,
bit: u32,
buffers: &mut SortBuffers,
) -> Result<(), Error> {
let every = LaunchConfig1D::new(keys.len().div_ceil(256) as u32, 256, 0);
let flag = module.prepare_zero_flags(every)?;
module.zero_flags(stream, &flag, keys, bit, &mut buffers.flags)?;
scan(module, stream, &buffers.flags, &mut buffers.scanned, &mut buffers.levels)?;
let scatter = module.prepare_split_scatter(every)?;
let (flags, scanned, out) = (&buffers.flags, &buffers.scanned, &mut buffers.spare);
module.split_scatter(stream, &scatter, keys, flags, scanned, out)?;
Ok(())
}
/// 1 pass on the 4-bit digit at `shift`, from `keys` into `buffers.spare`.
fn digit_pass(
module: &Module,
stream: &Arc<CudaStream>,
keys: &DeviceBuffer<u32>,
shift: u32,
buffers: &mut SortBuffers,
) -> Result<(), Error> {
let tiles = LaunchConfig1D::new(keys.len().div_ceil(TILE) as u32, 256, 0);
let count = module.prepare_digit_counts(tiles)?;
module.digit_counts(stream, &count, keys, shift, &mut buffers.counts)?;
let levels = &mut buffers.count_levels;
scan(module, stream, &buffers.counts, &mut buffers.positions, levels)?;
let scatter = module.prepare_scatter_digits(tiles)?;
let (counts, positions) = (&buffers.counts, &buffers.positions);
let out = &mut buffers.spare;
module.scatter_digits(stream, &scatter, keys, shift, counts, positions, out)?;
Ok(())
}
/// 32 stable splits of 1 bit, bit 0 first. The result ends in `keys`.
fn sort_bits(
module: &Module,
stream: &Arc<CudaStream>,
keys: &mut DeviceBuffer<u32>,
buffers: &mut SortBuffers,
) -> Result<(), Error> {
for bit in 0..32 {
split(module, stream, keys, bit, buffers)?;
std::mem::swap(keys, &mut buffers.spare);
}
Ok(())
}
/// 8 passes of 4 bits, digit 0 first. The result ends in `keys`.
fn sort_digits(
module: &Module,
stream: &Arc<CudaStream>,
keys: &mut DeviceBuffer<u32>,
buffers: &mut SortBuffers,
) -> Result<(), Error> {
for shift in (0..32).step_by(4) {
digit_pass(module, stream, keys, shift, buffers)?;
std::mem::swap(keys, &mut buffers.spare);
}
Ok(())
}
fn print(name: &str, values: &[u32]) {
let cells: Vec<String> = values.iter().map(|v| v.to_string()).collect();
println!(" {name:13} {}", cells.join(" "));
}
/// The worked example: 8 keys of 3 bits, 3 splits, then 1 pass on a 4-bit digit.
fn small_example(module: &Module, stream: &Arc<CudaStream>) -> Result<bool, Error> {
let host = [5u32, 2, 7, 2, 0, 6, 3, 5];
let sorted = [0u32, 2, 2, 3, 5, 5, 6, 7];
let mut buffers = SortBuffers::new(stream, 8)?;
let mut keys = DeviceBuffer::from_host(stream, &host)?;
println!("radix sort of 5 2 7 2 0 6 3 5");
for bit in 0..3 {
split(module, stream, &keys, bit, &mut buffers)?;
std::mem::swap(&mut keys, &mut buffers.spare);
print(&format!("split bit {bit}"), &keys.to_host_vec(stream)?);
}
let by_splits = keys.to_host_vec(stream)?;
let keys = DeviceBuffer::from_host(stream, &host)?;
let bins = DeviceBuffer::<u32>::zeroed(stream, RADIX)?.cast_elem::<DeviceAtomicU32>();
let one = module.prepare_hist_shared(LaunchConfig1D::new(1, 256, 0))?;
module.hist_shared(stream, &one, &keys, 0, &bins)?;
let hist = bins.cast_elem::<u32>().to_host_vec(stream)?[..8].to_vec();
print("histogram", &hist);
digit_pass(module, stream, &keys, 0, &mut buffers)?;
let inclusive = buffers.positions.to_host_vec(stream)?;
let starts: Vec<u32> = (0..8).map(|d| inclusive[d] - hist[d]).collect();
print("digit starts", &starts);
let by_digits = buffers.spare.to_host_vec(stream)?;
print("4-bit pass", &by_digits);
Ok(by_splits == sorted && by_digits == sorted)
}
/// The 3 histograms of the low 4 bits of N keys, on random keys and on keys all equal.
fn histograms(module: &Module, stream: &Arc<CudaStream>) -> Result<bool, Error> {
let grid = LaunchConfig1D::new(GRID, 256, 0);
let global = module.prepare_hist_global(grid)?;
let shared = module.prepare_hist_shared(grid)?;
let aggregated = module.prepare_hist_aggregated(grid)?;
let gb = 4.0 * N as f64 / 1e9;
let mut ok = true;
println!("histograms of the low 4 bits of {N} keys, average of 20 runs");
print!(" keys global ms GB/s shared ms GB/s");
println!(" warp-aggregated ms GB/s");
for (name, host) in [("random", random(N, 7)), ("all 7", vec![7u32; N])] {
let keys = DeviceBuffer::from_host(stream, &host)?;
let mut expected = vec![0u32; RADIX];
for k in &host {
expected[(k & 15) as usize] += 1;
}
let run = |kernel: usize, bins: &Bins| -> Result<(), Error> {
match kernel {
0 => module.hist_global(stream, &global, &keys, 0, bins)?,
1 => module.hist_shared(stream, &shared, &keys, 0, bins)?,
_ => module.hist_aggregated(stream, &aggregated, &keys, 0, bins)?,
}
Ok(())
};
let mut ms = [0.0; 3];
for (kernel, time) in ms.iter_mut().enumerate() {
let scratch = DeviceBuffer::<u32>::zeroed(stream, RADIX)?.cast_elem();
*time = time_ms(stream, || run(kernel, &scratch))?;
let bins = DeviceBuffer::<u32>::zeroed(stream, RADIX)?.cast_elem();
run(kernel, &bins)?;
ok &= bins.cast_elem::<u32>().to_host_vec(stream)? == expected;
}
let rate = |t: f64| gb / (t / 1e3);
let (a, b, c) = (ms[0], ms[1], ms[2]);
print!(" {name:10} {a:10.2} {:6.1} {b:11.2} {:6.1}", rate(a), rate(b));
println!(" {c:20.2} {:6.1}", rate(c));
}
Ok(ok)
}
/// Both radix sorts of N random keys, best of 3 runs each, checked against sort_unstable.
fn sorts(module: &Module, stream: &Arc<CudaStream>) -> Result<bool, Error> {
let host = random(N, 11);
let mut expected = host.clone();
expected.sort_unstable();
let mut buffers = SortBuffers::new(stream, N)?;
let mut ok = true;
let mut best = [f64::MAX; 2];
for (method, fastest) in best.iter_mut().enumerate() {
for run in 0..4 {
let mut keys = DeviceBuffer::from_host(stream, &host)?;
stream.synchronize()?;
let start = Instant::now();
if method == 0 {
sort_bits(module, stream, &mut keys, &mut buffers)?;
} else {
sort_digits(module, stream, &mut keys, &mut buffers)?;
}
stream.synchronize()?;
let ms = start.elapsed().as_secs_f64() * 1e3;
if run > 0 {
*fastest = fastest.min(ms); // run 0 warms up
}
ok &= keys.to_host_vec(stream)? == expected;
}
}
let rate = |ms: f64| N as f64 / 1e6 / (ms / 1e3);
println!("radix sorts of {N} random 32-bit keys, best of 3 runs");
println!(" 32 passes of 1 bit {:8.2} ms {:7.1} Mkeys/s", best[0], rate(best[0]));
println!(" 8 passes of 4 bits {:8.2} ms {:7.1} Mkeys/s", best[1], rate(best[1]));
// The 3 parts of 1 pass of 4 bits on the random keys, averaged like the histograms.
let keys = DeviceBuffer::from_host(stream, &host)?;
let tiles = LaunchConfig1D::new(N.div_ceil(TILE) as u32, 256, 0);
let count = module.prepare_digit_counts(tiles)?;
let scatter = module.prepare_scatter_digits(tiles)?;
let count_ms = time_ms(stream, || {
Ok(module.digit_counts(stream, &count, &keys, 0, &mut buffers.counts)?)
})?;
let scan_ms = time_ms(stream, || {
let levels = &mut buffers.count_levels;
scan(module, stream, &buffers.counts, &mut buffers.positions, levels)
})?;
let (counts, positions) = (&buffers.counts, &buffers.positions);
let out = &mut buffers.spare;
let scatter_ms = time_ms(stream, || {
Ok(module.scatter_digits(stream, &scatter, &keys, 0, counts, positions, out)?)
})?;
print!(" 1 pass of 4 bits: counts {count_ms:.2} ms, scan {scan_ms:.2} ms,");
println!(" scatter {scatter_ms:.2} ms");
Ok(ok)
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let mut passed = small_example(&module, &stream)?;
passed &= histograms(&module, &stream)?;
passed &= sorts(&module, &stream)?;
println!("{}", if passed { "PASSED" } else { "FAILED" });
Ok(())
}// Chapter 22: histograms of 4-bit digits with atomics, a radix sort by 1-bit splits,
// and a radix sort by 4-bit digits whose offsets come from a histogram and a scan.
// Build: nvcc -O3 -arch=native radix_sort_histogram.cu -o radix_sort_histogram
#include <algorithm>
#include <chrono>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cuda_runtime.h>
const int TILE = 1024; // keys per block in the scan and the sort
const int N = 16 << 20; // keys in the measured runs
const int RADIX = 16; // digit values of a 4-bit pass
const int GRID = 1024; // blocks of the histogram kernels
const unsigned FULL = 0xffffffff;
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// Runs `launch` for 0.4 s so that the clocks rise, then averages 20 runs, in ms.
template <typename F>
double timeMs(F launch)
{
double warm = nowMs();
while (nowMs() - warm < 400) {
launch();
check(cudaDeviceSynchronize());
}
double t0 = nowMs();
for (int r = 0; r < 20; ++r) {
launch();
}
check(cudaGetLastError());
check(cudaDeviceSynchronize());
return (nowMs() - t0) / 20;
}
__device__ unsigned digitOf(unsigned key, int shift)
{
return (key >> shift) & (RADIX - 1);
}
// 1. Every count is an atomic addition on 1 of 16 bins in global memory.
__global__ void histGlobal(const unsigned* keys, int shift, unsigned* bins, int n)
{
int stride = gridDim.x * blockDim.x;
for (int index = blockIdx.x * blockDim.x + threadIdx.x; index < n; index += stride) {
atomicAdd(&bins[digitOf(keys[index], shift)], 1u);
}
}
// 2. Each block counts into private bins in shared memory and merges them once.
__global__ void histShared(const unsigned* keys, int shift, unsigned* bins, int n)
{
__shared__ unsigned local[RADIX];
if (threadIdx.x < RADIX) {
local[threadIdx.x] = 0;
}
__syncthreads();
int stride = gridDim.x * blockDim.x;
for (int index = blockIdx.x * blockDim.x + threadIdx.x; index < n; index += stride) {
atomicAdd(&local[digitOf(keys[index], shift)], 1u);
}
__syncthreads();
if (threadIdx.x < RADIX) {
atomicAdd(&bins[threadIdx.x], local[threadIdx.x]);
}
}
// 3. As 2, but the lanes of a warp with equal digits add their count with 1 atomic.
__global__ void histAggregated(const unsigned* keys, int shift, unsigned* bins, int n)
{
__shared__ unsigned local[RADIX];
if (threadIdx.x < RADIX) {
local[threadIdx.x] = 0;
}
__syncthreads();
int lane = threadIdx.x % 32;
int stride = gridDim.x * blockDim.x;
for (int base = blockIdx.x * blockDim.x; base < n; base += stride) {
int index = base + threadIdx.x;
unsigned digit = index < n ? digitOf(keys[index], shift) : RADIX;
unsigned peers = __match_any_sync(FULL, digit);
int leader = __ffs(peers) - 1;
if (lane == leader && digit < RADIX) {
atomicAdd(&local[digit], __popc(peers));
}
}
__syncthreads();
if (threadIdx.x < RADIX) {
atomicAdd(&bins[threadIdx.x], local[threadIdx.x]);
}
}
// The scan of Chapter 21: 256 threads, 4 elements each, warp shuffles and 2 barriers.
__device__ unsigned warpScan(unsigned value)
{
int lane = threadIdx.x % 32;
for (int offset = 1; offset < 32; offset *= 2) {
unsigned left = __shfl_up_sync(FULL, value, offset);
if (lane >= offset) {
value += left;
}
}
return value;
}
__global__ void scanWarps(const unsigned* x, unsigned* y, unsigned* sums, int n)
{
__shared__ unsigned warps[8];
int first = blockIdx.x * TILE + 4 * threadIdx.x;
int lane = threadIdx.x % 32;
int warp = threadIdx.x / 32;
unsigned prefix[4];
unsigned own = 0;
for (int element = 0; element < 4; ++element) {
own += first + element < n ? x[first + element] : 0;
prefix[element] = own;
}
unsigned warpPrefix = warpScan(own);
if (lane == 31) {
warps[warp] = warpPrefix;
}
__syncthreads();
if (warp == 0) {
unsigned scannedTotal = warpScan(lane < 8 ? warps[lane] : 0);
if (lane < 8) {
warps[lane] = scannedTotal;
}
}
__syncthreads();
unsigned before = warpPrefix - own + (warp > 0 ? warps[warp - 1] : 0);
for (int element = 0; element < 4; ++element) {
if (first + element < n) {
y[first + element] = before + prefix[element];
}
}
if (threadIdx.x == 255) {
sums[blockIdx.x] = before + prefix[3];
}
}
__global__ void addOffsets(unsigned* y, const unsigned* scanned, int n)
{
if (blockIdx.x == 0) {
return;
}
unsigned offset = scanned[blockIdx.x - 1];
for (int step = 0; step < 4; ++step) {
int index = blockIdx.x * TILE + step * 256 + threadIdx.x;
if (index < n) {
y[index] += offset;
}
}
}
// Inclusive scan of n elements: the tiles, then the tile totals (in place), then offsets.
void scan(const unsigned* x, unsigned* y, int n, unsigned* scratch)
{
int tiles = (n + TILE - 1) / TILE;
scanWarps<<<tiles, 256>>>(x, y, scratch, n);
if (tiles > 1) {
scan(scratch, scratch, tiles, scratch + tiles);
addOffsets<<<tiles, 256>>>(y, scratch, n);
}
}
// The split on 1 bit: flags[index] = 1 if the bit of keys[index] is 0.
__global__ void zeroFlags(const unsigned* keys, int bit, unsigned* flags, int n)
{
int index = blockIdx.x * blockDim.x + threadIdx.x;
if (index < n) {
flags[index] = 1 - ((keys[index] >> bit) & 1);
}
}
// Zero-bit keys go to their exclusive scan, one-bit keys after all zero-bit keys.
__global__ void splitScatter(const unsigned* keys, const unsigned* flags,
const unsigned* scanned, unsigned* out, int n)
{
int index = blockIdx.x * blockDim.x + threadIdx.x;
if (index < n) {
unsigned zeros = scanned[n - 1];
unsigned upto = scanned[index]; // zero-bit keys among 0 to index
unsigned at = flags[index] == 1 ? upto - 1 : zeros + index - upto;
out[at] = keys[index];
}
}
// The 4-bit pass, step 1: the digit histogram of every tile, stored digit by digit:
// counts[digit * tiles + tile] is the number of keys with that digit in that tile.
__global__ void digitCounts(const unsigned* keys, int shift, unsigned* counts, int n)
{
__shared__ unsigned local[RADIX];
if (threadIdx.x < RADIX) {
local[threadIdx.x] = 0;
}
__syncthreads();
for (int step = 0; step < 4; ++step) {
int index = blockIdx.x * TILE + step * 256 + threadIdx.x;
if (index < n) {
atomicAdd(&local[digitOf(keys[index], shift)], 1u);
}
}
__syncthreads();
if (threadIdx.x < RADIX) {
counts[threadIdx.x * gridDim.x + blockIdx.x] = local[threadIdx.x];
}
}
// The 4-bit pass, step 3: every key goes to the start of its digit in its tile, plus
// the keys with the same digit before it in the tile. 4 steps of 256 keys, in order.
__global__ void scatterDigits(const unsigned* keys, int shift, const unsigned* counts,
const unsigned* scanned, unsigned* out, int n)
{
__shared__ unsigned start[RADIX];
__shared__ unsigned warpCounts[8 * RADIX]; // [warp][digit]
int lane = threadIdx.x % 32;
int warp = threadIdx.x / 32;
unsigned below = (1u << lane) - 1;
if (threadIdx.x < RADIX) {
int entry = threadIdx.x * gridDim.x + blockIdx.x;
start[threadIdx.x] = scanned[entry] - counts[entry]; // the exclusive scan
}
for (int step = 0; step < 4; ++step) {
if (threadIdx.x < 8 * RADIX) {
warpCounts[threadIdx.x] = 0;
}
__syncthreads();
int index = blockIdx.x * TILE + step * 256 + threadIdx.x;
unsigned key = index < n ? keys[index] : 0;
unsigned digit = index < n ? digitOf(key, shift) : RADIX;
unsigned peers = __match_any_sync(FULL, digit);
unsigned rank = __popc(peers & below);
if (rank == 0 && digit < RADIX) {
warpCounts[warp * RADIX + digit] = __popc(peers);
}
__syncthreads();
if (digit < RADIX) {
unsigned before = 0;
for (int other = 0; other < warp; ++other) {
before += warpCounts[other * RADIX + digit];
}
out[start[digit] + before + rank] = key;
}
__syncthreads();
if (threadIdx.x < RADIX) {
for (int other = 0; other < 8; ++other) {
start[threadIdx.x] += warpCounts[other * RADIX + threadIdx.x];
}
}
__syncthreads();
}
}
struct Buffers {
unsigned* spare; // the other half of each pass
unsigned* flags; // 1-bit sort: flags, or 4-bit: counts
unsigned* scanned;
unsigned* scratch; // the tile totals of the scan
};
// 32 stable splits of 1 bit, bit 0 first. After an even number of passes the sorted
// keys are back in `keys`.
void sortBits(unsigned*& keys, Buffers& buffers, int n)
{
int blocks = (n + 255) / 256;
unsigned* flags = buffers.flags;
unsigned* scanned = buffers.scanned;
for (int bit = 0; bit < 32; ++bit) {
zeroFlags<<<blocks, 256>>>(keys, bit, flags, n);
scan(flags, scanned, n, buffers.scratch);
splitScatter<<<blocks, 256>>>(keys, flags, scanned, buffers.spare, n);
std::swap(keys, buffers.spare);
}
}
// 8 passes of 4 bits: digit histograms per tile, 1 scan of the table, a stable scatter.
void sortDigits(unsigned*& keys, Buffers& buffers, int n)
{
int tiles = (n + TILE - 1) / TILE;
unsigned* counts = buffers.flags;
unsigned* scanned = buffers.scanned;
for (int shift = 0; shift < 32; shift += 4) {
digitCounts<<<tiles, 256>>>(keys, shift, counts, n);
scan(counts, scanned, RADIX * tiles, buffers.scratch);
scatterDigits<<<tiles, 256>>>(keys, shift, counts, scanned, buffers.spare, n);
std::swap(keys, buffers.spare);
}
}
std::vector<unsigned> toHost(const unsigned* device, int n)
{
std::vector<unsigned> host(n);
check(cudaMemcpy(host.data(), device, n * sizeof(unsigned), cudaMemcpyDeviceToHost));
return host;
}
void print(const char* name, const std::vector<unsigned>& v)
{
std::printf(" %-13s", name);
for (unsigned x : v) {
std::printf(" %u", x);
}
std::printf("\n");
}
// The worked example: 8 keys of 3 bits, 3 splits, then 1 pass on a 4-bit digit.
bool smallExample(Buffers& buffers)
{
std::vector<unsigned> host = {5, 2, 7, 2, 0, 6, 3, 5};
unsigned *keys, *other, *bins;
check(cudaMalloc(&keys, 8 * sizeof(unsigned)));
check(cudaMalloc(&other, 8 * sizeof(unsigned)));
check(cudaMalloc(&bins, RADIX * sizeof(unsigned)));
check(cudaMemcpy(keys, host.data(), 8 * sizeof(unsigned), cudaMemcpyHostToDevice));
std::printf("radix sort of 5 2 7 2 0 6 3 5\n");
unsigned* from = keys;
unsigned* to = other;
for (int bit = 0; bit < 3; ++bit) {
zeroFlags<<<1, 256>>>(from, bit, buffers.flags, 8);
scan(buffers.flags, buffers.scanned, 8, buffers.scratch);
splitScatter<<<1, 256>>>(from, buffers.flags, buffers.scanned, to, 8);
std::swap(from, to);
char name[16];
std::snprintf(name, sizeof(name), "split bit %d", bit);
print(name, toHost(from, 8));
}
std::vector<unsigned> bySplits = toHost(from, 8);
check(cudaMemcpy(keys, host.data(), 8 * sizeof(unsigned), cudaMemcpyHostToDevice));
check(cudaMemset(bins, 0, RADIX * sizeof(unsigned)));
histShared<<<1, 256>>>(keys, 0, bins, 8);
std::vector<unsigned> hist = toHost(bins, 8);
print("histogram", hist);
digitCounts<<<1, 256>>>(keys, 0, buffers.flags, 8);
scan(buffers.flags, buffers.scanned, RADIX, buffers.scratch);
scatterDigits<<<1, 256>>>(keys, 0, buffers.flags, buffers.scanned, other, 8);
std::vector<unsigned> inclusive = toHost(buffers.scanned, 8);
std::vector<unsigned> starts(8);
for (int digit = 0; digit < 8; ++digit) {
starts[digit] = inclusive[digit] - hist[digit];
}
print("digit starts", starts);
std::vector<unsigned> byDigits = toHost(other, 8);
print("4-bit pass", byDigits);
check(cudaFree(keys));
check(cudaFree(other));
check(cudaFree(bins));
std::vector<unsigned> sorted = {0, 2, 2, 3, 5, 5, 6, 7};
return bySplits == sorted && byDigits == sorted;
}
// The 3 histograms of the low 4 bits of N keys, on random keys and on keys all equal.
bool histograms(unsigned* keys)
{
unsigned* bins;
check(cudaMalloc(&bins, RADIX * sizeof(unsigned)));
double gb = 4.0 * N / 1e9;
bool ok = true;
std::printf("histograms of the low 4 bits of %d keys, average of 20 runs\n", N);
std::printf(" keys global ms GB/s shared ms GB/s");
std::printf(" warp-aggregated ms GB/s\n");
for (int input = 0; input < 2; ++input) {
std::vector<unsigned> host(N);
unsigned state = 7;
for (int i = 0; i < N; ++i) {
state = state * 1664525u + 1013904223u;
host[i] = input == 0 ? state : 7;
}
check(cudaMemcpy(keys, host.data(), N * sizeof(unsigned), cudaMemcpyHostToDevice));
std::vector<unsigned> expected(RADIX, 0);
for (unsigned k : host) {
expected[k & 15] += 1;
}
double ms[3];
for (int kernel = 0; kernel < 3; ++kernel) {
auto run = [&] {
if (kernel == 0) {
histGlobal<<<GRID, 256>>>(keys, 0, bins, N);
} else if (kernel == 1) {
histShared<<<GRID, 256>>>(keys, 0, bins, N);
} else {
histAggregated<<<GRID, 256>>>(keys, 0, bins, N);
}
};
ms[kernel] = timeMs(run);
check(cudaMemset(bins, 0, RADIX * sizeof(unsigned)));
run();
ok = ok && toHost(bins, RADIX) == expected;
}
std::printf(" %-10s %10.2f %6.1f %11.2f %6.1f %20.2f %6.1f\n",
input == 0 ? "random" : "all 7", ms[0], gb / (ms[0] / 1e3),
ms[1], gb / (ms[1] / 1e3), ms[2], gb / (ms[2] / 1e3));
}
check(cudaFree(bins));
return ok;
}
// Both radix sorts of N random keys, best of 3 runs each, checked against std::sort.
bool sorts(unsigned* keys, Buffers& buffers)
{
std::vector<unsigned> host(N);
unsigned state = 11;
for (int i = 0; i < N; ++i) {
state = state * 1664525u + 1013904223u;
host[i] = state;
}
std::vector<unsigned> expected = host;
std::sort(expected.begin(), expected.end());
bool ok = true;
double best[2] = {1e30, 1e30};
for (int method = 0; method < 2; ++method) {
for (int run = 0; run < 4; ++run) {
size_t bytes = N * sizeof(unsigned);
check(cudaMemcpy(keys, host.data(), bytes, cudaMemcpyHostToDevice));
double start = nowMs();
if (method == 0) {
sortBits(keys, buffers, N);
} else {
sortDigits(keys, buffers, N);
}
check(cudaDeviceSynchronize());
double ms = nowMs() - start;
if (run > 0) { // run 0 warms up
best[method] = std::min(best[method], ms);
}
ok = ok && toHost(keys, N) == expected;
}
}
std::printf("radix sorts of %d random 32-bit keys, best of 3 runs\n", N);
std::printf(" 32 passes of 1 bit %8.2f ms %7.1f Mkeys/s\n", best[0],
N / 1e6 / (best[0] / 1e3));
std::printf(" 8 passes of 4 bits %8.2f ms %7.1f Mkeys/s\n", best[1],
N / 1e6 / (best[1] / 1e3));
// The 3 parts of 1 pass of 4 bits on the random keys, averaged like the histograms.
check(cudaMemcpy(keys, host.data(), N * sizeof(unsigned), cudaMemcpyHostToDevice));
int tiles = (N + TILE - 1) / TILE;
unsigned* counts = buffers.flags;
unsigned* starts = buffers.scanned;
unsigned* spare = buffers.spare;
unsigned* scratch = buffers.scratch;
double countMs = timeMs([&] { digitCounts<<<tiles, 256>>>(keys, 0, counts, N); });
double scanMs = timeMs([&] { scan(counts, starts, RADIX * tiles, scratch); });
auto move = [&] { scatterDigits<<<tiles, 256>>>(keys, 0, counts, starts, spare, N); };
double scatterMs = timeMs(move);
std::printf(" 1 pass of 4 bits: counts %.2f ms, scan %.2f ms, scatter %.2f ms\n",
countMs, scanMs, scatterMs);
return ok;
}
int main()
{
unsigned* keys;
Buffers buffers;
check(cudaMalloc(&keys, N * sizeof(unsigned)));
check(cudaMalloc(&buffers.spare, N * sizeof(unsigned)));
check(cudaMalloc(&buffers.flags, N * sizeof(unsigned)));
check(cudaMalloc(&buffers.scanned, N * sizeof(unsigned)));
check(cudaMalloc(&buffers.scratch, N / 512 * sizeof(unsigned)));
bool ok = smallExample(buffers);
ok = histograms(keys) && ok;
ok = sorts(keys, buffers) && ok;
check(cudaFree(keys));
check(cudaFree(buffers.spare));
check(cudaFree(buffers.flags));
check(cudaFree(buffers.scanned));
check(cudaFree(buffers.scratch));
std::printf("%s\n", ok ? "PASSED" : "FAILED");
return ok ? 0 : 1;
}
Common mistakes
- An unstable pass. Positions handed out by an atomic counter group the keys by digit but lose their order, and the sort fails on large inputs while it may pass on small ones (Section 22.8). Place keys by start plus rank.
- The most significant digit first. A least-significant-digit sort by stable passes must start at bit 0. Starting at the top requires sorting each group separately.
- Counting into global bins. With few bins, every global atomic operation queues behind others for the same address. Count into private bins in shared memory and merge once per block.
- Merging before every thread has counted. Without the barrier before the merge, a thread can add its private bin to the global bin while other threads still count into it.
- A match or a ballot inside a branch. All lanes of the warp must execute it. Give the lanes past the end of the array a value that no key has, and call it unconditionally.
- The table of counts laid out tile by tile. Only the digit-major layout makes 1 scan give the start of every digit in every tile.
Summary
- A radix sort orders integer keys by their digits, least significant first. Theorem 22.1 shows that it is correct when every pass is stable.
- A split on 1 bit is 2 stream compactions that share 1 exclusive scan: keys with bit 0 go to \(e_i\), and keys with bit 1 go to \(Z + i - e_i\).
- A histogram counts keys by digit. Atomic additions make one thread per key correct, but contention makes them slow when many threads update 1 bin, and private bins in shared memory remove most of it.
- A pass on a digit of \(r\) bits places every key at the exclusive scan of the digit histogram plus its rank. Laying out the counts of the tiles digit by digit lets 1 scan serve every tile.
- Passes of 4 bits move 96 bytes per key for a 32-bit sort, against 1,280 for passes of 1 bit, and the measured sort ran 6.5 times as fast.
In Chapter 23, we turn to softmax and layer normalization, which combine reductions with arithmetic on every element.
Exercises
- Sort \((13, 2, 9, 2, 15, 0, 7, 13)\), keys of 4 bits, by 2 passes of 2 bits. Give the histogram, the starts and the ranks of each pass.
- Extend the radix sort to sort pairs (key, index), so that it returns the permutation that sorts the keys. Which kernels change?
- Signed integers in two’s complement do not sort correctly as unsigned keys. Which single bit must be flipped before the sort, and after it?
- Measure the histogram of 8-bit digits (256 bins) with the three kernels of Section 22.6, on random keys and on keys that are all equal, and compare with the 16-bin results.
- Replace the 3 passes of Section 22.7 (count, scan, scatter) by a version that keeps each tile’s keys sorted by digit in shared memory before writing them, so that the writes of a warp go to fewer places. Measure the effect.
- Estimate, from the byte count of Section 22.7.4, the time of a sort of 16,777,216 keys by 4 passes of 8 bits at the measured rate of the 4-bit sort.
Sources and further reading
- D. E. Knuth, The Art of Computer Programming, vol. 3, Sorting and Searching, 2nd ed., Addison-Wesley, 1998, Section 5.2.5: radix sorting.
- T. H. Cormen, C. E. Leiserson, R. L. Rivest and C. Stein, Introduction to Algorithms, 4th ed., MIT Press, 2022, Sections 8.2 and 8.3: counting sort and radix sort.
- G. E. Blelloch, “Prefix Sums and Their Applications”, Technical Report CMU-CS-90-190, Carnegie Mellon University, 1990: the split and radix sort from scans.
- N. Satish, M. Harris and M. Garland, “Designing Efficient Sorting Algorithms for Manycore GPUs”, IEEE IPDPS, 2009.
- D. Merrill and A. Grimshaw, “High Performance and Scalable Radix Sorting”, Parallel Processing Letters 21(2), 2011.
- A. Adinets and D. Merrill, “Onesweep: A Faster Least Significant Digit Radix Sort for GPUs”, arXiv:2206.01784, 2022.
- A. Pathak, “An Introduction to Tiled Parallel Programming, Simplified”, 2026.
- NVIDIA, CUDA C++ Programming Guide, “Atomic Functions” and “Warp Match Functions”.
Normalization
A normalization rescales the values of a row of a matrix by statistics of that row. This family contains 1 chapter, Chapter 23, which treats the 2 normalizations that every layer of a transformer model applies. The first is softmax, which divides the exponential of each value by the sum of the exponentials of its row. The second is layer normalization, which subtracts the mean of the row and divides by its standard deviation. Both operations appear many times per layer, on rows of a few hundred to more than 100,000 values, so their speed matters as much as their accuracy.
The 2 operations share 1 structure. In neither of them can an output be computed from its input alone, because every output needs a number that is computed from the whole row first: the maximum and the sum of exponentials in softmax, and the mean and the variance in layer normalization. Each operation is therefore a reduction over the row followed by an element-by-element computation. On a GPU, 1 block of threads handles 1 row. The threads of the block reduce their parts of the row, combine the partial results, and then write the outputs.
The idea that connects the algorithms of the family is a partial result that can be corrected. A sum of exponentials taken relative to 1 maximum can be moved to a larger maximum by 1 multiplication, and a sum of squared deviations from 1 mean can be moved to a new mean by 1 addition. With these corrections, a single pass over the row computes both of the statistics that the direct formulas compute in 2 passes. In the same way, 2 partial results computed by different threads merge into the result of their union. The online softmax and Welford’s method are the 2 algorithms built on this idea, and we prove both of them correct with a loop invariant.
In Chapter 23, we derive both operations on a matrix of 2 rows of 4 values. We show 2 numerical
failures of the direct formulas in f32, an overflow and a cancellation, together with their
remedies. We then develop the 1-pass algorithms, their merge rules, the block-wide reduction with
warp shuffles and barriers, and fused kernels that read each value only once. We build on
the reductions and warp shuffles of Chapter 8 and on the cuda-oxide kernels, shared memory and
launch contracts of Chapters 13 and 15. As in Chapter 7, we measure every kernel against the memory
bandwidth.
Chapter 23: Softmax and Layer Normalization
Every layer of a transformer model applies 2 operations to the rows of a matrix. The first, softmax, turns a row of scores into probabilities that are positive and add up to 1. The second, layer normalization, shifts and scales a row so that its values have mean 0 and variance 1. The 2 operations have one property in common, which shapes everything in this chapter. No output value can be computed from its own input alone. Every output depends on a statistic of its whole row, namely the largest value and the sum of exponentials for softmax, and the mean and the variance for layer normalization. Each operation is therefore a reduction over the row, which produces the statistic, followed by an element-by-element computation that uses the result of the reduction.
In this chapter, we derive both operations on a matrix of 2 rows of 4 values, which is small enough to check every number with a pencil. We first find 2 numerical failures of the direct formulas in single precision, an overflow in softmax and a cancellation in the variance, and we study the standard remedy for each. The remedies appear to require extra passes over the row, and we then show how to remove those passes. The online softmax finds the maximum and the sum in 1 pass, and Welford’s method finds the mean and the variance in 1 pass. Both rest on the same idea, a partial result that can be corrected when more of the row arrives, and both allow partial results computed by different threads to be combined. We prove each algorithm correct, map it onto 1 block of threads per row, implement it in Rust and in CUDA C++, and finally measure it against the memory bandwidth of the GPU.
This chapter covers
- softmax and layer normalization of the rows of a matrix, computed by hand
- overflow of the exponential in
f32, and why subtracting the row maximum leaves softmax unchanged - cancellation in the variance formula \(\overline{x^2} - \mu^2\), with a negative variance in
f32 - the online softmax and Welford’s method, each with a loop invariant and a proof
- merging 2 partial results, and the empty state
- One block per row: warp shuffles, block-wide reductions and their 2 barriers
- fused kernels that read each value once, and the bytes per element of every version
- measured times in Rust and C++, and the reasons for each gap to the memory bandwidth
The code of the chapter is in
code/oxide/ch23_softmax_layernorm/
for Rust and in
code/cuda/ch23_softmax_layernorm/
for C++. The Rust crate’s Cargo.toml and rust-toolchain.toml are those of Chapter 13 with a
different package name.
23.1 The problem
23.1.1 The worked example
We use the same matrix throughout the chapter. It has 2 rows of 4 values each:
\[ X = \begin{pmatrix} 1 & 2 & 3 & 4 \\ 2 & 4 & 4 & 5 \end{pmatrix}. \]
We write \(x_{rj}\) for the value in row \(r\) and column \(j\), counting both from 0, and \(n\) for the length of a row, which is 4 here. For example, \(x_{03} = 4\) is the last value of row 0, and \(x_{12} = 4\) is the third value of row 1. Both operations of the chapter work on 1 row at a time. Each reads a row of \(X\) and writes the row with the same number of its result, and it never looks at any other row. Figure 23.1 shows \(X\) together with the 2 results that we compute by hand in this section, the softmax \(P\) and the layer normalization \(Y\).
We will return several times to 2 entries of these results, \(p_{03} = 0.6439\) and \(y_{00} = -1.3416\). In Section 23.2, we will see that the direct formulas turn both of them into NaN for rows that differ from row 0 only by a constant added to every value.
The matrix is stored in row-major order, that is, row 0 first and then row 1, in a single array of \(2n = 8\) floats. The value \(x_{rj}\) therefore sits at position \(r \cdot n + j\) of the array, since the \(r\) rows before it occupy \(r \cdot n\) positions. For example, \(x_{12}\) sits at position \(1 \cdot 4 + 2 = 6\). A whole row is thus a contiguous piece of memory, and the GPU algorithm of Section 23.4 relies on this fact.
23.1.2 Softmax
A model often produces a row of scores, 1 score per possible answer, and needs to turn the row into probabilities. Probabilities must be positive and must add up to 1, while scores can be any real numbers, including negative ones. A simple way to obtain positive numbers is to apply the exponential function to every score, since \(e^x > 0\) for every real \(x\). A simple way to make positive numbers add up to 1 is to divide each of them by their total. Softmax performs exactly these 2 steps.
Definition 23.1 Softmax. The softmax of a row \(x_0, \dots, x_{n-1}\) is the row \(p_0, \dots, p_{n-1}\) with
\[ p_j = \frac{e^{x_j}}{\sum_{i \in [0, n)} e^{x_i}}, \qquad j \in [0, n). \]
The inputs \(x_j\) are often called logits, and the outputs are positive and add up to 1.
Example. For row 0 of \(X\), \(p_3 = e^4 / (e^1 + e^2 + e^3 + e^4) = 54.598 / 84.791 = 0.6439\).
| Symbol | Meaning | In the example (row 0, \(j = 3\)) |
|---|---|---|
| \(n\) | number of values in the row | 4 |
| \(x_j\) | input value in column \(j\) of the row | \(x_3 = 4\) |
| \(e^{x_j}\) | exponential of the input, the numerator | \(e^4 = 54.598\) |
| \(\sum_{i \in [0, n)} e^{x_i}\) | sum of the exponentials of the whole row, the denominator | 84.791 |
| \(p_j\) | output in column \(j\) | 0.6439 |
Note that the numerator depends only on \(x_j\), whereas the denominator is the same for every column and depends on the whole row. Every output is positive because an exponential is positive, and the outputs add up to 1 because they share 1 denominator, which is the sum of all the numerators. Softmax therefore turns any row of real numbers into a probability distribution. It also preserves order: a larger input receives a larger output. More precisely, an input larger by 1 receives an output larger by a factor of \(e = 2.718\), since \(e^{x + 1} = e \cdot e^x\).
Figure 23.2 computes row 0 by hand. The 4 exponentials are 2.718, 7.389, 20.086 and 54.598, and their sum is 84.791. Dividing each of them by the sum gives 0.0321, 0.0871, 0.2369 and 0.6439. The value 4 receives 64% of the total, although it is only 4 times the value 1. The reason is that the exponential magnifies differences: \(e^4\) is \(e^3 = 20.1\) times \(e^1\).
Row 1 is computed in the same way. Its denominator is \(e^2 + e^4 + e^4 + e^5 = 7.389 + 54.598 + 54.598 + 148.413 = 264.998\), and its outputs are 0.0279, 0.2060, 0.2060 and 0.5601. As we would expect, the 2 equal inputs receive equal outputs.
Softmax appears in 2 places in a transformer. In an attention layer, it is applied to every row of a matrix of scores between tokens, so a row holds one value per token of the sequence, often 1,024 to 32,768 values. At the output of the model, it is applied to a row with one value per word of the vocabulary, often 32,000 to 128,000 values. A GPU implementation must therefore handle many short rows as well as a few long ones, and in Section 23.7, we measure both cases.
23.1.3 Layer normalization
The values that a layer of a model produces can drift: from 1 row to the next, or from 1 training step to the next, their center may move and their spread may grow or shrink. Layer normalization removes this drift. It measures where the values of a row are centered and how widely they are spread, and then rescales the row so that it is centered at 0 with a spread of 1. The center is measured by the mean, and the spread by the variance, which we now define.
Definition 23.2 Mean, variance and layer normalization. The mean of a row is \(\mu = \frac{1}{n} \sum_{j} x_j\), and its variance is the mean squared deviation from the mean, \(\sigma^2 = \frac{1}{n} \sum_j (x_j - \mu)^2\). The square root \(\sigma\) is the standard deviation. The layer normalization of the row is
\[ y_j = \frac{x_j - \mu}{\sqrt{\sigma^2 + \varepsilon}} \, \gamma_j + \beta_j, \qquad j \in [0, n), \]
where \(\varepsilon\) is a small constant, and \(\gamma_j\) and \(\beta_j\) are a scale and a shift for column \(j\) that the model learns.
Example. For row 0 of \(X\), \(\mu = 2.5\), \(\sigma^2 = 1.25\), and with \(\gamma_j = 1\), \(\beta_j = 0\) and \(\varepsilon = 10^{-5}\), \(y_0 = -1.5 / \sqrt{1.25001} = -1.3416\).
| Symbol | Meaning | In the example (row 0, \(j = 0\)) |
|---|---|---|
| \(\mu\) | mean of the row, the center of its values | 2.5 |
| \(x_j - \mu\) | deviation of value \(j\) from the mean | \(1 - 2.5 = -1.5\) |
| \(\sigma^2\) | variance, the mean of the squared deviations | 1.25 |
| \(\sigma\) | standard deviation, the square root of the variance | 1.118 |
| \(\varepsilon\) | small constant that keeps the square root away from 0 | \(10^{-5}\) |
| \(\gamma_j, \beta_j\) | learned scale and shift of column \(j\) | 1 and 0 |
| \(y_j\) | output in column \(j\) | \(-1.3416\) |
The formula is easiest to read from the inside out. The deviation \(x_j - \mu\) moves the center of the row to 0. Dividing by \(\sqrt{\sigma^2 + \varepsilon}\), which is almost exactly the standard deviation, makes the spread 1. Finally, \(\gamma_j\) and \(\beta_j\) let the model choose a different scale and center for each column, if that serves it better. In this chapter, we take \(\gamma_j = 1\) and \(\beta_j = 0\) in all hand computations, so that the last step changes nothing.
Figure 23.3 carries out the definition on row 0. The mean is \(10 / 4 = 2.5\). The deviations from the mean are \(-1.5, -0.5, 0.5\) and \(1.5\), their squares are 2.25, 0.25, 0.25 and 2.25, and the variance is the mean of these squares, \(5 / 4 = 1.25\). Each deviation is then multiplied by \(1 / \sqrt{1.25 + 10^{-5}} = 0.8944\), which gives \(-1.3416, -0.4472, 0.4472\) and \(1.3416\). The outputs have mean 0 and variance \(1.25 / 1.25001\), which is 1 up to the small effect of \(\varepsilon\).
For row 1, the mean is \(15 / 4 = 3.75\), the deviations are \(-1.75, 0.25, 0.25\) and \(1.25\), the variance is \(4.75 / 4 = 1.1875\), and the outputs are \(-1.6059, 0.2294, 0.2294\) and \(1.1471\). The constant \(\varepsilon\) matters only for a row whose values are all equal. Such a row has variance 0, and without \(\varepsilon\), every output would be \(0 / 0\).
We can now see that both definitions have the same shape. Each of them needs 1 or 2 numbers computed from the whole row, the sum of exponentials in one case and the mean and the variance in the other, before it can produce its first output. In the rest of the chapter, we study how to compute these numbers quickly and accurately.
Exercises
23.1 Compute the softmax of the row 0, 0, 0, 10. Which fraction of the total does the last value
receive?
23.2 Show that the outputs of softmax add up to 1, and that the outputs of layer normalization
with \(\gamma_j = 1\) and \(\beta_j = 0\) add up to 0.
23.3 Compute the layer normalization of the row 4, 4, 4, 4 with and without \(\varepsilon\).
23.2 The sequential algorithms
23.2.1 Overflow in f32
The formulas of Section 23.1 are exact in real arithmetic, but a computer evaluates them with
numbers of limited range and precision. The kernels of this chapter compute in single
precision, the 32-bit floating-point type f32 in Rust and float in C++. Before we evaluate
softmax in this type, we recall what it can hold.
Definition 23.3 The f32 type. An f32 number holds a sign,
an 8-bit exponent and a 24-bit significand. Its largest finite value is about
\(3.40 \times 10^{38}\). A result larger than that is rounded to the special value
\(\infty\), and an expression without a defined value, such as \(\infty / \infty\) or
\(0 \cdot \infty\), gives the special value NaN, “not a number”. Every arithmetic operation
with a NaN operand gives NaN.
Example. \(e^{88} = 1.65 \times 10^{38}\) fits in an f32; \(e^{89} = 4.49 \times 10^{38}\)
does not and becomes \(\infty\).
The largest f32 equals \(e^{88.72}\), so the exponential of any input above 88.72 overflows.
Inputs of that size are not unusual in a model, and we now follow what happens to one of them.
Suppose that we add 100 to every value of \(X\). Row 0 becomes 101, 102, 103 and 104, and the
exponentials range from \(7.31 \times 10^{43}\) to \(1.47 \times 10^{45}\), all beyond the
largest f32. Each of them therefore becomes \(\infty\), their sum is \(\infty\), and every
output is \(\infty / \infty\), which is NaN, as shown in the left half of Figure 23.4. The entry
\(p_{03} = 0.6439\) is lost, and so is every other entry of the row, although the true softmax
of this row is ordinary, as we show next.
23.2.2 Subtracting the maximum
The exponentials in Figure 23.4 overflow because the inputs are large, yet the outputs that we want are ordinary probabilities. This suggests that the size of the inputs should not matter to the result, and indeed it does not. The reason is a familiar property of fractions: multiplying the numerator and the denominator of a fraction by the same nonzero number does not change its value. Subtracting a constant \(c\) from every input multiplies every exponential by the same number \(e^{-c}\), and therefore leaves every output unchanged. If we choose \(c\) to be the largest input of the row, no exponential can exceed 1.
Theorem 23.1 For every real number \(c\), the softmax of \(x_0 - c, \dots, x_{n-1} - c\) equals the softmax of \(x_0, \dots, x_{n-1}\). If \(c = m = \max_j x_j\), then every exponential \(e^{x_j - m}\) lies in \((0, 1]\), and the denominator \(\sum_j e^{x_j - m}\) lies in \([1, n]\).
Proof. Since \(e^{x_j - c} = e^{x_j} e^{-c}\),
\[ \frac{e^{x_j - c}}{\sum_i e^{x_i - c}} = \frac{e^{x_j} e^{-c}}{e^{-c} \sum_i e^{x_i}} = \frac{e^{x_j}}{\sum_i e^{x_i}}, \]
because the positive factor \(e^{-c}\) cancels. With \(c = m\), every \(x_j - m \le 0\), so \(0 < e^{x_j - m} \le 1\). The sum has \(n\) such terms, so it is at most \(n\), and the term of a column where \(x_j = m\) equals \(e^0 = 1\), so the sum is at least 1.
In the theorem, \(c\) is any constant subtracted from all inputs, and \(m\) is the largest input of the row. For row 0 of \(X + 100\), \(m = 104\), and the shifted inputs \(x_j - m\) are \(-3, -2, -1\) and 0.
The theorem gives more than freedom from overflow. A denominator of at least 1 cannot be 0, so the division is always defined. Moreover, since shifting a whole row by a constant does not change its softmax, the matrix \(X + 100\) has exactly the softmax \(P\) of \(X\). For row 0 of \(X + 100\), the exponentials of the shifted inputs are 0.0498, 0.1353, 0.3679 and 1, which add up to 1.5530, and the outputs are 0.0321, 0.0871, 0.2369 and 0.6439 again, as shown in the right half of Figure 23.4.
23.2.3 Softmax in 3 passes
The subtraction of the maximum has a cost. The maximum must be known before the first exponential is computed, and the sum of the exponentials must be known before the first output is written. The algorithm therefore reads the row 3 times, once for each of these 3 steps. Since the number of times an algorithm reads its data will decide its speed on a GPU, we first give this quantity a name.
Definition 23.4 Pass. A pass is 1 traversal of a row in which every value of the row is read once. The memory traffic of an algorithm is the number of bytes it reads and writes in main memory.
Example. An algorithm that reads a row of 4 f32 values 3 times and writes 4 results has 3
passes and moves \(12 \cdot 4 + 4 \cdot 4 = 64\) bytes.
Softmax-3-Pass(\(x, p, n\))
- \(m = -\infty\)
- for \(j \in [0, n)\) {
- \(m = \max(m, x_j)\) // pass 1: the maximum
- }
- \(s = 0\)
- for \(j \in [0, n)\) {
- \(s = s + e^{x_j - m}\) // pass 2: the sum
- }
- for \(j \in [0, n)\) {
- \(p_j = e^{x_j - m} / s\) // pass 3: the outputs
- }
Lines 1 to 4 find the maximum \(m\), lines 5 to 8 add the shifted exponentials into the sum \(s\), and lines 9 to 11 write the outputs. Each of lines 3, 7 and 10 executes \(n\) times, so the algorithm performs \(n\) comparisons, \(2n\) exponentials and \(n\) divisions. Figure 23.5 follows the 3 passes on row 1. Pass 1 finds \(m = 5\). Pass 2 adds \(e^{-3} + e^{-1} + e^{-1} + e^{0} = 0.0498 + 0.3679 + 0.3679 + 1 = 1.7855\). Pass 3 writes 0.0279, 0.2060, 0.2060 and 0.5601, which is row 1 of \(P\) in Figure 23.1.
Let us count the memory traffic of the example. Each pass reads all 4 values of the row, so the row of 16 bytes is read 3 times, and 16 bytes of output are written. This makes 64 bytes in all, or 16 bytes per element. In general, a matrix of \(R\) rows of \(C\) values each costs \(16RC\) bytes, where \(R\) counts the rows and \(C\) the values in a row. For \(R = C = 4{,}096\), that is 268 MB, which takes 2.63 ms on a GPU whose memory delivers 102 GB/s. The arithmetic, about 3 operations per element, takes little time compared with this traffic, and therefore the number of passes decides the time.
23.2.4 Layer normalization in 2 or 3 passes
Layer normalization has the same difficulty. The definition of the variance needs the mean before the squared deviations can be summed, so a direct algorithm also reads the row 3 times, once for the mean, once for the variance and once for the outputs. A well-known identity removes one of these passes, because it expresses the variance through sums that do not need the mean in advance.
Theorem 23.2 The variance of a row equals the mean of the squares minus the square of the mean: \(\sigma^2 = \frac{1}{n} \sum_j x_j^2 - \mu^2\).
Proof. We expand the square in the definition of the variance. This gives \(\frac{1}{n} \sum_j (x_j - \mu)^2 = \frac{1}{n} \sum_j x_j^2 - 2 \mu \frac{1}{n} \sum_j x_j + \mu^2 = \frac{1}{n} \sum_j x_j^2 - 2\mu^2 + \mu^2\), since \(\frac{1}{n} \sum_j x_j = \mu\).
For row 0 of \(X\), the mean of the squares is \((1 + 4 + 9 + 16) / 4 = 7.5\), the square of the mean is \(2.5^2 = 6.25\), and their difference is 1.25, the variance that we found in Figure 23.3. The point of the identity is that the sum of the values and the sum of their squares can both be accumulated in the same pass, since neither needs the mean. The variance then needs 1 pass instead of 2, as the following procedure shows.
LayerNorm-Sum-Of-Squares(\(x, y, n, \gamma, \beta\))
- \(\mathsf{sum} = 0\), \(\mathsf{squares} = 0\)
- for \(j \in [0, n)\) {
- \(\mathsf{sum} = \mathsf{sum} + x_j\), \(\mathsf{squares} = \mathsf{squares} + x_j^2\) // pass 1: 2 sums
- }
- \(\mu = \mathsf{sum} / n\), \(\sigma^2 = \mathsf{squares} / n - \mu^2\)
- for \(j \in [0, n)\) {
- \(y_j = (x_j - \mu) / \sqrt{\sigma^2 + \varepsilon} \cdot \gamma_j + \beta_j\) // pass 2: the outputs
- }
Here \(\mathsf{sum}\) is the running sum of the values and \(\mathsf{squares}\) the running sum of their squares. On
row 0, line 3 accumulates \(\mathsf{sum} = 10\) and \(\mathsf{squares} = 1 + 4 + 9 + 16 = 30\), and line 5 gives
\(\mu = 10 / 4 = 2.5\) and \(\sigma^2 = 30 / 4 - 2.5^2 = 7.5 - 6.25 = 1.25\), the variance of
Figure 23.3. The algorithm reads each value twice and writes each output once, which makes 12
bytes per element. In exact arithmetic, it is correct. In f32, however, it can fail completely,
as we show next.
23.2.5 Cancellation
An f32 number has only 24 bits of significand, so it can represent only a limited number of
digits. Large numbers are therefore stored less finely than small ones: near 1, neighboring f32
numbers are very close together, while near \(10^8\), they are several units apart. A result that
falls between 2 neighbors must be rounded to one of them. We make this precise before we apply
it to the variance.
Definition 23.5 Spacing and cancellation. The f32 numbers
between \(2^k\) and \(2^{k+1}\) are spaced \(2^{k-23}\) apart, so every result in that range
is rounded to a multiple of \(2^{k-23}\). Cancellation is the loss of correct digits when 2
nearly equal numbers, each carrying a rounding error, are subtracted: the difference is small,
but the errors are not.
Example. Between \(2^{26} = 67{,}108{,}864\) and \(2^{27}\), f32 numbers are
\(2^3 = 8\) apart, so \(10{,}001^2 = 100{,}020{,}001\) is stored as 100,020,000.
In the definition, \(2^k\) is the power of 2 just below the number, and \(2^{k-23}\) is the gap
between 2 neighboring f32 numbers in that range. For example, for numbers near \(10^8\),
\(k = 26\), and the gap is \(2^{26-23} = 8\).
We now add 10,000 to every value of \(X\). Row 0 becomes 10,001, 10,002, 10,003 and 10,004. Its
deviations from the mean are those of row 0 of \(X\), so its variance is still 1.25, and its
layer normalization is still \(-1.3416, -0.4472, 0.4472\) and \(1.3416\). Figure 23.6 runs
LayerNorm-Sum-Of-Squares on this row in f32, 1 rounding at a time.
f32: \(-8\) instead of 1.25.Let us follow the roundings in order. The squares lie near \(10^8\), where f32 numbers are 8
apart, and 3 of the 4 squares are rounded. Once the running sum passes \(2.68 \times 10^8\), the
spacing becomes 32. The last addition, \(300{,}120{,}000 + 100{,}080{,}016 = 400{,}200{,}016\),
lies exactly halfway between 2 neighbors and is rounded to 400,200,000. Dividing by 4 gives the
mean of the squares, 100,050,000. The mean itself is 10,002.5, which is exact in f32, but its
square, 100,050,006.25, is rounded to 100,050,008. Line 5 then subtracts the 2 results:
\[ \sigma^2 = 100{,}050{,}000 - 100{,}050{,}008 = -8. \]
The first number is the mean of the squares, \(b / n\), and the second is the square of the mean, \(\mu^2\), each after rounding. The true difference, 1.25, is smaller than the spacing 8 of the numbers being subtracted, so not a single correct digit survives the subtraction. The result is not even positive, so \(\sqrt{-8 + 10^{-5}}\) is NaN, and every output of the row is NaN. The entry \(y_{00} = -1.3416\) is lost. The GPU kernel of Section 23.6 prints the same 8 NaNs for \(X + 10{,}000\).
The failure needs no extreme values. Rows of activations with a large common offset and a small spread occur in practice, and in Section 23.7, we measure an error of 2.97 on outputs of size 1 for values near 1,000. The difficulty lies in forming the squares of the values themselves, which are large whenever the values are large, even when the variance is small. The remedy is therefore to form only squares of deviations, which are small whenever the variance is small.
Exercises
23.4 Which is the largest integer \(k\) for which \(e^k\) is finite in f32? And in f64,
whose largest value is about \(1.8 \times 10^{308}\)?
23.5 Show that Theorem 23.1 holds for any \(c\), but that only \(c \ge \max_j x_j\) guarantees
that no exponential overflows. Which choice of \(c\) also guarantees a denominator of at least
1?
23.6 Repeat Figure 23.6 for row 0 of \(X + 1{,}000\), where f32 numbers near \(10^6\) are
0.0625 apart. Is the variance exact?
23.3 One pass over the row
23.3.1 The dependence on the maximum
Recall that Softmax-3-Pass reads the row 3 times because of 2 dependences. Line 7 needs \(m\), which is known only after the last iteration of line 3, and line 10 needs \(s\), which is known only after the last iteration of line 7. The second dependence cannot be avoided, since an output \(e^{x_j - m} / s\) cannot be written before the whole sum \(s\) is known. The first dependence, however, deserves a closer look.
Suppose that we process row 1, which holds 2, 4, 4 and 5, from the left, and that we pretend that the largest value seen so far is the maximum. After the first value, the maximum so far is 2, and the sum so far is \(e^{2-2} = 1\). The second value, 4, is larger, so the sum so far was taken relative to the wrong maximum. We wanted the term \(e^{2-4}\), and we have \(e^{2-2}\) instead. The work is not lost, however. Since \(e^{a} \cdot e^{b} = e^{a+b}\), the term that we have becomes the term that we want when we multiply it by \(e^{2-4}\):
\[ e^{2-2} \cdot e^{2-4} = e^{2-4}. \]
Here, the first factor is the term relative to the old maximum 2, the second factor is the correction from the old maximum 2 to the new maximum 4, and the right side is the term relative to the new maximum. The correction factor depends only on the 2 maxima, not on the value of the term. The same multiplication therefore corrects any number of terms at once, because every term of the sum was taken relative to the same old maximum.
Key observation A sum of exponentials taken relative to 1 maximum \(m\) becomes the sum relative to a larger maximum \(m’\) by 1 multiplication, since \(e^{x - m} \cdot e^{m - m’} = e^{x - m’}\) for every term. The maximum therefore does not have to be known before the sum begins: the sum can be corrected each time the maximum grows.
| Symbol | Meaning | In the example |
|---|---|---|
| \(x\) | a value already added to the sum | 2 |
| \(m\) | the old maximum, relative to which the sum was taken | 2 |
| \(m’\) | the new, larger maximum | 4 |
| \(e^{m - m’}\) | correction factor, the same for every term | \(e^{-2} = 0.1353\) |
23.3.2 The online softmax
We now carry out the observation on row 1, 1 value at a time. We keep 2 numbers while we read the row: \(m\), the largest value seen so far, and \(s\), the sum of \(e^{x - m}\) over the values \(x\) seen so far. We start from \(m = -\infty\) and \(s = 0\), which describe a row with no values, since no value has been seen and the sum of no terms is 0. Figure 23.7 shows the 4 steps.
- The first value is 2. It is larger than \(m = -\infty\), so the old sum is multiplied by \(e^{-\infty - 2} = 0\), and the new value contributes \(e^{2-2} = 1\). We now have \(m = 2\) and \(s = 1\).
- The second value is 4. It is larger than \(m = 2\), so the old sum is moved to the new maximum by the factor \(e^{2-4}\), and the new value contributes \(e^0 = 1\). We now have \(s = 1 \cdot e^{2-4} + 1 = 0.1353 + 1 = 1.1353\) and \(m = 4\).
- The third value is 4. It is not larger than \(m = 4\), so the maximum stays, and the value adds \(e^{4-4} = 1\) to the sum, which becomes \(s = 2.1353\).
- The fourth value is 5. It is larger than \(m = 4\), so we obtain \(s = 2.1353 \cdot e^{4-5} + 1 = 0.7855 + 1 = 1.7855\) and \(m = 5\).
The final pair, \(m = 5\) and \(s = 1.7855\), is exactly what passes 1 and 2 of Figure 23.5 computed, but we obtained it in 1 pass instead of 2.
The pair \((m, s)\) carries everything that the algorithm needs to remember about the values already read. We give such a pair a name, so that we can reason about it.
Definition 23.6 Softmax state. A softmax state \((m, s)\) describes a set \(S\) of values when \(m = \max S\) and \(s = \sum_{x \in S} e^{x - m}\). The empty state \((-\infty, 0)\) describes the empty set.
Example. \((4, 1.1353)\) describes the values 2, 4: \(4 = \max\{2, 4\}\) and \(e^{2-4} + e^{4-4} = 1.1353\).
Online-Softmax(\(x, p, n\))
- \(m = -\infty\), \(s = 0\) // the empty state
- for \(j \in [0, n)\) {
- if \(x_j > m\) {
- \(s = s \cdot e^{m - x_j} + 1\) // move the sum to the new maximum
- \(m = x_j\)
- } else {
- \(s = s + e^{x_j - m}\)
- }
- }
- for \(j \in [0, n)\) {
- \(p_j = e^{x_j - m} / s\)
- }
Lines 1 to 9 form the first pass, and they replace lines 1 to 8 of Softmax-3-Pass. Lines 10 to 12 are its third pass, unchanged. Line 4 is the correction of the key observation, followed by the term \(e^{x_j - x_j} = 1\) of the new value. Line 4 also handles the first value without a special case: when \(m = -\infty\), the factor \(e^{m - x_j}\) is 0, and \(s\) becomes 1. The loop computes 1 exponential per value, either on line 4 or on line 7, so the amount of arithmetic is the same as before, \(2n\) exponentials in all. What changes is the traffic. The algorithm makes 2 reads and 1 write per element, which is 12 bytes instead of 16.
The algorithm is short, but each step relies on the previous state being exactly right, so we now prove that it is correct.
Theorem 23.3 When the loop of lines 2 to 9 of Online-Softmax ends, \(m = \max_j x_j\) and \(s = \sum_{j \in [0,n)} e^{x_j - m}\). The outputs of line 11 are therefore the softmax of \(x\).
Proof. We show that the loop maintains the invariant
\[ \text{at the start of iteration } j, \quad (m, s) \text{ describes } \{x_0, \dots, x_{j-1}\}, \]
that is, \(m = \max_{i < j} x_i\) and \(s = \sum_{i < j} e^{x_i - m}\), where \(i\) runs over the values already read (Figure 23.8). For example, on row 1 at the start of iteration \(j = 2\), the values read are 2 and 4, and \((m, s) = (4, 1.1353)\).
Initialization. Before iteration 0, the set is empty, and line 1 sets the empty state.
Maintenance. Assume that the invariant holds at the start of iteration \(j\). If \(x_j > m\), the new maximum is \(x_j\). Line 4 multiplies every term \(e^{x_i - m}\) of \(s\) by \(e^{m - x_j}\), which turns it into \(e^{x_i - x_j}\) by the key observation, and adds \(e^{x_j - x_j} = 1\), the term of the new value. Line 5 sets \(m = x_j\). If \(x_j \le m\), the maximum does not change, and line 7 adds the term \(e^{x_j - m}\) of the new value. In both cases, \((m, s)\) describes \(\{x_0, \dots, x_j\}\) at the start of iteration \(j + 1\).
Termination. The loop ends with \(j = n\), when \((m, s)\) describes the whole row. Line 11 then computes \(e^{x_j - m} / s\), which is the softmax by Theorem 23.1.
The online softmax was published by Milakov and Gimelshein in 2018. It is also at the core of attention kernels that never store the full matrix of scores, because such kernels, too, see a row of scores in pieces.
23.3.3 Merging 2 states
A GPU does not traverse a row from the left with a single thread. Instead, many threads each traverse a part of the row, and their partial results must then be combined. Suppose, for example, that 1 thread has read the values 2 and 4 of row 1, and another thread the values 4 and 5. Each thread holds a softmax state of its own part, taken relative to its own maximum. To combine the 2 states, we move both sums to the larger of the 2 maxima, by the key observation, and add them. The key observation thus combines 2 states as easily as it adds 1 value.
Merge-Softmax(\((m_a, s_a), (m_b, s_b)\))
- \(m = \max(m_a, m_b)\)
- if \(m = -\infty\) {
- return \((-\infty, 0)\) // both states are empty
- }
- return \((m,\; s_a e^{m_a - m} + s_b e^{m_b - m})\)
Theorem 23.4 If \((m_a, s_a)\) describes a set \(A\) and \((m_b, s_b)\) describes a set \(B\) disjoint from \(A\), then Merge-Softmax returns the state that describes \(A \cup B\).
Proof. The maximum of \(A \cup B\) is the larger of the 2 maxima, which line 1 computes. If both sets are empty, so is the union, and line 3 returns the empty state. Otherwise, \(m\) is finite, and line 5 moves each sum to \(m\) by the key observation: \(s_a e^{m_a - m} = \sum_{x \in A} e^{x - m}\), and likewise for \(B\). If 1 of the sets is empty, its factor is \(e^{-\infty} = 0\) and its sum 0 contributes nothing. Because \(A\) and \(B\) are disjoint, the 2 sums together contain each term of \(A \cup B\) once.
In the procedure, \((m_a, s_a)\) and \((m_b, s_b)\) are the 2 states to be merged, and the factors \(e^{m_a - m}\) and \(e^{m_b - m}\) move each sum from its own maximum to the common maximum \(m\). The factor of the state that already has the larger maximum is \(e^0 = 1\).
The left half of Figure 23.9 merges the two halves of row 1 in this way. The values 2 and 4 have the state \((m_a, s_a) = (4, 1.1353)\), and the values 4 and 5 have the state \((m_b, s_b) = (5, e^{-1} + 1) = (5, 1.3679)\). The merge gives \(m = 5\) and \(s = 1.1353 \cdot e^{4-5} + 1.3679 \cdot e^{5-5} = 0.4177 + 1.3679 = 1.7855\), which is the sum of Figure 23.7.
The theorem has two consequences that matter for the GPU. First, the result depends only on the
union of the sets, so merges can be grouped in any order. Merging \(A\) with \(B\) and then
with a third set \(C\) gives the same state as merging \(A\) with the merge of \(B\) and
\(C\). An operation with this property is called associative, and associativity is what
allows the threads to combine their states in a tree of merges instead of a chain. Second, the
test on line 2 is necessary. Without it, 2 empty states give \(0 \cdot e^{-\infty - (-\infty)}\),
and \(-\infty - (-\infty)\) is NaN in f32. On a GPU, many threads can hold empty states, and in
Section 23.5, we show what happens when line 2 is missing.
23.3.4 Welford’s method
The same idea removes the extra pass of the variance, and it removes the cancellation at the same time. Recall from Section 23.2.5 that the trouble came from squaring the values themselves. We would rather sum the squared deviations from the mean, as the definition does, but the mean is not known until the whole row has been read. We therefore proceed as we did with the maximum. We use the mean of the values seen so far, and we correct the sum each time this mean moves.
While reading the row, we keep 3 numbers: the count \(n\) of values seen, their mean \(\mu\), and the sum \(q\) of their squared deviations from \(\mu\). The variance of the values seen is then \(q / n\). For example, after the values 1 and 2 of row 0, we have \(n = 2\), \(\mu = 1.5\) and \(q = (-0.5)^2 + 0.5^2 = 0.5\). When a new value \(x\) arrives, the mean moves, while every deviation in \(q\) was measured from the old mean. As with the maximum, the old sum can be corrected without visiting the old values again, and we now derive the correction.
Let \(\mu\) be the mean of the first \(k - 1\) values, let \(x\) be the \(k\)-th value, and let \(\delta = x - \mu\) be the deviation of the new value from the old mean. In our example, with the third value \(x = 3\), we have \(k = 3\), \(\mu = 1.5\) and \(\delta = 1.5\). The new mean is the total of the \(k\) values divided by \(k\):
\[ \mu’ = \frac{(k - 1)\mu + x}{k} = \mu + \frac{\delta}{k}. \]
| Symbol | Meaning | In the example |
|---|---|---|
| \(k\) | number of values after the new one is added | 3 |
| \(\mu\) | mean of the first \(k - 1\) values, the old mean | 1.5 |
| \(x\) | the new value | 3 |
| \(\delta\) | deviation of the new value from the old mean, \(x - \mu\) | 1.5 |
| \(\mu’\) | mean of all \(k\) values, the new mean | \(1.5 + 1.5 / 3 = 2\) |
In words, the mean moves toward the new value by \(1/k\) of the distance between them. The old values now deviate from \(\mu’\) instead of \(\mu\). Shifting the center of \(k - 1\) values by \(\mu’ - \mu = \delta / k\) adds \((k - 1)(\delta / k)^2\) to the sum of their squared deviations. No other term appears, because the cross terms contain the sum of the deviations from \(\mu\), which is 0. In the example, the old values 1 and 2 had the squared deviations 0.25 and 0.25 from 1.5, and they have 1 and 0 from 2, so their sum grows by \(2 \cdot 0.5^2 = 0.5\). The new value adds its own squared deviation, \((x - \mu’)^2 = (\delta (k-1)/k)^2\), which is \(1^2 = 1\) in the example. Together, the new sum is
\[ q’ = q + (k-1)\frac{\delta^2}{k^2} + \frac{(k-1)^2 \delta^2}{k^2} = q + \delta^2 \frac{k-1}{k} = q + \delta \, (x - \mu’), \]
where the last step uses \(x - \mu’ = \delta (k-1)/k\).
| Symbol | Meaning | In the example |
|---|---|---|
| \(q\) | sum of squared deviations of the old values from \(\mu\) | 0.5 |
| \(x - \mu’\) | deviation of the new value from the new mean | \(3 - 2 = 1\) |
| \(q’\) | sum of squared deviations of all \(k\) values from \(\mu’\) | \(0.5 + 1.5 \cdot 1 = 2\) |
Indeed, the values 1, 2 and 3 have the squared deviations 1, 0 and 1 from their mean 2, which add up to 2. The final form of the update needs only the old mean and the new mean, and that it multiplies 2 deviations, never 2 values.
Welford-Update(\((n, \mu, q), x\))
- \(n = n + 1\)
- \(\delta = x - \mu\) // deviation from the old mean
- \(\mu = \mu + \delta / n\)
- \(q = q + \delta \cdot (x - \mu)\) // old deviation times new deviation
- return \((n, \mu, q)\)
Line 2 computes the deviation \(\delta\) from the old mean, line 3 moves the mean, and line 4 adds the product of the old and the new deviation of \(x\) to \(q\). Figure 23.10 applies the update to the whole of row 0, starting from the state \((0, 0, 0)\). The value 1 gives \(\delta = 1\), \(\mu = 1\) and \(q = 1 \cdot 0 = 0\). The value 2 gives \(\delta = 1\), \(\mu = 1.5\) and \(q = 0 + 1 \cdot 0.5 = 0.5\). The value 3 gives \(\delta = 1.5\), \(\mu = 2\) and \(q = 0.5 + 1.5 \cdot 1 = 2\), as we computed above. The value 4 gives \(\delta = 2\), \(\mu = 2.5\) and \(q = 2 + 2 \cdot 1.5 = 5\). The variance is therefore \(5 / 4 = 1.25\), as in Figure 23.3.
We now run the same steps on the row 10,001 to 10,004 in f32, the row on which the sum of
squares failed. The means 10,001, 10,001.5, 10,002 and 10,002.5 are exact in f32, and the
deviations are 1, 1, 1.5 and 2, as before, so \(q\) is again exactly 5, and the variance is 1.25.
No square of a value near 10,000 is ever formed. Every number added to \(q\) is of the size of
the deviations, and the deviations are small whenever the variance is small. This is exactly the
property that the sum of squares lacked.
Theorem 23.5 After Welford-Update has been applied to \(x_0, \dots, x_{k-1}\), starting from \((0, 0, 0)\), the state is \(\big(k, \mu_k, \sum_{i<k} (x_i - \mu_k)^2\big)\), where \(\mu_k\) is the mean of the \(k\) values.
Proof. We use the invariant that after \(k\) updates, the state is \((k, \mu_k, q_k)\) with \(q_k = \sum_{i<k} (x_i - \mu_k)^2\). For example, after \(k = 3\) updates on row 0, the state is \((3, 2, 2)\).
Initialization. For \(k = 0\), the state \((0, 0, 0)\) has count 0 and \(q_0 = 0\), the empty sum. The mean 0 of the empty state does not enter any later result, since line 3 of the first update gives \(\mu = 0 + (x_0 - 0)/1 = x_0\).
Maintenance. Assume that the invariant holds after \(k - 1\) updates, and apply the update to \(x_{k-1}\). Line 1 makes the count \(k\), and line 3 computes \(\mu_k = \mu_{k-1} + \delta / k\), the new mean derived above. For the sum, write each old deviation as \(x_i - \mu_k = (x_i - \mu_{k-1}) - \delta/k\). Squaring and summing over \(i < k - 1\) gives \(q_{k-1} + (k-1)\delta^2/k^2\), since \(\sum_{i<k-1} (x_i - \mu_{k-1}) = 0\). Adding the new term \((x_{k-1} - \mu_k)^2 = \delta^2 (k-1)^2/k^2\) gives \(q_{k-1} + \delta^2 (k-1)/k\), which is what line 4 adds, \(\delta (x_{k-1} - \mu_k)\).
Termination. After the last value, the state is \((n, \mu, q)\) with \(q / n = \sigma^2\).
Welford’s method has a price. It performs 1 division per value, on line 3, where the sum of squares performs only 1 multiplication. In Section 23.7, we measure what this division costs on a GPU.
23.3.5 Merging 2 Welford states
As with softmax, each thread of a GPU will hold the state of a part of the row, and the states must then be merged. Suppose that 1 thread has read the values 1 and 2 of row 0, and another thread the values 3 and 4. The first thread holds the state \((2, 1.5, 0.5)\), and the second the state \((2, 3.5, 0.5)\). The count and the mean of the union are easy to obtain: the counts add up, and the mean of the union is the average of the 2 means, weighted by the counts. The sums \(q\), however, were measured from 2 different means, and neither of them is the mean of the union. They must be corrected in the same way as in Welford’s update. The following rule is due to Chan, Golub and LeVeque.
Merge-Welford(\((n_a, \mu_a, q_a), (n_b, \mu_b, q_b)\))
- \(n = n_a + n_b\)
- if \(n = 0\) {
- return \((0, 0, 0)\) // both states are empty
- }
- \(\delta = \mu_b - \mu_a\)
- \(\mu = \mu_a + \delta \, n_b / n\)
- \(q = q_a + q_b + \delta^2 \, n_a n_b / n\)
- return \((n, \mu, q)\)
Theorem 23.6 If \((n_a, \mu_a, q_a)\) and \((n_b, \mu_b, q_b)\) are the states of 2 disjoint sets \(A\) and \(B\), then Merge-Welford returns the state of \(A \cup B\).
Proof. If both sets are empty, line 3 returns the empty state. Otherwise, the mean of the union is the weighted mean \((n_a \mu_a + n_b \mu_b)/n = \mu_a + \delta n_b / n\), which line 6 computes. Each value of \(A\) deviates from the new mean \(\mu\) by its deviation from \(\mu_a\) minus \(\mu - \mu_a = \delta n_b / n\). As in the proof of Theorem 23.5, the cross terms vanish, so \(A\) contributes \(q_a + n_a (\delta n_b / n)^2\). Likewise, \(B\) contributes \(q_b + n_b (\delta n_a / n)^2\). The sum of the 2 extra terms is \(\delta^2 n_a n_b (n_b + n_a) / n^2 = \delta^2 n_a n_b / n\), which line 7 adds.
The right half of Figure 23.9 merges the halves of row 0 with this rule.
| Symbol | Meaning | In the example |
|---|---|---|
| \(n_a, \mu_a, q_a\) | count, mean and sum of squared deviations of the first part | 2, 1.5, 0.5 (values 1, 2) |
| \(n_b, \mu_b, q_b\) | the same for the second part | 2, 3.5, 0.5 (values 3, 4) |
| \(n\) | count of the union | 4 |
| \(\delta\) | distance between the 2 means, \(\mu_b - \mu_a\) | 2 |
| \(\mu\) | mean of the union | \(1.5 + 2 \cdot 2 / 4 = 2.5\) |
| \(q\) | sum of squared deviations of the union | \(0.5 + 0.5 + 4 \cdot 2 \cdot 2 / 4 = 5\) |
The result, \((4, 2.5, 5)\), is the state that Figure 23.10 reached by updating 1 value at a time. The last term of line 7, \(\delta^2 n_a n_b / n = 4\) in the example, accounts for the distance between the 2 means. Each half measured its deviations from its own mean, whereas the union needs them from the common mean. In the example, the mean of each half lies 1 unit from the common mean 2.5, which adds \(2 \cdot 1^2 = 2\) for the 2 values of each half, and 4 in all.
Exercises
23.7 Run Online-Softmax on row 0, 1, 2, 3, 4. How many times does line 4
execute, and how many times line 7?
23.8 Merge the softmax states of the values 2 and of 4, 4, 5 (first compute each state), and check
the result against Figure 23.7.
23.9 Apply Welford-Update to row 1 and check that \(q / 4 = 1.1875\).
Then merge the states of 2, 4, 4 and of 5 with Merge-Welford.
23.4 The parallel algorithm
23.4.1 Rows and blocks
We now distribute the work over the threads of a GPU. Before we do so, we recall the terms that we need.
Definition 23.7 Kernel, thread, block, grid. A kernel is a function that the GPU runs many times at once; each run is a thread with its own variables. A block is a group of threads that run on the same streaming multiprocessor (SM), share a region of fast memory, and can wait for one another. The grid is the set of all blocks of 1 launch. Inside a block, each thread can read its index \(\mathsf{threadIdx{.}x}\), and the index of its block, \(\mathsf{blockIdx{.}x}\).
Example. For the 4,096 rows of Section 23.7, the grid has 4,096 blocks of 256 threads; for \(X\), it has 2 blocks of 256 threads.
The rows are independent of each other, and every row needs a reduction whose result all its outputs share. Since the threads of a block can share data and wait for one another, while different blocks cannot, we give each row to 1 block: block \(\mathsf{blockIdx{.}x}\) computes row \(\mathsf{blockIdx{.}x}\). The threads of the block then divide the row between them in a fixed pattern. The number of threads in a block, \(\mathsf{blockDim{.}x}\), is 256 in all our kernels. Thread \(\mathsf{threadIdx{.}x}\) takes the columns \(\mathsf{threadIdx{.}x}, \mathsf{threadIdx{.}x} + \mathsf{blockDim{.}x}, \mathsf{threadIdx{.}x} + 2 \cdot \mathsf{blockDim{.}x}, \dots\) of its row, that is, every column whose remainder on division by \(\mathsf{blockDim{.}x}\) is \(\mathsf{threadIdx{.}x}\). A row of 4,096 values therefore gives each thread \(4{,}096 / 256 = 16\) values. For example, thread 5 takes the columns 5, 261, 517, and so on up to 3,845, as shown in Figure 23.11.
It may seem more natural to give each thread a contiguous piece of the row. The interleaved pattern is chosen instead because of the way the memory serves reads. The threads of a block run in groups of 32, and the hardware serves the reads of such a group together when they fall on neighboring addresses.
Definition 23.8 Warp, lane, coalesced access. A warp is a group of 32 consecutive threads of a block, threads \(32 \cdot \mathsf{warp}\) to \(32 \cdot \mathsf{warp} + 31\) for warp \(\mathsf{warp}\), that execute each instruction together. The position \(\mathsf{threadIdx{.}x} \bmod 32\) of a thread in its warp is its lane. A memory access of a warp is coalesced when its 32 threads read 32 consecutive 4-byte values, 128 contiguous bytes, which the memory system serves together.
Example. A block of 256 threads has 8 warps. In the first step, warp 0 of a block reads columns 0 to 31 of its row, 128 contiguous bytes.
In every step of the interleaved pattern, the 32 threads of a warp read 32 consecutive columns, so every access is coalesced. For example, in the second step, warp 0 reads columns 256 to 287. The contiguous alternative, which gives thread \(\mathsf{threadIdx{.}x}\) the 16 columns \(16 \cdot \mathsf{threadIdx{.}x}\) to \(16 \cdot \mathsf{threadIdx{.}x} + 15\), would make the 32 threads of a warp read addresses that lie \(16 \cdot 4 = 64\) bytes apart, and the memory system could not serve them together.
On \(X\), block 1 has 256 threads for only 4 values. Threads 0 to 3 receive 2, 4, 4 and 5, and threads 4 to 255 receive nothing. Each thread runs Online-Softmax or Welford-Update over its own columns, and a thread without columns keeps the empty state. Every thread then holds the state of a different set of columns. These sets are disjoint, and their union is the row. By Theorems 23.4 and 23.6, merging all 256 states therefore gives the state of the row. It remains to merge them quickly, and to give the result to all 256 threads, because every thread writes outputs.
23.4.2 Merging inside a warp
We begin with the 32 threads of a single warp. Each of them holds a state in its registers, and we want every one of them to end with the merge of all 32 states. The threads of a warp can read each other’s registers directly, with an instruction that we now define.
Definition 23.9 Warp shuffle. A warp shuffle lets every lane of a warp read a register of another lane of the same warp in 1 instruction, without shared memory and without a barrier. In the xor shuffle with mask \(k\), lane \(i\) receives the value of lane \(i \oplus k\), where \(\oplus\) is the bitwise exclusive or of the 2 lane numbers.
Example. With mask 16, lane 3 receives the value of lane \(3 \oplus 16 = 19\), and lane 19 the value of lane 3: the 2 lanes exchange values.
When the mask \(k\) is a power of 2, the exclusive or flips exactly 1 bit of the lane number. In the example, 3 is 00011 in binary, and flipping the bit of value 16 gives 10011, which is 19. With such a mask, the lanes therefore form pairs \(\{i, i \oplus k\}\) that exchange values. If both lanes of each pair merge the value they receive into their own, both of them hold the merge of the pair. With mask 16, for example, lanes 3 and 19 both end with the merge of their 2 states. Repeating the exchange with masks 16, 8, 4, 2 and 1 leaves every lane holding the merge of all 32 states, after 5 steps. This pattern is called a butterfly, after the crossing lines of its diagram. Figure 23.12 shows it on 8 lanes, with the maximum as the merge, for block 1 of the example: 4 lanes hold 2, 4, 4 and 5, and the other 4 lanes hold \(-\infty\). After the steps with masks 4, 2 and 1, every lane holds 5.
The butterfly is correct for the same reason as the merges. Before the first step, lane \(i\)
holds the state of its own set of columns. After the steps with masks 16 down to \(k\), lane
\(i\) holds the merge over all lanes whose numbers differ from \(i\) only in the bits of value
\(k\) or more. For example, after the step with mask 16, lane 3 holds the merge over lanes 3 and
19, and after the step with mask 8, the merge over lanes 3, 11, 19 and 27. The step with mask
\(k / 2\) merges this group with the group of lane \(i \oplus k/2\), which is disjoint from it
and which, together with it, forms the group for \(k / 2\). After the step with mask 1, the group
is the whole warp. In Chapter 8, we used a different shuffle, shfl_down, which leaves the result
in lane 0 only, whereas the xor shuffle leaves it in every lane.
23.4.3 Merging across the warps of a block
After the butterfly, every lane of a warp holds the state of its warp, but a block of 256 threads has 8 warps, and a shuffle cannot reach a register in another warp. The 8 warps of a block must therefore exchange their results through memory that the whole block shares.
Definition 23.10 Shared memory and barrier. Shared memory is a small, fast memory on each SM that the threads of 1 block can read and write, and no other block can. A barrier is a point in a kernel that no thread of a block may pass until every thread of the block has reached it.
Example. A block of 8 warps keeps 8 slots of shared memory, 1 per warp, 32 bytes in all.
The exchange takes 3 steps. First, lane 0 of each warp writes its warp’s result to the slot of its warp. Then, a barrier makes sure that all 8 slots have been written before anyone reads them. Finally, every thread reads all 8 slots and merges them itself, so that every thread ends with the result of the row. Reading 8 slots costs less than a second round of shuffles, and it needs no broadcast of the result afterward. The following procedure, shown in Figure 23.13, combines the butterfly with these 3 steps.
Block-Reduce(\(\mathsf{value}, \otimes, \mathsf{slots}\))
- for \(\mathsf{mask} \in (16, 8, 4, 2, 1)\) {
- \(\mathsf{value} = \mathsf{value} \otimes \mathsf{Shuffle-Xor}(\mathsf{value}, \mathsf{mask})\) // the butterfly of Section 23.4.2
- }
- if \(\mathsf{threadIdx{.}x} \bmod 32 = 0\) {
- \(\mathsf{slots}[\lfloor \mathsf{threadIdx{.}x} / 32 \rfloor] = \mathsf{value}\) // lane 0 writes its warp's slot
- }
- Barrier() // barrier 1: all slots written
- \(\mathsf{result} = \mathsf{slots}[0] \otimes \mathsf{slots}[1] \otimes \dots \otimes \mathsf{slots}[7]\)
- Barrier() // barrier 2: all slots read
- return \(\mathsf{result}\)
Here \(\mathsf{value}\) is the value or state that the calling thread contributes, and \(\otimes\) is the merge: \(\max\) for the maximum, \(+\) for a sum, and Merge-Softmax or Merge-Welford for a state. The expression \(\lfloor \mathsf{threadIdx{.}x} / 32 \rfloor\) is the number of the warp of the thread; for example, thread 70 belongs to warp 2. Line 7 is needed because line 8 reads slots that other warps write on line 5. Line 9 is needed when the same slots are used again by a second reduction, since no warp may write a slot for the second reduction while another warp is still reading the slots of the first. In Section 23.5, we remove line 9 and show what goes wrong.
23.4.4 The kernels
We now have all the pieces of the kernels. For the online softmax, every thread of block \(\mathsf{blockIdx{.}x}\) works on row \(\mathsf{row} = \mathsf{blockIdx{.}x}\) and executes the following procedure. A block has \(\mathsf{blockDim{.}x} = 256\) threads, and \(C\) is the length of a row, 4 for \(X\) and 4,096 in the measurements.
Softmax-Online-Kernel(\(X, P, C\))
- \((m, s) = (-\infty, 0)\)
- for \(\mathsf{column} \in [\mathsf{threadIdx{.}x}, C)\) stride \(\mathsf{blockDim{.}x}\) {
- update \((m, s)\) with \(x_{\mathsf{row},\mathsf{column}}\) // lines 3 to 8 of Online-Softmax
- }
- \((m, s) = \) Block-Reduce\(((m, s),\) Merge-Softmax\()\)
- for \(\mathsf{column} \in [\mathsf{threadIdx{.}x}, C)\) stride \(\mathsf{blockDim{.}x}\) {
- \(p_{\mathsf{row},\mathsf{column}} = e^{x_{\mathsf{row},\mathsf{column}} - m} / s\)
- }
Lines 1 to 4 run the first pass of Online-Softmax on the thread’s own columns. Line 5 merges the 256 states into the state of the row and gives it to every thread. Lines 6 to 8 then write the thread’s outputs. In block 1 of \(X\), for example, thread 2 reads \(x_{1,2} = 4\) on line 3, receives \((m, s) = (5, 1.7855)\) on line 5, and writes \(p_{1,2} = e^{4-5} / 1.7855 = 0.2060\) on line 7. Because the kernel calls Block-Reduce only once, barrier 2 is not needed, and the code leaves it out.
The layer-normalization kernel has the same shape, with Welford-Update on line 3, Merge-Welford on line 5, and the output \(y_{\mathsf{row},\mathsf{column}} = (x_{\mathsf{row},\mathsf{column}} - \mu)\, \gamma_{\mathsf{column}} / \sqrt{q / C + \varepsilon} + \beta_{\mathsf{column}}\) on line 7, where \(q / C\) is the variance of the row. The 3-pass softmax calls Block-Reduce twice, with \(\max\) after pass 1 and with \(+\) after pass 2.
Each of these kernels still reads the row at least twice, once to reduce it and once to write the outputs. Note, however, that a thread of a row of 4,096 values handles only 16 of them, and a thread can keep 16 values in its registers. If it does, the second read is unnecessary.
Definition 23.11 Register, fused kernel. Registers are the fastest storage of a GPU; each thread has its own, and a value in a register costs no memory traffic to reuse. A fused kernel keeps its share of the row in registers between the reduction and the output, so it reads each value from memory once.
Example. For rows of 4,096 values and 256 threads, a fused kernel holds 16 values per thread in 16 registers, 64 bytes per thread.
Softmax-Fused-Kernel(\(X, P\))
- for \(\mathsf{index} \in [0, 16)\) {
- \(\mathsf{kept}[\mathsf{index}] = x_{\mathsf{row},\, \mathsf{index} \cdot \mathsf{blockDim{.}x} + \mathsf{threadIdx{.}x}}\) // the only read of the row
- }
- \(m = \) Block-Reduce\((\max_{\mathsf{index}} \mathsf{kept}[\mathsf{index}], \max)\)
- for \(\mathsf{index} \in [0, 16)\) {
- \(\mathsf{kept}[\mathsf{index}] = e^{\mathsf{kept}[\mathsf{index}] - m}\)
- }
- \(s = \) Block-Reduce\((\sum_{\mathsf{index}} \mathsf{kept}[\mathsf{index}], +)\)
- for \(\mathsf{index} \in [0, 16)\) {
- \(p_{\mathsf{row},\, \mathsf{index} \cdot \mathsf{blockDim{.}x} + \mathsf{threadIdx{.}x}} = \mathsf{kept}[\mathsf{index}] / s\)
- }
Here \(\mathsf{kept}[\mathsf{index}]\) is a value that the thread keeps in a register, and it holds column \(\mathsf{index} \cdot \mathsf{blockDim{.}x} + \mathsf{threadIdx{.}x}\) of the row. For example, thread 5 keeps column \(0 \cdot 256 + 5 = 5\) in \(\mathsf{kept}[0]\) and column \(15 \cdot 256 + 5 = 3{,}845\) in \(\mathsf{kept}[15]\), the same 16 columns as in Figure 23.11.
The fused kernel needs no online softmax. Once the values are in registers, a second and a third pass over them cost no memory traffic, and the plain 3-pass order is the simplest. Line 6 overwrites each value with its exponential, so that line 10 only divides. Likewise, the fused layer normalization uses the definition directly, with 1 reduction for the mean and then 1 over the squared deviations \((\mathsf{kept}[\mathsf{index}] - \mu)^2\), both from registers. It thereby avoids the cancellation without paying for Welford’s division. The price of fusion is generality. The number of values per thread must be a constant when the kernel is compiled, because registers cannot be indexed by a value known only at run time. Moreover, a row of 65,536 values would need 256 registers per thread for the row alone. For these reasons, libraries compile fused kernels for common row lengths and fall back to a 2-pass kernel for the others.
23.4.5 Counting the bytes
We can now compare the kernels by the number of bytes that each of them moves. Figure 23.14 counts the traffic of each kernel per element of the matrix, with 4 bytes per value.
For a matrix of \(R\) rows of \(C\) values each, a kernel that moves \(b\) bytes per element moves \(bRC\) bytes in all. On a memory of bandwidth \(W\), that is, a memory that delivers \(W\) bytes per second, it therefore needs at least \(bRC / W\) seconds. For example, the 3-pass softmax, with \(b = 16\), \(R = C = 4{,}096\) and \(W = 102\) GB/s, needs at least \(16 \cdot 4{,}096^2 / (102 \cdot 10^9) \) s, or 2.63 ms. The following table gives the bound for every kernel.
| Kernel | Bytes per element | Bytes per matrix | Lower bound at 102 GB/s |
|---|---|---|---|
| softmax, 3 passes | 16 | 268 MB | 2.63 ms |
| softmax, online; layer norm, sum of squares or Welford | 12 | 201 MB | 1.97 ms |
| softmax or layer norm, fused | 8 | 134 MB | 1.32 ms |
Each kernel performs only a few arithmetic operations per 4 bytes that it reads, far fewer than a GPU can perform in the time that the memory needs to deliver those bytes, so the bytes set the time. The model assumes that every read reaches main memory. A block reads its row of 16 KiB repeatedly within a short time, however, and some of the repeated reads may be served by a cache instead. In Section 23.7, we measure how much this matters.
Exercises
23.10 Which columns does thread 200 read in a row of 4,096? Which warp does it belong to, and
which lane?
23.11 Carry out Figure 23.12 with the sum instead of the maximum, on the values 0.0498, 0.3679,
0.3679, 1 and 4 zeros.
23.12 A row has 65,536 values and a block has 256 threads. How many values does each thread read,
and how many bytes does the 3-pass kernel move for 256 such rows?
23.5 Correctness
The warps of a block do not run in lockstep. They run at different speeds, and 1 warp can be several instructions ahead of another. The kernels contain 2 safeguards against the errors that this can cause, the second barrier of Block-Reduce and the test for 2 empty states in the merges. In this section, we remove 1 safeguard at a time, follow the wrong values that appear, and then prove that the complete kernel is correct.
23.5.1 The second barrier
Suppose that we remove line 9 of Block-Reduce and run the layer normalization by the sum of squares. This kernel calls Block-Reduce twice in a row, once for \(\sum x\) and once for \(\sum x^2\), and both calls use the same 8 slots. Between the 2 calls, a warp does almost nothing, only 1 division and 5 shuffles. A fast warp can therefore leave the first call, finish the shuffles of the second, and write its sum of squares into its slot while a slow warp is still reading the sums of the first call.
Figure 23.15 follows this sequence of events on row 94 of the test matrix of Section 23.7, whose 4,096 values lie between 999 and 1,001. Each warp holds 512 values, so the sums in the slots are near 512,000, and the sums of squares are near \(5.12 \times 10^8\). Suppose that warp 5 finishes reading the 8 sums early and writes its sum of squares, 511,965,734, into slot 5, while warp 0 has read only slots 0 to 4. Warp 0 then adds 511,965,734 instead of 511,982.8, and it obtains the sum 515,549,697 instead of 4,095,945. Its mean is therefore \(515{,}549{,}697 / 4{,}096 = 125{,}866.6\) instead of 999.99, its variance \(999{,}973.7 - 125{,}866.6^2\) is negative, and its 512 outputs are NaN.
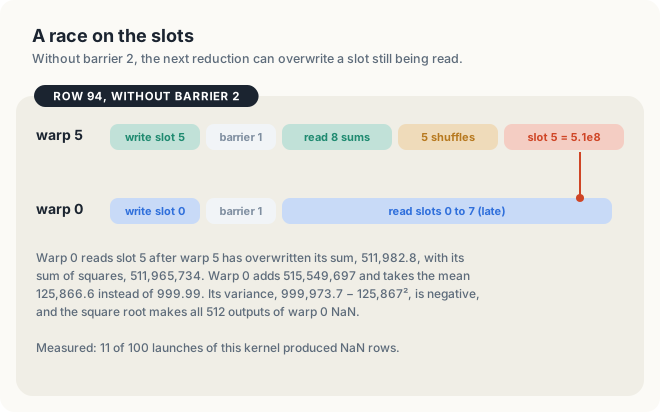
A failure of this kind is called a race, because the result depends on the relative speed of the warps. On most launches, the slow warp finishes reading in time, and the result is correct. We ran the kernel without barrier 2 on the 4,096 rows of the test 100 times and compared every row with a reference. The program printed the following summary.
first bad row 94 error NaN
layernorm sum of squares: 11 of 100 runs wrong, 12 rows
In 11 of the 100 launches, at least 1 row was NaN, 12 rows in all, and the first wrong row of the first failing launch was row 94. The other 89 launches were correct. A race is therefore hard to find, since a test that runs the kernel once passes 9 times in 10. On the example, \(X\), the race cannot change the output at all. Only warp 0 of each block holds values, and the other warps write sums of 0, which do not change any total (Exercise 23.13).
23.5.2 The empty state
We now restore barrier 2 and remove instead lines 2 to 4 of Merge-Softmax, the test for 2 empty states. On rows of 4,096 values, every thread holds 16 values, so no state is empty, and every result is still correct. On \(X\), however, threads 4 to 255 of each block hold the empty state \((-\infty, 0)\). In the first step of the butterfly, lane 4 merges with lane 20, and both of them are empty. The merge computes \(m = -\infty\) and \(s = 0 \cdot e^{-\infty - (-\infty)} + 0 \cdot e^{-\infty - (-\infty)}\). The difference \(-\infty - (-\infty)\) is NaN, so \(s\) is NaN. Every later merge that includes lane 4 inherits the NaN, and after the 5 steps, every lane of warp 0 holds \(s = \text{NaN}\). The program, run with the test removed, prints the following rows.
softmax, online, X
NaN NaN NaN NaN
NaN NaN NaN NaN
Recall that the proof of Theorem 23.4 relied on the merge returning the empty state for 2 empty states. Without line 2, the merge does not do so, and the proof no longer applies. The same holds for Merge-Welford, where 2 empty states would compute \(0 \cdot 0 / 0\).
23.5.3 The kernels are correct
With both safeguards in place, the kernels are correct, and we now prove this for the online softmax. The proof assembles the results of Sections 23.3 and 23.4: each thread computes the state of its own columns, the butterfly merges the states of a warp, and the slots merge the states of the warps.
Theorem 23.7 When Softmax-Online-Kernel finishes, \(p_{\mathsf{row},j}\) is the softmax of row \(\mathsf{row}\) of \(X\) for every row and every \(j \in [0, C)\).
Proof. Fix a block, and let \(\mathsf{row} = \mathsf{blockIdx{.}x}\). By Theorem 23.3 applied to the columns of thread \(\mathsf{threadIdx{.}x}\), after line 4 the state of thread \(\mathsf{threadIdx{.}x}\) describes the set \(S_{\mathsf{threadIdx{.}x}} = \{x_{\mathsf{row},j} : j \equiv \mathsf{threadIdx{.}x} \pmod{\mathsf{blockDim{.}x}}\}\) of the values in the columns whose remainder on division by \(\mathsf{blockDim{.}x}\) is \(\mathsf{threadIdx{.}x}\). This set is empty when \(\mathsf{threadIdx{.}x} \ge C\). For example, in block 1 of \(X\), \(S_2 = \{x_{1,2}\} = \{4\}\), and \(S_7\) is empty. The sets \(S_0, \dots, S_{255}\) are disjoint, and their union is the row. In the butterfly of line 5, each step merges 2 disjoint groups of lanes (Section 23.4.2), so by Theorem 23.4, lane 0 of warp \(\mathsf{warp}\) holds the state of the union of the sets of its 32 threads, after the 5 steps. The merge is defined even for 2 empty states, because of line 2 of Merge-Softmax. Lane 0 writes it to slot \(\mathsf{warp}\). Because of barrier 1, every slot is written before any thread reads it, so every thread merges the 8 states of the 8 warps, which by Theorem 23.4 is the state \((m, s)\) of the whole row. The slots are not written again in this kernel, so no barrier 2 is needed. Lines 6 to 8 then compute \(e^{x_{\mathsf{row},j} - m} / s\) for the thread’s columns, which is the softmax by Theorem 23.1, and the columns of the 256 threads cover the row. Different blocks touch different rows, so they do not interfere.
The same argument, with Theorems 23.5 and 23.6 in place of Theorems 23.3 and 23.4, proves the Welford kernel. For a kernel that calls Block-Reduce twice with the same slots, the proof needs 1 more fact, namely that no slot is written by the second call before every thread has read it in the first. Barrier 2 provides this fact, and it is exactly the barrier that we removed in Section 23.5.1.
Rule Between the last read of a shared slot and the next write to it, place a barrier that every thread of the block reaches.
Exercises
23.13 Explain why removing barrier 2 can never change the outputs for \(X\), where only warp 0
of each block holds values.
23.14 In the fused softmax, Block-Reduce is called with \(\max\) and then
with \(+\). Describe an interleaving without barrier 2 that gives a wrong maximum, and the effect
on the outputs.
23.15 Why does the online kernel of Section 23.4.4 not need barrier 2, while the 3-pass kernel
does?
23.6 Implementation
23.6.1 Warp and block reductions
We now turn the procedures of Section 23.4 into code, beginning with the reductions that every
kernel uses. The following code implements the butterfly, lines 1 to 3 of
Block-Reduce, twice: warp_max uses \(\max\) as the merge, and
warp_sum uses \(+\).
mod kernels {
// ...
#[device]
fn warp_max(mut value: f32) -> f32 {
let mut mask = 16;
while mask > 0 {
value = value.max(warp::shuffle_xor_f32(value, mask));
mask /= 2;
}
value
}
#[device]
fn warp_sum(mut value: f32) -> f32 {
let mut mask = 16;
while mask > 0 {
value += warp::shuffle_xor_f32(value, mask);
mask /= 2;
}
value
}
// ...
}__device__ float warpMax(float value)
{
for (int mask = 16; mask > 0; mask /= 2) {
value = fmaxf(value, __shfl_xor_sync(0xffffffff, value, mask));
}
return value;
}
__device__ float warpSum(float value)
{
for (int mask = 16; mask > 0; mask /= 2) {
value += __shfl_xor_sync(0xffffffff, value, mask);
}
return value;
}
The loop runs for the masks 16, 8, 4, 2 and 1, halving the mask after each step. In Rust, it is a
while loop, which is the form of device loop that cuda-oxide compiles (Section 9.7), and
warp::shuffle_xor_f32 is the xor shuffle. In C++, __shfl_xor_sync takes a first argument,
0xffffffff, whose 32 bits name the 32 lanes that take part, and all of them must execute the
call. Both f32::max and fmaxf return the larger of 2 floats.
The following code implements the whole of Block-Reduce for the maximum. It calls the warp maximum and then adds lines 4 to 10 of the procedure.
mod kernels {
// ...
/// The maximum over the block, returned to every thread. `slots` holds 8 floats.
#[device]
fn block_max(value: f32, slots: *mut f32) -> f32 {
let value = warp_max(value);
let warp = thread::threadIdx_x() as usize / 32;
if warp::lane_id() == 0 {
// SAFETY: lane 0 of each warp writes its own slot, before the barrier.
unsafe { *slots.add(warp) = value };
}
thread::sync_threads();
// SAFETY: between the 2 barriers the slots are only read.
let mut largest = unsafe { *slots };
let mut other = 1;
while other < WARPS {
largest = largest.max(unsafe { *slots.add(other) });
other += 1;
}
thread::sync_threads();
largest
}
// ...
}// The maximum over the block, returned to every thread. `slots` holds 8 floats.
__device__ float blockMax(float value, float* slots)
{
value = warpMax(value);
int warp = threadIdx.x / 32;
if (threadIdx.x % 32 == 0) {
slots[warp] = value;
}
__syncthreads();
float largest = slots[0];
for (int other = 1; other < WARPS; ++other) {
largest = fmaxf(largest, slots[other]);
}
__syncthreads();
return largest;
}
The correspondence with the procedure is direct. Lane 0 writes the slot of its warp, the first
call to sync_threads is barrier 1, the loop over other is line 8, and the second call to
sync_threads is barrier 2. Both barriers sit outside every if, so every thread of the block
reaches them. The function block_sum differs only in the merge. The two languages differ, however,
in where the slots live. A cuda-oxide #[device] function cannot declare shared memory of its
own, so each kernel declares static mut SLOTS: SharedArray<f32, 8> and passes a raw pointer to
the helper. Every access through the pointer is unsafe, with a // SAFETY: comment that names
the threads that touch the slots and the barriers between which they do so. The C++ helper
receives the same pointer from a __shared__ array of its kernel and needs no such annotation.
23.6.2 The 3-pass kernel
The following kernel implements Softmax-3-Pass with one block per row.
mod kernels {
// ...
/// 3 passes over the row: the maximum, the sum of exp(x - max), the outputs.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn softmax_three_pass(input: &[f32], mut out: DisjointSlice<f32>, cols: u32) {
static mut SLOTS: SharedArray<f32, 8> = SharedArray::UNINIT;
// SAFETY: the pointer is only used by the block helpers, between barriers.
let slots = unsafe { (*&raw mut SLOTS).as_mut_ptr() };
let base = thread::blockIdx_x() as usize * cols as usize;
let tid = thread::threadIdx_x() as usize;
let mut largest = f32::NEG_INFINITY;
let mut column = tid;
while column < cols as usize {
largest = largest.max(input[base + column]);
column += BLOCK as usize;
}
let top = block_max(largest, slots);
let mut sum = 0.0;
let mut column = tid;
while column < cols as usize {
sum += (input[base + column] - top).exp();
column += BLOCK as usize;
}
let total = block_sum(sum, slots);
let mut column = tid;
while column < cols as usize {
let probability = (input[base + column] - top).exp() / total;
// SAFETY: each block writes only its own row, and each thread only its own
// columns threadIdx.x, threadIdx.x + 256, ...
unsafe { *out.get_unchecked_mut(base + column) = probability };
column += BLOCK as usize;
}
}
// ...
}// 3 passes over the row: the maximum, the sum of exp(x - max), the outputs.
__global__ void softmaxThreePass(const float* in, float* out, int cols)
{
__shared__ float slots[WARPS];
const float* row = in + (size_t)blockIdx.x * cols;
float* result = out + (size_t)blockIdx.x * cols;
float largest = -INFINITY;
for (int column = threadIdx.x; column < cols; column += BLOCK) {
largest = fmaxf(largest, row[column]);
}
float top = blockMax(largest, slots);
float sum = 0.0f;
for (int column = threadIdx.x; column < cols; column += BLOCK) {
sum += expf(row[column] - top);
}
float total = blockSum(sum, slots);
for (int column = threadIdx.x; column < cols; column += BLOCK) {
result[column] = expf(row[column] - top) / total;
}
}
Block \(\mathsf{blockIdx{.}x}\) starts at element base = blockIdx.x × cols of the matrix, which is
the row-major position of its row; for row 1 of \(X\), base is \(1 \cdot 4 = 4\). Each of the 3 loops starts at
column tid and advances by BLOCK, the pattern of Figure 23.11. The 3 loops are the 3 passes of
Softmax-3-Pass, with block_max and block_sum between them. The kernel
works for any row length, including the 4 of \(X\).
The Rust kernel writes through a DisjointSlice<f32>, the output type of Chapter 13, whose safe
method lets each thread write only the element at its own global index. Here, however, thread
\(\mathsf{threadIdx{.}x}\) of block \(\mathsf{blockIdx{.}x}\) writes the elements
\(\mathsf{blockIdx{.}x} \cdot C + \mathsf{threadIdx{.}x} + 256 \cdot \mathsf{step}\) for
\(\mathsf{step} = 0, 1, \dots\).
No other thread writes these elements, but they are not the thread’s global index, so the kernel
calls get_unchecked_mut and states this argument in the SAFETY comment. The C++ kernel writes
through a plain pointer. The attribute #[launch_contract(domain = 1, block = (256, 1, 1))] records
that the kernel expects 1-dimensional blocks of 256 threads, and the host’s
prepare_softmax_three_pass checks a launch configuration against it before the first launch. The
Rust kernel also reads through a slice, input[base + j], and every such read is checked against
the slice length. In Section 23.7.5, we measure what these checks cost.
23.6.3 The online kernel
The following code shows the merge of 2 softmax states and the kernel Softmax-Online-Kernel that uses it.
mod kernels {
// ...
/// Merges 2 softmax states (maximum m, sum of exp(x - m)); (-inf, 0) is empty.
#[device]
fn merge_softmax(
largest: f32,
sum: f32,
other_largest: f32,
other_sum: f32,
) -> (f32, f32) {
let top = largest.max(other_largest);
if top == f32::NEG_INFINITY {
return (top, 0.0);
}
let first_part = sum * (largest - top).exp();
let second_part = other_sum * (other_largest - top).exp();
(top, first_part + second_part)
}
// ...
}
mod kernels {
// ...
/// 2 passes: a running maximum and a rescaled running sum, then the outputs.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn softmax_online(input: &[f32], mut out: DisjointSlice<f32>, cols: u32) {
static mut MAXES: SharedArray<f32, 8> = SharedArray::UNINIT;
static mut SUMS: SharedArray<f32, 8> = SharedArray::UNINIT;
let base = thread::blockIdx_x() as usize * cols as usize;
let tid = thread::threadIdx_x() as usize;
let mut largest = f32::NEG_INFINITY;
let mut sum = 0.0;
let mut column = tid;
while column < cols as usize {
let value = input[base + column];
if value > largest {
sum = sum * (largest - value).exp() + 1.0;
largest = value;
} else {
sum += (value - largest).exp();
}
column += BLOCK as usize;
}
let mut mask = 16;
while mask > 0 {
let m2 = warp::shuffle_xor_f32(largest, mask);
let s2 = warp::shuffle_xor_f32(sum, mask);
(largest, sum) = merge_softmax(largest, sum, m2, s2);
mask /= 2;
}
let warp = tid / 32;
if warp::lane_id() == 0 {
// SAFETY: lane 0 of each warp writes its own slots, before the barrier.
unsafe {
MAXES[warp] = largest;
SUMS[warp] = sum;
}
}
thread::sync_threads();
// SAFETY: after the barrier the slots are only read.
let (mut top, mut total) = unsafe { (MAXES[0], SUMS[0]) };
let mut other = 1;
while other < WARPS {
(top, total) = unsafe { merge_softmax(top, total, MAXES[other], SUMS[other]) };
other += 1;
}
let mut column = tid;
while column < cols as usize {
let probability = (input[base + column] - top).exp() / total;
// SAFETY: each block writes only its own row, and each thread only its own
// columns threadIdx.x, threadIdx.x + 256, ...
unsafe { *out.get_unchecked_mut(base + column) = probability };
column += BLOCK as usize;
}
}
// ...
}// A softmax state: the maximum m and the sum s of exp(x - m). (-inf, 0) is the empty state.
struct SoftmaxState {
float largest; // m
float sum; // s
};
__device__ SoftmaxState mergeSoftmax(SoftmaxState first, SoftmaxState second)
{
float top = fmaxf(first.largest, second.largest);
if (top == -INFINITY) {
return {top, 0.0f};
}
float firstPart = first.sum * expf(first.largest - top);
float secondPart = second.sum * expf(second.largest - top);
return {top, firstPart + secondPart};
}
// 2 passes: a running maximum and a rescaled running sum, then the outputs.
__global__ void softmaxOnline(const float* in, float* out, int cols)
{
__shared__ SoftmaxState slots[WARPS];
const float* row = in + (size_t)blockIdx.x * cols;
float* result = out + (size_t)blockIdx.x * cols;
SoftmaxState state = {-INFINITY, 0.0f};
for (int column = threadIdx.x; column < cols; column += BLOCK) {
float value = row[column];
if (value > state.largest) {
state.sum = state.sum * expf(state.largest - value) + 1.0f;
state.largest = value;
} else {
state.sum += expf(value - state.largest);
}
}
for (int mask = 16; mask > 0; mask /= 2) {
SoftmaxState other;
other.largest = __shfl_xor_sync(0xffffffff, state.largest, mask);
other.sum = __shfl_xor_sync(0xffffffff, state.sum, mask);
state = mergeSoftmax(state, other);
}
if (threadIdx.x % 32 == 0) {
slots[threadIdx.x / 32] = state;
}
__syncthreads();
SoftmaxState all = slots[0];
for (int other = 1; other < WARPS; ++other) {
all = mergeSoftmax(all, slots[other]);
}
for (int column = threadIdx.x; column < cols; column += BLOCK) {
result[column] = expf(row[column] - all.largest) / all.sum;
}
}
The function merge_softmax is Merge-Softmax, including the test for 2
empty states that we removed in Section 23.5.2. The first loop of the kernel is lines 1 to 4 of
Softmax-Online-Kernel, and its if and else branches are lines 3 to 8
of Online-Softmax. The butterfly shuffles both numbers of the state in each
step. Lane 0 of each warp then writes its state to 2 slots, and after the barrier, every thread
merges the 8 states. The final loop is lines 6 to 8. In Rust, the state is 2 local variables
updated by a destructuring assignment, (m, s) = merge_softmax(m, s, m2, s2). In C++, it is a
struct with 2 members, and the slots are an array of that struct.
23.6.4 Welford’s kernel
The following code shows the merge of 2 Welford states and the layer-normalization kernel built on Welford-Update.
mod kernels {
// ...
/// Merges 2 Welford states (count n, mean, sum of squared deviations q).
#[device]
fn merge_welford(first: (f32, f32, f32), second: (f32, f32, f32)) -> (f32, f32, f32) {
let count = first.0 + second.0;
if count == 0.0 {
return first;
}
let delta = second.1 - first.1;
let mean = first.1 + delta * second.0 / count;
let between = delta * delta * first.0 * second.0 / count;
(count, mean, first.2 + second.2 + between)
}
// ...
}
mod kernels {
// ...
/// Layer norm with Welford's running mean and squared deviations, merged per block.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn layernorm_welford(
input: &[f32],
gamma: &[f32],
beta: &[f32],
mut out: DisjointSlice<f32>,
cols: u32,
) {
static mut STATE: SharedArray<f32, 24> = SharedArray::UNINIT;
let base = thread::blockIdx_x() as usize * cols as usize;
let tid = thread::threadIdx_x() as usize;
let mut state = (0.0f32, 0.0f32, 0.0f32);
let mut column = tid;
while column < cols as usize {
let value = input[base + column];
let count = state.0 + 1.0;
let delta = value - state.1;
let mean = state.1 + delta / count;
state = (count, mean, state.2 + delta * (value - mean));
column += BLOCK as usize;
}
let mut mask = 16;
while mask > 0 {
let other = (
warp::shuffle_xor_f32(state.0, mask),
warp::shuffle_xor_f32(state.1, mask),
warp::shuffle_xor_f32(state.2, mask),
);
state = merge_welford(state, other);
mask /= 2;
}
let warp = tid / 32;
if warp::lane_id() == 0 {
// SAFETY: lane 0 of each warp writes its own 3 slots, before the barrier.
unsafe {
STATE[3 * warp] = state.0;
STATE[3 * warp + 1] = state.1;
STATE[3 * warp + 2] = state.2;
}
}
thread::sync_threads();
// SAFETY: after the barrier the slots are only read.
let mut all = unsafe { (STATE[0], STATE[1], STATE[2]) };
let mut other = 1;
while other < WARPS {
let slot = 3 * other;
let next = unsafe { (STATE[slot], STATE[slot + 1], STATE[slot + 2]) };
all = merge_welford(all, next);
other += 1;
}
let mean = all.1;
let inverse_std = 1.0 / (all.2 / cols as f32 + EPS).sqrt();
let mut column = tid;
while column < cols as usize {
let scaled = (input[base + column] - mean) * inverse_std;
let normalized = scaled * gamma[column] + beta[column];
// SAFETY: each block writes only its own row, and each thread only its own
// columns threadIdx.x, threadIdx.x + 256, ...
unsafe { *out.get_unchecked_mut(base + column) = normalized };
column += BLOCK as usize;
}
}
// ...
}// A Welford state: the count n, the mean, and the sum q of squared deviations.
struct WelfordState {
float count; // n
float mean;
float squares; // q
};
__device__ WelfordState mergeWelford(WelfordState first, WelfordState second)
{
float count = first.count + second.count;
if (count == 0.0f) {
return first;
}
float delta = second.mean - first.mean;
float mean = first.mean + delta * second.count / count;
float between = delta * delta * first.count * second.count / count;
return {count, mean, first.squares + second.squares + between};
}
// Layer norm with Welford's running mean and squared deviations, merged per block.
__global__ void layernormWelford(const float* in, const float* gamma, const float* beta,
float* out, int cols)
{
__shared__ WelfordState slots[WARPS];
const float* row = in + (size_t)blockIdx.x * cols;
float* result = out + (size_t)blockIdx.x * cols;
WelfordState state = {0.0f, 0.0f, 0.0f};
for (int column = threadIdx.x; column < cols; column += BLOCK) {
float value = row[column];
state.count += 1.0f;
float delta = value - state.mean;
state.mean += delta / state.count;
state.squares += delta * (value - state.mean);
}
for (int mask = 16; mask > 0; mask /= 2) {
WelfordState other;
other.count = __shfl_xor_sync(0xffffffff, state.count, mask);
other.mean = __shfl_xor_sync(0xffffffff, state.mean, mask);
other.squares = __shfl_xor_sync(0xffffffff, state.squares, mask);
state = mergeWelford(state, other);
}
if (threadIdx.x % 32 == 0) {
slots[threadIdx.x / 32] = state;
}
__syncthreads();
WelfordState all = slots[0];
for (int other = 1; other < WARPS; ++other) {
all = mergeWelford(all, slots[other]);
}
float inverseStd = 1.0f / sqrtf(all.squares / cols + EPS);
for (int column = threadIdx.x; column < cols; column += BLOCK) {
float normalized = (row[column] - all.mean) * inverseStd;
result[column] = normalized * gamma[column] + beta[column];
}
}
The first loop applies Welford-Update to the thread’s columns, and its 4
lines are the 4 lines of the procedure. The state holds the count as a float, so that
all 3 numbers can be shuffled with the same instruction. This is safe, because counts up to
\(2^{24}\) are exact in f32. After the warp merge, lane 0 writes 3 numbers. In Rust, they
occupy 3 consecutive slots of a SharedArray<f32, 24>, and in C++, 1 slot of an array of
WelfordState. The variance of the row is \(q / C\), and inverseStd (inverse_std in Rust),
the reciprocal of the standard
deviation, is \(1 / \sqrt{q / C + \varepsilon}\). For row 0 of \(X\), inverseStd is
\(1 / \sqrt{5 / 4 + 10^{-5}} = 0.8944\), the factor of Figure 23.3.
23.6.5 The fused kernels
The following code implements Softmax-Fused-Kernel, which keeps the 16 values of each thread in registers.
mod kernels {
// ...
/// 1 read: each thread keeps its 16 values of the row in registers.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn softmax_fused(input: &[f32], mut out: DisjointSlice<f32>) {
static mut SLOTS: SharedArray<f32, 8> = SharedArray::UNINIT;
// SAFETY: the pointer is only used by the block helpers, between barriers.
let slots = unsafe { (*&raw mut SLOTS).as_mut_ptr() };
let base = thread::blockIdx_x() as usize * COLS;
let tid = thread::threadIdx_x() as usize;
let mut kept = [0.0f32; PER_THREAD];
let mut largest = f32::NEG_INFINITY;
let mut index = 0;
#[unroll]
while index < PER_THREAD {
kept[index] = input[base + index * BLOCK as usize + tid];
largest = largest.max(kept[index]);
index += 1;
}
let top = block_max(largest, slots);
let mut sum = 0.0;
let mut index = 0;
#[unroll]
while index < PER_THREAD {
kept[index] = (kept[index] - top).exp();
sum += kept[index];
index += 1;
}
let scale = 1.0 / block_sum(sum, slots);
let mut index = 0;
#[unroll]
while index < PER_THREAD {
let column = index * BLOCK as usize + tid;
// SAFETY: each block writes only its own row, and each thread only its own
// columns threadIdx.x, threadIdx.x + 256, ...
unsafe { *out.get_unchecked_mut(base + column) = kept[index] * scale };
index += 1;
}
}
// ...
}// 1 read: each thread keeps its 16 values of the row in registers.
__global__ void softmaxFused(const float* in, float* out)
{
__shared__ float slots[WARPS];
const float* row = in + (size_t)blockIdx.x * COLS;
float* result = out + (size_t)blockIdx.x * COLS;
float kept[PER_THREAD];
float largest = -INFINITY;
#pragma unroll
for (int index = 0; index < PER_THREAD; ++index) {
kept[index] = row[index * BLOCK + threadIdx.x];
largest = fmaxf(largest, kept[index]);
}
float top = blockMax(largest, slots);
float sum = 0.0f;
#pragma unroll
for (int index = 0; index < PER_THREAD; ++index) {
kept[index] = expf(kept[index] - top);
sum += kept[index];
}
float scale = 1.0f / blockSum(sum, slots);
#pragma unroll
for (int index = 0; index < PER_THREAD; ++index) {
result[index * BLOCK + threadIdx.x] = kept[index] * scale;
}
}
The 3 loops are lines 1 to 3, 5 to 7 and 9 to 11 of Softmax-Fused-Kernel.
The array kept of PER_THREAD = COLS / 256 = 16 values has a size fixed at compile time, and this
is why the row length is the constant COLS = 4096 and not an argument. Each loop has a constant
trip count and is fully unrolled, so that every kept[index] names a fixed register. In Rust, the loop is
a while loop marked #[unroll]; in Section 9.7, we found this form necessary for cuda-oxide to
keep a small array in registers. In C++, it is a for loop under #pragma unroll. The fused layer
normalization in the complete programs has the same 3 loops, which compute the mean, the squared
deviations and the outputs.
23.6.6 The host program
The host program first runs the kernels on \(X\), \(X + 100\) and \(X + 10{,}000\). The following code prepares the launches and runs them on the 2 rows of the example.
fn main() -> Result<(), Error> {
// ...
let two_rows = LaunchConfig1D::new(2, BLOCK, 0);
let naive_two = module.prepare_softmax_naive(two_rows)?;
let three_two = module.prepare_softmax_three_pass(two_rows)?;
let online_two = module.prepare_softmax_online(two_rows)?;
let sq_two = module.prepare_layernorm_naive(two_rows)?;
let welford_two = module.prepare_layernorm_welford(two_rows)?;
println!("the 2 x 4 example X = [1 2 3 4; 2 4 4 5]");
module.softmax_naive(&stream, &naive_two, &small, &mut out, 4)?;
print_matrix("softmax without the maximum, X", &out.to_host_vec(&stream)?, 4);
module.softmax_naive(&stream, &naive_two, &shifted, &mut out, 4)?;
let naive_big = out.to_host_vec(&stream)?;
print_matrix("softmax without the maximum, X + 100", &naive_big, 4);
module.softmax_three_pass(&stream, &three_two, &small, &mut out, 4)?;
let three_x = out.to_host_vec(&stream)?;
print_matrix("softmax, 3 passes, X", &three_x, 4);
module.softmax_three_pass(&stream, &three_two, &shifted, &mut out, 4)?;
let three_big = out.to_host_vec(&stream)?;
print_matrix("softmax, 3 passes, X + 100", &three_big, 4);
module.softmax_online(&stream, &online_two, &small, &mut out, 4)?;
let online_x = out.to_host_vec(&stream)?;
print_matrix("softmax, online, X", &online_x, 4);
// ...
}int main()
{
// ...
std::printf("the 2 x 4 example X = [1 2 3 4; 2 4 4 5]\n");
softmaxNaive<<<2, BLOCK>>>(small, o, 4);
printMatrix("softmax without the maximum, X", toHost(o, 8), 4);
softmaxNaive<<<2, BLOCK>>>(shifted, o, 4);
std::vector<float> naiveBig = toHost(o, 8);
printMatrix("softmax without the maximum, X + 100", naiveBig, 4);
softmaxThreePass<<<2, BLOCK>>>(small, o, 4);
std::vector<float> threeX = toHost(o, 8);
printMatrix("softmax, 3 passes, X", threeX, 4);
softmaxThreePass<<<2, BLOCK>>>(shifted, o, 4);
std::vector<float> threeBig = toHost(o, 8);
printMatrix("softmax, 3 passes, X + 100", threeBig, 4);
softmaxOnline<<<2, BLOCK>>>(small, o, 4);
std::vector<float> onlineX = toHost(o, 8);
printMatrix("softmax, online, X", onlineX, 4);
// ...
}
A launch configuration of 2 blocks of 256 threads covers the 2 rows. In Rust, each
prepare_<kernel> call checks the configuration against the kernel’s launch contract once, and the
launches that follow use the prepared configuration. In C++, the launch is written
softmaxThreePass<<<2, BLOCK>>>(...). For the example, the program prints the following output.
$ cargo oxide run
the 2 x 4 example X = [1 2 3 4; 2 4 4 5]
softmax without the maximum, X
0.0321 0.0871 0.2369 0.6439
0.0279 0.2060 0.2060 0.5601
softmax without the maximum, X + 100
NaN NaN NaN NaN
NaN NaN NaN NaN
softmax, 3 passes, X
0.0321 0.0871 0.2369 0.6439
0.0279 0.2060 0.2060 0.5601
softmax, 3 passes, X + 100
0.0321 0.0871 0.2369 0.6439
0.0279 0.2060 0.2060 0.5601
softmax, online, X
0.0321 0.0871 0.2369 0.6439
0.0279 0.2060 0.2060 0.5601
layer norm, sum of squares, X
-1.3416 -0.4472 0.4472 1.3416
-1.6059 0.2294 0.2294 1.1471
layer norm, sum of squares, X + 10000
NaN NaN NaN NaN
NaN NaN NaN NaN
layer norm, Welford, X + 10000
-1.3416 -0.4472 0.4472 1.3416
-1.6059 0.2294 0.2294 1.1471
Every line matches a hand computation of this chapter. Without the maximum, \(X\) gives the
\(P\) of Figure 23.1, and \(X + 100\) gives NaN, as in Figure 23.4. With the maximum, \(X\)
and \(X + 100\) give the same \(P\), as Theorem 23.1 states. The sum of squares gives \(Y\)
for \(X\) and NaN for \(X + 10{,}000\), as in Figure 23.6, and Welford’s method gives \(Y\)
for both. The program compares each of these results with a softmax and a layer normalization
computed in f64 on the CPU, and it requires the NaNs where the analysis predicts them.
For the timed runs, a kernel takes about 2 ms, which is too short to time a single launch
reliably. The function time_ms, shown below, therefore runs the kernel 100 times first, so that
the GPU raises its clock. It then times 7 batches of 20 launches each and returns the median batch
time divided by 20.
/// Time of 1 run of `launch`, in milliseconds: the median of 7 batches of 20 runs,
/// after 100 warm-up runs.
fn time_ms(
stream: &Arc<CudaStream>,
mut launch: impl FnMut() -> Result<(), Error>,
) -> Result<f64, Error> {
for _ in 0..100 {
launch()?;
}
stream.synchronize()?;
let mut batches = Vec::new();
for _ in 0..7 {
let start = Instant::now();
for _ in 0..20 {
launch()?;
}
stream.synchronize()?;
batches.push(start.elapsed().as_secs_f64() * 1e3 / 20.0);
}
batches.sort_by(f64::total_cmp);
Ok(batches[3])
}// Time of 1 run of `launch`, in milliseconds: the median of 7 batches of 20 runs,
// after 100 warm-up runs.
template <typename F>
double timeMs(F launch)
{
for (int warmup = 0; warmup < 100; ++warmup) {
launch();
}
check(cudaDeviceSynchronize());
std::vector<double> batches;
for (int batch = 0; batch < 7; ++batch) {
double start = nowMs();
for (int timed = 0; timed < 20; ++timed) {
launch();
}
check(cudaGetLastError());
check(cudaDeviceSynchronize());
batches.push_back((nowMs() - start) / 20);
}
std::sort(batches.begin(), batches.end());
return batches[3];
}
Exercises
23.16 block_sum in Rust starts its loop over the slots at w = 0 with s = 0.0, while
block_max starts at w = 1 with the value of slot 0. Why can block_max not start from
m = 0.0?
23.17 Change ROWS and COLS to 16,384 rows of 1,024 columns. Which constant must change for the
fused kernels to stay correct?
23.7 Measurements
23.7.1 Platform and method
The measurements come from a Jetson Orin NX 16 GB, an integrated GPU with 8 SMs, 102 GB/s of
memory bandwidth and 2 MiB of L2 cache. The test matrices have 4,096 rows of 4,096 f32 values,
which is 64 MiB, far larger than the L2 cache. The softmax inputs are uniform in \([-10, 10)\).
The layer-normalization inputs are uniform in \([999, 1001)\), so that their mean is large
compared with their spread, and they use a different \(\gamma_j\) and \(\beta_j\) for each
column. The same softmax inputs are also arranged as 256 rows of 65,536 values. Each time is the
median of 7 batches of 20 launches. Repeated runs differ by up to 10%, and we quote 1 run of 3,
made with no other work on the GPU or the memory.
23.7.2 Results
After the example, the Rust program printed the following results.
softmax of 4096 rows x 4096 columns, median of 7 x 20 runs
kernel bytes/elem ms GB/s max error
3 passes 16 2.025 132.6 1.37e-9
online 12 2.255 89.3 1.36e-9
fused 8 1.435 93.6 1.37e-9
softmax of 256 rows x 65536 columns, median of 7 x 20 runs
kernel bytes/elem ms GB/s max error
3 passes 16 3.985 67.4 1.22e-10
online 12 3.015 66.8 1.18e-10
layer norm of 4096 rows x 4096 columns, values 1,000 + [-1, 1)
kernel bytes/elem ms GB/s max error
sum, sum x2 12 1.808 111.3 2.97e0
Welford 12 2.112 95.3 1.88e-4
fused 8 1.424 94.3 1.81e-4
PASSED
The GB/s column divides the modeled bytes of Section 23.4.5 by the measured time. For example,
the fused softmax moves \(8 \cdot 4{,}096^2\) bytes, 134 MB, in 1.435 ms, which gives 93.6 GB/s.
The following table collects the times of both programs, together with those of the Rust program
built with cargo oxide run --unchecked-indexing, an option that we explain in Section 23.7.5.
| Kernel | Bytes per element | Rust (ms) | Rust, unchecked (ms) | C++ (ms) | C++, modeled (GB/s) |
|---|---|---|---|---|---|
| softmax, 3 passes | 16 | 2.025 | 1.684 | 1.434 | 187.2 |
| softmax, online | 12 | 2.255 | 1.545 | 1.480 | 136.1 |
| softmax, fused | 8 | 1.435 | 1.446 | 1.417 | 94.8 |
| softmax, 3 passes, rows of 65,536 | 16 | 3.985 | 3.088 | 3.129 | 85.8 |
| softmax, online, rows of 65,536 | 12 | 3.015 | 2.453 | 2.373 | 84.8 |
| layer norm, sum of squares | 12 | 1.808 | 1.433 | 1.464 | 137.5 |
| layer norm, Welford | 12 | 2.112 | 1.902 | 1.920 | 104.9 |
| layer norm, fused | 8 | 1.424 | 1.424 | 1.445 | 92.9 |
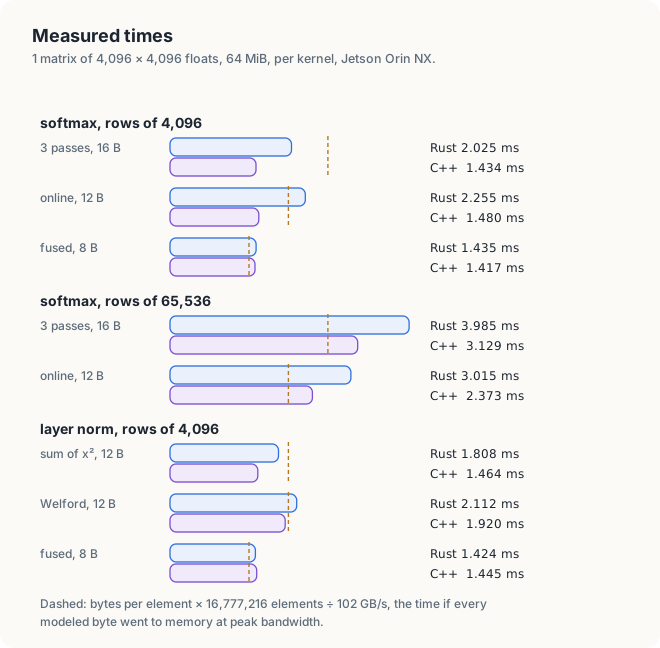
We begin with the fused kernels, which match the model. They move 134 MB in 1.42 to 1.45 ms, that is, at 93 to 95 GB/s, which is 91 to 93% of the 102 GB/s of the memory. This is the fraction that a well-behaved streaming kernel reaches on this GPU. The other numbers need explanations, which we give in the next 4 sections.
23.7.3 Why 3 passes cost no more than 1 on rows of 4,096
The C++ 3-pass softmax takes 1.434 ms, the same time as the fused kernel, although it reads each value 3 times. Its modeled rate, 187.2 GB/s, is 1.8 times the bandwidth of the memory, which would be impossible if every read reached the memory. We conclude that most of its second and third reads were served by the L2 cache.
A simple count confirms this conclusion. An SM of this GPU holds at most 1,536 threads, that is, 6 blocks of 256, so at most \(8 \cdot 6 = 48\) rows are being processed at any moment on the 8 SMs. Each row occupies 16 KiB, so all the rows in progress fit in \(48 \cdot 16 = 768\) KiB, which is less than the 2 MiB of the L2 cache. A row read in pass 1 is therefore still in the cache when passes 2 and 3 read it, and the traffic to the memory is 8 bytes per element, as for the fused kernel. For the same reason, the online kernel saves nothing here, 1.480 ms against 1.434 ms in C++, because the read that it removes was a cache hit.
23.7.4 Rows of 65,536
With rows of 65,536 values, which occupy 256 KiB each, the 48 rows in progress would occupy \(48 \cdot 256\) KiB = 12 MiB, 6 times the size of the L2 cache. A row is then no longer in the cache when the next pass reads it, and every pass reaches the memory. The model of Section 23.4.5 therefore holds. The C++ 3-pass kernel takes 3.129 ms for 268 MB, which is 85.8 GB/s, and the online kernel takes 2.373 ms for 201 MB, which is 84.8 GB/s. The ratio of the 2 times, \(3.129 / 2.373 = 1.32\), is the ratio of their traffic, \(16 / 12 = 1.33\). For long rows, such as those of the output layer of a language model, the online softmax thus saves a quarter of the time. For short rows, the cache had already removed the extra pass.
23.7.5 Bounds checks in the Rust loops
On rows of 4,096 values, the Rust 3-pass and online kernels are 41% and 52% slower than the C++
kernels (2.025 against 1.434 ms, and 2.255 against 1.480 ms), while the fused kernels run at the
same speed in both languages. The difference lies in how the kernels read the row. A Rust kernel
reads input[base + j] from a slice, and every such read compares the index with the slice length
and branches to a trap when the index is out of range. In the fused kernels, the 16 reads are
unrolled and independent of each other, and the checks cost nothing measurable. In the other
kernels, the reads sit in loops whose trip count is known only at run time, and there the checks
are not free.
cuda-oxide can remove the checks. Built with cargo oxide run --unchecked-indexing, the same
program runs the online kernel in 1.545 ms, the long-row kernels in 3.088 and 2.453 ms, and the sum
of squares in 1.433 ms, all within 5% of C++. The 3-pass kernel on short rows improves from 2.025
to 1.684 ms, but it remains 17% slower than C++. The flag makes every out-of-range index
undefined behavior, exactly like get_unchecked, in every kernel of the program. The kernels of
this chapter read only indices \(b \cdot C + j\) with \(b < R\) and \(j < C\), so they stay in
range, but the compiler no longer checks this claim. A per-kernel form,
#[kernel(unchecked_indexing)], limits the trust to the kernels that need the speed.
23.7.6 Welford’s division, and the accuracy
The Welford kernel moves the same 12 bytes per element as the sum of squares, but it takes \(1.920 - 1.464 = 0.456\) ms longer in C++. Since the traffic is the same, the difference must come from computation. Per value, the sum of squares performs 2 additions, 1 of them combined with a multiplication. Welford’s update performs 3 subtractions or additions, 1 combined multiplication and addition, and a division, which a GPU computes with a sequence of several instructions. The kernel is close enough to the memory limit that this extra arithmetic shows in the time. The fused layer normalization avoids both costs, because it moves only 8 bytes per element and computes the variance from registers in 2 inexpensive passes.
The error column shows the cancellation of Section 23.2.5 on the GPU. The sum of squares reaches an
error of 2.97 on outputs whose typical size is 1, so its results are useless, although it runs at
the same speed as the correct kernels. Welford’s method and the fused kernel stay within
\(1.9 \times 10^{-4}\) of the f64 reference. This remaining error has a definite source. The
values lie near 1,000, where f32 numbers are \(6.1 \times 10^{-5}\) apart, so the mean is exact
only to a few times this spacing. Dividing by the standard deviation, \(\sqrt{0.33} = 0.58\),
multiplies the error by 1.7. The softmax errors, about \(10^{-9}\) on probabilities near
\(2.4 \times 10^{-4}\), are at the level of f32 rounding.
Exercises
23.18 With 4 bytes per value and 102 GB/s, how long must the fused layer normalization take at
least for 16,384 rows of 1,024 values? Would the 3-pass softmax be served by the L2 cache at that
row length?
23.19 Estimate the times of the 3-pass and online softmax for 64 rows of 128,000 values on a GPU
with 3.35 TB/s of memory bandwidth and 50 MB of L2 cache.
23.8 The complete programs
//! Chapter 23: softmax and layer normalization of the rows of a matrix, in cuda-oxide.
//!
//! cargo oxide run
use std::sync::Arc;
use std::time::Instant;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, LaunchConfig1D};
use cuda_device::{DisjointSlice, SharedArray, cuda_module, device, kernel, launch_contract};
use cuda_device::{thread, warp};
const BLOCK: u32 = 256;
const WARPS: usize = BLOCK as usize / 32;
const ROWS: usize = 4096;
const COLS: usize = 4096;
const PER_THREAD: usize = COLS / BLOCK as usize;
const EPS: f32 = 1e-5;
type Error = Box<dyn std::error::Error>;
#[cuda_module]
mod kernels {
use super::*;
#[device]
fn warp_max(mut value: f32) -> f32 {
let mut mask = 16;
while mask > 0 {
value = value.max(warp::shuffle_xor_f32(value, mask));
mask /= 2;
}
value
}
#[device]
fn warp_sum(mut value: f32) -> f32 {
let mut mask = 16;
while mask > 0 {
value += warp::shuffle_xor_f32(value, mask);
mask /= 2;
}
value
}
/// The maximum over the block, returned to every thread. `slots` holds 8 floats.
#[device]
fn block_max(value: f32, slots: *mut f32) -> f32 {
let value = warp_max(value);
let warp = thread::threadIdx_x() as usize / 32;
if warp::lane_id() == 0 {
// SAFETY: lane 0 of each warp writes its own slot, before the barrier.
unsafe { *slots.add(warp) = value };
}
thread::sync_threads();
// SAFETY: between the 2 barriers the slots are only read.
let mut largest = unsafe { *slots };
let mut other = 1;
while other < WARPS {
largest = largest.max(unsafe { *slots.add(other) });
other += 1;
}
thread::sync_threads();
largest
}
/// The sum over the block, returned to every thread. `slots` holds 8 floats.
#[device]
fn block_sum(value: f32, slots: *mut f32) -> f32 {
let value = warp_sum(value);
let warp = thread::threadIdx_x() as usize / 32;
if warp::lane_id() == 0 {
// SAFETY: lane 0 of each warp writes its own slot, before the barrier.
unsafe { *slots.add(warp) = value };
}
thread::sync_threads();
// SAFETY: between the 2 barriers the slots are only read.
let mut sum = 0.0;
let mut other = 0;
while other < WARPS {
sum += unsafe { *slots.add(other) };
other += 1;
}
thread::sync_threads();
sum
}
/// Merges 2 softmax states (maximum m, sum of exp(x - m)); (-inf, 0) is empty.
#[device]
fn merge_softmax(
largest: f32,
sum: f32,
other_largest: f32,
other_sum: f32,
) -> (f32, f32) {
let top = largest.max(other_largest);
if top == f32::NEG_INFINITY {
return (top, 0.0);
}
let first_part = sum * (largest - top).exp();
let second_part = other_sum * (other_largest - top).exp();
(top, first_part + second_part)
}
/// Merges 2 Welford states (count n, mean, sum of squared deviations q).
#[device]
fn merge_welford(first: (f32, f32, f32), second: (f32, f32, f32)) -> (f32, f32, f32) {
let count = first.0 + second.0;
if count == 0.0 {
return first;
}
let delta = second.1 - first.1;
let mean = first.1 + delta * second.0 / count;
let between = delta * delta * first.0 * second.0 / count;
(count, mean, first.2 + second.2 + between)
}
/// Softmax without the maximum: exp(x) / sum of exp(x). Overflows for large x.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn softmax_naive(input: &[f32], mut out: DisjointSlice<f32>, cols: u32) {
static mut SLOTS: SharedArray<f32, 8> = SharedArray::UNINIT;
// SAFETY: the pointer is only used by the block helpers, between barriers.
let slots = unsafe { (*&raw mut SLOTS).as_mut_ptr() };
let base = thread::blockIdx_x() as usize * cols as usize;
let tid = thread::threadIdx_x() as usize;
let mut sum = 0.0;
let mut column = tid;
while column < cols as usize {
sum += input[base + column].exp();
column += BLOCK as usize;
}
let total = block_sum(sum, slots);
let mut column = tid;
while column < cols as usize {
let probability = input[base + column].exp() / total;
// SAFETY: each block writes only its own row, and each thread only its own
// columns threadIdx.x, threadIdx.x + 256, ...
unsafe { *out.get_unchecked_mut(base + column) = probability };
column += BLOCK as usize;
}
}
/// 3 passes over the row: the maximum, the sum of exp(x - max), the outputs.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn softmax_three_pass(input: &[f32], mut out: DisjointSlice<f32>, cols: u32) {
static mut SLOTS: SharedArray<f32, 8> = SharedArray::UNINIT;
// SAFETY: the pointer is only used by the block helpers, between barriers.
let slots = unsafe { (*&raw mut SLOTS).as_mut_ptr() };
let base = thread::blockIdx_x() as usize * cols as usize;
let tid = thread::threadIdx_x() as usize;
let mut largest = f32::NEG_INFINITY;
let mut column = tid;
while column < cols as usize {
largest = largest.max(input[base + column]);
column += BLOCK as usize;
}
let top = block_max(largest, slots);
let mut sum = 0.0;
let mut column = tid;
while column < cols as usize {
sum += (input[base + column] - top).exp();
column += BLOCK as usize;
}
let total = block_sum(sum, slots);
let mut column = tid;
while column < cols as usize {
let probability = (input[base + column] - top).exp() / total;
// SAFETY: each block writes only its own row, and each thread only its own
// columns threadIdx.x, threadIdx.x + 256, ...
unsafe { *out.get_unchecked_mut(base + column) = probability };
column += BLOCK as usize;
}
}
/// 2 passes: a running maximum and a rescaled running sum, then the outputs.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn softmax_online(input: &[f32], mut out: DisjointSlice<f32>, cols: u32) {
static mut MAXES: SharedArray<f32, 8> = SharedArray::UNINIT;
static mut SUMS: SharedArray<f32, 8> = SharedArray::UNINIT;
let base = thread::blockIdx_x() as usize * cols as usize;
let tid = thread::threadIdx_x() as usize;
let mut largest = f32::NEG_INFINITY;
let mut sum = 0.0;
let mut column = tid;
while column < cols as usize {
let value = input[base + column];
if value > largest {
sum = sum * (largest - value).exp() + 1.0;
largest = value;
} else {
sum += (value - largest).exp();
}
column += BLOCK as usize;
}
let mut mask = 16;
while mask > 0 {
let m2 = warp::shuffle_xor_f32(largest, mask);
let s2 = warp::shuffle_xor_f32(sum, mask);
(largest, sum) = merge_softmax(largest, sum, m2, s2);
mask /= 2;
}
let warp = tid / 32;
if warp::lane_id() == 0 {
// SAFETY: lane 0 of each warp writes its own slots, before the barrier.
unsafe {
MAXES[warp] = largest;
SUMS[warp] = sum;
}
}
thread::sync_threads();
// SAFETY: after the barrier the slots are only read.
let (mut top, mut total) = unsafe { (MAXES[0], SUMS[0]) };
let mut other = 1;
while other < WARPS {
(top, total) = unsafe { merge_softmax(top, total, MAXES[other], SUMS[other]) };
other += 1;
}
let mut column = tid;
while column < cols as usize {
let probability = (input[base + column] - top).exp() / total;
// SAFETY: each block writes only its own row, and each thread only its own
// columns threadIdx.x, threadIdx.x + 256, ...
unsafe { *out.get_unchecked_mut(base + column) = probability };
column += BLOCK as usize;
}
}
/// 1 read: each thread keeps its 16 values of the row in registers.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn softmax_fused(input: &[f32], mut out: DisjointSlice<f32>) {
static mut SLOTS: SharedArray<f32, 8> = SharedArray::UNINIT;
// SAFETY: the pointer is only used by the block helpers, between barriers.
let slots = unsafe { (*&raw mut SLOTS).as_mut_ptr() };
let base = thread::blockIdx_x() as usize * COLS;
let tid = thread::threadIdx_x() as usize;
let mut kept = [0.0f32; PER_THREAD];
let mut largest = f32::NEG_INFINITY;
let mut index = 0;
#[unroll]
while index < PER_THREAD {
kept[index] = input[base + index * BLOCK as usize + tid];
largest = largest.max(kept[index]);
index += 1;
}
let top = block_max(largest, slots);
let mut sum = 0.0;
let mut index = 0;
#[unroll]
while index < PER_THREAD {
kept[index] = (kept[index] - top).exp();
sum += kept[index];
index += 1;
}
let scale = 1.0 / block_sum(sum, slots);
let mut index = 0;
#[unroll]
while index < PER_THREAD {
let column = index * BLOCK as usize + tid;
// SAFETY: each block writes only its own row, and each thread only its own
// columns threadIdx.x, threadIdx.x + 256, ...
unsafe { *out.get_unchecked_mut(base + column) = kept[index] * scale };
index += 1;
}
}
/// Layer norm with variance = mean of squares - square of mean, in 1 pass of sums.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn layernorm_naive(
input: &[f32],
gamma: &[f32],
beta: &[f32],
mut out: DisjointSlice<f32>,
cols: u32,
) {
static mut SLOTS: SharedArray<f32, 8> = SharedArray::UNINIT;
// SAFETY: the pointer is only used by the block helpers, between barriers.
let slots = unsafe { (*&raw mut SLOTS).as_mut_ptr() };
let base = thread::blockIdx_x() as usize * cols as usize;
let tid = thread::threadIdx_x() as usize;
let mut sum = 0.0;
let mut squares = 0.0;
let mut column = tid;
while column < cols as usize {
let value = input[base + column];
sum += value;
squares += value * value;
column += BLOCK as usize;
}
let mean = block_sum(sum, slots) / cols as f32;
let var = block_sum(squares, slots) / cols as f32 - mean * mean;
let inverse_std = 1.0 / (var + EPS).sqrt();
let mut column = tid;
while column < cols as usize {
let scaled = (input[base + column] - mean) * inverse_std;
let normalized = scaled * gamma[column] + beta[column];
// SAFETY: each block writes only its own row, and each thread only its own
// columns threadIdx.x, threadIdx.x + 256, ...
unsafe { *out.get_unchecked_mut(base + column) = normalized };
column += BLOCK as usize;
}
}
/// Layer norm with Welford's running mean and squared deviations, merged per block.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn layernorm_welford(
input: &[f32],
gamma: &[f32],
beta: &[f32],
mut out: DisjointSlice<f32>,
cols: u32,
) {
static mut STATE: SharedArray<f32, 24> = SharedArray::UNINIT;
let base = thread::blockIdx_x() as usize * cols as usize;
let tid = thread::threadIdx_x() as usize;
let mut state = (0.0f32, 0.0f32, 0.0f32);
let mut column = tid;
while column < cols as usize {
let value = input[base + column];
let count = state.0 + 1.0;
let delta = value - state.1;
let mean = state.1 + delta / count;
state = (count, mean, state.2 + delta * (value - mean));
column += BLOCK as usize;
}
let mut mask = 16;
while mask > 0 {
let other = (
warp::shuffle_xor_f32(state.0, mask),
warp::shuffle_xor_f32(state.1, mask),
warp::shuffle_xor_f32(state.2, mask),
);
state = merge_welford(state, other);
mask /= 2;
}
let warp = tid / 32;
if warp::lane_id() == 0 {
// SAFETY: lane 0 of each warp writes its own 3 slots, before the barrier.
unsafe {
STATE[3 * warp] = state.0;
STATE[3 * warp + 1] = state.1;
STATE[3 * warp + 2] = state.2;
}
}
thread::sync_threads();
// SAFETY: after the barrier the slots are only read.
let mut all = unsafe { (STATE[0], STATE[1], STATE[2]) };
let mut other = 1;
while other < WARPS {
let slot = 3 * other;
let next = unsafe { (STATE[slot], STATE[slot + 1], STATE[slot + 2]) };
all = merge_welford(all, next);
other += 1;
}
let mean = all.1;
let inverse_std = 1.0 / (all.2 / cols as f32 + EPS).sqrt();
let mut column = tid;
while column < cols as usize {
let scaled = (input[base + column] - mean) * inverse_std;
let normalized = scaled * gamma[column] + beta[column];
// SAFETY: each block writes only its own row, and each thread only its own
// columns threadIdx.x, threadIdx.x + 256, ...
unsafe { *out.get_unchecked_mut(base + column) = normalized };
column += BLOCK as usize;
}
}
/// 1 read: the row stays in registers; the mean first, then the squared deviations.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn layernorm_fused(
input: &[f32],
gamma: &[f32],
beta: &[f32],
mut out: DisjointSlice<f32>,
) {
static mut SLOTS: SharedArray<f32, 8> = SharedArray::UNINIT;
// SAFETY: the pointer is only used by the block helpers, between barriers.
let slots = unsafe { (*&raw mut SLOTS).as_mut_ptr() };
let base = thread::blockIdx_x() as usize * COLS;
let tid = thread::threadIdx_x() as usize;
let mut kept = [0.0f32; PER_THREAD];
let mut sum = 0.0;
let mut index = 0;
#[unroll]
while index < PER_THREAD {
kept[index] = input[base + index * BLOCK as usize + tid];
sum += kept[index];
index += 1;
}
let mean = block_sum(sum, slots) / COLS as f32;
let mut squares = 0.0;
let mut index = 0;
#[unroll]
while index < PER_THREAD {
kept[index] -= mean;
squares += kept[index] * kept[index];
index += 1;
}
let inverse_std = 1.0 / (block_sum(squares, slots) / COLS as f32 + EPS).sqrt();
let mut index = 0;
#[unroll]
while index < PER_THREAD {
let column = index * BLOCK as usize + tid;
let normalized = kept[index] * inverse_std * gamma[column] + beta[column];
// SAFETY: each block writes only its own row, and each thread only its own
// columns threadIdx.x, threadIdx.x + 256, ...
unsafe { *out.get_unchecked_mut(base + column) = normalized };
index += 1;
}
}
}
/// Time of 1 run of `launch`, in milliseconds: the median of 7 batches of 20 runs,
/// after 100 warm-up runs.
fn time_ms(
stream: &Arc<CudaStream>,
mut launch: impl FnMut() -> Result<(), Error>,
) -> Result<f64, Error> {
for _ in 0..100 {
launch()?;
}
stream.synchronize()?;
let mut batches = Vec::new();
for _ in 0..7 {
let start = Instant::now();
for _ in 0..20 {
launch()?;
}
stream.synchronize()?;
batches.push(start.elapsed().as_secs_f64() * 1e3 / 20.0);
}
batches.sort_by(f64::total_cmp);
Ok(batches[3])
}
/// Uniform numbers in [low, high) from a small linear congruential generator.
fn uniform(n: usize, low: f32, high: f32, seed: u32) -> Vec<f32> {
let mut state = seed;
(0..n)
.map(|_| {
state = state.wrapping_mul(1_664_525).wrapping_add(1_013_904_223);
low + (high - low) * ((state >> 8) as f32 / 16_777_216.0)
})
.collect()
}
/// The softmax of each row, computed in f64.
fn softmax_reference(input: &[f32], cols: usize) -> Vec<f64> {
let mut out = Vec::with_capacity(input.len());
for row in input.chunks(cols) {
let top = row.iter().fold(f64::NEG_INFINITY, |m, &v| m.max(v as f64));
let total: f64 = row.iter().map(|&v| (v as f64 - top).exp()).sum();
out.extend(row.iter().map(|&v| (v as f64 - top).exp() / total));
}
out
}
/// The layer norm of each row, computed in f64.
fn layernorm_reference(input: &[f32], gamma: &[f32], beta: &[f32]) -> Vec<f64> {
let cols = gamma.len();
let mut out = Vec::with_capacity(input.len());
for row in input.chunks(cols) {
let mean = row.iter().map(|&v| v as f64).sum::<f64>() / cols as f64;
let var = row.iter().map(|&v| (v as f64 - mean).powi(2)).sum::<f64>() / cols as f64;
let rstd = 1.0 / (var + EPS as f64).sqrt();
for (j, &v) in row.iter().enumerate() {
out.push((v as f64 - mean) * rstd * gamma[j] as f64 + beta[j] as f64);
}
}
out
}
/// The largest difference between `gpu` and `exact`; NaN if any GPU value is NaN.
fn max_error(gpu: &[f32], exact: &[f64]) -> f64 {
let mut worst = 0.0f64;
for (&g, &e) in gpu.iter().zip(exact) {
let diff = (g as f64 - e).abs();
if diff.is_nan() {
return f64::NAN;
}
worst = worst.max(diff);
}
worst
}
/// Prints a matrix of `cols` columns, 1 row per line.
fn print_matrix(name: &str, values: &[f32], cols: usize) {
println!(" {name}");
for row in values.chunks(cols) {
let shown: Vec<String> = row.iter().map(|v| format!("{v:8.4}")).collect();
println!(" {}", shown.join(" "));
}
}
/// Prints 1 line of a results table: bytes per element, time, bandwidth and error.
fn report(name: &str, bytes: usize, ms: f64, error: f64) {
let gb = (ROWS * COLS * bytes) as f64 / 1e9 / (ms / 1e3);
println!(" {name:<11} {bytes:>10} {ms:7.3} {gb:7.1} {error:11.2e}");
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let all_rows = LaunchConfig1D::new(ROWS as u32, BLOCK, 0);
let header = " kernel bytes/elem ms GB/s max error";
// 1. The 2 x 4 example X, and X shifted by 100 and by 10,000.
let x = [1.0f32, 2.0, 3.0, 4.0, 2.0, 4.0, 4.0, 5.0];
let x100: Vec<f32> = x.iter().map(|v| v + 100.0).collect();
let x10k: Vec<f32> = x.iter().map(|v| v + 10_000.0).collect();
let ones = DeviceBuffer::from_host(&stream, &[1.0f32; 4])?;
let zeros = DeviceBuffer::from_host(&stream, &[0.0f32; 4])?;
let small = DeviceBuffer::from_host(&stream, &x)?;
let shifted = DeviceBuffer::from_host(&stream, &x100)?;
let far = DeviceBuffer::from_host(&stream, &x10k)?;
let mut out = DeviceBuffer::<f32>::zeroed(&stream, 8)?;
let two_rows = LaunchConfig1D::new(2, BLOCK, 0);
let naive_two = module.prepare_softmax_naive(two_rows)?;
let three_two = module.prepare_softmax_three_pass(two_rows)?;
let online_two = module.prepare_softmax_online(two_rows)?;
let sq_two = module.prepare_layernorm_naive(two_rows)?;
let welford_two = module.prepare_layernorm_welford(two_rows)?;
println!("the 2 x 4 example X = [1 2 3 4; 2 4 4 5]");
module.softmax_naive(&stream, &naive_two, &small, &mut out, 4)?;
print_matrix("softmax without the maximum, X", &out.to_host_vec(&stream)?, 4);
module.softmax_naive(&stream, &naive_two, &shifted, &mut out, 4)?;
let naive_big = out.to_host_vec(&stream)?;
print_matrix("softmax without the maximum, X + 100", &naive_big, 4);
module.softmax_three_pass(&stream, &three_two, &small, &mut out, 4)?;
let three_x = out.to_host_vec(&stream)?;
print_matrix("softmax, 3 passes, X", &three_x, 4);
module.softmax_three_pass(&stream, &three_two, &shifted, &mut out, 4)?;
let three_big = out.to_host_vec(&stream)?;
print_matrix("softmax, 3 passes, X + 100", &three_big, 4);
module.softmax_online(&stream, &online_two, &small, &mut out, 4)?;
let online_x = out.to_host_vec(&stream)?;
print_matrix("softmax, online, X", &online_x, 4);
module.layernorm_naive(&stream, &sq_two, &small, &ones, &zeros, &mut out, 4)?;
let sq_x = out.to_host_vec(&stream)?;
print_matrix("layer norm, sum of squares, X", &sq_x, 4);
module.layernorm_naive(&stream, &sq_two, &far, &ones, &zeros, &mut out, 4)?;
let sq_far = out.to_host_vec(&stream)?;
print_matrix("layer norm, sum of squares, X + 10000", &sq_far, 4);
module.layernorm_welford(&stream, &welford_two, &far, &ones, &zeros, &mut out, 4)?;
let welford_far = out.to_host_vec(&stream)?;
print_matrix("layer norm, Welford, X + 10000", &welford_far, 4);
let p = softmax_reference(&x, 4);
let y = layernorm_reference(&x, &[1.0; 4], &[0.0; 4]);
let example_ok = max_error(&three_x, &p) < 1e-6
&& max_error(&three_big, &p) < 1e-6
&& max_error(&online_x, &p) < 1e-6
&& max_error(&sq_x, &y) < 1e-4
&& max_error(&welford_far, &y) < 1e-4
&& naive_big.iter().all(|v| v.is_nan())
&& sq_far.iter().all(|v| v.is_nan());
// 2. Softmax of 4,096 rows of 4,096 logits in [-10, 10): 16 KiB per row.
let n = ROWS * COLS;
let cols = COLS as u32;
let logits = uniform(n, -10.0, 10.0, 1);
let input = DeviceBuffer::from_host(&stream, &logits)?;
let mut out = DeviceBuffer::<f32>::zeroed(&stream, n)?;
let exact = softmax_reference(&logits, COLS);
let three = module.prepare_softmax_three_pass(all_rows)?;
let online = module.prepare_softmax_online(all_rows)?;
let fused = module.prepare_softmax_fused(all_rows)?;
println!("softmax of {ROWS} rows x {COLS} columns, median of 7 x 20 runs");
println!("{header}");
let ms = time_ms(&stream, || {
Ok(module.softmax_three_pass(&stream, &three, &input, &mut out, cols)?)
})?;
let three_error = max_error(&out.to_host_vec(&stream)?, &exact);
report("3 passes", 16, ms, three_error);
let ms = time_ms(&stream, || {
Ok(module.softmax_online(&stream, &online, &input, &mut out, cols)?)
})?;
let online_error = max_error(&out.to_host_vec(&stream)?, &exact);
report("online", 12, ms, online_error);
let ms = time_ms(&stream, || {
Ok(module.softmax_fused(&stream, &fused, &input, &mut out)?)
})?;
let fused_error = max_error(&out.to_host_vec(&stream)?, &exact);
report("fused", 8, ms, fused_error);
// 3. The same logits as 256 rows of 65,536: 256 KiB per row.
let long = 65_536;
let long_rows = LaunchConfig1D::new((n / long) as u32, BLOCK, 0);
let three_long = module.prepare_softmax_three_pass(long_rows)?;
let online_long = module.prepare_softmax_online(long_rows)?;
let wide = long as u32;
let exact = softmax_reference(&logits, long);
println!("softmax of {} rows x {long} columns, median of 7 x 20 runs", n / long);
println!("{header}");
let ms = time_ms(&stream, || {
Ok(module.softmax_three_pass(&stream, &three_long, &input, &mut out, wide)?)
})?;
let three_long_error = max_error(&out.to_host_vec(&stream)?, &exact);
report("3 passes", 16, ms, three_long_error);
let ms = time_ms(&stream, || {
Ok(module.softmax_online(&stream, &online_long, &input, &mut out, wide)?)
})?;
let online_long_error = max_error(&out.to_host_vec(&stream)?, &exact);
report("online", 12, ms, online_long_error);
// 4. Layer norm of 4,096 rows of values 1,000 + [-1, 1).
let values = uniform(n, 999.0, 1001.0, 2);
let gamma: Vec<f32> = (0..COLS).map(|j| 0.5 + 0.25 * (j % 3) as f32).collect();
let beta: Vec<f32> = (0..COLS).map(|j| 0.1 * (j % 5) as f32 - 0.2).collect();
let input = DeviceBuffer::from_host(&stream, &values)?;
let g = DeviceBuffer::from_host(&stream, &gamma)?;
let b = DeviceBuffer::from_host(&stream, &beta)?;
let exact = layernorm_reference(&values, &gamma, &beta);
let naive = module.prepare_layernorm_naive(all_rows)?;
let welford = module.prepare_layernorm_welford(all_rows)?;
let fused = module.prepare_layernorm_fused(all_rows)?;
println!("layer norm of {ROWS} rows x {COLS} columns, values 1,000 + [-1, 1)");
println!("{header}");
let ms = time_ms(&stream, || {
Ok(module.layernorm_naive(&stream, &naive, &input, &g, &b, &mut out, cols)?)
})?;
let naive_error = max_error(&out.to_host_vec(&stream)?, &exact);
report("sum, sum x2", 12, ms, naive_error);
let ms = time_ms(&stream, || {
Ok(module.layernorm_welford(&stream, &welford, &input, &g, &b, &mut out, cols)?)
})?;
let welford_error = max_error(&out.to_host_vec(&stream)?, &exact);
report("Welford", 12, ms, welford_error);
let ms = time_ms(&stream, || {
Ok(module.layernorm_fused(&stream, &fused, &input, &g, &b, &mut out)?)
})?;
let norm_error = max_error(&out.to_host_vec(&stream)?, &exact);
report("fused", 8, ms, norm_error);
// 5. Softmax within 1e-6, layer norm within 1e-3; the sum of squares must be off.
let short = [three_error, online_error, fused_error];
let long = [three_long_error, online_long_error];
let softmax_ok = short.iter().chain(&long).all(|&e| e < 1e-6);
let layernorm_ok = welford_error < 1e-3 && norm_error < 1e-3 && naive_error > 0.1;
let ok = example_ok && softmax_ok && layernorm_ok;
println!("{}", if ok { "PASSED" } else { "FAILED" });
Ok(())
}// Chapter 23: softmax and layer normalization of the rows of a matrix, in CUDA C++.
// Build: nvcc -O3 -arch=native softmax_layernorm.cu -o softmax_layernorm
#include <algorithm>
#include <chrono>
#include <cmath>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cuda_runtime.h>
const int BLOCK = 256;
const int WARPS = BLOCK / 32;
const int ROWS = 4096;
const int COLS = 4096;
const int PER_THREAD = COLS / BLOCK;
const float EPS = 1e-5f;
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
__device__ float warpMax(float value)
{
for (int mask = 16; mask > 0; mask /= 2) {
value = fmaxf(value, __shfl_xor_sync(0xffffffff, value, mask));
}
return value;
}
__device__ float warpSum(float value)
{
for (int mask = 16; mask > 0; mask /= 2) {
value += __shfl_xor_sync(0xffffffff, value, mask);
}
return value;
}
// The maximum over the block, returned to every thread. `slots` holds 8 floats.
__device__ float blockMax(float value, float* slots)
{
value = warpMax(value);
int warp = threadIdx.x / 32;
if (threadIdx.x % 32 == 0) {
slots[warp] = value;
}
__syncthreads();
float largest = slots[0];
for (int other = 1; other < WARPS; ++other) {
largest = fmaxf(largest, slots[other]);
}
__syncthreads();
return largest;
}
// The sum over the block, returned to every thread. `slots` holds 8 floats.
__device__ float blockSum(float value, float* slots)
{
value = warpSum(value);
int warp = threadIdx.x / 32;
if (threadIdx.x % 32 == 0) {
slots[warp] = value;
}
__syncthreads();
float sum = 0.0f;
for (int other = 0; other < WARPS; ++other) {
sum += slots[other];
}
__syncthreads();
return sum;
}
// A softmax state: the maximum m and the sum s of exp(x - m). (-inf, 0) is the empty state.
struct SoftmaxState {
float largest; // m
float sum; // s
};
__device__ SoftmaxState mergeSoftmax(SoftmaxState first, SoftmaxState second)
{
float top = fmaxf(first.largest, second.largest);
if (top == -INFINITY) {
return {top, 0.0f};
}
float firstPart = first.sum * expf(first.largest - top);
float secondPart = second.sum * expf(second.largest - top);
return {top, firstPart + secondPart};
}
// A Welford state: the count n, the mean, and the sum q of squared deviations.
struct WelfordState {
float count; // n
float mean;
float squares; // q
};
__device__ WelfordState mergeWelford(WelfordState first, WelfordState second)
{
float count = first.count + second.count;
if (count == 0.0f) {
return first;
}
float delta = second.mean - first.mean;
float mean = first.mean + delta * second.count / count;
float between = delta * delta * first.count * second.count / count;
return {count, mean, first.squares + second.squares + between};
}
// Softmax without the maximum: exp(x) / sum of exp(x). Overflows for large x.
__global__ void softmaxNaive(const float* in, float* out, int cols)
{
__shared__ float slots[WARPS];
const float* row = in + (size_t)blockIdx.x * cols;
float* result = out + (size_t)blockIdx.x * cols;
float sum = 0.0f;
for (int column = threadIdx.x; column < cols; column += BLOCK) {
sum += expf(row[column]);
}
float total = blockSum(sum, slots);
for (int column = threadIdx.x; column < cols; column += BLOCK) {
result[column] = expf(row[column]) / total;
}
}
// 3 passes over the row: the maximum, the sum of exp(x - max), the outputs.
__global__ void softmaxThreePass(const float* in, float* out, int cols)
{
__shared__ float slots[WARPS];
const float* row = in + (size_t)blockIdx.x * cols;
float* result = out + (size_t)blockIdx.x * cols;
float largest = -INFINITY;
for (int column = threadIdx.x; column < cols; column += BLOCK) {
largest = fmaxf(largest, row[column]);
}
float top = blockMax(largest, slots);
float sum = 0.0f;
for (int column = threadIdx.x; column < cols; column += BLOCK) {
sum += expf(row[column] - top);
}
float total = blockSum(sum, slots);
for (int column = threadIdx.x; column < cols; column += BLOCK) {
result[column] = expf(row[column] - top) / total;
}
}
// 2 passes: a running maximum and a rescaled running sum, then the outputs.
__global__ void softmaxOnline(const float* in, float* out, int cols)
{
__shared__ SoftmaxState slots[WARPS];
const float* row = in + (size_t)blockIdx.x * cols;
float* result = out + (size_t)blockIdx.x * cols;
SoftmaxState state = {-INFINITY, 0.0f};
for (int column = threadIdx.x; column < cols; column += BLOCK) {
float value = row[column];
if (value > state.largest) {
state.sum = state.sum * expf(state.largest - value) + 1.0f;
state.largest = value;
} else {
state.sum += expf(value - state.largest);
}
}
for (int mask = 16; mask > 0; mask /= 2) {
SoftmaxState other;
other.largest = __shfl_xor_sync(0xffffffff, state.largest, mask);
other.sum = __shfl_xor_sync(0xffffffff, state.sum, mask);
state = mergeSoftmax(state, other);
}
if (threadIdx.x % 32 == 0) {
slots[threadIdx.x / 32] = state;
}
__syncthreads();
SoftmaxState all = slots[0];
for (int other = 1; other < WARPS; ++other) {
all = mergeSoftmax(all, slots[other]);
}
for (int column = threadIdx.x; column < cols; column += BLOCK) {
result[column] = expf(row[column] - all.largest) / all.sum;
}
}
// 1 read: each thread keeps its 16 values of the row in registers.
__global__ void softmaxFused(const float* in, float* out)
{
__shared__ float slots[WARPS];
const float* row = in + (size_t)blockIdx.x * COLS;
float* result = out + (size_t)blockIdx.x * COLS;
float kept[PER_THREAD];
float largest = -INFINITY;
#pragma unroll
for (int index = 0; index < PER_THREAD; ++index) {
kept[index] = row[index * BLOCK + threadIdx.x];
largest = fmaxf(largest, kept[index]);
}
float top = blockMax(largest, slots);
float sum = 0.0f;
#pragma unroll
for (int index = 0; index < PER_THREAD; ++index) {
kept[index] = expf(kept[index] - top);
sum += kept[index];
}
float scale = 1.0f / blockSum(sum, slots);
#pragma unroll
for (int index = 0; index < PER_THREAD; ++index) {
result[index * BLOCK + threadIdx.x] = kept[index] * scale;
}
}
// Layer norm with variance = mean of squares - square of mean, in 1 pass of sums.
__global__ void layernormNaive(const float* in, const float* gamma, const float* beta,
float* out, int cols)
{
__shared__ float slots[WARPS];
const float* row = in + (size_t)blockIdx.x * cols;
float* result = out + (size_t)blockIdx.x * cols;
float sum = 0.0f;
float squares = 0.0f;
for (int column = threadIdx.x; column < cols; column += BLOCK) {
float value = row[column];
sum += value;
squares += value * value;
}
float mean = blockSum(sum, slots) / cols;
float variance = blockSum(squares, slots) / cols - mean * mean;
float inverseStd = 1.0f / sqrtf(variance + EPS);
for (int column = threadIdx.x; column < cols; column += BLOCK) {
result[column] = (row[column] - mean) * inverseStd * gamma[column] + beta[column];
}
}
// Layer norm with Welford's running mean and squared deviations, merged per block.
__global__ void layernormWelford(const float* in, const float* gamma, const float* beta,
float* out, int cols)
{
__shared__ WelfordState slots[WARPS];
const float* row = in + (size_t)blockIdx.x * cols;
float* result = out + (size_t)blockIdx.x * cols;
WelfordState state = {0.0f, 0.0f, 0.0f};
for (int column = threadIdx.x; column < cols; column += BLOCK) {
float value = row[column];
state.count += 1.0f;
float delta = value - state.mean;
state.mean += delta / state.count;
state.squares += delta * (value - state.mean);
}
for (int mask = 16; mask > 0; mask /= 2) {
WelfordState other;
other.count = __shfl_xor_sync(0xffffffff, state.count, mask);
other.mean = __shfl_xor_sync(0xffffffff, state.mean, mask);
other.squares = __shfl_xor_sync(0xffffffff, state.squares, mask);
state = mergeWelford(state, other);
}
if (threadIdx.x % 32 == 0) {
slots[threadIdx.x / 32] = state;
}
__syncthreads();
WelfordState all = slots[0];
for (int other = 1; other < WARPS; ++other) {
all = mergeWelford(all, slots[other]);
}
float inverseStd = 1.0f / sqrtf(all.squares / cols + EPS);
for (int column = threadIdx.x; column < cols; column += BLOCK) {
float normalized = (row[column] - all.mean) * inverseStd;
result[column] = normalized * gamma[column] + beta[column];
}
}
// 1 read: the row stays in registers; the mean first, then the squared deviations.
__global__ void layernormFused(const float* in, const float* gamma, const float* beta,
float* out)
{
__shared__ float slots[WARPS];
const float* row = in + (size_t)blockIdx.x * COLS;
float* result = out + (size_t)blockIdx.x * COLS;
float kept[PER_THREAD];
float sum = 0.0f;
#pragma unroll
for (int index = 0; index < PER_THREAD; ++index) {
kept[index] = row[index * BLOCK + threadIdx.x];
sum += kept[index];
}
float mean = blockSum(sum, slots) / COLS;
float squares = 0.0f;
#pragma unroll
for (int index = 0; index < PER_THREAD; ++index) {
kept[index] -= mean;
squares += kept[index] * kept[index];
}
float inverseStd = 1.0f / sqrtf(blockSum(squares, slots) / COLS + EPS);
#pragma unroll
for (int index = 0; index < PER_THREAD; ++index) {
int column = index * BLOCK + threadIdx.x;
result[column] = kept[index] * inverseStd * gamma[column] + beta[column];
}
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// Time of 1 run of `launch`, in milliseconds: the median of 7 batches of 20 runs,
// after 100 warm-up runs.
template <typename F>
double timeMs(F launch)
{
for (int warmup = 0; warmup < 100; ++warmup) {
launch();
}
check(cudaDeviceSynchronize());
std::vector<double> batches;
for (int batch = 0; batch < 7; ++batch) {
double start = nowMs();
for (int timed = 0; timed < 20; ++timed) {
launch();
}
check(cudaGetLastError());
check(cudaDeviceSynchronize());
batches.push_back((nowMs() - start) / 20);
}
std::sort(batches.begin(), batches.end());
return batches[3];
}
// Uniform numbers in [low, high) from a small linear congruential generator.
std::vector<float> uniform(size_t n, float low, float high, unsigned seed)
{
std::vector<float> v(n);
unsigned state = seed;
for (size_t i = 0; i < n; ++i) {
state = state * 1664525u + 1013904223u;
v[i] = low + (high - low) * ((state >> 8) / 16777216.0f);
}
return v;
}
// The softmax of each row, computed in double.
std::vector<double> softmaxReference(const std::vector<float>& in, int cols)
{
std::vector<double> out(in.size());
for (size_t rowIndex = 0; rowIndex < in.size() / cols; ++rowIndex) {
const float* row = in.data() + rowIndex * cols;
double top = -INFINITY;
for (int column = 0; column < cols; ++column) {
top = std::max(top, (double)row[column]);
}
double total = 0.0;
for (int column = 0; column < cols; ++column) {
total += std::exp(row[column] - top);
}
for (int column = 0; column < cols; ++column) {
out[rowIndex * cols + column] = std::exp(row[column] - top) / total;
}
}
return out;
}
// The layer norm of each row, computed in double.
std::vector<double> layernormReference(const std::vector<float>& in,
const std::vector<float>& gamma,
const std::vector<float>& beta)
{
int cols = gamma.size();
std::vector<double> out(in.size());
for (size_t rowIndex = 0; rowIndex < in.size() / cols; ++rowIndex) {
const float* row = in.data() + rowIndex * cols;
double mean = 0.0;
for (int column = 0; column < cols; ++column) {
mean += row[column];
}
mean /= cols;
double variance = 0.0;
for (int column = 0; column < cols; ++column) {
variance += (row[column] - mean) * (row[column] - mean);
}
double inverseStd = 1.0 / std::sqrt(variance / cols + EPS);
for (int column = 0; column < cols; ++column) {
double normalized = (row[column] - mean) * inverseStd;
out[rowIndex * cols + column] = normalized * gamma[column] + beta[column];
}
}
return out;
}
// The largest difference between `gpu` and `exact`; NaN if any GPU value is NaN.
double maxError(const std::vector<float>& gpu, const std::vector<double>& exact)
{
double worst = 0.0;
for (size_t i = 0; i < gpu.size(); ++i) {
double diff = std::fabs(gpu[i] - exact[i]);
if (std::isnan(diff)) {
return NAN;
}
worst = std::max(worst, diff);
}
return worst;
}
bool allNan(const std::vector<float>& v)
{
return std::all_of(v.begin(), v.end(), [](float x) { return std::isnan(x); });
}
std::vector<float> toHost(const float* d, size_t n)
{
std::vector<float> h(n);
check(cudaMemcpy(h.data(), d, n * sizeof(float), cudaMemcpyDeviceToHost));
return h;
}
float* toDevice(const std::vector<float>& h)
{
float* d;
check(cudaMalloc(&d, h.size() * sizeof(float)));
check(cudaMemcpy(d, h.data(), h.size() * sizeof(float), cudaMemcpyHostToDevice));
return d;
}
// Prints a matrix of `cols` columns, 1 row per line.
void printMatrix(const char* name, const std::vector<float>& v, int cols)
{
std::printf(" %s\n", name);
for (size_t i = 0; i < v.size(); ++i) {
std::printf(i % cols == 0 ? " " : " ");
if (std::isnan(v[i])) {
std::printf("%8s", "NaN");
} else {
std::printf("%8.4f", v[i]);
}
if (i % cols == cols - 1) {
std::printf("\n");
}
}
}
// Prints 1 line of a results table: bytes per element, time, bandwidth and error.
void report(const char* name, int bytes, double ms, double error)
{
double gb = (double)ROWS * COLS * bytes / 1e9 / (ms / 1e3);
std::printf(" %-11s %10d %7.3f %7.1f %11.2e\n", name, bytes, ms, gb, error);
}
int main()
{
const char* header = " kernel bytes/elem ms GB/s max error";
// 1. The 2 x 4 example X, and X shifted by 100 and by 10,000.
std::vector<float> x = {1, 2, 3, 4, 2, 4, 4, 5};
std::vector<float> x100(8);
std::vector<float> x10k(8);
for (int i = 0; i < 8; ++i) {
x100[i] = x[i] + 100.0f;
x10k[i] = x[i] + 10000.0f;
}
float* ones = toDevice(std::vector<float>(4, 1.0f));
float* zeros = toDevice(std::vector<float>(4, 0.0f));
float* small = toDevice(x);
float* shifted = toDevice(x100);
float* far = toDevice(x10k);
float* o;
check(cudaMalloc(&o, 8 * sizeof(float)));
std::printf("the 2 x 4 example X = [1 2 3 4; 2 4 4 5]\n");
softmaxNaive<<<2, BLOCK>>>(small, o, 4);
printMatrix("softmax without the maximum, X", toHost(o, 8), 4);
softmaxNaive<<<2, BLOCK>>>(shifted, o, 4);
std::vector<float> naiveBig = toHost(o, 8);
printMatrix("softmax without the maximum, X + 100", naiveBig, 4);
softmaxThreePass<<<2, BLOCK>>>(small, o, 4);
std::vector<float> threeX = toHost(o, 8);
printMatrix("softmax, 3 passes, X", threeX, 4);
softmaxThreePass<<<2, BLOCK>>>(shifted, o, 4);
std::vector<float> threeBig = toHost(o, 8);
printMatrix("softmax, 3 passes, X + 100", threeBig, 4);
softmaxOnline<<<2, BLOCK>>>(small, o, 4);
std::vector<float> onlineX = toHost(o, 8);
printMatrix("softmax, online, X", onlineX, 4);
layernormNaive<<<2, BLOCK>>>(small, ones, zeros, o, 4);
std::vector<float> sqX = toHost(o, 8);
printMatrix("layer norm, sum of squares, X", sqX, 4);
layernormNaive<<<2, BLOCK>>>(far, ones, zeros, o, 4);
std::vector<float> sqFar = toHost(o, 8);
printMatrix("layer norm, sum of squares, X + 10000", sqFar, 4);
layernormWelford<<<2, BLOCK>>>(far, ones, zeros, o, 4);
std::vector<float> welfordFar = toHost(o, 8);
printMatrix("layer norm, Welford, X + 10000", welfordFar, 4);
std::vector<double> p = softmaxReference(x, 4);
std::vector<double> y = layernormReference(x, std::vector<float>(4, 1.0f),
std::vector<float>(4, 0.0f));
bool exampleOk = maxError(threeX, p) < 1e-6 && maxError(threeBig, p) < 1e-6;
exampleOk = exampleOk && maxError(onlineX, p) < 1e-6 && maxError(sqX, y) < 1e-4;
exampleOk = exampleOk && maxError(welfordFar, y) < 1e-4;
exampleOk = exampleOk && allNan(naiveBig) && allNan(sqFar);
// 2. Softmax of 4,096 rows of 4,096 logits in [-10, 10): 16 KiB per row.
size_t n = (size_t)ROWS * COLS;
std::vector<float> logits = uniform(n, -10.0f, 10.0f, 1);
float* in = toDevice(logits);
float* out;
check(cudaMalloc(&out, n * sizeof(float)));
std::vector<double> exact = softmaxReference(logits, COLS);
std::printf("softmax of %d rows x %d columns, median of 7 x 20 runs\n", ROWS, COLS);
std::printf("%s\n", header);
double ms = timeMs([&] { softmaxThreePass<<<ROWS, BLOCK>>>(in, out, COLS); });
double threeError = maxError(toHost(out, n), exact);
report("3 passes", 16, ms, threeError);
ms = timeMs([&] { softmaxOnline<<<ROWS, BLOCK>>>(in, out, COLS); });
double onlineError = maxError(toHost(out, n), exact);
report("online", 12, ms, onlineError);
ms = timeMs([&] { softmaxFused<<<ROWS, BLOCK>>>(in, out); });
double fusedError = maxError(toHost(out, n), exact);
report("fused", 8, ms, fusedError);
// 3. The same logits as 256 rows of 65,536: 256 KiB per row.
int wide = 65536;
int longRows = n / wide;
exact = softmaxReference(logits, wide);
std::printf("softmax of %d rows x %d columns, median of 7 x 20 runs\n", longRows, wide);
std::printf("%s\n", header);
ms = timeMs([&] { softmaxThreePass<<<longRows, BLOCK>>>(in, out, wide); });
double threeLongError = maxError(toHost(out, n), exact);
report("3 passes", 16, ms, threeLongError);
ms = timeMs([&] { softmaxOnline<<<longRows, BLOCK>>>(in, out, wide); });
double onlineLongError = maxError(toHost(out, n), exact);
report("online", 12, ms, onlineLongError);
// 4. Layer norm of 4,096 rows of values 1,000 + [-1, 1).
std::vector<float> values = uniform(n, 999.0f, 1001.0f, 2);
std::vector<float> gamma(COLS);
std::vector<float> beta(COLS);
for (int j = 0; j < COLS; ++j) {
gamma[j] = 0.5f + 0.25f * (j % 3);
beta[j] = 0.1f * (j % 5) - 0.2f;
}
check(cudaMemcpy(in, values.data(), n * sizeof(float), cudaMemcpyHostToDevice));
float* g = toDevice(gamma);
float* b = toDevice(beta);
exact = layernormReference(values, gamma, beta);
std::printf("layer norm of %d rows x %d columns, values 1,000 + [-1, 1)\n", ROWS, COLS);
std::printf("%s\n", header);
ms = timeMs([&] { layernormNaive<<<ROWS, BLOCK>>>(in, g, b, out, COLS); });
double naiveError = maxError(toHost(out, n), exact);
report("sum, sum x2", 12, ms, naiveError);
ms = timeMs([&] { layernormWelford<<<ROWS, BLOCK>>>(in, g, b, out, COLS); });
double welfordError = maxError(toHost(out, n), exact);
report("Welford", 12, ms, welfordError);
ms = timeMs([&] { layernormFused<<<ROWS, BLOCK>>>(in, g, b, out); });
double normError = maxError(toHost(out, n), exact);
report("fused", 8, ms, normError);
// 5. Softmax within 1e-6, layer norm within 1e-3; the sum of squares must be off.
bool softmaxOk = threeError < 1e-6 && onlineError < 1e-6 && fusedError < 1e-6;
softmaxOk = softmaxOk && threeLongError < 1e-6 && onlineLongError < 1e-6;
bool layernormOk = welfordError < 1e-3 && normError < 1e-3 && naiveError > 0.1;
bool ok = exampleOk && softmaxOk && layernormOk;
std::printf("%s\n", ok ? "PASSED" : "FAILED");
cudaFree(ones);
cudaFree(zeros);
cudaFree(small);
cudaFree(shifted);
cudaFree(far);
cudaFree(o);
cudaFree(in);
cudaFree(out);
cudaFree(g);
cudaFree(b);
return ok ? 0 : 1;
}
Common mistakes
- Computing the exponential before subtracting the maximum. Inputs above 88.72 overflow
f32, and the softmax of the row becomes NaN. - Computing the variance as the mean of the squares minus the square of the mean. The result loses all its digits when the mean is large compared with the spread, and can be negative, which makes the square root NaN.
- Merging 2 empty states without a test. \(-\infty - (-\infty)\) is NaN for the softmax merge, and \(0 / 0\) is NaN for the Welford merge. Threads without values hold empty states whenever a row is shorter than the block.
- Leaving out the second barrier of a block reduction. A warp that finishes early overwrites a slot that another warp still reads when 2 reductions use the same slots. The result is wrong on a few launches in a hundred.
- Counting bytes without asking where they come from. A model that sends every read to main memory overestimates repeated reads of a short row, which the L2 cache serves.
- Leaving out \(\varepsilon\). A row of equal values has variance 0, and the division gives NaN.
Summary
- Softmax divides the exponential of each value by the sum of the exponentials of its row. Layer normalization subtracts the row mean and divides by the standard deviation, with a small \(\varepsilon\) under the square root, and then applies a scale and a shift per column.
- Subtracting the row maximum leaves softmax unchanged (Theorem 23.1) and keeps every exponential in
\((0, 1]\). The variance computed as \(\overline{x^2} - \mu^2\), the mean of
the squares minus the square of the mean, suffers from cancellation. It gives \(-8\) instead of
1.25 for 10,001 to 10,004 in
f32. - A sum of exponentials relative to 1 maximum is moved to a larger one by 1 multiplication. The online softmax uses this to find the maximum and the sum in 1 pass, and Welford’s method applies the same idea to the mean and the sum of squared deviations.
- Partial states of disjoint parts of a row merge into the state of their union. The merges are associative, which allows a tree of merges, and they must treat 2 empty states separately.
- With one block per row, the threads read coalesced columns, merge within each warp by an xor butterfly, and merge across warps through 8 shared slots and 2 barriers. Removing the second barrier produced NaN rows in 11 of 100 launches.
- Fused kernels keep the row in registers, read it once, and reached 91 to 93% of the 102 GB/s of the measured GPU. On rows of 4,096 values, the L2 cache served the extra passes of the other kernels. On rows of 65,536 values, it could not, and the online softmax was 1.32 times as fast as 3 passes, which is the ratio of their traffic.
Exercises
- Compute by hand the softmax of the row 0, 0, 0, 10, with and without subtracting the maximum. What fraction of the total does the last value receive?
- Apply Welford’s update by hand to 1,000.5, 999.5, 1,000.5, 999.5. Then compute the mean of the squares minus the square of the mean, rounding each square to the nearest 0.0625. Compare both variances with the exact value, 0.25.
- Prove that Merge-Softmax is commutative: merging \(a\) with \(b\) gives the same state as merging \(b\) with \(a\).
- Write Online-Softmax for a row that arrives in pieces of 4 values, using Merge-Softmax once per piece. How many exponentials does it compute per value?
- Write a softmax kernel that assigns 1 warp of 32 threads to each row, with no shared memory and no barrier, and measure it against the fused kernel on rows of 1,024.
- The online kernel computes 1 exponential per value in its first loop and 1 in its second. Count the exponentials of the 3-pass kernel. What does the online kernel save, if not arithmetic?
- Replace the division in Welford-Update by a multiplication with a reciprocal computed once per count. Is the result still exact on Figure 23.10? Measure the effect on the kernel.
- Build the Rust program with
--unchecked-indexingand run it on your GPU. Which kernels change, and by how much?
Sources and further reading
- M. Milakov and N. Gimelshein, Online normalizer calculation for softmax, arXiv:1805.02867, 2018. The online softmax of Section 23.3.2.
- B. P. Welford, Note on a method for calculating corrected sums of squares and products, Technometrics 4(3), 1962. The update of Section 23.3.4.
- T. F. Chan, G. H. Golub and R. J. LeVeque, Updating formulae and a pairwise algorithm for computing sample variances, Stanford technical report STAN-CS-79-773, 1979. The merge of Section 23.3.5.
- J. L. Ba, J. R. Kiros and G. E. Hinton, Layer normalization, arXiv:1607.06450, 2016.
- N. J. Higham, Accuracy and Stability of Numerical Algorithms, 2nd ed., SIAM, 2002. Chapter 1 on cancellation, and chapter 4 on the accuracy of summation.
- T. Dao et al., FlashAttention: fast and memory-efficient exact attention with IO-awareness, NeurIPS 2022. The online softmax applied inside attention.
- T. H. Cormen, C. E. Leiserson, R. L. Rivest and C. Stein, Introduction to Algorithms, 4th ed., MIT Press, 2022. Loop invariants and the pseudocode conventions of this chapter.
- A. Pathak, An Introduction to Tiled Parallel Programming, Simplified, 2026. The worked-example method of this chapter, applied to the matrix product.
Chapter 24: Capstone: An Image Pipeline
In Chapters 14 to 23, we derived 1 parallel algorithm at a time: a map, a reduction, a matrix product, a stencil, a scan, a histogram and a normalization. A real program, however, chains several of them. Each kernel reads what the previous kernel wrote, the data travel from host memory to the device and back, and the slowest stage sets the rate of the whole program. Image processing illustrates this well, because its common operations fall into the patterns of Part V. Some of them compute each output pixel from 1 input pixel, some from a small window around it, and some from every pixel of the image.
In this chapter, we build a pipeline of 4 stages that turns a color image into a map of its edges. The stages are conversion to gray, histogram equalization, a Gaussian blur and the Sobel edge detector. We carry an image of 8 × 8 pixels through every stage by hand, derive each kernel from the chapter of Part V in which we developed its pattern, and prove that a blur in 2 passes of 5 weights equals the blur with 25 weights. We then run the pipeline in Rust and in CUDA C++ on images of 1,920 × 1,080 pixels, check every pixel against the CPU, and find which stage takes the most time and why. Finally, we process a batch of images on several streams, so that copies overlap with computation.
This chapter covers
- An 8 × 8 image carried by hand through gray conversion, equalization, blur and edge detection
- The pattern behind each stage: a map, a histogram with a scan, and 2 stencils
- The proof that 2 passes of 5 weights equal 1 pass of 25 weights, and the work it saves
- A shared tile with a halo, and the wrong pixels a missing halo produces
- One easy mistake for each stage, with the wrong value it gives on the example
- The host program: buffers, streams, and an exact comparison with the CPU
- The time of each stage, and copies overlapped with kernels on 2 and 3 streams
The programs are in
code/oxide/ch24_capstone/
(Rust, cargo oxide run) and
code/cuda/ch24_capstone/capstone.cu
(C++, with its build command in its first lines). Both programs compute the same images from the
same input, and both print the same report.
24.1 The problem
24.1.1 Images in memory
An image is a rectangle of pixels, whereas memory is a single line of numbered bytes. Before we can write any kernel, we must therefore fix how the rectangle is laid out along the line.
Definition 24.1 Pixel and image. A pixel is the smallest element of an image. A pixel of a gray image is 1 byte, a level from 0 (black) to 255 (white). A pixel of a color image is 3 bytes, the levels of red, green and blue. An image of width \(W\) and height \(H\) stores its pixels row by row: pixel \((x, y)\), in column \(x\) of row \(y\), is byte \(yW + x\) of a gray image, and its 3 bytes start at byte \(3(yW + x)\) of a color image.
Example. In an image of width 8, pixel \((3, 0)\) is byte 3 of the gray image, and its color bytes are bytes 9, 10 and 11.
The formula \(yW + x\) counts the pixels that come before pixel \((x, y)\): the \(y\) whole rows above it, of \(W\) pixels each, and the \(x\) pixels to its left in its own row. For example, in an image of width 8, pixel \((2, 3)\) is byte \(3 \cdot 8 + 2 = 26\) of the gray image, and its color bytes start at byte \(3 \cdot 26 = 78\). We always write a pixel position as \((x, y)\), column first, as in the figures of this chapter, whose column numbers run across the top and whose row numbers run down the left side.
24.1.2 The worked example
We use 1 image throughout the chapter, shown in Figure 24.1. It has 8 × 8 pixels of 4 colors, 16 pixels of each color. There are 2 rows of sky at the top and 2 rows of ground at the bottom, and between them, a house of 4 × 4 pixels with hill on both sides. The test image of the programs, described in Section 24.8, is the same kind of scene at 1,920 × 1,080 pixels.
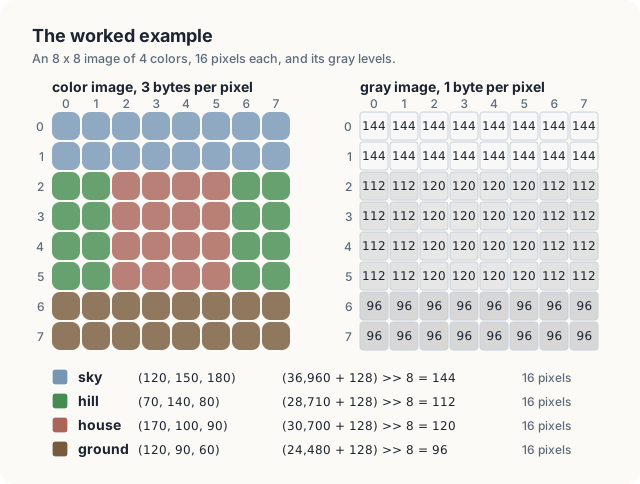
The 4 gray levels, 96, 112, 120 and 144, lie within 48 of each other, on a scale that runs from 0 to 255. The image therefore has low contrast. Its darkest pixel is a dark gray, its brightest pixel is a light gray, and the hill and the house differ by only 8 levels. The pipeline improves the image in 4 stages.
- Gray conversion replaces each color pixel by 1 level (Figure 24.1, right).
- Histogram equalization spreads the levels in use over the whole scale. The 4 levels move to 0, 85, 170 and 255.
- A Gaussian blur replaces each pixel by a weighted average of the 5 × 5 pixels around it, which removes noise and softens the steps between regions.
- Sobel edges measure how fast the level changes at each pixel. The result is bright where 2 regions meet and dark inside a region.
Each stage reads the image that the previous stage wrote. What distinguishes the stages, from the point of view of a parallel program, is the number of input pixels on which 1 output pixel depends. We name the three cases that occur.
Definition 24.2 Point, neighborhood and global operations. An image operation is a point operation if each output pixel depends only on the input pixel at the same position. It is a neighborhood operation if each output pixel depends on a small window of input pixels around its position. It is a global operation if its result depends on every pixel of the image.
Example. Gray conversion is a point operation; the blur, with a window of 5 × 5, and the Sobel detector, with a window of 3 × 3, are neighborhood operations; equalization contains a global operation, the histogram of all 64 levels.
Figure 24.2 shows the pipeline as the 7 kernels of our programs, together with the buffers between them. The equalization takes three kernels and the blur takes 2, for reasons that we explain in Sections 24.4 and 24.5. Figure 24.3 shows what the programs produce for their test image of 1,920 × 1,080 pixels.
Note that equalization strengthens the grain of the test image together with the scene, because it stretches every difference between levels, including the small random ones. The blur removes most of the grain before the edge detector runs, so the edge image shows the outlines of the objects and only a faint texture elsewhere.
Exercises
24.1 At which byte of a gray image of width 1,920 is pixel \((10, 2)\) stored? At which bytes are
its 3 color bytes?
24.2 In the example, which pixels does the blur of pixel \((0, 0)\) depend on, if positions
outside the image are not counted? Which pixels does the equalized level of pixel \((0, 0)\)
depend on?
24.3 Classify as point, neighborhood or global: inverting an image (\(255 - v\)); finding its
brightest level; replacing each pixel by the median of its 3 × 3 window.
24.2 The sequential pipeline
24.2.1 The algorithm
On a CPU, the 4 stages become a sequence of loops. One detail must be settled first. A blur window near the border of the image reaches past the border, so we need a level for positions outside the image. We let such a position take the level of the nearest pixel inside the image, and we write
\[ \mathrm{clamp}(i, n) = \min(\max(i, 0), n - 1) \]
for this rule. Here \(i\) is a column or row number that may lie outside the image, and \(n\) is the width or the height. For example, with \(n = 8\), \(\mathrm{clamp}(-2, 8) = 0\), \(\mathrm{clamp}(5, 8) = 5\) and \(\mathrm{clamp}(9, 8) = 7\). The 5 weights of the blur are \(w = (1, 4, 6, 4, 1)\), and we explain them in Section 24.5.
Image-Pipeline(\(\mathsf{rgb}, W, H\))
- for \(\mathsf{pixel} \in [0, W \cdot H)\) {
- \(\mathsf{byte} = 3 \cdot \mathsf{pixel}\) // the first of its 3 bytes
- \(\mathsf{gray}[\mathsf{pixel}] = (77\, \mathsf{rgb}[\mathsf{byte}] + 150\, \mathsf{rgb}[\mathsf{byte}+1] + 29\, \mathsf{rgb}[\mathsf{byte}+2] + 128) \gg 8\)
- }
- \(\mathsf{bins}[\mathsf{level}] = 0\) for every \(\mathsf{level} \in [0, 256)\)
- for \(\mathsf{pixel} \in [0, W \cdot H)\) {
- \(\mathsf{bins}[\mathsf{gray}[\mathsf{pixel}]] = \mathsf{bins}[\mathsf{gray}[\mathsf{pixel}]] + 1\) // histogram
- }
- \(\mathsf{total} = 0\)
- for \(\mathsf{level} \in [0, 256)\) {
- \(\mathsf{total} = \mathsf{total} + \mathsf{bins}[\mathsf{level}]\), \(\;\mathsf{cdf}[\mathsf{level}] = \mathsf{total}\) // scan
- }
- \(\mathsf{first} = \mathsf{cdf}[\mathsf{level}]\) for the lowest \(\mathsf{level}\) with \(\mathsf{bins}[\mathsf{level}] > 0\), \(\;\mathsf{span} = W \cdot H - \mathsf{first}\)
- for \(\mathsf{level} \in [0, 256)\) {
- \(\mathsf{table}[\mathsf{level}] = \lfloor (\max(\mathsf{cdf}[\mathsf{level}] - \mathsf{first}, 0) \cdot 255 + \lfloor \mathsf{span}/2 \rfloor) / \mathsf{span} \rfloor\)
- }
- for \(\mathsf{pixel} \in [0, W \cdot H)\) {
- \(\mathsf{equal}[\mathsf{pixel}] = \mathsf{table}[\mathsf{gray}[\mathsf{pixel}]]\)
- }
- for \(y \in [0, H)\), \(x \in [0, W)\) {
- \(\mathsf{rows}[y][x] = \sum_{j \in [0,5)} w_j \cdot \mathsf{equal}[y][\mathrm{clamp}(x + j - 2, W)]\)
- }
- for \(y \in [0, H)\), \(x \in [0, W)\) {
- \(\mathsf{blurred}[y][x] = (\sum_{i \in [0,5)} w_i \cdot \mathsf{rows}[\mathrm{clamp}(y + i - 2, H)][x] + 128) \gg 8\)
- }
- for \(y \in [0, H)\), \(x \in [0, W)\) {
- \((g_x, g_y) = \) Sobel\((\mathsf{blurred}, x, y)\)
- \(\mathsf{edges}[y][x] = \min(\lfloor \sqrt{g_x^2 + g_y^2}\,/\,4 + 1/2 \rfloor, 255)\)
- }
Lines 1 to 4 convert to gray, lines 5 to 19 equalize, lines 20 to 25 blur in 2 passes, and lines 26 to 29 compute the edges. The symbol \(\gg 8\) is a shift right by 8 bits, which is a division by 256 that discards the remainder; for example, \(37{,}088 \gg 8 = 144\). In lines 13 and 15, \(\mathsf{first}\) is the cumulative count of the darkest level in use, and \(\mathsf{span}\) is the number of pixels above that level. In the example, \(\mathsf{first} = 16\) and \(\mathsf{span} = 64 - 16 = 48\). In Sections 24.3 to 24.6, we explain each group of lines on the example. In this section, we count the work and examine what each line depends on.
24.2.2 Counting the work
Lines 2 and 3 run once for each pixel, 64 times in our example, with 3 multiplications each time. Lines 7 and 18 also run 64 times. Lines 11 and 15 run 256 times, once for each possible level, whatever the size of the image. Lines 21 and 24 each run 64 times with 5 multiply-adds, which makes 320 multiply-adds per pass. Line 27 reads the 8 neighbors of each of the 64 outputs and adds 12 weighted terms. The example therefore needs 192 multiplications for the gray levels, 640 multiply-adds for the blur and 768 weighted terms for the edges, and the CPU performs them one after another.
In general, with \(N = W \cdot H\) pixels, every line except lines 11 and 15 runs \(N\) times. For an image of 1,920 × 1,080 pixels, \(N = 2{,}073{,}600\), and the 2 blur passes alone perform \(2 \cdot 5N = 20{,}736{,}000\) multiply-adds. In Section 24.10, we measure the whole sequence on 8 CPU cores at 38 to 51 images per second.
24.2.3 What each line depends on
The sequential order of the loops hides how little most lines need. Lines 2 and 3 compute \(\mathsf{gray}[\mathsf{pixel}]\) from the 3 bytes of pixel \(\mathsf{pixel}\) and from nothing else. Line 18 reads \(\mathsf{gray}[\mathsf{pixel}]\) and 1 entry of a table of 256 bytes. Line 21 reads 5 pixels of 1 row, line 24 reads 5 row sums of 1 column, and line 27 reads the 3 × 3 pixels around \((x, y)\). For each of these lines, every output could be computed at the same time as every other output, as soon as its few inputs exist.
Lines 5 to 15 are different. The table entry of line 15 needs \(\mathsf{cdf}[\mathsf{level}]\), which counts every pixel of the image with a level of at most \(\mathsf{level}\). For example, \(\mathsf{cdf}[112] = 32\) counts the 16 pixels of level 96 and the 16 pixels of level 112, wherever they lie in the image. No entry of the table, and therefore no pixel of the equalized image, can be computed until the histogram of the whole image is complete.
Key observation Each stage of the pipeline is a pattern of Part V, decided by how many input pixels 1 output pixel depends on: 1 pixel (a map), a small window (a stencil), or all pixels (a histogram followed by a scan). The patterns give the kernels; the pipeline connects them, in an order that only the histogram constrains.
Exercises
24.4 How many times does line 21 read each pixel of the equalized image, away from the border? How
many times does line 27 read each pixel of the blurred image?
24.5 Lines 11 and 15 run 256 times for an image of any size. What fraction of the work of
Image-Pipeline do they represent for the image of 1,920 × 1,080 pixels?
24.6 Which lines of Image-Pipeline could start on pixel \(\mathsf{pixel}\) before lines 2 and 3 have finished every
pixel? Which could not, and why?
24.3 Conversion to gray
24.3.1 The weights
A gray image needs 1 level per pixel, so we must combine the 3 levels of a color pixel into 1. The plain average would be the simplest choice, but it does not match what a viewer sees, because the eye is most sensitive to green and least sensitive to blue. A pure green pixel therefore looks brighter than a pure blue pixel of the same level. The ITU-R BT.601 standard weighs the 3 levels accordingly: \[ Y = 0.299\,R + 0.587\,G + 0.114\,B. \]
| Symbol | Meaning | For the sky of the example |
|---|---|---|
| \(R, G, B\) | levels of red, green and blue of the pixel | 120, 150, 180 |
| 0.299, 0.587, 0.114 | weights of the 3 colors, summing to 1 | |
| \(Y\) | perceived brightness, the gray level | 144.45 |
For the sky, \(Y = 0.299 \cdot 120 + 0.587 \cdot 150 + 0.114 \cdot 180 = 35.88 + 88.05 + 20.52 = 144.45\).
Our programs compute with the same weights in integers. Each weight is multiplied by 256 and rounded to the nearest integer: \(0.299 \cdot 256 = 76.5\) becomes 77, \(0.587 \cdot 256 = 150.3\) becomes 150, and \(0.114 \cdot 256 = 29.2\) becomes 29. The 3 integers sum to exactly 256, so a white pixel (255, 255, 255) gives \(255 \cdot 256\) and keeps level 255 after the division by 256. The division is a shift right by 8 bits. Adding 128, half of 256, before the shift makes the division round to the nearest level instead of down. For the sky, we obtain \[ 77 \cdot 120 + 150 \cdot 150 + 29 \cdot 180 = 9{,}240 + 22{,}500 + 5{,}220 = 36{,}960, \qquad (36{,}960 + 128) \gg 8 = 144, \] which is the floating-point value 144.45, rounded. Figure 24.1 lists the same computation for the other 3 colors.
We use integers for a reason that we make precise in Section 24.8. The programs compare every pixel of the GPU’s output with the CPU’s output, and they can demand exact equality only if both processors perform exactly the same operations. Integer additions and multiplications give the same result on every processor. Floating-point expressions do not always do so, because the GPU compiler may fuse a multiplication and an addition into 1 instruction that rounds once instead of twice. In Chapter 10, we measured such differences on 585,903 of 2,097,152 values.
24.3.2 The kernel
Gray conversion is a map, the pattern of Chapter 14, and its kernel therefore gives each pixel its own thread. We first restate the terms that we need.
Definition 24.3 Kernel, thread, block and grid. A kernel is a function that the GPU runs many times at once, and each run is a thread. Threads are grouped into blocks of up to 1,024 threads; the threads of a block run on the same processor of the GPU, a streaming multiprocessor (SM), and can share a small fast memory and wait for one another. The grid is the set of all blocks of 1 launch. Each thread reads its position from the built-in values \(\mathsf{blockIdx}\), \(\mathsf{blockDim}\) and \(\mathsf{threadIdx}\).
Example. The gray kernel for the 8 × 8 example could run as 1 block of 64 threads; thread 3 converts pixel \((3, 0)\).
Gray-Kernel(\(\mathsf{rgb}, \mathsf{gray}, W, H\))
- \(\mathsf{pixel} = \mathsf{blockIdx{.}x} \cdot \mathsf{blockDim{.}x} + \mathsf{threadIdx{.}x}\)
- if \(\mathsf{pixel} \in [0, W \cdot H)\) {
- \(\mathsf{red} = \mathsf{rgb}[3 \cdot \mathsf{pixel}]\), \(\;\mathsf{green} = \mathsf{rgb}[3 \cdot \mathsf{pixel} + 1]\), \(\;\mathsf{blue} = \mathsf{rgb}[3 \cdot \mathsf{pixel} + 2]\) // 3 reads
- \(\mathsf{gray}[\mathsf{pixel}] = (77 \cdot \mathsf{red} + 150 \cdot \mathsf{green} + 29 \cdot \mathsf{blue} + 128) \gg 8\) // 1 write
- }
Line 1 gives each thread a pixel number \(\mathsf{pixel}\). Line 2 skips the threads of the last block whose number lies past the end of the image, since such threads have no pixel to convert. Figure 24.4 follows thread 3 of the example. It reads bytes 9, 10 and 11, computes 144, and writes byte 3 of the gray image. This makes 3 reads from global memory and 1 write, and no other thread is involved.
The GPU runs the threads of a block in groups of 32, and the order of the bytes in memory decides how fast the reads of such a group are served.
Definition 24.4 Warp and coalesced access. A warp is a group of 32 consecutive threads of a block that execute the same instruction together; its threads are its lanes 0 to 31. An access of a warp to global memory is coalesced when its 32 addresses fall into as few aligned segments of 32 bytes as the data allow, so that the memory system serves the whole warp with a few transfers.
Example. The 32 threads of a warp of the gray kernel read pixels \(\mathsf{pixel}\) to \(\mathsf{pixel} + 31\), which are 96 consecutive bytes of the color image, and the memory system serves each of the 3 read instructions from the same 3 segments of 32 bytes.
For the image of 1,920 × 1,080 pixels, the programs launch 8,100 blocks of 256 threads, and since \(8{,}100 \cdot 256 = 2{,}073{,}600\), this is exactly one thread per pixel. The following kernels implement lines 1 to 5 of Gray-Kernel.
mod kernels {
// ...
/// 1 thread per pixel. BT.601 weights in 8-bit fixed point: 77 + 150 + 29 = 256.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn grayscale(rgb: &[u8], mut gray: DisjointSlice<u8>) {
let idx = thread::index_1d();
let byte = 3 * idx.get();
if let Some(gray_pixel) = gray.get_mut(idx) {
let (red, green) = (rgb[byte] as u32, rgb[byte + 1] as u32);
let blue = rgb[byte + 2] as u32;
*gray_pixel = ((77 * red + 150 * green + 29 * blue + 128) >> 8) as u8;
}
}
// ...
}// 1 thread per pixel. BT.601 weights in 8-bit fixed point: 77 + 150 + 29 = 256.
__global__ void grayscale(const uint8_t* rgb, uint8_t* gray)
{
int pixel = blockIdx.x * blockDim.x + threadIdx.x;
if (pixel < PIXELS) {
unsigned red = rgb[3 * pixel];
unsigned green = rgb[3 * pixel + 1];
unsigned blue = rgb[3 * pixel + 2];
gray[pixel] = (77 * red + 150 * green + 29 * blue + 128) >> 8;
}
}
In Rust, thread::index_1d() is line 1, and the test of line 2 is the call gray.get_mut(idx). The
output is a DisjointSlice, a slice that hands each thread only the element of its own index, and
get_mut returns None for a thread whose index lies past the end, so the write needs no unsafe
block. The attribute #[launch_contract(domain = 1, block = (256, 1, 1))] records the block shape.
The host must prepare every launch against it, and a launch with another shape is refused on the
host before it reaches the GPU. The C++ kernel tests the index itself and writes through a raw
pointer. In both languages, the levels are widened to 32-bit integers before the multiplication,
because \(77 \cdot 255 = 19{,}635\) does not fit in a byte.
24.3.3 Weights that do not sum to 256
A common mistake is to truncate the 3 weights instead of rounding them. Since \(0.299 \cdot 256 = 76.54\), truncation gives 76, and the 3 weights 76, 150 and 29 then sum to 255 instead of 256. Every level then comes out slightly too dark, and the error grows with the level. The sky keeps level 144, since \((76 \cdot 120 + 22{,}500 + 5{,}220 + 128) \gg 8 = 36{,}968 \gg 8 = 144\), but a white pixel gives \((255 \cdot 255 + 128) \gg 8 = 65{,}153 \gg 8 = 254\) instead of 255. A test image with no white pixel does not reveal the mistake, whereas a test that converts (255, 255, 255) does.
Exercises
24.7 Convert the pixels (255, 0, 0), (0, 255, 0) and (0, 0, 255) with the integer weights. Explain
why the 3 results differ.
24.8 A warp of the gray kernel reads 96 bytes with 3 load instructions. How many bytes would each
load instruction move if each thread converted 4 pixels and read its 12 bytes as 3 words of 4
bytes?
24.9 Without the 128 in line 4, which of the 4 colors of the example changes its gray level?
24.4 Histogram equalization
24.4.1 The method on the example
The image of the example uses only 4 levels, which lie between 96 and 144, while the scale offers 256 levels between 0 and 255. We would like the levels in use to spread over the whole scale, with the darkest level in use becoming black and the brightest becoming white. Equalization achieves this by moving each level to a new level in proportion to the number of pixels at or below it. It needs 2 quantities, which we now define.
Definition 24.5 Histogram and cumulative count. The histogram of a gray image counts, for each level \(v \in [0, 256)\), the pixels whose level is \(v\); we call the counts \(\mathsf{bins}[v]\). The cumulative count \(c(v)\) is the number of pixels whose level is at most \(v\), \(c(v) = \sum_{u \le v} \mathsf{bins}[u]\). The sequence \(c\) is the inclusive scan of the histogram (Chapter 21).
Example. The gray image of Figure 24.1 has \(\mathsf{bins}[96] = \mathsf{bins}[112] = \mathsf{bins}[120] = \mathsf{bins}[144] = 16\) and every other count 0. Its cumulative counts are \(c(96) = 16\), \(c(112) = 32\), \(c(120) = 48\) and \(c(144) = 64\).
The cumulative count tells us what fraction of the pixels is at least as dark as a given level. If 50% of the pixels have a level of at most \(v\), equalization moves \(v\) to about 50% of 255. Since the darkest level in use should become 0 and the brightest should become 255, we subtract the cumulative count \(c_{\min}\) of the darkest level in use, and we divide by what remains.
Definition 24.6 Equalization table. For an image of \(N\) pixels, let \(c_{\min}\) be the cumulative count at the lowest level in use. The equalization table maps level \(v\) to \[ \mathrm{new}(v) = \mathrm{round}\left(\frac{\max(c(v) - c_{\min}, 0)}{N - c_{\min}} \cdot 255\right), \] and the equalized image replaces each level \(v\) by \(\mathrm{new}(v)\).
Example. With \(N = 64\) and \(c_{\min} = c(96) = 16\), \(\mathrm{new}(112) = \mathrm{round}(16 \cdot 255 / 48) = 85\).
| Symbol | Meaning | For level 112 of the example |
|---|---|---|
| \(N\) | number of pixels in the image | 64 |
| \(c(v)\) | number of pixels with a level of at most \(v\) | \(c(112) = 32\) |
| \(c_{\min}\) | cumulative count at the darkest level in use | \(c(96) = 16\) |
| \(c(v) - c_{\min}\) | pixels above the darkest level and at most \(v\) | 16 |
| \(N - c_{\min}\) | pixels above the darkest level | 48 |
| \(\mathrm{new}(v)\) | equalized level | \(\mathrm{round}(16 / 48 \cdot 255) = 85\) |
The fraction in the formula runs from 0 at the darkest level in use to 1 at the brightest level in use, and the factor 255 stretches it over the whole scale. Figure 24.5 works the whole table. Level 96 moves to \(\mathrm{round}(0 \cdot 255 / 48) = 0\), level 120 to \(\mathrm{round}(32 \cdot 255 / 48) = 170\), and level 144 to \(\mathrm{round}(48 \cdot 255 / 48) = 255\). The 4 levels, which were within 48 of each other, now cover the whole scale in equal steps of 85, because each of them holds a quarter of the pixels. In the programs, line 15 of Image-Pipeline performs the rounding in integers. For a numerator \(a\) and a denominator \(s\), the expression \(\lfloor (a + \lfloor s/2 \rfloor) / s \rfloor\) is \(a / s\) rounded to the nearest integer, and for level 112, it gives \(\lfloor (4{,}080 + 24) / 48 \rfloor = 85\).
The cumulative count never decreases as \(v\) grows, and therefore neither does \(\mathrm{new}(v)\). Hence 2 pixels that were in a given order of brightness keep that order. Equalization changes the contrast of an image, not its arrangement of light and dark.
The method splits into 3 steps with different patterns: the histogram, which is a global operation, the table of 256 entries, which is a scan, and the replacement of each level, which is a map. Each step needs the previous one to be complete, so the programs use 1 kernel for each step.
24.4.2 The histogram kernel
In a histogram kernel, many threads add to the same few counters, and their additions must not interfere with each other. Recall that in Chapter 22, we solved this problem with atomic operations and with private counters for each block. We restate the terms here.
Definition 24.7 Shared memory, barrier and atomic operation. Shared memory is a small memory on each SM that the threads of 1 block share; it answers in a few cycles, and its contents last as long as the block. A barrier is a point in a kernel that no thread of a block passes until every thread of the block has reached it. An atomic operation reads a memory word, changes it and writes it back as 1 step, so that no other thread can access the word in between.
Example. 2 threads that add 1 to the same counter with an atomic addition always leave it 2 higher.
Each block of the histogram kernel counts into its own 256 counters in shared memory, and it adds them to the global counters only once, at the end. The following procedure gives the details.
Histogram-Kernel(\(\mathsf{gray}, \mathsf{bins}, N\))
- \(\mathsf{stride} = \mathsf{gridDim{.}x} \cdot 256\) // threads in the grid
- \(\mathsf{local}[\mathsf{threadIdx{.}x}] = 0\) // 256 threads clear 256 counters
- Barrier()
- for \(\mathsf{pixel} = \mathsf{blockIdx{.}x} \cdot 256 + \mathsf{threadIdx{.}x}\); \(\mathsf{pixel} < N\); \(\mathsf{pixel} = \mathsf{pixel} + \mathsf{stride}\) {
- Atomic-Add\((\mathsf{local}[\mathsf{gray}[\mathsf{pixel}]], 1)\) // shared memory
- }
- Barrier()
- if \(\mathsf{local}[\mathsf{threadIdx{.}x}] > 0\) {
- Atomic-Add\((\mathsf{bins}[\mathsf{threadIdx{.}x}], \mathsf{local}[\mathsf{threadIdx{.}x}])\) // global memory
- }
Line 1 computes the number of threads in the grid, and line 2 clears the counters, 1 per thread. The loop of lines 4 to 6 walks through the image with a stride of the whole grid, that is, a thread advances by the total number of threads, \(\mathsf{gridDim{.}x} \cdot 256\), from 1 pixel to its next. Line 5 counts each pixel in the block’s own counter for its level. The barrier of line 3 ensures that no count starts before every counter is 0, and the barrier of line 7 ensures that no block total is read before every count of the block is done. Lines 8 to 10 add the block’s 256 totals to the global histogram, skipping the counters that stayed at 0.
For the image of 1,920 × 1,080 pixels, the programs launch 64 blocks of 256 threads, 16,384 threads in all, so each thread counts 2,073,600 / 16,384 = 126.6 pixels, that is, 126 or 127. The global counters therefore receive at most \(64 \cdot 256 = 16{,}384\) atomic additions instead of 2,073,600. For the 8 × 8 example, 1 block would suffice. Threads 0 to 63 would each count 1 pixel, and threads 96, 112, 120 and 144 would each add 16 to the global counter of their level.
mod kernels {
// ...
/// Counts gray levels in shared bins, then adds each block's bins to the global ones.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn histogram(gray: &[u8], bins: &[DeviceAtomicU32]) {
static mut LOCAL: SharedArray<u32, 256> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
// SAFETY: each thread zeroes only its own bin, before the barrier.
unsafe { LOCAL[tid] = 0 };
thread::sync_threads();
let stride = (thread::gridDim_x() * 256) as usize;
let mut pixel = thread::index_1d().get();
while pixel < gray.len() {
// SAFETY: between the 2 barriers every access to LOCAL is atomic.
let bin = unsafe {
let base = (*&raw mut LOCAL).as_mut_ptr();
BlockAtomicU32::from_ptr(base.add(gray[pixel] as usize))
};
bin.fetch_add(1, AtomicOrdering::Relaxed);
pixel += stride;
}
thread::sync_threads();
// SAFETY: after the barrier no thread writes LOCAL again.
let local = unsafe { LOCAL[tid] };
if local > 0 {
bins[tid].fetch_add(local, AtomicOrdering::Relaxed);
}
}
// ...
}// Counts gray levels in shared bins, then adds each block's bins to the global ones.
__global__ void histogram(const uint8_t* gray, unsigned* bins)
{
__shared__ unsigned local[256];
local[threadIdx.x] = 0;
__syncthreads();
int stride = gridDim.x * 256;
for (int pixel = blockIdx.x * 256 + threadIdx.x; pixel < PIXELS; pixel += stride) {
atomicAdd(&local[gray[pixel]], 1u);
}
__syncthreads();
if (local[threadIdx.x] > 0) {
atomicAdd(&bins[threadIdx.x], local[threadIdx.x]);
}
}
The two kernels follow Histogram-Kernel line by line, and they differ only in how they reach shared
memory. C++ declares __shared__ unsigned local[256] and calls atomicAdd on an element. Rust
declares static mut LOCAL: SharedArray<u32, 256> and turns the address of an element into a
BlockAtomicU32, an integer whose operations are atomic among the threads of 1 block, which is all
that shared memory needs. The global counters are a slice of DeviceAtomicU32, whose operations are
atomic among all threads of the device. Every direct access to LOCAL is unsafe, because the
compiler cannot check how concurrent threads use shared memory. Each // SAFETY: comment states
the argument instead, which rests on the 2 barriers of the pseudocode.
24.4.3 The table kernel
The table needs the scan of the 256 counts and the value \(\mathsf{cumulative}_{\min}\). A scan of 256 values is small, so a single block of 256 threads computes it, with thread \(\mathsf{level}\) responsible for level \(\mathsf{level}\). As in the block scan of Chapter 21, the block first scans each warp with register shuffles and then scans the 8 warp totals.
Table-Kernel(\(\mathsf{bins}, \mathsf{table}\))
- \(\mathsf{level} = \mathsf{threadIdx{.}x}\), \(\;\mathsf{lane} = \mathsf{level} \bmod 32\), \(\;\mathsf{warp} = \lfloor \mathsf{level} / 32 \rfloor\)
- \(\mathsf{count} = \) Atomic-Exchange\((\mathsf{bins}[\mathsf{level}], 0)\) // read and clear
- \(\mathsf{partial} = \) Warp-Scan\((\mathsf{count})\) // inclusive, within the warp
- if \(\mathsf{lane} = 31\) { \(\mathsf{warps}[\mathsf{warp}] = \mathsf{partial}\) }
- if \(\mathsf{level} = 0\) { \(\mathsf{first} = \infty\) }
- Barrier()
- if \(\mathsf{warp} = 0\) and \(\mathsf{lane} < 8\) { \(\mathsf{warps}[\mathsf{lane}] = \) Warp-Scan\((\mathsf{warps}[\mathsf{lane}])\) }
- Barrier()
- \(\mathsf{cumulative} = \mathsf{partial} + \mathsf{warps}[\mathsf{warp} - 1]\) if \(\mathsf{warp} > 0\), else \(\mathsf{cumulative} = \mathsf{partial}\) // cumulative = c(level)
- if \(\mathsf{count} > 0\) { Atomic-Min\((\mathsf{first}, \mathsf{cumulative})\) }
- Barrier()
- \(\mathsf{span} = \mathsf{warps}[7] - \mathsf{first}\)
- \(\mathsf{table}[\mathsf{level}] = \lfloor (\max(\mathsf{cumulative} - \mathsf{first}, 0) \cdot 255 + \lfloor \mathsf{span}/2 \rfloor) / \mathsf{span} \rfloor\)
In the procedure, \(\mathsf{lane}\) is the position of thread \(\mathsf{level}\) in its warp and \(\mathsf{warp}\) the number of its warp; for thread 112, for example, \(\mathsf{lane} = 16\) and \(\mathsf{warp} = 3\). The array \(\mathsf{warps}\) in shared memory holds the 8 warp totals, and \(\mathsf{first}\) receives the smallest cumulative count of a level in use, which is \(\mathsf{cumulative}_{\min}\).
Let us follow the example. The 4 levels in use belong to 2 warps. Warp 3 holds threads 96 to 127, and its scan gives 16 at lane 0 (level 96), 32 at lane 16 (level 112), and 48 from lane 24 (level 120) to lane 31, so \(\mathsf{warps}[3] = 48\). Warp 4 holds level 144 at lane 16, so \(\mathsf{warps}[4] = 16\). After line 7, the scanned warp totals are 0, 0, 0, 48, 64, 64, 64 and 64, and line 9 gives thread 144 the count \(\mathsf{cumulative} = 16 + 48 = 64\). Line 10 leaves \(\mathsf{first} = 16\), the smallest cumulative count among the 4 levels in use, which is \(\mathsf{cumulative}_{\min}\). The total number of pixels is the last warp total, \(\mathsf{warps}[7] = 64\), so the kernel needs no parameter for \(N\).
Line 2 reads each count with an atomic exchange, which returns the old value and stores 0. The kernel therefore leaves the global histogram cleared for the next image, and the pipeline needs no separate launch to clear it. In the programs, line 13 works in 64-bit integers, because \(\max(\mathsf{cumulative} - \mathsf{first}, 0) \cdot 255\) reaches \(2{,}073{,}600 \cdot 255 = 528{,}768{,}000\) for the large image, which is close to the limit of a 32-bit integer. Line 12 gives a span of 0 for an image of a single level, and in that case, the programs keep every level unchanged.
mod kernels {
// ...
/// 1 block of 256 threads, 1 thread per gray level: the cumulative count of the level,
/// then its new level. Each bin is read and reset to 0 for the next image.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn equalise_table(bins: &[DeviceAtomicU32], mut table: DisjointSlice<u8>) {
static mut WARPS: SharedArray<u32, 8> = SharedArray::UNINIT;
static mut FIRST: SharedArray<u32, 1> = SharedArray::UNINIT;
let level = thread::threadIdx_x() as usize;
let lane = warp::lane_id() as usize;
let warp = level / 32;
let count = bins[level].swap(0, AtomicOrdering::Relaxed);
let inclusive = warp_scan(count);
if lane == 31 {
// SAFETY: lane 31 of each warp writes its own slot, before the barrier.
unsafe { WARPS[warp] = inclusive };
}
if level == 0 {
// SAFETY: only thread 0 writes FIRST before the barrier.
unsafe { FIRST[0] = u32::MAX };
}
thread::sync_threads();
if warp == 0 {
// SAFETY: only warp 0 touches WARPS between the 2 barriers.
let warp_total = if lane < 8 { unsafe { WARPS[lane] } } else { 0 };
let scanned_total = warp_scan(warp_total);
if lane < 8 {
unsafe { WARPS[lane] = scanned_total };
}
}
thread::sync_threads();
// SAFETY: WARPS is only read from here on; FIRST is changed only atomically.
let cdf = inclusive + if warp > 0 { unsafe { WARPS[warp - 1] } } else { 0 };
let first = unsafe { BlockAtomicU32::from_ptr((*&raw mut FIRST).as_mut_ptr()) };
if count > 0 {
first.fetch_min(cdf, AtomicOrdering::Relaxed);
}
thread::sync_threads();
let min = first.load(AtomicOrdering::Relaxed);
let span = (unsafe { WARPS[7] } - min) as u64;
let above = cdf.saturating_sub(min) as u64;
let new_level = if span == 0 {
level as u64
} else {
(above * 255 + span / 2) / span
};
if let Some(entry) = table.get_mut(thread::index_1d()) {
*entry = new_level as u8;
}
}
// ...
}// 1 block of 256 threads, 1 thread per gray level: the cumulative count of the level,
// then its new level. Each bin is read and reset to 0 for the next image.
__global__ void equaliseTable(unsigned* bins, uint8_t* table)
{
__shared__ unsigned warps[8];
__shared__ unsigned first;
int level = threadIdx.x;
int lane = level % 32;
int warp = level / 32;
unsigned count = atomicExch(&bins[level], 0u);
unsigned inclusive = warpScan(count);
if (lane == 31) {
warps[warp] = inclusive;
}
if (level == 0) {
first = 0xffffffffu;
}
__syncthreads();
if (warp == 0) {
unsigned scannedTotal = warpScan(lane < 8 ? warps[lane] : 0);
if (lane < 8) {
warps[lane] = scannedTotal;
}
}
__syncthreads();
unsigned cdf = inclusive + (warp > 0 ? warps[warp - 1] : 0);
if (count > 0) {
atomicMin(&first, cdf);
}
__syncthreads();
uint64_t span = warps[7] - first;
uint64_t above = cdf > first ? cdf - first : 0;
uint64_t newLevel = span == 0 ? level : (above * 255 + span / 2) / span;
table[level] = newLevel;
}
The 3 barriers of Table-Kernel are the 3 calls to sync_threads() and __syncthreads(). All of
them lie outside every if, so every thread of the block reaches them. Line 13 writes the table
through table.get_mut(...) in Rust, which is again a DisjointSlice, and through a plain store in
C++. The scan inside a warp is the device function warp_scan (warpScan in C++), which adds the
value of the lane 1, 2, 4, 8 and 16 places lower with shuffle_up_sync (__shfl_up_sync). We
derived this function in Chapter 21.
24.4.4 Applying the table
The last step of the equalization is a map. In the following kernels, each thread reads 1 gray level and writes the entry of the table for that level.
mod kernels {
// ...
/// 1 thread per pixel: the new level of each pixel, looked up in the table.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn apply_table(gray: &[u8], table: &[u8], mut out: DisjointSlice<u8>) {
let idx = thread::index_1d();
let pixel = idx.get();
if let Some(cell) = out.get_mut(idx) {
*cell = table[gray[pixel] as usize];
}
}
// ...
}// 1 thread per pixel: the new level of each pixel, looked up in the table.
__global__ void applyTable(const uint8_t* gray, const uint8_t* table, uint8_t* out)
{
int pixel = blockIdx.x * blockDim.x + threadIdx.x;
if (pixel < PIXELS) {
out[pixel] = table[gray[pixel]];
}
}
The read table[gray[i]] is a gather, a read whose address depends on data. The 32 threads of a
warp read 32 entries of the table at unpredictable positions, which is the opposite of a coalesced
access. The table holds only 256 bytes, however, so after the first accesses, it stays in the L1
cache of each SM, and the gathers cost little.
24.4.5 A histogram without atomic additions
A common mistake in the histogram is to count with a plain addition, local[gray[i]] += 1. Such an
addition takes 3 steps, a read, an add and a write, and 2 threads that count the same level can
interleave these steps, as shown in Figure 24.6. Both threads read the old count 7, both write 8,
and 1 of the 2 pixels is lost.
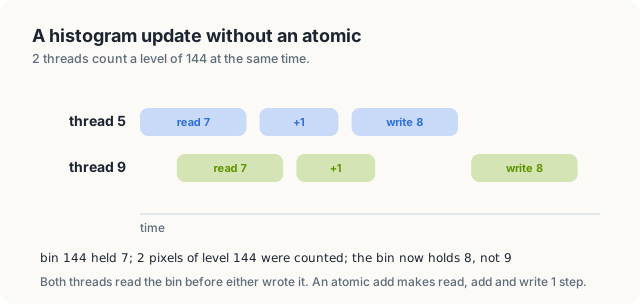
On the example, 16 threads of 1 block count the 16 sky pixels, all of them of level 144. If they lose any of their additions, \(\mathsf{bins}[144]\) ends below 16, the total \(\mathsf{warps}[7]\) ends below 64, and the table changes. We ran the C++ program with this 1 change, and it printed the following report.
$ ./capstone # local[gray[i]] += 1, no atomicAdd
...
image pixels that differ from the CPU
gray 0
equalised 1961635 first at (0, 0): GPU 104, CPU 97
blurred 1988211 first at (0, 0): GPU 112, CPU 106
edges 1302442 first at (0, 0): GPU 9, CPU 10
...
FAILED
The gray image is still right, but 1,961,635 of the 2,073,600 equalized pixels, 95%, are wrong. A lost count lowers the cumulative count of its level and of every level above it, and with it, the table entry of almost every level. For example, pixel \((0, 0)\) became 104 instead of 97. The error then passes through the blur and the edges. Note also that the histogram stage of this broken program ran in 0.050 ms instead of about 0.12 ms, because plain additions do not wait for one another. A faster kernel is therefore no evidence of a correct one.
Exercises
24.10 Compute the equalization table for an image of 10 pixels with the levels 4, 4, 4, 5, 5, 6, 6,
6, 6, 7, on a scale of 8 levels (replace 255 by 7).
24.11 In Table-Kernel, why must line 10 run after the barrier of line 8 and not before it?
24.12 Histogram-Kernel is launched with 64 blocks. How many atomic additions reach global memory
for the 8 × 8 example with 1 block, and for the large image with 64 blocks?
24.5 A separable Gaussian blur
24.5.1 The weights
A blur replaces each pixel by a weighted average of the pixels around it. Averaging removes small random differences between neighboring pixels, such as the grain of the test image, at the cost of softening the edges between regions. A Gaussian blur uses weights that fall off with the distance from the center in the shape of the normal distribution, so that near pixels count more than far ones. We use the 5 weights \(w = (1, 4, 6, 4, 1)\) in each direction. They are the binomial coefficients of order 4, which approximate a normal distribution with a standard deviation of 1 pixel, since the binomial distribution of order 4 with probability 1/2 has variance \(4 \cdot \tfrac12 \cdot \tfrac12 = 1\). The 5 weights sum to 16.
The 2-dimensional blur over a window of 5 × 5 pixels gives the pixel in row \(i\) and column \(j\) of the window the weight \(w_i w_j\), as shown on the left of Figure 24.7. For example, the pixel in row 0 and column 2 of the window has the weight \(w_0 w_2 = 1 \cdot 6 = 6\). The 25 weights run from 1 at the corners to 36 at the center, and they sum to \(16 \cdot 16 = 256\), so a region of constant level keeps its level after the division by 256.
Definition 24.8 Separable filter. A filter on a window of \(k \times k\) pixels is separable if its weight at row \(i\) and column \(j\) of the window is a product \(a_i b_j\) of a column weight and a row weight. Its row pass replaces each pixel by the sum of its \(k\) row neighbors weighted by \(b\), and its column pass does the same along the columns with the weights \(a\).
Example. The blur is separable with \(a = b = (1, 4, 6, 4, 1)\); the weight 36 at the center is \(6 \cdot 6\), and the weight 4 at row 0 and column 1 is \(1 \cdot 4\).
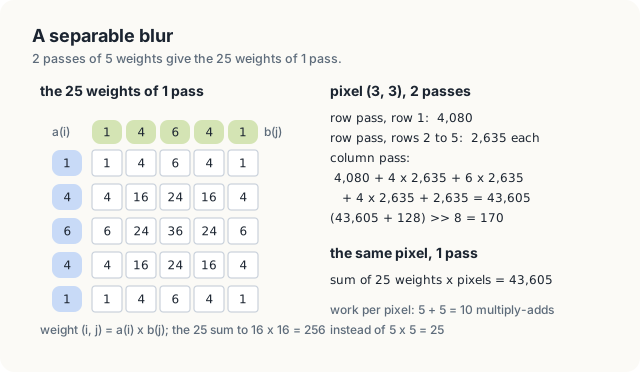
24.5.2 Separability
A direct blur multiplies 25 pixels by 25 weights for every output. Since each weight is a product of a weight for its row and a weight for its column, we may hope to apply the 2 factors one after the other, first along the rows and then along the columns. Let us blur pixel \((3, 3)\) of the equalized image by hand in this way, in 2 passes, as shown in Figure 24.8.
The row pass at \((3, y)\) reads pixels 1 to 5 of row \(y\), the window of width 5 centered on column 3. In rows 2 to 5, these pixels are 85, 170, 170, 170 and 170, so the row sum is \(85 + 4 \cdot 170 + 6 \cdot 170 + 4 \cdot 170 + 170 = 2{,}635\). In row 1, all 5 pixels are 255, and the sum is \(16 \cdot 255 = 4{,}080\). The column pass at \((3, 3)\) then reads the row sums of rows 1 to 5 and weighs them in the same way: \[ 4{,}080 + 4 \cdot 2{,}635 + 6 \cdot 2{,}635 + 4 \cdot 2{,}635 + 2{,}635 = 4{,}080 + 15 \cdot 2{,}635 = 43{,}605. \] The first term is the row sum of row 1 with weight 1, and the next 4 terms are the row sums of rows 2 to 5 with the weights 4, 6, 4 and 1. Finally, \((43{,}605 + 128) \gg 8 = 170\). Adding the 25 products of the 5 × 5 window with the weights of Figure 24.7 gives the same 43,605. This agreement is not a coincidence of the example, as the following theorem shows.
Theorem 24.1 Let \(e\) be an image of \(W \times H\) levels, let \(R(x, y) = \sum_{j \in [0,5)} w_j\, e(\mathrm{clamp}(x + j - 2, W), y)\) be its row sums, and let \(B(x, y) = (\sum_{i \in [0,5)} w_i\, R(x, \mathrm{clamp}(y + i - 2, H)) + 128) \gg 8\). Then for every pixel, \[ B(x, y) = \Big(\sum_{i \in [0,5)} \sum_{j \in [0,5)} w_i w_j\, e(\mathrm{clamp}(x + j - 2, W), \mathrm{clamp}(y + i - 2, H)) + 128\Big) \gg 8, \] the 2-dimensional blur with the 25 weights \(w_i w_j\).
| Symbol | Meaning | For pixel \((3, 3)\) of the example |
|---|---|---|
| \(e(x, y)\) | level of pixel \((x, y)\) of the equalized image | \(e(1, 2) = 85\) |
| \(w_j\) | weight \(j\) of the 5 weights \((1, 4, 6, 4, 1)\) | \(w_2 = 6\) |
| \(x + j - 2\) | column \(j\) of the window, which starts 2 columns left of \(x\) | columns 1 to 5 |
| \(R(x, y)\) | row sum, the result of the row pass | \(R(3, 2) = 2{,}635\) |
| \(B(x, y)\) | blurred level, the result of the column pass | 170 |
Proof. Fix \((x, y)\) and write \(y_i = \mathrm{clamp}(y + i - 2, H)\) and \(x_j = \mathrm{clamp}(x + j - 2, W)\). By the definition of \(R\), \(R(x, y_i) = \sum_j w_j\, e(x_j, y_i)\): the clamp acts on each coordinate separately, so the columns \(x_j\) that the row pass reads in row \(y_i\) do not depend on \(i\). Hence \[ \sum_i w_i\, R(x, y_i) = \sum_i w_i \sum_j w_j\, e(x_j, y_i) = \sum_i \sum_j w_i w_j\, e(x_j, y_i), \] since multiplication distributes over the inner sum. Every quantity is a non-negative integer: a row sum is at most \(16 \cdot 255 = 4{,}080\), and a column sum at most \(16 \cdot 4{,}080 = 65{,}280\), far below \(2^{32}\). Every addition and multiplication is therefore exact, the two sides are the same integer before the shift, and the shift gives the same result.
The proof needs the row pass to keep its sums whole. A program that divides by 16 with rounding after each pass, instead of by 256 once at the end, computes a different image. On the example, the row sum 2,635 becomes 165, 4,080 becomes 255, and pixel \((3, 3)\) becomes \((255 + 15 \cdot 165 + 8) \gg 4 = 171\) instead of 170. In this way, 16 of the 64 pixels of the example change. Our programs therefore store the row sums unscaled, in 2 bytes per pixel.
24.5.3 Counting the savings
The 2-dimensional blur performs 25 multiply-adds per pixel, whereas the 2 passes perform \(5 + 5 = 10\). For a window of \(k \times k\) pixels, the counts are \(k^2\) and \(2k\), so the saving grows with the window. It is 2.5 times for \(k = 5\), and 7.5 times for \(k = 15\), with 225 multiply-adds against 30. For the image of 1,920 × 1,080 pixels, the 2 passes save \(15 \cdot 2{,}073{,}600 = 31{,}104{,}000\) multiply-adds per image.
The 2 passes cost memory traffic instead. The row pass writes its sums to an intermediate image of 2 bytes per pixel, 4.1 MB for the large image, and the column pass reads this image back. In Section 24.9, we show that the time of the blur is set by this traffic, not by the multiply-adds.
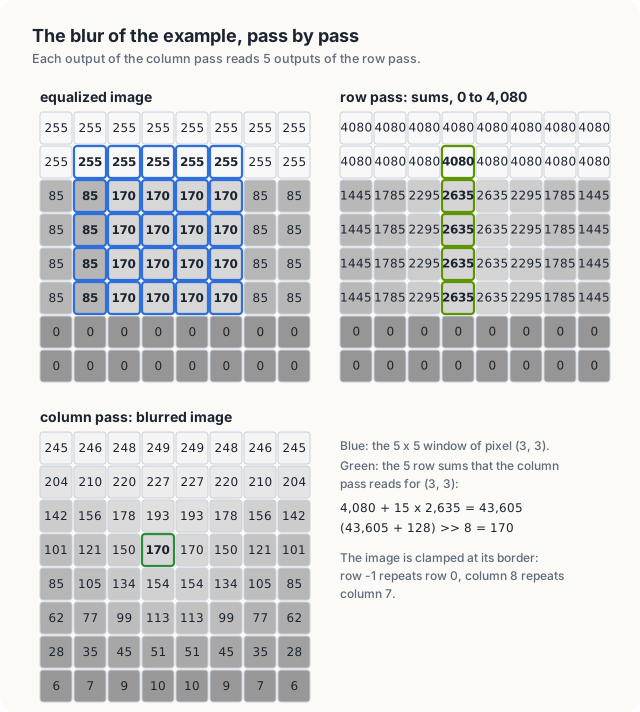
24.5.4 The tile and its halo
Each output of the row pass reads 5 pixels, and each pixel is read by 5 outputs. A kernel that reads its inputs from global memory therefore fetches every pixel 5 times. Recall from Chapter 20 that tiling removes this repetition. The threads of a block first copy the pixels that the block needs into shared memory, once, and every thread then reads its 5 inputs from the copy.
Definition 24.9 Tile and halo. A tile is the piece of the input that a block copies into shared memory. For a block of \(\mathsf{blockDim{.}x}\) outputs of a filter that reads \(r\) positions on each side, the tile holds \(\mathsf{blockDim{.}x} + 2r\) inputs: the \(\mathsf{blockDim{.}x}\) positions of the block’s own outputs and \(r\) more on each side. The \(2r\) extra positions are the halo.
Example. A block of 8 outputs of the row pass, with \(r = 2\), needs a tile of 12 pixels; its halo is 2 pixels on the left and 2 on the right.
Figure 24.9 shows the tile of row 2 of the example for a block of 8 threads. The slot with number \(\mathsf{slot}\) holds pixel \(\mathsf{left} + \mathsf{slot} - 2\) of the row, clamped, where \(\mathsf{left}\) is the column of the first output of the block. The shift by 2 makes room for the 2 halo pixels on the left. In the example, \(\mathsf{left} = 0\), so slot 2 holds pixel 0, and slots 0 and 1 hold the clamped pixels \(-2\) and \(-1\), which are both pixel 0. Thread \(\mathsf{threadIdx{.}x}\) copies its own pixel into slot \(\mathsf{threadIdx{.}x} + 2\), and threads 0 and 1 also copy the 4 halo slots. After a barrier, thread \(\mathsf{threadIdx{.}x}\) reads slots \(\mathsf{threadIdx{.}x}\) to \(\mathsf{threadIdx{.}x} + 4\), which hold pixels \(\mathsf{left} + \mathsf{threadIdx{.}x} - 2\) to \(\mathsf{left} + \mathsf{threadIdx{.}x} + 2\). For example, thread 3 reads slots 3 to 7, which hold pixels 1 to 5.
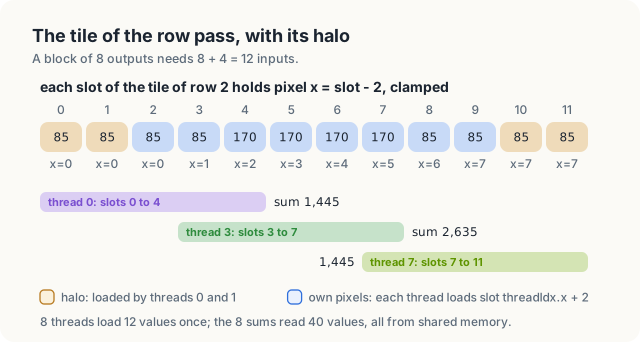
Blur-Rows(\(\mathsf{src}, \mathsf{rows}, W\))
- \(\mathsf{left} = \mathsf{blockIdx{.}x} \cdot \mathsf{blockDim{.}x}\), \(\;y = \mathsf{blockIdx{.}y}\)
- \(\mathsf{tile}[\mathsf{threadIdx{.}x} + 2] = \mathsf{src}[y][\mathrm{clamp}(\mathsf{left} + \mathsf{threadIdx{.}x}, W)]\) // own pixel
- if \(\mathsf{threadIdx{.}x} < 2\) {
- \(\mathsf{tile}[\mathsf{threadIdx{.}x}] = \mathsf{src}[y][\mathrm{clamp}(\mathsf{left} + \mathsf{threadIdx{.}x} - 2, W)]\) // left halo
- \(\mathsf{tile}[\mathsf{blockDim{.}x} + 2 + \mathsf{threadIdx{.}x}] = \mathsf{src}[y][\mathrm{clamp}(\mathsf{left} + \mathsf{blockDim{.}x} + \mathsf{threadIdx{.}x}, W)]\) // right halo
- }
- Barrier()
- \(\mathsf{rows}[y][\mathsf{left} + \mathsf{threadIdx{.}x}] = \sum_{\mathsf{tap} \in [0,5)} w_{\mathsf{tap}} \cdot \mathsf{tile}[\mathsf{threadIdx{.}x} + \mathsf{tap}]\)
Lines 2 to 6 are the joint copy, line 7 separates the copy from the reads, and line 8 is line 21 of Image-Pipeline with every read taken from the tile. A block now fetches \(\mathsf{blockDim{.}x} + 4\) pixels from global memory for \(\mathsf{blockDim{.}x}\) outputs, instead of \(5 \cdot \mathsf{blockDim{.}x}\). The programs use \(\mathsf{blockDim{.}x} = 128\), which gives 132 fetches instead of 640 per block, and 15 blocks cover a row of 1,920 pixels exactly.
The column pass works in the same way along the columns. A block of 32 × 8 threads computes 8 rows of 32 columns, and its tile holds the 8 + 4 = 12 rows of 32 row sums that these outputs read. The block is 32 threads wide, so that a warp reads 32 consecutive row sums of 1 row, which are 64 consecutive bytes. The column pass finishes with the rounding of line 24 of Image-Pipeline, \((sum + 128) \gg 8\). The following code shows both passes.
mod kernels {
// ...
/// Row pass, weights 1 4 6 4 1. Slot `slot` of the tile holds pixel left + slot - 2,
/// clamped: 2 halo slots on the left, 128 own pixels, 2 halo slots on the right.
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (128, 1, 1))]
pub fn blur_rows(src: &[u8], mut out: DisjointSlice<u16, Index2D<W>>) {
static mut TILE: SharedArray<u32, { ROW_T + 4 }> = SharedArray::UNINIT;
let thread_idx = thread::threadIdx_x() as usize;
let left = thread::blockIdx_x() as usize * ROW_T;
let row = thread::blockIdx_y() as usize * W;
let pixel = |slot: usize| src[row + tap(left + slot, W)] as u32;
// SAFETY: each slot is written by exactly 1 thread, before the barrier.
unsafe { TILE[thread_idx + 2] = pixel(thread_idx + 2) };
if thread_idx < 2 {
unsafe { TILE[thread_idx] = pixel(thread_idx) };
unsafe { TILE[ROW_T + 2 + thread_idx] = pixel(ROW_T + 2 + thread_idx) };
}
thread::sync_threads();
// SAFETY: after the barrier the tile is only read.
let window = |offset: usize| unsafe { TILE[thread_idx + offset] };
let sum = window(0) + 4 * window(1) + 6 * window(2) + 4 * window(3) + window(4);
if let Some(idx) = thread::index_2d::<W>()
&& let Some(cell) = out.get_mut(idx)
{
*cell = sum as u16;
}
}
/// Column pass on a tile of 32 columns and 8 + 4 rows. The 2 passes weigh by
/// 16 x 16 = 256, so the result is the rounded sum shifted right by 8.
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (32, 8, 1))]
pub fn blur_cols(src: &[u16], mut out: DisjointSlice<u8, Index2D<W>>) {
static mut TILE: SharedArray<u32, { (COL_H + 4) * COL_W }> = SharedArray::UNINIT;
let tile_col = thread::threadIdx_x() as usize;
let tile_row = thread::threadIdx_y() as usize;
let x = thread::blockIdx_x() as usize * COL_W + tile_col;
let top = thread::blockIdx_y() as usize * COL_H;
let value = |slot: usize| src[tap(top + slot, H) * W + x] as u32;
// SAFETY: each slot is written by exactly 1 thread, before the barrier.
unsafe { TILE[(tile_row + 2) * COL_W + tile_col] = value(tile_row + 2) };
if tile_row < 2 {
unsafe { TILE[tile_row * COL_W + tile_col] = value(tile_row) };
let below = COL_H + 2 + tile_row;
unsafe { TILE[below * COL_W + tile_col] = value(below) };
}
thread::sync_threads();
// SAFETY: after the barrier the tile is only read.
let window = |offset: usize| {
let slot = (tile_row + offset) * COL_W + tile_col;
unsafe { TILE[slot] }
};
let sum = window(0) + 4 * window(1) + 6 * window(2) + 4 * window(3) + window(4);
if let Some(idx) = thread::index_2d::<W>()
&& let Some(cell) = out.get_mut(idx)
{
*cell = ((sum + 128) >> 8) as u8;
}
}
// ...
}// Row pass, weights 1 4 6 4 1. Slot `slot` of the tile holds pixel left + slot - 2,
// clamped: 2 halo slots on the left, 128 own pixels, 2 halo slots on the right.
__global__ void blurRows(const uint8_t* src, uint16_t* out)
{
__shared__ unsigned tile[ROW_T + 4];
int left = blockIdx.x * ROW_T;
const uint8_t* row = src + blockIdx.y * W;
tile[threadIdx.x + 2] = row[tap(left + threadIdx.x + 2, W)];
if (threadIdx.x < 2) {
tile[threadIdx.x] = row[tap(left + threadIdx.x, W)];
tile[ROW_T + 2 + threadIdx.x] = row[tap(left + ROW_T + 2 + threadIdx.x, W)];
}
__syncthreads();
const unsigned* window = tile + threadIdx.x;
unsigned sum = window[0] + 4 * window[1] + 6 * window[2] + 4 * window[3] + window[4];
out[blockIdx.y * W + left + threadIdx.x] = sum;
}
// Column pass on a tile of 32 columns and 8 + 4 rows. The 2 passes weigh by
// 16 x 16 = 256, so the result is the rounded sum shifted right by 8.
__global__ void blurCols(const uint16_t* src, uint8_t* out)
{
__shared__ unsigned tile[COL_H + 4][COL_W];
int tileRow = threadIdx.y;
int tileCol = threadIdx.x;
int x = blockIdx.x * COL_W + tileCol;
int top = blockIdx.y * COL_H;
tile[tileRow + 2][tileCol] = src[tap(top + tileRow + 2, H) * W + x];
if (tileRow < 2) {
tile[tileRow][tileCol] = src[tap(top + tileRow, H) * W + x];
tile[COL_H + 2 + tileRow][tileCol] = src[tap(top + COL_H + 2 + tileRow, H) * W + x];
}
__syncthreads();
unsigned sum = tile[tileRow][tileCol] + 4 * tile[tileRow + 1][tileCol];
sum += 6 * tile[tileRow + 2][tileCol] + 4 * tile[tileRow + 3][tileCol];
sum += tile[tileRow + 4][tileCol];
out[(top + tileRow) * W + x] = (sum + 128) >> 8;
}
In the row pass, the line that writes TILE[tx + 2] (C++: tile[tx + 2]) is line 2 of Blur-Rows,
the if tx < 2 block is lines 3 to 6, and the barrier is line 7. The device function tap(i, n)
computes \(\mathrm{clamp}(i - 2, n)\), so tap(x0 + s, W) is the pixel that belongs in slot
\(\mathsf{slot}\). The two languages declare the tile differently. C++ writes __shared__ unsigned tile[ROW_T + 4]. Rust writes static mut TILE: SharedArray<u32, { ROW_T + 4 }>, a type whose length is part of
the type and must be a constant, and this is why the tile widths are the constants ROW_T, COL_W
and COL_H. Every access to the tile is unsafe in Rust, and the 2 // SAFETY: comments state the
argument that we prove in the next section. The output is a DisjointSlice<u16, Index2D<W>>,
addressed by the thread’s 2-dimensional index thread::index_2d::<W>(), so the write needs no
unsafe block.
24.5.5 Correctness of the tile
The tiled row pass is correct if every slot holds the right pixel at the moment when it is read. We now prove that this is the case.
Theorem 24.2 After the barrier of line 7 of Blur-Rows, every slot \(\mathsf{slot} \in [0, \mathsf{blockDim{.}x} + 4)\) of the tile holds \(\mathsf{src}[y][\mathrm{clamp}(\mathsf{left} + \mathsf{slot} - 2, W)]\), and line 8 computes the row sum \(R(\mathsf{left} + \mathsf{threadIdx{.}x}, y)\) of Theorem 24.1.
Proof. Line 2 writes slot \(\mathsf{threadIdx{.}x} + 2\) for \(\mathsf{threadIdx{.}x} \in [0, \mathsf{blockDim{.}x})\), that is, the slots \([2, \mathsf{blockDim{.}x} + 2)\). Lines 4 and 5 write slots \(\mathsf{threadIdx{.}x}\) and \(\mathsf{blockDim{.}x} + 2 + \mathsf{threadIdx{.}x}\) for \(\mathsf{threadIdx{.}x} \in [0, 2)\), that is, the slots \([0, 2)\) and \([\mathsf{blockDim{.}x} + 2, \mathsf{blockDim{.}x} + 4)\). The 3 ranges are disjoint and together cover \([0, \mathsf{blockDim{.}x} + 4)\), so every slot is written exactly once, and each write into a slot \(\mathsf{slot}\) stores the pixel \(\mathsf{left} + \mathsf{slot} - 2\), clamped. No thread passes the barrier of line 7 before every thread has finished lines 2 to 6, so every slot holds its value before any thread reads. After the barrier, the tile is only read. Thread \(\mathsf{threadIdx{.}x}\) reads slots \(\mathsf{threadIdx{.}x} + \mathsf{tap}\) for \(\mathsf{tap} \in [0, 5)\), which hold \(\mathsf{src}[y][\mathrm{clamp}(\mathsf{left} + \mathsf{threadIdx{.}x} + \mathsf{tap} - 2, W)]\), and line 8 adds them with the weights \(w_{\mathsf{tap}}\), which is \(R(\mathsf{left} + \mathsf{threadIdx{.}x}, y)\).
The same argument, with rows in place of columns, proves the column pass.
24.5.6 A missing halo
The halo is easy to forget, because the block has \(\mathsf{blockDim{.}x}\) threads, and it seems natural to copy \(\mathsf{blockDim{.}x}\) values. Suppose that lines 3 to 6 of Blur-Rows are left out. Slots 0, 1, \(\mathsf{blockDim{.}x} + 2\) and \(\mathsf{blockDim{.}x} + 3\) are then never written, and the proof of Theorem 24.2 fails at its first step. The threads whose windows reach into those slots read whatever the memory held before. These are threads 0 and 1 on the left, and threads \(\mathsf{blockDim{.}x} - 2\) and \(\mathsf{blockDim{.}x} - 1\) on the right.
Figure 24.10 shows the effect on the example, with a block of 8 threads per row and with 0 in the 4 slots that are never written. Thread 0 of row 2 should add \(85 + 4 \cdot 85 + 6 \cdot 85 + 4 \cdot 85 + 170 = 1{,}445\), but it adds \(0 + 0 + 6 \cdot 85 + 4 \cdot 85 + 170 = 1{,}020\) instead. The column pass spreads the error down the column, and pixel \((0, 3)\) of the blurred image becomes 71 instead of 101. In all, 30 of the 64 blurred pixels are wrong, all of them in columns 0, 1, 6 and 7.
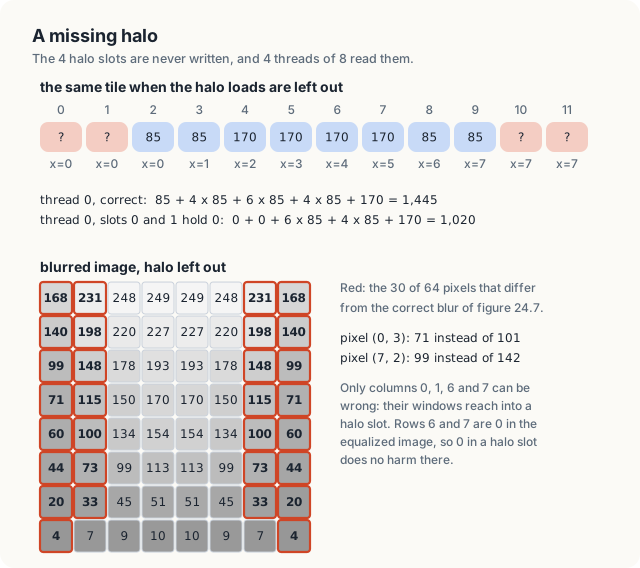
In the programs, the block has 128 threads, so threads 0, 1, 126 and 127 of each block read an
unwritten slot. A row has 15 blocks, so 60 columns of the image are at risk, which is
\(60 \cdot 1{,}080 = 64{,}800\) blurred pixels. We removed the if tx < 2 block from the Rust
kernel and ran the program, which printed the following report.
$ cargo oxide run # blur_rows without the `if tx < 2` block
...
image pixels that differ from the CPU
gray 0
equalised 0
blurred 56548 first at (0, 0): GPU 164, CPU 106
edges 81436 first at (0, 0): GPU 84, CPU 10
...
FAILED
The program compiled without a warning. The reads of the tile are inside unsafe blocks,
and the compiler accepts the argument of their // SAFETY: comments without checking it. Of the
64,800 blurred pixels at risk, 56,548, or 87%, are wrong; in the others, the old contents of shared
memory happened to give the right sum. Pixel \((0, 0)\) is 164 instead of 106. The edge image has
more wrong pixels, 81,436, because the Sobel operator reads a 3 × 3 window, and every wrong blurred
pixel spoils the edges of its neighbors. The 60 columns at risk thus become 90 columns of edges at
risk, 97,200 pixels. The C++ program with the same change gave 56,646 wrong blurred pixels and
81,212 wrong edge pixels. In the picture, the errors form thin vertical stripes, 1 every 128
columns, which are hard to see by looking at the image, whereas the comparison with the CPU finds
them at once.
Rule A tile for \(\mathsf{blockDim{.}x}\) outputs of a filter that reads \(r\) positions on each side holds \(\mathsf{blockDim{.}x} + 2r\) inputs, and every one of them must be written before the barrier. Count the slots, not the threads.
Exercises
24.13 Compute the row sum and the blurred level of pixel \((1, 2)\) of the example by hand, and
check them against Figure 24.8.
24.14 A block of the row pass has 256 threads instead of 128. How many pixels does it fetch, and
what fraction of its fetches are halo? How many columns of the image would a missing halo put at
risk?
24.15 Prove that rounding after each pass, \((sum + 8) \gg 4\) twice, can differ from rounding once
at the end, using pixel \((3, 3)\) of the example.
24.6 Sobel edges
24.6.1 The gradient
An edge in an image is a place where the level changes quickly from 1 pixel to the next. Inside a region of the example, such as the sky, neighboring pixels have almost the same level, while at the border between the sky and the house, the level drops by about 70 within 2 rows. To find edges, we therefore estimate how fast the level changes at each pixel. The Sobel operator makes this estimate in two directions from the 3 × 3 neighborhood of the pixel. Its horizontal component \(g_x\) is the weighted sum of the column to the right of the pixel minus the weighted sum of the column to its left, with the weights 1, 2 and 1 from top to bottom. Its vertical component \(g_y\) is the weighted sum of the row below the pixel minus that of the row above, with the same weights from left to right. The middle pixel of each column or row receives the weight 2 because it is closest to the center.
Definition 24.10 Gradient magnitude. The gradient magnitude at a pixel is the length \(\sqrt{g_x^2 + g_y^2}\) of the vector \((g_x, g_y)\). Our edge image stores it divided by 4, rounded to the nearest integer and limited to 255: \[ \mathrm{edge}(x, y) = \min\big(\lfloor \sqrt{g_x^2 + g_y^2} / 4 + 1/2 \rfloor, 255\big). \]
Example. At pixel \((3, 1)\) of the blurred example, \(g_x = 30\) and \(g_y = -238\), and the edge level is 60 (Figure 24.11).
| Symbol | Meaning | At pixel \((3, 1)\) |
|---|---|---|
| \(g_x\) | rate of change from left to right | 30 |
| \(g_y\) | rate of change from top to bottom | \(-238\) |
| \(\sqrt{g_x^2 + g_y^2}\) | gradient magnitude, the length of \((g_x, g_y)\) | 239.88 |
| \(\lfloor z / 4 + 1/2 \rfloor\) | \(z / 4\) rounded to the nearest integer | \(\lfloor 59.97 + 0.5 \rfloor = 60\) |
| \(\min(\ldots, 255)\) | limit to the largest level of a byte | 60 |
The division by 4 scales the result to the range of a byte. A sharp step from level 0 to level 255 gives \(g_x = (1 + 2 + 1) \cdot 255 = 1{,}020\), and \(1{,}020 / 4 = 255\), the brightest level. Figure 24.11 works pixel \((3, 1)\), which lies where the sky meets the house. Its neighborhood in the blurred image has the rows 248, 249, 249; 220, 227, 227; and 178, 193, 193. Therefore, \[ g_x = (249 + 2 \cdot 227 + 193) - (248 + 2 \cdot 220 + 178) = 896 - 866 = 30, \] \[ g_y = (178 + 2 \cdot 193 + 193) - (248 + 2 \cdot 249 + 249) = 757 - 995 = -238. \] In \(g_x\), the first bracket is the right column of the neighborhood, from top to bottom, and the second bracket is the left column. In \(g_y\), the first bracket is the row below, from left to right, and the second bracket is the row above. The level falls by about 70 from the row above to the row below, and it barely changes from left to right. The magnitude is \(\sqrt{900 + 56{,}644} = \sqrt{57{,}544} = 239.88\), and \(239.88 / 4 = 59.97\) rounds to 60.
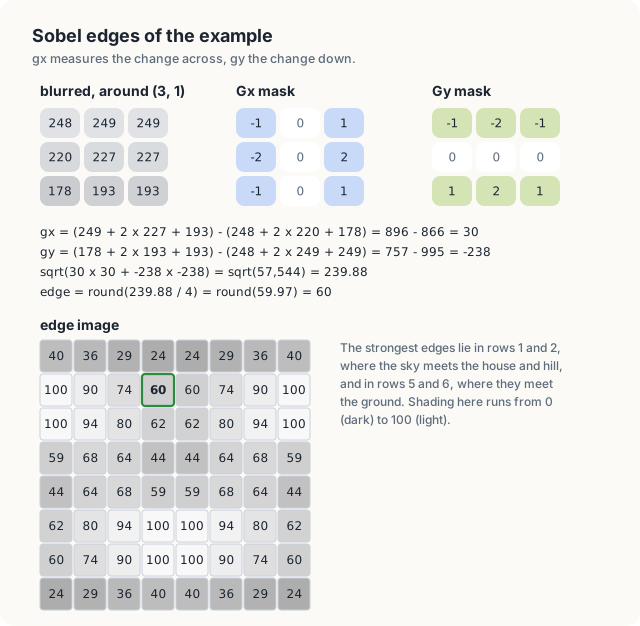
24.6.2 The kernel
The Sobel operator is a stencil of radius 1, the pattern of Chapter 19, and its kernel therefore gives each output pixel a thread. In the following procedure, \(\mathsf{at}(\mathsf{row}, \mathsf{col})\) is the level of the blurred image in row \(\mathsf{row}\) and column \(\mathsf{col}\), with both coordinates clamped to the image.
Sobel-Kernel(\(\mathsf{src}, \mathsf{edges}, W, H\))
- \(x = \mathsf{blockIdx{.}x} \cdot \mathsf{blockDim{.}x} + \mathsf{threadIdx{.}x}\), \(\;y = \mathsf{blockIdx{.}y} \cdot \mathsf{blockDim{.}y} + \mathsf{threadIdx{.}y}\)
- \(\mathsf{at}(\mathsf{row}, \mathsf{col}) = \mathsf{src}[\mathrm{clamp}(\mathsf{row}, H)][\mathrm{clamp}(\mathsf{col}, W)]\)
- \(g_x = (\mathsf{at}(y{-}1, x{+}1) + 2 \cdot \mathsf{at}(y, x{+}1) + \mathsf{at}(y{+}1, x{+}1)) - (\mathsf{at}(y{-}1, x{-}1) + 2 \cdot \mathsf{at}(y, x{-}1) + \mathsf{at}(y{+}1, x{-}1))\)
- \(g_y = (\mathsf{at}(y{+}1, x{-}1) + 2 \cdot \mathsf{at}(y{+}1, x) + \mathsf{at}(y{+}1, x{+}1)) - (\mathsf{at}(y{-}1, x{-}1) + 2 \cdot \mathsf{at}(y{-}1, x) + \mathsf{at}(y{-}1, x{+}1))\)
- \(\mathsf{edges}[y][x] = \min(\lfloor \sqrt{g_x^2 + g_y^2}\,/\,4 + 1/2 \rfloor, 255)\)
We let each thread use the 8 pixels around its own, since the center has weight 0 in both masks, and it writes 1 byte. The kernel reads the 8 pixels from global memory without a shared tile. A pixel is read by up to 9 threads, but those threads belong to the same block or to neighboring blocks, and most of the repeated reads are served by the L1 cache of the SM. Exercise 24.18 asks whether a tile would help. The following kernels implement the procedure.
mod kernels {
// ...
/// Sobel gradient magnitude divided by 4, rounded and clamped to 255. The 8 neighbors
/// come from global memory; neighboring threads share them through the L1 cache.
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (32, 8, 1))]
pub fn sobel(src: &[u8], mut out: DisjointSlice<u8, Index2D<W>>) {
let (x, y) = (thread::index_2d_col(), thread::index_2d_row());
let (x_left, x_right) = (x.saturating_sub(1), (x + 1).min(W - 1));
let (y_above, y_below) = (y.saturating_sub(1), (y + 1).min(H - 1));
let at = |row: usize, col: usize| src[row * W + col] as i32;
if let Some(idx) = thread::index_2d::<W>()
&& let Some(cell) = out.get_mut(idx)
{
let right = at(y_above, x_right) + 2 * at(y, x_right) + at(y_below, x_right);
let left = at(y_above, x_left) + 2 * at(y, x_left) + at(y_below, x_left);
let below = at(y_below, x_left) + 2 * at(y_below, x) + at(y_below, x_right);
let above = at(y_above, x_left) + 2 * at(y_above, x) + at(y_above, x_right);
let (gx, gy) = (right - left, below - above);
let magnitude = sqrt_rn_f32((gx * gx + gy * gy) as f32);
*cell = (magnitude * 0.25 + 0.5).min(255.0) as u8;
}
}
}// Sobel gradient magnitude divided by 4, rounded and clamped to 255. The 8 neighbors
// come from global memory; neighboring threads share them through the L1 cache.
__global__ void sobel(const uint8_t* src, uint8_t* out)
{
int x = blockIdx.x * blockDim.x + threadIdx.x;
int y = blockIdx.y * blockDim.y + threadIdx.y;
int xLeft = max(x - 1, 0);
int xRight = min(x + 1, W - 1);
int yAbove = max(y - 1, 0);
int yBelow = min(y + 1, H - 1);
const uint8_t* upper = src + yAbove * W;
const uint8_t* middle = src + y * W;
const uint8_t* lower = src + yBelow * W;
int right = upper[xRight] + 2 * middle[xRight] + lower[xRight];
int left = upper[xLeft] + 2 * middle[xLeft] + lower[xLeft];
int below = lower[xLeft] + 2 * lower[x] + lower[xRight];
int above = upper[xLeft] + 2 * upper[x] + upper[xRight];
int gx = right - left;
int gy = below - above;
float magnitude = sqrtf(float(gx * gx + gy * gy));
out[y * W + x] = fminf(magnitude * 0.25f + 0.5f, 255.0f);
}
The kernels compute the 4 weighted sums of lines 3 and 4 as right, left, below and above,
and the clamped neighbor positions xLeft, xRight, yAbove and yBelow (x_left and so on in
Rust) of line 2. The largest possible component is
\(4 \cdot 255 = 1{,}020\), so the sum of squares is at most \(2 \cdot 1{,}020^2 = 2{,}080{,}800\).
This is an integer below \(2^{24} = 16{,}777{,}216\), and its conversion to a 32-bit float is
therefore exact. The square root is sqrt_rn_f32 in Rust and sqrtf in C++. Both round to the
nearest float, as the IEEE 754 standard requires of a square root, and so do the CPU’s f32::sqrt
and std::sqrt. The multiplication by 0.25 is exact, because 0.25 is a power of 2.
We also compiled the C++ program with --use_fast_math, which replaces sqrtf by an approximate
square root. The edge image still agreed with the CPU’s edge image in every pixel, with the same
checksum. The rounding of line 5 depends on the exact root only at the sums of squares
\((4k + 2)^2\), where \(k\) is any non-negative integer. For example, for \(g_x = 10\) and
\(g_y = 0\), with \(k = 2\), we have \(\sqrt{100} = 10\) and \(10 / 4 + 1/2 = 3\) exactly,
and a root slightly below 10 would give 2. The approximate root of the measured GPU returned these
integer roots exactly. The programs nevertheless keep the correctly rounded root, because it agrees
with the CPU by its definition, not by a test on 1 GPU and 1 image.
24.6.3 Neighbors outside the image
A common mistake in a stencil is to forget the clamp of line 2 of Sobel-Kernel. At pixel \((3, 0)\), the kernel then reads row \(-1\), which does not exist. In a buffer stored row by row, row \(-1\) lies before the start of the image, and column \(-1\) of row \(y\) is the last pixel of row \(y - 1\). If the memory before the image holds 0, pixel \((3, 0)\) of the example gets \(g_y = (220 + 2 \cdot 227 + 227) - 0 = 901\) and the edge level 225 instead of 24, and 27 of the 28 border pixels of the example change. We removed the 4 clamps from the C++ kernel and ran the program, which printed the following report.
$ ./capstone # sobel with xl = x - 1, xr = x + 1, ...
...
image pixels that differ from the CPU
gray 0
equalised 0
blurred 0
edges 5852 first at (0, 0): GPU 129, CPU 10
...
FAILED
The image has \(2 \cdot 1{,}920 + 2 \cdot 1{,}078 = 5{,}996\) border pixels, and 5,852 of them are wrong, while every interior pixel is right. Pixel \((0, 0)\) became 129 instead of 10. Note that the kernel did not stop. The reads before the first row and after the last one landed in other memory of the program, and the device reported no error. In Rust, the same reads would be caught, because cuda-oxide checks every slice index against the length of the slice and stops the kernel when the index lies outside. The column wrap of \(x - 1\) at \(x = 0\), however, stays inside the slice, and it would not be caught.
Exercises
24.16 Compute the edge level of pixel \((0, 1)\) of the example from the blurred image of Figure
24.8.
24.17 Which levels of a blurred image of constant level give an edge level other than 0?
24.18 Write a Sobel kernel that copies a tile of \((8 + 2) \times (32 + 2)\) pixels into shared
memory, and compare its time with the kernel above. Explain the result with the role of the L1
cache.
24.7 The host pipeline
24.7.1 Buffers
Recall that the host is the CPU and its memory, and the device is the GPU and its memory. The host program keeps the device buffers of 1 image in a structure, so that it can process several images at once with 1 set of buffers for each image. The following table lists the buffers of a set.
| Buffer | Element | Elements | Size |
|---|---|---|---|
rgb | byte | 3 per pixel | 6.2 MB |
gray, equal, blurred, edges | byte | 1 per pixel | 2.1 MB each |
rows | 16-bit integer | 1 per pixel | 4.1 MB |
bins | 32-bit atomic integer | 256 | 1,024 bytes |
table | byte | 256 | 256 bytes |
A set occupies \(6.2 + 4 \cdot 2.1 + 4.1 = 18.7\) MB. In Rust, each buffer is a DeviceBuffer,
which frees its memory when the structure is dropped. In C++, the function freeBuffers calls
cudaFree for each buffer.
24.7.2 Streams
The 7 kernels of 1 image must run in order, the copy of the input must finish before the first kernel, and the copy of the output must wait for the last kernel. A stream provides this order.
Definition 24.11 Stream. A stream is a queue of device work, copies and kernel launches, that the device executes in the order in which the host issued it. Work in 1 stream starts only after the previous work in the same stream has finished. Work in different streams has no order and may run at the same time.
Example. The 7 kernels of 1 image, issued on stream 0, run one after the other; the kernels of a second image, on stream 1, may run while the first image is copied.
The host functions stage and process, shown below, issue the 7 launches of 1 image on 1 stream.
A launch returns to the host as soon as the work is queued, so the host issues all 7 launches without
waiting, and the stream keeps them in order.
/// Launches stage `index` of the pipeline on `stream`.
fn stage(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
buffers: &mut Buffers,
index: usize,
) -> Result<(), Error> {
let line = LaunchConfig1D::new((PIXELS / 256) as u32, 256, 0);
let rows = LaunchConfig2D::new(((W / ROW_T) as u32, H as u32), (ROW_T as u32, 1), 0);
let grid = ((W / COL_W) as u32, (H / COL_H) as u32);
let tiles = LaunchConfig2D::new(grid, (COL_W as u32, COL_H as u32), 0);
match index {
0 => {
let launch = module.prepare_grayscale(line)?;
module.grayscale(stream, &launch, &buffers.rgb, &mut buffers.gray)?;
}
1 => {
let launch = module.prepare_histogram(LaunchConfig1D::new(64, 256, 0))?;
module.histogram(stream, &launch, &buffers.gray, &buffers.bins)?;
}
2 => {
let launch = module.prepare_equalise_table(LaunchConfig1D::new(1, 256, 0))?;
module.equalise_table(stream, &launch, &buffers.bins, &mut buffers.table)?;
}
3 => {
let launch = module.prepare_apply_table(line)?;
let (gray, table) = (&buffers.gray, &buffers.table);
module.apply_table(stream, &launch, gray, table, &mut buffers.equal)?;
}
4 => {
let launch = module.prepare_blur_rows(rows)?;
module.blur_rows(stream, &launch, &buffers.equal, &mut buffers.rows)?;
}
5 => {
let launch = module.prepare_blur_cols(tiles)?;
module.blur_cols(stream, &launch, &buffers.rows, &mut buffers.blurred)?;
}
_ => {
let launch = module.prepare_sobel(tiles)?;
module.sobel(stream, &launch, &buffers.blurred, &mut buffers.edges)?;
}
}
Ok(())
}
/// All 7 stages of 1 image, in order, on `stream`.
fn process(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
buffers: &mut Buffers,
) -> Result<(), Error> {
for index in 0..STAGES.len() {
stage(module, stream, buffers, index)?;
}
Ok(())
}// Launches stage `index` of the pipeline on `stream`.
void stage(cudaStream_t stream, Buffers& buffers, int index)
{
int line = PIXELS / 256;
dim3 rows(W / ROW_T, H);
dim3 tiles(W / COL_W, H / COL_H);
dim3 tile(COL_W, COL_H);
switch (index) {
case 0:
grayscale<<<line, 256, 0, stream>>>(buffers.rgb, buffers.gray);
break;
case 1:
histogram<<<64, 256, 0, stream>>>(buffers.gray, buffers.bins);
break;
case 2:
equaliseTable<<<1, 256, 0, stream>>>(buffers.bins, buffers.table);
break;
case 3:
applyTable<<<line, 256, 0, stream>>>(buffers.gray, buffers.table, buffers.equal);
break;
case 4:
blurRows<<<rows, ROW_T, 0, stream>>>(buffers.equal, buffers.rows);
break;
case 5:
blurCols<<<tiles, tile, 0, stream>>>(buffers.rows, buffers.blurred);
break;
default:
sobel<<<tiles, tile, 0, stream>>>(buffers.blurred, buffers.edges);
}
}
// All 7 stages of 1 image, in order, on `stream`.
void process(cudaStream_t stream, Buffers& buffers)
{
for (int index = 0; index < 7; ++index) {
stage(stream, buffers, index);
}
}
The launch configurations match the 3 shapes of kernel. The configuration line covers the image
with 8,100 blocks of 256 threads for the 2 maps. The configuration rows gives each of the 1,080
image rows 15 blocks of 128 threads. The column pass and the Sobel kernel use 60 × 135 blocks of
32 × 8 threads, because \(60 \cdot 32 = 1{,}920\) and \(135 \cdot 8 = 1{,}080\). The histogram uses
a fixed grid of 64 blocks, and the table kernel uses 1 block. In Rust, each prepare_ call checks a
configuration against the launch contract of its kernel and returns an error if the block shape
differs, and the launch itself takes the prepared value. In C++, the triple-angle-bracket launch
takes any configuration.
24.8 Checking against the CPU
As we saw in Section 24.5.6, a GPU program can produce an image that looks right and is wrong in a few thousand pixels. Both programs therefore compute the whole pipeline a second time on the CPU and compare the 2 results pixel by pixel. The CPU version uses the same integer formulas, the same clamping and a correctly rounded square root, so every pixel must agree exactly, and no tolerance is needed.
The CPU version is also the baseline for the speed of the GPU, so it uses every core. The function
par_rows (parRows in C++), shown below, divides the rows of an output image into 1 band per core
and processes the bands on separate threads. In Rust, chunks_mut hands each thread its own band as
a separate mutable slice, so the compiler verifies that no 2 threads write the same row.
/// Runs `f(y, row)` for every row of `out`, the rows split into 1 band per CPU core.
fn par_rows<T: Send>(out: &mut [T], f: impl Fn(usize, &mut [T]) + Sync) {
let cores = std::thread::available_parallelism().map_or(1, |n| n.get());
let band = H.div_ceil(cores);
std::thread::scope(|s| {
for (k, chunk) in out.chunks_mut(band * W).enumerate() {
let f = &f;
s.spawn(move || {
for (r, row) in chunk.chunks_mut(W).enumerate() {
f(k * band + r, row);
}
});
}
});
}// Runs f(y, row) for every row y, the rows split into 1 band per CPU core.
template <typename F>
void parRows(F f)
{
int cores = std::max(1u, std::thread::hardware_concurrency());
int band = (H + cores - 1) / cores;
std::vector<std::thread> threads;
for (int k = 0; k < cores; ++k) {
threads.emplace_back([=] {
for (int y = k * band; y < std::min(H, (k + 1) * band); ++y) {
f(y);
}
});
}
for (std::thread& t : threads) {
t.join();
}
}
The programs generate the test image themselves. It shows a house below a hill, a sky that brightens toward the horizon, and a sun, with random grain of up to 8 levels on every pixel. Its colors lie in a narrow range of levels, so the image has low contrast, and equalization has a visible effect (Figure 24.3). For each of the 4 images, both programs print the number of pixels in which the GPU differs from the CPU, as follows.
$ ./capstone # C++, Jetson Orin NX
GPU: Orin, 8 SMs image 1920 x 1080 = 2073600 pixels
...
image pixels that differ from the CPU
gray 0
equalised 0
blurred 0
edges 0
edge image checksum: 166b66c2
All 4 images agree in all 2,073,600 pixels. The last line is a checksum of the GPU’s edge image, and the Rust and the C++ programs print the same value, 166b66c2. The two languages therefore produce the same edge image, byte for byte. The batch of Section 24.10 checks the output once more, by comparing the last edge image that each stream copies back with the CPU’s edge image of the same input.
24.9 Time per stage
24.9.1 Measurements
The measurements come from an integrated GPU, a Jetson Orin NX with 8 SMs and 102 GB/s of memory bandwidth. Each stage is timed alone, as the mean of 100 launches, after the GPU has run the pipeline for 0.4 s to raise its clock. The programs report the time and the effective bandwidth, which is the number of bytes that the stage must read and write divided by its time. Times drift by about 10% between runs.
| Stage | Bytes per pixel | Rust | C++ | C++, effective |
|---|---|---|---|---|
| grayscale | 4 | 0.200 ms | 0.183 ms | 45.4 GB/s |
| histogram | 1 | 0.056 ms | 0.055 ms | 38.0 GB/s |
| equalize table | 0 | 0.007 ms | 0.007 ms | |
| apply table | 2 | 0.185 ms | 0.192 ms | 21.6 GB/s |
| blur rows | 3 | 0.301 ms | 0.208 ms | 29.9 GB/s |
| blur columns | 3 | 0.280 ms | 0.210 ms | 29.7 GB/s |
| sobel | 2 | 0.350 ms | 0.225 ms | 18.4 GB/s |
| sum of the 7 stages | 15 | 1.380 ms | 1.079 ms | 28.8 GB/s |
| the 7 stages in turn | 1.489 ms | 1.165 ms |
The bytes per pixel are those that a stage must move. For example, the gray kernel reads 3 bytes and writes 1, and the row pass reads 1 byte and writes a 2-byte row sum. For the gray kernel in C++, the effective bandwidth is therefore \(4 \cdot 2{,}073{,}600\) bytes in 0.183 ms, about 45 GB/s. The histogram was the only stage whose time changed by much more than 10% between runs, from 0.054 to 0.117 ms in both languages, and the table quotes the more frequent value. The 7 stages issued 1 after the other take 1.165 ms in C++, slightly more than the sum of their separate times.
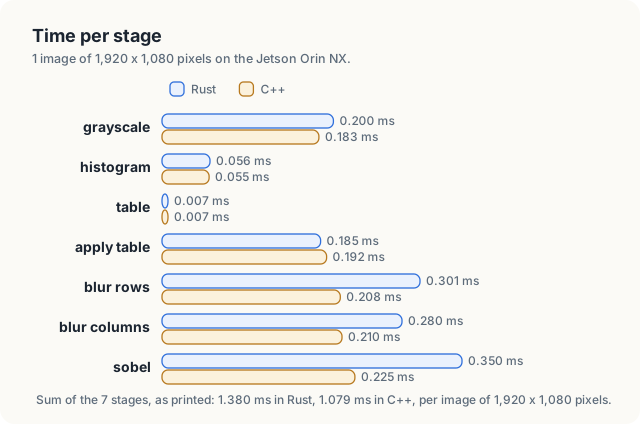
The table kernel, a single block of 256 threads, takes 0.007 ms, which is about the cost of launching any kernel. A kernel with almost no parallelism thus costs nothing noticeable when it handles 256 values between two kernels that handle 2 million.
24.9.2 Which stage dominates, and why
The blur dominates. Its 2 passes take \(0.208 + 0.210 = 0.418\) ms in C++, 39% of the 1.079 ms of the 7 stages. The Sobel kernel follows with 21%, the apply-table kernel with 18% and the gray kernel with 17%, while the histogram and the table together take 6%.
The arithmetic does not explain this order. The 2 blur passes perform 10 multiply-adds per pixel, 20.7 million per image. The measured GPU has 1,024 lanes (8 SMs of 128) at up to 1.17 GHz, which gives about \(1.2 \cdot 10^{12}\) simple integer operations per second. The multiply-adds therefore account for about 0.02 ms of the 0.418 ms. Likewise, the square roots of the Sobel kernel are a small part of its time.
What the stages have in common is memory traffic. Together, they must read and write 15 bytes per pixel, which is \(15 \cdot 2{,}073{,}600 = 31.1\) MB per image. At the 102 GB/s of the memory, this would take 0.305 ms, but the stages take 1.079 ms, an effective 28.8 GB/s, or 28% of the peak. The blur takes the largest share because it moves the most bytes, 6 per pixel. The row pass reads the equalized image and writes 2-byte row sums, and the column pass reads them back and writes the blurred image. The intermediate image of 4.1 MB is the price of the separable form. Theorem 24.1 saves 15 multiply-adds per pixel, which cost little here, while the 2 passes add 4 bytes of traffic per pixel, which cost more. A 1-pass blur with a tile of \((8 + 4) \times (32 + 4)\) inputs would move about 2 bytes per pixel and perform 25 multiply-adds. Exercise 7 at the end of the chapter asks for such a kernel.
The effective rates stay far below 102 GB/s because every access is narrow. Each thread of these kernels reads and writes 1 or 2 bytes, so 1 load instruction of a warp moves only 32 or 64 bytes. In Chapter 8, we measured the same effect with a histogram: 13.7 GB/s with 1-byte loads and 82.9 GB/s with 16-byte loads. The Sobel kernel has the lowest rate, 18.4 GB/s, because it issues the most load instructions per byte. For each byte that it writes, its code reads 12 bytes, most of them answered by the L1 cache, and it takes a square root. The apply-table kernel, at 21.6 GB/s, adds a gather to its 2 bytes. Moreover, each kernel runs for only a fraction of a millisecond, so its start-up and its last, partly filled wave of blocks are a visible part of its time.
24.9.3 Rust and C++
The Rust kernels take 1.380 ms against 1.079 ms in C++, which is 28% more. The difference lies in 3
kernels: the row pass (0.301 against 0.208 ms), the column pass (0.280 against 0.210 ms) and the
Sobel kernel (0.350 against 0.225 ms). The 2 maps and the histogram are within 10% of each other in
the two languages. The 3 slower kernels are those that index slices most. In cuda-oxide, every index
into a slice, such as src[r * W + c], compiles to a comparison with the length of the slice and a
branch that stops the kernel if the index lies outside. The Sobel kernel performs 12 such reads per
pixel. We ran the Rust program with #[kernel(unchecked_indexing)] on every kernel, which removes
the checks. It gave 0.228 ms for each blur pass, 0.268 ms for the Sobel kernel and 1.175 ms for the
7 stages, with the same edge image. The checks therefore account for about 2/3 of the difference.
The flag makes an index out of range undefined behavior, as it is in C++, and so the programs keep
the checks.
24.10 A batch of images on streams
24.10.1 Copies and kernels
A program that processes a sequence of video frames must also copy each frame to the device and each result back. Per image, the copy in moves 6.2 MB, and the copy out moves 2.1 MB. On 1 stream, the 2 copies and the 7 kernels run one after the other, and the SMs wait during the copies. The copies, however, are not performed by the SMs, so in principle they could run while the SMs work on another image.
Definition 24.12 Copy engine and pinned memory. A copy engine is a unit of the GPU that moves data between host memory and device memory while the SMs run kernels. Pinned memory is host memory that the operating system keeps at a fixed physical address, so that a copy engine can read and write it without the CPU. An asynchronous copy, one that returns to the host before it is done, requires pinned memory.
Example. While the SMs blur image 0, a copy engine can copy image 1 from pinned host memory into the buffers of a second stream.
The batch therefore gives image \(\mathsf{image}\) to stream \(\mathsf{image} \bmod S\), with 1 set of buffers for each of the \(S\) streams, as in Chapter 6. Here \(S\) is the number of streams, and \(\mathsf{image} \bmod S\) is the remainder of \(\mathsf{image}\) on division by \(S\); with \(S = 3\), for example, images 0, 3 and 6 go to stream 0, and image 4 goes to stream 1. The programs call such a set of buffers a lane, a name that has nothing to do with the lanes of a warp.
Batch(\(\mathsf{images}, n, S\))
- for \(\mathsf{image} \in [0, n)\) {
- \(\mathsf{slot} = \mathsf{image} \bmod S\)
- on stream \(\mathsf{slot}\): copy \(\mathsf{images}[\mathsf{image}]\) into \(\mathsf{lanes}[\mathsf{slot}].\mathsf{rgb}\) // host to device
- on stream \(\mathsf{slot}\): the 7 kernels on \(\mathsf{lanes}[\mathsf{slot}]\)
- on stream \(\mathsf{slot}\): copy \(\mathsf{lanes}[\mathsf{slot}].\mathsf{edges}\) into \(\mathsf{out}[\mathsf{slot}]\) // device to host
- }
- wait for every stream
The kernels of images \(\mathsf{image}\) and \(\mathsf{image} + S\) use the same lane on the same stream, so they run in order and cannot overwrite each other’s buffers. The host loop issues all the work at once and then waits in line 7. The following code implements the procedure.
/// Uploads, processes and downloads `count` images, image `image` on stream
/// image % streams.len().
/// Returns images per second.
fn batch(
module: &kernels::LoadedModule,
streams: &[Arc<CudaStream>],
lanes: &mut [Buffers],
inputs: &[PinnedHostBuffer<u8>],
outputs: &mut [PinnedHostBuffer<u8>],
count: usize,
) -> Result<f64, Error> {
let start = Instant::now();
for image in 0..count {
let slot = image % streams.len();
let (stream, buffers) = (&streams[slot], &mut lanes[slot]);
let input = &inputs[image % inputs.len()];
// SAFETY: no host buffer is read, written or dropped until every stream is
// synchronized below, after all copies have completed.
unsafe { buffers.rgb.copy_from_pinned_host_async(stream, input)? };
process(module, stream, buffers)?;
unsafe { buffers.edges.copy_to_pinned_host_async(stream, &mut outputs[slot])? };
}
for stream in streams {
stream.synchronize()?;
}
Ok(count as f64 / start.elapsed().as_secs_f64())
}// Uploads, processes and downloads `count` images, image `image` on stream image % n.
// Returns images per second.
double batch(cudaStream_t* streams, Buffers* lanes, int n, uint8_t** inputs,
uint8_t** outputs, int count)
{
double t0 = nowMs();
for (int image = 0; image < count; ++image) {
int slot = image % n;
cudaStream_t stream = streams[slot];
Buffers& buffers = lanes[slot];
const uint8_t* input = inputs[image % 4];
uint8_t* output = outputs[slot];
size_t bytes = 3 * PIXELS;
check(cudaMemcpyAsync(buffers.rgb, input, bytes, cudaMemcpyHostToDevice, stream));
process(stream, buffers);
uint8_t* edges = buffers.edges;
check(cudaMemcpyAsync(output, edges, PIXELS, cudaMemcpyDeviceToHost, stream));
}
for (int slot = 0; slot < n; ++slot) {
check(cudaStreamSynchronize(streams[slot]));
}
return count / ((nowMs() - t0) / 1e3);
}
In Rust, the 2 asynchronous copies are unsafe, because the device reads and writes the host buffers
after the call has returned, and the compiler cannot see when the device is done. The // SAFETY:
comment states the condition that makes the copies correct, namely that no host buffer is read,
written or dropped until every stream has been synchronized. The C++ calls to cudaMemcpyAsync
carry the same condition without a marker.
24.10.2 Measured overlap
The programs first time the 2 copies alone, and then process a batch of 128 images on 1, 2 and 3 streams, after 1 batch to warm up. The C++ program printed the following results.
copy in 0.201 ms 30.9 GB/s
copy out 0.070 ms 29.8 GB/s
batch of 128 images: copy in, 7 stages, copy out
1 stream(s) 695.3 images/s
2 stream(s) 835.3 images/s
3 stream(s) 859.5 images/s
CPU, 8 threads 37.7 images/s
batch outputs match the CPU: yes
PASSED
The Rust program measured 573.4, 686.7 and 689.9 images/s on 1, 2 and 3 streams, and 51.0 images/s for its CPU version. The CPU rates varied between runs, from 37.7 to 51.0 images/s.
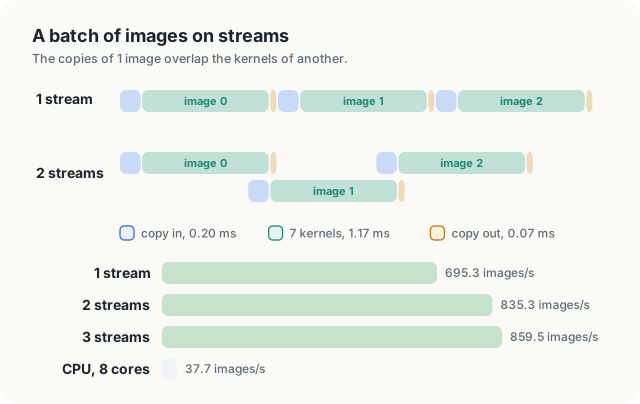
The rates follow from the measured times. On 1 stream, an image costs its copy in, its 7 kernels and its copy out in turn, that is, \(0.201 + 1.165 + 0.070 = 1.436\) ms, or 696 images/s, and the measured 695.3 images/s agrees. The copies take 0.271 ms of the 1.436 ms, or 19%. If they were hidden completely, the kernels alone would set the rate, at 1 image per 1.165 ms, or 858 images/s.
With 2 streams, the program reaches 835.3 images/s, which is 1.197 ms per image. Of the 0.271 ms of copies per image, 0.239 ms, or 88%, now run while kernels run. With 3 streams, it reaches 859.5 images/s, which is 1.163 ms per image, so the copies are hidden completely, and the kernels of consecutive images run back to back (Figure 24.13). More streams cannot help, because the SMs are then busy all the time. On this integrated GPU, the copies and the kernels share the same memory, and they still overlap well. The copy engine moves about 31 GB/s and the kernels about 29 GB/s, together well under the 102 GB/s of the memory.
The Rust program follows the same account. Its times, \(0.203 + 1.489 + 0.072 = 1.764\) ms, predict 567 images/s on 1 stream, against 573.4 measured. On 3 streams, its 689.9 images/s, or 1.450 ms per image, are again the rate of its kernels alone. On 3 streams, the GPU processes images 22.8 times as fast as the CPU version in the C++ run, 859.5 against 37.7 images/s. In the Rust run, the factor is 13.5, 689.9 against 51.0 images/s. Both programs produce exactly the same output as the CPU.
Exercises
24.19 Use the measured times of the copies and of the 7 kernels to predict the rate on 1 stream and
the best possible rate on many streams. Compare with the measurements.
24.20 Run the batch with 4 and 6 streams. Explain why the rate stops growing.
24.21 The Rust program spends more time per image in its kernels than the C++ program. Does the
benefit of a second stream, as a fraction, grow or shrink when the kernels are slower?
24.11 The complete programs
The following listings give the whole Rust program, src/main.rs, and the whole C++ program,
capstone.cu.
//! Chapter 24: an image pipeline. Gray conversion, histogram equalization, a separable
//! Gaussian blur and Sobel edges, checked pixel by pixel against the CPU, then a batch of
//! images on 1, 2 and 3 streams.
//!
//! cargo oxide run
use std::fs::File;
use std::io::{BufWriter, Write};
use std::sync::Arc;
use std::time::Instant;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, LaunchConfig1D, LaunchConfig2D};
use cuda_core::PinnedHostBuffer;
use cuda_device::atomic::{AtomicOrdering, BlockAtomicU32, DeviceAtomicU32};
use cuda_device::float::sqrt_rn_f32;
use cuda_device::thread::Index2D;
use cuda_device::{DisjointSlice, SharedArray, cuda_module, device, kernel, launch_contract};
use cuda_device::{thread, warp};
const W: usize = 1920;
const H: usize = 1080;
const PIXELS: usize = W * H; // 2,073,600
const BATCH: usize = 128;
const ROW_T: usize = 128; // outputs per block of the row pass
const COL_W: usize = 32; // columns per block of the column pass
const COL_H: usize = 8; // rows per block of the column pass
type Error = Box<dyn std::error::Error>;
#[cuda_module]
mod kernels {
use super::*;
/// Position `i - 2` clamped to [0, n): slot `i` of a window that starts 2 before.
#[device]
fn tap(slot: usize, size: usize) -> usize {
if slot < 2 { 0 } else { (slot - 2).min(size - 1) }
}
#[device]
fn warp_scan(mut value: u32) -> u32 {
let lane = warp::lane_id();
let mut step = 0;
#[unroll]
while step < 5 {
let offset = 1 << step;
let left = warp::shuffle_up_sync(u32::MAX, value, offset);
if lane >= offset {
value += left;
}
step += 1;
}
value
}
/// 1 thread per pixel. BT.601 weights in 8-bit fixed point: 77 + 150 + 29 = 256.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn grayscale(rgb: &[u8], mut gray: DisjointSlice<u8>) {
let idx = thread::index_1d();
let byte = 3 * idx.get();
if let Some(gray_pixel) = gray.get_mut(idx) {
let (red, green) = (rgb[byte] as u32, rgb[byte + 1] as u32);
let blue = rgb[byte + 2] as u32;
*gray_pixel = ((77 * red + 150 * green + 29 * blue + 128) >> 8) as u8;
}
}
/// Counts gray levels in shared bins, then adds each block's bins to the global ones.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn histogram(gray: &[u8], bins: &[DeviceAtomicU32]) {
static mut LOCAL: SharedArray<u32, 256> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
// SAFETY: each thread zeroes only its own bin, before the barrier.
unsafe { LOCAL[tid] = 0 };
thread::sync_threads();
let stride = (thread::gridDim_x() * 256) as usize;
let mut pixel = thread::index_1d().get();
while pixel < gray.len() {
// SAFETY: between the 2 barriers every access to LOCAL is atomic.
let bin = unsafe {
let base = (*&raw mut LOCAL).as_mut_ptr();
BlockAtomicU32::from_ptr(base.add(gray[pixel] as usize))
};
bin.fetch_add(1, AtomicOrdering::Relaxed);
pixel += stride;
}
thread::sync_threads();
// SAFETY: after the barrier no thread writes LOCAL again.
let local = unsafe { LOCAL[tid] };
if local > 0 {
bins[tid].fetch_add(local, AtomicOrdering::Relaxed);
}
}
/// 1 block of 256 threads, 1 thread per gray level: the cumulative count of the level,
/// then its new level. Each bin is read and reset to 0 for the next image.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn equalise_table(bins: &[DeviceAtomicU32], mut table: DisjointSlice<u8>) {
static mut WARPS: SharedArray<u32, 8> = SharedArray::UNINIT;
static mut FIRST: SharedArray<u32, 1> = SharedArray::UNINIT;
let level = thread::threadIdx_x() as usize;
let lane = warp::lane_id() as usize;
let warp = level / 32;
let count = bins[level].swap(0, AtomicOrdering::Relaxed);
let inclusive = warp_scan(count);
if lane == 31 {
// SAFETY: lane 31 of each warp writes its own slot, before the barrier.
unsafe { WARPS[warp] = inclusive };
}
if level == 0 {
// SAFETY: only thread 0 writes FIRST before the barrier.
unsafe { FIRST[0] = u32::MAX };
}
thread::sync_threads();
if warp == 0 {
// SAFETY: only warp 0 touches WARPS between the 2 barriers.
let warp_total = if lane < 8 { unsafe { WARPS[lane] } } else { 0 };
let scanned_total = warp_scan(warp_total);
if lane < 8 {
unsafe { WARPS[lane] = scanned_total };
}
}
thread::sync_threads();
// SAFETY: WARPS is only read from here on; FIRST is changed only atomically.
let cdf = inclusive + if warp > 0 { unsafe { WARPS[warp - 1] } } else { 0 };
let first = unsafe { BlockAtomicU32::from_ptr((*&raw mut FIRST).as_mut_ptr()) };
if count > 0 {
first.fetch_min(cdf, AtomicOrdering::Relaxed);
}
thread::sync_threads();
let min = first.load(AtomicOrdering::Relaxed);
let span = (unsafe { WARPS[7] } - min) as u64;
let above = cdf.saturating_sub(min) as u64;
let new_level = if span == 0 {
level as u64
} else {
(above * 255 + span / 2) / span
};
if let Some(entry) = table.get_mut(thread::index_1d()) {
*entry = new_level as u8;
}
}
/// 1 thread per pixel: the new level of each pixel, looked up in the table.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn apply_table(gray: &[u8], table: &[u8], mut out: DisjointSlice<u8>) {
let idx = thread::index_1d();
let pixel = idx.get();
if let Some(cell) = out.get_mut(idx) {
*cell = table[gray[pixel] as usize];
}
}
/// Row pass, weights 1 4 6 4 1. Slot `slot` of the tile holds pixel left + slot - 2,
/// clamped: 2 halo slots on the left, 128 own pixels, 2 halo slots on the right.
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (128, 1, 1))]
pub fn blur_rows(src: &[u8], mut out: DisjointSlice<u16, Index2D<W>>) {
static mut TILE: SharedArray<u32, { ROW_T + 4 }> = SharedArray::UNINIT;
let thread_idx = thread::threadIdx_x() as usize;
let left = thread::blockIdx_x() as usize * ROW_T;
let row = thread::blockIdx_y() as usize * W;
let pixel = |slot: usize| src[row + tap(left + slot, W)] as u32;
// SAFETY: each slot is written by exactly 1 thread, before the barrier.
unsafe { TILE[thread_idx + 2] = pixel(thread_idx + 2) };
if thread_idx < 2 {
unsafe { TILE[thread_idx] = pixel(thread_idx) };
unsafe { TILE[ROW_T + 2 + thread_idx] = pixel(ROW_T + 2 + thread_idx) };
}
thread::sync_threads();
// SAFETY: after the barrier the tile is only read.
let window = |offset: usize| unsafe { TILE[thread_idx + offset] };
let sum = window(0) + 4 * window(1) + 6 * window(2) + 4 * window(3) + window(4);
if let Some(idx) = thread::index_2d::<W>()
&& let Some(cell) = out.get_mut(idx)
{
*cell = sum as u16;
}
}
/// Column pass on a tile of 32 columns and 8 + 4 rows. The 2 passes weigh by
/// 16 x 16 = 256, so the result is the rounded sum shifted right by 8.
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (32, 8, 1))]
pub fn blur_cols(src: &[u16], mut out: DisjointSlice<u8, Index2D<W>>) {
static mut TILE: SharedArray<u32, { (COL_H + 4) * COL_W }> = SharedArray::UNINIT;
let tile_col = thread::threadIdx_x() as usize;
let tile_row = thread::threadIdx_y() as usize;
let x = thread::blockIdx_x() as usize * COL_W + tile_col;
let top = thread::blockIdx_y() as usize * COL_H;
let value = |slot: usize| src[tap(top + slot, H) * W + x] as u32;
// SAFETY: each slot is written by exactly 1 thread, before the barrier.
unsafe { TILE[(tile_row + 2) * COL_W + tile_col] = value(tile_row + 2) };
if tile_row < 2 {
unsafe { TILE[tile_row * COL_W + tile_col] = value(tile_row) };
let below = COL_H + 2 + tile_row;
unsafe { TILE[below * COL_W + tile_col] = value(below) };
}
thread::sync_threads();
// SAFETY: after the barrier the tile is only read.
let window = |offset: usize| {
let slot = (tile_row + offset) * COL_W + tile_col;
unsafe { TILE[slot] }
};
let sum = window(0) + 4 * window(1) + 6 * window(2) + 4 * window(3) + window(4);
if let Some(idx) = thread::index_2d::<W>()
&& let Some(cell) = out.get_mut(idx)
{
*cell = ((sum + 128) >> 8) as u8;
}
}
/// Sobel gradient magnitude divided by 4, rounded and clamped to 255. The 8 neighbors
/// come from global memory; neighboring threads share them through the L1 cache.
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (32, 8, 1))]
pub fn sobel(src: &[u8], mut out: DisjointSlice<u8, Index2D<W>>) {
let (x, y) = (thread::index_2d_col(), thread::index_2d_row());
let (x_left, x_right) = (x.saturating_sub(1), (x + 1).min(W - 1));
let (y_above, y_below) = (y.saturating_sub(1), (y + 1).min(H - 1));
let at = |row: usize, col: usize| src[row * W + col] as i32;
if let Some(idx) = thread::index_2d::<W>()
&& let Some(cell) = out.get_mut(idx)
{
let right = at(y_above, x_right) + 2 * at(y, x_right) + at(y_below, x_right);
let left = at(y_above, x_left) + 2 * at(y, x_left) + at(y_below, x_left);
let below = at(y_below, x_left) + 2 * at(y_below, x) + at(y_below, x_right);
let above = at(y_above, x_left) + 2 * at(y_above, x) + at(y_above, x_right);
let (gx, gy) = (right - left, below - above);
let magnitude = sqrt_rn_f32((gx * gx + gy * gy) as f32);
*cell = (magnitude * 0.25 + 0.5).min(255.0) as u8;
}
}
}
/// The device buffers of 1 image in flight.
struct Buffers {
rgb: DeviceBuffer<u8>,
gray: DeviceBuffer<u8>,
bins: DeviceBuffer<DeviceAtomicU32>,
table: DeviceBuffer<u8>,
equal: DeviceBuffer<u8>,
rows: DeviceBuffer<u16>,
blurred: DeviceBuffer<u8>,
edges: DeviceBuffer<u8>,
}
impl Buffers {
fn new(stream: &Arc<CudaStream>) -> Result<Self, Error> {
Ok(Buffers {
rgb: DeviceBuffer::zeroed(stream, 3 * PIXELS)?,
gray: DeviceBuffer::zeroed(stream, PIXELS)?,
bins: DeviceBuffer::<u32>::zeroed(stream, 256)?.cast_elem(),
table: DeviceBuffer::zeroed(stream, 256)?,
equal: DeviceBuffer::zeroed(stream, PIXELS)?,
rows: DeviceBuffer::zeroed(stream, PIXELS)?,
blurred: DeviceBuffer::zeroed(stream, PIXELS)?,
edges: DeviceBuffer::zeroed(stream, PIXELS)?,
})
}
}
/// Name of each stage, and the bytes it must read and write per pixel.
const STAGES: [(&str, usize); 7] = [
("grayscale", 4),
("histogram", 1),
("table", 0),
("apply table", 2),
("blur rows", 3),
("blur columns", 3),
("sobel", 2),
];
/// Launches stage `index` of the pipeline on `stream`.
fn stage(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
buffers: &mut Buffers,
index: usize,
) -> Result<(), Error> {
let line = LaunchConfig1D::new((PIXELS / 256) as u32, 256, 0);
let rows = LaunchConfig2D::new(((W / ROW_T) as u32, H as u32), (ROW_T as u32, 1), 0);
let grid = ((W / COL_W) as u32, (H / COL_H) as u32);
let tiles = LaunchConfig2D::new(grid, (COL_W as u32, COL_H as u32), 0);
match index {
0 => {
let launch = module.prepare_grayscale(line)?;
module.grayscale(stream, &launch, &buffers.rgb, &mut buffers.gray)?;
}
1 => {
let launch = module.prepare_histogram(LaunchConfig1D::new(64, 256, 0))?;
module.histogram(stream, &launch, &buffers.gray, &buffers.bins)?;
}
2 => {
let launch = module.prepare_equalise_table(LaunchConfig1D::new(1, 256, 0))?;
module.equalise_table(stream, &launch, &buffers.bins, &mut buffers.table)?;
}
3 => {
let launch = module.prepare_apply_table(line)?;
let (gray, table) = (&buffers.gray, &buffers.table);
module.apply_table(stream, &launch, gray, table, &mut buffers.equal)?;
}
4 => {
let launch = module.prepare_blur_rows(rows)?;
module.blur_rows(stream, &launch, &buffers.equal, &mut buffers.rows)?;
}
5 => {
let launch = module.prepare_blur_cols(tiles)?;
module.blur_cols(stream, &launch, &buffers.rows, &mut buffers.blurred)?;
}
_ => {
let launch = module.prepare_sobel(tiles)?;
module.sobel(stream, &launch, &buffers.blurred, &mut buffers.edges)?;
}
}
Ok(())
}
/// All 7 stages of 1 image, in order, on `stream`.
fn process(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
buffers: &mut Buffers,
) -> Result<(), Error> {
for index in 0..STAGES.len() {
stage(module, stream, buffers, index)?;
}
Ok(())
}
/// Average time of 100 runs of `launch`, in milliseconds, after 1 warm-up run.
fn time_ms(
stream: &Arc<CudaStream>,
mut launch: impl FnMut() -> Result<(), Error>,
) -> Result<f64, Error> {
launch()?;
stream.synchronize()?;
let start = Instant::now();
for _ in 0..100 {
launch()?;
}
stream.synchronize()?;
Ok(start.elapsed().as_secs_f64() * 1e3 / 100.0)
}
/// Uploads, processes and downloads `count` images, image `image` on stream
/// image % streams.len().
/// Returns images per second.
fn batch(
module: &kernels::LoadedModule,
streams: &[Arc<CudaStream>],
lanes: &mut [Buffers],
inputs: &[PinnedHostBuffer<u8>],
outputs: &mut [PinnedHostBuffer<u8>],
count: usize,
) -> Result<f64, Error> {
let start = Instant::now();
for image in 0..count {
let slot = image % streams.len();
let (stream, buffers) = (&streams[slot], &mut lanes[slot]);
let input = &inputs[image % inputs.len()];
// SAFETY: no host buffer is read, written or dropped until every stream is
// synchronized below, after all copies have completed.
unsafe { buffers.rgb.copy_from_pinned_host_async(stream, input)? };
process(module, stream, buffers)?;
unsafe { buffers.edges.copy_to_pinned_host_async(stream, &mut outputs[slot])? };
}
for stream in streams {
stream.synchronize()?;
}
Ok(count as f64 / start.elapsed().as_secs_f64())
}
/// The 4 images of the pipeline that are kept: gray, equalized, blurred and edges.
struct Images {
gray: Vec<u8>,
equal: Vec<u8>,
blurred: Vec<u8>,
edges: Vec<u8>,
}
/// Runs `f(y, row)` for every row of `out`, the rows split into 1 band per CPU core.
fn par_rows<T: Send>(out: &mut [T], f: impl Fn(usize, &mut [T]) + Sync) {
let cores = std::thread::available_parallelism().map_or(1, |n| n.get());
let band = H.div_ceil(cores);
std::thread::scope(|s| {
for (k, chunk) in out.chunks_mut(band * W).enumerate() {
let f = &f;
s.spawn(move || {
for (r, row) in chunk.chunks_mut(W).enumerate() {
f(k * band + r, row);
}
});
}
});
}
/// The CPU version of `tap`.
fn tap(slot: usize, size: usize) -> usize {
if slot < 2 { 0 } else { (slot - 2).min(size - 1) }
}
/// The same 7 stages on the CPU, with the same integer arithmetic, rows on every core.
fn cpu_pipeline(rgb: &[u8]) -> Images {
let mut gray = vec![0u8; PIXELS];
par_rows(&mut gray, |y, row| {
for (x, gray_pixel) in row.iter_mut().enumerate() {
let byte = 3 * (y * W + x);
let (red, green) = (rgb[byte] as u32, rgb[byte + 1] as u32);
let blue = rgb[byte + 2] as u32;
*gray_pixel = ((77 * red + 150 * green + 29 * blue + 128) >> 8) as u8;
}
});
let mut bins = [0u32; 256];
for &level in &gray {
bins[level as usize] += 1;
}
let min = bins.iter().copied().find(|&count| count > 0).unwrap_or(0);
let span = (PIXELS as u32 - min) as u64;
let mut table = [0u8; 256];
let mut cdf = 0u32;
for level in 0..256 {
cdf += bins[level];
let above = cdf.saturating_sub(min) as u64;
let new_level = if span == 0 {
level as u64
} else {
(above * 255 + span / 2) / span
};
table[level] = new_level as u8;
}
let mut equal = vec![0u8; PIXELS];
par_rows(&mut equal, |y, row| {
for (x, equal_pixel) in row.iter_mut().enumerate() {
*equal_pixel = table[gray[y * W + x] as usize];
}
});
let mut rows = vec![0u32; PIXELS];
par_rows(&mut rows, |y, row| {
let window = |slot: usize| equal[y * W + tap(slot, W)] as u32;
for (x, row_sum) in row.iter_mut().enumerate() {
let near = window(x) + 4 * window(x + 1) + 6 * window(x + 2);
*row_sum = near + 4 * window(x + 3) + window(x + 4);
}
});
let mut blurred = vec![0u8; PIXELS];
par_rows(&mut blurred, |y, row| {
for (x, blurred_pixel) in row.iter_mut().enumerate() {
let window = |offset: usize| rows[tap(y + offset, H) * W + x];
let sum = window(0) + 4 * window(1) + 6 * window(2) + 4 * window(3) + window(4);
*blurred_pixel = ((sum + 128) >> 8) as u8;
}
});
let mut edges = vec![0u8; PIXELS];
par_rows(&mut edges, |y, row| {
let at = |row: usize, col: usize| blurred[row * W + col] as i32;
let (y_above, y_below) = (y.saturating_sub(1), (y + 1).min(H - 1));
for (x, edge) in row.iter_mut().enumerate() {
let (x_left, x_right) = (x.saturating_sub(1), (x + 1).min(W - 1));
let right = at(y_above, x_right) + 2 * at(y, x_right) + at(y_below, x_right);
let left = at(y_above, x_left) + 2 * at(y, x_left) + at(y_below, x_left);
let below = at(y_below, x_left) + 2 * at(y_below, x) + at(y_below, x_right);
let above = at(y_above, x_left) + 2 * at(y_above, x) + at(y_above, x_right);
let (gx, gy) = (right - left, below - above);
let magnitude = ((gx * gx + gy * gy) as f32).sqrt();
*edge = (magnitude * 0.25 + 0.5).min(255.0) as u8;
}
});
Images { gray, equal, blurred, edges }
}
/// A synthetic 1920 x 1080 scene with low contrast: sky, sun, hills, a house, grain.
fn scene(seed: u32) -> Vec<u8> {
let mut state = seed;
let mut rgb = vec![0u8; 3 * PIXELS];
let shift = seed as f32 * 0.05;
for y in 0..H {
for x in 0..W {
let (u, v) = (x as f32 / W as f32, y as f32 / H as f32);
let hill = 0.62 + 0.07 * (u * 9.0 + shift * 20.0).sin();
let sun = (x as f32 - (0.72 + shift) * W as f32).hypot(y as f32 - 260.0);
let house = (0.18..0.34).contains(&u) && (0.48..0.80).contains(&v);
let window = (0.22..0.27).contains(&u) && (0.56..0.64).contains(&v);
let roof = v < 0.48 && v > 0.36 && (u - 0.26).abs() < (v - 0.36) * 0.75;
let base = if window {
[92, 96, 88]
} else if house {
[150, 118, 104]
} else if roof {
[128, 92, 84]
} else if sun < 72.0 {
[176, 168, 120]
} else if v > hill {
[84, 112, 78]
} else {
let sky = (v * 40.0) as i32;
[110 + sky, 126 + sky, 150]
};
state = state.wrapping_mul(1_664_525).wrapping_add(1_013_904_223);
let grain = (state >> 28) as i32 - 8;
let p = 3 * (y * W + x);
for c in 0..3 {
rgb[p + c] = (base[c] + grain).clamp(0, 255) as u8;
}
}
}
rgb
}
/// Writes a binary PGM (gray) or PPM (RGB) file.
fn write_image(path: &str, data: &[u8], channels: usize) -> Result<(), Error> {
let mut file = BufWriter::new(File::create(path)?);
let magic = if channels == 3 { "P6" } else { "P5" };
write!(file, "{magic}\n{W} {H}\n255\n")?;
file.write_all(data)?;
Ok(())
}
/// Prints how many pixels of 2 images differ, and the first one that does.
fn report(label: &str, gpu: &[u8], cpu: &[u8]) -> usize {
let wrong = gpu.iter().zip(cpu).filter(|(a, b)| a != b).count();
print!(" {label:<10} {wrong:8}");
if let Some(i) = (0..PIXELS).find(|&i| gpu[i] != cpu[i]) {
let (x, y) = (i % W, i / W);
print!(" first at ({x}, {y}): GPU {}, CPU {}", gpu[i], cpu[i]);
}
println!();
wrong
}
/// FNV-1a hash of an image, to compare the outputs of 2 programs.
fn checksum(data: &[u8]) -> u32 {
let mut h = 2_166_136_261u32;
for &byte in data {
h = (h ^ byte as u32).wrapping_mul(16_777_619);
}
h
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let streams = [ctx.new_stream()?, ctx.new_stream()?, ctx.new_stream()?];
let stream = &streams[0];
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let name = ctx.device_name()?;
let sms = ctx.multiprocessor_count()?;
println!("GPU: {name}, {sms} SMs image {W} x {H} = {PIXELS} pixels");
let scenes: Vec<Vec<u8>> = (0..4).map(scene).collect();
let reference: Vec<Images> = scenes.iter().map(|rgb| cpu_pipeline(rgb)).collect();
// 1. Each stage of 1 image, timed alone.
let mut b = Buffers::new(stream)?;
b.rgb = DeviceBuffer::from_host(stream, &scenes[0])?;
let warm = Instant::now();
while warm.elapsed().as_secs_f64() < 0.4 {
time_ms(stream, || process(&module, stream, &mut b))?; // raise the GPU clock
}
println!("stage ms GB/s");
let mut total = 0.0;
for (k, (label, bytes)) in STAGES.iter().enumerate() {
let ms = time_ms(stream, || stage(&module, stream, &mut b, k))?;
let gb = (bytes * PIXELS) as f64 / 1e9 / (ms / 1e3);
println!(" {label:<13} {ms:7.3} {gb:7.1}");
total += ms;
}
let all = time_ms(stream, || process(&module, stream, &mut b))?;
println!(" sum of stages {total:7.3}");
println!(" all 7 in turn {all:7.3}");
// 2. The GPU's images against the CPU's, pixel by pixel.
let gpu = Images {
gray: b.gray.to_host_vec(stream)?,
equal: b.equal.to_host_vec(stream)?,
blurred: b.blurred.to_host_vec(stream)?,
edges: b.edges.to_host_vec(stream)?,
};
let cpu = &reference[0];
println!("image pixels that differ from the CPU");
let mut wrong = report("gray", &gpu.gray, &cpu.gray);
wrong += report("equalised", &gpu.equal, &cpu.equal);
wrong += report("blurred", &gpu.blurred, &cpu.blurred);
wrong += report("edges", &gpu.edges, &cpu.edges);
println!("edge image checksum: {:08x}", checksum(&gpu.edges));
std::fs::create_dir_all("target/images")?;
write_image("target/images/input.ppm", &scenes[0], 3)?;
write_image("target/images/gray.pgm", &gpu.gray, 1)?;
write_image("target/images/equalised.pgm", &gpu.equal, 1)?;
write_image("target/images/blurred.pgm", &gpu.blurred, 1)?;
write_image("target/images/edges.pgm", &gpu.edges, 1)?;
// 3. The CPU on every core, 4 images.
let start = Instant::now();
for rgb in &scenes {
cpu_pipeline(rgb);
}
let cpu_rate = scenes.len() as f64 / start.elapsed().as_secs_f64();
let cores = std::thread::available_parallelism().map_or(1, |n| n.get());
// 4. The copies alone, then a batch: copy in, 7 stages, copy out, on 1 to 3 streams.
let mut inputs = Vec::new();
for rgb in &scenes {
inputs.push(PinnedHostBuffer::from_slice(&ctx, rgb)?);
}
let mut outputs = Vec::new();
for _ in 0..3 {
outputs.push(PinnedHostBuffer::from_slice(&ctx, &vec![0u8; PIXELS])?);
}
let mut lanes = vec![b, Buffers::new(stream)?, Buffers::new(stream)?];
stream.synchronize()?;
let lane = &mut lanes[0];
let copy_in = time_ms(stream, || {
// SAFETY: time_ms synchronizes the stream before the host buffers are used again.
unsafe { lane.rgb.copy_from_pinned_host_async(stream, &inputs[0])? };
Ok(())
})?;
let copy_out = time_ms(stream, || {
// SAFETY: as above.
unsafe { lane.edges.copy_to_pinned_host_async(stream, &mut outputs[0])? };
Ok(())
})?;
let rate_in = (3 * PIXELS) as f64 / 1e9 / (copy_in / 1e3);
let rate_out = PIXELS as f64 / 1e9 / (copy_out / 1e3);
println!("copy in {copy_in:6.3} ms {rate_in:5.1} GB/s");
println!("copy out {copy_out:6.3} ms {rate_out:5.1} GB/s");
batch(&module, &streams, &mut lanes, &inputs, &mut outputs, BATCH)?; // warm up
println!("batch of {BATCH} images: copy in, 7 stages, copy out");
let mut correct = true;
for n in 1..=3 {
let (some, used, out) = (&streams[..n], &mut lanes[..n], &mut outputs[..n]);
let rate = batch(&module, some, used, &inputs, out, BATCH)?;
println!(" {n} stream(s) {rate:6.1} images/s");
for k in 0..n {
let last = (BATCH - 1 - (BATCH - 1 - k) % n) % inputs.len();
correct &= outputs[k].as_slice() == reference[last].edges.as_slice();
}
}
println!(" CPU, {cores} threads {cpu_rate:6.1} images/s");
let verdict = if wrong == 0 && correct { "PASSED" } else { "FAILED" };
println!("batch outputs match the CPU: {}", if correct { "yes" } else { "no" });
println!("{verdict}");
Ok(())
}// Chapter 24: an image pipeline. Gray conversion, histogram equalization, a separable
// Gaussian blur and Sobel edges, checked pixel by pixel against the CPU, then a batch of
// images on 1, 2 and 3 streams.
// Build: nvcc -O3 -arch=native -Xcompiler -ffp-contract=off capstone.cu -o capstone
#include <algorithm>
#include <chrono>
#include <cmath>
#include <cstdint>
#include <cstdio>
#include <cstdlib>
#include <cstring>
#include <thread>
#include <vector>
#include <cuda_runtime.h>
const int W = 1920;
const int H = 1080;
const int PIXELS = W * H; // 2,073,600
const int BATCH = 128;
const int ROW_T = 128; // outputs per block of the row pass
const int COL_W = 32; // columns per block of the column pass
const int COL_H = 8; // rows per block of the column pass
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// Position slot - 2 clamped to [0, size): slot `slot` of a window that starts 2 before.
__host__ __device__ int tap(int slot, int size)
{
int position = slot < 2 ? 0 : slot - 2;
return position < size ? position : size - 1;
}
__device__ unsigned warpScan(unsigned value)
{
int lane = threadIdx.x % 32;
#pragma unroll
for (int offset = 1; offset < 32; offset *= 2) {
unsigned left = __shfl_up_sync(0xffffffffu, value, offset);
if (lane >= offset) {
value += left;
}
}
return value;
}
// 1 thread per pixel. BT.601 weights in 8-bit fixed point: 77 + 150 + 29 = 256.
__global__ void grayscale(const uint8_t* rgb, uint8_t* gray)
{
int pixel = blockIdx.x * blockDim.x + threadIdx.x;
if (pixel < PIXELS) {
unsigned red = rgb[3 * pixel];
unsigned green = rgb[3 * pixel + 1];
unsigned blue = rgb[3 * pixel + 2];
gray[pixel] = (77 * red + 150 * green + 29 * blue + 128) >> 8;
}
}
// Counts gray levels in shared bins, then adds each block's bins to the global ones.
__global__ void histogram(const uint8_t* gray, unsigned* bins)
{
__shared__ unsigned local[256];
local[threadIdx.x] = 0;
__syncthreads();
int stride = gridDim.x * 256;
for (int pixel = blockIdx.x * 256 + threadIdx.x; pixel < PIXELS; pixel += stride) {
atomicAdd(&local[gray[pixel]], 1u);
}
__syncthreads();
if (local[threadIdx.x] > 0) {
atomicAdd(&bins[threadIdx.x], local[threadIdx.x]);
}
}
// 1 block of 256 threads, 1 thread per gray level: the cumulative count of the level,
// then its new level. Each bin is read and reset to 0 for the next image.
__global__ void equaliseTable(unsigned* bins, uint8_t* table)
{
__shared__ unsigned warps[8];
__shared__ unsigned first;
int level = threadIdx.x;
int lane = level % 32;
int warp = level / 32;
unsigned count = atomicExch(&bins[level], 0u);
unsigned inclusive = warpScan(count);
if (lane == 31) {
warps[warp] = inclusive;
}
if (level == 0) {
first = 0xffffffffu;
}
__syncthreads();
if (warp == 0) {
unsigned scannedTotal = warpScan(lane < 8 ? warps[lane] : 0);
if (lane < 8) {
warps[lane] = scannedTotal;
}
}
__syncthreads();
unsigned cdf = inclusive + (warp > 0 ? warps[warp - 1] : 0);
if (count > 0) {
atomicMin(&first, cdf);
}
__syncthreads();
uint64_t span = warps[7] - first;
uint64_t above = cdf > first ? cdf - first : 0;
uint64_t newLevel = span == 0 ? level : (above * 255 + span / 2) / span;
table[level] = newLevel;
}
// 1 thread per pixel: the new level of each pixel, looked up in the table.
__global__ void applyTable(const uint8_t* gray, const uint8_t* table, uint8_t* out)
{
int pixel = blockIdx.x * blockDim.x + threadIdx.x;
if (pixel < PIXELS) {
out[pixel] = table[gray[pixel]];
}
}
// Row pass, weights 1 4 6 4 1. Slot `slot` of the tile holds pixel left + slot - 2,
// clamped: 2 halo slots on the left, 128 own pixels, 2 halo slots on the right.
__global__ void blurRows(const uint8_t* src, uint16_t* out)
{
__shared__ unsigned tile[ROW_T + 4];
int left = blockIdx.x * ROW_T;
const uint8_t* row = src + blockIdx.y * W;
tile[threadIdx.x + 2] = row[tap(left + threadIdx.x + 2, W)];
if (threadIdx.x < 2) {
tile[threadIdx.x] = row[tap(left + threadIdx.x, W)];
tile[ROW_T + 2 + threadIdx.x] = row[tap(left + ROW_T + 2 + threadIdx.x, W)];
}
__syncthreads();
const unsigned* window = tile + threadIdx.x;
unsigned sum = window[0] + 4 * window[1] + 6 * window[2] + 4 * window[3] + window[4];
out[blockIdx.y * W + left + threadIdx.x] = sum;
}
// Column pass on a tile of 32 columns and 8 + 4 rows. The 2 passes weigh by
// 16 x 16 = 256, so the result is the rounded sum shifted right by 8.
__global__ void blurCols(const uint16_t* src, uint8_t* out)
{
__shared__ unsigned tile[COL_H + 4][COL_W];
int tileRow = threadIdx.y;
int tileCol = threadIdx.x;
int x = blockIdx.x * COL_W + tileCol;
int top = blockIdx.y * COL_H;
tile[tileRow + 2][tileCol] = src[tap(top + tileRow + 2, H) * W + x];
if (tileRow < 2) {
tile[tileRow][tileCol] = src[tap(top + tileRow, H) * W + x];
tile[COL_H + 2 + tileRow][tileCol] = src[tap(top + COL_H + 2 + tileRow, H) * W + x];
}
__syncthreads();
unsigned sum = tile[tileRow][tileCol] + 4 * tile[tileRow + 1][tileCol];
sum += 6 * tile[tileRow + 2][tileCol] + 4 * tile[tileRow + 3][tileCol];
sum += tile[tileRow + 4][tileCol];
out[(top + tileRow) * W + x] = (sum + 128) >> 8;
}
// Sobel gradient magnitude divided by 4, rounded and clamped to 255. The 8 neighbors
// come from global memory; neighboring threads share them through the L1 cache.
__global__ void sobel(const uint8_t* src, uint8_t* out)
{
int x = blockIdx.x * blockDim.x + threadIdx.x;
int y = blockIdx.y * blockDim.y + threadIdx.y;
int xLeft = max(x - 1, 0);
int xRight = min(x + 1, W - 1);
int yAbove = max(y - 1, 0);
int yBelow = min(y + 1, H - 1);
const uint8_t* upper = src + yAbove * W;
const uint8_t* middle = src + y * W;
const uint8_t* lower = src + yBelow * W;
int right = upper[xRight] + 2 * middle[xRight] + lower[xRight];
int left = upper[xLeft] + 2 * middle[xLeft] + lower[xLeft];
int below = lower[xLeft] + 2 * lower[x] + lower[xRight];
int above = upper[xLeft] + 2 * upper[x] + upper[xRight];
int gx = right - left;
int gy = below - above;
float magnitude = sqrtf(float(gx * gx + gy * gy));
out[y * W + x] = fminf(magnitude * 0.25f + 0.5f, 255.0f);
}
// The device buffers of 1 image in flight.
struct Buffers {
uint8_t* rgb;
uint8_t* gray;
unsigned* bins;
uint8_t* table;
uint8_t* equal;
uint16_t* rows;
uint8_t* blurred;
uint8_t* edges;
};
Buffers allocBuffers()
{
Buffers b;
check(cudaMalloc(&b.rgb, 3 * PIXELS));
check(cudaMalloc(&b.gray, PIXELS));
check(cudaMalloc(&b.bins, 256 * sizeof(unsigned)));
check(cudaMalloc(&b.table, 256));
check(cudaMalloc(&b.equal, PIXELS));
check(cudaMalloc(&b.rows, PIXELS * sizeof(uint16_t)));
check(cudaMalloc(&b.blurred, PIXELS));
check(cudaMalloc(&b.edges, PIXELS));
check(cudaMemset(b.bins, 0, 256 * sizeof(unsigned)));
return b;
}
void freeBuffers(Buffers& b)
{
cudaFree(b.rgb);
cudaFree(b.gray);
cudaFree(b.bins);
cudaFree(b.table);
cudaFree(b.equal);
cudaFree(b.rows);
cudaFree(b.blurred);
cudaFree(b.edges);
}
// Name of each stage, and the bytes it must read and write per pixel.
struct Stage {
const char* name;
int bytes;
};
const Stage STAGES[7] = {
{"grayscale", 4},
{"histogram", 1},
{"table", 0},
{"apply table", 2},
{"blur rows", 3},
{"blur columns", 3},
{"sobel", 2},
};
// Launches stage `index` of the pipeline on `stream`.
void stage(cudaStream_t stream, Buffers& buffers, int index)
{
int line = PIXELS / 256;
dim3 rows(W / ROW_T, H);
dim3 tiles(W / COL_W, H / COL_H);
dim3 tile(COL_W, COL_H);
switch (index) {
case 0:
grayscale<<<line, 256, 0, stream>>>(buffers.rgb, buffers.gray);
break;
case 1:
histogram<<<64, 256, 0, stream>>>(buffers.gray, buffers.bins);
break;
case 2:
equaliseTable<<<1, 256, 0, stream>>>(buffers.bins, buffers.table);
break;
case 3:
applyTable<<<line, 256, 0, stream>>>(buffers.gray, buffers.table, buffers.equal);
break;
case 4:
blurRows<<<rows, ROW_T, 0, stream>>>(buffers.equal, buffers.rows);
break;
case 5:
blurCols<<<tiles, tile, 0, stream>>>(buffers.rows, buffers.blurred);
break;
default:
sobel<<<tiles, tile, 0, stream>>>(buffers.blurred, buffers.edges);
}
}
// All 7 stages of 1 image, in order, on `stream`.
void process(cudaStream_t stream, Buffers& buffers)
{
for (int index = 0; index < 7; ++index) {
stage(stream, buffers, index);
}
}
// Average time of 100 runs of `launch`, in milliseconds, after 1 warm-up run.
template <typename F>
double timeMs(cudaStream_t stream, F launch)
{
launch();
check(cudaStreamSynchronize(stream));
double t0 = nowMs();
for (int timed = 0; timed < 100; ++timed) {
launch();
}
check(cudaGetLastError());
check(cudaStreamSynchronize(stream));
return (nowMs() - t0) / 100;
}
// Uploads, processes and downloads `count` images, image `image` on stream image % n.
// Returns images per second.
double batch(cudaStream_t* streams, Buffers* lanes, int n, uint8_t** inputs,
uint8_t** outputs, int count)
{
double t0 = nowMs();
for (int image = 0; image < count; ++image) {
int slot = image % n;
cudaStream_t stream = streams[slot];
Buffers& buffers = lanes[slot];
const uint8_t* input = inputs[image % 4];
uint8_t* output = outputs[slot];
size_t bytes = 3 * PIXELS;
check(cudaMemcpyAsync(buffers.rgb, input, bytes, cudaMemcpyHostToDevice, stream));
process(stream, buffers);
uint8_t* edges = buffers.edges;
check(cudaMemcpyAsync(output, edges, PIXELS, cudaMemcpyDeviceToHost, stream));
}
for (int slot = 0; slot < n; ++slot) {
check(cudaStreamSynchronize(streams[slot]));
}
return count / ((nowMs() - t0) / 1e3);
}
// The 4 images of the pipeline that are kept: gray, equalized, blurred and edges.
struct Images {
std::vector<uint8_t> gray, equal, blurred, edges;
};
// Runs f(y, row) for every row y, the rows split into 1 band per CPU core.
template <typename F>
void parRows(F f)
{
int cores = std::max(1u, std::thread::hardware_concurrency());
int band = (H + cores - 1) / cores;
std::vector<std::thread> threads;
for (int k = 0; k < cores; ++k) {
threads.emplace_back([=] {
for (int y = k * band; y < std::min(H, (k + 1) * band); ++y) {
f(y);
}
});
}
for (std::thread& t : threads) {
t.join();
}
}
// The same 7 stages on the CPU, with the same integer arithmetic, rows on every core.
Images cpuPipeline(const std::vector<uint8_t>& rgb)
{
Images img;
img.gray.resize(PIXELS);
parRows([&](int y) {
for (int x = 0; x < W; ++x) {
int byte = 3 * (y * W + x);
unsigned red = rgb[byte];
unsigned green = rgb[byte + 1];
unsigned blue = rgb[byte + 2];
img.gray[y * W + x] = (77 * red + 150 * green + 29 * blue + 128) >> 8;
}
});
unsigned bins[256] = {};
for (uint8_t level : img.gray) {
bins[level] += 1;
}
unsigned first = 0;
unsigned cdf = 0;
for (int level = 0; level < 256 && first == 0; ++level) {
first = bins[level];
}
uint64_t span = PIXELS - first;
uint8_t table[256];
for (int level = 0; level < 256; ++level) {
cdf += bins[level];
uint64_t above = cdf > first ? cdf - first : 0;
table[level] = span == 0 ? level : (above * 255 + span / 2) / span;
}
img.equal.resize(PIXELS);
parRows([&](int y) {
for (int x = 0; x < W; ++x) {
img.equal[y * W + x] = table[img.gray[y * W + x]];
}
});
std::vector<unsigned> rows(PIXELS);
parRows([&](int y) {
const uint8_t* equal = &img.equal[y * W];
for (int x = 0; x < W; ++x) {
unsigned sum = equal[tap(x, W)] + 4 * equal[tap(x + 1, W)];
sum += 6 * equal[tap(x + 2, W)] + 4 * equal[tap(x + 3, W)];
rows[y * W + x] = sum + equal[tap(x + 4, W)];
}
});
img.blurred.resize(PIXELS);
parRows([&](int y) {
for (int x = 0; x < W; ++x) {
unsigned sum = rows[tap(y, H) * W + x] + 4 * rows[tap(y + 1, H) * W + x];
sum += 6 * rows[tap(y + 2, H) * W + x] + 4 * rows[tap(y + 3, H) * W + x];
sum += rows[tap(y + 4, H) * W + x];
img.blurred[y * W + x] = (sum + 128) >> 8;
}
});
img.edges.resize(PIXELS);
parRows([&](int y) {
const uint8_t* src = img.blurred.data();
const uint8_t* upper = src + std::max(y - 1, 0) * W;
const uint8_t* middle = src + y * W;
const uint8_t* lower = src + std::min(y + 1, H - 1) * W;
for (int x = 0; x < W; ++x) {
int xLeft = std::max(x - 1, 0);
int xRight = std::min(x + 1, W - 1);
int right = upper[xRight] + 2 * middle[xRight] + lower[xRight];
int left = upper[xLeft] + 2 * middle[xLeft] + lower[xLeft];
int below = lower[xLeft] + 2 * lower[x] + lower[xRight];
int above = upper[xLeft] + 2 * upper[x] + upper[xRight];
int gx = right - left;
int gy = below - above;
float magnitude = std::sqrt(float(gx * gx + gy * gy));
img.edges[y * W + x] = std::min(magnitude * 0.25f + 0.5f, 255.0f);
}
});
return img;
}
// A synthetic 1920 x 1080 scene with low contrast: sky, sun, hills, a house, grain.
std::vector<uint8_t> scene(unsigned seed)
{
unsigned state = seed;
std::vector<uint8_t> rgb(3 * PIXELS);
float shift = seed * 0.05f;
for (int y = 0; y < H; ++y) {
for (int x = 0; x < W; ++x) {
float u = float(x) / W;
float v = float(y) / H;
float hill = 0.62f + 0.07f * std::sin(u * 9.0f + shift * 20.0f);
float sunX = float(x) - (0.72f + shift) * W;
float sun = std::hypot(sunX, float(y) - 260.0f);
bool house = u >= 0.18f && u < 0.34f && v >= 0.48f && v < 0.80f;
bool window = u >= 0.22f && u < 0.27f && v >= 0.56f && v < 0.64f;
bool roof = v < 0.48f && v > 0.36f;
roof = roof && std::fabs(u - 0.26f) < (v - 0.36f) * 0.75f;
int base[3];
if (window) {
base[0] = 92, base[1] = 96, base[2] = 88;
} else if (house) {
base[0] = 150, base[1] = 118, base[2] = 104;
} else if (roof) {
base[0] = 128, base[1] = 92, base[2] = 84;
} else if (sun < 72.0f) {
base[0] = 176, base[1] = 168, base[2] = 120;
} else if (v > hill) {
base[0] = 84, base[1] = 112, base[2] = 78;
} else {
int sky = int(v * 40.0f);
base[0] = 110 + sky, base[1] = 126 + sky, base[2] = 150;
}
state = state * 1664525u + 1013904223u;
int grain = int(state >> 28) - 8;
int p = 3 * (y * W + x);
for (int c = 0; c < 3; ++c) {
rgb[p + c] = std::clamp(base[c] + grain, 0, 255);
}
}
}
return rgb;
}
// Prints how many pixels of 2 images differ, and the first one that does.
using Image = std::vector<uint8_t>;
int report(const char* label, const Image& gpu, const Image& cpu)
{
int wrong = 0;
int firstWrong = -1;
for (int i = 0; i < PIXELS; ++i) {
if (gpu[i] != cpu[i]) {
wrong += 1;
firstWrong = firstWrong < 0 ? i : firstWrong;
}
}
std::printf(" %-10s %8d", label, wrong);
if (firstWrong >= 0) {
int x = firstWrong % W;
int y = firstWrong / W;
int g = gpu[firstWrong];
int c = cpu[firstWrong];
std::printf(" first at (%d, %d): GPU %d, CPU %d", x, y, g, c);
}
std::printf("\n");
return wrong;
}
// FNV-1a hash of an image, to compare the outputs of 2 programs.
unsigned checksum(const std::vector<uint8_t>& data)
{
unsigned h = 2166136261u;
for (uint8_t byte : data) {
h = (h ^ byte) * 16777619u;
}
return h;
}
std::vector<uint8_t> download(const uint8_t* device)
{
std::vector<uint8_t> host(PIXELS);
check(cudaMemcpy(host.data(), device, PIXELS, cudaMemcpyDeviceToHost));
return host;
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
int sms = prop.multiProcessorCount;
std::printf("GPU: %s, %d SMs ", prop.name, sms);
std::printf("image %d x %d = %d pixels\n", W, H, PIXELS);
cudaStream_t streams[3];
for (cudaStream_t& s : streams) {
check(cudaStreamCreate(&s));
}
cudaStream_t s = streams[0];
std::vector<std::vector<uint8_t>> scenes;
std::vector<Images> reference;
for (unsigned seed = 0; seed < 4; ++seed) {
scenes.push_back(scene(seed));
reference.push_back(cpuPipeline(scenes.back()));
}
// 1. Each stage of 1 image, timed alone.
Buffers lanes[3] = {allocBuffers(), allocBuffers(), allocBuffers()};
Buffers& b = lanes[0];
check(cudaMemcpy(b.rgb, scenes[0].data(), 3 * PIXELS, cudaMemcpyHostToDevice));
double warm = nowMs();
while (nowMs() - warm < 400) {
timeMs(s, [&] { process(s, b); }); // raise the GPU clock
}
std::printf("stage ms GB/s\n");
double total = 0;
for (int k = 0; k < 7; ++k) {
double ms = timeMs(s, [&] { stage(s, b, k); });
double gb = double(STAGES[k].bytes) * PIXELS / 1e9 / (ms / 1e3);
std::printf(" %-13s %7.3f %7.1f\n", STAGES[k].name, ms, gb);
total += ms;
}
double all = timeMs(s, [&] { process(s, b); });
std::printf(" sum of stages %7.3f\n", total);
std::printf(" all 7 in turn %7.3f\n", all);
// 2. The GPU's images against the CPU's, pixel by pixel.
Images gpu;
gpu.gray = download(b.gray);
gpu.equal = download(b.equal);
gpu.blurred = download(b.blurred);
gpu.edges = download(b.edges);
const Images& cpu = reference[0];
std::printf("image pixels that differ from the CPU\n");
int wrong = report("gray", gpu.gray, cpu.gray);
wrong += report("equalised", gpu.equal, cpu.equal);
wrong += report("blurred", gpu.blurred, cpu.blurred);
wrong += report("edges", gpu.edges, cpu.edges);
std::printf("edge image checksum: %08x\n", checksum(gpu.edges));
// 3. The CPU on every core, 4 images.
double t0 = nowMs();
for (const std::vector<uint8_t>& rgb : scenes) {
cpuPipeline(rgb);
}
double cpuRate = scenes.size() / ((nowMs() - t0) / 1e3);
unsigned cores = std::thread::hardware_concurrency();
// 4. The copies alone, then a batch: copy in, 7 stages, copy out, on 1 to 3 streams.
uint8_t* inputs[4];
uint8_t* outputs[3];
for (int k = 0; k < 4; ++k) {
check(cudaMallocHost(&inputs[k], 3 * PIXELS));
std::memcpy(inputs[k], scenes[k].data(), 3 * PIXELS);
}
for (int k = 0; k < 3; ++k) {
check(cudaMallocHost(&outputs[k], PIXELS));
}
auto copyIn = [&] {
check(cudaMemcpyAsync(b.rgb, inputs[0], 3 * PIXELS, cudaMemcpyHostToDevice, s));
};
auto copyOut = [&] {
check(cudaMemcpyAsync(outputs[0], b.edges, PIXELS, cudaMemcpyDeviceToHost, s));
};
double inMs = timeMs(s, copyIn);
double outMs = timeMs(s, copyOut);
double inRate = 3.0 * PIXELS / 1e9 / (inMs / 1e3);
double outRate = 1.0 * PIXELS / 1e9 / (outMs / 1e3);
std::printf("copy in %6.3f ms %5.1f GB/s\n", inMs, inRate);
std::printf("copy out %6.3f ms %5.1f GB/s\n", outMs, outRate);
batch(streams, lanes, 3, inputs, outputs, BATCH);
std::printf("batch of %d images: copy in, 7 stages, copy out\n", BATCH);
bool correct = true;
for (int n = 1; n <= 3; ++n) {
double rate = batch(streams, lanes, n, inputs, outputs, BATCH);
std::printf(" %d stream(s) %6.1f images/s\n", n, rate);
for (int k = 0; k < n; ++k) {
int last = (BATCH - 1 - (BATCH - 1 - k) % n) % 4;
const uint8_t* expect = reference[last].edges.data();
correct = correct && std::memcmp(outputs[k], expect, PIXELS) == 0;
}
}
std::printf(" CPU, %u threads %6.1f images/s\n", cores, cpuRate);
bool passed = wrong == 0 && correct;
std::printf("batch outputs match the CPU: %s\n", correct ? "yes" : "no");
std::printf("%s\n", passed ? "PASSED" : "FAILED");
for (int k = 0; k < 4; ++k) {
cudaFreeHost(inputs[k]);
}
for (int k = 0; k < 3; ++k) {
cudaFreeHost(outputs[k]);
freeBuffers(lanes[k]);
}
for (cudaStream_t& st : streams) {
cudaStreamDestroy(st);
}
return passed ? 0 : 1;
}
Common mistakes
- Computing in floating point and comparing exactly. A floating-point expression may be evaluated differently on the GPU, for example with a fused multiply-add. Use integer arithmetic where the result must match exactly, or compare with a tolerance.
- Fixed-point weights that do not sum to the scale. Weights of 76, 150 and 29 sum to 255, and white becomes 254 (Section 24.3.3).
- Counting with a plain addition. 2 threads that count the same level can lose 1 of the 2 counts. Count with an atomic addition instead (Section 24.4.5).
- Rounding each pass of a separable filter. Theorem 24.1 holds only if the row pass keeps its sums whole and the rounding happens once at the end.
- Forgetting the halo of a tile. A tile of \(T\) outputs of a filter of radius \(r\) needs \(T + 2r\) inputs. The missing slots hold whatever the memory held before, and the result is wrong in a few columns only (Section 24.5.6).
- Leaving a global histogram uncleared. A histogram kernel adds to its counts. Here, the table kernel clears each count as it reads it.
- Reusing a pinned output buffer on 2 streams. 2 streams that copy into the same host buffer can do so in either order. Give each stream its own buffer, or synchronize before reusing it.
Summary
- The 4 stages of the pipeline are patterns of Part V: gray conversion and the table lookup are maps, equalization needs a histogram and a scan of 256 counts, and the blur and the Sobel detector are stencils.
- The worked example of 8 × 8 pixels goes from levels 96, 112, 120 and 144 to 0, 85, 170 and 255, to a blurred image in which pixel (3, 3) is 170, and to an edge image in which pixel (3, 1) is 60.
- Integer arithmetic, a correctly rounded square root and 1 rounding at the end of the blur make the GPU’s images equal to the CPU’s in every pixel, and the Rust and C++ programs equal to each other.
- A separable filter of \(k \times k\) weights costs \(2k\) multiply-adds instead of \(k^2\), and Theorem 24.1 proves the 2 passes exact.
- A tile for \(T\) outputs of radius \(r\) holds \(T + 2r\) inputs. Without the halo, 4 threads of each block read unwritten slots.
- On the measured GPU, the 7 kernels take 1.079 ms per image of 1,920 × 1,080 pixels in C++ and 1.380 ms in Rust. The blur takes the largest share, 39%, because it moves the most bytes, and every stage runs at 18 to 45 GB/s because its accesses are 1 or 2 bytes wide.
- On 3 streams, the copies hide completely behind the kernels: 859.5 images/s in C++ and 689.9 in Rust, against 37.7 to 51.0 images/s for the CPU version on 8 cores.
Exercises
- Carry an 8 × 8 image whose top 4 rows have level 100 and bottom 4 rows level 140 through the whole pipeline by hand: the equalized levels, the row sums, the blurred column 0, and the edge level of pixel \((0, 3)\).
- The grayscale and apply-table kernels cannot be fused into 1, because equalization needs the whole histogram first. Which other pairs of consecutive kernels could be fused, and how many bytes per pixel would each fusion save?
- Fuse the column pass of the blur and the Sobel kernel. What halo does the fused kernel need, and how many rows of row sums must its tile hold for a block of 8 output rows?
- Change the gray kernel to convert 4 pixels per thread, reading its 12 color bytes as 3 words of 4 bytes. Measure the effective bandwidth, and compare it with the 1-byte and 16-byte loads of Section 8.8.
- Replace the tiled row pass by a kernel that reads its 5 inputs directly from global memory, and measure the difference. Explain it with the L1 cache.
- Add
#[kernel(unchecked_indexing)]to 1 Rust kernel at a time and find which kernels gain most. - Write a 1-pass blur that copies a tile of \((8 + 4) \times (32 + 4)\) equalized pixels into shared memory and applies the 25 weights of Figure 24.7 directly. Count the bytes it moves per pixel and the multiply-adds it performs, measure it against the 2 passes, and explain the result with Section 24.9.2.
- Make the equalization table kernel work for images of 16-bit levels (65,536 bins). Which parts of Table-Kernel no longer fit in 1 block?
Sources and further reading
- ITU-R Recommendation BT.601, Studio encoding parameters of digital television for standard 4:3 and wide-screen 16:9 aspect ratios: the luma weights 0.299, 0.587 and 0.114.
- R. C. Gonzalez and R. E. Woods, Digital Image Processing, 4th ed., Pearson, 2018: histogram equalization, smoothing filters, separable filters and the Sobel operator (chapter 3).
- I. Sobel and G. Feldman, “A 3 × 3 isotropic gradient operator for image processing”, 1968, presented at the Stanford Artificial Intelligence Project.
- T. H. Cormen, C. E. Leiserson, R. L. Rivest and C. Stein, Introduction to Algorithms, 4th ed., MIT Press, 2022: the style of the pseudocode, and loop-invariant proofs.
- A. Pathak, An Introduction to Tiled Parallel Programming, Simplified, 2026: tiles, barriers and their proof on a worked example.
- IEEE 754-2019, Standard for Floating-Point Arithmetic: the correctly rounded square root.
- NVIDIA, CUDA C++ Programming Guide: shared memory, atomic functions, streams and asynchronous
copies, and
--use_fast_math. - cuda-oxide source, rev b7fe543:
SharedArray,DisjointSlicewithIndex2D,BlockAtomicU32,DeviceAtomicU32::swap,sqrt_rn_f32and#[kernel(unchecked_indexing)].
Chapter 25: Profiling, Debugging & Performance Engineering
Every performance claim in the earlier chapters rested on a measurement. We timed kernels with CUDA events, counted wrong elements, and compared results with a reference computed on the CPU. Recall that a CUDA event is a marker that a program places in a stream of GPU work; the GPU writes the time at which it reaches the marker, so the difference between 2 events is the time of the work issued between them. Each of these measurements answers a single question about a single run. When a program is slower than expected, or produces a wrong answer only some of the time, we need tools that tell us more: a record of what the GPU did and when, the counts that the hardware keeps for each kernel, a checker that inspects every memory access, and a clock that a thread can read from inside a kernel.
In this chapter, we introduce these tools and apply each of them to a program from an earlier chapter: the stream pipeline of Chapter 6, the matrix multiplication of Chapter 9, the vector addition of Chapter 3 and the block sum of Chapter 5. We use an in-kernel clock to measure the latencies that we assumed in Chapter 1, about 4 cycles for an arithmetic operation and several hundred cycles for a read from memory. A cycle is 1 period of the clock that drives the GPU’s processors: at a clock rate of 1 GHz, a cycle lasts 1 ns. We then turn to the question of whether a measurement or a test result can be trusted, and we close with the procedure that connects all of these tools: measure, explain, change one thing, and measure again.
This chapter covers
- profilers, traces and hardware performance counters
- reading an Nsight Systems timeline and accounting for its run time
- the sections of an Nsight Compute report, and a speed-of-light analysis done by hand
- finding out-of-bounds accesses, races, barrier errors and uninitialized reads with Compute Sanitizer
- stopping a single GPU thread with
cuda-gdb - measuring latencies in cycles with
clock64(), in C++ and in Rust - warm-up, medians and a protocol for timing kernels
- units in the last place, tolerances for sums, and known-answer tests
- a systematic process for performance work
The code of the chapter is in
code/ch16_profiling/
for C++ and in
code/oxide/ch16_latency/
for Rust. The measurements in this chapter come from 2 integrated GPUs: a Jetson Orin NX (8 SMs,
102 GB/s), the first GPU below, and a Jetson AGX Thor (20 SMs, 273 GB/s), the second. An
integrated GPU is built on the same chip as the CPU and uses the same memory. An SM, or
streaming multiprocessor, is one of the processors of the GPU, and the rate in GB/s is the peak
rate at which the GPU can move data to and from its memory.
25.1 Tools for performance and correctness
25.1.1 Profilers, traces and counters
Consider a program that copies an array to the GPU, runs 1 kernel on it, and copies the result back, and suppose that the whole run takes 20 ms. A clock read before and after the run tells us only the 20 ms. To make the program faster, we need 2 further pieces of information. The first is how the 20 ms divide among the 3 steps. If the 2 copies take 15 ms and the kernel 5 ms, no change to the kernel can save more than 5 ms. The second, once we know that the kernel matters, is what the kernel did during its time: whether it was reading memory, computing, or waiting. A profiler is a program that records what another program does while it runs, and on a GPU the 2 questions are answered by two kinds of record.
Definition 25.1 Trace and hardware performance counter. A trace is a list of timestamped events, each with a start time and an end time. A hardware performance counter is a register inside the GPU that counts events of one kind while a kernel runs.
Example. The trace of section 25.2 records a copy that started at 0.665 ms and ended at 1.470 ms, and a kernel that ran from 1.978 ms to 3.311 ms. A counter of bytes read from DRAM would read 268,435,456 after a kernel that reads 256 MiB once.
Here DRAM is the GPU’s main memory, the large memory outside the processors; on an integrated GPU it is the same memory that the CPU uses. Recall that a warp is a group of 32 threads that execute each instruction together. Besides bytes read from DRAM, counters record quantities such as the number of instructions issued and the number of cycles in which a warp could not proceed. A trace tells us where the time of a whole program went. Counters tell us why a particular kernel took the time it did.
NVIDIA provides 1 profiler for each kind of record. Nsight Systems, run as nsys, traces the
whole program: the CUDA calls made by the CPU and the copies and kernels executed by the GPU, all
on a common time axis. Nsight Compute, run as ncu, reads the counters of 1 kernel at a time.
A GPU has fewer counter registers than there are kinds of events to count. For example, if a GPU
had 4 counter registers and we asked for 12 kinds of events, the 12 could not be counted in 1
run; they would need 3 runs of 4 kinds each. Therefore, ncu runs the same kernel several times,
counts a different set of events in each run, and restores the kernel’s memory before each run,
so that every run starts from the same data. This repetition is called replay. Replay makes
ncu slow, and it is the reason why the kernel times reported by ncu differ from those of an
ordinary run.
Profilers do not check whether a program is correct. For correctness, the CUDA toolkit provides 2 other tools. Compute Sanitizer adds checks to every memory access of a kernel while it runs, and to every barrier, a point in a kernel at which the threads of a block wait for each other. cuda-gdb is a debugger: a program that controls another program, stops it at chosen points called breakpoints, and shows its state. cuda-gdb can stop a kernel at a source line and show the variables of any one of its threads. Figure 25.1 pairs each question that we ask in this chapter with the tool that answers it.
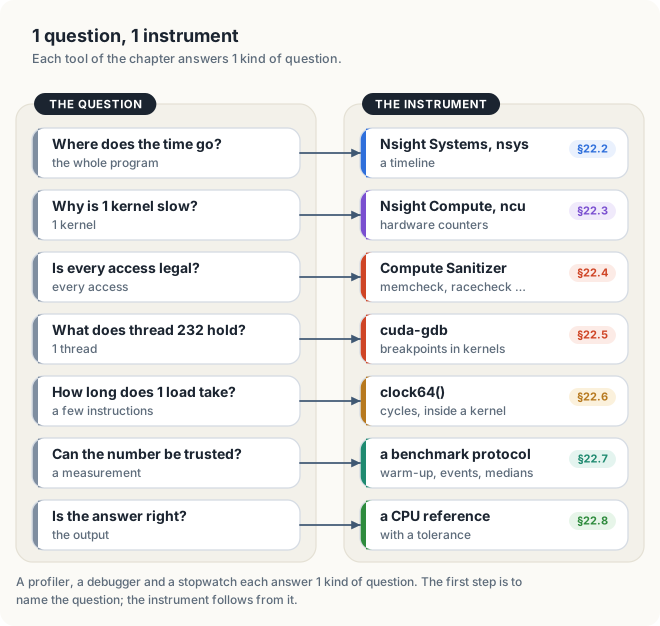
25.1.2 Which tool to use first
The order in which we apply these tools follows from Amdahl’s law (Chapter 1, section 1.3). Amdahl’s law states that if a fraction \(p\) of a run is made \(s\) times faster, the run takes \((1 - p) + p / s\) of its original time. Making a kernel faster can only shorten the part of the run during which that kernel executes. Take the run of 20 ms of section 25.1.1, in which the copies take 15 ms and the kernel 5 ms, so \(p\) = 5 / 20 = 0.25. A kernel twice as fast, \(s = 2\), gives a run of 15 + 5 / 2 = 17.5 ms. A kernel 10 times as fast gives 15 + 0.5 = 15.5 ms, and even an infinitely fast kernel leaves the 15 ms of copies.
Key observation A change to 1 part of a run can save at most the time that part takes. Before we speed up any part, we must know how long each part takes.
The pipeline of Chapter 6, a program that copies data in, processes it with a kernel and copies it out, shows the same effect on measured times. Its 1-stream version, which we trace in section 25.2, takes 20.95 ms: 6.18 ms of copy in, 10.40 ms of kernel and 4.19 ms of copy out, executed one after another. If we made the kernel twice as fast, it would take 10.40 / 2 = 5.20 ms, and the run would take 20.95 − 5.20 = 15.75 ms. Overlapping the copies with the kernel instead, using 2 streams and 8 chunks, brought the run down to 13.59 ms without changing the kernel at all.
The timeline showed where the time went before any kernel was tuned, and it pointed to the larger gain. For this reason, we start with Nsight Systems, and we turn to Nsight Compute only once the timeline shows that a kernel dominates the run.
25.1.3 Access permissions for counters and debuggers
Hardware counters and debugger control are restricted on most systems. In 2018, researchers showed that a program could learn about the work of another program from the GPU’s performance counters. An attack of this kind, in which 1 program infers another program’s data from a shared resource instead of reading the data itself, is called a side channel. The vulnerability was registered as CVE-2018-6260; a CVE number is the identifier under which a published security vulnerability is listed. Since then, NVIDIA’s drivers have allowed only administrators to read the counters, unless the owner of the machine changes a driver option. Debugging is restricted for a similar reason: a debugger can read any memory of the program it controls. The table below lists what each tool needs.
| Tool | Needs |
|---|---|
nsys (trace) | no special rights |
ncu (counters) | counter access: an administrator, or the driver option below |
compute-sanitizer | debugger access |
cuda-gdb | debugger access |
On a machine that we administer, sudo ncu ... reads the counters. A desktop Linux system can
allow every user to read them with the driver option NVreg_RestrictProfilingToAdminUsers=0, set
in a file under /etc/modprobe.d/; NVIDIA’s page for ERR_NVGPUCTRPERM gives the steps for each
operating system. Here sudo runs 1 command with administrator rights, and a driver option
is a setting that the GPU driver reads when the operating system loads it. On Jetson modules,
counter and debugger access go through 2 device files, special files under /dev through
which a program talks to a driver: /dev/nvhost-prof-gpu and /dev/nvhost-dbg-gpu. Like any
file, a device file has an owner and a group, a named set of users who share its permissions.
Both files belong to the group debug, so the tools must be run with sudo or by a member of
that group.
25.2 Timelines with Nsight Systems
25.2.1 Recording a trace
Recall from Chapter 6 that a stream is a queue of GPU work whose operations run in the order in
which they were issued, and that work in different streams may overlap. Chapter 6’s program
streams performs the same work in three ways: copy in, kernel and copy out on 1 stream; the same in 8
chunks on 2 streams; and the same in 32 chunks. A chunk is 1 of the equal pieces into which
the data is split, so that the copy of 1 chunk can run while the kernel works on another. We can
trace the program without changing a line of code:
$ nsys profile -t cuda -o streams ./streams
$ nsys stats --report cuda_gpu_kern_sum,cuda_gpu_mem_time_sum streams.nsys-rep
The option -t cuda records CUDA calls, copies and kernels, and -o names the report file. The
command nsys stats prints summaries of the report as tables. The first summary lists every
kernel (the columns Min, Max and StdDev are omitted here):
Time (%) Total Time (ns) Instances Avg (ns) Med (ns) Name
99.5 297,936,832 248 1,201,358.2 336,896.0 work(float *, int, int)
0.5 1,368,576 1,001 1,367.2 1,376.0 empty()
A summary is useful only if we can account for its numbers. Before it measures, the program
warms up: it runs the work a few times without timing it, for reasons that we explain in
section 25.7.1. It launches work 40 times while it warms up, in 5 runs of 8 chunks. It launches the kernel twice to time a single launch, and
once to time the 3 stages separately. Then come 5 runs of 1 chunk, 5 runs of 8 chunks and 5 runs of
32 chunks. In total, this gives 40 + 2 + 1 + 5 + 40 + 160 = 248 launches, which is the number in the
table. The median time, 0.34 ms, is that of the kernel on 1 chunk of 32, because 160 of the 248
launches are of that size.
25.2.2 Accounting for the run time
The report also holds the start and end time of every copy and kernel. Figure 25.2 draws 2 repetitions from it on a common scale: the last run of the 1-stream pipeline and the first run of the 2-stream pipeline with 8 chunks.
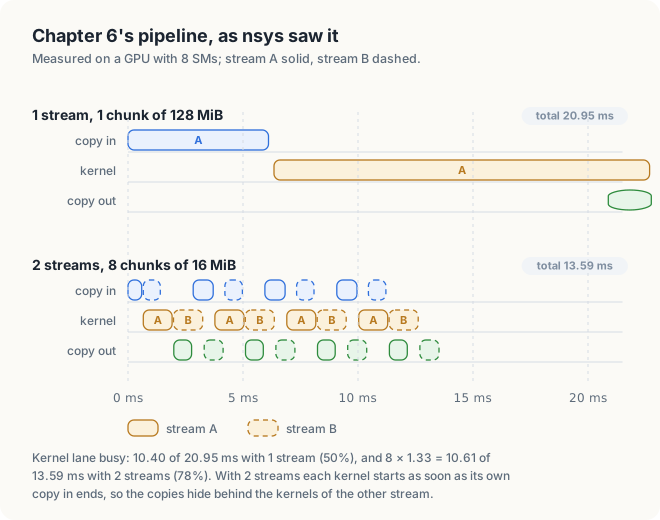
We say that a lane of the timeline is busy while it executes an operation. The fraction of the run during which the kernel lane is busy measures how well the pipeline keeps the arithmetic units supplied with work. With 1 stream, the kernel lane is busy for 10.40 ms of 20.95 ms, or 50% of the run. With 2 streams, the 8 kernels take 1.32 to 1.33 ms each, 10.61 ms in total, out of 13.59 ms, or 78% of the run.
We can go further and account for every millisecond of the 2-stream run. To see how, let us first work a smaller case by hand. Suppose that the data is split into 2 chunks, and that for each chunk the copy in takes 1 ms, the kernel 2 ms and the copy out 1 ms. On 1 stream, the 6 operations run one after another, and the run takes 2 × (1 + 2 + 1) = 8 ms. On 2 streams, chunk 0 goes to stream A and chunk 1 to stream B, and operations of different streams may overlap:
| Time (ms) | Copy-in lane | Kernel lane | Copy-out lane |
|---|---|---|---|
| 0 to 1 | chunk 0 | idle | idle |
| 1 to 2 | chunk 1 | chunk 0 | idle |
| 2 to 3 | idle | chunk 0 | idle |
| 3 to 4 | idle | chunk 1 | chunk 0 |
| 4 to 5 | idle | chunk 1 | idle |
| 5 to 6 | idle | idle | chunk 1 |
The run takes 6 ms. The kernel lane is busy for 4 of the 6 ms, and the two kernels run back to back, from 1 ms to 5 ms. The run is therefore made of three parts: the first copy in, 1 ms; the kernels, 2 + 2 = 4 ms; and the last copy out, 1 ms. The copies of the other chunk are hidden behind the kernels.
Key observation When the kernels of a pipeline run back to back, the run lasts as long as the first copy in, plus all the kernels, plus the last copy out. Any further time is a gap in the kernel lane, and each gap has a cause that the trace can show.
The 2-stream run of Figure 25.2 can be accounted for in the same way.
Worked example: accounting for the 2-stream run
- The run cannot be shorter than the first copy in, 0.66 ms, followed by the 8 kernels back to back, 10.61 ms, followed by the last copy out, 0.90 ms: 12.17 ms in total.
- The trace shows 3 gaps in the kernel lane, before kernels 3, 5 and 7, of 0.47 ms, 0.48 ms and 0.48 ms: 1.42 ms in total.
- 12.17 ms + 1.42 ms = 13.59 ms, which is the measured run.
The 3 gaps have a single cause. A stream executes its operations in the order in which they were issued. The chunks alternate between the streams, so stream A receives chunks 0, 2, 4 and 6, and its queue holds copy in 0, kernel 0, copy out 0, copy in 2, kernel 2, copy out 2, and so on. Stream A therefore holds the copy out of chunk 0 before the copy in of chunk 2, so chunk 2 cannot start copying until the result of chunk 0 has left the GPU, at 2.83 ms. Its copy then takes 0.94 ms, and kernel 3 starts at 3.78 ms, although the kernel lane has been idle since 3.31 ms. Exercise 2 asks the reader to remove these gaps.
Tracing a program can change its timing, because the profiler does work of its own to record each event. The program also times the same pipeline itself, without the profiler, and printed 13.08 ms, 13.31 ms and 13.34 ms in 3 runs. The traced run, 13.59 ms, is within 4% of those times, so the trace describes the program as it normally runs.
25.2.3 Common timeline patterns
Most performance problems of a GPU program are visible on a timeline. The table below lists the common patterns, their likely causes, and the chapters in which we treat them. Four terms in it come from earlier chapters. Pageable memory is ordinary host memory, which the operating system may move, and pinned memory is host memory locked in place, so that the GPU can copy it directly (Chapter 4). The launch cost is the CPU time that 1 kernel launch takes before it returns. A CUDA graph records a sequence of launches once and then issues the whole sequence with 1 call.
| What the timeline shows | Likely cause | Remedy |
|---|---|---|
| kernel lane idle while a copy runs, and the reverse | 1 stream, or copies from pageable memory | streams and pinned memory (Chapters 4 and 6) |
| short gaps between many tiny kernels | the CPU’s launch cost, a few µs per launch | CUDA graphs (section 6.7) |
long CPU calls such as cudaMalloc between kernels | allocation inside the loop | allocate once, before the loop |
| kernel lane busy nearly all the time | the kernels themselves | Nsight Compute (section 25.3) |
25.2.4 Tracing a Rust program
nsys traces any program that uses the CUDA driver, regardless of the language in which it was
written. For the Rust program of section 25.6, it prints the Rust names of the kernels:
$ nsys profile -t cuda -o rust ./target/release/ch16_latency
$ nsys stats --report cuda_gpu_kern_sum rust.nsys-rep
Time (%) Total Time (ns) Instances Avg (ns) Med (ns) Name
99.5 19,164,896 3 6,388,298.7 8,258,176.0 chase
0.3 63,680 1 63,680.0 63,680.0 dependent_fma
0.1 23,680 1 23,680.0 23,680.0 independent_fma
The summary of CPU calls shows cuLaunchKernel and cuModuleLoadData where the C++ program shows
cudaLaunchKernel. CUDA offers 2 sets of host functions. The runtime API is the set whose
names begin with cuda, such as cudaMalloc and cudaLaunchKernel. The driver API is a
lower-level set whose names begin with cu, such as cuLaunchKernel, and cuModuleLoadData
loads the compiled code of the kernels onto the GPU. cuda-oxide calls the driver API directly,
whereas the C++ programs call the runtime API, which in turn calls the driver (Chapter 12).
25.3 Kernel analysis with Nsight Compute
25.3.1 Sections of a kernel report
ncu organizes its counters into sections, named groups of related counters with the
quantities computed from them, and 3 of them answer most questions.
The speed of light of a hardware unit is its peak rate. The SpeedOfLight section reports how
close the kernel came to the peak rate of the arithmetic units and to that of the memory system, as
percentages. A kernel that comes close to 100% for one of these units is limited by that unit, as
the roofline model of Chapter 1 predicts. Recall that the roofline model bounds the rate of a
kernel by the smaller of two limits: the peak arithmetic rate, and the memory bandwidth multiplied by
the number of operations the kernel performs per byte it moves. In Section 25.3.3, we compute these
percentages by hand.
The Occupancy section reports how fully the kernel uses the SMs. Recall that an SM runs
blocks, groups of up to 1,024 threads that share its fast shared memory, and that it keeps
the warps of several blocks resident at once: their registers stay on the SM, so the SM can
switch from 1 warp to another in any cycle. When 1 warp waits for a load, the SM issues an
instruction of another warp. The more warps are resident, the more likely it is that some warp is
ready to issue.
Definition 25.2 Occupancy. The occupancy of a kernel is the number of warps resident on an SM divided by the maximum number of warps the SM can hold (Chapter 2, section 2.9).
Example. An SM of either GPU of this chapter holds at most 1,536 threads, which is 1,536 / 32 = 48 warps. A kernel of which 3 blocks of 256 threads fit on 1 SM keeps 3 × 8 = 24 warps resident, and its occupancy is 24 / 48 = 50%.
The theoretical occupancy follows from the kernel’s registers, its shared memory and its block size, because these determine how many blocks fit on 1 SM at once. The achieved occupancy is the average measured while the kernel ran. It is lower than the theoretical occupancy when blocks finish unevenly, so that for part of the run an SM holds fewer blocks than it could.
The WarpStateStats section reports stalls. A stall is a cycle in which a warp could not issue
its next instruction. Global memory is the memory in DRAM that every thread of a kernel can
reach. The section counts stalls by reason, such as waiting for a load from global memory
(long_scoreboard), waiting for shared memory (short_scoreboard), or waiting at a barrier
(barrier). The scoreboard is the table in which the SM tracks which registers still wait for
the result of an earlier instruction. Loads from global memory take hundreds of cycles and are
tracked on the long scoreboard; loads from shared memory, which are much faster, are tracked on
the short one.
For Chapter 9’s kernel with 4 × 4 patches, on a machine where counters are allowed, the command is
$ sudo ncu --section SpeedOfLight --section Occupancy -k regex:patches -c 1 ./sgemm
The option --section chooses the sections to collect, and adding --section WarpStateStats
adds the stall reasons. The option -k selects kernels by name; regex:patches selects every
kernel whose name contains the text patches. The option -c 1 profiles only the first launch
that matches. Without counter access, ncu stops before the kernel runs and names the
setting described in section 25.1.3:
==ERROR== ERR_NVGPUCTRPERM - The user does not have permission to access NVIDIA GPU
Performance Counters on the target device 0.
25.3.2 Peak rates from device attributes
Several numbers of the report can be computed without counters, from the limits that the GPU
reports and a kernel time measured with events. The CUDA runtime describes the GPU in a
cudaDeviceProp structure, with 1 field for each property, and cudaDeviceGetAttribute returns
single values. Listing 25.1 prints the limits that we use in the rest of the chapter, and the 2 peak
rates they imply.
Before we read the output, let us see how a peak rate follows from such limits, on a small GPU
that we invent for the purpose. FP32 is the 32-bit floating-point format, the type float. A
FLOP is 1 floating-point operation, and a multiply-add \(a \times b + c\), which the
hardware performs as 1 instruction, counts as 2 FLOP. Suppose that our GPU has 2 SMs, that each SM
has 4 FP32 units, and that each unit completes 1 multiply-add per cycle at a clock of 1 GHz. In
each cycle the GPU then completes 2 × 4 = 8 multiply-adds, or 16 FLOP, and in 1 s it completes 16
× 109 FLOP: its peak is 16 GFLOP/s. The memory side works the same way. The memory
bus is the set of wires between the GPU and DRAM, and its width is the number of bits that cross
it in 1 transfer. The memory of these GPUs makes 2 transfers per cycle of its own clock, the
memory clock. A bus of 64 bits carries 8 bytes per transfer, so at a memory clock of 1 GHz it
moves 2 × 8 bytes × 109 = 16 GB/s.
Listing 25.1 The limits of the GPU, and the peaks they imply. code/ch16_profiling/measure.cu
/// Asks the driver for 1 integer attribute of `device`.
fn attribute(device: CUdevice, which: CUdevice_attribute) -> Result<i32, DriverError> {
let mut value = 0;
// SAFETY: `value` is a valid place for 1 integer; `device` came from a live context.
unsafe { cuDeviceGetAttribute(&mut value, which, device).result()? };
Ok(value)
}
/// Print the limits the GPU reports, and the peaks they imply.
fn limits(ctx: &CudaContext) -> Result<(), DriverError> {
let device = ctx.cu_device();
let (major, minor) = ctx.compute_capability()?;
let sms = ctx.multiprocessor_count()?;
let sm_clock_khz = attribute(device, SM_CLOCK)?;
let mem_clock_khz = attribute(device, MEM_CLOCK)?;
let bus_bits = attribute(device, BUS_BITS)?;
let shared_kib = attribute(device, SHM)? / 1024;
let l2_kib = attribute(device, L2_BYTES)? / 1024;
let registers = attribute(device, REGS)?;
let max_threads = ctx.max_threads_per_multiprocessor()?;
let name = ctx.device_name()?;
println!("{name}, compute capability {major}.{minor}");
println!(" SMs {sms:8}");
println!(" threads per SM, at most {max_threads:8}");
println!(" registers per SM {registers:8}");
println!(" shared memory per SM {shared_kib:8} KiB");
println!(" L2 cache {l2_kib:8} KiB");
println!(" SM clock {:8} MHz", sm_clock_khz / 1000);
println!(" memory clock {:8} MHz", mem_clock_khz / 1000);
println!(" memory bus {bus_bits:8} bits");
// 128 FP32 units per SM from compute capability 8.6; 2 FLOP per multiply-add.
let peak_gflops = sms as f64 * 128.0 * 2.0 * sm_clock_khz as f64 / 1e6;
// 2 transfers per memory clock (double data rate) of bus_bits / 8 bytes each.
let peak_gbs = 2.0 * mem_clock_khz as f64 * 1e3 * (bus_bits / 8) as f64 / 1e9;
println!(" FP32 peak from the clock {peak_gflops:8.0} GFLOP/s");
println!(" bandwidth from the clock {peak_gbs:8.1} GB/s");
Ok(())
}// Print the limits the GPU reports, and the peaks they imply.
void limits()
{
cudaDeviceProp p;
check(cudaGetDeviceProperties(&p, 0));
int smClockKHz = attribute(cudaDevAttrClockRate);
int memClockKHz = attribute(cudaDevAttrMemoryClockRate);
int busBits = attribute(cudaDevAttrGlobalMemoryBusWidth);
size_t sharedKiB = p.sharedMemPerMultiprocessor / 1024;
std::printf("%s, compute capability %d.%d\n", p.name, p.major, p.minor);
std::printf(" SMs %8d\n", p.multiProcessorCount);
std::printf(" threads per SM, at most %8d\n", p.maxThreadsPerMultiProcessor);
std::printf(" registers per SM %8d\n", p.regsPerMultiprocessor);
std::printf(" shared memory per SM %8zu KiB\n", sharedKiB);
std::printf(" L2 cache %8d KiB\n", p.l2CacheSize / 1024);
std::printf(" SM clock %8d MHz\n", smClockKHz / 1000);
std::printf(" memory clock %8d MHz\n", memClockKHz / 1000);
std::printf(" memory bus %8d bits\n", busBits);
// 128 FP32 units per SM from compute capability 8.6; 2 FLOP per multiply-add.
double peakGflops = p.multiProcessorCount * 128 * 2.0 * smClockKHz / 1e6;
// 2 transfers per memory clock (double data rate) of busBits / 8 bytes each.
double peakGBs = 2.0 * memClockKHz * 1e3 * (busBits / 8) / 1e9;
std::printf(" FP32 peak from the clock %8.0f GFLOP/s\n", peakGflops);
std::printf(" bandwidth from the clock %8.1f GB/s\n", peakGBs);
}
Orin, compute capability 8.7 NVIDIA Thor, compute capability 11.0
SMs 8 SMs 20
threads per SM, at most 1536 threads per SM, at most 1536
registers per SM 65536 registers per SM 65536
shared memory per SM 164 KiB shared memory per SM 228 KiB
L2 cache 2048 KiB L2 cache 32768 KiB
SM clock 1173 MHz SM clock 1048 MHz
memory clock 1173 MHz memory clock 4266 MHz
memory bus 256 bits memory bus 256 bits
FP32 peak from the clock 2402 GFLOP/s FP32 peak from the clock 5369 GFLOP/s
bandwidth from the clock 75.1 GB/s bandwidth from the clock 273.0 GB/s
The output of the 2 GPUs is printed side by side. Each line is a limit that we used in an earlier chapter. The number of SMs and the maximum number of threads per SM determine how many warps can be resident (Chapter 2). The number of registers per SM determined the occupancy of Chapter 9’s kernels. The L2 cache is a memory on the GPU chip, shared by all SMs, that keeps recently used data; each SM also has a smaller L1 cache of its own. The size of the L2 cache determines how large the data of a test must be for the test to measure memory rather than the cache (section 25.7).
The 2 peak rates require care. The FP32 peak is computed as for the small GPU above: the number of SMs × 128 FP32 units × 2 FLOP per multiply-add × the clock rate. For the first GPU, this gives 8 × 128 × 2 × 1.173 GHz = 2,402 GFLOP/s, which agrees with NVIDIA’s figure of 2.4 TFLOP/s, given in the GPU’s data sheet, the specification that the manufacturer publishes. The memory peak is 2 transfers per memory clock × the bus width in bytes. For the second GPU, this gives 2 × 4.266 GHz × 32 bytes = 273.0 GB/s, which agrees with NVIDIA’s figure. The other 2 results, however, are wrong. The first GPU reports its SM clock as the memory clock and a bus of 256 bits where its data sheet gives 128 bits, so the product, 75.1 GB/s, falls below the 102 GB/s of the data sheet. The second GPU reports 1,048 MHz as its SM clock, while its data-sheet peak of 8.1 TFLOP/s implies 8,100 / (20 × 128 × 2) = 1.58 GHz. A peak rate computed from reported attributes is therefore only a starting point, and the data sheet is the reference. In this chapter, we use the data-sheet peaks of Chapter 2: 2.4 TFLOP/s and 102 GB/s for the first GPU, and 8.1 TFLOP/s and 273 GB/s for the second.
25.3.3 Speed-of-light analysis without counters
Let us begin with a kernel small enough to count by hand: y = 2 x over 4 floats. Each thread
reads 1 element of x, 4 bytes, multiplies it by 2, and writes 1 element of y, 4 more bytes.
The 4 threads together move 4 × 8 = 32 bytes and perform 4 FLOP. Whatever the length of the
arrays, the kernel performs 1 FLOP for every 8 bytes it moves. Now suppose that the kernel ran on
the small GPU of section 25.3.2, with 16 GFLOP/s and 16 GB/s, and that it moved 16 GB in 2 s. Its
memory rate would be 16 GB / 2 s = 8 GB/s, half of the memory peak. In the same 2 s it would
perform 16 GB / 8 bytes = 2 × 10⁹ FLOP, a rate of 1 GFLOP/s, or 1 / 16 = 6% of the
arithmetic peak. The memory system would be far busier than the arithmetic units, and the kernel’s
time would be limited by memory.
Definition 25.3 Speed of light, arithmetic intensity and ridge point. The speed-of-light percentage of a kernel for 1 unit is the rate that the kernel achieved on that unit divided by the unit’s peak rate. The arithmetic intensity of a kernel is the number of FLOP it performs per byte it moves. The ridge point of a GPU is its arithmetic peak divided by its memory bandwidth. A kernel whose arithmetic intensity lies below the ridge point is memory-bound: its time is limited by the memory bandwidth.
Example. y = 2 x has an arithmetic intensity of 1 FLOP / 8 bytes = 0.125 FLOP/B. The first
GPU has a ridge point of 2,400 GFLOP/s / 102 GB/s ≈ 24 FLOP/B, so y = 2 x is memory-bound on it.
For memory, the achieved rate is the number of bytes the kernel moves divided by its time. For
arithmetic, it is the number of operations divided by the time. The program measure.cu times the
kernel y = 2 x over 2 arrays of 256 MiB each, which is larger than the L2 cache of either GPU;
we explain in section 25.7 how the time was taken.
On the first GPU, the median time of the kernel is 8.35 ms. Each of the 67,108,864 elements is read once and written once, so the kernel moves 2 × 4 bytes per element, 536,870,912 bytes or 512 MiB in total. The achieved memory rate is therefore 536,870,912 bytes / 8.35 ms = 64.3 GB/s, which is 64.3 / 102 = 63% of the peak. The kernel performs 1 multiplication per element, 67,108,864 FLOP in total, so its arithmetic rate is 67,108,864 FLOP / 8.35 ms = 8.0 GFLOP/s, or 8.0 / 2,400 = 0.33% of the peak. The kernel is memory-bound: its arithmetic intensity, 1 FLOP per 8 bytes or 0.125 FLOP/B, lies far below the GPU’s ridge point of 24 FLOP/B (Chapter 2, section 2.1.5).
Let us now apply the same analysis to Chapter 9’s best kernel, in which each thread computes a 4 × 4 patch of \(C\). The kernel ran at 901.4 GFLOP/s on the first GPU, which is 901.4 / 2,400 = 38% of the arithmetic peak. Its memory side requires a count of the loads. Recall that a tile is a rectangular piece of a matrix that a block copies into shared memory and uses many times. Each block of 256 threads computes a 64 × 64 tile of \(C\). At each of its 4,096 / 16 = 256 steps, the block loads a 64 × 16 tile of \(A\) and a 16 × 64 tile of \(B\), 2,048 floats in total. Over the whole run, a block therefore loads 256 × 2,048 × 4 bytes = 2 MiB, and the 4,096 blocks load 8 GiB, or 8,589,934,592 bytes, in 152.47 ms. This is a load rate of 56.3 GB/s.
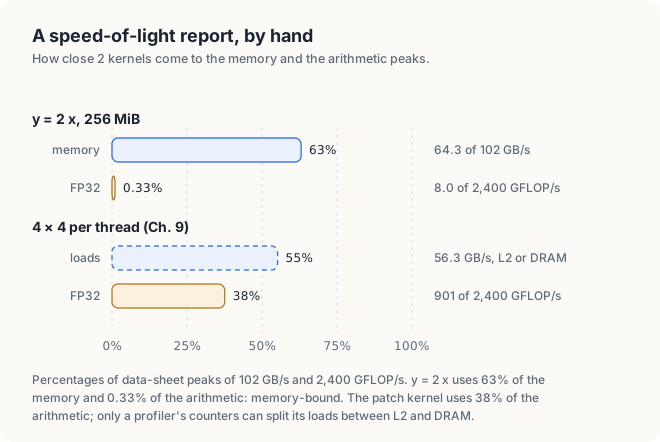
Figure 25.3 draws both results. The second one shows the limit of an analysis done by hand. The
56.3 GB/s of loads are served by the L2 cache or by DRAM, and the program cannot tell which. Tiles
that several blocks need may stay in the 2 MiB L2 cache between their uses. If all loads came from
DRAM, the kernel would use 55% of the memory peak; if most came from L2, it would use much less.
ncu reads this split from counters (dram__bytes and the L2 hit rate) and reports it directly.
The achieved occupancy and the stall reasons are likewise available only from counters.
The theoretical occupancy, on the other hand, can be computed without counters. The CUDA function
cudaOccupancyMaxActiveBlocksPerMultiprocessor, which we mentioned in Chapter 2, returns how many
blocks of a given size fit on 1 SM, given the registers and shared memory of the kernel.
Listing 25.2 The theoretical occupancy of scale.
fn main() -> Result<(), Error> {
// ...
let scale = module.prepare_scale(LaunchConfig1D::new(1, 256, 0))?;
let blocks = scale.function().max_active_blocks_per_multiprocessor(256, 0)?;
println!("blocks of 256 per SM {blocks:7} = {} threads", blocks * 256);
// ...
}int main()
{
// ...
int blocks;
check(cudaOccupancyMaxActiveBlocksPerMultiprocessor(&blocks, scale, 256, 0));
std::printf("blocks of 256 per SM %7d = %d threads\n", blocks, blocks * 256);
// ...
}
blocks of 256 per SM 6 = 1536 threads
Six blocks of 256 threads are 1,536 threads, or 48 warps, which is the limit of an SM on both GPUs. The theoretical occupancy of the kernel is therefore 48 / 48 = 100%.
25.4 Compute Sanitizer
25.4.1 Bugs that produce no error
The most dangerous bugs of a GPU program produce no error message. An allocation is a range of
memory returned by a single call such as cudaMalloc. A kernel that writes past the end of an array
usually writes into memory that belongs to no allocation, or to another array of the same program.
The hardware raises no fault, the error by which a processor stops an illegal access, and the
launch reports success.
Compute Sanitizer finds such bugs by instrumentation: it rewrites the kernel so that every
load, store and barrier first calls a check, and then runs the rewritten kernel. For example, the
statement c[i] = a[i] + b[i] contains 2 loads and 1 store. In the rewritten kernel, each of the 3
accesses is preceded by a call that looks up the address in the table of the program’s
allocations and reports an error if the 4 bytes at that address do not lie inside one of them. A
kernel with 3 accesses per thread thus makes 3 additional calls per thread, each far more costly
than the access it checks.
Two more terms appear in the table of checkers. An access is misaligned when its address is
not a multiple of its size, such as a 4-byte load from address 6. A race is a pair of
accesses to the same location by different threads, at least one of them a write, with nothing
that orders them; we work an example in section 25.4.3. The tool has 4 checkers, selected with the
option --tool:
| Checker | Finds |
|---|---|
memcheck (the default) | loads and stores outside any allocation, misaligned accesses, errors from CUDA calls |
racecheck | 2 accesses to the same shared-memory location, at least one of them a write, with no barrier between them |
synccheck | barriers used in ways the hardware does not define |
initcheck | loads of global memory that nothing has written |
The program bugs.cu contains 1 bug for each checker, each taken from an earlier chapter. We build
it with -lineinfo, which records for each instruction the source line it came from, so that the
checkers can report line numbers:
$ nvcc -arch=native -lineinfo bugs.cu -o bugs
$ ./bugs bounds; ./bugs race; ./bugs barrier; ./bugs uninit # second GPU
1,024 threads for 1,000 elements: 0 wrong elements
64 blocks of 256 ones: 64 wrong block sums
2 barriers, 1 per branch: 0 wrong elements of 256
sum of 1,024 floats nobody wrote: 0
The exit status of a program is the number it returns to the shell when it ends, and 0 means success. On the second GPU, all 4 runs exit with status 0, and 3 of the 4 print a result that looks correct. The first GPU printed the same lines for 3 of the bugs; in section 25.4.4 we describe what it did with the fourth.
25.4.2 Out-of-bounds accesses (memcheck)
Recall from Chapter 3 that we round the number of threads up to a whole number of blocks, and that
the kernel needs a guard, if (i < n), so that the extra threads do nothing. Consider a small
case first: 10 elements and blocks of 4 threads. Two blocks give only 8 threads, so we launch 3
blocks, 12 threads. Thread \(t\) of block \(b\) handles element \(i = 4b + t\), and the last
block covers \(i\) = 8, 9, 10 and 11. Elements 10 and 11 do not exist, so without the guard
threads 2 and 3 of block 2 read and write the 2 positions immediately past the end of each array.
Listing 25.3 leaves the guard out.
Listing 25.3 Vector addition without its guard. code/ch16_profiling/bugs.cu
mod kernels {
// ...
/// 1. Chapter 3's vector addition without its guard `if let Some(..)`.
#[cfg(feature = "no_guard")]
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn add_no_guard(a: &[f32], b: &[f32], mut c: DisjointSlice<f32>) {
let i = thread::index_1d();
let k = i.get();
*c.get_mut(i) = a[k] + b[k];
}
// ...
}In Rust, get_mut returns an Option, which is None for an index past the end of c, so the
guard cannot be left out, and the compiler rejects the kernel:
$ cargo oxide build --features no_guard
error[E0614]: type `Option<&mut f32>` cannot be dereferenced
--> src/main.rs:25:9
|
25 | *c.get_mut(i) = a[k] + b[k];
| ^^^^^^^^^^^^^ can't be dereferenced
// 1. Chapter 3's vector addition without its guard `if (i < n)`.
__global__ void addNoGuard(const float* a, const float* b, float* c, int n)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
c[i] = a[i] + b[i];
}
The program launches 4 blocks of 256 threads, 1,024 threads in total, for 1,000 elements.
Threads 1,000 to 1,023 therefore read a[i] and b[i] and write c[i] past the end of each
array. Nevertheless, all 1,000 elements of c were correct. memcheck shows why:
$ compute-sanitizer --tool memcheck ./bugs bounds
========= Invalid __global__ read of size 4 bytes
========= at addNoGuard(const float *, const float *, float *, int)+0xa0 in bugs.cu:23
========= by thread (232,0,0) in block (3,0,0)
========= Access to 0xfffd63800fa0 is out of bounds
========= and is 1 bytes after the nearest allocation at 0xfffd63800000 of size
========= 4,000 bytes
...
========= Access to 0xfffd63800fd0 is out of bounds
========= and is 48 bytes before the nearest allocation at 0xfffd63801000 of size
========= 4,000 bytes
...
CUDA error: unspecified launch failure
========= ERROR SUMMARY: 25 errors
Thread 232 of block 3 has the index 3 × 256 + 232 = 1,000, which is the first element past the end.
The array a starts at address ...800000, and the next allocation starts at ...801000, 0x1000
= 4,096 bytes later. In other words, cudaMalloc placed each array of 4,000 bytes at the start of a
4,096-byte slot. The unused bytes between the end of an array and the end of its slot are called
padding. The 24 extra threads access 24 × 4 = 96 bytes past the end of each array, which is
exactly the 4,096 − 4,000 = 96 bytes of padding, as Figure 25.4 shows. Because no other array was
affected, the bug was invisible in the output. With 1,010 elements, the slots would hold only
4,096 − 4,040 = 56 bytes of padding, and the last 10 threads would write into the next array.
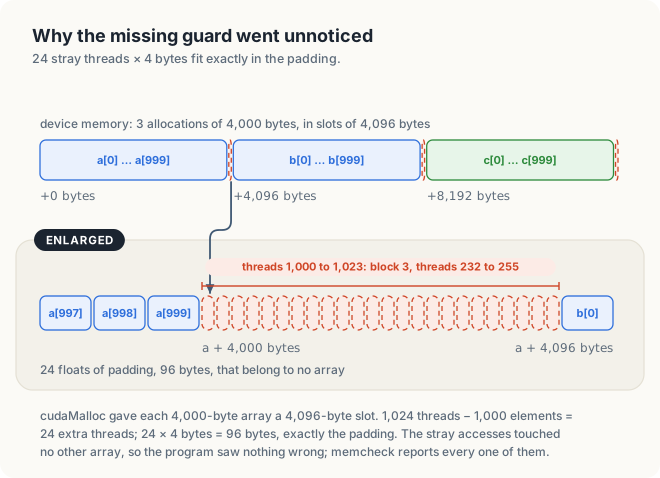
memcheck reports 24 invalid reads, 1 for each extra thread, and stops the kernel. The program’s next
CUDA call then fails, which is the 25th error. The same check applied to Chapter 3’s program, which
has the guard, ends with ERROR SUMMARY: 0 errors.
25.4.3 Shared-memory races (racecheck)
In Chapter 5, we summed 256 values per block as a tree in shared memory, with a barrier after each
level of the tree. Let us recall the method on 8 values, held by 8 threads in an array s in
shared memory:
s = [3, 1, 4, 1, 5, 9, 2, 6]
stride 4: s[t] ← s[t] + s[t + 4] for t < 4 s = [8, 10, 6, 7, ...]
stride 2: s[t] ← s[t] + s[t + 2] for t < 2 s = [14, 17, ...]
stride 1: s[t] ← s[t] + s[t + 1] for t < 1 s = [31, ...]
Each level halves the number of active threads, and after log2 8 = 3 levels s[0]
holds the sum, 31. At the first level, thread 0 reads s[4], a value that thread 4 stored. Now
suppose that threads 0 to 3 form 1 warp and threads 4 to 7 another, and that the first warp
reaches the addition before the second has stored its values. Thread 0 then reads whatever s[4]
held before, for example 0, and the block sum becomes 3 + 0 + … instead of 3 + 5 + …. The
barrier after the stores forbids this order. No thread may read until every thread has stored.
Definition 25.4 Race. A race is a pair of accesses to the same location by different threads, at least one of them a write, with nothing that orders them.
Example. In the sum of 8 values without a barrier, the store of s[4] by thread 4 and the read
of s[4] by thread 0 form a race.
Listing 25.4 leaves the barriers out of the sum of 256 values.
Listing 25.4 A block sum without barriers.
mod kernels {
// ...
/// 2. Chapter 5's block sum with its barriers left out.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_no_barrier(input: &[f32], mut out: DisjointSlice<f32>) {
static mut S: SharedArray<f32, 256> = SharedArray::UNINIT;
let t = thread::threadIdx_x() as usize;
let block = thread::blockIdx_x() as usize;
// SAFETY: none. No barrier orders these stores before the loads below: the bug.
unsafe { S[t] = input[block * 256 + t] };
let mut step: usize = 0;
#[unroll]
while step < 8 {
let stride: usize = 128 >> step;
if t < stride {
// SAFETY: none, as above.
unsafe { S[t] += S[t + stride] };
}
step += 1;
}
if t == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *out.get_unchecked_mut(block) = S[0] };
}
}
// ...
}// 2. Chapter 5's block sum with its barriers left out.
__global__ void sumNoBarrier(const float* in, float* out)
{
__shared__ float s[256];
int t = threadIdx.x;
s[t] = in[blockIdx.x * 256 + t];
for (int stride = 128; stride > 0; stride /= 2) {
if (t < stride) {
s[t] += s[t + stride];
}
}
if (t == 0) {
out[blockIdx.x] = s[0];
}
}
In Rust every access to the shared array S is unsafe, and the compiler accepts the kernel
without its barriers; the Rust program also printed 64 wrong block sums.
All 64 block sums were wrong, and racecheck reports the conflicting lines:
$ compute-sanitizer --tool racecheck ./bugs race
========= Error: Race reported between Write access at sumNoBarrier(...)+0x1a0 in bugs.cu:31
========= and Read access at sumNoBarrier(...)+0x130 in bugs.cu:35 [32768 hazards]
...
========= RACECHECK SUMMARY: 4 hazards displayed (3 errors, 1 warning)
racecheck calls each observed instance of a race a hazard; the count of 32,768 in the first
message is the number of times it observed the race between the same 2 lines. Line 31 stores
the value of each thread into s[t], and line 35 reads s[t + stride]. In the first step, thread 0 of warp 0 reads s[128], but s[128] is
written by thread 128, which belongs to warp 4. Nothing orders the 2 warps. Figure 25.5 shows the
case in which warp 0 reads the location before warp 4 has written it.
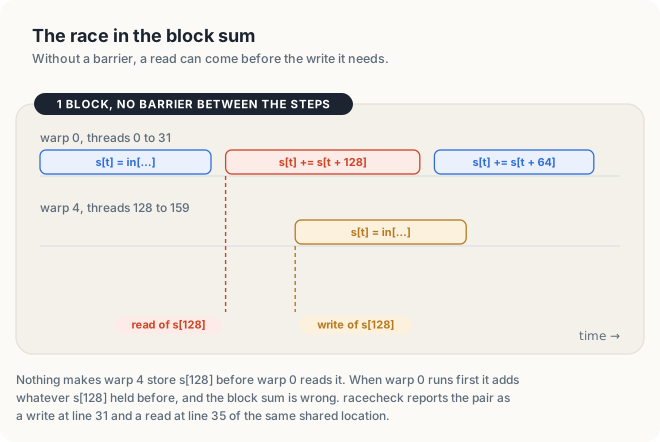
Key observation The warps of a block advance at different speeds, and nothing orders a store by 1 warp before a load by another. A value that 1 thread stores in shared memory and another thread loads needs a barrier between the store and the load.
25.4.4 Barriers in divergent code (synccheck)
The behavior of __syncthreads() is defined only when every thread of the block reaches the same
barrier instruction. The threads of a warp diverge when they take different branches of an
if statement, and the code inside such an if statement is called divergent code. Take a
block of 4 threads and the condition “\(t\) is even”. Threads 0 and 2 enter the first branch and
threads 1 and 3 the second. If each branch holds its own barrier, threads 0 and 2 wait at 1
barrier instruction while threads 1 and 3 wait at another, and neither barrier is reached by all
4 threads. Listing 25.5 places 1 barrier in each branch of an if statement in the same way, so
the even and odd threads of every warp wait at 2 different instructions.
Listing 25.5 2 barriers, 1 per branch.
mod kernels {
// ...
/// 3. Even and odd threads of each warp wait at 2 different barriers.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn barrier_in_branch(mut out: DisjointSlice<f32>) {
static mut S: SharedArray<f32, 256> = SharedArray::UNINIT;
let t = thread::threadIdx_x() as usize;
// SAFETY: each thread writes only its own cell, before the barrier.
unsafe { S[t] = t as f32 };
if t % 2 == 0 {
thread::sync_threads();
} else {
thread::sync_threads();
}
let Some(o) = out.get_mut(thread::index_1d()) else {
return;
};
// SAFETY: after the barrier, no thread writes S.
*o = unsafe { S[255 - t] };
}
// ...
}// 3. Even and odd threads of each warp wait at 2 different barriers.
__global__ void barrierInBranch(float* out)
{
__shared__ float s[256];
int t = threadIdx.x;
s[t] = t;
if (t % 2 == 0) {
__syncthreads();
out[t] = s[255 - t];
} else {
__syncthreads();
out[t] = s[255 - t];
}
}
On the second GPU, the kernel produced the correct 256 elements, because the hardware happened to release both groups of threads together. On the first GPU, the same program never finished. The same source file thus gave 2 different outcomes on 2 GPUs. A program of this kind has undefined behavior: the language does not specify its result, so each machine may do something different. synccheck reports the cause:
$ compute-sanitizer --tool synccheck ./bugs barrier
========= Barrier error detected. Divergent thread(s) in warp.
========= at barrierInBranch(float *)+0xd0 in bugs.cu:52
========= by thread (64,0,0) in block (0,0,0)
...
========= ERROR SUMMARY: 128 errors
The 128 errors are 1 for each of the 128 even threads that waited at line 52 while the odd threads
of their warps waited at line 55. The correct kernel moves the barrier out of the if statement,
where all 256 threads reach it.
25.4.5 Reads of uninitialized memory (initcheck)
cudaMalloc returns memory that still holds whatever it last contained. Memory is
uninitialized until the program first writes it, and a load from uninitialized memory returns
a value that the program did not choose. Listing 25.6 sums 1,024 floats that nothing has written.
Listing 25.6 A sum of unwritten memory.
mod kernels {
// ...
/// 4. A sum over memory that nothing has written.
#[kernel]
#[launch_contract(domain = 1, block = (32, 1, 1))]
pub fn sum_unwritten(input: &[f32], total: &[DeviceAtomicF32]) {
let mut sum = 0.0;
let mut i = thread::threadIdx_x() as usize;
while i < input.len() {
sum += input[i];
i += 32;
}
total[0].fetch_add(sum, AtomicOrdering::Relaxed);
}
}// 4. A sum over memory that nothing has written.
__global__ void sumUnwritten(const float* in, float* out, int n)
{
float sum = 0.0f;
for (int i = threadIdx.x; i < n; i += 32) {
sum += in[i];
}
atomicAdd(out, sum);
}
In Rust, unwritten device memory comes only from the unsafe function
DeviceBuffer::uninitialized_async; the safe constructors zeroed and from_host write it first.
The result was 0, because the memory happened to contain zeros. initcheck reports all 1,024 reads, each with its thread:
$ compute-sanitizer --tool initcheck ./bugs uninit
========= Uninitialized __global__ memory read of size 4 bytes
========= at sumUnwritten(const float *, float *, int)+0x180 in bugs.cu:65
========= by thread (0,0,0) in block (0,0,0)
...
========= ERROR SUMMARY: 1024 errors
25.4.6 Overhead and limits of instrumentation
Every check adds work. The Rust program of section 25.6 measures a load from the L1 cache in 39
cycles. Under memcheck, the same loop took 8,463 cycles per load, 217 times as long. A run under
Compute Sanitizer therefore tells us whether a program is correct, but never how fast it is. The
same run ended with ERROR SUMMARY: 0 errors, which shows that programs written with cuda-oxide can
be checked in the same way as C++ programs.
A clean run, moreover, is evidence only about the inputs and the timing of that run. A race that did not occur in 1 run may occur in the next, and an out-of-bounds index that depends on the input may not be reached by the test input. In Section 25.8, we add tests that check the result itself.
The out-of-bounds kernel produced every element correctly and exited with status 0. A program that passes its tests can still access memory it does not own. Run Compute Sanitizer on every kernel before trusting it.
25.5 Debugging a kernel with cuda-gdb
cuda-gdb extends the GNU debugger, gdb, the standard debugger of Linux, with support for GPU
threads. A breakpoint on a line of a kernel stops the whole grid as soon as any thread reaches it.
At that moment thousands of threads are stopped, each with its own variables, and the debugger can
show the variables of only one of them at a time. The focus is the thread that the debugger
currently shows. The program is built with -G, which keeps device variables in a form the
debugger can read and turns off most optimizations, and with -g for the host code. A debugging
session can be scripted with -batch and 1 -ex option per command. In the session below, the
breakpoint has a condition, an expression that the debugger evaluates for each thread that
reaches the line; it stops only where the expression is true, here at thread 232 of block 3, the
first extra thread of section 25.4.2:
$ nvcc -arch=native -G -g bugs.cu -o bugs_debug
$ cuda-gdb -q -batch \
-ex 'break bugs.cu:23 if blockIdx.x == 3 && threadIdx.x == 232' \
-ex 'run bounds' -ex 'print i' -ex 'print n' -ex 'continue' ./bugs_debug
[Switching focus to CUDA kernel 0, grid 1, block (3,0,0), thread (232,0,0), device 0, sm 3,
warp 7, lane 8]
CUDA thread hit Breakpoint 1, addNoGuard<<<(4,1,1),(256,1,1)>>> (a=0x32b200000,
b=0x32b201000, c=0x32b202000, n=1000) at bugs.cu:23
23 c[i] = a[i] + b[i];
$1 = 1000
$2 = 1000
1,024 threads for 1,000 elements: 0 wrong elements
[Inferior 1 (process 3104365) exited normally]
The debugger confirms the reasoning of section 25.4.2 from inside the kernel. Thread 232 of block 3
has i = 1000, which equals n, and is about to access a[1000]. The focus line also locates the
thread in the hardware. The lane of a thread is its position within its warp, from 0 to 31.
Thread 232 belongs to warp 232 / 32 = 7, rounded down, at lane 232 − 7 × 32 = 8, and it ran on SM
3. The word Inferior in the last line is gdb’s name for the program being debugged. The 3 pointers lie 0x1000 = 4,096 bytes apart, which matches the slots of
Figure 25.4.
cuda-gdb is the tool for the bugs that Compute Sanitizer cannot detect, because they involve no
illegal access: wrong arithmetic on indices, a wrong weight in a stencil, or a branch taken by the
wrong threads.
25.6 Timing inside a kernel with clock64()
25.6.1 The per-SM cycle counter
Events measure the time of a whole kernel. To measure a few instructions, we need a clock that a
thread can read. The function clock64() returns the value of a 64-bit counter that each SM
increments once per cycle of its own clock. The difference between 2 readings taken by the same
thread is the number of cycles between them. The counters of different SMs are not synchronized,
so 2 readings can be compared only when the same thread took both.
In Chapter 1, we assumed 2 latencies, about 4 cycles for an addition and about 500 cycles for a
read from main memory, and argued from them that a GPU needs many threads. The program latency.cu
measures these latencies.
A clock that ticks once per cycle does not by itself show how long 1 operation takes, because an SM works on several operations at once. Suppose that a multiply-add takes 4 cycles from start to result, and that the SM can start a new one in every cycle. Consider 3 multiply-adds written 2 ways:
dependent: v ← v × 0.999 + 1; v ← v × 0.999 + 1; v ← v × 0.999 + 1
independent: a ← a × 0.999 + 1; b ← b × 0.999 + 1; c ← c × 0.999 + 1
In the first line, each operation needs the v that the previous one produced. The first runs
from cycle 0 to cycle 4, the second cannot start until cycle 4 and ends at cycle 8, and the third
ends at cycle 12: 3 operations take 3 × 4 = 12 cycles. In the second line, the 3 operations do not
need each other’s results, so the SM starts them in cycles 0, 1 and 2, and the last ends at cycle
6. 12 cycles divided by 3 operations gives 4 cycles, the time of 1 operation; 6 cycles divided by
3 gives 2 cycles, a number that depends on how many operations were in flight.
Definition 25.5 Latency and dependent chain. The latency of an operation is the time from its start to the moment its result can be used. A dependent chain is a sequence of operations in which each operation needs the result of the previous one, so that no 2 of them overlap.
Example. A dependent chain of 3 multiply-adds with a latency of 4 cycles takes 3 × 4 = 12 cycles.
Key observation The time of a dependent chain of \(k\) operations divided by \(k\) is the latency of 1 operation. To measure a latency, we time a long dependent chain and divide.
The pseudocode below shows the 2 measurements.
KERNEL dependentFma, 1 thread:
v ← x[0]
t0 ← clock64()
repeat 4,096 times:
v ← v × 0.999 + 1 # needs the v of the line before
t1 ← clock64()
x[0] ← v # keeps the compiler from deleting the loop
cycles ← t1 − t0
KERNEL chase(next, warm, hops), 1 thread:
j ← 0
repeat warm times: j ← next[j] # brings the chain into the caches
t0 ← clock64()
repeat hops times: j ← next[j] # each load needs the index the last one returned
t1 ← clock64()
out ← j
cycles ← t1 − t0
25.6.2 Latency of arithmetic
Listing 25.7 implements the first measurement in two forms.
Listing 25.7 1 dependent chain, and 4 independent chains, timed with clock64(). code/ch16_profiling/latency.cu
mod kernels {
// ...
/// 1 thread, 1 chain: each multiply-add needs the result of the one before.
#[kernel]
#[launch_contract(domain = 1, block = (1, 1, 1))]
pub fn dependent_fma(
start: f32,
mut out: DisjointSlice<f32>,
mut cycles: DisjointSlice<u64>,
) {
let mut v = start;
let t0 = debug::clock64();
let mut k = 0;
#[unroll(16)]
while k < STEPS {
v = float::fma_rn_f32(v, 0.999, 1.0);
k += 1;
}
let t1 = debug::clock64();
if let Some(o) = out.get_mut(thread::index_1d()) {
*o = v;
}
if let Some(c) = cycles.get_mut(thread::index_1d()) {
*c = t1 - t0;
}
}
/// 1 thread, 4 chains: the multiply-adds of 1 step do not wait for each other.
#[kernel]
#[launch_contract(domain = 1, block = (1, 1, 1))]
pub fn independent_fma(
start: f32,
mut out: DisjointSlice<f32>,
mut cycles: DisjointSlice<u64>,
) {
let (mut v0, mut v1, mut v2, mut v3) = (start, start, start, start);
let t0 = debug::clock64();
let mut k = 0;
#[unroll(4)]
while k < STEPS / 4 {
v0 = float::fma_rn_f32(v0, 0.999, 1.0);
v1 = float::fma_rn_f32(v1, 0.999, 1.0);
v2 = float::fma_rn_f32(v2, 0.999, 1.0);
v3 = float::fma_rn_f32(v3, 0.999, 1.0);
k += 1;
}
let t1 = debug::clock64();
if let Some(o) = out.get_mut(thread::index_1d()) {
*o = v0 + v1 + v2 + v3;
}
if let Some(c) = cycles.get_mut(thread::index_1d()) {
*c = t1 - t0;
}
}
// ...
}// 1 thread, 1 chain: each multiply-add needs the result of the one before.
__global__ void dependentFma(float* x, long long* cycles)
{
float v = x[0];
long long t0 = clock64();
for (int k = 0; k < STEPS; ++k) {
v = fmaf(v, 0.999f, 1.0f);
}
long long t1 = clock64();
x[0] = v;
cycles[0] = t1 - t0;
}
// 1 thread, 4 chains: the 4 multiply-adds of a step do not wait for each other.
__global__ void independentFma(float* x, long long* cycles)
{
float v0 = x[0], v1 = x[1], v2 = x[2], v3 = x[3];
long long t0 = clock64();
for (int k = 0; k < STEPS / 4; ++k) {
v0 = fmaf(v0, 0.999f, 1.0f);
v1 = fmaf(v1, 0.999f, 1.0f);
v2 = fmaf(v2, 0.999f, 1.0f);
v3 = fmaf(v3, 0.999f, 1.0f);
}
long long t1 = clock64();
x[0] = v0 + v1 + v2 + v3;
cycles[0] = t1 - t0;
}
The first kernel performs 4,096 multiply-adds as a single dependent chain. The second kernel performs the same 4,096 multiply-adds as 4 chains of 1,024. The 4 operations of each step do not depend on each other, so the SM can start each of them before the previous one has finished.
25.6.3 Latency of loads
A pointer chase measures the latency of a load. An array next holds, at each position, the
position of the next load, so that each load must wait for the one before it. Consider an array of
8 positions in which every position points 2 positions further on, wrapping around at the end:
position 0 1 2 3 4 5 6 7
next 2 3 4 5 6 7 0 1
A thread that starts at j = 0 loads next[0] = 2, then next[2] = 4, then next[4] = 6, then
next[6] = 0. It cannot issue the load of next[2] before the load of next[0] has returned,
because only that load tells it the position 2. The loads therefore form a dependent chain, and
their time divided by their number is the latency of 1 load. After \(k\) hops the thread stands
at position \(2k \bmod 8\), where \(x \bmod c\) is the remainder of \(x\) divided by \(c\):
after 4 hops, at 8 mod 8 = 0. The host builds the
array with a fixed step of 32 ints, 128 bytes, so that every load touches a new cache line, the
128-byte unit in which the caches hold data (Chapter 7, section 7.2). We use 3 chains of different
sizes, which are served from different levels of the memory hierarchy. A chain of 4 KiB fits in the
L1 cache. A chain of 1 MiB fits in the L2 cache but not in L1. The third chain spans 256 MiB with a
step of 1 MiB + 128 bytes and has no warm-up, so every load goes to DRAM.
Listing 25.8 The pointer chase.
mod kernels {
// ...
/// 1 thread follows a chain of indices; the first `warm` hops are not timed.
#[kernel]
#[launch_contract(domain = 1, block = (1, 1, 1))]
pub fn chase(
next: &[u32],
warm: u32,
hops: u32,
mut out: DisjointSlice<u32>,
mut cycles: DisjointSlice<u64>,
) {
let mut j = 0;
let mut k = 0;
while k < warm {
// SAFETY: the host builds every entry of `next` below next.len().
j = unsafe { *next.get_unchecked(j as usize) };
k += 1;
}
let t0 = debug::clock64();
k = 0;
while k < hops {
// SAFETY: as above.
j = unsafe { *next.get_unchecked(j as usize) };
k += 1;
}
let t1 = debug::clock64();
if let Some(o) = out.get_mut(thread::index_1d()) {
*o = j;
}
if let Some(c) = cycles.get_mut(thread::index_1d()) {
*c = t1 - t0;
}
}
}// 1 thread follows a chain: each load needs the index the load before returned.
// The first `warm` hops bring the chain into the caches; the next `hops` are timed.
__global__ void chase(const int* next, int warm, int hops, int* out, long long* cycles)
{
int j = 0;
for (int k = 0; k < warm; ++k) {
j = next[j];
}
long long t0 = clock64();
for (int k = 0; k < hops; ++k) {
j = next[j];
}
long long t1 = clock64();
out[0] = j;
cycles[0] = t1 - t0;
}
The host checks that each chain ended at the expected position: after \(w\) warm-up hops and \(h\) timed hops of step \(s\) through \(c\) positions, the index is \((w + h)\,s \bmod c\). In the array of 8 positions above, with \(s\) = 2, 1 warm-up hop and 3 timed hops end at (1 + 3) × 2 mod 8 = 0, the position we found by hand.
$ ./latency # first GPU
4096 multiply-adds in 1 thread, cycles per multiply-add
1 dependent chain 4.24
4 independent chains 1.31
1 thread follows a chain of loads, cycles per load
4 KiB chain, from L1 39
1 MiB chain, from L2 191
256 MiB chain, from DRAM 607
PASSED: 0 of 3 chains end in the wrong place
The program divides the cycles of the dependent chain by its 4,096 multiply-adds, which gives 4.24 cycles per operation, or about 17,400 cycles in total. The latency of a multiply-add is therefore about 4 cycles, as we assumed in Chapter 1; the extra 0.24 cycles come from the loop’s own counting and branching. With 4 independent chains, a multiply-add takes 1.31 cycles, so the SM completes about 4 times as many operations per cycle. This is what Little’s law predicts (Chapter 1, section 1.1.4). Little’s law states that the number of operations in flight equals the rate at which they complete multiplied by their latency, so the rate equals the number in flight divided by the latency. Four operations in flight with a latency of 4 cycles complete at a rate of 4 / 4 = 1 per cycle.
The loads can be converted from cycles to time in the same way. At 1,173 MHz, a cycle lasts 1 / 1.173 GHz = 0.85 ns, so a load from L1 takes 39 × 0.85 = 33 ns, a load from L2 takes 191 × 0.85 = 163 ns, and a load from DRAM takes 607 × 0.85 = 517 ns. A single load from DRAM thus costs as much time as 607 / 4.24 = 143 dependent multiply-adds.
Figure 25.6 places the 5 numbers on a logarithmic scale. The DRAM latency varied more than the others. Over 14 runs of the C++ and Rust programs, it ranged from 598 to 1,137 cycles. The L1 latency stayed at 39 cycles, and the L2 latency at 190 to 191 cycles in all runs but 2, which gave 431 and 689 cycles. On an integrated GPU, DRAM is shared with the CPU cores, the display and every other program, and the loads of a single thread wait behind theirs. For this reason, we report the DRAM latency as a range.
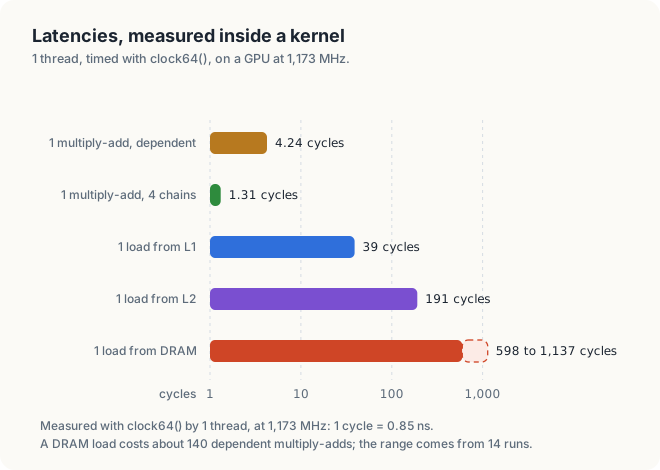
25.6.4 Latency measurement in Rust
cuda-oxide exposes the same counter as cuda_device::debug::clock64(), and the multiply-add as
cuda_device::float::fma_rn_f32, which rounds its exact result to the nearest float, like fmaf
in C++. The kernels launch 1 thread with the contract block = (1, 1, 1), a declaration that the
kernel is always launched with blocks of that shape. They write their results through
DisjointSlice, the slice type of Chapter 13 through which each thread writes only its own
elements. The chase of Listing 25.8 reads next with get_unchecked, which reads an element without first
comparing the index with the length of the slice; we explain why in section 25.9.
$ cargo oxide run # first GPU
4096 multiply-adds in 1 thread, cycles per multiply-add
1 dependent chain 4.07
4 independent chains 1.12
1 thread follows a chain of loads, cycles per load
4 KiB chain, from L1 39
1 MiB chain, from L2 191
256 MiB chain, from DRAM 599
PASSED: every chain ends where the host expects
The load latencies match those of the C++ program cycle for cycle. The multiply-add loops of the
Rust program are unrolled 16 and 4 times by #[unroll] (Chapter 9, section 9.7). Unrolling a
loop \(k\) times copies its body \(k\) times into each iteration, so that the loop counter is
updated and tested \(k\) times less often: a loop of 4,096 steps unrolled 16 times makes 256
iterations. Less of each step is therefore spent on counting, and the Rust kernels are 0.17 to
0.19 cycles faster per operation.
25.7 The benchmarking discipline
25.7.1 Warm-up effects
A benchmark is a measurement of a program’s speed made in such a way that it can be repeated
and compared. The first rule of benchmarking is to measure the program in the state in which it
will normally run. To show the difference, measure.cu times the kernel y = 2 x 40 times in a row with
events, starting after the GPU has been idle. Listing 25.9 shows how a single launch is timed.
Listing 25.9 1 launch, timed with 2 events.
/// The time of 1 launch of `scale`, in milliseconds, measured with 2 events.
fn time_scale(
stream: &CudaStream,
module: &kernels::LoadedModule,
x: &DeviceBuffer<f32>,
y: &mut DeviceBuffer<f32>,
) -> Result<f32, Error> {
let blocks = x.len().div_ceil(256) as u32;
let launch = module.prepare_scale(LaunchConfig1D::new(blocks, 256, 0))?;
let start = stream.record_event(Some(TIMING))?;
module.scale(stream, &launch, x, y)?;
let stop = stream.record_event(Some(TIMING))?;
stop.synchronize()?;
Ok(start.elapsed_ms(&stop)?)
}// The time of 1 launch of `scale`, in milliseconds, measured with 2 events.
float timeScale(const float* x, float* y, int n)
{
cudaEvent_t start, stop;
check(cudaEventCreate(&start));
check(cudaEventCreate(&stop));
check(cudaEventRecord(start));
scale<<<(n + 255) / 256, 256>>>(x, y, n);
check(cudaEventRecord(stop));
check(cudaEventSynchronize(stop));
float ms;
check(cudaEventElapsedTime(&ms, start, stop));
check(cudaEventDestroy(start));
check(cudaEventDestroy(stop));
return ms;
}
y = 2 x over 256 MiB, the first 40 runs in ms
19.83 14.43 10.63 13.25 10.64 11.40 10.62 9.67 8.48 8.46
8.47 8.47 8.46 8.47 10.43 8.39 8.37 8.38 8.35 8.35
8.34 8.35 8.36 8.33 8.32 8.36 10.33 8.38 8.40 8.35
8.34 8.34 12.91 9.80 8.36 8.35 8.36 8.36 8.34 8.35
mean of all 40 runs 9.46 ms
median of runs 21 to 40 8.35 ms
bytes moved 512 MiB
achieved bandwidth 64.3 GB/s
blocks of 256 per SM 6 = 1536 threads
PASSED: 0 of 67108864 elements wrong
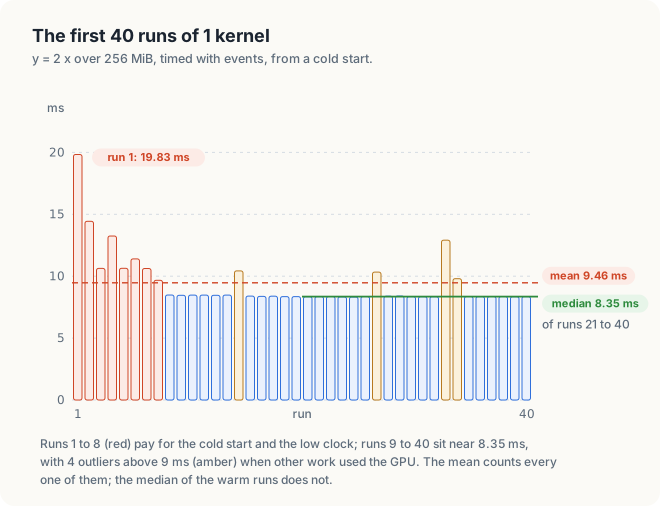
As Figure 25.7 shows, the same kernel on the same data took 19.83 ms the first time and 8.35 ms once warm. Two effects contribute to the difference. First, a first launch pays one-time costs, such as loading the kernel’s code onto the GPU. Second, a power governor, the part of the driver or firmware that sets the clock rate according to the load, lowers the GPU clock while the GPU is idle and raises it only after it has seen sustained load (Chapter 6). The governor of the Jetson modules behaves this way, so runs 2 to 8 executed at a lower clock. The runs after run 8 that took much longer than their neighbors, 10.43, 10.33, 12.91 and 9.80 ms, are outliers: single measurements far from the typical value, usually caused by something outside the program. When the program was run again immediately, while the clock was still high, its first run took 8.92 ms. A measurement taken without warm-up therefore depends on what the machine did in the seconds before it.
25.7.2 Mean and median
The mean of a set of times is their sum divided by their number. The median is the middle value once the times are sorted; for an even number of times, it is the mean of the 2 middle values. Consider 5 runs that took 8, 8, 8, 8 and 20 ms. The mean is (4 × 8 + 20) / 5 = 10.4 ms, longer than 4 of the 5 runs. The median is the third of the sorted times, 8 ms. If the slow run had taken 100 ms instead of 20 ms, the mean would rise to 26.4 ms, and the median would stay at 8 ms. In general, a single slow run moves the mean by its whole excess divided by the number of runs, but it moves the median at most to a neighboring value.
The 40 runs above illustrate the difference. The mean of all 40 runs is 9.46 ms, because the 8 warm-up runs and the 4 outliers pull it 1.11 ms above the typical run. When runs 21 to 40 are sorted, positions 10 and 11 both hold 8.35 ms, so their median is 8.35 ms. The outlier of 12.91 ms alone adds (12.91 − 8.35) / 40 = 0.11 ms to the mean of 40 runs, and nothing to the median.
The outliers came from other work on the GPU, such as a desktop that draws its windows with the same GPU. An earlier run of the same kernel, while that other work was heavier, gave a mean of 11.56 ms and a median of 9.74 ms. A busy machine shifts even the median, so a measurement protocol must also check that the machine is idle before it measures.
25.7.3 A measurement protocol
The following protocol collects these rules. Each rule prevents a mistake that we observed in the measurements of this chapter or of an earlier chapter.
BENCHMARK kernel:
check the GPU is idle # nvidia-smi or tegrastats
allocate every buffer before timing # no cudaMalloc inside the timed region
size the data well beyond the L2 cache # or the test measures the cache
run the kernel for about 0.4 s # warm-up: one-time costs, clocks
repeat R times:
record event start; launch; record event stop
times[r] ← elapsed(start, stop)
report median(times) and the spread # not the mean of a few runs
verify the output # a fast wrong kernel is not a result
record GPU, clocks, CUDA version, flags # the limits of listing 25.1
nvidia-smi and tegrastats are NVIDIA’s command-line tools that report the load and clock of
the GPU, on desktop and Jetson systems respectively. The spread of the times is the range from
the fastest to the slowest of the \(R\) runs. We use events rather than CPU clocks because a
launch returns to the CPU before the kernel ends;
in Chapter 6 we measured 0.07 ms for the launch call against 10.4 ms for the kernel itself. Events are
timestamped by the GPU. We size the data beyond the L2 cache because a test that fits in the cache
measures the cache. For example, on a GPU whose L2 cache holds 32 MiB, Chapter 7’s test on 16 MiB
of data reported 432 GB/s, above that GPU’s memory bandwidth of 273 GB/s. The 256 MiB arrays of
measure.cu are 128 times the size of an L2 cache of 2 MiB and 8 times that of an L2 cache of 32
MiB. We record the environment because the clocks, the compiler flags (-O3, -arch,
--use_fast_math) and the CUDA version all change results, and a number reported without them
cannot be reproduced. Finally, we run the whole program 3 times and quote a quiet run, and we expect
10% to 20% drift between runs on GPUs whose clocks change with load and temperature.
25.8 Verifying results
25.8.1 Units in the last place
A differential test compares a result with a trusted reference computed in another way,
usually on the CPU in double precision, the 64-bit floating-point format double, whose rounding
errors are far smaller than those of float. For integers, the comparison is exact. For
floating-point numbers, it needs a tolerance, the largest difference that still counts as
correct, and the tolerance needs a unit.
An absolute number such as 0.001 is not a good unit, and a small example shows the reason. Consider a small floating-point format that we invent for the purpose, with 8 evenly spaced values between each 2 consecutive powers of 2. Between 1 and 2, its values are 1, 1.125, 1.25, …, 1.875, which lie 1/8 = 0.125 apart. Between 2 and 4 there are again 8 values, 2, 2.25, 2.5, …, 3.75, now 0.25 apart, and between 8 and 16 the values are 8, 9, 10, …, 15, 1 apart. Rounding to the nearest value alone can move a result near 1.3 by up to 0.0625, half a step, but a result near 12 by up to 0.5. An error of 0.5 is therefore 4 steps near 1.3 and half a step near 12. A useful unit must therefore grow with the value, as the spacing does.
A float stores a number as a significand of 24 bits multiplied by a power of 2. Between 2 consecutive powers of 2, \(2^e\) and \(2^{e+1}\), there are therefore \(2^{23}\) floats, evenly spaced \(2^{e-23}\) apart, and the spacing doubles at every power of 2, exactly as in the small format.
Definition 25.6 Unit in the last place. 1 unit in the last place, or 1 ULP, is the spacing of the floats around a value. The error of a result in ULPs is its distance from the correct value divided by that spacing.
Example. In the small format, 1 ULP is 0.125 between 1 and 2 and 1 between 8 and 16. For a real float near 1, 1 ULP is \(2^{-23}\) ≈ 0.000000119.
Figure 25.8 draws the small floating-point format, so that the doubling of the spacing is visible.
For example, e10 = 22,026.47 lies between 214 = 16,384 and 215 = 32,768, so \(e = 14\), and 1 ULP there is \(2^{14-23} = 2^{-9}\) = 0.00195. An error of 2 ULPs is therefore 0.0039 at 22,026.47 and \(2 \times 2^{-23}\) = 0.00000024 near 1. Both errors have the same relative size, the error divided by the value: about 1 part in 4 million.
Because positive floats are stored in order, the number of floats between 2 of them is the
difference of their bit patterns read as integers. For example, the float 1.0 has the bit pattern
0x3F80_0000, and the next larger float, 1 + 2−23, has the pattern 0x3F80_0001. The
difference of the two patterns read as integers is 1, and the 2 floats are 1 ULP apart. Listing 25.10 uses this property to measure the
error of expf, and of __expf, the faster hardware version that --use_fast_math substitutes,
against the nearest float to the exact value. --use_fast_math is a compiler flag of nvcc that
replaces standard math functions with faster and less accurate versions.
Listing 25.10 The distance between 2 floats in ULPs. code/ch16_profiling/verify.cu
/// The number of floats between a and b, for 2 floats of the same sign.
fn ulps(a: f32, b: f32) -> i64 {
let ia = a.to_bits() as i32 as i64;
let ib = b.to_bits() as i32 as i64;
(ia - ib).abs()
}
/// The largest distance in ULPs between y and the nearest float to exp(x).
fn exp_error(x: &[f32], y: &[f32]) -> i64 {
let mut worst = 0;
for (&x, &y) in x.iter().zip(y) {
let exact = (x as f64).exp() as f32;
worst = worst.max(ulps(y, exact));
}
worst
}// The number of floats between a and b, for 2 floats of the same sign.
int64_t ulps(float a, float b)
{
int32_t ia, ib;
std::memcpy(&ia, &a, sizeof(float));
std::memcpy(&ib, &b, sizeof(float));
return std::llabs(int64_t(ia) - int64_t(ib));
}
// The largest distance in ULPs between y and the nearest float to exp(x).
int64_t expError(const std::vector<float>& x, const std::vector<float>& y)
{
int64_t worst = 0;
for (size_t i = 0; i < x.size(); ++i) {
float exact = float(std::exp(double(x[i])));
worst = std::max(worst, ulps(y[i], exact));
}
return worst;
}
y = exp(x) for 1,048,576 values of x in [-10, 10)
expf largest error 2 ULPs
__expf largest error 8 ULPs
The CUDA programming guide gives expf a maximum error of 2 ULPs, and the measurement agrees. A
test of expf can therefore use a tolerance of 2 ULPs. The same test fails a kernel compiled with
--use_fast_math, so that flag is a decision about accuracy as well as about speed.
25.8.2 Tolerances for sums
A sum has no ULP bound of its own, because its error grows with the number of additions. Each addition of 2 floats rounds its exact result to the nearest float. Rounding to the nearest float moves a value by at most half a ULP, and half a ULP is at most \(u = 2^{-24}\) of the value. For example, the floats between 1 and 2 lie \(2^{-23}\) apart, so rounding a result near 1 moves it by at most \(2^{-24}\).
Consider 4 inputs summed in two ways. As a tree, \((x_0 + x_1) + (x_2 + x_3)\), every input passes through 2 additions on its way to the total. In a loop, \(((x_0 + x_1) + x_2) + x_3\), the inputs \(x_0\) and \(x_1\) pass through 3 additions, \(x_2\) through 2 and \(x_3\) through 1. Each addition that an input passes through may round the partial sum that contains it, and so adds an error of at most \(u\) times that partial sum. An input element that passes through \(d\) additions on its way to the total therefore contributes rounding errors of at most \(d\,u\) times its own size, and the error of the sum is bounded by
\[ |\text{error}| \le d \cdot u \cdot \sum_i |x_i| \]
| Symbol | Meaning | In the example |
|---|---|---|
| \(d\) | most additions any element passes through | 84 |
| \(u\) | largest relative rounding of 1 addition | \(2^{-24}\) = 5.96 × 10⁻⁸ |
| \(\sum_i \lvert x_i \rvert\) | sum of the sizes of the inputs | 8,391,134.58 |
| \(d\,u\sum_i \lvert x_i \rvert\) | the tolerance | 42.01 |
The program verify.cu sums 16,777,216 random floats in [0, 1) with the 2-launch reduction of
Chapter 8. To obtain the tolerance, we count the additions that an element can pass through.
Worked example: \(d\) for the 2-launch sum
- Launch 1 runs 1,024 blocks of 256 threads, 262,144 threads in total. We let each thread add 16,777,216 / 262,144 = 64 elements in a loop: up to 64 additions.
- Its block then adds the 256 thread sums as a tree of log2 256 = 8 levels: 8 more additions.
- Launch 2 runs 1 block of 256 threads over the 1,024 block sums: 4 additions per thread, then 8 levels of the tree.
- \(d\) = 64 + 8 + 4 + 8 = 84, and the tolerance is 84 × 2−24 × 8,391,134.58 = 42.01.
Listing 25.11 The sum tested against its tolerance, and against a known answer.
/// Sum x on the GPU twice: correctly, and as a caller passing 1 element too few.
fn sum_test(
stream: &CudaStream,
module: &kernels::LoadedModule,
title: &str,
x: &[f32],
tolerance: f64,
) -> Result<(), Error> {
let n = x.len() as u32;
let dx = DeviceBuffer::from_host(stream, x)?;
let mut partial = DeviceBuffer::<f32>::zeroed(stream, 1024)?;
let mut total = DeviceBuffer::<f32>::zeroed(stream, 1)?;
let exact: f64 = x.iter().map(|&v| v as f64).sum();
let good_sum = gpu_sum(stream, module, &dx, n, &mut partial, &mut total)?;
let bad_sum = gpu_sum(stream, module, &dx, n - 1, &mut partial, &mut total)?;
let good = (good_sum as f64 - exact).abs();
let bad = (bad_sum as f64 - exact).abs();
let good_verdict = verdict(good, tolerance);
let bad_verdict = verdict(bad, tolerance);
println!("{title}");
println!(" exact sum {exact:12.2}");
println!(" tolerance {tolerance:12.2}");
println!(" n elements error {good:6.2} {good_verdict}");
println!(" n - 1 elements error {bad:6.2} {bad_verdict}");
Ok(())
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
exp_test(&stream, &module)?;
let n = 1 << 24;
let mut state: u32 = 1;
let mut magnitude = 0.0;
let mut random = Vec::with_capacity(n);
for _ in 0..n {
state = state.wrapping_mul(1_664_525).wrapping_add(1_013_904_223);
let v = (state >> 8) as f32 / 16_777_216.0;
magnitude += v as f64;
random.push(v);
}
// Each element passes through at most 84 additions on the way to the total:
// 64 + 8 in launch 1, 4 + 8 in launch 2. Each rounds by 2^-24 of its sum at most.
let bound = 84.0 * 2f64.powi(-24) * magnitude;
let title = "sum of 16,777,216 random floats in [0, 1)";
sum_test(&stream, &module, title, &random, bound)?;
// Partial sums of ones are whole numbers up to 2^24, which floats hold exactly.
let ones = vec![1.0f32; n];
sum_test(&stream, &module, "sum of 16,777,216 ones", &ones, 0.0)?;
Ok(())
}// Sum x on the GPU twice: correctly, and as a caller passing 1 element too few.
void sumTest(const char* title, const std::vector<float>& x, double tolerance)
{
int n = x.size();
float *dx, *partial;
check(cudaMalloc(&dx, n * sizeof(float)));
check(cudaMalloc(&partial, 1025 * sizeof(float)));
check(cudaMemcpy(dx, x.data(), n * sizeof(float), cudaMemcpyHostToDevice));
double exact = 0.0;
for (float v : x) {
exact += v;
}
double good = std::fabs(gpuSum(dx, n, partial) - exact);
double bad = std::fabs(gpuSum(dx, n - 1, partial) - exact);
std::printf("%s\n", title);
std::printf(" exact sum %12.2f\n", exact);
std::printf(" tolerance %12.2f\n", tolerance);
std::printf(" n elements error %6.2f %s\n", good, verdict(good, tolerance));
std::printf(" n - 1 elements error %6.2f %s\n", bad, verdict(bad, tolerance));
check(cudaFree(dx));
check(cudaFree(partial));
}
int main()
{
expTest();
const int n = 1 << 24;
std::vector<float> random(n), ones(n, 1.0f);
uint32_t state = 1;
double magnitude = 0.0;
for (float& v : random) {
state = state * 1664525u + 1013904223u;
v = (state >> 8) / 16777216.0f;
magnitude += v;
}
// Each element passes through at most 84 additions on the way to the total:
// 64 + 8 in launch 1, 4 + 8 in launch 2. Each rounds by 2^-24 of its sum at most.
double bound = 84 * std::ldexp(1.0, -24) * magnitude;
sumTest("sum of 16,777,216 random floats in [0, 1)", random, bound);
// Partial sums of ones are whole numbers up to 2^24, which floats hold exactly.
sumTest("sum of 16,777,216 ones", ones, 0.0);
return 0;
}
25.8.3 Known-answer and property tests
The test runs the sum twice: once correctly, and once through a caller that passes \(n - 1\) instead of \(n\). An off-by-one error is a count or an index that is 1 too large or 1 too small, and it is among the most common bugs in loops over arrays. Here, the faulty sum leaves out the last element.
sum of 16,777,216 random floats in [0, 1)
exact sum 8391134.58
tolerance 42.01
n elements error 0.42 PASSED
n - 1 elements error 0.58 PASSED
sum of 16,777,216 ones
exact sum 16777216.00
tolerance 0.00
n elements error 0.00 PASSED
n - 1 elements error 1.00 FAILED
The bug passes the differential test. The missing element is smaller than 1, while the tolerance is 42.01, and a test that allows for rounding cannot detect an error smaller than the rounding it allows. The second input detects the bug. When every element equals 1, every partial sum is a whole number no larger than 224 = 16,777,216. A float represents every whole number up to 224 exactly, so no addition rounds, the correct answer is exact, and the tolerance is 0. Figure 25.9 places both results.
A known-answer test chooses its input so that the correct result is known exactly. A property test checks a relation that every correct result satisfies, whatever the input. For example, the counts of a histogram add up to the number of elements (Chapters 5 and 8), a transpose applied twice gives back the input (Chapter 7), and the last element of an inclusive scan equals the sum of the input. Recall that an inclusive scan replaces each element by the sum of itself and all elements before it: the scan of [3, 1, 4] is [3, 4, 8], and its last element, 8, is the sum of the input. Property tests need no reference at all, so they also detect bugs that a reference shares with the code it checks.
A tolerance wide enough for rounding is wide enough to hide small bugs. Add inputs whose answer is known exactly, and test them with a tolerance of 0.
25.9 A systematic optimization process
The tools of this chapter fit into a single procedure, which we followed in every earlier chapter:
- Measure, using the protocol of section 25.7.
- Form a hypothesis, a proposed cause that a measurement can confirm or refute, using the timeline, the counters or a count by hand.
- Change one thing.
- Measure again, in the same way.
- Verify that the results are still correct.
Figure 25.10 applies the procedure to a case from this chapter. The first Rust version of the
pointer chase indexed next[j as usize] in a for loop and measured 62 cycles per L1 load,
against 39 cycles in C++. Rust performs a bounds check before every indexing operation such as
next[j]: it compares the index with the length of the slice, and it stops the program if the
index lies past the end, instead of reading another array’s memory. Our hypothesis was that the
bounds check of next[j] lies on the dependent chain. The check compares j with the length of
the slice before each load, so each load must wait for the index returned by the previous load and
then for the comparison.
The first attempt replaced the for loop with a while loop and the indexing with
get_unchecked at the same time, and it measured 39 cycles. Because two things had changed, the
measurement could not tell which change mattered. Measured separately, the while loop with the
bounds check still took 62 cycles. The bounds check alone accounted for the 23 cycles, and the form
of the loop for none of them.
The L2 latencies also changed, from 408 cycles to 295 and then to 191, but each of these was a
single run, and 2 runs of the final program gave 431 and 689 cycles. These differences may be
noise, so we draw no conclusion from them. Finally, verification confirmed that every chain still
ended at the index the host predicts, and the SAFETY comment in the code records why the
unchecked load stays within bounds.
Most of the analysis in the earlier chapters concerns step 2. The roofline model of Chapter 1 tells us whether a kernel is limited by memory or by arithmetic, the coalescing rules of Chapter 7 tell us how many sectors a warp moves, and the reuse count of Chapter 9 tells us how often each value is fetched. Recall that coalescing is the combining of the accesses of a warp’s 32 threads into as few memory transactions as possible, and that a sector is the 32-byte unit in which the memory system moves data. The procedure above is how each of these explanations was checked.
25.10 The complete programs
Listing 25.12 The complete bugs programs. code/oxide/ch16_bugs/src/main.rs and code/ch16_profiling/bugs.cu
//! Chapter 16 in Rust: the bugs of bugs.cu, for Compute Sanitizer to find.
//!
//! cargo oxide run -- race | barrier | uninit
//! cargo oxide build --features no_guard # the bounds bug: does not compile
use std::sync::Arc;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, LaunchConfig1D};
use cuda_device::atomic::{AtomicOrdering, DeviceAtomicF32};
use cuda_device::{DisjointSlice, SharedArray, cuda_module, kernel, launch_contract, thread};
type Error = Box<dyn std::error::Error>;
#[cuda_module]
mod kernels {
use super::*;
/// 1. Chapter 3's vector addition without its guard `if let Some(..)`.
#[cfg(feature = "no_guard")]
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn add_no_guard(a: &[f32], b: &[f32], mut c: DisjointSlice<f32>) {
let i = thread::index_1d();
let k = i.get();
*c.get_mut(i) = a[k] + b[k];
}
/// 2. Chapter 5's block sum with its barriers left out.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_no_barrier(input: &[f32], mut out: DisjointSlice<f32>) {
static mut S: SharedArray<f32, 256> = SharedArray::UNINIT;
let t = thread::threadIdx_x() as usize;
let block = thread::blockIdx_x() as usize;
// SAFETY: none. No barrier orders these stores before the loads below: the bug.
unsafe { S[t] = input[block * 256 + t] };
let mut step: usize = 0;
#[unroll]
while step < 8 {
let stride: usize = 128 >> step;
if t < stride {
// SAFETY: none, as above.
unsafe { S[t] += S[t + stride] };
}
step += 1;
}
if t == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *out.get_unchecked_mut(block) = S[0] };
}
}
/// 3. Even and odd threads of each warp wait at 2 different barriers.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn barrier_in_branch(mut out: DisjointSlice<f32>) {
static mut S: SharedArray<f32, 256> = SharedArray::UNINIT;
let t = thread::threadIdx_x() as usize;
// SAFETY: each thread writes only its own cell, before the barrier.
unsafe { S[t] = t as f32 };
if t % 2 == 0 {
thread::sync_threads();
} else {
thread::sync_threads();
}
let Some(o) = out.get_mut(thread::index_1d()) else {
return;
};
// SAFETY: after the barrier, no thread writes S.
*o = unsafe { S[255 - t] };
}
/// 4. A sum over memory that nothing has written.
#[kernel]
#[launch_contract(domain = 1, block = (32, 1, 1))]
pub fn sum_unwritten(input: &[f32], total: &[DeviceAtomicF32]) {
let mut sum = 0.0;
let mut i = thread::threadIdx_x() as usize;
while i < input.len() {
sum += input[i];
i += 32;
}
total[0].fetch_add(sum, AtomicOrdering::Relaxed);
}
}
fn race(stream: &Arc<CudaStream>, module: &kernels::LoadedModule) -> Result<(), Error> {
let blocks = 64;
let input = DeviceBuffer::from_host(stream, &vec![1.0f32; blocks * 256])?;
let mut out = DeviceBuffer::<f32>::zeroed(stream, blocks)?;
let launch = module.prepare_sum_no_barrier(LaunchConfig1D::new(blocks as u32, 256, 0))?;
module.sum_no_barrier(stream, &launch, &input, &mut out)?;
let sums = out.to_host_vec(stream)?;
let wrong = sums.iter().filter(|&&sum| sum != 256.0).count();
println!("{blocks} blocks of 256 ones: {wrong} wrong block sums");
Ok(())
}
fn barrier(stream: &Arc<CudaStream>, module: &kernels::LoadedModule) -> Result<(), Error> {
let mut out = DeviceBuffer::<f32>::zeroed(stream, 256)?;
let launch = module.prepare_barrier_in_branch(LaunchConfig1D::new(1, 256, 0))?;
module.barrier_in_branch(stream, &launch, &mut out)?;
let values = out.to_host_vec(stream)?;
let wrong = (0..256).filter(|&t| values[t] != (255 - t) as f32).count();
println!("2 barriers, 1 per branch: {wrong} wrong elements of 256");
Ok(())
}
fn uninit(stream: &Arc<CudaStream>, module: &kernels::LoadedModule) -> Result<(), Error> {
let n = 1024;
// SAFETY: none. Nothing writes `input` before the kernel reads it: the bug.
let input = unsafe { DeviceBuffer::<f32>::uninitialized_async(stream, n)? };
let total = DeviceBuffer::<f32>::zeroed(stream, 1)?.cast_elem::<DeviceAtomicF32>();
let launch = module.prepare_sum_unwritten(LaunchConfig1D::new(1, 32, 0))?;
module.sum_unwritten(stream, &launch, &input, &total)?;
let sum = total.cast_elem::<f32>().to_host_vec(stream)?[0];
println!("sum of 1,024 floats nobody wrote: {sum}");
Ok(())
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
match std::env::args().nth(1).as_deref() {
Some("race") => race(&stream, &module)?,
Some("barrier") => barrier(&stream, &module)?,
Some("uninit") => uninit(&stream, &module)?,
_ => return Err("usage: cargo oxide run -- race | barrier | uninit".into()),
}
ctx.synchronize()?;
Ok(())
}// Chapter 16: 4 bugs that print no error, for Compute Sanitizer to find.
// Build: nvcc -arch=native -lineinfo bugs.cu -o bugs
// Run: ./bugs bounds | race | barrier | uninit
#include <cstdio>
#include <cstdlib>
#include <cstring>
#include <vector>
#include <cuda_runtime.h>
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
// 1. Chapter 3's vector addition without its guard `if (i < n)`.
__global__ void addNoGuard(const float* a, const float* b, float* c, int n)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
c[i] = a[i] + b[i];
}
// 2. Chapter 5's block sum with its barriers left out.
__global__ void sumNoBarrier(const float* in, float* out)
{
__shared__ float s[256];
int t = threadIdx.x;
s[t] = in[blockIdx.x * 256 + t];
for (int stride = 128; stride > 0; stride /= 2) {
if (t < stride) {
s[t] += s[t + stride];
}
}
if (t == 0) {
out[blockIdx.x] = s[0];
}
}
// 3. Even and odd threads of each warp wait at 2 different barriers.
__global__ void barrierInBranch(float* out)
{
__shared__ float s[256];
int t = threadIdx.x;
s[t] = t;
if (t % 2 == 0) {
__syncthreads();
out[t] = s[255 - t];
} else {
__syncthreads();
out[t] = s[255 - t];
}
}
// 4. A sum over memory that nothing has written.
__global__ void sumUnwritten(const float* in, float* out, int n)
{
float sum = 0.0f;
for (int i = threadIdx.x; i < n; i += 32) {
sum += in[i];
}
atomicAdd(out, sum);
}
void bounds()
{
const int n = 1000;
std::vector<float> a(n, 1.0f), b(n, 2.0f), c(n);
size_t bytes = n * sizeof(float);
float *da, *db, *dc;
check(cudaMalloc(&da, bytes));
check(cudaMalloc(&db, bytes));
check(cudaMalloc(&dc, bytes));
check(cudaMemcpy(da, a.data(), bytes, cudaMemcpyHostToDevice));
check(cudaMemcpy(db, b.data(), bytes, cudaMemcpyHostToDevice));
addNoGuard<<<4, 256>>>(da, db, dc, n);
check(cudaGetLastError());
check(cudaMemcpy(c.data(), dc, bytes, cudaMemcpyDeviceToHost));
int wrong = 0;
for (int i = 0; i < n; ++i) {
wrong += c[i] != 3.0f;
}
std::printf("1,024 threads for 1,000 elements: %d wrong elements\n", wrong);
check(cudaFree(da));
check(cudaFree(db));
check(cudaFree(dc));
}
void race()
{
const int blocks = 64;
std::vector<float> in(blocks * 256, 1.0f), out(blocks);
float *din, *dout;
check(cudaMalloc(&din, in.size() * sizeof(float)));
check(cudaMalloc(&dout, blocks * sizeof(float)));
check(cudaMemcpy(din, in.data(), in.size() * sizeof(float), cudaMemcpyHostToDevice));
sumNoBarrier<<<blocks, 256>>>(din, dout);
check(cudaGetLastError());
check(cudaMemcpy(out.data(), dout, blocks * sizeof(float), cudaMemcpyDeviceToHost));
int wrong = 0;
for (float sum : out) {
wrong += sum != 256.0f;
}
std::printf("%d blocks of 256 ones: %d wrong block sums\n", blocks, wrong);
check(cudaFree(din));
check(cudaFree(dout));
}
void barrier()
{
std::vector<float> out(256);
float* dout;
check(cudaMalloc(&dout, 256 * sizeof(float)));
barrierInBranch<<<1, 256>>>(dout);
check(cudaGetLastError());
check(cudaMemcpy(out.data(), dout, 256 * sizeof(float), cudaMemcpyDeviceToHost));
int wrong = 0;
for (int t = 0; t < 256; ++t) {
wrong += out[t] != 255 - t;
}
std::printf("2 barriers, 1 per branch: %d wrong elements of 256\n", wrong);
check(cudaFree(dout));
}
void uninit()
{
const int n = 1024;
float *din, *dout;
check(cudaMalloc(&din, n * sizeof(float)));
check(cudaMalloc(&dout, sizeof(float)));
check(cudaMemset(dout, 0, sizeof(float)));
sumUnwritten<<<1, 32>>>(din, dout, n);
check(cudaGetLastError());
float sum;
check(cudaMemcpy(&sum, dout, sizeof(float), cudaMemcpyDeviceToHost));
std::printf("sum of 1,024 floats nobody wrote: %g\n", sum);
check(cudaFree(din));
check(cudaFree(dout));
}
int main(int argc, char** argv)
{
const char* bug = argc > 1 ? argv[1] : "";
if (std::strcmp(bug, "bounds") == 0) {
bounds();
} else if (std::strcmp(bug, "race") == 0) {
race();
} else if (std::strcmp(bug, "barrier") == 0) {
barrier();
} else if (std::strcmp(bug, "uninit") == 0) {
uninit();
} else {
std::fprintf(stderr, "usage: bugs bounds | race | barrier | uninit\n");
return 1;
}
check(cudaDeviceSynchronize());
return 0;
}
Listing 25.13 The complete measure programs. code/oxide/ch16_measure/src/main.rs and code/ch16_profiling/measure.cu
//! Chapter 16 in Rust: the GPU's limits, the warm-up effect, and a kernel report by hand.
//!
//! cargo oxide run
use cuda_core::sys::CUevent_flags_enum_CU_EVENT_DEFAULT as TIMING;
use cuda_core::sys::{CUdevice, CUdevice_attribute, cuDeviceGetAttribute};
use cuda_core::sys::{
CUdevice_attribute_enum_CU_DEVICE_ATTRIBUTE_CLOCK_RATE as SM_CLOCK,
CUdevice_attribute_enum_CU_DEVICE_ATTRIBUTE_GLOBAL_MEMORY_BUS_WIDTH as BUS_BITS,
CUdevice_attribute_enum_CU_DEVICE_ATTRIBUTE_L2_CACHE_SIZE as L2_BYTES,
CUdevice_attribute_enum_CU_DEVICE_ATTRIBUTE_MAX_REGISTERS_PER_MULTIPROCESSOR as REGS,
// shared memory per SM, in bytes
CUdevice_attribute_enum_CU_DEVICE_ATTRIBUTE_MAX_SHARED_MEMORY_PER_MULTIPROCESSOR as SHM,
CUdevice_attribute_enum_CU_DEVICE_ATTRIBUTE_MEMORY_CLOCK_RATE as MEM_CLOCK,
};
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, DriverError, IntoResult};
use cuda_core::LaunchConfig1D;
use cuda_device::{DisjointSlice, cuda_module, kernel, launch_contract, thread};
type Error = Box<dyn std::error::Error>;
#[cuda_module]
mod kernels {
use super::*;
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn fill(mut x: DisjointSlice<f32>) {
let i = thread::index_1d();
let k = i.get();
if let Some(v) = x.get_mut(i) {
*v = (k % 1000) as f32;
}
}
/// y = 2 x: reads 4 bytes and writes 4 bytes per element.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scale(x: &[f32], mut y: DisjointSlice<f32>) {
let i = thread::index_1d();
let k = i.get();
if let Some(v) = y.get_mut(i) {
*v = 2.0 * x[k];
}
}
}
/// The time of 1 launch of `scale`, in milliseconds, measured with 2 events.
fn time_scale(
stream: &CudaStream,
module: &kernels::LoadedModule,
x: &DeviceBuffer<f32>,
y: &mut DeviceBuffer<f32>,
) -> Result<f32, Error> {
let blocks = x.len().div_ceil(256) as u32;
let launch = module.prepare_scale(LaunchConfig1D::new(blocks, 256, 0))?;
let start = stream.record_event(Some(TIMING))?;
module.scale(stream, &launch, x, y)?;
let stop = stream.record_event(Some(TIMING))?;
stop.synchronize()?;
Ok(start.elapsed_ms(&stop)?)
}
/// Asks the driver for 1 integer attribute of `device`.
fn attribute(device: CUdevice, which: CUdevice_attribute) -> Result<i32, DriverError> {
let mut value = 0;
// SAFETY: `value` is a valid place for 1 integer; `device` came from a live context.
unsafe { cuDeviceGetAttribute(&mut value, which, device).result()? };
Ok(value)
}
/// Print the limits the GPU reports, and the peaks they imply.
fn limits(ctx: &CudaContext) -> Result<(), DriverError> {
let device = ctx.cu_device();
let (major, minor) = ctx.compute_capability()?;
let sms = ctx.multiprocessor_count()?;
let sm_clock_khz = attribute(device, SM_CLOCK)?;
let mem_clock_khz = attribute(device, MEM_CLOCK)?;
let bus_bits = attribute(device, BUS_BITS)?;
let shared_kib = attribute(device, SHM)? / 1024;
let l2_kib = attribute(device, L2_BYTES)? / 1024;
let registers = attribute(device, REGS)?;
let max_threads = ctx.max_threads_per_multiprocessor()?;
let name = ctx.device_name()?;
println!("{name}, compute capability {major}.{minor}");
println!(" SMs {sms:8}");
println!(" threads per SM, at most {max_threads:8}");
println!(" registers per SM {registers:8}");
println!(" shared memory per SM {shared_kib:8} KiB");
println!(" L2 cache {l2_kib:8} KiB");
println!(" SM clock {:8} MHz", sm_clock_khz / 1000);
println!(" memory clock {:8} MHz", mem_clock_khz / 1000);
println!(" memory bus {bus_bits:8} bits");
// 128 FP32 units per SM from compute capability 8.6; 2 FLOP per multiply-add.
let peak_gflops = sms as f64 * 128.0 * 2.0 * sm_clock_khz as f64 / 1e6;
// 2 transfers per memory clock (double data rate) of bus_bits / 8 bytes each.
let peak_gbs = 2.0 * mem_clock_khz as f64 * 1e3 * (bus_bits / 8) as f64 / 1e9;
println!(" FP32 peak from the clock {peak_gflops:8.0} GFLOP/s");
println!(" bandwidth from the clock {peak_gbs:8.1} GB/s");
Ok(())
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
limits(&ctx)?;
let n: usize = 64 << 20; // 67,108,864 floats, 256 MiB per array
let bytes = 2.0 * (n * size_of::<f32>()) as f64;
let mut x = DeviceBuffer::<f32>::zeroed(&stream, n)?;
let mut y = DeviceBuffer::<f32>::zeroed(&stream, n)?;
let fill = module.prepare_fill(LaunchConfig1D::new(n.div_ceil(256) as u32, 256, 0))?;
module.fill(&stream, &fill, &mut x)?;
stream.synchronize()?;
// The first 40 runs of y = 2 x.
let mut ms = Vec::with_capacity(40);
for _ in 0..40 {
let t = time_scale(&stream, &module, &x, &mut y)?;
ms.push(t);
}
println!("y = 2 x over 256 MiB, the first 40 runs in ms");
for (r, t) in ms.iter().enumerate() {
let end = if r % 10 == 9 { "\n" } else { "" };
print!(" {t:5.2}{end}");
}
let total: f64 = ms.iter().map(|&t| t as f64).sum();
let mean = total / ms.len() as f64;
let mut last = ms[20..].to_vec();
last.sort_by(f32::total_cmp);
let median = (last[9] + last[10]) / 2.0;
println!("mean of all 40 runs {mean:7.2} ms");
println!("median of runs 21 to 40 {median:7.2} ms");
// The report by hand: bytes moved / time.
let gbs = bytes / (median as f64 * 1e-3) / 1e9;
let mib = bytes / (1 << 20) as f64;
println!("bytes moved {mib:7.0} MiB");
println!("achieved bandwidth {gbs:7.1} GB/s");
let scale = module.prepare_scale(LaunchConfig1D::new(1, 256, 0))?;
let blocks = scale.function().max_active_blocks_per_multiprocessor(256, 0)?;
println!("blocks of 256 per SM {blocks:7} = {} threads", blocks * 256);
let result = y.to_host_vec(&stream)?;
let expected = |i: usize| 2.0 * (i % 1000) as f32;
let wrong = (0..n).filter(|&i| result[i] != expected(i)).count();
let verdict = if wrong == 0 { "PASSED" } else { "FAILED" };
println!("{verdict}: {wrong} of {n} elements wrong");
if wrong > 0 {
return Err("wrong elements".into());
}
Ok(())
}// Chapter 16: the GPU's limits, the warm-up effect, and a kernel report by hand.
// Build: nvcc -arch=native measure.cu -o measure
#include <algorithm>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cuda_runtime.h>
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
int attribute(cudaDeviceAttr attr)
{
int value;
check(cudaDeviceGetAttribute(&value, attr, 0));
return value;
}
__global__ void fill(float* x, int n)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
x[i] = i % 1000;
}
}
// y = 2 x: reads 4 bytes and writes 4 bytes per element.
__global__ void scale(const float* x, float* y, int n)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
y[i] = 2.0f * x[i];
}
}
// The time of 1 launch of `scale`, in milliseconds, measured with 2 events.
float timeScale(const float* x, float* y, int n)
{
cudaEvent_t start, stop;
check(cudaEventCreate(&start));
check(cudaEventCreate(&stop));
check(cudaEventRecord(start));
scale<<<(n + 255) / 256, 256>>>(x, y, n);
check(cudaEventRecord(stop));
check(cudaEventSynchronize(stop));
float ms;
check(cudaEventElapsedTime(&ms, start, stop));
check(cudaEventDestroy(start));
check(cudaEventDestroy(stop));
return ms;
}
// Print the limits the GPU reports, and the peaks they imply.
void limits()
{
cudaDeviceProp p;
check(cudaGetDeviceProperties(&p, 0));
int smClockKHz = attribute(cudaDevAttrClockRate);
int memClockKHz = attribute(cudaDevAttrMemoryClockRate);
int busBits = attribute(cudaDevAttrGlobalMemoryBusWidth);
size_t sharedKiB = p.sharedMemPerMultiprocessor / 1024;
std::printf("%s, compute capability %d.%d\n", p.name, p.major, p.minor);
std::printf(" SMs %8d\n", p.multiProcessorCount);
std::printf(" threads per SM, at most %8d\n", p.maxThreadsPerMultiProcessor);
std::printf(" registers per SM %8d\n", p.regsPerMultiprocessor);
std::printf(" shared memory per SM %8zu KiB\n", sharedKiB);
std::printf(" L2 cache %8d KiB\n", p.l2CacheSize / 1024);
std::printf(" SM clock %8d MHz\n", smClockKHz / 1000);
std::printf(" memory clock %8d MHz\n", memClockKHz / 1000);
std::printf(" memory bus %8d bits\n", busBits);
// 128 FP32 units per SM from compute capability 8.6; 2 FLOP per multiply-add.
double peakGflops = p.multiProcessorCount * 128 * 2.0 * smClockKHz / 1e6;
// 2 transfers per memory clock (double data rate) of busBits / 8 bytes each.
double peakGBs = 2.0 * memClockKHz * 1e3 * (busBits / 8) / 1e9;
std::printf(" FP32 peak from the clock %8.0f GFLOP/s\n", peakGflops);
std::printf(" bandwidth from the clock %8.1f GB/s\n", peakGBs);
}
int main()
{
limits();
const int n = 64 << 20; // 67,108,864 floats, 256 MiB per array
const double bytes = 2.0 * n * sizeof(float);
float *x, *y;
check(cudaMalloc(&x, n * sizeof(float)));
check(cudaMalloc(&y, n * sizeof(float)));
fill<<<(n + 255) / 256, 256>>>(x, n);
check(cudaDeviceSynchronize());
// The first 40 runs of y = 2 x.
std::vector<float> ms(40);
for (float& t : ms) {
t = timeScale(x, y, n);
}
std::printf("y = 2 x over 256 MiB, the first 40 runs in ms\n");
for (int r = 0; r < 40; ++r) {
const char* end = r % 10 == 9 ? "\n" : "";
std::printf(" %5.2f%s", ms[r], end);
}
double mean = 0.0;
for (float t : ms) {
mean += t / ms.size();
}
std::vector<float> last(ms.begin() + 20, ms.end());
std::sort(last.begin(), last.end());
float median = (last[9] + last[10]) / 2;
std::printf("mean of all 40 runs %7.2f ms\n", mean);
std::printf("median of runs 21 to 40 %7.2f ms\n", median);
// The report by hand: bytes moved / time.
double gbs = bytes / (median * 1e-3) / 1e9;
std::printf("bytes moved %7.0f MiB\n", bytes / (1 << 20));
std::printf("achieved bandwidth %7.1f GB/s\n", gbs);
int blocks;
check(cudaOccupancyMaxActiveBlocksPerMultiprocessor(&blocks, scale, 256, 0));
std::printf("blocks of 256 per SM %7d = %d threads\n", blocks, blocks * 256);
std::vector<float> result(n);
check(cudaMemcpy(result.data(), y, n * sizeof(float), cudaMemcpyDeviceToHost));
int wrong = 0;
for (int i = 0; i < n; ++i) {
wrong += result[i] != 2.0f * (i % 1000);
}
const char* verdict = wrong ? "FAILED" : "PASSED";
std::printf("%s: %d of %d elements wrong\n", verdict, wrong, n);
check(cudaFree(x));
check(cudaFree(y));
return wrong ? 1 : 0;
}
Listing 25.14 The complete latency programs. code/oxide/ch16_latency/src/main.rs and code/ch16_profiling/latency.cu
//! Chapter 16 in Rust: latencies in cycles, measured inside a kernel with clock64().
//!
//! cargo oxide run
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, LaunchConfig1D};
use cuda_device::{DisjointSlice, cuda_module, kernel, launch_contract, thread};
use cuda_device::{debug, float};
const STEPS: u32 = 4096;
type Error = Box<dyn std::error::Error>;
#[cuda_module]
mod kernels {
use super::*;
/// 1 thread, 1 chain: each multiply-add needs the result of the one before.
#[kernel]
#[launch_contract(domain = 1, block = (1, 1, 1))]
pub fn dependent_fma(
start: f32,
mut out: DisjointSlice<f32>,
mut cycles: DisjointSlice<u64>,
) {
let mut v = start;
let t0 = debug::clock64();
let mut k = 0;
#[unroll(16)]
while k < STEPS {
v = float::fma_rn_f32(v, 0.999, 1.0);
k += 1;
}
let t1 = debug::clock64();
if let Some(o) = out.get_mut(thread::index_1d()) {
*o = v;
}
if let Some(c) = cycles.get_mut(thread::index_1d()) {
*c = t1 - t0;
}
}
/// 1 thread, 4 chains: the multiply-adds of 1 step do not wait for each other.
#[kernel]
#[launch_contract(domain = 1, block = (1, 1, 1))]
pub fn independent_fma(
start: f32,
mut out: DisjointSlice<f32>,
mut cycles: DisjointSlice<u64>,
) {
let (mut v0, mut v1, mut v2, mut v3) = (start, start, start, start);
let t0 = debug::clock64();
let mut k = 0;
#[unroll(4)]
while k < STEPS / 4 {
v0 = float::fma_rn_f32(v0, 0.999, 1.0);
v1 = float::fma_rn_f32(v1, 0.999, 1.0);
v2 = float::fma_rn_f32(v2, 0.999, 1.0);
v3 = float::fma_rn_f32(v3, 0.999, 1.0);
k += 1;
}
let t1 = debug::clock64();
if let Some(o) = out.get_mut(thread::index_1d()) {
*o = v0 + v1 + v2 + v3;
}
if let Some(c) = cycles.get_mut(thread::index_1d()) {
*c = t1 - t0;
}
}
/// 1 thread follows a chain of indices; the first `warm` hops are not timed.
#[kernel]
#[launch_contract(domain = 1, block = (1, 1, 1))]
pub fn chase(
next: &[u32],
warm: u32,
hops: u32,
mut out: DisjointSlice<u32>,
mut cycles: DisjointSlice<u64>,
) {
let mut j = 0;
let mut k = 0;
while k < warm {
// SAFETY: the host builds every entry of `next` below next.len().
j = unsafe { *next.get_unchecked(j as usize) };
k += 1;
}
let t0 = debug::clock64();
k = 0;
while k < hops {
// SAFETY: as above.
j = unsafe { *next.get_unchecked(j as usize) };
k += 1;
}
let t1 = debug::clock64();
if let Some(o) = out.get_mut(thread::index_1d()) {
*o = j;
}
if let Some(c) = cycles.get_mut(thread::index_1d()) {
*c = t1 - t0;
}
}
}
/// Cycles per load along a chain of `count` indices, each pointing `stride` ahead,
/// and whether the chain ended where the host expects.
fn chase_cycles(
stream: &CudaStream,
module: &kernels::LoadedModule,
count: u32,
stride: u32,
warm: u32,
hops: u32,
) -> Result<(f64, bool), Error> {
let chain: Vec<u32> = (0..count).map(|i| (i + stride) % count).collect();
let next = DeviceBuffer::from_host(stream, &chain)?;
let mut out = DeviceBuffer::<u32>::zeroed(stream, 1)?;
let mut cycles = DeviceBuffer::<u64>::zeroed(stream, 1)?;
let one = module.prepare_chase(LaunchConfig1D::new(1, 1, 0))?;
module.chase(stream, &one, &next, warm, hops, &mut out, &mut cycles)?;
let cycles = cycles.to_host_vec(stream)?[0] as f64 / hops as f64;
let end = out.to_host_vec(stream)?[0] as u64;
let expected = (warm + hops) as u64 * stride as u64 % count as u64;
Ok((cycles, end == expected))
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let mut out = DeviceBuffer::<f32>::zeroed(&stream, 1)?;
let mut cycles = DeviceBuffer::<u64>::zeroed(&stream, 1)?;
let one = LaunchConfig1D::new(1, 1, 0);
let dep = module.prepare_dependent_fma(one)?;
module.dependent_fma(&stream, &dep, 0.0, &mut out, &mut cycles)?;
let dependent = cycles.to_host_vec(&stream)?[0] as f64 / STEPS as f64;
let ind = module.prepare_independent_fma(one)?;
module.independent_fma(&stream, &ind, 0.0, &mut out, &mut cycles)?;
let independent = cycles.to_host_vec(&stream)?[0] as f64 / STEPS as f64;
println!("{STEPS} multiply-adds in 1 thread, cycles per multiply-add");
println!(" 1 dependent chain {dependent:6.2}");
println!(" 4 independent chains {independent:6.2}");
// 128-byte steps (32 indices), so that every load touches a new cache line.
// The DRAM chain jumps 1 MiB + 128 bytes per load and is not warmed first.
let (l1, ok1) = chase_cycles(&stream, &module, 1024, 32, 1024, 4096)?;
let (l2, ok2) = chase_cycles(&stream, &module, 256 << 10, 32, 8192, 8192)?;
let (dram, ok3) = chase_cycles(&stream, &module, 64 << 20, (1 << 18) + 32, 0, 4096)?;
println!("1 thread follows a chain of loads, cycles per load");
println!(" 4 KiB chain, from L1 {l1:6.0}");
println!(" 1 MiB chain, from L2 {l2:6.0}");
println!(" 256 MiB chain, from DRAM {dram:6.0}");
let wrong = [ok1, ok2, ok3].iter().filter(|ok| !**ok).count();
if wrong == 0 {
println!("PASSED: every chain ends where the host expects");
Ok(())
} else {
Err(format!("FAILED: {wrong} of 3 chains end in the wrong place").into())
}
}// Chapter 16: latencies in clock cycles, measured inside a kernel with clock64().
// Build: nvcc -arch=native latency.cu -o latency
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cuda_runtime.h>
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
const int STEPS = 4096;
// 1 thread, 1 chain: each multiply-add needs the result of the one before.
__global__ void dependentFma(float* x, long long* cycles)
{
float v = x[0];
long long t0 = clock64();
for (int k = 0; k < STEPS; ++k) {
v = fmaf(v, 0.999f, 1.0f);
}
long long t1 = clock64();
x[0] = v;
cycles[0] = t1 - t0;
}
// 1 thread, 4 chains: the 4 multiply-adds of a step do not wait for each other.
__global__ void independentFma(float* x, long long* cycles)
{
float v0 = x[0], v1 = x[1], v2 = x[2], v3 = x[3];
long long t0 = clock64();
for (int k = 0; k < STEPS / 4; ++k) {
v0 = fmaf(v0, 0.999f, 1.0f);
v1 = fmaf(v1, 0.999f, 1.0f);
v2 = fmaf(v2, 0.999f, 1.0f);
v3 = fmaf(v3, 0.999f, 1.0f);
}
long long t1 = clock64();
x[0] = v0 + v1 + v2 + v3;
cycles[0] = t1 - t0;
}
// 1 thread follows a chain: each load needs the index the load before returned.
// The first `warm` hops bring the chain into the caches; the next `hops` are timed.
__global__ void chase(const int* next, int warm, int hops, int* out, long long* cycles)
{
int j = 0;
for (int k = 0; k < warm; ++k) {
j = next[j];
}
long long t0 = clock64();
for (int k = 0; k < hops; ++k) {
j = next[j];
}
long long t1 = clock64();
out[0] = j;
cycles[0] = t1 - t0;
}
// Cycles per load along a chain of `count` ints, each pointing `stride` ints ahead.
// Counts in `wrong` a chain that does not end where the host expects.
double chaseCycles(int count, int stride, int warm, int hops, int& wrong)
{
std::vector<int> next(count);
for (int i = 0; i < count; ++i) {
next[i] = (i + stride) % count;
}
int *dnext, *dout;
long long* dcycles;
check(cudaMalloc(&dnext, count * sizeof(int)));
check(cudaMalloc(&dout, sizeof(int)));
check(cudaMalloc(&dcycles, sizeof(long long)));
check(cudaMemcpy(dnext, next.data(), count * sizeof(int), cudaMemcpyHostToDevice));
chase<<<1, 1>>>(dnext, warm, hops, dout, dcycles);
check(cudaGetLastError());
long long cycles;
int end;
check(cudaMemcpy(&cycles, dcycles, sizeof(long long), cudaMemcpyDeviceToHost));
check(cudaMemcpy(&end, dout, sizeof(int), cudaMemcpyDeviceToHost));
wrong += end != (long long)(warm + hops) * stride % count;
check(cudaFree(dnext));
check(cudaFree(dout));
check(cudaFree(dcycles));
return double(cycles) / hops;
}
int main()
{
float* x;
long long* dcycles;
check(cudaMalloc(&x, 4 * sizeof(float)));
check(cudaMalloc(&dcycles, sizeof(long long)));
check(cudaMemset(x, 0, 4 * sizeof(float)));
long long dep, ind;
size_t size = sizeof(long long);
dependentFma<<<1, 1>>>(x, dcycles);
check(cudaMemcpy(&dep, dcycles, size, cudaMemcpyDeviceToHost));
independentFma<<<1, 1>>>(x, dcycles);
check(cudaMemcpy(&ind, dcycles, size, cudaMemcpyDeviceToHost));
std::printf("%d multiply-adds in 1 thread, cycles per multiply-add\n", STEPS);
std::printf(" 1 dependent chain %6.2f\n", double(dep) / STEPS);
std::printf(" 4 independent chains %6.2f\n", double(ind) / STEPS);
// 128-byte steps (32 ints), so that every load touches a new cache line.
// The DRAM chain jumps 1 MiB + 128 bytes per load and is not warmed first.
int wrong = 0;
double l1 = chaseCycles(1024, 32, 1024, 4096, wrong); // 4 KiB, L1
double l2 = chaseCycles(256 << 10, 32, 8192, 8192, wrong); // 1 MiB, L2
double dram = chaseCycles(64 << 20, (1 << 18) + 32, 0, 4096, wrong); // 256 MiB
std::printf("1 thread follows a chain of loads, cycles per load\n");
std::printf(" 4 KiB chain, from L1 %6.0f\n", l1);
std::printf(" 1 MiB chain, from L2 %6.0f\n", l2);
std::printf(" 256 MiB chain, from DRAM %6.0f\n", dram);
const char* verdict = wrong ? "FAILED" : "PASSED";
std::printf("%s: %d of 3 chains end in the wrong place\n", verdict, wrong);
check(cudaFree(x));
check(cudaFree(dcycles));
return wrong ? 1 : 0;
}
Listing 25.15 The complete verify programs. code/oxide/ch16_verify/src/main.rs and code/ch16_profiling/verify.cu
//! Chapter 16 in Rust: GPU results against the CPU, with a tolerance worked out in advance.
//!
//! cargo oxide run
use std::f32::consts::LOG2_E;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, LaunchConfig1D};
use cuda_device::{DisjointSlice, SharedArray, cuda_module, float, kernel, launch_contract};
use cuda_device::thread;
type Error = Box<dyn std::error::Error>;
#[cuda_module]
mod kernels {
use super::*;
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn exp_accurate(x: &[f32], mut y: DisjointSlice<f32>) {
let i = thread::index_1d();
let k = i.get();
if let Some(v) = y.get_mut(i) {
*v = x[k].exp();
}
}
/// exp(x) as 2^(x log2 e), with the hardware's approximate 2^x, as __expf computes it.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn exp_fast(x: &[f32], mut y: DisjointSlice<f32>) {
let i = thread::index_1d();
let k = i.get();
if let Some(v) = y.get_mut(i) {
*v = float::ex2_approx_ftz_f32(x[k] * LOG2_E);
}
}
/// Each thread sums a strided share of x; the block adds the 256 sums as a tree.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum(x: &[f32], n: u32, mut block_sums: DisjointSlice<f32>) {
static mut S: SharedArray<f32, 256> = SharedArray::UNINIT;
let t = thread::threadIdx_x() as usize;
let block = thread::blockIdx_x() as usize;
let grid = thread::gridDim_x() as usize * 256;
let mut v = 0.0;
let mut i = block * 256 + t;
while i < n as usize {
v += x[i];
i += grid;
}
// SAFETY: each thread writes only its own cell, before the barrier.
unsafe { S[t] = v };
thread::sync_threads();
let mut step: usize = 0;
#[unroll]
while step < 8 {
let stride: usize = 128 >> step;
if t < stride {
// SAFETY: in this step thread t alone writes cell t, and it reads cell
// t + stride, which no thread writes in this step.
unsafe { S[t] += S[t + stride] };
}
thread::sync_threads();
step += 1;
}
if t == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *block_sums.get_unchecked_mut(block) = S[0] };
}
}
}
/// The number of floats between a and b, for 2 floats of the same sign.
fn ulps(a: f32, b: f32) -> i64 {
let ia = a.to_bits() as i32 as i64;
let ib = b.to_bits() as i32 as i64;
(ia - ib).abs()
}
/// The largest distance in ULPs between y and the nearest float to exp(x).
fn exp_error(x: &[f32], y: &[f32]) -> i64 {
let mut worst = 0;
for (&x, &y) in x.iter().zip(y) {
let exact = (x as f64).exp() as f32;
worst = worst.max(ulps(y, exact));
}
worst
}
/// 2 launches: 1,024 blocks write 1,024 partial sums, then 1 block adds them.
fn gpu_sum(
stream: &CudaStream,
module: &kernels::LoadedModule,
x: &DeviceBuffer<f32>,
n: u32,
partial: &mut DeviceBuffer<f32>,
total: &mut DeviceBuffer<f32>,
) -> Result<f32, Error> {
let many = module.prepare_sum(LaunchConfig1D::new(1024, 256, 0))?;
let one = module.prepare_sum(LaunchConfig1D::new(1, 256, 0))?;
module.sum(stream, &many, x, n, partial)?;
module.sum(stream, &one, partial, 1024, total)?;
Ok(total.to_host_vec(stream)?[0])
}
fn exp_test(stream: &CudaStream, module: &kernels::LoadedModule) -> Result<(), Error> {
let n = 1 << 20;
let point = |i: usize| -10.0 + 20.0 * i as f32 / n as f32;
let x: Vec<f32> = (0..n).map(point).collect();
let dx = DeviceBuffer::from_host(stream, &x)?;
let mut dy = DeviceBuffer::<f32>::zeroed(stream, n)?;
let blocks = n.div_ceil(256) as u32;
println!("y = exp(x) for 1,048,576 values of x in [-10, 10)");
let accurate = module.prepare_exp_accurate(LaunchConfig1D::new(blocks, 256, 0))?;
module.exp_accurate(stream, &accurate, &dx, &mut dy)?;
let y = dy.to_host_vec(stream)?;
let error = exp_error(&x, &y);
println!(" exp largest error {error:3} ULPs");
let fast = module.prepare_exp_fast(LaunchConfig1D::new(blocks, 256, 0))?;
module.exp_fast(stream, &fast, &dx, &mut dy)?;
let y = dy.to_host_vec(stream)?;
let error = exp_error(&x, &y);
println!(" ex2_approx largest error {error:3} ULPs");
Ok(())
}
fn verdict(error: f64, tolerance: f64) -> &'static str {
if error <= tolerance { "PASSED" } else { "FAILED" }
}
/// Sum x on the GPU twice: correctly, and as a caller passing 1 element too few.
fn sum_test(
stream: &CudaStream,
module: &kernels::LoadedModule,
title: &str,
x: &[f32],
tolerance: f64,
) -> Result<(), Error> {
let n = x.len() as u32;
let dx = DeviceBuffer::from_host(stream, x)?;
let mut partial = DeviceBuffer::<f32>::zeroed(stream, 1024)?;
let mut total = DeviceBuffer::<f32>::zeroed(stream, 1)?;
let exact: f64 = x.iter().map(|&v| v as f64).sum();
let good_sum = gpu_sum(stream, module, &dx, n, &mut partial, &mut total)?;
let bad_sum = gpu_sum(stream, module, &dx, n - 1, &mut partial, &mut total)?;
let good = (good_sum as f64 - exact).abs();
let bad = (bad_sum as f64 - exact).abs();
let good_verdict = verdict(good, tolerance);
let bad_verdict = verdict(bad, tolerance);
println!("{title}");
println!(" exact sum {exact:12.2}");
println!(" tolerance {tolerance:12.2}");
println!(" n elements error {good:6.2} {good_verdict}");
println!(" n - 1 elements error {bad:6.2} {bad_verdict}");
Ok(())
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
exp_test(&stream, &module)?;
let n = 1 << 24;
let mut state: u32 = 1;
let mut magnitude = 0.0;
let mut random = Vec::with_capacity(n);
for _ in 0..n {
state = state.wrapping_mul(1_664_525).wrapping_add(1_013_904_223);
let v = (state >> 8) as f32 / 16_777_216.0;
magnitude += v as f64;
random.push(v);
}
// Each element passes through at most 84 additions on the way to the total:
// 64 + 8 in launch 1, 4 + 8 in launch 2. Each rounds by 2^-24 of its sum at most.
let bound = 84.0 * 2f64.powi(-24) * magnitude;
let title = "sum of 16,777,216 random floats in [0, 1)";
sum_test(&stream, &module, title, &random, bound)?;
// Partial sums of ones are whole numbers up to 2^24, which floats hold exactly.
let ones = vec![1.0f32; n];
sum_test(&stream, &module, "sum of 16,777,216 ones", &ones, 0.0)?;
Ok(())
}// Chapter 16: GPU results against the CPU, with a tolerance worked out in advance.
// Build: nvcc -arch=native verify.cu -o verify
#include <cmath>
#include <cstdint>
#include <cstdio>
#include <cstdlib>
#include <cstring>
#include <vector>
#include <cuda_runtime.h>
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
__global__ void expAccurate(const float* x, float* y, int n)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
y[i] = expf(x[i]);
}
}
__global__ void expFast(const float* x, float* y, int n)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
y[i] = __expf(x[i]);
}
}
// Each thread sums a strided share of x; the block adds the 256 sums as a tree.
__global__ void sum(const float* x, int n, float* blockSums)
{
__shared__ float s[256];
int t = threadIdx.x;
float v = 0.0f;
for (int i = blockIdx.x * 256 + t; i < n; i += gridDim.x * 256) {
v += x[i];
}
s[t] = v;
__syncthreads();
for (int stride = 128; stride > 0; stride /= 2) {
if (t < stride) {
s[t] += s[t + stride];
}
__syncthreads();
}
if (t == 0) {
blockSums[blockIdx.x] = s[0];
}
}
// The number of floats between a and b, for 2 floats of the same sign.
int64_t ulps(float a, float b)
{
int32_t ia, ib;
std::memcpy(&ia, &a, sizeof(float));
std::memcpy(&ib, &b, sizeof(float));
return std::llabs(int64_t(ia) - int64_t(ib));
}
// The largest distance in ULPs between y and the nearest float to exp(x).
int64_t expError(const std::vector<float>& x, const std::vector<float>& y)
{
int64_t worst = 0;
for (size_t i = 0; i < x.size(); ++i) {
float exact = float(std::exp(double(x[i])));
worst = std::max(worst, ulps(y[i], exact));
}
return worst;
}
// 2 launches: 1,024 blocks write 1,024 partial sums, then 1 block adds them.
float gpuSum(const float* dx, int n, float* partial)
{
sum<<<1024, 256>>>(dx, n, partial);
sum<<<1, 256>>>(partial, 1024, partial + 1024);
check(cudaGetLastError());
float total;
check(cudaMemcpy(&total, partial + 1024, sizeof(float), cudaMemcpyDeviceToHost));
return total;
}
void expTest()
{
const int n = 1 << 20;
std::vector<float> x(n), y(n);
for (int i = 0; i < n; ++i) {
x[i] = -10.0f + 20.0f * i / n;
}
float *dx, *dy;
check(cudaMalloc(&dx, n * sizeof(float)));
check(cudaMalloc(&dy, n * sizeof(float)));
check(cudaMemcpy(dx, x.data(), n * sizeof(float), cudaMemcpyHostToDevice));
int blocks = (n + 255) / 256;
std::printf("y = exp(x) for 1,048,576 values of x in [-10, 10)\n");
expAccurate<<<blocks, 256>>>(dx, dy, n);
check(cudaMemcpy(y.data(), dy, n * sizeof(float), cudaMemcpyDeviceToHost));
std::printf(" expf largest error %3lld ULPs\n", (long long)expError(x, y));
expFast<<<blocks, 256>>>(dx, dy, n);
check(cudaMemcpy(y.data(), dy, n * sizeof(float), cudaMemcpyDeviceToHost));
std::printf(" __expf largest error %3lld ULPs\n", (long long)expError(x, y));
check(cudaFree(dx));
check(cudaFree(dy));
}
const char* verdict(double error, double tolerance)
{
return error <= tolerance ? "PASSED" : "FAILED";
}
// Sum x on the GPU twice: correctly, and as a caller passing 1 element too few.
void sumTest(const char* title, const std::vector<float>& x, double tolerance)
{
int n = x.size();
float *dx, *partial;
check(cudaMalloc(&dx, n * sizeof(float)));
check(cudaMalloc(&partial, 1025 * sizeof(float)));
check(cudaMemcpy(dx, x.data(), n * sizeof(float), cudaMemcpyHostToDevice));
double exact = 0.0;
for (float v : x) {
exact += v;
}
double good = std::fabs(gpuSum(dx, n, partial) - exact);
double bad = std::fabs(gpuSum(dx, n - 1, partial) - exact);
std::printf("%s\n", title);
std::printf(" exact sum %12.2f\n", exact);
std::printf(" tolerance %12.2f\n", tolerance);
std::printf(" n elements error %6.2f %s\n", good, verdict(good, tolerance));
std::printf(" n - 1 elements error %6.2f %s\n", bad, verdict(bad, tolerance));
check(cudaFree(dx));
check(cudaFree(partial));
}
int main()
{
expTest();
const int n = 1 << 24;
std::vector<float> random(n), ones(n, 1.0f);
uint32_t state = 1;
double magnitude = 0.0;
for (float& v : random) {
state = state * 1664525u + 1013904223u;
v = (state >> 8) / 16777216.0f;
magnitude += v;
}
// Each element passes through at most 84 additions on the way to the total:
// 64 + 8 in launch 1, 4 + 8 in launch 2. Each rounds by 2^-24 of its sum at most.
double bound = 84 * std::ldexp(1.0, -24) * magnitude;
sumTest("sum of 16,777,216 random floats in [0, 1)", random, bound);
// Partial sums of ones are whole numbers up to 2^24, which floats hold exactly.
sumTest("sum of 16,777,216 ones", ones, 0.0);
return 0;
}
Common mistakes
- Tuning a kernel before reading the timeline. In section 25.1.2, a kernel twice as fast saved 5.20 ms, while overlapping the copies saved 7.36 ms without changing the kernel.
- Trusting a clean exit. The out-of-bounds kernel produced correct output and exit status 0. The 2 barriers in 2 branches did the same on 1 GPU and hung another.
- Timing under a tool. memcheck made a load 217 times as slow, and the replay of
ncuchanges the caches between runs. Time kernels with events in an ordinary run. - Timing a cold kernel. The first run took 19.83 ms, and the warm runs 8.35 ms.
- Reporting the mean of a few runs. 4 outliers and 8 warm-up runs pulled the mean 1.11 ms above the median.
- Dividing by a computed peak. Each GPU reported 1 attribute that gives a wrong peak rate. Use the data sheet.
- A tolerance with no unit or no derivation. Count ULPs for single operations, derive the bound for sums, and add known-answer inputs with a tolerance of 0.
- Changing two things between measurements. The first fix of the Rust chase changed two things, and only a second measurement showed which one mattered.
- Profiling a debug build.
-Gturns off optimization. Profile the build that will run, built with-lineinfofor source lines.
Summary
- A trace records when each copy and kernel ran, and hardware counters record what happened inside a kernel. Nsight Systems reads the first and Nsight Compute the second, and the timeline comes first.
- The trace of Chapter 6’s pipeline accounted for the whole run: 0.66 ms + 10.61 ms + 0.90 ms of copies and kernels and 1.42 ms of gaps made up the 13.59 ms. The gaps came from the order of operations within a stream.
- A speed-of-light analysis can also be done by hand from the GPU’s limits and an event time.
y = 2 xused 63% of the GPU’s memory bandwidth and 0.33% of its arithmetic peak. - Compute Sanitizer found 4 bugs that printed no error: accesses to padding, a race between warps, 2 barriers in 2 branches, and a read of unwritten memory.
clock64()measured 4.24 cycles per dependent multiply-add, 39 cycles for a load from L1, 191 cycles from L2 and 598 to 1,137 cycles from DRAM, in C++ and in Rust.- Warm up, report medians, use events, use data larger than the L2 cache, check that the machine is idle, and verify the output.
- Count floating-point errors in ULPs, derive tolerances from error bounds, and add known-answer and property tests, which a tolerance cannot replace.
- Measure, form a hypothesis, change one thing, measure again, and verify.
In Chapter 26, we move from the single program to the GPU as a device in the whole system: how the CPU reaches the GPU’s registers, and how the GPU’s copy engines reach memory.
Exercises
- Account for the 1-stream run of Figure 25.2 in the way we accounted for the 2-stream run in section 25.2.2. What fraction of the run did each lane spend busy?
- Issue all 8 copies in of the 2-stream pipeline before any kernel, or use 3 streams, and trace the program again. Do the 3 gaps of 0.47 ms disappear? Account for the new total.
- Profile
sgemmof Chapter 9 withncuon a machine where you can read counters. Compare theSpeedOfLightpercentages with Figure 25.3, and find how much of the patch kernel’s 8 GiB of loads came from DRAM. - Change
bugs.cuto use 1,010 elements. Which elements of which array does the unguarded kernel now overwrite? Predict the answer, then check it with memcheck. - Put the 2 barriers of Listing 25.5 into a block of 64 threads in which the 2 branches fall in
different warps (for example,
t < 32). Does synccheck still report an error? Explain. Run the program under synccheck first, because the plain program may hang, as it did on the first GPU. - Extend
latency.cuwith a chain of 16 MiB. Where does its latency fall between the L2 and DRAM figures on a GPU with a 2 MiB L2 cache, and on one with a 40 MiB L2 cache? - Run
measuretwice in a row, then again after 5 minutes of idle time. Compare the first 10 runs of each, and explain the difference. - Derive the tolerance of
verify.cu’s sum for 226 elements. Then construct an input with a known exact sum other than all ones, and use it to detect the \(n - 1\) bug. - Compile
verify.cuwith--use_fast_math. Which line of its output changes, and why?
Sources and further reading
- NVIDIA, Nsight Systems User Guide: https://docs.nvidia.com/nsight-systems/UserGuide/
- NVIDIA, Nsight Compute Profiling Guide, “Metrics Structure”, “Replay” and the sections
SpeedOfLight,OccupancyandWarpStateStats: https://docs.nvidia.com/nsight-compute/ - NVIDIA, Compute Sanitizer User Manual: https://docs.nvidia.com/compute-sanitizer/
- NVIDIA, CUDA-GDB: https://docs.nvidia.com/cuda/cuda-gdb/
- NVIDIA, “ERR_NVGPUCTRPERM: Permission issue with Performance Counters”: https://developer.nvidia.com/ERR_NVGPUCTRPERM
- H. Naghibijouybari, A. Neupane, Z. Qian and N. Abu-Ghazaleh, “Rendered Insecure: GPU Side Channel Attacks are Practical”, ACM CCS 2018: the attack behind CVE-2018-6260.
- NVIDIA, CUDA C++ Programming Guide, “Mathematical Functions” (error bounds of
expfand__expf) and “Synchronization Functions”: https://docs.nvidia.com/cuda/cuda-c-programming-guide/ - D. Goldberg, “What Every Computer Scientist Should Know About Floating-Point Arithmetic”, ACM Computing Surveys 23(1), 1991.
- N. J. Higham, Accuracy and Stability of Numerical Algorithms, 2nd ed., SIAM, 2002, chapter 4 (summation).
- H. Wong et al., “Demystifying GPU Microarchitecture through Microbenchmarking”, ISPASS 2010:
pointer chases and
clock()on a GPU.
Chapter 26: GPU Systems Programming & Memory-Mapped I/O
So far, we have used the GPU only through the CUDA API. cudaMalloc returns a pointer,
cudaMemcpy moves data, and a kernel launch with <<<grid, block>>> returns to the host after
a few microseconds while the kernel continues to run on the device. In Chapter 6, we measured a
launch at 3.77 µs. Because the CPU and the GPU are separate devices, a launch cannot be an
ordinary function call: the CPU must deliver the work to the GPU through the hardware that
connects them. The driver is the software that operates the GPU on behalf of programs; in section
26.7 we show that it consists of 2 parts. In this chapter, we study the hardware that connects the
CPU and the GPU and the way the driver uses it.
We start with the physical addresses through which a CPU reaches any device, and with the way the operating system finds a GPU and the address ranges that the GPU occupies. We then look at the two ways in which the CPU and the GPU exchange information: small stores into the GPU’s registers, called memory-mapped I/O, and bulk transfers that the GPU performs by itself, called direct memory access. With these mechanisms in place, we follow a kernel launch from the CPU to the GPU’s streaming multiprocessors (SMs), the processors that run the threads of a kernel, and we build a working model of the mechanism with 2 CPU threads, in C++ and in Rust.
This chapter covers
- physical addresses, and memory-mapped I/O: devices that answer to addresses
- PCIe devices, their configuration space and their base address registers (BARs)
- Three ways to attach a GPU: a discrete card on PCIe, an integrated GPU presented as a PCIe function, and an integrated GPU described by the device tree
- the control path (MMIO) and the data path (DMA), and why they differ
- cached, write-combined and device memory, measured from the CPU
- work rings and doorbells: how a kernel launch reaches the GPU without a system call
- the order of writes before a doorbell, and the errors that a wrong order causes
- the IOMMU, which checks every address a device uses
- the kernel-mode and user-mode drivers, and how to observe all of it on Linux
The code of the chapter is in
code/ch17_systems/
for C++ and in
code/oxide/ch17_systems/
for Rust. Neither needs root, the administrator account of Linux: everything we show in the
chapter can be read by an ordinary user.
26.1 The GPU is a device on a bus
26.1.1 Physical addresses and memory-mapped I/O
A processor names every byte it reads or writes by a number, its address. The addresses that a program uses are virtual: each process has its own, and the same virtual address in 2 processes may name 2 different bytes. The processor’s memory management unit (MMU) translates each virtual address into a physical address: the number that leaves the core and travels on the chip’s internal buses. The MMU translates in units of pages, blocks of usually 4 KiB, and it reads the translation of each page from the page tables that the operating system keeps. For example, with pages of 4 KiB = 0x1000 bytes, the virtual address 0x7F12_3456 lies in virtual page 0x7F123 at offset 0x456. If the page table maps that page to physical page 0x80042, the physical address is 0x8004_2456: the page number changes, and the offset within the page stays. The set of all physical addresses is the physical address space. On a 64-bit Arm or x86 machine it spans far more numbers than the machine has bytes of memory, and most physical addresses lead nowhere.
The chip’s interconnect, the network of internal buses that joins the cores to everything else, decides where each physical address goes. Some ranges lead to the memory controllers and so to DRAM, the main memory. Other ranges lead to devices: a disk controller, a network card, the GPU. A register of a device is a small storage location inside the device, often 4 bytes, whose contents control the device or report its state.
To see how a device can be reached by address, consider a small machine that we invent for the purpose, whose physical addresses run from 0x0000 to 0xFFFF. Its interconnect sends the addresses 0x0000 to 0x7FFF to DRAM, and the addresses 0x8000 to 0x80FF to a device with 64 registers of 4 bytes each. A store of the value 1 to address 0x0010 writes 1 into DRAM, and a later load from 0x0010 returns the 1. A store of the value 1 to address 0x8004 instead reaches the device: 0x8004 − 0x8000 = 4 bytes past the start of its range, which is register 1. If register 1 is the device’s “start” register, the store starts the device. Both stores are the same instruction; only the address differs.
Definition 26.1 Memory-mapped I/O. Memory-mapped I/O, or MMIO, is the arrangement in which a range of physical addresses leads to the registers of a device, so that a load from one of those addresses reads a register and a store writes one. The device is operated with the same load and store instructions that work on memory, and the address alone decides whether an instruction reaches DRAM or a device.
Example. In the small machine above, a store to 0x8004 writes register 1 of the device, while a store to 0x0010 writes DRAM.
Figure 26.1 shows the ranges that matter to this chapter on a Jetson Orin NX, a machine whose
GPU is built into the processor chip. They come from the machine’s device tree, a
description of the hardware that the firmware, the program stored on the board that starts
the machine, hands to Linux at boot. The device tree holds 1 node for each built-in device,
and each node holds named properties. The property reg lists the physical addresses of the
device’s registers.
The GPU’s node in that device tree holds 3 pairs of (address, size). Read as raw
bytes, its reg property is:
$ xxd -g4 /sys/firmware/devicetree/base/bus@0/gpu@17000000/reg
00000000: 00000000 17000000 00000000 01000000 ................
00000010: 00000000 18000000 00000000 01000000 ................
00000020: 00000000 03b41000 00000000 00001000 ................
Each number in the property is written as 2 words of 32 bits, high word first, and each row holds an address followed by a size. A window is a range of physical addresses that leads to 1 device. The first row therefore describes a window at 0x1700_0000 of 0x0100_0000 = 16,777,216 bytes, or 16 MiB. The second row describes another 16 MiB window at 0x1800_0000, and the third a window of 0x1000 = 4,096 bytes at 0x03B4_1000.
The word kernel has 2 meanings in this chapter. The operating-system kernel is the part of the
operating system that runs with full privileges and controls the hardware; we call it “the
kernel”. A GPU kernel, the function that runs on the GPU, appears mostly in the phrase “kernel
launch”. The Linux kernel’s binding for this family of GPUs, the document that states what
the device tree must say about such a device, names the first 2 windows bar0 and bar1, after
the BARs of a PCIe GPU that we introduce in section 26.2.
A store by the CPU to 0x1700_0000 + \(r\) writes the GPU’s register at offset \(r\) of
bar0. The driver, not a program, decides which offsets to touch; in section 26.7 we show how the
operating system keeps ordinary programs away from these addresses.
26.1.2 PCIe: links, functions and addresses
Most devices in a computer are attached to the processor chip through PCIe (PCI Express), the standard connection for expansion devices. In Section 4.1.2, we described its physical side: a link of 1 to 16 lanes, each lane a pair of wires in each direction, carrying about 2 GB/s each way per lane in generation 4.0 and 4 GB/s in 5.0.
In this chapter, we need its logical side. PCIe carries transactions, packets with a type, an address and data. A CPU store to an address inside a device’s window becomes a memory write transaction that travels down the link. A CPU load becomes a memory read transaction, and the device answers with a completion packet that carries the data back. For example, a CPU store of the 4-byte value 1 to offset 0x10 of a device’s window becomes 1 packet that says “memory write, address = window start + 0x10, data = 1”. A CPU load from the same address becomes 2 packets: a “memory read, address = window start + 0x10, length 4” that travels to the device, and a completion with the 4 bytes that travels back. The root complex is the part of the processor chip that turns the CPU’s loads and stores into transactions and back; each of its connectors is a root port. A device at the end of a link is an endpoint.
Each endpoint holds one or more functions, logical devices with their own registers. A
function is named by 4 numbers, written domain:bus:device.function. A domain is 1 separate
tree of PCIe buses, here 1 per root port, and a bus is 1 level of links within that tree. An
NVMe drive is a solid-state disk that is attached by PCIe and follows the NVM Express
standard. The NVMe drive of the same machine is 0004:01:00.0, domain 4, bus 1, device 0,
function 0. lspci lists every function the kernel found:
$ lspci # Orin NX
0001:00:00.0 PCI bridge: NVIDIA Corporation Device 229e (rev a1)
0001:01:00.0 Network controller: Realtek ... RTL8822CE 802.11ac PCIe Wireless Network Adapter
0004:00:00.0 PCI bridge: NVIDIA Corporation Device 229c (rev a1)
0004:01:00.0 Non-Volatile memory controller: Samsung Electronics Co Ltd Device a80c
0008:00:00.0 PCI bridge: NVIDIA Corporation Device 229c (rev a1)
0008:01:00.0 Ethernet controller: Realtek ... RTL8111/8168/8411 PCI Express Gigabit Ethernet
The machine has 3 root ports in use, each shown as a PCI bridge, a function that connects 1 bus to the next, on bus 0 of its own domain, with 1 device behind each: a Wi-Fi card, an NVMe drive and an Ethernet controller. The GPU is not in the list: on this machine it is not a PCIe device at all.
26.1.3 Discrete and integrated GPUs
A discrete GPU is a separate card with its own memory, joined to the CPU by a PCIe link (or, on Grace Hopper, by NVLink-C2C, NVIDIA’s link between a CPU chip and a GPU chip). An integrated GPU is built on the same chip as the CPU and uses the same memory. An integrated GPU can be attached in 2 different ways (figure 26.2).
The GPU of figure 26.1 is a platform device: a device that Linux does not discover on a bus but learns about from the device tree, by its fixed register addresses. We call it the platform-device GPU below. An integrated GPU can instead be presented to software as a PCIe function behind an internal root port. The same PCIe machinery that finds a discrete card then finds it. A Jetson AGX Thor attaches its GPU this way, and we call it the PCIe-function GPU:
$ lspci -nn # Jetson AGX Thor
0000:01:00.0 3D controller [0302]: NVIDIA Corporation Device [10de:2b00] (rev a1)
0001:01:00.0 Network controller [0280]: Realtek ... RTL8852CE PCIe 802.11ax Wireless ...
0002:01:00.0 Ethernet controller [0200]: Realtek Semiconductor Co., Ltd. Device [10ec:8126]
0005:01:00.0 Non-Volatile memory controller [0108]: Sandisk Corp WD PC SN5000S M.2 2280 ...
The table puts the 7 GPUs of the earlier chapters side by side. The link column is the path between the CPU and the GPU, with the bandwidth of section 4.1.3. The last column names kinds of DRAM: LPDDR is built for low power and is used in mobile and embedded chips, while GDDR and HBM are built for high bandwidth and are used on graphics cards and data-center GPUs.
| GPU | Attached by | Bandwidth each way | GPU memory |
|---|---|---|---|
| Jetson Orin NX 16 GB | on-chip bus, platform device | none needed: 1 memory | 16 GB LPDDR5, shared |
| Jetson AGX Thor | on-chip, presented as PCIe 01:00.0 | none needed: 1 memory | 128 GB LPDDR5X, shared |
| DGX Spark (GB10) | NVLink-C2C inside 1 package | none needed: 1 memory | 128 GB LPDDR5X, shared |
| GeForce RTX 4090 | PCIe 4.0 × 16 | 32 GB/s | 24 GB GDDR6X, own |
| GeForce RTX 5090 | PCIe 5.0 × 16 | 64 GB/s | 32 GB GDDR7, own |
| A100 | PCIe 4.0 × 16 | 32 GB/s | 40 or 80 GB HBM2e, own |
| H100 | PCIe 5.0 × 16 | 64 GB/s | 80 GB HBM, own |
A program can ask the CUDA runtime how its GPU is attached. The first part of the chapter’s
program prints what cudaGetDeviceProperties and cudaDeviceGetPCIBusId report.
Listing 26.1 What the runtime knows about the device.
/// Asks the driver for 1 integer attribute of `device`.
fn attribute(device: CUdevice, which: CUdevice_attribute) -> Result<i32, DriverError> {
let mut value = 0;
// SAFETY: `value` is a valid place for 1 integer, and `device` came from a live context.
unsafe { cuDeviceGetAttribute(&mut value, which, device).result()? };
Ok(value)
}
fn main() -> Result<(), DriverError> {
let ctx = CudaContext::new(0)?;
let device = ctx.cu_device();
let (major, minor) = ctx.compute_capability()?;
println!("device {}, sm_{major}{minor}", ctx.device_name()?);
println!("SMs {}", ctx.multiprocessor_count()?);
println!("integrated {}\n", attribute(device, INTEGRATED)?);
// ...
}// 1. What the CUDA runtime knows about the device and how it is attached.
void identity()
{
cudaDeviceProp p;
check(cudaGetDeviceProperties(&p, 0));
char busId[32];
check(cudaDeviceGetPCIBusId(busId, sizeof(busId), 0));
double gib = p.totalGlobalMem / 1073741824.0;
int l2Mib = p.l2CacheSize >> 20;
int viaHostTables = p.pageableMemoryAccessUsesHostPageTables;
std::printf("device %s, sm_%d%d\n", p.name, p.major, p.minor);
std::printf("PCI address %s\n", busId);
std::printf("integrated %d\n", p.integrated);
std::printf("memory %.1f GiB, L2 %d MiB\n", gib, l2Mib);
std::printf("copy engines %d\n", p.asyncEngineCount);
std::printf("canMapHostMemory %d\n", p.canMapHostMemory);
std::printf("unifiedAddressing %d\n", p.unifiedAddressing);
std::printf("pageableAccess %d\n", p.pageableMemoryAccess);
std::printf("viaHostPageTables %d\n", viaHostTables);
std::printf("hostNativeAtomic %d\n\n", p.hostNativeAtomicSupported);
}
device Orin, sm_87 device NVIDIA Thor, sm_110
PCI address 0000:00:00.0 PCI address 0000:01:00.0
integrated 1 integrated 1
memory 15.3 GiB, L2 2 MiB memory 122.8 GiB, L2 32 MiB
copy engines 2 copy engines 2
canMapHostMemory 1 canMapHostMemory 1
unifiedAddressing 1 unifiedAddressing 1
pageableAccess 0 pageableAccess 1
viaHostPageTables 0 viaHostPageTables 1
hostNativeAtomic 1 hostNativeAtomic 1
Both GPUs report integrated = 1. The PCIe-function GPU reports the address that lspci
showed, 0000:01:00.0. The platform-device GPU reports 0000:00:00.0: it has no PCIe address, and
the runtime fills the field with zeros. Both report 2 copy engines, units that move data,
which we describe in section 26.5. canMapHostMemory = 1 means that a kernel can access pinned host
memory, host memory that the operating system may not move (Chapter 4), through a pointer. unifiedAddressing = 1 means that the CPU and the GPU share 1 range of
virtual addresses for CUDA allocations, so that the value of a pointer alone tells whether it
names host or device memory; this arrangement is called unified virtual addressing (UVA). The
last 3 lines return in section 26.6, where we explain how the PCIe-function GPU can use the CPU’s
page tables.
The Rust program asks the driver directly. cuda-core wraps the common queries, such as
device_name and multiprocessor_count. For an attribute it does not wrap, such as
INTEGRATED, the program calls cuDeviceGetAttribute from cuda_core::sys, the raw bindings,
inside 1 small unsafe function. The raw bindings are Rust declarations of the C functions of
the CUDA driver, which Rust can call only inside unsafe code. The Rust program prints:
device Orin, sm_87 device NVIDIA Thor, sm_110
SMs 8 SMs 20
integrated 1 integrated 1
26.2 Configuration space and BARs
26.2.1 The configuration header
Before an operating system can use a PCIe function, it must learn what the function is and
where its registers should live. Every function therefore carries a configuration space:
4 KiB of registers that the root complex can read and write by bus number, device number and
function number, before any other address has been assigned. Its first 64 bytes, the
configuration header, have the same layout on every PCIe function ever made. Linux lets an
ordinary user read them from sysfs, a file system under /sys in which the kernel shows
devices and their attributes as files. Here is the header of the PCIe-function GPU:
$ xxd -g1 -l 64 /sys/bus/pci/devices/0000:01:00.0/config
00000000: de 10 00 2b 06 04 10 00 a1 00 02 03 00 00 00 00 ...+............
00000010: 0c 00 00 c0 d0 00 00 00 00 00 00 00 00 00 00 00 ................
00000020: 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 ................
00000030: 00 00 00 00 40 00 00 00 00 00 00 00 a5 01 00 00 ....@...........
Figure 26.3 decodes the fields that matter. PCIe stores numbers wider than 1 byte with the low
byte first, an order called little-endian, so the first 2 bytes, de 10, are the number
0x10de. In the worked example below, a bit \(k\) of a number is the digit worth
\(2^k\) in its binary form, counted from bit 0 at the right. A prefetchable window is one
whose reads have no side effects, so the processor may read it ahead of need; we explain side
effects in section 26.3.1. An interrupt is a signal from a device that makes the CPU stop its
current work and run a routine of the driver; we return to them in section 26.7.
The header contains 6 fields of 4 bytes, at bytes 16 to 39, that tell the operating system where the function’s own registers and memory may be reached.
Definition 26.2 Base address register. A base address register, or BAR, is one of the 6 fields of a configuration header that each describe 1 window of the function’s registers or memory. The function decides how large the window is and of what kind; the operating system decides where in the physical address space the window starts, by writing the start address into the BAR. A 64-bit address occupies 2 neighboring fields.
Example. The BAR0 of the PCIe-function GPU holds the start address 0xd0_c000_0000 of a window of 16 MiB, which contains the GPU’s registers.
Worked example: decoding the configuration header
- Vendor and device, bytes 0 to 3: 0x10de is NVIDIA’s vendor number, assigned by the
PCI-SIG, the industry group that maintains the PCI standards; 0x2b00 is the device number NVIDIA gave this GPU.
lspci -nnprinted the same pair as[10de:2b00]. - Command, bytes 4 and 5: 0x0406 = binary 0000 0100 0000 0110. Bit 1 lets the function answer memory transactions (its BARs are live). Bit 2 lets it start transactions of its own (it may read and write memory: DMA, section 26.5). Bit 10 switches off the old interrupt wire in favor of messages (section 26.7).
- Class, bytes 9 to 11: programming interface 0x00, subclass 0x02, class 0x03. Class 3 is “display controller” and subclass 2 is “3D controller”, a GPU with no display output.
- BAR0, bytes 16 to 23: the 8 bytes read low first are 0x0000_00d0_c000_000c. Its low 4 bits, 0xc = binary 1100, are flags: bit 0 = 0, a memory window; bits 2:1 = 10, a 64-bit address; bit 3 = 1, prefetchable. With the flags cleared, the window starts at 0xd0_c000_0000.
The address in a BAR is thus the result of a negotiation between the function, which fixes the
size and kind of the window, and the operating system, which fixes its place. lspci -v prints
the result of that negotiation:
$ lspci -vv -s 0000:01:00.0 # Jetson AGX Thor, as a normal user
0000:01:00.0 3D controller: NVIDIA Corporation Device 2b00 (rev a1)
Control: I/O- Mem+ BusMaster+ SpecCycle- MemWINV- VGASnoop- ParErr- Stepping- SERR- ...
Interrupt: pin A routed to IRQ 421
IOMMU group: 83
Region 0: Memory at d0c0000000 (64-bit, prefetchable) [size=16M]
Capabilities: <access denied>
Kernel driver in use: nvidia
Mem+ BusMaster+ are bits 1 and 2 of the command register, and Region 0 is BAR0 at the
address decoded above. IRQ 421 is the number under which Linux lists the function’s interrupt,
and the IOMMU group is explained in section 26.6. The capabilities are a list of optional
features of the function, kept in the configuration space after the header. They start at offset
0x40, lie beyond the first 64 bytes, and Linux shows them only to root.
26.2.2 BAR sizing
lspci reported [size=16M], although no field of the header holds a size. The size is found
by a procedure that the PCI specification defines.
Let us first work the procedure on a BAR of only 8 bits, which we invent for the purpose and which describes a window of 16 bytes. A window of 16 = 24 bytes must start at a multiple of 16, such as 0x30 or 0xA0, and every multiple of 16 has 0 in its low 4 bits. The device therefore stores only the high 4 bits of the address and wires the low 4 bits to 0: whatever software writes there, they read back as 0. Software writes all ones, 0xFF = binary 1111 1111, and reads back 0xF0 = binary 1111 0000. Inverting the bits gives 0x0F = 15, and adding 1 gives 16, the size of the window.
Key observation A window of \(2^k\) bytes starts at a multiple of \(2^k\), so the low \(k\) bits of its address are always 0, and the device need not store them. The number of low bits that stay 0 after software writes all ones reveals \(k\), and therefore the size.
A real BAR works in the same way. A device implements only the high bits of each BAR’s address: the bits below the window’s size are wired to 0, because a window of \(2^k\) bytes must start at a multiple of \(2^k\). Software writes all ones into the BAR and reads it back; the bits that stayed 0 reveal the size. The lowest 4 bits of a memory BAR hold flags instead of address bits, so the flags must be cleared before the bits are inverted. Figure 26.4 works the procedure for the NVMe drive of figure 26.1 and for the PCIe-function GPU.
Let us follow the procedure for the NVMe drive. Its window is 16 KiB = 16,384 bytes =
\(2^{14}\) bytes, so address bits 13 to 0 of its BAR are wired to 0. When software writes
0xFFFF_FFFF, the low word reads back as 0xFFFF_C004: bits 31 to 14 are 1, bits 13 to 4 are 0,
and bits 3 to 0 hold the flags, 0x4, which mark a 64-bit memory window. Clearing the flags gives
0xFFFF_C000, inverting gives 0x0000_3FFF = 16,383, and adding 1 gives 16,384 bytes. The same
steps on the PCIe-function GPU give 0x0100_0000 = 16,777,216 bytes, the [size=16M] that
lspci printed.
The kernel performs this sizing once, at boot, for every BAR of every function. Ordinary programs never do it, and should not: a BAR full of ones points the device at the wrong address until it is restored. It follows from the procedure that the size of a BAR is always a power of 2. A GPU with 24 GiB of memory that wants all of it visible through 1 window needs a BAR of 32 GiB, the next power of 2.
26.2.3 Bus addresses and CPU addresses
The address written in a BAR is the address that the device sees on its link, a bus address. The CPU need not use the same number: the address with which the CPU reaches the window, the CPU address, may differ from the bus address by a fixed amount that the root port adds or subtracts. The NVMe drive of figure 26.1 shows the difference:
$ xxd -g1 -s 16 -l 8 /sys/bus/pci/devices/0004:01:00.0/config
00000010: 04 00 00 40 00 00 00 00 ...@....
$ lspci -v -s 0004:01:00.0 | grep Region
Region 0: Memory at 2428000000 (64-bit, non-prefetchable) [size=16K]
The BAR holds 0x4000_0000 (flags 0x4, a 64-bit window that is not prefetchable). The CPU
reaches the same registers at 0x24_2800_0000. The root port translates between the 2: a CPU
store to 0x24_2800_0000 + \(r\) leaves the root port as a PCIe write to bus address
0x4000_0000 + \(r\). For the PCIe-function GPU the 2 numbers happen to be equal: its BAR
holds 0xd0_c000_0000, and lspci reports the CPU address d0c0000000. A driver must never
assume either case; Linux keeps the two kinds of address apart in its types for exactly this
reason.
26.2.4 The BARs of a GPU
NVIDIA’s open-source kernel driver describes the windows of its GPUs. BAR0 holds the GPU’s registers. BAR1 is a window onto the GPU’s own memory, through which the CPU can read and write device memory with loads and stores. On consumer cards BAR1 has traditionally been 256 MiB, a small sliding view of the whole memory. With Resizable BAR, a PCIe feature that lets the system grow a BAR at boot, it can cover all of the memory. Data-center GPUs such as the A100 and the H100 offer a BAR1 at least as large as their memory.
The PCIe-function GPU has only BAR0, 16 MiB of registers. It has no memory of its own to
expose: its memory is the system’s DRAM, which the CPU already reaches directly. The device
tree of the platform-device GPU gives it a bar0 and a bar1 of 16 MiB each, plus a 4 KiB
window, again with no window onto a separate memory.
26.3 Memory-mapped I/O as the control path
26.3.1 Loads and stores with side effects
A load from DRAM has no effect on the memory, and reading the same address twice gives the same value. A load from a device register can have an effect: reading a status register may clear the event it reports, and 2 reads may return 2 different values because the device changed state in between. A store to a register is a command, such as “start”, “reset” or “new work is waiting”. Such effects are called side effects, and they change what the processor may do with the addresses.
Consider a status register that holds 1 when a copy has finished and that clears itself to 0 when it is read. The device finishes a copy, and the register holds 1. The driver loads it and gets 1. A second load gets 0, because the first load cleared it; the device reports each event exactly once. Now suppose that the processor kept a copy of the register in its cache, as it does for memory. The second load would be served from the cache and return 1 again, and the driver would count 1 finished copy twice. Suppose instead that the processor loaded the register early, on a guess that the program would soon need it, and then discarded the value. The register would be cleared, and the driver would never see the event at all.
A processor keeps copies of memory in its caches, small fast memories near the core, and it performs speculative reads: loads issued ahead of a program, on a guess that the program will need the data soon. Both behaviors are wrong for a device, as the example shows: a cached copy of a status register goes stale, and a load that the processor issued early may trigger a side effect the program never asked for. Every page in a program’s address space therefore carries a memory type in its page-table entry, the record of the page table that holds the page’s translation, and the memory type tells the processor how it may treat the addresses. Arm and x86 use different names for the types, and the table gives both:
| Memory type (Arm name; x86 name) | Cached | Speculative reads | Stores merged | Used for |
|---|---|---|---|---|
| Normal, cacheable (WB) | yes | yes | yes | DRAM |
| Normal, non-cacheable (WC, write-combining) | no | yes | yes | frame buffers, BAR1-like windows |
| Device-nGnRE (UC, uncached) | no | no | no | registers in BAR0 |
WB stands for write-back, the ordinary cached type; UC for uncached. In the Arm name Device-nGnRE, the letters state that the processor may not gather (nG) or reorder (nR) the accesses, and that a write may be acknowledged early (E), before it reaches the device. A frame buffer is the memory that holds the image shown on a display.
Write-combining memory is not cached, but the processor may gather several stores to neighboring addresses in a small buffer and send them as 1 larger transaction. For example, 16 stores of 4 bytes to the addresses 0x1000, 0x1004, …, 0x103C fill 64 neighboring bytes. Without combining they leave the core as 16 transactions of 4 bytes; with combining they leave as 1 transaction of 64 bytes. A program that fills a frame buffer or a command buffer with a stream of stores runs much faster that way. Device memory forbids even that. Each store reaches the device as written, in program order.
On PCIe the two directions differ in cost. A memory write is posted: the root complex sends it and lets the CPU continue at once, without waiting for any reply. A memory read is non-posted: it must wait for the device’s completion to travel back across the link, typically several hundred nanoseconds to more than a microsecond, a few thousand CPU cycles. Drivers therefore write registers freely and read them as rarely as they can.
The CPU uses MMIO for control: a few bytes that tell the device what to do. Bulk data takes another path, in which the device itself reads and writes memory while the CPU does other work.
Definition 26.3 Direct memory access. Direct memory access, or DMA, is a transfer that a device performs itself, reading or writing memory without a CPU core moving each byte. The path of MMIO stores from the CPU to the device is the control path; the path of DMA between memory and the device is the data path.
Example. To copy 64 MiB to the GPU, the CPU writes a short description of the copy into memory and stores 4 bytes into a GPU register by MMIO. The GPU then reads the description, and the 64 MiB, from DRAM by DMA (figure 26.5).
26.3.2 CPU access speed by memory type
The registers of a GPU are out of reach of an ordinary program, but the memory types
are not. CUDA can allocate host memory with the write-combining type: cudaHostAlloc with the
flag cudaHostAllocWriteCombined. The second part of the chapter’s program runs the same 2
loops, a write of every word and a sum of every word, over 64 MiB of 4 kinds of memory: pageable
memory from malloc, which the operating system may move; pinned memory from cudaMallocHost;
pinned write-combined memory; and managed memory from cudaMallocManaged, which CPU and GPU
reach through the same pointer (Chapter 4).
Listing 26.2 The same CPU loops over each kind of memory.
fn main() -> Result<(), DriverError> {
// ...
let words = 16 << 20; // 16,777,216 words, 64 MiB
let mut pageable = vec![0u32; words];
let mut pinned = PinnedHostBuffer::<u32>::zeroed(&ctx, words)?;
println!("CPU access to 64 MiB through each mapping:");
time_cpu("Vec (pageable)", &mut pageable);
time_cpu("PinnedHostBuffer", pinned.as_mut_slice());
// ...
}// 2. The same CPU loops over 4 kinds of memory.
void memoryTypes()
{
const size_t bytes = 64u << 20;
const int reps = 5;
uint32_t* pageable = static_cast<uint32_t*>(std::malloc(bytes));
uint32_t* pinned = nullptr;
uint32_t* combined = nullptr;
uint32_t* managed = nullptr;
check(cudaMallocHost(&pinned, bytes));
check(cudaHostAlloc(&combined, bytes, cudaHostAllocWriteCombined));
check(cudaMallocManaged(&managed, bytes));
std::printf("CPU access to %zu MiB through each mapping:\n", bytes >> 20);
timeCpu("malloc (pageable)", pageable, bytes, reps);
timeCpu("cudaMallocHost (pinned)", pinned, bytes, reps);
timeCpu("write-combined pinned", combined, bytes, reps);
timeCpu("cudaMallocManaged", managed, bytes, reps);
std::printf("\n");
check(cudaFree(managed));
check(cudaFreeHost(combined));
check(cudaFreeHost(pinned));
std::free(pageable);
}
timeCpu writes the value 1 into every word, sums every word, keeps the best of 5 passes, and
checks that the sum equals the number of words. The output on both machines:
CPU access to 64 MiB through each mapping: # Orin NX
malloc (pageable) write 27.02 GB/s read 12.03 GB/s PASSED
cudaMallocHost (pinned) write 26.62 GB/s read 11.93 GB/s PASSED
write-combined pinned write 13.75 GB/s read 1.09 GB/s PASSED
cudaMallocManaged write 27.20 GB/s read 12.13 GB/s PASSED
CPU access to 64 MiB through each mapping: # Thor
malloc (pageable) write 41.61 GB/s read 20.52 GB/s PASSED
cudaMallocHost (pinned) write 41.43 GB/s read 20.61 GB/s PASSED
write-combined pinned write 41.44 GB/s read 20.69 GB/s PASSED
cudaMallocManaged write 41.38 GB/s read 20.69 GB/s PASSED
On the platform-device machine, 3 of the 4 kinds of memory behave alike, because all 3 are
ordinary cacheable DRAM to the CPU. They ran at about 27 GB/s for writes and 12 GB/s for reads,
the speed of 1 CPU core. Write-combined memory is different. Its reads ran at 1.09 GB/s, 12.03
/ 1.09 ≈ 11 times slower, because no read is served from a cache and none is fetched ahead:
each load waits for DRAM. Its writes ran at 13.75 GB/s, half the cached speed but 13 times its
own reads, because the write-combining buffer still merges the stores into whole lines. On the
PCIe-function machine the flag changed nothing: all 4 kinds ran at about 41 GB/s and 21 GB/s.
CUDA’s documentation describes the flag as a request that helps “on some system
configurations”, and there the memory was mapped cacheable. The Rust program measures the 2
kinds that cuda-core can allocate, Vec and PinnedHostBuffer; cuda-core has no
write-combined allocation at revision b7fe543 of its source. On the platform-device machine it found the same as
C++: 27.41 and 27.58 GB/s for writes, 12.43 and 12.32 GB/s for reads. Runs differ by about 10%
from one to the next.
26.3.3 Ordering writes before a doorbell
A device usually learns of new work in 2 steps. The CPU first writes the work itself into memory, then stores into 1 register, the doorbell, to tell the device to look. The order of those 2 steps decides whether the device sees the work. If the doorbell’s store reached the device first, the device would read the memory before the work was in it.
Let us follow 1 submission with numbers. Slot 3 of an array in memory holds 0, left over from earlier, and the CPU wants the device to run the command 42. It performs 2 stores:
store 1: slot[3] ← 42 (to cacheable memory)
store 2: doorbell ← 3 (to a device register: "slot 3 is ready")
If store 1 becomes visible first, the device receives the doorbell, reads slot 3 and finds 42. If store 2 becomes visible first, the device reads slot 3 before 42 has arrived and finds 0, the old value. The program is the same in both cases; only the order in which the 2 stores became visible differs.
The processor does not keep stores in program order on its own. An Arm core may let a later
store become visible before an earlier one, and stores to cacheable memory and stores to device
registers travel by different paths. A memory barrier is an instruction that keeps the order:
every memory access before it completes, as seen by other observers, before any after it. A memory
barrier differs from the barrier __syncthreads() of earlier chapters, which makes the threads of
a block wait for each other; a memory barrier orders the accesses of 1 thread. In this chapter,
“barrier” means a memory barrier. On Arm the barriers are the DMB and DSB instructions. In C++
and Rust, a store with release ordering is a store that becomes visible only after every
access that precedes it in the program; it places the barrier before the store. Linux’s writel(), the function a driver uses to
write a 32-bit register, puts a write barrier before the store for exactly this case, so that a
device started by the register sees every earlier write to memory. In Section 26.4.6, we show what
happens when the order is wrong.
Rule Write the work into memory, then execute a memory barrier, then store to the doorbell.
26.4 Work rings and doorbells
26.4.1 A ring of work entries
A kernel launch returns in microseconds because the CPU does not hand the work to the GPU and wait; it leaves the work in memory for the GPU to collect. Suppose that a program launches 3 kernels, A, B and C, in a row, and that each takes 1 ms on the GPU. If each launch waited for the GPU to accept the kernel, the CPU would wait for A to finish before it could hand over B. If the CPU instead writes A, B and C into a list in memory, 1 after another, it can return from the 3 launches at once, and the GPU takes the kernels from the list in order. The list needs a fixed size, because memory for it is set aside in advance, and it must be reusable, because a program may launch millions of kernels. Both needs are met by using a fixed array in a circle.
Definition 26.4 Ring buffer, PUT and GET. A ring buffer is an array of a fixed number \(n\) of slots, used in a circle, with 2 counters. PUT counts the entries the producer, here the CPU, has written, and GET counts the entries the consumer, here the GPU, has finished. Both only grow. Entry number \(c\) lives in slot \(c \bmod n\), the remainder of \(c\) divided by \(n\), so the slots are reused once the ring wraps around.
Example. With \(n\) = 8 slots, entry #9 lives in slot 9 mod 8 = 1, the slot that entry #1 used before it.
The entries waiting to be run are those from GET to PUT − 1, so there are PUT − GET of them. The ring is empty when PUT = GET and full when PUT − GET = \(n\). The pseudocode shows both sides.
host, to submit entry e: device, forever:
while PUT - GET = n: wait wait until GET ≠ PUT
ring[PUT mod n] ← e run ring[GET mod n]
barrier GET ← GET + 1
PUT ← PUT + 1 (the doorbell)
Worked example: a ring of 8 slots
- GET = 2 and PUT = 7: entries #2 to #6 are waiting, PUT − GET = 7 − 2 = 5 of them, in slots 2 to 6.
- The host writes 3 more entries. Entry #7 goes to slot 7 mod 8 = 7, #8 to slot 8 mod 8 = 0, #9 to slot 9 mod 8 = 1. PUT is now 10.
- PUT − GET = 10 − 2 = 8 = the number of slots: the ring is full. Entry #10 would go to slot 10 mod 8 = 2, which still holds #2, not yet run; the host must wait until GET passes 2.
- Each counter has 1 writer: the host moves PUT, the device moves GET. Neither side needs a lock, a variable that lets only 1 thread at a time into a section of code.
| Symbol | Meaning | In the example |
|---|---|---|
| \(n\) | number of slots in the ring | 8 |
| PUT | entries written by the host so far | 7, then 10 |
| GET | entries finished by the device so far | 2 |
| PUT − GET | entries waiting; the ring is full when it equals \(n\) | 5, then 8 |
| \(c \bmod n\) | slot of entry \(c\) | #9 → slot 1 |
26.4.2 The ring and the doorbell of an NVIDIA GPU
An NVIDIA GPU receives work through channels. A channel is 1 ordered stream of commands from 1 process, a running program with its own address space, to the GPU; the CUDA runtime places each stream’s work on 1 of a pool of channels. Each channel has 3 structures in memory that both the CPU and the GPU can reach. NVIDIA’s open-source kernel driver publishes their layouts in its class headers, C header files that define the registers and memory structures of each generation of GPU:
- The pushbuffer holds the commands themselves, called methods: “set this kernel’s parameters”, “launch with this grid”, “signal this semaphore”. A semaphore here is a word in memory that the GPU writes when it reaches a point in the stream of commands, so that the CPU can learn how far the GPU has come. A launch is a short run of methods.
- The GPFIFO is the ring of the previous section. Each entry is 8 bytes and points at a
piece of the pushbuffer: its address and its length (
GP_ENTRY__SIZE= 8 in the headers). - USERD is a small page of counters for the channel. At offset 0x8c it holds
GPPut, the ring’s PUT, which the CPU writes; at offset 0x88,GPGet, which the GPU writes.
Since the Volta generation of 2017, the doorbell is a register named NOTIFY_CHANNEL_PENDING, at
offset 0x90 of a 64 KiB “user mode” window that the headers place at offset 0x81_0000 of BAR0.
The CPU stores the channel’s work-submit token, a number the driver gives each channel,
into that register. A system call is a request from a program to the operating-system kernel,
in which the processor switches into the kernel and back; it costs far more than a store. The
register’s page is mapped into the process, that is, the process’s page table holds an entry
for it, so the process can store to the register directly and needs no system call. Figure 26.7
puts the steps of 1 launch in order.
Steps 1 to 5 are the launch call that we timed in Chapter 6: a few ordinary stores into memory, 1 barrier and 1 store to a register, 3.77 µs with the rest of the runtime’s work. Steps 6 to 9 happen later, on the GPU’s own time. The part of the GPU that reads the ring, its host interface, fetches entries and methods from memory by DMA, so the CPU never waits for the GPU to accept anything. Only when the ring is full does a launch wait, exactly as the host waits in the worked example.
26.4.3 Doorbells in an NVMe drive
The design is not peculiar to GPUs. An NVMe drive, whose specification is public, takes its commands the same way. The host writes 64-byte commands into a submission queue in memory, then writes the queue’s new tail, the slot after the last command written, which plays the role of PUT, into a doorbell register in BAR0. The drive reports finished commands in a second ring, the completion queue, and the host tells the drive how far it has read that ring by writing the queue’s head, the role of GET, into a second doorbell. The drive has 1 pair of queues for administration commands, such as creating queues, and further pairs for I/O queues, which carry reads and writes of data. The specification places the doorbells right after the drive’s 4 KiB of control registers. In the formulas, \(a \ll b\) means \(a\) shifted left by \(b\) bits, which is \(a \times 2^b\):
\[ \text{SQ tail doorbell of queue } y = \text{0x1000} + 2y \cdot (4 \ll \text{DSTRD}) \]
\[ \text{CQ head doorbell of queue } y = \text{0x1000} + (2y + 1) \cdot (4 \ll \text{DSTRD}) \]
| Symbol | Meaning | On the drive of figure 26.1 |
|---|---|---|
| \(y\) | queue number; 0 is the administration queue | 0 to 8 |
| DSTRD | doorbell stride, read from the drive’s capability register | 0 (the usual value) |
| \(4 \ll \text{DSTRD}\) | bytes between doorbells | 4 |
Before we use the formulas on the real drive, let us place the doorbells of the first 2 queues by hand, with DSTRD = 0 and so 4 bytes between doorbells. Queue 0 has its submission doorbell at 0x1000 + 0 × 4 = 0x1000 and its completion doorbell at 0x1000 + 1 × 4 = 0x1004. Queue 1 follows at 0x1000 + 2 × 4 = 0x1008 and 0x1000 + 3 × 4 = 0x100C. The doorbells thus alternate, submission and completion, queue after queue, each 4 bytes wide.
For example, /proc/interrupts, a file in which Linux lists every interrupt line and the number
of interrupts each has received, lists 9 interrupt lines for the drive of figure 26.1,
nvme0q0 to nvme0q8: the administration queue and 8 I/O queues, 1 per CPU core. With a
stride of 4 bytes, the submission doorbell of queue 8 sits at 0x1000 + 2 × 8 × 4 = 0x1040, and
its completion doorbell at 0x1000 + 17 × 4 = 0x1044. The highest doorbell, at 0x1047, lies well
inside the 16 KiB = 0x4000-byte BAR0 that we sized in figure 26.4.
26.4.4 A software model of a work ring
The chapter’s program builds the mechanism with 2 CPU threads, so that we can run it, time it, and observe what happens when the order of writes is wrong. A host thread submits entries; a device thread plays the GPU’s host interface. Each entry carries an opcode, a number that names the operation requested, and an argument. The device thread spends 2 µs on each entry, a stand-in for a kernel, and adds the argument to a sum, so the program can check that every entry was run exactly once.
The doorbell here is an atomic counter, PUT, that the device thread watches. An atomic variable is one whose loads and stores another thread never sees half done, and whose accesses can carry an ordering such as release. A real device would be woken by a store to its register instead of watching memory, but the order of events is the same. A cache line is the unit of 64 bytes in which the CPU’s caches hold and move memory. Each counter sits on its own cache line, as each register of a device has its own address.
Listing 26.3 The ring, the device and the doorbell.
const CAPACITY: u32 = 64;
/// Keeps 1 value alone on a 64-byte cache line, as each register has its own address.
#[repr(align(64))]
struct Line<T>(T);
/// A ring of entries (opcode in the high 32 bits, argument in the low 32) and 2 counters.
struct Channel {
ring: [AtomicU64; CAPACITY as usize],
doorbell: Line<AtomicU32>, // PUT: entries written so far
get: Line<AtomicU32>, // GET: entries the device has finished
stop: Line<AtomicBool>,
}
/// The device: wait for the doorbell, run every entry up to PUT, then report GET.
fn device(ch: &Channel, work_us: f64) -> u64 {
let mut get = 0u32;
let mut sum = 0u64;
while !ch.stop.0.load(Ordering::Acquire) {
let put = ch.doorbell.0.load(Ordering::Acquire);
while get != put {
let entry = ch.ring[(get % CAPACITY) as usize].load(Ordering::Relaxed);
spin_us(work_us);
sum += if entry >> 32 == 1 { entry & 0xffff_ffff } else { 0 };
get += 1;
ch.get.0.store(get, Ordering::Release);
}
}
sum
}
/// The host: write the entry, then ring the doorbell. Waits only when the ring is full.
fn submit(ch: &Channel, depth: u32, put: &mut u32, arg: u32) {
while put.wrapping_sub(ch.get.0.load(Ordering::Acquire)) >= depth {
spin_loop();
}
let entry = (1u64 << 32) | arg as u64;
ch.ring[(*put % CAPACITY) as usize].store(entry, Ordering::Relaxed);
ch.doorbell.0.store(*put + 1, Ordering::Release);
*put += 1;
}// 3. A ring of work entries and a doorbell, between a host thread and a device thread.
struct Entry {
uint32_t opcode;
uint32_t arg;
};
struct Channel {
static const uint32_t capacity = 64;
Entry ring[capacity];
// Each counter on its own 64-byte cache line, as each register has its own address.
alignas(64) std::atomic<uint32_t> doorbell{0}; // PUT: entries written so far
alignas(64) std::atomic<uint32_t> get{0}; // GET: entries the device finished
alignas(64) std::atomic<bool> stop{false};
uint64_t sum = 0; // the device's result
};
// The device: wait for the doorbell, run every entry up to PUT, then report GET.
void device(Channel* ch, double workUs)
{
uint32_t get = 0;
while (!ch->stop.load(std::memory_order_acquire)) {
uint32_t put = ch->doorbell.load(std::memory_order_acquire);
while (get != put) {
Entry e = ch->ring[get % Channel::capacity];
spinUs(workUs);
ch->sum += e.opcode == 1 ? e.arg : 0;
get += 1;
ch->get.store(get, std::memory_order_release);
}
}
}
// The host: write an entry, then ring the doorbell. Waits only when the ring is full.
void submit(Channel* ch, uint32_t depth, uint32_t& put, uint32_t arg, bool doorbellFirst)
{
while (put - ch->get.load(std::memory_order_acquire) >= depth) {
}
Entry& slot = ch->ring[put % Channel::capacity];
if (doorbellFirst) {
ch->doorbell.store(put + 1, std::memory_order_release);
slot = Entry{1, arg};
} else {
slot = Entry{1, arg};
ch->doorbell.store(put + 1, std::memory_order_release);
}
put += 1;
}
submit waits while the ring holds depth entries, writes the entry, then stores PUT + 1 with
release ordering: the barrier of section 26.3.3, built into the store. The device loads PUT
with acquire ordering, the counterpart of release. No access that follows the load in the
program may become visible before it. The 2 orderings pair: once the device sees PUT = \(c\) +
1, it also sees entry \(c\). The doorbellFirst branch exists to break that order on purpose
(section 26.4.6).
Rust’s version stores each entry in an AtomicU64, with the opcode in the high 32 bits. Rust
does not allow 2 threads to touch the same plain memory when one of them writes, so the slots are
atomics too. A Relaxed store is an atomic store that promises no ordering with other accesses;
it compiles to an ordinary store, and the Release store of the doorbell provides the order.
26.4.5 Ring depth and run-ahead
The program submits 200 bursts of 32 entries. After each burst the host does 64 µs of work of its own, so the work a GPU would do and the work the CPU does could overlap. A burst is a group of entries that the host submits one after another without other work in between. The depth of a ring is its number of slots \(n\), and it limits the run-ahead of the host: the number of entries by which the host may be ahead of the device. We run the program with a ring of depth 1, 4, 32 and 64: the host may run at most that many entries ahead of the device. Before we run it, we can predict the time of 1 burst.
Worked example: 1 burst at depth 1, 4 and 32
- The device needs 32 entries × 2 µs = 64 µs per burst, and the host needs 64 µs for its own work.
- Depth 1: the host can submit entry \(k\) only after the device has finished entry \(k − 1\). It waits through almost all 64 µs of the device’s work, then works alone for 64 µs. A burst takes about 64 + 64 = 128 µs, and 200 bursts take 200 × 128 µs = 25.6 ms.
- Depth 4: the host writes 4 entries at once, then 1 more each time the device finishes 1. Its last entry goes in after the device has finished 28: 28 × 2 µs = 56 µs. Then come 64 µs of its own work: 56 + 64 = 120 µs per burst, 200 × 120 µs = 24.0 ms.
- Depth 32: the whole burst fits. The host writes 32 entries in about a microsecond and starts its own work while the device runs them; both take 64 µs, so a burst takes 64 µs, and 200 bursts take 12.8 ms. Depth 64 can do no better.
Work queue: 200 bursts of 32 entries, 2 us each, 64 us of host work: # Orin NX, C++
depth 1, entry first 30.85 ms sum 20483200 of 20483200 PASSED
depth 4, entry first 26.01 ms sum 20483200 of 20483200 PASSED
depth 32, entry first 13.69 ms sum 20483200 of 20483200 PASSED
depth 64, entry first 14.21 ms sum 20483200 of 20483200 PASSED
Work queue: 200 bursts of 32 entries, 2 us each, 64 us of host work: # Thor, C++
depth 1, entry first 28.66 ms sum 20483200 of 20483200 PASSED
depth 4, entry first 25.76 ms sum 20483200 of 20483200 PASSED
depth 32, entry first 13.50 ms sum 20483200 of 20483200 PASSED
depth 64, entry first 13.49 ms sum 20483200 of 20483200 PASSED
Work queue: 200 bursts of 32 entries, 2 us each, 64 us of host work: # Orin NX, Rust
depth 1 29.80 ms sum 20483200 of 20483200 PASSED
depth 4 25.01 ms sum 20483200 of 20483200 PASSED
depth 32 13.69 ms sum 20483200 of 20483200 PASSED
depth 64 13.86 ms sum 20483200 of 20483200 PASSED
Every run summed all 6,400 arguments, 1 + 2 + … + 6,400 = 6,400 × 6,401 / 2 = 20,483,200, so every entry ran exactly once. The times follow the prediction. Depth 1 took 28.7 to 30.9 ms against 25.6 ms predicted, depth 4 took 25.0 to 26.0 ms against 24.0 ms, and depths 32 and 64 took 13.5 to 14.2 ms against 12.8 ms. The measured times sit 4% to 21% above the predictions: the cost of the threads waking, the clock reads and the cache lines moving between the 2 cores. Figure 26.8 draws 1 burst at depth 1 and at depth 32.
Key observation The host’s own work overlaps the device’s work only for the entries that the ring can hold. When the ring holds the whole burst, the host submits everything at once, and the two kinds of work run side by side.
Note that the ring halves the total time only when it holds the whole burst. A ring is a queue, and a queue lets the producer run ahead of the consumer by as many entries as it holds; this is the mechanism behind Chapter 6’s asynchronous launches and streams. A GPU’s rings hold hundreds of entries, so a program can queue many kernels and copies before it must wait.
A launch is a few stores into a ring in memory and 1 store to a doorbell. The deeper the ring, the further the CPU can run ahead of the GPU.
26.4.6 Ordering errors
Run with --doorbell-first, the program stores PUT + 1 before it writes the entry. The device
may then see the new PUT, read the slot, and find whatever the slot held before: an entry from
the previous lap, the previous pass of the counters around the ring, or nothing. For example,
in a ring of 8 slots, entry #9 goes to slot 1, which still holds entry #1. If the device reads
slot 1 between the doorbell and the write of entry #9, it runs the argument of entry #1 a second
time and never runs that of entry #9.
$ ./systems --doorbell-first # Orin NX
depth 1, doorbell first 31.50 ms sum 20479232 of 20483200 FAILED
depth 4, doorbell first 25.35 ms sum 20483200 of 20483200 PASSED
depth 32, doorbell first 13.50 ms sum 20483200 of 20483200 PASSED
depth 64, doorbell first 13.50 ms sum 20483200 of 20483200 PASSED
At depth 1 the device read stale slots and lost 20,483,200 − 20,479,232 = 3,968 from the sum. The other 3 depths passed in this run. Over 5 runs on the platform-device machine, 4 of the 20 results were wrong, and on the PCIe-function machine 3 of 12; which ones fail changes from run to run. Depth 1 fails most often, because the device thread is idle and watching PUT when the doorbell rings, so it reaches the slot in the instant before the entry arrives. The same swap in the Rust program failed at depth 1 in all 5 runs.
The Rust version shows a further point. A data race is a pair of accesses to the same plain, non-atomic memory by 2 threads, at least one of them a write, with nothing that orders them. Rust does not compile a program in which 2 threads touch the same plain memory in this way, so the slots had to be atomics. The broken program is nevertheless free of data races in Rust’s sense, and it still loses entries. The compiler can prove that every access is safe, but not that the protocol, entry first and doorbell second, is followed. The C++ version is worse off. There the swap also creates a data race, and its behavior is undefined: the language does not specify what the program does. In a driver, the same mistake causes the GPU to execute stale commands, rarely and usually under load.
Write the work, then a barrier, then the doorbell. In the other order, the program passed most runs and failed some, which makes the error hard to find.
26.5 DMA as the data path
Recall from Definition 26.3 that DMA is a transfer that a device performs itself, reading or
writing memory without a CPU core moving each byte. A PCIe function may do it only while its bus
master bit is set, bit 2 of the command register that figure 26.3 decoded (BusMaster+ in
lspci). A GPU uses DMA for 2 different jobs. Its host interface reads the work rings and
pushbuffers, as in steps 6 and 7 of figure 26.7. Its copy engines, units that do nothing
but move data, carry out cudaMemcpy and its asynchronous forms; both GPUs of listing 26.1
report 2 of them.
A copy engine is told what to move by a descriptor, a small record in memory with a source
address, a destination address and a length. A copy of 64 MiB from a host buffer to a device
buffer, for example, can be described by 1 descriptor that holds the address of the host buffer,
the address of the device buffer and the length 67,108,864 bytes. For cudaMemcpy from a host
buffer to the device, the sequence is:
- The driver makes sure the host buffer’s pages cannot move, by pinning them or by staging the data through a pinned buffer, that is, by copying it first into a pinned buffer of its own (section 4.2.2 explains why).
- It writes one or more descriptors, as methods in a channel’s pushbuffer.
- It rings the channel’s doorbell, as in section 26.4.2.
- The copy engine reads the descriptors, then reads the source by DMA and writes the destination, while the CPU does other work.
- The engine signals completion, by writing a value into memory that the driver checks or by raising an interrupt (section 26.7).
The addresses in a descriptor are the addresses that the device uses, not the CPU’s virtual addresses. On a system with an IOMMU they are not physical addresses either, as the next section explains.
26.6 The IOMMU
A device that can write any physical address can overwrite any memory, including the kernel’s. A faulty device, or a malicious one plugged into an external port, could then take over the machine. The remedy is the same as for processes: give the device addresses of its own, and translate them through a table that only the kernel can change.
Let us follow 1 translation by hand, with the example addresses of figure 26.9. A device is given a buffer of 4 pages of 4 KiB that it sees at the device addresses 0x1000_0000 to 0x1000_3FFF. In physical memory, the 4 pages lie scattered, at the physical pages that the figure numbers 3, 0, 5 and 1. The device writes to the address 0x1000_2010. The translation takes 3 steps:
- Subtract the start of the buffer: 0x1000_2010 − 0x1000_0000 = 0x2010.
- Split the result into a page number and an offset: 0x2010 / 0x1000 = page 2, remainder 0x010.
- Look up page 2 in the table, which gives physical page 5, and add the offset: the write lands at byte 0x010 of physical page 5.
A write to the address 0x2000_0000 finds no entry in the table. The translation fails, the write is refused, and the memory that the address would have reached is untouched.
Definition 26.5 IOMMU. An IOMMU (input-output memory management unit; the Arm name is SMMU, system MMU) sits between devices and memory and does for DMA what the CPU’s MMU does for loads and stores. It translates every address a device uses, an I/O virtual address or IOVA, through page tables that the kernel controls, and it refuses any address the kernel has not mapped for that device.
Example. In figure 26.9, the IOVA 0x1000_2010 is translated to byte 0x010 of physical page 5, and the IOVA 0x2000_0000 is refused with a fault, an error that the IOMMU reports to the kernel.
The IOMMU gives 2 benefits besides safety. A buffer whose pages lie scattered in physical memory looks contiguous, a single unbroken range of addresses, to the device, so 1 descriptor can cover it. And the kernel can take a mapping away, for example when a device is unplugged or handed to a virtual machine, a complete operating system that runs as a program on top of another.
The mappings have a cost. A 64 MiB buffer in 4 KiB pages has 67,108,864 ÷ 4,096 = 16,384 pages, so before a copy engine can read it, the kernel writes 16,384 entries into the IOMMU’s page table. The IOMMU caches recent translations in its own TLB (translation lookaside buffer), a small cache of page-table entries. A buffer that is pinned once and reused keeps its entries, whereas a buffer that is pinned again for every copy has them rebuilt each time; section 4.2.3 discusses why pinning is slow to set up.
Both machines route their devices through SMMUs. The platform-device machine has 3 SMMU
instances, separate SMMU units that each serve part of the devices, and 53 IOMMU groups,
sets of devices that the IOMMU cannot tell apart and that are always isolated together; its NVMe
drive is in group 5. The PCIe-function machine has 5
SMMU instances of Arm’s version 3 and 86 groups; its GPU is in group 83 (IOMMU group: 83 in
the lspci output of section 26.2.1).
Some systems let a device go further and use the CPU’s own page tables. With ATS, address
translation services, a PCIe device asks the IOMMU for translations and caches them, and the
IOMMU can walk, that is, read entry by entry, the same page tables the CPU uses for a
process. nvidia-smi -q on the
PCIe-function machine reports Addressing Mode : ATS. This is why its GPU printed
pageableAccess 1 and viaHostPageTables 1 in listing 26.1: it can follow a pointer returned
by malloc, because it translates the address the same way the CPU does. The platform-device
GPU printed 0 for both, so a kernel there needs memory that CUDA allocated or registered.
26.7 The kernel-mode and user-mode drivers
The GPU is driven by 2 pieces of software, and the division between them follows from the cost of entering the kernel. Consider a program that allocates 1 buffer and then launches 1,000 kernels. The allocation changes page tables and the IOMMU, which only the kernel may do, so it must enter the kernel, but it happens once. The 1,000 launches happen often, and each needs only the stores of section 26.4.2, which a process can make itself once the right pages are mapped into it. The work is therefore split: the rare work that needs privileges goes to a part of the driver inside the kernel, and the frequent work goes to a part inside the process.
Definition 26.6 Kernel-mode and user-mode drivers. The kernel-mode driver (KMD) is the part of the GPU driver that runs inside the operating-system kernel. It alone maps the GPU’s BARs, programs the IOMMU, handles the GPU’s interrupts, manages its power and clocks, and allocates its memory. The user-mode driver (UMD) is the part of the driver that is a library loaded into each process. It implements the API, builds pushbuffers and ring entries, and keeps each context’s state.
Example. For CUDA, the UMD is libcuda.so, the library behind both the runtime API and the
driver API. cudaMalloc asks the KMD for memory; a kernel launch is made by libcuda.so alone.
A CUDA context holds the state of 1 process on 1 GPU: its allocations, its loaded kernels and
its channels. A program reaches the KMD through device files, special files in /dev whose
operations the kernel forwards to a driver. The UMD opens them, calls ioctl on them to ask for
setup work (allocate memory, create a channel), and calls mmap on them to map pages into the
process. ioctl is the system call that sends a driver-specific request through an open device
file, and mmap is the system call that maps pages, here pages of a device file, into the
address space of the process. Among those pages are the channel’s ring, pushbuffer and USERD, and the page holding
the doorbell register. From then on the UMD submits work by itself, with ordinary stores
(figure 26.10).
The 2 machines use different KMDs, which the chapter’s program shows. Each KMD is a kernel
module, a piece of the kernel that is loaded separately, and Linux shows the files that a
process holds open under /proc/<pid>/fd, where <pid> is the number of the process. Listing
the device files that a running systems process holds open:
$ ls -l /proc/<pid>/fd | grep /dev # Orin NX: nvgpu and nvmap modules
/dev/nvgpu/igpu0/ctrl /dev/nvmap /dev/dri/render...
$ ls -l /proc/<pid>/fd | grep /dev # Thor: nvidia and nvidia_uvm modules
/dev/nvidia0 (18 times) /dev/nvidiactl /dev/nvidia-uvm (2 times) /dev/nvmap ...
On the PCIe-function machine the process also had 13 mappings of /dev/nvidiactl and 2 of
/dev/nvidia0 in its address space. The platform-device GPU is driven by nvgpu, NVIDIA’s
driver for Tegra GPUs, the GPUs built into NVIDIA’s Tegra and Jetson chips, which binds to the
platform device 17000000.gpu under the name gk20a. The PCIe-function GPU is driven by
nvidia, the same open kernel module that drives discrete GPUs, with nvidia_uvm for unified
memory, the managed memory of section 26.3.2.
The split explains three facts that we stated in earlier chapters without a reason. A launch costs a few microseconds, not the tens that a system call and a return would add, because it does not enter the kernel. A CUDA context belongs to a process, because the mappings and the channels belong to a process. And a crashed kernel ends with an error in 1 process, not a crashed machine, because the KMD stays in control of the GPU and can reset the faulty channel.
Interrupts go the other way, from the device to the CPU. A device raises one to report an event, such as a finished copy or a fault, and the CPU stops what it is doing to run the KMD’s handler, the routine of the driver that deals with the event. The interrupt controller is the unit that collects the interrupts of all devices and delivers them to the CPU cores. The platform-device GPU uses wires into the interrupt controller, named in its device tree; the PCIe-function GPU sends MSI (message-signaled interrupts), which are memory writes to a special address, so they need no wire.
The device tree of the platform-device GPU gives it 4 interrupts, numbered 0x44, 0x46, 0x47 and
0x43 among the interrupt controller’s shared peripheral interrupts, the interrupts of devices
that any core may handle, and named stall0, stall1, stall2 and nonstall. The Arm
interrupt controller is called the GIC, generic interrupt controller. On a GICv3, numbers 0 to
31 are reserved for interrupts that belong to 1 core, so shared peripheral interrupts start at
number 32, so 0x44 = 68 becomes interrupt 68 + 32 = 100, and
/proc/interrupts lists it as GICv3 100 gk20a_stall; the other 3 appear as 99, 102 and 103.
Line 103 had counted 49,415,447 interrupts after 2,590,200 s of uptime, the time since the
machine started, or about 19 interrupts per second. The PCIe-function GPU uses 8 MSI
vectors, separate MSI interrupts each with its own number, listed as 8 lines named
nvidia.
Interrupts are for events that the CPU must hear about. The submission of work never needs one: the doorbell is a store from the CPU, and the CPU learns that work has finished by reading GET, or a semaphore the GPU wrote, in memory.
26.8 Observing the system on Linux
The mechanisms of this chapter can be observed on any Linux machine with a GPU, without root
privileges. The table lists the commands and what each one showed on the 2 machines. The file
/proc/<pid>/maps lists every mapped range of a process’s address space, with the file, if any,
that each range maps, and /sys/class/iommu and /sys/kernel/iommu_groups list the IOMMU
instances and groups of section 26.6.
| Command | Shows | Platform-device GPU | PCIe-function GPU |
|---|---|---|---|
lspci -nn | PCIe functions with vendor and device | no GPU on PCIe | 01:00.0 [10de:2b00] |
lspci -vv -s <addr> | command bits, BARs, IOMMU group, driver | NVMe: 16K BAR0, group 5 | GPU: 16M BAR0, group 83, nvidia |
xxd -l 64 /sys/bus/pci/devices/<addr>/config | the configuration header | NVMe | GPU |
/sys/bus/platform/devices/*gpu* | platform devices and their driver | 17000000.gpu, gk20a | none |
/sys/firmware/devicetree/base/.../reg | register windows from the device tree | 3 windows | not needed |
/proc/interrupts | interrupt lines and counts | gk20a_stall on GIC 99 to 103 | 8 × nvidia (MSI) |
ls /sys/class/iommu, /sys/kernel/iommu_groups | IOMMU instances and groups | 3, 53 groups | 5 (SMMUv3), 86 groups |
/proc/<pid>/fd, /proc/<pid>/maps | device files a CUDA process uses | nvgpu/igpu0/ctrl, nvmap | nvidia0, nvidiactl, nvidia-uvm |
nvidia-smi -q | bus ID, addressing mode, BAR1 size | not available | ATS |
One file needs root: /proc/iomem, the kernel’s map of the physical address space. An ordinary
user sees its names but every address as 0, because physical addresses help an attacker who is
trying to exploit a kernel bug:
$ grep gpu /proc/iomem # Orin NX, as a normal user
00000000-00000000 : 17000000.gpu gpu@17000000
00000000-00000000 : 17000000.gpu gpu@17000000
The platform-device GPU is not in lspci. How does Linux find it, and where are its registers?
It is a platform device: the firmware’s device tree describes it, and Linux reads the
description at boot. Its reg property gives 3 windows: 16 MiB at 0x1700_0000, 16 MiB at
0x1800_0000 and 4 KiB at 0x03B4_1000. The gk20a driver, part of the nvgpu module, binds to
it.
26.9 CUDA calls and the mechanisms beneath them
We can now relate each CUDA call that touches the hardware to the mechanisms of this chapter. 4
terms in the table need a word of explanation. The GPU has its own page tables, so a pointer
returned by cudaMalloc is a GPU virtual address, which the GPU translates as the CPU’s MMU
translates a CPU virtual address. Zero-copy access is a kernel’s direct access to pinned host
memory through the bus, without a copy into device memory. A page fault is the event in which
a processor finds no valid translation for an address; managed memory uses it to migrate
pages, that is, to move them to the processor that touched them. Peer access is the access by
1 GPU to the memory of another GPU.
| CUDA call | What happens underneath |
|---|---|
cudaMalloc | the KMD allocates device memory and maps it in the GPU’s page tables; the pointer is a GPU virtual address |
kernel<<<...>>> | the UMD writes methods and a ring entry, then stores to the doorbell; no system call |
cudaMemcpy | pins or stages the host buffer, writes copy descriptors, rings the doorbell, waits for completion |
cudaMemcpyAsync | the same on a stream’s channel, without the wait, so copies overlap kernels (Chapter 6) |
cudaMallocHost | pins host pages and maps them in the IOMMU once, so copy engines can read them directly |
cudaHostAlloc(..., cudaHostAllocWriteCombined) | pinned memory mapped write-combining for the CPU: fast streaming writes, slow reads |
cudaHostGetDevicePointer | gives the GPU an address for pinned host memory (zero-copy, section 4.6) |
cudaMallocManaged | 1 address for CPU and GPU; pages migrate on faults, or are shared outright with ATS |
cudaDeviceEnablePeerAccess | lets 1 GPU’s DMA reach another GPU’s memory (Chapter 27) |
cudaStreamSynchronize | waits until the stream’s GET passes its last entry, by polling memory or by an interrupt |
26.10 The complete programs
Listing 26.4 The complete programs. code/oxide/ch17_systems/src/main.rs and code/ch17_systems/systems.cu
//! Chapter 17 in Rust: what the driver reports about the GPU, CPU access to pinned
//! memory, and a work queue with a doorbell between 2 threads.
//!
//! cargo oxide run
use std::hint::{black_box, spin_loop};
use std::sync::atomic::{AtomicBool, AtomicU32, AtomicU64, Ordering};
use std::thread;
use std::time::Instant;
use cuda_core::sys::CUdevice_attribute_enum_CU_DEVICE_ATTRIBUTE_INTEGRATED as INTEGRATED;
use cuda_core::sys::{CUdevice, CUdevice_attribute, cuDeviceGetAttribute};
use cuda_core::{CudaContext, DriverError, IntoResult, PinnedHostBuffer};
/// Asks the driver for 1 integer attribute of `device`.
fn attribute(device: CUdevice, which: CUdevice_attribute) -> Result<i32, DriverError> {
let mut value = 0;
// SAFETY: `value` is a valid place for 1 integer, and `device` came from a live context.
unsafe { cuDeviceGetAttribute(&mut value, which, device).result()? };
Ok(value)
}
/// Sums every word, so that the reads cannot be skipped.
fn cpu_read(x: &[u32]) -> u32 {
x.iter().fold(0u32, |s, &v| s.wrapping_add(v))
}
/// Best-of-5 CPU write and read bandwidth over `x`, in GB/s.
fn time_cpu(name: &str, x: &mut [u32]) {
let bytes = (x.len() * size_of::<u32>()) as f64;
let mut best_write = f64::MAX;
let mut best_read = f64::MAX;
let mut sum = 0;
for _ in 0..5 {
let t0 = Instant::now();
x.fill(1);
let t1 = Instant::now();
sum = black_box(cpu_read(black_box(&*x)));
best_write = best_write.min((t1 - t0).as_secs_f64());
best_read = best_read.min(t1.elapsed().as_secs_f64());
}
let verdict = if sum as usize == x.len() { "PASSED" } else { "FAILED" };
let (write, read) = (bytes / best_write / 1e9, bytes / best_read / 1e9);
println!("{name:<24} write {write:6.2} GB/s read {read:6.2} GB/s {verdict}");
}
fn spin_us(us: f64) {
let start = Instant::now();
while start.elapsed().as_secs_f64() * 1e6 < us {
spin_loop();
}
}
const CAPACITY: u32 = 64;
/// Keeps 1 value alone on a 64-byte cache line, as each register has its own address.
#[repr(align(64))]
struct Line<T>(T);
/// A ring of entries (opcode in the high 32 bits, argument in the low 32) and 2 counters.
struct Channel {
ring: [AtomicU64; CAPACITY as usize],
doorbell: Line<AtomicU32>, // PUT: entries written so far
get: Line<AtomicU32>, // GET: entries the device has finished
stop: Line<AtomicBool>,
}
/// The device: wait for the doorbell, run every entry up to PUT, then report GET.
fn device(ch: &Channel, work_us: f64) -> u64 {
let mut get = 0u32;
let mut sum = 0u64;
while !ch.stop.0.load(Ordering::Acquire) {
let put = ch.doorbell.0.load(Ordering::Acquire);
while get != put {
let entry = ch.ring[(get % CAPACITY) as usize].load(Ordering::Relaxed);
spin_us(work_us);
sum += if entry >> 32 == 1 { entry & 0xffff_ffff } else { 0 };
get += 1;
ch.get.0.store(get, Ordering::Release);
}
}
sum
}
/// The host: write the entry, then ring the doorbell. Waits only when the ring is full.
fn submit(ch: &Channel, depth: u32, put: &mut u32, arg: u32) {
while put.wrapping_sub(ch.get.0.load(Ordering::Acquire)) >= depth {
spin_loop();
}
let entry = (1u64 << 32) | arg as u64;
ch.ring[(*put % CAPACITY) as usize].store(entry, Ordering::Relaxed);
ch.doorbell.0.store(*put + 1, Ordering::Release);
*put += 1;
}
/// 200 bursts: submit 32 entries of 2 us each, then do 64 us of the host's own work.
fn run_queue(depth: u32) {
let ch = Channel {
ring: std::array::from_fn(|_| AtomicU64::new(0)),
doorbell: Line(AtomicU32::new(0)),
get: Line(AtomicU32::new(0)),
stop: Line(AtomicBool::new(false)),
};
let (sum, expected, ms) = thread::scope(|s| {
let dev = s.spawn(|| device(&ch, 2.0));
let mut put = 0u32;
let mut expected = 0u64;
let start = Instant::now();
for _ in 0..200 {
for _ in 0..32 {
let arg = put + 1;
expected += arg as u64;
submit(&ch, depth, &mut put, arg);
}
spin_us(64.0);
}
while ch.get.0.load(Ordering::Acquire) != put {
spin_loop();
}
let ms = start.elapsed().as_secs_f64() * 1e3;
ch.stop.0.store(true, Ordering::Release);
(dev.join().unwrap_or(0), expected, ms)
});
let verdict = if sum == expected { "PASSED" } else { "FAILED" };
println!("depth {depth:2} {ms:7.2} ms sum {sum} of {expected} {verdict}");
}
fn main() -> Result<(), DriverError> {
let ctx = CudaContext::new(0)?;
let device = ctx.cu_device();
let (major, minor) = ctx.compute_capability()?;
println!("device {}, sm_{major}{minor}", ctx.device_name()?);
println!("SMs {}", ctx.multiprocessor_count()?);
println!("integrated {}\n", attribute(device, INTEGRATED)?);
let words = 16 << 20; // 16,777,216 words, 64 MiB
let mut pageable = vec![0u32; words];
let mut pinned = PinnedHostBuffer::<u32>::zeroed(&ctx, words)?;
println!("CPU access to 64 MiB through each mapping:");
time_cpu("Vec (pageable)", &mut pageable);
time_cpu("PinnedHostBuffer", pinned.as_mut_slice());
println!("\nWork queue: 200 bursts of 32 entries, 2 us each, 64 us of host work:");
for depth in [1, 4, 32, 64] {
run_queue(depth);
}
Ok(())
}// Chapter 17: the GPU as a device. What CUDA reports about it, how fast the CPU
// reaches each kind of memory mapping, and a work queue with a doorbell.
// Build: nvcc -arch=native -O2 systems.cu -o systems
#include <algorithm>
#include <atomic>
#include <chrono>
#include <cstdint>
#include <cstdio>
#include <cstdlib>
#include <cstring>
#include <thread>
#include <cuda_runtime.h>
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
double nowUs()
{
using namespace std::chrono;
return duration<double, std::micro>(steady_clock::now().time_since_epoch()).count();
}
void spinUs(double us)
{
double end = nowUs() + us;
while (nowUs() < end) {
}
}
// 1. What the CUDA runtime knows about the device and how it is attached.
void identity()
{
cudaDeviceProp p;
check(cudaGetDeviceProperties(&p, 0));
char busId[32];
check(cudaDeviceGetPCIBusId(busId, sizeof(busId), 0));
double gib = p.totalGlobalMem / 1073741824.0;
int l2Mib = p.l2CacheSize >> 20;
int viaHostTables = p.pageableMemoryAccessUsesHostPageTables;
std::printf("device %s, sm_%d%d\n", p.name, p.major, p.minor);
std::printf("PCI address %s\n", busId);
std::printf("integrated %d\n", p.integrated);
std::printf("memory %.1f GiB, L2 %d MiB\n", gib, l2Mib);
std::printf("copy engines %d\n", p.asyncEngineCount);
std::printf("canMapHostMemory %d\n", p.canMapHostMemory);
std::printf("unifiedAddressing %d\n", p.unifiedAddressing);
std::printf("pageableAccess %d\n", p.pageableMemoryAccess);
std::printf("viaHostPageTables %d\n", viaHostTables);
std::printf("hostNativeAtomic %d\n\n", p.hostNativeAtomicSupported);
}
// CPU reads every word of `x` and returns the sum, so the reads cannot be skipped.
uint32_t cpuRead(const uint32_t* x, size_t n)
{
uint32_t s = 0;
for (size_t i = 0; i < n; ++i) {
s += x[i];
}
return s;
}
void cpuWrite(uint32_t* x, size_t n, uint32_t v)
{
for (size_t i = 0; i < n; ++i) {
x[i] = v;
}
}
// CPU write and read bandwidth over `bytes` of `x`, in GB/s, best of `reps` passes.
void timeCpu(const char* name, uint32_t* x, size_t bytes, int reps)
{
size_t n = bytes / sizeof(uint32_t);
cpuWrite(x, n, 1);
double bestWrite = 1e30;
double bestRead = 1e30;
uint32_t sum = 0;
for (int r = 0; r < reps; ++r) {
double t0 = nowUs();
cpuWrite(x, n, 1);
double t1 = nowUs();
sum = cpuRead(x, n);
double t2 = nowUs();
bestWrite = std::min(bestWrite, t1 - t0);
bestRead = std::min(bestRead, t2 - t1);
}
double writeGBs = bytes / bestWrite / 1e3;
double readGBs = bytes / bestRead / 1e3;
const char* verdict = sum == n ? "PASSED" : "FAILED";
std::printf("%-24s write %6.2f GB/s ", name, writeGBs);
std::printf("read %6.2f GB/s %s\n", readGBs, verdict);
}
// 2. The same CPU loops over 4 kinds of memory.
void memoryTypes()
{
const size_t bytes = 64u << 20;
const int reps = 5;
uint32_t* pageable = static_cast<uint32_t*>(std::malloc(bytes));
uint32_t* pinned = nullptr;
uint32_t* combined = nullptr;
uint32_t* managed = nullptr;
check(cudaMallocHost(&pinned, bytes));
check(cudaHostAlloc(&combined, bytes, cudaHostAllocWriteCombined));
check(cudaMallocManaged(&managed, bytes));
std::printf("CPU access to %zu MiB through each mapping:\n", bytes >> 20);
timeCpu("malloc (pageable)", pageable, bytes, reps);
timeCpu("cudaMallocHost (pinned)", pinned, bytes, reps);
timeCpu("write-combined pinned", combined, bytes, reps);
timeCpu("cudaMallocManaged", managed, bytes, reps);
std::printf("\n");
check(cudaFree(managed));
check(cudaFreeHost(combined));
check(cudaFreeHost(pinned));
std::free(pageable);
}
// 3. A ring of work entries and a doorbell, between a host thread and a device thread.
struct Entry {
uint32_t opcode;
uint32_t arg;
};
struct Channel {
static const uint32_t capacity = 64;
Entry ring[capacity];
// Each counter on its own 64-byte cache line, as each register has its own address.
alignas(64) std::atomic<uint32_t> doorbell{0}; // PUT: entries written so far
alignas(64) std::atomic<uint32_t> get{0}; // GET: entries the device finished
alignas(64) std::atomic<bool> stop{false};
uint64_t sum = 0; // the device's result
};
// The device: wait for the doorbell, run every entry up to PUT, then report GET.
void device(Channel* ch, double workUs)
{
uint32_t get = 0;
while (!ch->stop.load(std::memory_order_acquire)) {
uint32_t put = ch->doorbell.load(std::memory_order_acquire);
while (get != put) {
Entry e = ch->ring[get % Channel::capacity];
spinUs(workUs);
ch->sum += e.opcode == 1 ? e.arg : 0;
get += 1;
ch->get.store(get, std::memory_order_release);
}
}
}
// The host: write an entry, then ring the doorbell. Waits only when the ring is full.
void submit(Channel* ch, uint32_t depth, uint32_t& put, uint32_t arg, bool doorbellFirst)
{
while (put - ch->get.load(std::memory_order_acquire) >= depth) {
}
Entry& slot = ch->ring[put % Channel::capacity];
if (doorbellFirst) {
ch->doorbell.store(put + 1, std::memory_order_release);
slot = Entry{1, arg};
} else {
slot = Entry{1, arg};
ch->doorbell.store(put + 1, std::memory_order_release);
}
put += 1;
}
// `bursts` times: submit `burst` entries, then do the host's own work.
void runQueue(uint32_t depth, bool doorbellFirst)
{
const int bursts = 200;
const int burst = 32;
const double workUs = 2.0;
const double hostUs = 64.0;
Channel ch;
std::thread dev(device, &ch, workUs);
uint32_t put = 0;
uint64_t expected = 0;
double t0 = nowUs();
for (int b = 0; b < bursts; ++b) {
for (int k = 0; k < burst; ++k) {
uint32_t arg = put + 1;
expected += arg;
submit(&ch, depth, put, arg, doorbellFirst);
}
spinUs(hostUs);
}
while (ch.get.load(std::memory_order_acquire) != put) {
}
double ms = (nowUs() - t0) / 1e3;
ch.stop.store(true, std::memory_order_release);
dev.join();
const char* order = doorbellFirst ? "doorbell first" : "entry first";
const char* verdict = ch.sum == expected ? "PASSED" : "FAILED";
unsigned long long got = ch.sum;
unsigned long long want = expected;
std::printf("depth %2u, %-14s %7.2f ms ", depth, order, ms);
std::printf("sum %llu of %llu %s\n", got, want, verdict);
}
int main(int argc, char** argv)
{
bool broken = argc > 1 && std::strcmp(argv[1], "--doorbell-first") == 0;
identity();
memoryTypes();
std::printf("Work queue: 200 bursts of 32 entries, 2 us each, 64 us of host work:\n");
runQueue(1, broken);
runQueue(4, broken);
runQueue(32, broken);
runQueue(64, broken);
return 0;
}
Common mistakes
- Dereferencing a device pointer on the CPU. A pointer from
cudaMallocis a GPU virtual address. On a discrete GPU the CPU has no mapping for it, and the program crashes. Only managed memory, pinned mapped memory, or ATS on systems that support it make 1 address valid on both sides. - Ringing the doorbell before the work is written. The device may read the slot early. Write the entry, then use a release store or a barrier, then the doorbell (section 26.4.6).
- Reading from write-combined memory. It is meant for streams of writes; the CPU read it 11 times slower than cached memory on the platform-device machine.
- Assuming a bus address equals a CPU address. On the platform-device machine the NVMe BAR holds 0x4000_0000 while the CPU uses 0x24_2800_0000.
- Pinning a buffer for every copy. Each pin rebuilds IOMMU entries and page locks; pin once and reuse the buffer.
- Expecting a PCIe address for every GPU. A platform-device GPU has none; the runtime reports 0000:00:00.0.
Summary
- Memory-mapped I/O makes a device’s registers answer to physical addresses; the address alone decides whether a load or store reaches DRAM or a device.
- A PCIe function is described by a 64-byte configuration header: vendor, device, class, command bits and up to 6 BARs. A BAR’s size is found by writing all ones and is always a power of 2: 16 KiB for an NVMe drive, 16 MiB for an integrated GPU’s registers.
- A discrete GPU has a BAR0 of registers and a BAR1 window on its own memory. An integrated GPU may be a PCIe function with only BAR0, or a platform device found in the device tree.
- MMIO is the control path: few bytes, written by the CPU, with posted writes and slow reads. DMA is the data path: the GPU reads and writes memory itself.
- The memory type of a mapping decides CPU speed: write-combined memory read 11 times slower than cached memory on the platform-device machine, while the PCIe-function machine mapped it cacheable.
- A kernel launch writes methods and an 8-byte entry into a ring in memory and stores 1 token to a doorbell register, with no system call. A deeper ring let the host run ahead: 200 bursts took 28.7 to 30.9 ms at depth 1 and 13.5 to 13.7 ms at depth 32, against 25.6 ms and 12.8 ms predicted.
- Writing the doorbell before the entry lost entries in some runs and not others; a release store or barrier between the 2 writes prevents it.
- The IOMMU translates and checks every device address. With ATS, the GPU can use the CPU’s
page tables and read
mallocmemory. - The kernel-mode driver sets up memory, channels, the IOMMU and interrupts through device files; the user-mode driver submits work by itself through mapped pages.
In Chapter 27, we extend the picture from 1 GPU to several, joined by NVLink: the same DMA, now from 1 GPU’s memory to another’s.
Exercises
- Run
lspci -vvon a machine with a discrete GPU. Find its BAR0 and BAR1, their sizes and whether they are prefetchable. Is Resizable BAR in use? - Compute the size of a BAR that reads back 0xFFF0_000C after all ones were written. What do the flag bits say?
- A GPU has 48 GiB of memory. What is the smallest BAR that shows all of it to the CPU?
- In the work ring of figure 26.6, GET = 13 and PUT = 19 with 8 slots. Which slots hold waiting entries, and how many more entries can the host write before it must wait?
- Predict the time of the chapter’s work queue at depth 16, then change the program to run it and compare. At what depth does the time stop falling, and why?
- Change the device thread’s work per entry from 2 µs to 4 µs. Predict and measure the times at depth 1 and 32.
- Change the program so the device thread reports GET only after every 8 entries instead of after each one. Which depths become slower, and why?
- On an x86 machine with a discrete GPU, run the memory-type part of the program. Does the write-combined flag change the CPU’s read speed there?
- Use
/proc/<pid>/fdand/proc/<pid>/mapson a running CUDA program on your machine. Which device files does it open, and how many mappings of each does it hold? - Using the NVMe formula of section 26.4.3, find the offset of queue 3’s completion doorbell when DSTRD = 2.
Sources and further reading
- PCI-SIG, PCI Express Base Specification: configuration space, BARs, posted and non-posted transactions, Resizable BAR, ATS.
- NVM Express, NVM Express Base Specification, “Controller Registers” (doorbell offsets): https://nvmexpress.org/specifications/
- NVIDIA, open GPU kernel modules, class headers
clc361.h(NOTIFY_CHANNEL_PENDING) andclc86f.h(GPFIFO entries, USERDGPPut/GPGet): https://github.com/NVIDIA/open-gpu-kernel-modules - NVIDIA, CUDA Runtime API,
cudaHostAllocandcudaDeviceProp: https://docs.nvidia.com/cuda/cuda-runtime-api/ - Linux kernel documentation, “Bus-Independent Device Accesses” (
writeland ordering) and “Dynamic DMA mapping using the generic device”: https://docs.kernel.org/driver-api/device-io.html, https://docs.kernel.org/core-api/dma-api.html - Linux kernel documentation, device-tree binding
nvidia,gk20a(thebar0/bar1windows). - Arm, Arm Architecture Reference Manual for A-profile: memory types,
DMBandDSB; Arm System Memory Management Unit Architecture Specification, SMMU version 3. lspci(8),pciutils: https://mj.ucw.cz/sw/pciutils/
Chapter 27: NVLink & NVSwitch - The Multi-GPU Interconnect
Every program in the previous chapters ran on a single GPU. Its threads read and wrote the GPU’s own memory, and the only other memory involved was host memory, reached over the link described in Chapter 4. Many applications need more than a single GPU. A model whose parameters do not fit in the memory of a GPU must be divided among several GPUs, and a computation that takes too long on a GPU can be shared among several GPUs to finish sooner. In both cases, the GPUs must exchange data while they compute, and the time spent on that exchange determines how much faster the program runs when GPUs are added.
In this chapter, we study the hardware that carries data between GPUs. We start by counting the bytes that each GPU sends in a step of a data-parallel training program, and the time those bytes take over PCIe. We then describe NVLink, NVIDIA’s interconnect between GPUs, and NVSwitch, the switch that connects many GPUs through NVLink, and we compare the ways in which 4, 8 and 72 GPUs are connected. Finally, we use the CUDA peer-to-peer API, which allows a GPU to copy to and access the memory of another GPU, and the tools that report how the GPUs of a machine are connected.
This chapter covers
- the reasons for using several GPUs, and the data they exchange in each step
- links, differential pairs, and bandwidth in each direction
- the NVLink generations, compared with PCIe and with the memory of the GPU itself
- full meshes, NVSwitch, and the number of links needed for 4, 8 and 72 GPUs
- bisection bandwidth
- unified virtual addressing, peer copies and direct access to a peer’s memory
- the CUDA peer-to-peer API in C++ and in Rust
- a performance model that shows when a faster interconnect helps
- reading the output of
nvidia-smi topo -m
The code of the chapter is in
code/ch18_peer/
for C++ and in
code/oxide/ch18_peer/
for Rust.
27.1 Scaling beyond a single GPU
27.1.1 Capacity and time
There are two reasons to use more than a single GPU, and they lead to different ways of dividing a program.
The first reason is capacity. A language model is defined by its parameters, the numbers that are learned during training. A model with 70 × 109 parameters, stored as 16-bit numbers of 2 bytes each, needs 70 × 109 × 2 = 140 GB for its parameters alone. An H100 has 80 GB of memory. Regardless of how fast the H100 computes, the model does not fit on a single H100. It needs at least 140 / 80 = 1.75, that is, 2 GPUs, and in practice more, because the computation also needs memory for its intermediate values.
The second reason is time. A computation that fits on a single GPU may still take too long there. Training a model repeats the same step many times, each time on a new batch, a group of training examples. If 8 GPUs each process a share of every batch, the training finishes sooner.
27.1.2 Dividing the work among GPUs
A program can be divided among GPUs in three ways, summarized in the following table. The division determines what data the GPUs must send to each other.
| Division | Each GPU holds | What crosses between GPUs |
|---|---|---|
| Data parallelism | a full copy of the model, and its own share of each batch | the results of each step, to be combined into 1 |
| Model parallelism | a part of every layer of the model | partial results inside every layer |
| Pipeline parallelism | whole layers, a few consecutive ones per GPU | each layer’s output, passed to the GPU with the next layer |
Data parallelism is the simplest of the 3, because every GPU runs the unchanged single-GPU program on its share of the data. Model parallelism and pipeline parallelism address the capacity problem, since no GPU holds the whole model. Real systems combine them, for example pipeline parallelism between groups of GPUs and model parallelism within each group. In every case, the GPUs send data to each other at every step.
27.1.3 Communication in data-parallel training
We use data parallelism as our example because its communication is easy to count. A training step computes a gradient for every parameter of the model. The gradient of a parameter is the direction and amount by which the parameter should change to reduce the model’s error on the batch. There is 1 gradient value per parameter, so the gradients occupy as many bytes as the parameters.
In data parallelism, each GPU computes gradients from its own share of the batch, so the gradients differ from GPU to GPU. Before any GPU updates its copy of the model, the gradients of all GPUs must be added, and every GPU must receive the sum. Otherwise, the copies of the model would diverge. The operation that adds a value held by every GPU and gives the sum to every GPU is called an all-reduce. We develop the all-reduce algorithms in Chapter 28; here we only need their cost. With the commonly used ring algorithm, each of \(N\) GPUs sends, and also receives, \(2(N - 1)/N\) times the size of the data.
Let us apply this to a concrete case. A model of 500 × 106 parameters in 16-bit numbers has 500 × 106 × 2 bytes = 1 GB of gradients. On \(N\) = 8 GPUs, each GPU sends 2 × (8 − 1) / 8 × 1 GB = 1.75 GB per step, and receives as much. PCIe 4.0 with 16 lanes, the widest PCIe connection of a GPU (lanes are defined in Section 27.2.1), carries 32 GB/s in each direction (Section 4.1.2), so sending 1.75 GB takes 1.75 / 32 = 0.0547 s, or 54.7 ms. Assume that a single GPU needs 400 ms to compute the step for the whole batch. Each of the 8 GPUs then needs 400 / 8 = 50 ms to compute its share.
The exchange therefore takes longer than the computation it serves. Figure 27.1 shows the resulting step. On 8 GPUs connected by PCIe, a step takes 50 + 54.7 = 104.7 ms, so the 8 GPUs together are only 400 / 104.7 = 3.8 times as fast as a single GPU. With the NVLink of an A100, which carries 300 GB/s in each direction, the exchange takes 1.75 / 300 = 5.8 ms, and the 8 GPUs are 400 / 55.8 = 7.2 times as fast. In Section 27.6, we generalize this example into a model.
NOTE: Training frameworks start sending the gradients of the last layers while the earlier layers are still being computed, so part of the exchange overlaps with computation, in the same way that the copies of Chapter 6 overlapped with kernels. Overlap can hide at most as much exchange time as there is computation to hide it behind. In this example, at most 50 ms of the 54.7 ms can be hidden, and the step still takes at least 54.7 ms.
Adding GPUs divides the computation of a step, but not the bytes that each GPU must exchange. The interconnect between the GPUs determines how many GPUs still make the program faster.
27.2 NVLink: a faster link between GPUs
27.2.1 Links and differential pairs
Before we describe NVLink, we need 4 terms for the hardware that connects 2 chips. We define them from the outside in: the system of connections, 1 connection, and the wires inside it.
Definition 27.1 Interconnect and link. An interconnect is the hardware that carries data between chips. A link is 1 connection of an interconnect between 2 chips. A link carries data in both directions, and its bandwidth in each direction is the maximum number of bytes that it can move per second in that direction.
Example. PCI Express (PCIe), described in Chapter 4, is the standard interconnect between a CPU and the devices plugged into it. A GPU in a PCIe slot is joined to the CPU by 1 PCIe link.
Both PCIe and NVLink transmit data as electrical signals over differential pairs. A differential pair is 2 wires that carry a signal as the difference between their voltages. Noise from outside affects both wires nearly equally, so the difference is disturbed much less than the voltage on a single wire would be. A pair carries data in 1 direction, so a link that carries data both ways needs pairs in both directions.
Definition 27.2 Lane. A PCIe lane consists of 2 differential pairs, 1 in each direction. A PCIe link is made of 1 or more lanes side by side, and its bandwidth is the number of lanes times the bandwidth of 1 lane.
Example. A lane of PCIe 4.0 carries 2 GB/s in each direction. A GPU in a slot with 16 lanes therefore has 16 × 2 = 32 GB/s in each direction, the figure used in Section 27.1.3.
Definition 27.3 NVLink. NVLink is NVIDIA’s interconnect between GPUs, and in some systems between a GPU and a CPU. It is organized into links, each a bundle of pairs in both directions. A GPU has many NVLink links. It can connect each link to a different GPU, or connect several links to the same GPU.
Example. An H100 has 18 NVLink links. In a server of 8 H100s connected directly, a GPU can give 2 links to each of the other 7 GPUs.
Let us compute the bandwidth of 1 NVLink link from its pairs. A link of NVLink 4, the generation used by the H100, has 2 pairs in each direction, and each pair signals at 100 Gbit/s. A link therefore carries 2 × 100 = 200 Gbit/s in each direction, which is 200 / 8 = 25 GB/s. An H100 has 18 links, for a total of 18 × 25 = 450 GB/s in each direction. The NVLink 3 of the A100 reached the same 25 GB/s per link with 4 pairs in each direction at half the signaling rate. NVLink 4 halved the number of pairs per link and doubled their rate, which leaves room on the chip for more links. Figure 27.2 shows a link and the 18 links of an H100.
27.2.2 Bandwidth in each direction
Recall from Definition 27.1 that the bandwidth of a link is the maximum amount of data it can carry per unit of time. A link with pairs in both directions has 2 bandwidths, 1 for each direction, and both can be used at the same time. NVIDIA quotes NVLink bandwidth as the sum of the two directions: the 900 GB/s quoted for an H100 is 450 GB/s in each direction. PCIe bandwidth is usually quoted per direction, as in Chapter 4: 32 GB/s for PCIe 4.0 with 16 lanes and 64 GB/s for PCIe 5.0.
A comparison between links must use the same convention for both. A GPU that sends its gradients to another GPU sends them in 1 direction, so in this chapter we quote every link per direction. In this unit, NVIDIA’s statement that the NVLink of the H100 has 7 times the bandwidth of PCIe 5.0 is confirmed: 450 / 64 = 7.0. The following table summarizes the quantities for an H100.
| Symbol | Meaning | For an H100 |
|---|---|---|
| \(L\) | links per GPU | 18 |
| \(b\) | bandwidth of 1 link, each way | 25 GB/s |
| \(B = L \cdot b\) | the GPU’s NVLink bandwidth, each way | 18 × 25 = 450 GB/s |
| \(2B\) | both ways, the figure NVIDIA quotes | 900 GB/s |
27.2.3 NVLink generations
Each generation of NVIDIA’s data-center GPUs has introduced a new generation of NVLink. The following table lists NVIDIA’s figures. The column for each direction is half of NVIDIA’s total.
| Link | GPU | Links | Each link, each way | Each way | Both ways (NVIDIA) |
|---|---|---|---|---|---|
| PCIe 4.0 × 16 | A100 PCIe, RTX 4090 | 16 lanes | 2 GB/s per lane | 32 GB/s | 64 GB/s |
| PCIe 5.0 × 16 | H100 PCIe, RTX 5090 | 16 lanes | 4 GB/s per lane | 64 GB/s | 128 GB/s |
| NVLink 2 | V100 | 6 | 25 GB/s | 150 GB/s | 300 GB/s |
| NVLink 3 | A100 | 12 | 25 GB/s | 300 GB/s | 600 GB/s |
| NVLink 4 | H100 | 18 | 25 GB/s | 450 GB/s | 900 GB/s |
| NVLink 5 | B200 | 18 | 50 GB/s | 900 GB/s | 1,800 GB/s |
| NVLink-C2C | GH200, CPU to GPU | 1 chip-to-chip link | 450 GB/s | 900 GB/s |
From the V100 to the H100, the rate of a single link stayed at 25 GB/s in each direction, and the bandwidth grew with the number of links: 6, 12 and 18. NVLink 5 instead doubled the rate of each link. The consumer GPUs in the table, the RTX 4090 and RTX 5090, have no NVLink, so 2 of them exchange data over PCIe. Integrated GPUs, such as the one in the DGX Spark, have no NVLink either. Each is the only GPU in its system, and it shares a single memory with the CPU.
Figure 27.3 converts these rates into the time needed to move the 1 GB of gradients from Section 27.1.3.
27.2.4 Peer bandwidth compared with local memory
A GPU’s own memory is still faster than any link. The last bar of Figure 27.3 is a copy within an H100. Its memory delivers 3,350 GB/s, and a copy both reads and writes every byte, so it moves data at 3,350 / 2 = 1,675 GB/s.
Definition 27.4 Peer. A peer of a GPU is another GPU in the same system, and the memory of a peer is called peer memory.
Example. In a server of 8 GPUs, GPU 0 has 7 peers, GPUs 1 to 7.
For a program, the important quantity is how many times slower peer memory is to reach than the GPU’s own memory. The following table uses the SXM versions of the data-center GPUs, which are modules mounted on a server board with NVLink. The same GPUs are also sold as PCIe cards, with different links and memory.
| GPU | Memory | Link to a peer, each way | Memory ÷ link |
|---|---|---|---|
| V100 SXM | 900 GB/s | NVLink 2, 150 GB/s | 6 |
| A100 SXM 80 GB | 2,039 GB/s | NVLink 3, 300 GB/s | 6.8 |
| H100 SXM | 3,350 GB/s | NVLink 4, 450 GB/s | 7.4 |
| B200 | 8,000 GB/s | NVLink 5, 900 GB/s | 8.9 |
| H100 SXM, over PCIe 5.0 | 3,350 GB/s | 64 GB/s | 52 |
Over NVLink, a peer’s memory is 6 to 9 times slower to reach than the GPU’s own memory. Over PCIe it is 52 times slower. This ratio, more than the bandwidth alone, determines which programs can treat several GPUs as 1 large GPU. For example, a kernel that reads 1 byte in 8 from a peer over NVLink spends about as much time on the link as on its own memory.
27.3 NVSwitch and topologies
27.3.1 Full-mesh topology
Once a system has more than 2 GPUs, there is more than 1 way to connect them, and the choice determines how fast each pair of GPUs can exchange data.
Definition 27.5 Topology. The topology of a multi-GPU system is the pattern of links that connects its GPUs: which pairs of chips are joined, and by how many links.
Example. 4 GPUs can be connected in a ring, 0–1–2–3–0, with 4 connections, or with a connection between every pair, with 6 connections. The 2 topologies use the same GPUs but give different bandwidths between GPUs 0 and 2: the ring has no direct connection between them.
The simplest topology gives every pair of GPUs its own link, and is called a full mesh. Let us count the links of a full mesh of 4 GPUs by hand. GPU 0 needs a link to each of GPUs 1, 2 and 3, and so do the other 3 GPUs. The 4 GPUs therefore have 4 × 3 = 12 link ends. Each link has 2 ends, 1 on each of the GPUs that it joins, so the link from GPU 0 to GPU 1 is counted once at GPU 0 and once at GPU 1. The mesh therefore has 12 / 2 = 6 links: 0–1, 0–2, 0–3, 1–2, 1–3 and 2–3. With 8 GPUs, each GPU needs 7 links, and the mesh needs 8 × 7 / 2 = 28. The same count for \(N\) GPUs gives the general rule: a full mesh of \(N\) GPUs needs \(N - 1\) links per GPU and \(N(N - 1)/2\) links in total.
Figure 27.4 shows both cases. The number of links in a mesh grows with the square of the number of GPUs, but the number of links on each GPU is fixed when the chip is designed.
Each GPU must therefore divide its links among its peers. An A100 has 12 links. In a mesh of 4 A100s, each GPU gives 12 / 3 = 4 links to each of its 3 peers, for 4 × 25 = 100 GB/s in each direction per pair. In a mesh of 8 H100s, each GPU could give 2 links to each of its 7 peers (18 / 7, rounded down, with 4 links left over), for 2 × 25 = 50 GB/s in each direction to any single peer. That is a ninth of the GPU’s 450 GB/s. The more GPUs a mesh connects, the less bandwidth is available between any 2 of them.
27.3.2 NVSwitch
A mesh runs out of links because every GPU must have a link of its own to every other GPU. A switch removes this requirement.
Definition 27.6 Switch and NVSwitch. A switch is a chip with many ports, each of which accepts 1 link, and it forwards data arriving at any port to any other port. NVSwitch is NVIDIA’s switch for NVLink. Instead of connecting GPUs to each other, each GPU connects all of its links to switches, and the switches forward its data to whichever GPU it addresses.
Example. 8 GPUs connected through switches need 8 connections, 1 bundle of links from each GPU to the switches, where a full mesh of the same 8 GPUs needs 28 links. A ninth GPU adds 1 more bundle, whereas in the mesh it would add 8 links.
The difference appears when a GPU communicates with a single peer. In a mesh, only the 2 links between the pair carry the data. Through switches, all 18 links of the GPU carry it, at the full 450 GB/s in each direction. A switch that allows every GPU to send at its full rate to any other GPU at the same time is called non-blocking. Figure 27.5 compares the two ways of connecting 8 H100s.
A switch also changes the path that data takes.
Definition 27.7 Hop. A hop is 1 crossing of a link, from 1 chip to the next chip on the path of the data. The latency of a transfer is the time between the start of the transfer and the arrival of its first byte, and every hop adds to it.
Example. In a full mesh, data from GPU 0 to GPU 3 crosses the link 0–3: 1 hop. Through a switch, it crosses the link from GPU 0 to the switch and then the link from the switch to GPU 3: 2 hops.
The switch therefore adds a hop: data travels from the GPU to a switch and then to the peer, and each hop adds latency. For exchanges larger than a few kilobytes, the gain in bandwidth outweighs the added latency.
27.3.3 NVLink systems
NVIDIA’s 8-GPU servers and its rack-scale systems are built from these components.
| System | GPUs | Switches | Each GPU’s links | Any pair, each way |
|---|---|---|---|---|
| DGX A100 | 8 A100 | 6 NVSwitch, 2nd generation | 12, 2 to each switch | 300 GB/s |
| DGX H100 | 8 H100 | 4 NVSwitch, 3rd generation, 64 ports each | 18, spread over the 4 | 450 GB/s |
| GB200 NVL72 | 72 B200 in 1 rack | 18 NVSwitch chips | 18 | 900 GB/s |
In the DGX A100, 12 links per GPU over 6 switches give 12 / 6 = 2 links from every GPU to every switch. In the DGX H100, the 8 GPUs bring 8 × 18 = 144 links to 4 × 64 = 256 switch ports. The third-generation NVSwitch also has ports for switches outside the server, so that up to 256 GPUs can be connected in a single NVLink network. The NVL72 connects 72 GPUs in a rack, each at 1,800 GB/s in both directions together: 72 × 1.8 TB/s = 129.6 TB/s, the 130 TB/s that NVIDIA quotes as the total for the rack.
The third-generation NVSwitch can also perform arithmetic. It can add the data that several GPUs send to it and return the sum, which can halve the number of bytes that some of the collective operations of Chapter 28 must move.
27.3.4 Bisection bandwidth
Topologies differ most when every GPU sends data at the same time, and a single number characterizes this case. Let us derive it on 4 GPUs before we define it. Connect GPUs 0, 1, 2 and 3 in a ring, 0–1–2–3–0, with 1 link of 25 GB/s on each edge, and let GPUs 0 and 1 each send data to GPUs 2 and 3 at the same time. Every byte must cross from the half {0, 1} to the half {2, 3}, and only 2 links join the halves: 1–2 and 3–0. The two halves can therefore exchange at most 2 × 25 = 50 GB/s in each direction, however fast each GPU is.
The answer depends on where we cut. The division into {0, 2} and {1, 3} is crossed by all 4 links of the ring, 100 GB/s. A program cannot choose which halves need to talk to each other, so the number that describes the topology is the worst case, the division crossed by the fewest links: 50 GB/s for this ring. In a full mesh of the same 4 GPUs, with 1 link per pair, every division into two halves of 2 GPUs is crossed by 2 × 2 = 4 links, 100 GB/s.
Definition 27.8 Bisection bandwidth. Divide the GPUs into two halves of equal size, choosing the division that leaves the fewest links crossing between the halves. The bisection bandwidth is the total bandwidth, in each direction, of the links that cross. It is the maximum amount of data that one half can send to the other half per unit of time, for the worst division.
Example. 4 GPUs in a ring with 1 link of 25 GB/s per edge have a bisection bandwidth of 2 × 25 = 50 GB/s; in a full mesh with 1 link per pair, 4 × 25 = 100 GB/s.
Figure 27.6 computes the bisection bandwidth of 8 GPUs, each with 18 links of 25 GB/s, connected in three ways.
Worked example: the bisection bandwidth of 8 GPUs
- Ring. Each GPU connects to its 2 neighbors with 9 links each: 9 × 25 = 225 GB/s per edge. A cut through the ring crosses 2 edges: 2 × 225 = 450 GB/s.
- Mesh. 4 GPUs on each side make 4 × 4 = 16 pairs that cross the cut, each with 2 links: 16 × 2 × 25 = 800 GB/s.
- Switch. Each of the 4 GPUs on one side sends at its full 450 GB/s through the switches: 4 × 450 = 1,800 GB/s.
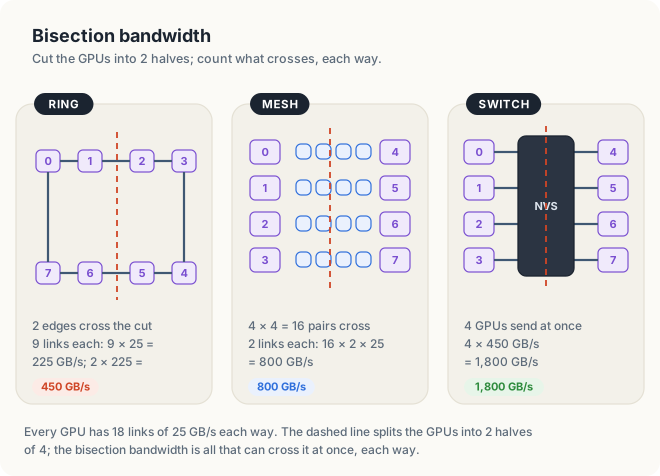
The links are the same in all three cases; only their arrangement differs. Some model-parallel programs make every GPU send to every other GPU at once, in every layer. Such exchanges run at the bisection bandwidth, and a switch gives them 4 times the bandwidth of a ring.
| Symbol | Meaning | For 8 H100s through switches |
|---|---|---|
| \(N\) | GPUs | 8 |
| \(B\) | 1 GPU’s bandwidth, each way | 450 GB/s |
| \(\frac{N}{2} B\) | bisection bandwidth of a non-blocking switch | 4 × 450 = 1,800 GB/s |
A mesh divides each GPU’s links among its peers, while a switch gives every pair all of them. The links that cross the middle of a system determine its performance when every GPU communicates at once.
27.4 Memory access across NVLink
A fast link would be useful even if it only carried copies. Together with CUDA, however, NVLink also allows a GPU to use the memory of another GPU almost as if it were its own. We now describe the 4 mechanisms that make this possible.
27.4.1 Unified virtual addressing
A pointer is a number, an address. Before a GPU can use a pointer into the memory of a peer, the program must be able to tell from that number which memory it refers to. If GPU 0 and GPU 1 each numbered their memory from the same starting address, the same pointer value could mean a byte on GPU 0 or a byte on GPU 1, and a copy function would need to be told which.
Definition 27.9 Unified virtual addressing. On a 64-bit system, CUDA places the host and all GPUs in a single range of virtual addresses. This arrangement is called unified virtual addressing (UVA). No 2 allocations, on any GPU or on the host, receive the same address, so the value of a pointer alone determines which memory it points to.
Example. A program allocates a on GPU 0 and b on GPU 1. Under UVA, the addresses of a and
of b lie in different parts of 1 address range, so the runtime can tell from the value of b
alone that it points into the memory of GPU 1.
The program of Section 27.5 uses cudaPointerGetAttributes to ask the
runtime where a buffer resides. It copies with cudaMemcpyDefault, which tells the runtime to
infer the direction of the copy from the 2 pointers.
UVA is related to the unified memory of Section 4.5, but it provides only part of it: the addresses are shared, while the data stays in the memory where it was allocated.
27.4.2 Peer copies and direct peer access
Data can reach a peer’s memory in two ways, and the program of Section 27.5 measures both.
- A copy.
cudaMemcpyPeerAsyncasks the copy engines of the GPU, the units that move data without using any streaming multiprocessor (SM) (Section 4.2.2), to move a block of bytes from 1 GPU to another. - Direct access. A kernel running on GPU 0 dereferences a pointer into the memory of GPU 1, and each load or store travels over the link. No copy is made, and the kernel reads only the bytes it needs, wherever they are in the peer’s memory.
Definition 27.10 Peer access. Peer access from GPU i to GPU j is the permission for kernels running on GPU i to load from and store to the memory of GPU j through pointers, and for copies from GPU i to GPU j to go directly to that memory. It is granted in 1 direction at a time.
Example. After GPU 0 enables peer access to GPU 1, a kernel on GPU 0 can read b[5] in the
memory of GPU 1. A kernel on GPU 1 still cannot read the memory of GPU 0 until GPU 1 enables peer
access to GPU 0.
Direct access must be enabled, once, with cudaDeviceEnablePeerAccess. Copies work without
it, but the runtime then stages them through host memory. It copies from GPU 0 to the host
and then from the host to GPU 1, crossing PCIe twice where once would suffice. Figure 27.7
shows the 3 paths that a copy can take.
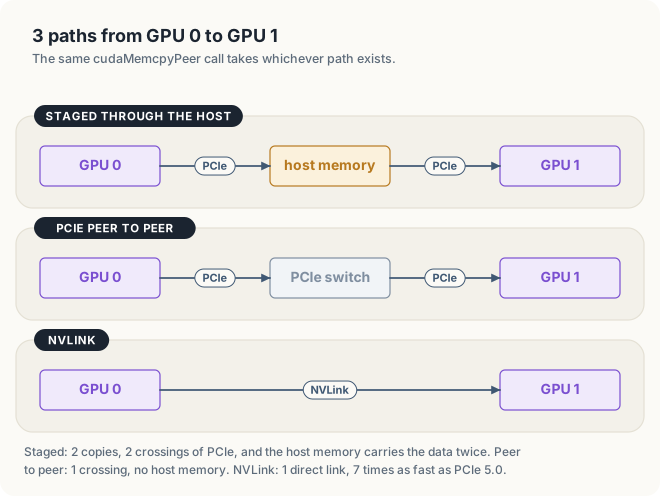
A peer-to-peer (P2P) transfer is any transfer from 1 GPU to another that does not pass
through host memory. In Figure 27.7, the second and third paths are peer-to-peer, and the first is
not. Over PCIe, the platform determines whether P2P is possible. It works most
reliably when the 2 GPUs are behind the same PCIe switch, and many desktop systems do not allow
it at all. Over NVLink it is always possible. cudaDeviceCanAccessPeer reports, for a pair of
GPUs, whether it is.
27.4.3 Atomic operations on peer memory
The atomic operations of Chapter 5 can target a peer’s memory, so threads on 2 GPUs can add to
the same counter. NVLink carries atomic operations as such, and the peer’s memory performs
them. Whether a given pair of GPUs supports this natively is reported by
cudaDeviceGetP2PAttribute with the attribute cudaDevP2PAttrNativeAtomicSupported. Each such
atomic operation crosses the link and waits for its result. Peer atomics are therefore suited
to infrequent events, such as a flag or a work counter, and not to an update per element.
27.4.4 NVLink-C2C and coherence
The Grace Hopper superchip, GH200, connects a Grace CPU and an H100 GPU with NVLink-C2C, a chip-to-chip link of 450 GB/s in each direction. The link is coherent: when the CPU writes a value that the GPU holds in a cache, the hardware updates or invalidates the GPU’s copy, and vice versa, so neither processor reads a stale value. CPU threads and GPU threads can therefore work on the same data at the same time, without copies and without the page migrations of unified memory. Integrated GPUs, such as the one in the DGX Spark, go further. They share a single memory with their CPU, so there is no second memory to copy to.
27.5 Peer-to-peer in CUDA
27.5.1 Structure of the program
The program of this section asks the system three questions and measures the answer to the last:
- How many GPUs are there, and what are they?
- Which GPUs can access the memory of which other GPUs?
- How fast do bytes move from GPU 0 to GPU 1, by a copy and by a kernel?
On a machine with 2 GPUs that can access each other, the copies go from GPU 0 to GPU 1. On a machine with a single GPU, they stay within GPU 0, and the program measures the GPU’s own memory, the baseline against which we compared every link in Section 27.2.4. The following pseudocode summarizes the program.
count ← number of GPUs
print each GPU's name and SMs
for each pair (i, j), i ≠ j:
print whether GPU i can access GPU j
if count > 1 and GPU 0 can access GPU 1:
src ← 0, dst ← 1, enable peer access from GPU 0 to GPU 1
else:
src ← 0, dst ← 0
a ← 128 MiB on GPU src, filled with known values
b ← 128 MiB on GPU dst
for each way in (cudaMemcpyPeerAsync, copy kernel on GPU src):
b ← 0
time 50 transfers of a into b, after 0.4 s of warm-up
check b against the known values
The measurements in this chapter come from 2 integrated GPUs: a Jetson Orin NX (8 SMs, 102 GB/s) and a Jetson AGX Thor (20 SMs, 32 MiB of L2 cache). The buffers are 128 MiB, 4 times the larger of the 2 L2 caches, so the copies measure memory rather than the cache (Chapter 7).
27.5.2 Querying peer access
cudaGetDeviceCount returns the number of GPUs, which are numbered from 0.
cudaDeviceCanAccessPeer sets its first argument to 1 if the GPU given by its second argument
can access the memory of the GPU given by its third argument. Note that the query has a
direction: whether GPU 0 can access GPU 1 and whether GPU 1 can access GPU 0 are queried, and
enabled, separately. Listing 27.1 prints the resulting matrix.
Listing 27.1 The number of GPUs and the peer matrix. Rust C++
fn device_count() -> Result<usize, DriverError> {
let mut count = 0;
// SAFETY: `count` is a valid place for the driver to write 1 integer, and the driver
// was initialized by `CudaContext::new` before this call.
unsafe { cuda_core::sys::cuDeviceGetCount(&mut count).result()? };
Ok(count as usize)
}
/// The peer matrix: can the GPU of each row read and write the memory of each column?
fn print_peer_matrix(gpus: &[Arc<CudaContext>]) -> Result<(), DriverError> {
print!("peer access (row can reach column):\n ");
for j in 0..gpus.len() {
print!(" GPU{j}");
}
println!();
for (i, from) in gpus.iter().enumerate() {
print!(" GPU{i}");
for (j, to) in gpus.iter().enumerate() {
let cell = if i == j {
"X"
} else if peer::can_access_peer(from, to)? {
"yes"
} else {
"no"
};
print!(" {cell:>4}");
}
println!();
}
Ok(())
}// The peer matrix: can the GPU of each row read and write the memory of each column?
void printPeerMatrix(int count)
{
std::printf("peer access (row can reach column):\n ");
for (int j = 0; j < count; ++j) {
std::printf(" GPU%d", j);
}
std::printf("\n");
for (int i = 0; i < count; ++i) {
std::printf(" GPU%d", i);
for (int j = 0; j < count; ++j) {
int ok = 0;
if (i != j) check(cudaDeviceCanAccessPeer(&ok, i, j));
const char* cell = i == j ? "X" : ok ? "yes" : "no";
std::printf(" %4s", cell);
}
std::printf("\n");
}
}
cuda-core, the host library of cuda-oxide, provides the same query as
peer::can_access_peer(from, to) between 2 CudaContexts. At revision b7fe543 it has no
function that returns the number of GPUs, so the Rust program calls the driver function
cuDeviceGetCount through cuda_core::sys, the raw driver bindings, in a single unsafe
line. The driver must already be initialized when the call is made, which
CudaContext::new(0) ensures.
27.5.3 Enabling peer access and allocating the buffers
cudaDeviceEnablePeerAccess(peer, 0) allows the current GPU, selected with cudaSetDevice, to
access the memory of the GPU peer. The second argument is reserved for flags and must be 0.
The call maps the peer’s memory into the page tables of the current GPU. This mapping takes
time, so the call is made once and not inside a loop.
Listing 27.2 Choosing the 2 GPUs and enabling access.
fn main() -> Result<(), Error> {
// ...
// Copy from GPU 0 to GPU 1 if GPU 0 can reach it, otherwise within GPU 0.
let reachable = count > 1 && peer::can_access_peer(&gpus[0], &gpus[1])?;
let (src, dst) = if reachable { (0, 1) } else { (0, 0) };
if reachable {
peer::enable_peer_access(&gpus[src], &gpus[dst])?;
} else {
println!("no peer to reach: copying within GPU0");
}
// ...
}int main()
{
// ...
// Copy from GPU 0 to GPU 1 if GPU 0 can reach it, otherwise within GPU 0.
int src = 0;
int dst = 0;
int ok = 0;
if (count > 1) check(cudaDeviceCanAccessPeer(&ok, 0, 1));
if (ok) {
dst = 1;
check(cudaSetDevice(src));
check(cudaDeviceEnablePeerAccess(dst, 0));
} else {
std::printf("no peer to reach: copying within GPU0\n");
}
// ...
}
peer::enable_peer_access(from, to) corresponds to cudaDeviceEnablePeerAccess; it also
returns Ok when access is already enabled.
Each buffer is allocated on its own GPU. Since cudaMalloc allocates on the current GPU, the
program selects GPU src before allocating a and GPU dst before allocating b.
cudaPointerGetAttributes then determines, from the pointer b alone, which GPU holds the
buffer.
Listing 27.3 A buffer on each GPU, and, in C++, the location of b reported through UVA.
fn main() -> Result<(), Error> {
// ...
let host: Vec<f32> = (0..N).map(|i| (i % 1000) as f32).collect();
let stream = gpus[src].new_stream()?;
let dst_stream = gpus[dst].new_stream()?;
let a = DeviceBuffer::from_host(&stream, &host)?;
let mut b = DeviceBuffer::<f32>::zeroed(&dst_stream, N)?;
// ...
}int main()
{
// ...
float* a;
float* b;
check(cudaSetDevice(src));
check(cudaMalloc(&a, BYTES));
check(cudaSetDevice(dst));
check(cudaMalloc(&b, BYTES));
check(cudaMemcpy(a, host.data(), BYTES, cudaMemcpyDefault));
// Unified addressing: the pointer alone tells the runtime which GPU holds it.
cudaPointerAttributes where;
check(cudaPointerGetAttributes(&where, b));
std::printf("buffer b lives on GPU%d\n", where.device);
// ...
}
In Rust, each GPU has its own CudaContext and its own stream, and a DeviceBuffer is
allocated on the GPU whose stream creates it.
27.5.4 Peer copies and copy kernels
The first method is a copy. cudaMemcpyPeerAsync(dst pointer, dst GPU, src pointer, src GPU, bytes, stream) names both GPUs, and when peer access is enabled the copy goes directly across
the link. With a single GPU, the source and destination are both GPU 0, and the call performs
an ordinary copy within its memory. The second method is a kernel running on GPU src in which
each thread copies 1 float from a to b. On 2 GPUs, the stores of this kernel are written to
the peer’s memory.
Listing 27.4 The copy kernel.
#[cuda_module]
mod kernels {
use super::*;
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn copy(src: &[f32], mut dst: DisjointSlice<f32>) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(out) = dst.get_mut(idx) {
*out = src[i];
}
}
}__global__ void copyKernel(const float* src, float* dst, size_t n)
{
size_t i = size_t(blockIdx.x) * blockDim.x + threadIdx.x;
if (i < n) dst[i] = src[i];
}
Listing 27.5 A copy and a kernel, each timed and checked.
fn main() -> Result<(), Error> {
// ...
let ms_peer = average_ms(&stream, || Ok(b.copy_from_device_async(&a, &stream)?))?;
let ok_peer = b.to_host_vec(&dst_stream)? == host;
report("copy_from_device_async", ms_peer, ok_peer);
b = DeviceBuffer::<f32>::zeroed(&dst_stream, N)?;
gpus[src].bind_to_thread()?;
let ms_kernel = average_ms(&stream, || Ok(module.copy(&stream, &launch, &a, &mut b)?))?;
let ok_kernel = b.to_host_vec(&dst_stream)? == host;
report("copy kernel on GPU0", ms_kernel, ok_kernel);
// ...
}int main()
{
// ...
auto peerCopy = [&] {
check(cudaMemcpyPeerAsync(b, dst, a, src, BYTES, stream));
};
unsigned blocks = unsigned((N + 255) / 256);
auto kernelCopy = [&] {
copyKernel<<<blocks, 256, 0, stream>>>(a, b, N);
};
clear(b, dst);
float msPeer = averageMs(peerCopy, stream);
bool okPeer = matches(b, host);
report("cudaMemcpyPeerAsync", msPeer, okPeer);
clear(b, dst);
float msKernel = averageMs(kernelCopy, stream);
check(cudaGetLastError());
bool okKernel = matches(b, host);
report("copy kernel on GPU0", msKernel, okKernel);
// ...
}
The function averageMs first runs its argument for 0.4 s so that the GPU’s clock can rise,
as measured in Chapter 6, and then times 50 runs with events. The function matches copies b
back to the host and compares all 33,554,432 floats with the values written into a. The
function clear sets b to 0 before each method, so that a method that copies nothing cannot
pass by finding the result of the previous method.
In Rust, DeviceBuffer::copy_from_device_async performs the copy. It calls the driver’s
device-to-device copy, which, with UVA, also works between GPUs. The kernel uses the 1-D launch
contract of Chapter 13: src is a plain slice, and DisjointSlice allows each thread to write
its own element of dst without unsafe code.
27.5.5 Results
$ nvcc -arch=native peer.cu -o peer && ./peer
GPUs: 1
GPU0 Orin, 8 SMs, unified addressing yes
peer access (row can reach column):
GPU0
GPU0 X
no peer to reach: copying within GPU0
buffer b lives on GPU0
128 MiB from GPU0 to GPU0, average of 50 copies
cudaMemcpyPeerAsync 3.462 ms 38.8 GB/s PASSED
copy kernel on GPU0 3.677 ms 36.5 GB/s PASSED
The first lines of the output are as expected. There is 1 GPU, so the matrix contains only its
diagonal, X, and the program copies within GPU 0. UVA is enabled, and
cudaPointerGetAttributes reports that b resides on GPU 0. On the second GPU, the program
prints the same first lines:
$ ./peer
GPUs: 1
GPU0 NVIDIA Thor, 20 SMs, unified addressing yes
peer access (row can reach column):
GPU0
GPU0 X
no peer to reach: copying within GPU0
buffer b lives on GPU0
Both copies pass on this GPU as well, in C++ and in Rust.
To interpret the rates, we use the reasoning of Section 27.2.4. A copy of 128 MiB, which is 134.2 MB, in 3.462 ms corresponds to 134.2 / 3.462 = 38.8 GB/s copied. Every copied byte is read once and written once, so the memory moved 2 × 38.8 = 77.6 GB/s, which is 76% of the GPU’s 102 GB/s. A copy cannot use all of the memory bandwidth, because the memory loses time each time it switches between reading and writing. The copy kernel ran within 6% of the copy call; in both cases the memory, not the SMs, limited the rate. Across 6 runs, the copy measured between 38.8 and 42.3 GB/s, a spread of 9%.
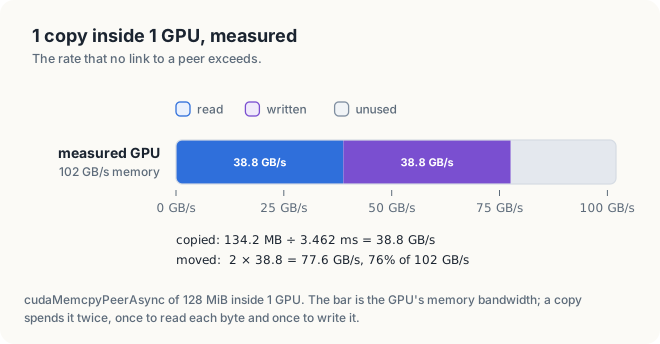
The Rust program prints the same lines except the UVA details, because cuda-core does not provide the pointer query at this revision.
$ cargo oxide run
GPUs: 1
GPU0 Orin, 8 SMs
peer access (row can reach column):
GPU0
GPU0 X
no peer to reach: copying within GPU0
128 MiB from GPU0 to GPU0, average of 50 copies
copy_from_device_async 3.528 ms 38.0 GB/s PASSED
copy kernel on GPU0 3.769 ms 35.6 GB/s PASSED
copy_from_device_async calls the same driver copy as the C++ program, and it ran within 2% of
it, which is within the spread between runs.
27.5.6 Output on a multi-GPU system
On a server with 8 GPUs connected through NVSwitch, the matrix contains yes in every cell off
the diagonal, because every GPU can reach every other GPU through the switches. On a desktop
with 2 consumer GPUs on PCIe, it may contain no. In that case, the copy still works, but it is
staged through host memory. When GPU 0 can access GPU 1, the program prints buffer b lives on GPU1, and the 2 rates are those of the link rather than of memory; between 2 H100s they can
approach 450 GB/s in each direction. The rate of a copy within a single GPU is an upper bound
that no link to a peer exceeds.
TIP: Run peer on a multi-GPU machine, such as a cloud instance with 2 or 8 GPUs, and
compare its rates with the table of Section 27.2.3. A rate far below the table usually means
that the copies are being staged through the host; check the matrix for no.
27.6 When a faster interconnect helps
27.6.1 A model of a training step
In Section 27.1.3, we computed the time of a step by hand. Writing the same arithmetic with symbols tells us when a faster link improves performance. Let a step take \(T_1\) on a single GPU. On \(N\) GPUs, each GPU computes for \(T_1 / N\) and then exchanges data for \(T_x\), a time that does not decrease with \(N\):
\[ T_N = \frac{T_1}{N} + T_x, \qquad S = \frac{T_1}{T_N} \]
| Symbol | Meaning | 8 A100s on PCIe 4.0 | 8 A100s on NVLink 3 |
|---|---|---|---|
| \(T_1\) | 1 step on 1 GPU | 400 ms | 400 ms |
| \(N\) | GPUs | 8 | 8 |
| \(T_x\) | exchange per step: bytes ÷ link, each way | 1.75 GB ÷ 32 GB/s = 54.7 ms | 1.75 GB ÷ 300 GB/s = 5.8 ms |
| \(T_N\) | 1 step on \(N\) GPUs | 50 + 54.7 = 104.7 ms | 50 + 5.8 = 55.8 ms |
| \(S\) | speedup | 400 ÷ 104.7 = 3.8 | 400 ÷ 55.8 = 7.2 |
The model is Amdahl’s law from Section 1.3, with \(T_x\) as the part that does not divide among processors, and its conclusion is the same: when \(T_x\) is comparable to \(T_1/N\), adding GPUs brings little benefit. The link determines \(T_x\), and therefore the number of GPUs that still improve performance.
For example, suppose we require the exchange to take at most a quarter of each GPU’s computation time, \(T_x \le T_1 / (4N)\), which here is 400 / 32 = 12.5 ms. Over PCIe 4.0, \(T_x\) = 54.7 ms, 4.4 times too long. Over NVLink 3, \(T_x\) = 5.8 ms, within the limit. The model also shows how the balance changes with the workload. Doubling the size of the model doubles both \(T_1\) and the number of bytes exchanged, so their ratio does not change. Halving the batch halves \(T_1\) but not the bytes, so the exchange becomes relatively more important.
27.6.2 Workloads and interconnect requirements
The model classifies programs by the ratio of their exchange time to their computation time.
| Workload | Exchange per step | Link |
|---|---|---|
| data-parallel training of a large model | all gradients, every step | NVLink pays off |
| model parallelism inside every layer | partial results, every layer | NVLink needed |
| graph analytics, databases spread over GPUs | small, scattered reads of peers’ memory | NVLink pays off |
| many independent jobs, 1 per GPU | none | PCIe is enough |
| loading a dataset once, then computing for hours | once | PCIe is enough |
| inference of a model that fits on 1 GPU | none between GPUs | PCIe is enough |
The entries of the table follow from the arithmetic of the model rather than from fixed rules. To decide for a given program, measure the 2 terms: \(T_1\) with the events of Chapter 6, and \(T_x\) with the program of Section 27.5 or with nccl-tests, which we introduce in Chapter 28.
27.7 Topology discovery
27.7.1 nvidia-smi topo -m
A program cannot choose good pairs of GPUs without knowing how they are connected. The command
nvidia-smi topo -m prints the topology as a matrix with 1 row and one column per GPU, and each
cell contains a code for the path between the 2 GPUs. On the second GPU of Section 27.5.5, it
prints the following:
$ nvidia-smi topo -m
GPU0 CPU Affinity NUMA Affinity GPU NUMA ID
GPU0 X 0-13 0 N/A
Legend:
X = Self
SYS = Connection traversing PCIe as well as the SMP interconnect between NUMA nodes (e.g., QPI/UPI)
NODE = Connection traversing PCIe as well as the interconnect between PCIe Host Bridges within a NUMA node
PHB = Connection traversing PCIe as well as a PCIe Host Bridge (typically the CPU)
PXB = Connection traversing multiple PCIe bridges (without traversing the PCIe Host Bridge)
PIX = Connection traversing at most a single PCIe bridge
NV# = Connection traversing a bonded set of # NVLinks
The matrix has a single cell, X, which is the GPU itself. The other columns identify the CPU
cores closest to the GPU, here cores 0 to 13. A NUMA node is a group of CPU cores together
with the memory attached to them; the GPU belongs to node 0, the only node of this system. On
some integrated GPUs, nvidia-smi does not implement the matrix and prints Failed to run topology matrix.
27.7.2 Connection codes
The legend lists the paths from the fastest, at the bottom, to the slowest, at the top. A PCIe bridge is a PCIe switch. A host bridge is the point where PCIe enters the CPU. An SMP interconnect connects the CPU sockets of a server with more than one CPU.
| Code | Path between the 2 GPUs | Peer to peer |
|---|---|---|
NV# | # NVLinks, bonded into 1 connection | yes, over NVLink |
PIX | at most 1 PCIe switch | usually possible |
PXB | several PCIe switches, not through the CPU | often possible |
PHB | through the CPU’s host bridge | depends on the platform |
NODE | between host bridges of 1 CPU | rarely |
SYS | across CPU sockets | no; staged through the host |
Figure 27.9 shows a matrix of this form for an example server with 4 GPUs on 2 CPU sockets, in which GPUs 0 and 1, and GPUs 2 and 3, are connected by 4 NVLinks. The figure illustrates the format; it is not output from a real machine.
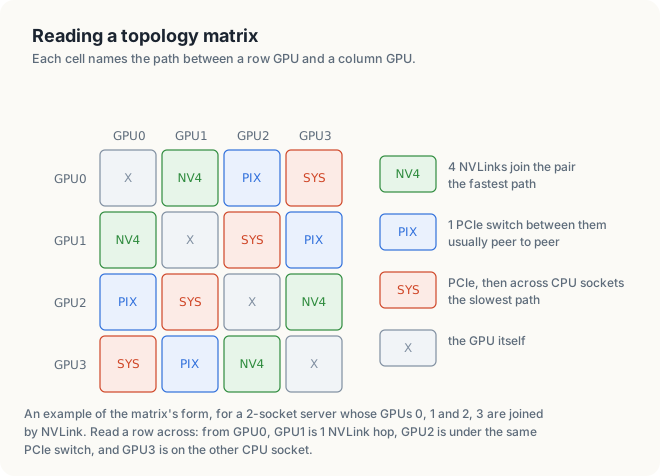
On such a server, a program that uses 2 GPUs should choose GPUs 0 and 1, or GPUs 2 and 3. Choosing GPUs 0 and 3 would send every byte across the CPU sockets.
27.7.3 NVLink status and NVML
nvidia-smi nvlink -s lists the NVLinks of each GPU, with the rate of each link and whether it
is active. On a GPU that is the only GPU in its system, it prints Device does not have or support Nvlink. A program that must adapt to the machine can read the same information from
NVML, the library on which nvidia-smi is built. nvmlDeviceGetTopologyCommonAncestor
returns the nearest common point on the paths of 2 GPUs, which corresponds to the codes of the
table above, and nvmlDeviceGetNvLinkState reports the state of each link.
27.8 The complete programs
Listing 27.6 The complete programs. code/oxide/ch18_peer/src/main.rs code/ch18_peer/peer.cu
//! Chapter 18 in Rust: which GPUs can reach each other's memory, and how fast bytes move.
//!
//! cargo oxide run
//!
//! With 2 or more GPUs that can reach each other, the copies go from GPU 0 to GPU 1.
//! With 1 GPU, they stay inside GPU 0 and measure its own memory instead.
use std::sync::Arc;
use std::time::{Duration, Instant};
use cuda_core::sys::CUevent_flags_enum_CU_EVENT_DEFAULT as TIMING;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, DriverError, IntoResult};
use cuda_core::{LaunchConfig1D, peer};
use cuda_device::{DisjointSlice, cuda_module, kernel, launch_contract, thread};
const N: usize = 32 << 20; // 33,554,432 floats, 128 MiB
const BYTES: usize = N * 4;
const REPS: u32 = 50;
type Error = Box<dyn std::error::Error>;
#[cuda_module]
mod kernels {
use super::*;
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn copy(src: &[f32], mut dst: DisjointSlice<f32>) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(out) = dst.get_mut(idx) {
*out = src[i];
}
}
}
fn device_count() -> Result<usize, DriverError> {
let mut count = 0;
// SAFETY: `count` is a valid place for the driver to write 1 integer, and the driver
// was initialized by `CudaContext::new` before this call.
unsafe { cuda_core::sys::cuDeviceGetCount(&mut count).result()? };
Ok(count as usize)
}
/// The peer matrix: can the GPU of each row read and write the memory of each column?
fn print_peer_matrix(gpus: &[Arc<CudaContext>]) -> Result<(), DriverError> {
print!("peer access (row can reach column):\n ");
for j in 0..gpus.len() {
print!(" GPU{j}");
}
println!();
for (i, from) in gpus.iter().enumerate() {
print!(" GPU{i}");
for (j, to) in gpus.iter().enumerate() {
let cell = if i == j {
"X"
} else if peer::can_access_peer(from, to)? {
"yes"
} else {
"no"
};
print!(" {cell:>4}");
}
println!();
}
Ok(())
}
/// Average time of 1 run of `run`, in milliseconds, after 0.4 s of warm-up runs.
fn average_ms(
stream: &CudaStream,
mut run: impl FnMut() -> Result<(), Error>,
) -> Result<f32, Error> {
let begin = Instant::now();
while begin.elapsed() < Duration::from_millis(400) {
run()?;
stream.synchronize()?;
}
let start = stream.record_event(Some(TIMING))?;
for _ in 0..REPS {
run()?;
}
let stop = stream.record_event(Some(TIMING))?;
stop.synchronize()?;
Ok(start.elapsed_ms(&stop)? / REPS as f32)
}
fn report(how: &str, ms: f32, ok: bool) {
let gb_per_s = BYTES as f64 / 1e9 / (ms as f64 / 1e3);
let verdict = if ok { "PASSED" } else { "FAILED" };
println!(" {how:<26} {ms:7.3} ms {gb_per_s:7.1} GB/s {verdict}");
}
fn main() -> Result<(), Error> {
let first = CudaContext::new(0)?;
let count = device_count()?;
println!("GPUs: {count}");
let mut gpus = vec![first];
for d in 1..count {
gpus.push(CudaContext::new(d)?);
}
for (d, gpu) in gpus.iter().enumerate() {
let name = gpu.device_name()?;
let sms = gpu.multiprocessor_count()?;
println!(" GPU{d} {name}, {sms} SMs");
}
print_peer_matrix(&gpus)?;
// Copy from GPU 0 to GPU 1 if GPU 0 can reach it, otherwise within GPU 0.
let reachable = count > 1 && peer::can_access_peer(&gpus[0], &gpus[1])?;
let (src, dst) = if reachable { (0, 1) } else { (0, 0) };
if reachable {
peer::enable_peer_access(&gpus[src], &gpus[dst])?;
} else {
println!("no peer to reach: copying within GPU0");
}
let host: Vec<f32> = (0..N).map(|i| (i % 1000) as f32).collect();
let stream = gpus[src].new_stream()?;
let dst_stream = gpus[dst].new_stream()?;
let a = DeviceBuffer::from_host(&stream, &host)?;
let mut b = DeviceBuffer::<f32>::zeroed(&dst_stream, N)?;
gpus[src].bind_to_thread()?;
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&gpus[src])? };
let launch = module.prepare_copy(LaunchConfig1D::new((N / 256) as u32, 256, 0))?;
println!("{} MiB from GPU{src} to GPU{dst}, average of {REPS} copies", BYTES >> 20);
let ms_peer = average_ms(&stream, || Ok(b.copy_from_device_async(&a, &stream)?))?;
let ok_peer = b.to_host_vec(&dst_stream)? == host;
report("copy_from_device_async", ms_peer, ok_peer);
b = DeviceBuffer::<f32>::zeroed(&dst_stream, N)?;
gpus[src].bind_to_thread()?;
let ms_kernel = average_ms(&stream, || Ok(module.copy(&stream, &launch, &a, &mut b)?))?;
let ok_kernel = b.to_host_vec(&dst_stream)? == host;
report("copy kernel on GPU0", ms_kernel, ok_kernel);
if !(ok_peer && ok_kernel) {
return Err("a copy did not match its source".into());
}
Ok(())
}// Chapter 18: which GPUs can reach each other's memory, and how fast bytes move.
// Build: nvcc -arch=native peer.cu -o peer
//
// With 2 or more GPUs that can reach each other, the copies go from GPU 0 to GPU 1.
// With 1 GPU, they stay inside GPU 0 and measure its own memory instead.
#include <chrono>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cuda_runtime.h>
const size_t N = size_t(32) << 20; // 33,554,432 floats, 128 MiB
const size_t BYTES = N * sizeof(float);
const int REPS = 50;
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
__global__ void copyKernel(const float* src, float* dst, size_t n)
{
size_t i = size_t(blockIdx.x) * blockDim.x + threadIdx.x;
if (i < n) dst[i] = src[i];
}
// The peer matrix: can the GPU of each row read and write the memory of each column?
void printPeerMatrix(int count)
{
std::printf("peer access (row can reach column):\n ");
for (int j = 0; j < count; ++j) {
std::printf(" GPU%d", j);
}
std::printf("\n");
for (int i = 0; i < count; ++i) {
std::printf(" GPU%d", i);
for (int j = 0; j < count; ++j) {
int ok = 0;
if (i != j) check(cudaDeviceCanAccessPeer(&ok, i, j));
const char* cell = i == j ? "X" : ok ? "yes" : "no";
std::printf(" %4s", cell);
}
std::printf("\n");
}
}
// Average time of 1 run of `run`, in milliseconds, after 0.4 s of warm-up runs.
template <typename F>
float averageMs(F run, cudaStream_t stream)
{
auto begin = std::chrono::steady_clock::now();
auto warm = std::chrono::milliseconds(400);
while (std::chrono::steady_clock::now() - begin < warm) {
run();
check(cudaStreamSynchronize(stream));
}
cudaEvent_t start, stop;
check(cudaEventCreate(&start));
check(cudaEventCreate(&stop));
check(cudaEventRecord(start, stream));
for (int r = 0; r < REPS; ++r) run();
check(cudaEventRecord(stop, stream));
check(cudaEventSynchronize(stop));
float ms;
check(cudaEventElapsedTime(&ms, start, stop));
check(cudaEventDestroy(start));
check(cudaEventDestroy(stop));
return ms / REPS;
}
bool matches(const float* dst, const std::vector<float>& expected)
{
std::vector<float> got(N);
check(cudaMemcpy(got.data(), dst, BYTES, cudaMemcpyDefault));
for (size_t i = 0; i < N; ++i) {
if (got[i] != expected[i]) return false;
}
return true;
}
void clear(float* p, int device)
{
check(cudaSetDevice(device));
check(cudaMemset(p, 0, BYTES));
check(cudaDeviceSynchronize());
check(cudaSetDevice(0));
}
void report(const char* how, float ms, bool ok)
{
double gbPerS = BYTES / 1e9 / (ms / 1e3);
const char* verdict = ok ? "PASSED" : "FAILED";
std::printf(" %-26s %7.3f ms %7.1f GB/s %s\n", how, ms, gbPerS, verdict);
}
int main()
{
int count = 0;
check(cudaGetDeviceCount(&count));
std::printf("GPUs: %d\n", count);
for (int d = 0; d < count; ++d) {
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, d));
const char* uva = prop.unifiedAddressing ? "yes" : "no";
std::printf(" GPU%d %s, %d SMs, ", d, prop.name, prop.multiProcessorCount);
std::printf("unified addressing %s\n", uva);
}
printPeerMatrix(count);
// Copy from GPU 0 to GPU 1 if GPU 0 can reach it, otherwise within GPU 0.
int src = 0;
int dst = 0;
int ok = 0;
if (count > 1) check(cudaDeviceCanAccessPeer(&ok, 0, 1));
if (ok) {
dst = 1;
check(cudaSetDevice(src));
check(cudaDeviceEnablePeerAccess(dst, 0));
} else {
std::printf("no peer to reach: copying within GPU0\n");
}
std::vector<float> host(N);
for (size_t i = 0; i < N; ++i) {
host[i] = float(i % 1000);
}
float* a;
float* b;
check(cudaSetDevice(src));
check(cudaMalloc(&a, BYTES));
check(cudaSetDevice(dst));
check(cudaMalloc(&b, BYTES));
check(cudaMemcpy(a, host.data(), BYTES, cudaMemcpyDefault));
// Unified addressing: the pointer alone tells the runtime which GPU holds it.
cudaPointerAttributes where;
check(cudaPointerGetAttributes(&where, b));
std::printf("buffer b lives on GPU%d\n", where.device);
check(cudaSetDevice(src));
cudaStream_t stream;
check(cudaStreamCreate(&stream));
std::printf("%zu MiB from GPU%d to GPU%d, ", BYTES >> 20, src, dst);
std::printf("average of %d copies\n", REPS);
auto peerCopy = [&] {
check(cudaMemcpyPeerAsync(b, dst, a, src, BYTES, stream));
};
unsigned blocks = unsigned((N + 255) / 256);
auto kernelCopy = [&] {
copyKernel<<<blocks, 256, 0, stream>>>(a, b, N);
};
clear(b, dst);
float msPeer = averageMs(peerCopy, stream);
bool okPeer = matches(b, host);
report("cudaMemcpyPeerAsync", msPeer, okPeer);
clear(b, dst);
float msKernel = averageMs(kernelCopy, stream);
check(cudaGetLastError());
bool okKernel = matches(b, host);
report("copy kernel on GPU0", msKernel, okKernel);
check(cudaStreamDestroy(stream));
check(cudaFree(a));
check(cudaFree(b));
return okPeer && okKernel ? 0 : 1;
}
Common mistakes
- Comparing bandwidth in both directions with bandwidth in each direction. NVIDIA’s 900 GB/s for an H100 is 450 GB/s in each direction, and the 64 GB/s of PCIe 5.0 is per direction. The ratio is 7, not 14.
- Assuming that every pair of GPUs supports peer-to-peer transfers. Check
cudaDeviceCanAccessPeer. Many desktop platforms answernoover PCIe, and a copy between such GPUs is staged through the host at a fraction of the expected rate. - Enabling access in 1 direction and using the other. Access from GPU 0 to GPU 1 does not give GPU 1 access to GPU 0. Enable each direction that a kernel uses.
- Ignoring the topology. 2 GPUs on different CPU sockets (
SYS) are much farther apart than 2 GPUs connected by NVLink. Readnvidia-smi topo -mand choose the pairs accordingly. - Using peer atomics on a frequently executed path. Each one crosses the link and waits for its result; use them for infrequent events.
- Measuring a link with data that fits in a cache. Use buffers several times the size of the L2 cache.
Summary
- Programs use several GPUs for capacity, when the data does not fit on a GPU, and for time. Data, model and pipeline parallelism divide the work differently, and all of them exchange data at every step.
- Data parallelism all-reduces the gradients. Each of \(N\) GPUs sends \(2(N - 1)/N\) times their size. For 1 GB on 8 GPUs, that is 1.75 GB: 54.7 ms over PCIe 4.0 and 5.8 ms over NVLink 3.
- An NVLink link carries 25 GB/s in each direction (50 GB/s in NVLink 5), and a GPU’s NVLink bandwidth is its number of links times the bandwidth of a link: 150, 300, 450 and 900 GB/s in each direction from the V100 to the B200. NVIDIA quotes twice these figures, for both directions together.
- Over NVLink, a peer’s memory is 6 to 9 times slower to reach than a GPU’s own memory; over PCIe, about 52 times slower.
- A full mesh needs \(N(N - 1)/2\) links and divides each GPU’s links among its peers; NVSwitch gives every pair all of them. For 8 GPUs with 18 links each, the bisection bandwidth is 450 GB/s in a ring, 800 GB/s in a mesh and 1,800 GB/s through switches.
- UVA gives all GPUs a single address space.
cudaDeviceEnablePeerAccessallows a kernel to use a pointer into a peer’s memory, andcudaMemcpyPeerAsynccopies directly when peer access is enabled. - Within a GPU, a copy of 128 MiB ran at 38.8 GB/s, using 76% of the memory bandwidth for its reads and writes. This rate is the upper bound against which any link is measured.
- A faster link pays off when the exchange time is comparable to each GPU’s share of the computation, \(T_x \approx T_1/N\).
In Chapter 28, we develop the all-reduce algorithms whose cost we used in this chapter, and NCCL, the library that runs them over the links that the topology provides.
Exercises
- A model has 7 × 10⁹ parameters in 16-bit numbers. How large are its gradients? How many bytes does each of 8 GPUs send per step in a ring all-reduce, and how long does that take over PCIe 5.0 and over NVLink 4?
- NVIDIA quotes the B200’s NVLink as 1,800 GB/s with 18 links. Compute the bandwidth of 1 link in each direction, and the time to move 1 GB to a peer.
- How many links does a full mesh of 16 GPUs need? With 18 links per GPU, how many links does each pair get, and what bandwidth in each direction at 25 GB/s per link?
- Compute the bisection bandwidth in each direction of 16 GPUs with 18 links each, connected (a) in a ring with 9 links to each neighbor, and (b) through a non-blocking switch.
- In the model of Section 27.6, find the smallest \(T_1\) for which 8 A100s on NVLink 3 reach a speedup of 6 with gradients of 1 GB.
- Run
peeron your GPU. Compute the memory traffic of the copy, 2 times the rate, as a share of your GPU’s memory bandwidth. Then changeNto 1 MiB of floats and explain the new rate. - On a machine with 2 GPUs, run
peerwith and without the call tocudaDeviceEnablePeerAccess. What changes in the rates, and why? - Read the
nvidia-smi topo -mmatrix of a cloud machine with 8 GPUs, from its provider’s documentation or by running it. Which pairs would you choose for a 2-GPU job?
Sources and further reading
- NVIDIA, NVLink and NVLink Switch, the generations and their bandwidths: https://www.nvidia.com/en-us/data-center/nvlink/
- NVIDIA, “NVIDIA Hopper Architecture In-Depth”, 2022, for NVLink 4, the third-generation NVSwitch and the comparison with NVLink 3: https://developer.nvidia.com/blog/nvidia-hopper-architecture-in-depth/
- NVIDIA, NVIDIA A100 Tensor Core GPU Architecture whitepaper, 2020, for NVLink 3 and the DGX A100.
- NVIDIA, NVIDIA Grace Hopper Superchip Architecture whitepaper, for NVLink-C2C.
- NVIDIA, DGX H100 User Guide: https://docs.nvidia.com/dgx/dgxh100-user-guide/
- NVIDIA, CUDA C++ Programming Guide, “Multi-Device System”, “Peer-to-Peer Memory Access”, “Peer-to-Peer Memory Copy” and “Unified Virtual Address Space”: https://docs.nvidia.com/cuda/cuda-c-programming-guide/
- NVIDIA, NVML API Reference, topology and NVLink queries: https://docs.nvidia.com/deploy/nvml-api/
Chapter 28: NCCL & Multi-GPU Collective Communication
In Chapter 27, we described the connections between GPUs: PCIe, NVLink and NVSwitch. In this chapter, we turn to the data that programs send over those connections. When several GPUs work on 1 problem, each GPU computes a partial result, and the partial results must be combined, usually in every iteration of the program. The time that this combination takes depends not only on the speed of the links but also on the order in which the GPUs send data to each other. For example, combining 100 MB from each of 4 GPUs takes 24 ms with one simple scheme and 6 ms with another, over the same links.
We first define the collective operations that multi-GPU programs use, and a simple model of the time that a message takes. We then analyze two algorithms for the most important collective, all-reduce: the ring and the tree. We count the steps and the bytes of each by hand, and derive the message size at which one becomes faster than the other. We then implement both algorithms in CUDA C++ and in Rust, run them on 1 GPU that holds the data of all the participants in its memory, and compare the measured times with the model. We end the chapter with NCCL, NVIDIA’s library of collective operations, and with the way frameworks such as PyTorch use it.
This chapter covers
- data-parallel training, and why every GPU needs the same sum of gradients
- the 5 common collectives: broadcast, reduce, all-reduce, reduce-scatter and all-gather
- a cost model for messages: a fixed time per message plus bytes divided by bandwidth
- processes, ranks and communicators: how the members of a group of GPUs are numbered
- the ring all-reduce, and why each GPU sends 2 (k − 1) / k of the message
- the tree all-reduce, and the message size below which it is faster than the ring
- both algorithms implemented on 1 GPU in C++ and Rust, verified and timed
- NCCL: creating a group with a unique ID, collectives on streams, and group calls
- NCCL in PyTorch, and the settings used to debug and tune it
The code of the chapter is in
code/ch19_collectives/
for C++ and in
code/oxide/ch19_collectives/
for Rust.
28.1 The multi-GPU programming problem
28.1.1 Data parallelism
The most common reason to combine data across GPUs is the training of neural networks, so we use it as our running example. A neural network computes its output from a large set of numbers called its parameters, and training adjusts the parameters so that the output improves. In each training step, the program runs a batch of examples through the network and computes the gradient, which contains 1 number per parameter. Each number tells in which direction and by how much the corresponding parameter should change to reduce the error on the batch.
Data parallelism divides each batch among several GPUs. Every GPU holds a complete copy of the parameters, processes its own share of the examples, and computes its own gradient. The copies of the parameters must stay identical, so before the next step every GPU needs the same combined gradient: the sum of the gradients of all the GPUs, usually divided by the number of GPUs.
Before we can describe how the GPUs combine their gradients, we need words for the programs that take part and for the way they are numbered. Each GPU of a data-parallel program is controlled by a program running on the host CPU, and in most systems each GPU has a program of its own.
Definition 28.1 Process. A process is a running instance of a program. It has its own memory on the host and its own threads, and it cannot read the variables of another process. Two processes exchange data only through an explicit channel, such as a file, a network connection or a library of collective operations.
Example. On a server with 4 GPUs, the command torchrun --nproc_per_node=4 train.py starts 4
processes. All 4 run the same program, train.py, and each process selects a different GPU.
The 4 processes of the example run the same code, yet each must behave slightly differently: it must select its own GPU, read its own share of the batch, and know which partner to send data to. Each process therefore needs a number that tells it which member of the group it is.
Definition 28.2 Group and rank. A group is a set of k processes that cooperate on 1 problem; k is the size of the group. The rank of a process is the number that identifies it within its group. The k members are numbered 0, 1, …, k − 1, and each number is given to exactly one member. We also call the member itself a rank, so “rank 2” means the process whose number is 2.
Example. 4 processes drive the 4 GPUs of a server, 1 GPU each, and form a group of size k = 4 with ranks 0, 1, 2 and 3; rank r drives GPU r. If 2 such servers form 1 group, then k = 8 and the ranks run from 0 to 7, while the GPU numbers within each server still run from 0 to 3. Rank 5, for example, drives GPU 1 of the second server.
Because a rank is usually 1 process that drives 1 GPU, “rank 3” and “the GPU of rank 3” refer to the same participant, and we use “rank” whenever the number matters. The numbers also let an algorithm describe a pattern of communication in 1 sentence. For example, “rank r sends to rank r + 1” describes 4 different transfers in a group of 4: from 0 to 1, from 1 to 2, from 2 to 3, and, counting modulo 4, from 3 to 0.
A process also needs to record which group it belongs to, since a program can form more than 1 group, for example 1 group of all 8 GPUs and 2 groups of the 4 GPUs of each server.
Definition 28.3 Communicator. A communicator is the object through which a process takes part in a group. It records the size k of the group, the rank of the process within the group, and the connections to the other members. Every collective operation (Section 28.2) is called on a communicator and involves exactly the members of its group.
Example. In the group of 4 processes above, each process holds 1 communicator. All 4 communicators record k = 4; the communicator of the process that drives GPU 2 records rank 2.
The following table shows the gradients of 4 ranks for a model with 3 parameters. Every rank must end the step holding the sum 6, 4, 4, or the average 1.5, 1, 1, so that all 4 ranks apply the same change to their parameters.
| Rank | Its gradient |
|---|---|
| 0 | 1, 2, 0 |
| 1 | 3, 0, 1 |
| 2 | 0, 1, 1 |
| 3 | 2, 1, 2 |
| sum | 6, 4, 4 |
| average | 1.5, 1, 1 |
Real models have far more parameters. A model with 250 million parameters stored as 32-bit floats has a gradient of 250 × 106 × 4 bytes = 1 GB, and every rank must combine its 1 GB with the gradients of all the other ranks in every step.
28.1.2 Combining gradients at a single rank
The most straightforward way to combine the gradients is to choose 1 rank as a collector. Every other rank sends its gradient to the collector, the collector adds the gradients, and then it sends the sum back to every other rank.
To estimate how long this takes, we need to know how the ranks are connected. Each GPU is connected to the others through a link, such as a PCIe slot or a set of NVLink lanes. A link carries data in both directions at the same time, and its bandwidth in each direction is the maximum number of bytes that it can move per second.
Assume that 4 ranks each hold 100 MB and that every link has a bandwidth of 25 GB/s in each direction. Ranks 1, 2 and 3 each send 100 MB to rank 0. All 300 MB must enter through the link of rank 0, which takes 300 MB ÷ 25 GB/s = 12 ms. Rank 0 then sends the 100 MB sum to each of the 3 other ranks, another 300 MB through the same link, which takes another 12 ms. The exchange therefore takes 24 ms. During those 24 ms, the links of ranks 1, 2 and 3 each carry only 100 MB in each direction, a third of what the link of rank 0 carries.
In general, the link of the collector carries k − 1 times the message in each direction, so the time grows with the number of ranks while the other links are mostly idle. In Section 28.4, we present an algorithm in which every link carries the same share, 150 MB in this example, and the same exchange takes 6 ms.
The busiest link determines the time of an exchange. A good collective algorithm spreads the bytes evenly over all the links.
28.2 Collective operations
28.2.1 Common collective operations
The exchange of Section 28.1.2 differs from the copies of earlier chapters in 1 respect. No single transfer produces the result. Every rank must contribute, and the operation is complete only when all of them have taken part.
Definition 28.4 Collective operation and root. A collective operation, or collective, is an operation in which every rank of a group takes part and whose result depends on data from all of the ranks. Every rank calls the same operation, and no rank can complete it alone. Some collectives single out 1 rank, called the root, which sends data to all the other ranks or receives data from all of them.
Example. In the exchange of Section 28.1.2, all 4 ranks take part, and rank 0, the collector, is the root.
Five collectives cover most programs. We work each of them by hand on the same 4 ranks, each of which holds 4 numbers:
| Rank | Its data |
|---|---|
| 0 | 1, 0, 2, 1 |
| 1 | 2, 1, 0, 3 |
| 2 | 0, 3, 1, 0 |
| 3 | 1, 2, 4, 1 |
| element-by-element sum | 4, 6, 7, 5 |
Each element of the sum adds 1 number from every rank. For example, element 1 of the sum is 0 + 1 + 3 + 2 = 6, the element 1 of ranks 0, 1, 2 and 3.
Definition 28.5 Broadcast. In a broadcast, the root holds a buffer, and afterward every rank holds a copy of it.
Example. With rank 0 as the root, the 4 numbers 1, 0, 2, 1 of rank 0 are copied to ranks 1, 2 and 3. Afterward all 4 ranks hold 1, 0, 2, 1, and the former data of ranks 1, 2 and 3 is overwritten.
Definition 28.6 Reduce. In a reduce, every rank holds a buffer of the same length, and afterward the root holds the element-by-element combination of all the buffers. The other ranks receive nothing.
Example. With rank 0 as the root and the sum as the combination, rank 0 ends with 4, 6, 7, 5. Ranks 1, 2 and 3 still hold their own data.
Definition 28.7 All-reduce. In an all-reduce, every rank holds a buffer of the same length, and afterward every rank holds the element-by-element combination of all the buffers. An all-reduce has no root.
Example. All 4 ranks end with 4, 6, 7, 5. The gradients of Section 28.1.1 are combined in the same way, and there every rank ends with 6, 4, 4.
Definition 28.8 Reduce-scatter. In a reduce-scatter, every rank holds a buffer of the same length, which is divided into k pieces of equal length. Afterward rank r holds piece r of the combination, and only that piece.
Example. With 4 ranks and 4 numbers, each piece is 1 number. Rank 0 ends with 4, rank 1 with 6, rank 2 with 7 and rank 3 with 5. Rank 1, for instance, receives element 1 of the sum, 0 + 1 + 3 + 2 = 6.
Definition 28.9 All-gather. In an all-gather, rank r holds piece r of a buffer, and afterward every rank holds all k pieces, in the order of the ranks.
Example. Rank 0 holds 4, rank 1 holds 6, rank 2 holds 7 and rank 3 holds 5. Afterward every rank holds 4, 6, 7, 5.
Figure 28.1 shows the 5 collectives on these 4 ranks.
The following table summarizes the 5 definitions.
| Collective | Before | After |
|---|---|---|
| broadcast | the root holds the data | every rank holds a copy |
| reduce | every rank holds data | the root holds the combination |
| all-reduce | every rank holds data | every rank holds the combination |
| reduce-scatter | every rank holds data | rank r holds piece r of the combination |
| all-gather | rank r holds piece r | every rank holds all the pieces |
Data-parallel training needs an all-reduce, because every rank contributes a gradient and every rank needs the sum.
28.2.2 Reduction operators
So far the combination has always been the sum, but the definitions of reduce, all-reduce and reduce-scatter allow other ways of combining 2 numbers into 1.
Definition 28.10 Reduction operator. A reduction operator combines 2 numbers into 1 and is applied element by element, such as a sum, a product, a minimum or a maximum. The operator must be associative, that is, (a + b) + c = a + (b + c), because each algorithm groups the operations in its own order.
Example. An all-reduce of the 4 ranks above with the maximum as its operator gives every rank 2, 3, 4, 3. Element 0, for instance, is the largest of 1, 2, 0 and 1.
NCCL provides ncclSum, ncclProd, ncclMin, ncclMax and ncclAvg, the sum divided by the
number of ranks.
Recall from Chapter 8 that floating-point addition is associative only up to rounding. 2 algorithms that group the same additions differently can therefore return results that differ in the last bits. For this reason, the tests in this chapter use small whole numbers, whose sums are exact in any order, so that every rank’s result can be compared exactly with the expected sum.
28.2.3 Relations between collectives
The 5 collectives are related to each other. An all-reduce produces the same result as a reduce followed by a broadcast. It also produces the same result as a reduce-scatter followed by an all-gather. In Figure 28.1, the reduce-scatter leaves the sum 4, 6, 7, 5 spread over the 4 ranks, 1 number on each rank. The all-gather then gives every rank all 4 numbers, which is the result of the all-reduce.
The ring algorithm of Section 28.4 uses the second decomposition. Its first half makes each rank responsible for computing one piece of the sum, so the additions are divided evenly among the ranks. Its second half distributes the finished pieces to all ranks.
A program needs every rank to hold the maximum of 1 value per rank. Which collective is it, and with which operator?
An all-reduce with the maximum as its operator, ncclMax in NCCL. Every rank contributes 1 value
and every rank needs the result.
28.3 A cost model for messages
To compare algorithms, we need an estimate of the time that 1 message takes, where a message is the data that 1 rank sends to 1 other rank in 1 transfer. Let us first estimate 2 messages by hand over a link of 25 GB/s. A message of 100 MB occupies the link for 100 × 106 B ÷ (25 × 109 B/s) = 4 ms. By the same division, a message of 4 KB would occupy it for 0.16 µs. However, a message of any size must be started by the sender, must cross the link, and must be detected by the receiver, and these actions take microseconds regardless of the number of bytes. The time of a message therefore has two parts: a fixed part that every message pays, and a part that grows with the number of bytes.
In Section 4.3, we modeled a copy between the host and the device in exactly this way, as a fixed start-up time plus the number of bytes divided by the bandwidth. The same model applies to a message between 2 ranks:
\[ T = \alpha + \frac{m}{B} \]
| Symbol | Meaning | In the example |
|---|---|---|
| \(\alpha\) | latency of a message: the fixed time that every message costs, regardless of its size | 10 µs |
| \(m\) | the size of the message | 4 KB or 100 MB |
| \(B\) | the bandwidth of the link | 25 GB/s |
| \(T\) | the time of 1 message | 10.2 µs or 4.0 ms |
The latency \(\alpha\) includes everything that does not depend on the size of the message: starting the transfer, the time for the signal to cross the link, and the time for the receiver to detect that the data has arrived. Many texts write the second term as \(\beta m\), where \(\beta = 1 / B\) is the time per byte, and therefore call this model the α-β model. We keep the bandwidth \(B\), because link bandwidths are quoted in GB/s.
For example, over a link with α = 10 µs and B = 25 GB/s, a message of 4 KB takes 10 µs + 4,000 B ÷ (25 × 109 B/s) = 10 µs + 0.16 µs = 10.2 µs, of which the fixed time is 98%. A message of 100 MB takes 10 µs + 100 × 106 B ÷ (25 × 109 B/s) = 10 µs + 4,000 µs = 4.0 ms, of which the fixed time is 0.25%. The 2 parameters are round numbers of the same order as the copies measured in Chapter 4.
Small messages are therefore latency-bound: their time is approximately the number of messages that must be sent one after another, multiplied by \(\alpha\). Large messages are bandwidth-bound: their time is approximately the number of bytes on the busiest link divided by \(B\). It follows that a good algorithm for small messages sends few messages in sequence, whereas a good algorithm for large messages sends few bytes over each link. As we will see in the next 2 sections, the ring is the better algorithm for large messages and the tree is the better algorithm for small ones.
28.4 Ring all-reduce
28.4.1 Chunks and steps of the ring
Recall the problem of Section 28.1.2. With a single collector, the link of rank 0 carried every byte of the exchange, while the links of ranks 1, 2 and 3 were mostly idle. A remedy follows from Section 28.2.3. An all-reduce is a reduce-scatter followed by an all-gather, and in a reduce-scatter each rank computes only one piece of the sum. If each of 4 ranks is responsible for a quarter of the sum, all 4 links can share the traffic. The ring all-reduce organizes the ranks and their data so that this happens. We first define its 2 ingredients and then follow the data by hand.
Definition 28.11 Ring. In a ring, the k ranks are arranged in a circle. Rank r sends only to the next rank, (r + 1) mod k, and receives only from the previous rank, (r − 1) mod k.
Example. In a ring of 4 ranks, rank 0 sends to rank 1, rank 1 to rank 2, rank 2 to rank 3, and rank 3 to rank 0. Rank 0 receives from rank 3.
Definition 28.12 Chunk and step. The message of m bytes on each rank is divided into k equal chunks of m / k bytes, numbered 0 to k − 1. A step is a round in which every rank sends exactly 1 chunk to the next rank and receives exactly 1 chunk from the previous rank, all at the same time.
Example. With k = 4 ranks of 8 floats each, every rank holds 4 chunks of 2 floats. In 1 step, the 4 ranks send 4 chunks at once, 1 over each link of the ring.
The algorithm has 2 phases, which correspond to the 2 collectives of Section 28.2.3:
- Reduce-scatter, k − 1 steps. In each step, every rank sends 1 chunk to the next rank, which adds it to its own copy of that chunk. Each chunk travels around the ring and collects the contribution of 1 more rank in every step.
- All-gather, k − 1 steps. At the start of this phase, every rank holds 1 complete chunk. In each step, every rank sends 1 complete chunk to the next rank, which stores it in place of its own copy.
Before we write the algorithm down, let us follow 1 chunk by hand. Take 4 ranks, and let rank r hold the value r + 1 in every element: rank 0 holds 1, rank 1 holds 2, rank 2 holds 3 and rank 3 holds 4, so every element of the sum is 1 + 2 + 3 + 4 = 10. Chunk 0 starts its journey at rank 0. In step 1, rank 0 sends its chunk 0, which holds 1, to rank 1, and rank 1 adds its own 2. Chunk 0 of rank 1 now holds 3 = 1 + 2, the contributions of ranks 0 and 1. In step 2, rank 1 passes this 3 to rank 2, which adds its 3 and obtains 6, the contributions of ranks 0, 1 and 2. In step 3, rank 2 passes the 6 to rank 3, which adds its 4 and obtains 10. After 3 steps, chunk 0 of rank 3 contains the contribution of every rank.
The all-gather phase then copies this finished chunk forward. In step 4, rank 3 sends the 10 to rank 0; in step 5, rank 0 sends it to rank 1; and in step 6, rank 1 sends it to rank 2. Chunk 0 has moved 6 times, each time to the next rank, and every rank now holds 10 in chunk 0. Every other chunk follows the same path, but chunk c starts at rank c. In step 1, therefore, rank 0 sends chunk 0, rank 1 sends chunk 1, rank 2 sends chunk 2 and rank 3 sends chunk 3, and each of the 4 links carries exactly 1 chunk.
28.4.2 A ring all-reduce example
We now trace all 4 chunks together, for 4 ranks with 8 floats each, so that each chunk holds 2 floats. Rank r starts with r + 1 in every element, as above. The 2 floats of a chunk always hold the same value in this example, so the table shows 1 number per chunk, in the order chunk 0, chunk 1, chunk 2, chunk 3. In each row, the notation 0→1: c0 means that rank 0 sends chunk 0 to rank 1, and the chunk that changed on each rank is printed in bold.
Worked example: 4 ranks, 8 floats each, so 4 chunks of 2 floats
| After step | Transfers | Rank 0 | Rank 1 | Rank 2 | Rank 3 |
|---|---|---|---|---|---|
| start | 1 1 1 1 | 2 2 2 2 | 3 3 3 3 | 4 4 4 4 | |
| 1, reduce-scatter | 0→1: c0, 1→2: c1, 2→3: c2, 3→0: c3 | 1 1 1 5 | 3 2 2 2 | 3 5 3 3 | 4 4 7 4 |
| 2, reduce-scatter | 0→1: c3, 1→2: c0, 2→3: c1, 3→0: c2 | 1 1 8 5 | 3 2 2 7 | 6 5 3 3 | 4 9 7 4 |
| 3, reduce-scatter | 0→1: c2, 1→2: c3, 2→3: c0, 3→0: c1 | 1 10 8 5 | 3 2 10 7 | 6 5 3 10 | 10 9 7 4 |
| 4, all-gather | 0→1: c1, 1→2: c2, 2→3: c3, 3→0: c0 | 10 10 8 5 | 3 10 10 7 | 6 5 10 10 | 10 9 7 10 |
| 5, all-gather | 0→1: c0, 1→2: c1, 2→3: c2, 3→0: c3 | 10 10 8 10 | 10 10 10 7 | 6 10 10 10 | 10 9 10 10 |
| 6, all-gather | 0→1: c3, 1→2: c0, 2→3: c1, 3→0: c2 | 10 10 10 10 | 10 10 10 10 | 10 10 10 10 | 10 10 10 10 |
In steps 1 to 3 the receiver adds the arriving chunk to its own; in steps 4 to 6 it overwrites its own chunk with the arriving one.
Every number in the table is a sum of contributions from consecutive ranks of the ring. For example, the 5 in chunk 3 of rank 0 after step 1 is 4 + 1, from ranks 3 and 0. In step 2, rank 0 passes it to rank 1, which adds 2 and obtains 7, the contributions of ranks 3, 0 and 1. In step 3, rank 1 passes the 7 to rank 2, which adds 3 and obtains 10. After step 3, each rank holds exactly 1 complete chunk: rank 0 holds chunk 1, rank 1 chunk 2, rank 2 chunk 3 and rank 3 chunk 0, that is, rank r holds chunk (r + 1) mod 4. Steps 4 to 6 copy each of these 4 complete chunks 3 times around the ring.
Figure 28.2 shows the data of every rank after every step. These are also the values that the program of Section 28.6 prints when it runs this case.
Animation 1 shows the same 6 steps with the chunks in transit between the ranks.
Key observation In every step of the ring, every rank sends exactly 1 chunk and receives exactly 1 chunk. All k links therefore carry the same number of bytes at the same time, and no link waits while another one works, which is the property that the single collector of Section 28.1.2 lacked.
The following procedure describes the algorithm from the point of view of rank r. The array \(data\) holds the k chunks of the rank, and all rank and chunk numbers are taken modulo k, so the previous rank of rank 0 is rank k − 1.
Ring-All-Reduce(\(data, r, k\))
- for \(s \in [0, k-1)\) { // reduce-scatter
- send \(data[(r - s) \bmod k]\) to rank \((r + 1) \bmod k\)
- \(c = (r - 1 - s) \bmod k\)
- receive \(x\) from rank \((r - 1) \bmod k\)
- \(data[c] = data[c] + x\)
- }
- // now \(data[(r + 1) \bmod k]\) holds the complete sum
- for \(s \in [0, k-1)\) { // all-gather
- send \(data[(r + 1 - s) \bmod k]\) to rank \((r + 1) \bmod k\)
- \(c = (r - s) \bmod k\)
- receive \(x\) from rank \((r - 1) \bmod k\)
- \(data[c] = x\)
- }
Lines 1 to 6 are the reduce-scatter, and iteration s of the loop is step s + 1 of the table. In line 2, rank r sends the chunk to which it added in the previous step; in step 1, where s = 0, this is its own chunk r, which no other rank has touched yet. The previous rank follows the same rule, so the chunk that arrives is chunk (r − 1 − s) mod k, which line 3 computes. Line 5 adds the arriving partial sum to the rank’s own contribution. For rank 1 in step 1, line 2 sends chunk 1, line 3 gives c = 0, and line 5 computes 2 + 1 = 3, the bold 3 in the first row of the table. Lines 8 to 13 are the all-gather. They have the same form, but rank r starts by sending its complete chunk, (r + 1) mod k, and line 12 overwrites the chunk instead of adding to it.
The code does not make it obvious that every rank ends with the complete sum in every chunk, so we prove it. The proof follows the partial sums of the table: after each step of the reduce-scatter, the chunk that a rank has just received contains the contributions of 1 more rank.
Theorem 28.1 Let the k ranks run Ring-All-Reduce. After step t of the reduce-scatter, for t = 1, …, k − 1, chunk (r − t) mod k of rank r holds the sum of the contributions of the t + 1 ranks r − t, r − t + 1, …, r, taken modulo k. When the procedure ends, every chunk of every rank holds the sum of the contributions of all k ranks.
For instance, after step 2 the table shows 7 in chunk (1 − 2) mod 4 = 3 of rank 1, and 7 = 4 + 1 + 2 are the contributions of ranks 3, 0 and 1.
Proof. Reduce-scatter, step 1. In step 1, s = 0, and rank r receives chunk (r − 1) mod k from rank r − 1. Rank r − 1 sends its own chunk r − 1 in line 2, and that chunk still holds only the contribution of rank r − 1. Line 5 adds the contribution of rank r. Chunk r − 1 of rank r therefore holds the contributions of ranks r − 1 and r, which is the claim for t = 1.
Reduce-scatter, step t + 1. Assume the claim after step t, where 1 ≤ t < k − 1. In step t + 1, s = t, and rank r receives chunk (r − 1 − t) mod k from rank r − 1. By the assumption applied to rank r − 1, this chunk holds the contributions of the t + 1 ranks r − 1 − t, …, r − 1. Rank r’s own copy of the chunk still holds only rank r’s contribution, because in steps 1 to t rank r changed only chunks r − 1, r − 2, …, r − t, and since t + 1 < k, chunk r − 1 − t is none of them. After line 5, chunk r − (t + 1) of rank r holds the contributions of the t + 2 ranks r − (t + 1), …, r, which is the claim for t + 1.
End of the reduce-scatter. After step k − 1, chunk (r − (k − 1)) mod k = (r + 1) mod k of rank r holds the contributions of k consecutive ranks of the ring, which are all k ranks, as line 7 states.
All-gather. We show that after t steps of the all-gather, rank r holds the complete sum in the t + 1 chunks (r + 1 − j) mod k for j = 0, …, t. For t = 0, this is the previous paragraph. In step t + 1, s = t, and rank r receives chunk (r − t) mod k from rank r − 1, which sends its chunk ((r − 1) + 1 − t) mod k = (r − t) mod k in line 9. By the assumption applied to rank r − 1, that chunk is complete, and line 12 copies it. Rank r thus gains the complete chunk r + 1 − (t + 1). After k − 1 steps, rank r holds the complete sum in the k chunks (r + 1 − j) mod k, j = 0, …, k − 1, which are all of its chunks. ∎
28.4.3 Steps and bytes of the ring
Let us first count the traffic of the example of Section 28.4.2. Each rank sends 1 chunk of 2 floats in each of 6 steps, 12 floats in all, and it receives the same 12 floats. The message on each rank is 8 floats, so each rank sends 12 ÷ 8 = 1.5 times its message.
Now count the collector of Section 28.1.2 on the same data. Ranks 1, 2 and 3 each send their 8 floats to rank 0, so 24 floats enter the link of rank 0. Rank 0 then sends the sum of 8 floats to each of the 3 other ranks, so 24 floats leave through the same link. The link of rank 0 thus carries 24 floats in each direction, twice the 12 floats of any link of the ring. Moreover, the collector cannot send the sum before it has received all 3 messages, so its two directions work one after the other: the exchange lasts as long as 24 + 24 = 48 floats crossing 1 link. In the ring, every link sends and receives its 12 floats at the same time, so the exchange lasts as long as 12 floats crossing 1 link. The ring is 48 ÷ 12 = 4 times as fast, a factor of k, as we show in Section 28.4.4 in general.
For k ranks and a message of m bytes, each phase of the ring takes k − 1 steps, so the all-reduce takes 2 (k − 1) steps. In each step, a rank sends 1 chunk of m / k bytes. Over the whole all-reduce, each rank therefore sends
\[ 2 (k - 1) \cdot \frac{m}{k} = \frac{2 (k - 1)}{k} \, m \]
bytes, and it receives the same number of bytes. For k = 4, the factor is 2 × 3 / 4 = 1.5, as counted above.
The factor 2 (k − 1) / k approaches 2 as the number of ranks grows. It is 1.5 for 4 ranks, 1.75 for 8 ranks and 1.97 for 64 ranks. The number of bytes on each link therefore barely grows with the number of ranks.
An argument from the 2 phases shows why no algorithm can do much better. In a reduce-scatter, each rank holds its contribution to the k − 1 pieces that other ranks finish, (k − 1) m / k bytes, and no other rank holds these bytes, so each rank must send at least (k − 1) m / k bytes. In an all-gather, each rank must receive the (k − 1) m / k bytes of the pieces that it did not finish. Every byte that is received was sent by some rank, so the k ranks together send at least k × (k − 1) m / k bytes, on average (k − 1) m / k per rank. Over the 2 phases, some rank must therefore send at least 2 (k − 1) m / k bytes. Patarasuk and Yuan proved in 2009 that the same bound holds for any all-reduce algorithm, not only for those built from these 2 phases: some rank must send at least 2 (k − 1) / k of the message over its link. The ring reaches this lower bound, so it is said to be bandwidth-optimal.
With the cost model of Section 28.3, the time of a ring all-reduce is
\[ T_{\text{ring}} = 2 (k - 1) \, \alpha + \frac{2 (k - 1)}{k} \cdot \frac{m}{B} \]
| Symbol | Meaning | For the example of section 28.1.2 |
|---|---|---|
| \(k\) | number of ranks | 4 |
| \(m\) | message per rank | 100 MB |
| \(2 (k - 1)\) | number of steps, each costing \(\alpha\) | 6 |
| \(2 (k - 1) m / k\) | bytes that each link carries in each direction | 150 MB |
| \(T_{\text{ring}}\) | the time, with α = 10 µs and B = 25 GB/s | 0.06 ms + 6 ms |
28.4.4 Comparison with a single collecting rank
Figure 28.3 compares the ring with the collector of Section 28.1.2, for the same 4 ranks, 100 MB and links of 25 GB/s. The link of the collector carries 300 MB in each direction, which takes 24 ms. Each link of the ring carries 2 × 3 / 4 × 100 MB = 150 MB in each direction, and all the links work at the same time, so the exchange takes 6 ms.
In general, the ratio between the 2 times is k. The link of the collector moves 2 (k − 1) m bytes, whereas each link of the ring moves 2 (k − 1) m / k bytes. For 8 ranks the ring is therefore 8 times as fast, and for 64 ranks 64 times as fast. The cost of the ring is its number of steps, 2 (k − 1), each of which pays α. For a large message, the fixed time of 6 × 10 µs = 60 µs is 1% of the 6 ms total. For a small message, however, the fixed time is nearly all of the total.
For large messages, the bandwidth term determines how long an all-reduce takes on real hardware. The following table assumes 8 GPUs in a ring and a gradient of 1 GB, the 250 million parameters of Section 28.1.1. It gives the bandwidth term, 1.75 × 1 GB ÷ B, at the rated bandwidth of each kind of link in 1 direction. Measured transfers reach less than the rated bandwidth, as we found for PCIe in Chapter 4.
| Link between GPUs | Rated bandwidth, 1 direction | 1.75 GB at that rate |
|---|---|---|
| PCIe 4.0 × 16 (RTX 4090, A100 PCIe) | 32 GB/s | 55 ms |
| PCIe 5.0 × 16 (RTX 5090, H100 PCIe) | 63 GB/s | 28 ms |
| InfiniBand NDR, 400 Gb/s (between servers) | 50 GB/s | 35 ms |
| NVLink 3, A100 SXM (12 links) | 300 GB/s | 5.8 ms |
| NVLink 4, H100 SXM (18 links) | 450 GB/s | 3.9 ms |
| NVLink 5, B200 (18 links) | 900 GB/s | 1.9 ms |
Note that NVIDIA quotes NVLink bandwidth as the total of both directions, 600, 900 and 1,800 GB/s for the 3 generations; the table gives half of each figure. SXM denotes the module form of a data-center GPU, which is mounted on a server board, as opposed to a PCIe card, and NDR is the 400 Gb/s generation of InfiniBand, a network that connects servers. A machine with only 1 GPU, such as a single DGX Spark, has no link between GPUs.
In a ring all-reduce, each link carries 2 (k − 1) / k of the message, which is less than twice the message for any number of ranks.
28.5 Tree all-reduce
28.5.1 Binomial trees
The ring needs 2 (k − 1) steps, and each step pays the latency α. For 1,024 ranks, this is 2,046 steps. A tree needs far fewer steps, because in each step it halves the number of ranks that still hold a partial sum, instead of adding 1 contribution at a time.
Let us first work a tree by hand on 4 ranks that hold 1, 2, 3 and 4, so that the sum is 10. In step 1, rank 1 sends its 2 to rank 0, which now holds 1 + 2 = 3, and at the same time rank 3 sends its 4 to rank 2, which now holds 3 + 4 = 7. Two partial sums remain, on ranks 0 and 2. In step 2, rank 2 sends its 7 to rank 0, which now holds 3 + 7 = 10, the complete sum. Two steps have reduced 4 contributions to 1. The broadcast repeats the same pairs in the opposite order and direction. In step 3, rank 0 sends 10 to rank 2. In step 4, rank 0 sends 10 to rank 1 and, at the same time, rank 2 sends 10 to rank 3. After 4 steps, every rank holds 10, whereas the ring of Section 28.4.2 needed 6 steps for the same 4 ranks.
The tree pays for its fewer steps with larger messages. In this example, rank 0 received the whole message in steps 1 and 2 and sent the whole message in steps 3 and 4, so its link carried 2 whole messages in each direction, compared with 1.5 messages for a link of the ring.
Definition 28.13 Binomial tree. For k ranks, where k is a power of 2, a binomial tree pairs up the ranks at a distance of 1, then pairs up the receivers at a distance of 2, then at a distance of 4, and so on, so it has log2 k levels. In each pair, the rank with the higher number sends to the rank with the lower number.
Example. For k = 4, the pairs of level 1 are ranks 1 → 0 and 3 → 2, and the pair of level 2 is rank 2 → 0. The tree has log2 4 = 2 levels.
A tree all-reduce has 2 phases:
- Reduce up the tree, log2 k steps. In step 1, every odd rank sends its whole message to the even rank below it, which adds it to its own data. In step 2, the receivers of step 1 pair up at a distance of 2, then at a distance of 4, and so on, until rank 0 holds the sum of all the messages.
- Broadcast down the tree, log2 k steps. The same pairs are used in the opposite order and direction: rank 0 sends the total to rank k / 2, then both of them send it on, and so on.
The following procedure describes the algorithm from the point of view of rank r. The variable \(d\) is the distance between the 2 ranks of a pair, and \(data\) is the whole message of the rank.
Tree-All-Reduce(\(data, r, k\))
- \(d = 1\) // k is a power of 2
- while \(d < k\) { // reduce: log2 k steps
- if \(r \bmod 2d = d\), send \(data\) to rank \(r - d\)
- if \(r \bmod 2d = 0\), receive \(x\) from rank \(r + d\) and set \(data = data + x\)
- \(d = 2d\)
- }
- \(d = k / 2\)
- while \(d \ge 1\) { // broadcast: log2 k steps
- if \(r \bmod 2d = 0\), send \(data\) to rank \(r + d\)
- if \(r \bmod 2d = d\), receive \(x\) from rank \(r - d\) and set \(data = x\)
- \(d = d / 2\)
- }
Lines 2 to 6 are the reduce phase. With d = 1, line 3 selects the odd ranks as senders and line 4 the even ranks as receivers, as in step 1 of the example. With d = 2, only ranks whose number is a multiple of 2 take part: rank 2 sends and rank 0 receives. A rank that has sent its data takes no further part in the reduce phase, because its number fails both tests for every larger d. Lines 8 to 12 are the broadcast phase, which uses the same pairs with d halving, and line 10 overwrites instead of adding.
Figure 28.4 shows the tree for k = 8. The all-reduce takes 2 × log2 8 = 6 steps, compared with 2 × 7 = 14 steps for a ring of 8 ranks. However, every arrow in the tree carries the whole message of m bytes, because the message is not divided into chunks. Rank 0 receives a message in each of the 3 steps of the reduce phase and sends a message in each of the 3 steps of the broadcast phase, so its link carries 3m in each direction, compared with 1.75m for a ring of 8 ranks. The time of the tree all-reduce is therefore
\[ T_{\text{tree}} = 2 \log_2 k \, \left( \alpha + \frac{m}{B} \right) \]
Compared with the ring, the number of steps contains \(\log_2 k\) in place of \(k - 1\), and every step carries the whole message rather than a chunk.
Key observation The ring divides the message into k chunks and sends 1 chunk per step in 2 (k − 1) steps; the tree sends the whole message in each of 2 log2 k steps. The ring therefore pays more fixed time α, and the tree more time per byte.
28.5.2 Choosing between the ring and the tree
Having derived the time of both algorithms, we can now determine which one is faster for a given message size. For k = 8, the 2 formulas are
\[ T_{\text{ring}} = 14 \alpha + 1.75 \frac{m}{B} \qquad T_{\text{tree}} = 6 \alpha + 6 \frac{m}{B} \]
The tree saves 8α of fixed time but carries 4.25 m / B more traffic. The 2 times are equal when 8α = 4.25 m / B, which happens at the crossover size
\[ m^{\ast} = \frac{8 \alpha B}{4.25} \]
Worked example: the crossover for α = 10 µs, B = 25 GB/s, k = 8
- 8α = 80 µs, the fixed time that the tree saves.
- m* = 80 × 10−6 s × 25 × 109 B/s ÷ 4.25 = 2,000,000 B ÷ 4.25 = 470,588 bytes, about 470 KB.
- Check: the ring takes 140 µs + 1.75 × 470,588 B ÷ 25 GB/s = 140 µs + 33 µs = 173 µs. The tree takes 6 × (10 µs + 18.8 µs) = 173 µs.
Below 470 KB the tree is faster, and above 470 KB the ring is faster. Figure 28.5 plots both formulas for messages from 1 KB to 1 GB. For a message of 4 KB, the tree takes 60 µs and the ring 140 µs. For a message of 1 GB, the ring takes 70 ms and the tree 240 ms.
A gradient of 1 GB is far above the crossover, which is why rings carry most of the traffic of data-parallel training. Small all-reduces, such as the reduction of a single loss value or of a flag that indicates whether training should stop, are far below it.
NCCL improves on both of these simple algorithms. Since version 2.4, it uses a double binary tree: 2 trees over the same ranks, each of which carries half of the data. A rank that is a leaf in one tree is an inner node in the other, so no rank performs the work of an inner node twice. In addition, the message is divided into small pieces that follow each other through the tree. This pipelining keeps every level of the tree busy at the same time. The result keeps the logarithmic number of steps of the tree and comes close to the bandwidth of the ring. NCCL chooses the ring, the tree or another algorithm for each call, based on the message size, the number of ranks and the topology, the way in which the GPUs are connected to each other.
For k = 64 and the same α and B, does the crossover move up or down?
Up. The ring takes 126α + 1.97 m / B, the binomial tree 12α + 12 m / B. They meet at 114α = 10.03 m / B, so m* = 114 × 10 µs × 25 GB/s ÷ 10.03 = 2.8 MB. More ranks mean many more ring steps, so the tree remains faster up to larger messages.
28.6 Simulating collectives on 1 GPU
28.6.1 Ranks as slices of a buffer
We now implement both algorithms. The program of this section runs them on 1 GPU by placing all k ranks in the memory of that GPU, as k slices of 1 buffer. Rank r owns the floats from r n to r n + n − 1, where n is the number of floats per rank. A send from rank r to rank r + 1 then becomes a read from 1 slice and a write into another.
The program measures the algorithms, not a network. All the simulated links share the memory of 1 GPU, so the transfers of 1 step do not each have a link of their own. In Section 28.6.4, we show how this affects the measured times.
The program first converts an algorithm into a plan: a list of steps, each of which is a list of
transfers that run at the same time. A transfer specifies the offset that it reads from and the
offset that it writes to, and its step specifies whether the transfer adds to the destination or
overwrites it. Listing 28.1 shows the data structures. The function addStep appends the
transfers of 1 step to the plan and records where they start, how many there are, how many floats
each one moves, and whether they add.
Listing 28.1 A plan of steps and transfers. Rust C++
/// 1 step of a collective: `count` transfers of `len` floats that run at the same time.
struct Step {
first: usize,
count: usize,
len: usize,
add: bool,
}
/// The (from, to) offsets of every transfer, and the steps that group them.
#[derive(Default)]
struct Plan {
pairs: Vec<u32>,
steps: Vec<Step>,
}
impl Plan {
fn add_step(&mut self, sends: &[(usize, usize)], len: usize, add: bool) {
let first = self.pairs.len() / 2;
for &(from, to) in sends {
self.pairs.push(from as u32);
self.pairs.push(to as u32);
}
self.steps.push(Step { first, count: sends.len(), len, add });
}
// ...
}// 1 send: `len` floats from offset `from` of the buffer to offset `to`.
struct Transfer {
int from;
int to;
};
// 1 step of a collective: transfers that run at the same time, on different links.
struct Step {
int first; // index of the step's first transfer in the plan
int count; // number of transfers
int len; // floats per transfer
bool add; // add into the destination, or overwrite it
};
struct Plan {
std::vector<Transfer> transfers;
std::vector<Step> steps;
};
void addStep(Plan& plan, const std::vector<Transfer>& sends, int len, bool add)
{
int first = int(plan.transfers.size());
plan.transfers.insert(plan.transfers.end(), sends.begin(), sends.end());
plan.steps.push_back({first, int(sends.size()), len, add});
}
The Rust version stores each transfer as 2 numbers in 1 flat Vec<u32>, so that the plan
can be copied to the GPU with DeviceBuffer::from_host and read by the kernel as a &[u32].
The function ring in Listing 28.2 builds the plan of the procedure Ring-All-Reduce of Section
28.4.2. The first loop creates the k − 1 reduce-scatter steps of lines 1 to 6. In step s, rank r
sends its chunk (r − s) mod k to rank (r + 1) % k, and the step adds. The second loop creates
the k − 1 all-gather steps, in which rank r sends its chunk (r + 1 − s) mod k, and the step
overwrites. The term + k inside each % keeps the left operand positive, because the % of a
negative int is negative in C++. The function tree builds the 2 phases of Section 28.5.1 in the
same way, with the distance d doubling in the reduce phase and halving in the broadcast phase.
Listing 28.2 The ring and the tree as plans.
/// Ring: reduce-scatter in k - 1 steps, then all-gather in k - 1 steps.
fn ring(k: usize, n: usize) -> Plan {
let mut plan = Plan::default();
let chunk = n / k;
let send = |r: usize, c: usize| (r * n + c * chunk, (r + 1) % k * n + c * chunk);
for s in 0..k - 1 {
let sends: Vec<_> = (0..k).map(|r| send(r, (r + k - s) % k)).collect();
plan.add_step(&sends, chunk, true);
}
for s in 0..k - 1 {
let sends: Vec<_> = (0..k).map(|r| send(r, (r + 1 + k - s) % k)).collect();
plan.add_step(&sends, chunk, false);
}
plan
}
/// Binomial tree, k a power of 2: sums climb to rank 0, then the total comes back down.
fn tree(k: usize, n: usize) -> Plan {
let mut plan = Plan::default();
let mut d = 1;
while d < k {
let sends: Vec<_> = (d..k).step_by(2 * d).map(|r| (r * n, (r - d) * n)).collect();
plan.add_step(&sends, n, true);
d *= 2;
}
d = k / 2;
while d >= 1 {
let sends: Vec<_> = (0..k).step_by(2 * d).map(|r| (r * n, (r + d) * n)).collect();
plan.add_step(&sends, n, false);
d /= 2;
}
plan
}// Ring: reduce-scatter in k - 1 steps, then all-gather in k - 1 steps.
// Rank r owns elements [r n, r n + n) of the buffer; chunk c is n / k floats.
Plan ring(int k, int n)
{
Plan plan;
int chunk = n / k;
for (int s = 0; s < k - 1; ++s) {
std::vector<Transfer> sends;
for (int r = 0; r < k; ++r) {
int c = (r - s + k) % k;
int next = (r + 1) % k;
sends.push_back({r * n + c * chunk, next * n + c * chunk});
}
addStep(plan, sends, chunk, true);
}
for (int s = 0; s < k - 1; ++s) {
std::vector<Transfer> sends;
for (int r = 0; r < k; ++r) {
int c = (r + 1 - s + k) % k;
int next = (r + 1) % k;
sends.push_back({r * n + c * chunk, next * n + c * chunk});
}
addStep(plan, sends, chunk, false);
}
return plan;
}
// Binomial tree, k a power of 2: sums climb to rank 0, then the total comes back down.
Plan tree(int k, int n)
{
Plan plan;
for (int d = 1; d < k; d *= 2) {
std::vector<Transfer> sends;
for (int r = d; r < k; r += 2 * d) {
sends.push_back({r * n, (r - d) * n});
}
addStep(plan, sends, n, true);
}
for (int d = k / 2; d >= 1; d /= 2) {
std::vector<Transfer> sends;
for (int r = 0; r < k; r += 2 * d) {
sends.push_back({r * n, (r + d) * n});
}
addStep(plan, sends, n, false);
}
return plan;
}
28.6.2 The step kernel
Each step of a plan runs as 1 launch of 1 kernel, the function that runs on the GPU. All the
transfers of a step share the launch. If a step has count transfers and each transfer is given
per blocks, block b works on transfer b / per, and the per blocks of a transfer stride
through its floats together. Figure 28.6 shows step one of the ring for 4 ranks.
Running all the transfers of a step in 1 launch is correct only if no transfer reads an element
that another transfer of the same step writes. Both algorithms satisfy this condition. In
reduce-scatter step s of the ring, rank r + 1 receives chunk (r − s) and sends chunk
(r + 1 − s), which are 2 different chunks. In a step of the tree, the ranks that send and the ranks
that receive are 2 separate sets. The order of the steps is maintained by the stream, the
queue of GPU work introduced in Chapter 6: a launch starts only after the previous launch on the
same stream has finished.
In the kernel runStep of Listing 28.3, each thread first reads the transfer of its block,
sends[blockIdx.x / per]. The loop then starts at the thread’s position within the per blocks
of the transfer and advances by stride, the total number of threads that work on the transfer.
In each iteration, the thread reads 1 float from the source slice and either adds it to the
destination or overwrites the destination, depending on add. The host function run computes
per and launches the kernel on the stream.
Listing 28.3 The step kernel and its launch.
mod kernels {
// ...
/// `per` blocks for each transfer of the step; block b works on transfer b / per.
/// `plan` holds (from, to) offset pairs; the step's pairs start at pair `first`.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn step(
mut all: DisjointSlice<f32>,
plan: &[u32],
first: u32,
len: u32,
per: u32,
add: u32,
) {
let b = thread::blockIdx_x();
let t = (first + b / per) as usize;
let from = plan[2 * t];
let to = plan[2 * t + 1];
let stride = per * BLOCK;
let mut i = (b % per) * BLOCK + thread::threadIdx_x();
while i < len {
// SAFETY: within 1 step no element is both read and written, and no 2
// threads write the same element, so these accesses cannot race.
unsafe {
let v = *all.get_unchecked_mut((from + i) as usize);
let d = all.get_unchecked_mut((to + i) as usize);
*d = if add != 0 { *d + v } else { v };
}
i += stride;
}
}
// ...
}
impl Gpu<'_> {
// ...
fn run(&mut self, steps: &[Step], pairs: &DeviceBuffer<u32>) -> Result<(), Error> {
for st in steps {
let per = st.len.div_ceil(BLOCK as usize).min((1024 / st.count).max(1)) as u32;
let config = LaunchConfig1D::new(st.count as u32 * per, BLOCK, 0);
let launch = self.module.prepare_step(config)?;
let (first, len, add) = (st.first as u32, st.len as u32, st.add as u32);
let all = &mut self.all;
self.module.step(self.stream, &launch, all, pairs, first, len, per, add)?;
}
Ok(())
}
// ...
}// `per` blocks for each transfer of the step; block b works on transfer b / per.
// Within 1 step no element is both read and written, so the transfers cannot race.
__global__ void runStep(float* all, const Transfer* sends, int len, int per, bool add)
{
Transfer t = sends[blockIdx.x / per];
int stride = per * blockDim.x;
for (int i = (blockIdx.x % per) * blockDim.x + threadIdx.x; i < len; i += stride) {
float v = all[t.from + i];
all[t.to + i] = add ? all[t.to + i] + v : v;
}
}
void run(const Gpu& gpu, const Step& st, cudaStream_t s)
{
int per = std::min((st.len + 255) / 256, std::max(1024 / st.count, 1));
const Transfer* sends = gpu.sends + st.first;
runStep<<<st.count * per, 256, 0, s>>>(gpu.all, sends, st.len, per, st.add);
}
The function run gives every step at most 1,024 blocks of 256 threads, divided among its
transfers, and never gives a transfer more blocks than it has floats to cover. For example, a tree
step with 1 transfer of 4 Mi floats receives all 1,024 blocks, whereas a ring step with 8
transfers receives 128 blocks for each transfer.
In Rust, 2 threads may write to the same DisjointSlice only at indices that the compiler can
prove to be different, which is the thread’s own index. The step kernel writes at to + i and
reads at from + i, where the offsets come from the plan, so it uses get_unchecked_mut inside an
unsafe block, as the per-block writes of Chapter 8 did. The SAFETY comment states the argument
of the previous paragraph. No element is both read and written within 1 step.
28.6.3 Running the 4-rank example
The measurements in this section come from a Jetson Orin NX, an integrated GPU with 8 SMs (streaming multiprocessors) and 102 GB/s of memory bandwidth. The program first runs the example of Section 28.4.2, 4 ranks of 8 floats, 1 step at a time, and prints the data of every rank after every step.
$ nvcc -arch=native allreduce.cu -o allreduce && ./allreduce
GPU: Orin, 8 SMs
ring all-reduce, 4 ranks of 8 floats: rank r starts with r + 1
rank 0 1 1 1 1 1 1 1 1
rank 1 2 2 2 2 2 2 2 2
rank 2 3 3 3 3 3 3 3 3
rank 3 4 4 4 4 4 4 4 4
after step 1 (reduce-scatter)
rank 0 1 1 1 1 1 1 5 5
rank 1 3 3 2 2 2 2 2 2
rank 2 3 3 5 5 3 3 3 3
rank 3 4 4 4 4 7 7 4 4
after step 2 (reduce-scatter)
rank 0 1 1 1 1 8 8 5 5
rank 1 3 3 2 2 2 2 7 7
rank 2 6 6 5 5 3 3 3 3
rank 3 4 4 9 9 7 7 4 4
after step 3 (reduce-scatter)
rank 0 1 1 10 10 8 8 5 5
rank 1 3 3 2 2 10 10 7 7
rank 2 6 6 5 5 3 3 10 10
rank 3 10 10 9 9 7 7 4 4
after step 4 (all-gather)
rank 0 10 10 10 10 8 8 5 5
rank 1 3 3 10 10 10 10 7 7
rank 2 6 6 5 5 10 10 10 10
rank 3 10 10 9 9 7 7 10 10
after step 5 (all-gather)
rank 0 10 10 10 10 8 8 10 10
rank 1 10 10 10 10 10 10 7 7
rank 2 6 6 10 10 10 10 10 10
rank 3 10 10 9 9 10 10 10 10
after step 6 (all-gather)
rank 0 10 10 10 10 10 10 10 10
rank 1 10 10 10 10 10 10 10 10
rank 2 10 10 10 10 10 10 10 10
rank 3 10 10 10 10 10 10 10 10
Each pair of columns is 1 chunk of 2 floats. The rows agree with the steps that we traced by hand in Section 28.4.2. After step 1, chunk 0 of rank 1 is 3 and chunk 3 of rank 0 is 5. After step 3, each rank holds 1 complete chunk of 10, and after step 6 all 32 floats are 10. The Rust program prints the same 35 lines.
28.6.4 Timing the ring and the tree
The program then runs both algorithms on 8 simulated ranks, for messages of 4 KiB, 64 KiB, 1 MiB
and 16 MiB per rank. For each size, it times 50 all-reduces with CUDA events (Chapter 6), each
starting from fresh values, and compares every element of every rank with the exact sum. Element
i of rank r starts as i % 16 + r, a whole number below 24, so the sum over 8 ranks is exact in
any order.
all-reduce on 8 simulated ranks
steps busiest rank sends
ring 14 1.75 x the message
tree 6 3.00 x the message
message ring tree
4 KiB 0.162 ms 0.070 ms
64 KiB 0.226 ms 0.143 ms
1024 KiB 0.913 ms 0.795 ms
16384 KiB 7.184 ms 6.645 ms
every rank holds the exact sum: PASSED
$ cargo oxide run
...
message ring tree
4 KiB 0.166 ms 0.073 ms
64 KiB 0.221 ms 0.129 ms
1024 KiB 1.082 ms 1.065 ms
16384 KiB 7.295 ms 6.655 ms
every rank holds the exact sum: PASSED
The first table confirms the counts of Sections 28.4.3 and 28.5.1: 14 and 6 steps, and 1.75 and 3 times the message through the busiest rank. Repeated runs differ by up to 25% at 1 MiB.
For small messages, the time follows the number of steps. At 4 KiB, the ring took 0.162 ms for 14 steps, 11.6 µs per step, and the tree took 0.070 ms for 6 steps, 11.7 µs per step. The tree was 0.162 ÷ 0.070 = 2.3 times as fast, which is the ratio of the step counts, 14 ÷ 6 = 2.3. On this GPU, the α of a step is therefore about 12 µs. A timeline from Nsight Systems (Chapter 25) divides it into about 9 µs inside the step kernel and 3.5 µs between 1 kernel and the next.
For large messages, the time follows the memory traffic. At 16 MiB, the two algorithms took about the same time, 7.2 ms and 6.6 ms. The reason is that the simulated links share 1 memory. A float that is added costs 12 bytes of memory traffic, 2 reads and 1 write, and a float that is copied costs 8 bytes, 1 read and 1 write. Both algorithms add (k − 1) n floats and copy (k − 1) n floats. For 16 MiB per rank, n = 16 MiB ÷ 4 bytes = 4,194,304 floats. The additions move 7 × 4,194,304 × 12 B = 352.3 MB and the copies 7 × 4,194,304 × 8 B = 234.9 MB, 587.2 MB in all, in the ring and in the tree alike. This is 35 bytes of memory traffic for every byte of the message. The ring took 7.184 ms, of which 0.162 ms was fixed time, so the memory moved 587.2 MB ÷ 7.022 ms = 84 GB/s, 82% of the GPU’s 102 GB/s.
The dashed lines of Figure 28.7 show the model T = steps × 11.6 µs + 35 m ÷ 84 GB/s. The model matches both ends of the measurements. At 1 MiB, where neither term dominates, the measured times lie about 0.3 ms above it.
On a machine with separate links, the two algorithms would differ at large sizes. A link of the ring would carry 1.75 × 16 MiB, whereas the link of the root of the tree would carry 3 × 16 MiB, so the ring would take about 1.75 ÷ 3 = 58% of the time of the tree. The simulation cannot show this difference, because its 8 links are 1 memory and only the total traffic matters. A simulation on 1 GPU therefore verifies the algorithm and measures the cost of its steps, but measuring the links requires 2 or more GPUs.
28.7 NCCL
28.7.1 Overview of NCCL
NCCL, the NVIDIA Collective Communications Library (pronounced “nickel”), implements the collectives of Section 28.2, as well as point-to-point sends and receives, for NVIDIA GPUs. It is open source, under a BSD license, and every major deep-learning framework uses it.
When a group of ranks starts, NCCL discovers the topology of the system: which GPUs share NVLink or an NVSwitch, which GPUs are under the same PCIe switch, and which GPUs are in other servers. From the topology, it builds rings and trees that use the fastest paths. For each pair of ranks, it chooses a transport, the path that the data takes. Within a server, it prefers peer-to-peer access over NVLink or PCIe, in which 1 GPU reads and writes the memory of another GPU directly. Where peer-to-peer access is not possible, it passes the data through a buffer in host memory. Between servers, it uses the network: InfiniBand, RoCE (remote memory access over Ethernet) or TCP sockets, the ordinary network connections of the operating system.
Each collective runs as 1 CUDA kernel on each rank, launched on a stream that the program chooses. The threads of the kernel move the data and perform the additions. They keep the steps of the algorithm in order through flags in memory, which the threads of 1 rank write and the threads of the next rank wait for. Unlike the simulation of Section 28.6, which launched 1 kernel per step, no host thread takes part between the steps. Figure 28.8 shows where NCCL sits between a framework and the hardware.
28.7.2 Communicators and the unique ID
Recall from Definition 28.3 that a communicator represents the membership of a rank in a group. In
NCCL, a communicator has the type ncclComm_t. It holds the size of the group, the number of the
rank within it, and the rings and connections that NCCL built for the group. Every collective takes
a communicator as a parameter.
Before ranks in different processes can communicate, they must agree that they belong to the same
group. One rank calls ncclGetUniqueId, which returns a ncclUniqueId, 128 bytes that identify the
group. The program sends these 128 bytes to every other rank through a channel of its own choice,
such as a file, a TCP connection, or a broadcast of MPI, the Message Passing Interface used in
supercomputer programs. Then, every rank calls ncclCommInitRank with the size of the group, the
ID and its own rank number. The following code shows these calls:
ncclUniqueId id;
if (rank == 0) check(ncclGetUniqueId(&id));
// send `id` to every rank, for example with MPI_Bcast
ncclComm_t comm;
check(cudaSetDevice(localGpu));
check(ncclCommInitRank(&comm, nranks, id, rank));
cuda-oxide does not wrap NCCL, so a Rust program makes these calls through other bindings to
the library, such as the nccl module of the cudarc crate, where Id::new and
Comm::from_rank correspond to the 2 calls above.
Rank 0 creates the ID in the second line, and every rank creates its communicator in the last line,
after selecting its GPU with cudaSetDevice. Note that ncclCommInitRank returns only when all
nranks ranks have called it with the same ID. A rank that never calls it, or that received a
different ID, leaves the other ranks waiting, which is the most common cause of hangs in multi-GPU
programs.
A single process that drives every GPU of 1 server does not need the ID. It can call
ncclCommInitAll, which creates k communicators at once, 1 for each device in a list.
28.7.3 Collectives on a stream
Once the communicator exists, an all-reduce is a single call:
check(ncclAllReduce(send, recv, count, ncclFloat, ncclSum, comm, stream));
check(cudaStreamSynchronize(stream));
In cudarc, the same collective is the method all_reduce of a Comm.
ncclAllReduce reads count floats at send on every rank and writes their sum into recv on
every rank; send and recv may be the same buffer. Like a kernel launch, the call returns as
soon as the work has been queued on stream. The all-reduce runs after the work queued before it
on that stream, so a kernel that computes the gradient and the all-reduce that sums it need no
other synchronization between them. The host waits for the result with cudaStreamSynchronize or
with an event, as described in Chapter 6.
Every rank must call the same collectives in the same order, with the same count and type. If 1
rank calls ncclAllReduce while another calls ncclBroadcast, both wait for partners that never
arrive.
28.7.4 Group calls
A single host thread may drive several GPUs, each with its own communicator. Such a thread must
start the collective on all of its GPUs before any of them can finish, because the kernel of each
rank waits for the other ranks. The functions ncclGroupStart and ncclGroupEnd mark such a
batch of calls. NCCL queues the calls between them and launches them together at ncclGroupEnd:
check(ncclGroupStart());
for (int r = 0; r < k; ++r) {
check(ncclAllReduce(data[r], data[r], n, ncclFloat, ncclSum, comms[r], streams[r]));
}
check(ncclGroupEnd());
cudarc provides the same pair as the functions group_start and group_end.
Without the group, the first call could block while it waits for ranks whose calls the same thread
has not yet made. Group calls also combine a ncclSend and a ncclRecv into 1 exchange, which is
how a halo is exchanged between neighboring GPUs.
28.8 NCCL in frameworks and performance tuning
28.8.1 PyTorch DistributedDataParallel
Most programs use NCCL through a framework. In PyTorch, the launcher torchrun starts 1 process per
GPU and gives each process its rank in environment variables: RANK is the rank in the whole group,
WORLD_SIZE is the size k of the group, and LOCAL_RANK is the rank among the processes of the
same server, which is the number of the GPU that the process uses. In the example of Definition
28.2, the process with rank 5 has LOCAL_RANK 1 and WORLD_SIZE 8. The program joins the group and
wraps its model:
import torch.distributed as dist
from torch.nn.parallel import DistributedDataParallel
dist.init_process_group(backend="nccl")
model = DistributedDataParallel(model.cuda(local_rank), device_ids=[local_rank])
outputs = model(inputs)
loss = loss_fn(outputs, targets)
loss.backward() # all-reduces the gradients through NCCL
init_process_group creates the NCCL communicator, and PyTorch’s own key-value store passes the
unique ID from rank 0 to the other ranks. DistributedDataParallel groups the gradients into
buckets of about 25 MB and starts an all-reduce for each bucket as soon as the backward pass
has computed all of its gradients. Because the backward pass computes the gradients of the last
layers first, their buckets are summed over the links while the gradients of the first layers are
still being computed. This is the overlap of computation and data transfer from Chapter 6, applied
to communication between GPUs.
28.8.2 Debugging and tuning NCCL
NCCL reads its settings from environment variables. The following table lists the ones that are used most often:
| Variable | Effect |
|---|---|
NCCL_DEBUG=INFO | prints the version, the topology found, and the rings and trees built |
NCCL_DEBUG=WARN | prints only problems |
NCCL_DEBUG_SUBSYS=INIT,COLL | limits the output to some parts, here start-up and collectives |
NCCL_ALGO=Ring or Tree | forces an algorithm, for experiments |
NCCL_PROTO=Simple, LL or LL128 | forces a protocol: LL (low latency) and LL128 store a flag with the data, for lower latency at lower bandwidth |
NCCL_P2P_DISABLE=1 | disables direct GPU-to-GPU transfers, to test whether peer access causes a problem |
NCCL_SOCKET_IFNAME=eth0 | chooses the network interface for start-up and socket traffic |
Forcing an algorithm or a protocol is useful for understanding a measurement. In production, the choice that NCCL makes from the topology and the message size is usually the faster one.
The NCCL tests, a separate open-source repository, measure collectives in isolation:
./build/all_reduce_perf -b 8 -e 128M -f 2 -g 4
This command times all-reduces from 8 bytes (-b) to 128 MB (-e), doubling the size each time
(-f 2), over 4 GPUs driven by 1 thread (-g 4). For each size, it prints 2 rates. The
algorithm bandwidth is the message size divided by the time. The bus bandwidth is the
algorithm bandwidth multiplied by 2 (k − 1) / k for an all-reduce, the factor of Section 28.4.3. The
bus bandwidth is the number of bytes that each link carried per second, so it can be compared
directly with the rated bandwidth of the link.
Finally, nvidia-smi topo -m prints the matrix of connections between the GPUs of a server. An
entry NV4 means 4 NVLinks; PIX, PXB, PHB and SYS mean PCIe paths of increasing length. A
ring that must cross a SYS path, between processor sockets, runs at the speed of that path.
28.9 The complete programs
Listing 28.4 The complete programs. code/oxide/ch19_collectives/src/main.rs code/ch19_collectives/allreduce.cu
//! Chapter 19 in Rust: ring and tree all-reduce, simulated on 1 GPU.
//! Each rank is a slice of 1 buffer in the memory of 1 GPU. No network is measured.
//!
//! cargo oxide run
use cuda_core::sys::CUevent_flags_enum_CU_EVENT_DEFAULT as TIMING;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, DriverError, LaunchConfig1D};
use cuda_device::{DisjointSlice, cuda_module, kernel, launch_contract, thread};
const BLOCK: u32 = 256;
type Error = Box<dyn std::error::Error>;
/// Milliseconds per all-reduce, and whether the result was exact.
type Timed = Result<(f32, bool), Error>;
#[cuda_module]
mod kernels {
use super::*;
/// `per` blocks for each transfer of the step; block b works on transfer b / per.
/// `plan` holds (from, to) offset pairs; the step's pairs start at pair `first`.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn step(
mut all: DisjointSlice<f32>,
plan: &[u32],
first: u32,
len: u32,
per: u32,
add: u32,
) {
let b = thread::blockIdx_x();
let t = (first + b / per) as usize;
let from = plan[2 * t];
let to = plan[2 * t + 1];
let stride = per * BLOCK;
let mut i = (b % per) * BLOCK + thread::threadIdx_x();
while i < len {
// SAFETY: within 1 step no element is both read and written, and no 2
// threads write the same element, so these accesses cannot race.
unsafe {
let v = *all.get_unchecked_mut((from + i) as usize);
let d = all.get_unchecked_mut((to + i) as usize);
*d = if add != 0 { *d + v } else { v };
}
i += stride;
}
}
/// Rank r, element i starts as i % 16 + r, or as r + 1 in the demo.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn fill(mut all: DisjointSlice<f32>, n: u32, demo: u32) {
let g = thread::index_1d();
let r = g.get() as u32 / n;
let i = g.get() as u32 % n;
if let Some(x) = all.get_mut(g) {
*x = if demo != 0 { (r + 1) as f32 } else { (i % 16 + r) as f32 };
}
}
}
/// 1 step of a collective: `count` transfers of `len` floats that run at the same time.
struct Step {
first: usize,
count: usize,
len: usize,
add: bool,
}
/// The (from, to) offsets of every transfer, and the steps that group them.
#[derive(Default)]
struct Plan {
pairs: Vec<u32>,
steps: Vec<Step>,
}
impl Plan {
fn add_step(&mut self, sends: &[(usize, usize)], len: usize, add: bool) {
let first = self.pairs.len() / 2;
for &(from, to) in sends {
self.pairs.push(from as u32);
self.pairs.push(to as u32);
}
self.steps.push(Step { first, count: sends.len(), len, add });
}
/// Bytes sent by the rank that sends the most; rank r owns offsets [r n, r n + n).
fn busiest_rank(&self, k: usize, n: usize) -> usize {
let mut sent = vec![0; k];
for st in &self.steps {
for t in st.first..st.first + st.count {
sent[self.pairs[2 * t] as usize / n] += st.len * 4;
}
}
sent.into_iter().max().unwrap_or(0)
}
}
/// Ring: reduce-scatter in k - 1 steps, then all-gather in k - 1 steps.
fn ring(k: usize, n: usize) -> Plan {
let mut plan = Plan::default();
let chunk = n / k;
let send = |r: usize, c: usize| (r * n + c * chunk, (r + 1) % k * n + c * chunk);
for s in 0..k - 1 {
let sends: Vec<_> = (0..k).map(|r| send(r, (r + k - s) % k)).collect();
plan.add_step(&sends, chunk, true);
}
for s in 0..k - 1 {
let sends: Vec<_> = (0..k).map(|r| send(r, (r + 1 + k - s) % k)).collect();
plan.add_step(&sends, chunk, false);
}
plan
}
/// Binomial tree, k a power of 2: sums climb to rank 0, then the total comes back down.
fn tree(k: usize, n: usize) -> Plan {
let mut plan = Plan::default();
let mut d = 1;
while d < k {
let sends: Vec<_> = (d..k).step_by(2 * d).map(|r| (r * n, (r - d) * n)).collect();
plan.add_step(&sends, n, true);
d *= 2;
}
d = k / 2;
while d >= 1 {
let sends: Vec<_> = (0..k).step_by(2 * d).map(|r| (r * n, (r + d) * n)).collect();
plan.add_step(&sends, n, false);
d /= 2;
}
plan
}
/// The ranks' buffer, and the stream and module that run the kernels on it.
struct Gpu<'a> {
stream: &'a CudaStream,
module: &'a kernels::LoadedModule,
all: DeviceBuffer<f32>,
}
impl Gpu<'_> {
fn fill(&mut self, k: usize, n: usize, demo: bool) -> Result<(), Error> {
let blocks = (k * n).div_ceil(BLOCK as usize) as u32;
let launch = self.module.prepare_fill(LaunchConfig1D::new(blocks, BLOCK, 0))?;
let all = &mut self.all;
Ok(self.module.fill(self.stream, &launch, all, n as u32, demo as u32)?)
}
fn run(&mut self, steps: &[Step], pairs: &DeviceBuffer<u32>) -> Result<(), Error> {
for st in steps {
let per = st.len.div_ceil(BLOCK as usize).min((1024 / st.count).max(1)) as u32;
let config = LaunchConfig1D::new(st.count as u32 * per, BLOCK, 0);
let launch = self.module.prepare_step(config)?;
let (first, len, add) = (st.first as u32, st.len as u32, st.add as u32);
let all = &mut self.all;
self.module.step(self.stream, &launch, all, pairs, first, len, per, add)?;
}
Ok(())
}
fn print_ranks(&self, k: usize, n: usize, when: &str) -> Result<(), DriverError> {
let h = self.all.to_host_vec(self.stream)?;
println!("{when}");
for r in 0..k {
let rank = &h[r * n..r * n + n];
let row: String = rank.iter().map(|v| format!("{v:3}")).collect();
println!(" rank {r} {row}");
}
Ok(())
}
/// True if every rank holds the exact sum of all ranks' starting values.
fn correct(&self, k: usize, n: usize) -> Result<bool, DriverError> {
let h = self.all.to_host_vec(self.stream)?;
for i in 0..n {
let sum: f32 = (0..k).map(|r| (i % 16 + r) as f32).sum();
if (0..k).any(|r| h[r * n + i] != sum) {
return Ok(false);
}
}
Ok(true)
}
/// Average time of 1 all-reduce in milliseconds, over `reps` runs from fresh data.
fn time(&mut self, plan: &Plan, k: usize, n: usize, reps: usize) -> Timed {
let pairs = DeviceBuffer::from_host(self.stream, &plan.pairs)?;
let mut total = 0.0;
for _ in 0..reps {
self.fill(k, n, false)?;
let start = self.stream.record_event(Some(TIMING))?;
self.run(&plan.steps, &pairs)?;
let stop = self.stream.record_event(Some(TIMING))?;
stop.synchronize()?;
total += start.elapsed_ms(&stop)?;
}
Ok((total / reps as f32, self.correct(k, n)?))
}
}
/// 4 ranks of 8 floats, printed after every step of the ring.
fn demo(gpu: &mut Gpu) -> Result<(), Error> {
let (k, n) = (4, 8);
let plan = ring(k, n);
let pairs = DeviceBuffer::from_host(gpu.stream, &plan.pairs)?;
let title = "ring all-reduce, 4 ranks of 8 floats: rank r starts with r + 1";
gpu.fill(k, n, true)?;
gpu.print_ranks(k, n, title)?;
for s in 0..plan.steps.len() {
gpu.run(&plan.steps[s..s + 1], &pairs)?;
let phase = if s < k - 1 { "reduce-scatter" } else { "all-gather" };
gpu.print_ranks(k, n, &format!("after step {} ({phase})", s + 1))?;
}
Ok(())
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let k = 8;
let max_n = 4 << 20; // 4 Mi floats, 16 MiB per rank
let all = DeviceBuffer::<f32>::zeroed(&stream, k * max_n)?;
let mut gpu = Gpu { stream: &stream, module: &module, all };
demo(&mut gpu)?;
for _ in 0..40 {
gpu.time(&ring(k, max_n), k, max_n, 1)?; // about 0.4 s: let the clocks rise
}
let message = max_n * 4;
let (r, t) = (ring(k, max_n), tree(k, max_n));
let ring_share = r.busiest_rank(k, max_n) as f64 / message as f64;
let tree_share = t.busiest_rank(k, max_n) as f64 / message as f64;
println!("\nall-reduce on {k} simulated ranks");
println!(" steps busiest rank sends");
println!(" ring {:4} {ring_share:.2} x the message", r.steps.len());
println!(" tree {:4} {tree_share:.2} x the message", t.steps.len());
println!("\n message ring tree");
let mut all_ok = true;
let mut n = 1024;
while n <= max_n {
let (ring_ms, ring_ok) = gpu.time(&ring(k, n), k, n, 50)?;
let (tree_ms, tree_ok) = gpu.time(&tree(k, n), k, n, 50)?;
all_ok = all_ok && ring_ok && tree_ok;
let kib = (n * 4) as f64 / 1024.0;
println!(" {kib:6.0} KiB {ring_ms:7.3} ms {tree_ms:7.3} ms");
n *= 16;
}
let verdict = if all_ok { "PASSED" } else { "FAILED" };
println!("every rank holds the exact sum: {verdict}");
Ok(())
}// Chapter 19: ring and tree all-reduce, simulated on 1 GPU.
// Each rank is a slice of 1 buffer in the memory of 1 GPU. No network is measured.
// Build: nvcc -arch=native allreduce.cu -o allreduce
#include <algorithm>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cuda_runtime.h>
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
// 1 send: `len` floats from offset `from` of the buffer to offset `to`.
struct Transfer {
int from;
int to;
};
// 1 step of a collective: transfers that run at the same time, on different links.
struct Step {
int first; // index of the step's first transfer in the plan
int count; // number of transfers
int len; // floats per transfer
bool add; // add into the destination, or overwrite it
};
struct Plan {
std::vector<Transfer> transfers;
std::vector<Step> steps;
};
void addStep(Plan& plan, const std::vector<Transfer>& sends, int len, bool add)
{
int first = int(plan.transfers.size());
plan.transfers.insert(plan.transfers.end(), sends.begin(), sends.end());
plan.steps.push_back({first, int(sends.size()), len, add});
}
// Ring: reduce-scatter in k - 1 steps, then all-gather in k - 1 steps.
// Rank r owns elements [r n, r n + n) of the buffer; chunk c is n / k floats.
Plan ring(int k, int n)
{
Plan plan;
int chunk = n / k;
for (int s = 0; s < k - 1; ++s) {
std::vector<Transfer> sends;
for (int r = 0; r < k; ++r) {
int c = (r - s + k) % k;
int next = (r + 1) % k;
sends.push_back({r * n + c * chunk, next * n + c * chunk});
}
addStep(plan, sends, chunk, true);
}
for (int s = 0; s < k - 1; ++s) {
std::vector<Transfer> sends;
for (int r = 0; r < k; ++r) {
int c = (r + 1 - s + k) % k;
int next = (r + 1) % k;
sends.push_back({r * n + c * chunk, next * n + c * chunk});
}
addStep(plan, sends, chunk, false);
}
return plan;
}
// Binomial tree, k a power of 2: sums climb to rank 0, then the total comes back down.
Plan tree(int k, int n)
{
Plan plan;
for (int d = 1; d < k; d *= 2) {
std::vector<Transfer> sends;
for (int r = d; r < k; r += 2 * d) {
sends.push_back({r * n, (r - d) * n});
}
addStep(plan, sends, n, true);
}
for (int d = k / 2; d >= 1; d /= 2) {
std::vector<Transfer> sends;
for (int r = 0; r < k; r += 2 * d) {
sends.push_back({r * n, (r + d) * n});
}
addStep(plan, sends, n, false);
}
return plan;
}
// Bytes sent by the rank that sends the most.
double busiestRank(const Plan& plan, int k, int n)
{
std::vector<double> sent(k, 0.0);
for (const Step& st : plan.steps) {
for (int t = st.first; t < st.first + st.count; ++t) {
sent[plan.transfers[t].from / n] += st.len * sizeof(float);
}
}
return *std::max_element(sent.begin(), sent.end());
}
// `per` blocks for each transfer of the step; block b works on transfer b / per.
// Within 1 step no element is both read and written, so the transfers cannot race.
__global__ void runStep(float* all, const Transfer* sends, int len, int per, bool add)
{
Transfer t = sends[blockIdx.x / per];
int stride = per * blockDim.x;
for (int i = (blockIdx.x % per) * blockDim.x + threadIdx.x; i < len; i += stride) {
float v = all[t.from + i];
all[t.to + i] = add ? all[t.to + i] + v : v;
}
}
// Rank r, element i starts as value(r, i); the sum over ranks is exact in floats.
__host__ __device__ float value(int r, int i, bool demo)
{
return demo ? float(r + 1) : float(i % 16 + r);
}
__global__ void fill(float* all, int k, int n, bool demo)
{
int g = blockIdx.x * blockDim.x + threadIdx.x;
if (g < k * n) all[g] = value(g / n, g % n, demo);
}
struct Gpu {
float* all;
Transfer* sends;
};
void run(const Gpu& gpu, const Step& st, cudaStream_t s)
{
int per = std::min((st.len + 255) / 256, std::max(1024 / st.count, 1));
const Transfer* sends = gpu.sends + st.first;
runStep<<<st.count * per, 256, 0, s>>>(gpu.all, sends, st.len, per, st.add);
}
void upload(const Gpu& gpu, const Plan& plan)
{
size_t bytes = plan.transfers.size() * sizeof(Transfer);
check(cudaMemcpy(gpu.sends, plan.transfers.data(), bytes, cudaMemcpyHostToDevice));
}
void printRanks(const Gpu& gpu, int k, int n, const char* when)
{
std::vector<float> h(k * n);
check(cudaMemcpy(h.data(), gpu.all, h.size() * sizeof(float), cudaMemcpyDeviceToHost));
std::printf("%s\n", when);
for (int r = 0; r < k; ++r) {
std::printf(" rank %d ", r);
for (int i = 0; i < n; ++i) std::printf("%3.0f", h[r * n + i]);
std::printf("\n");
}
}
// 4 ranks of 8 floats, printed after every step of the ring.
void demo(const Gpu& gpu)
{
const int k = 4;
const int n = 8;
Plan plan = ring(k, n);
upload(gpu, plan);
fill<<<1, k * n>>>(gpu.all, k, n, true);
printRanks(gpu, k, n, "ring all-reduce, 4 ranks of 8 floats: rank r starts with r + 1");
for (size_t s = 0; s < plan.steps.size(); ++s) {
run(gpu, plan.steps[s], 0);
char when[64];
const char* phase = s < k - 1 ? "reduce-scatter" : "all-gather";
std::snprintf(when, sizeof when, "after step %zu (%s)", s + 1, phase);
printRanks(gpu, k, n, when);
}
}
// True if every rank holds the exact sum of all ranks' starting values.
bool correct(const Gpu& gpu, int k, int n)
{
std::vector<float> h(size_t(k) * n);
check(cudaMemcpy(h.data(), gpu.all, h.size() * sizeof(float), cudaMemcpyDeviceToHost));
for (int i = 0; i < n; ++i) {
float sum = 0.0f;
for (int r = 0; r < k; ++r) sum += value(r, i, false);
for (int r = 0; r < k; ++r) {
if (h[size_t(r) * n + i] != sum) return false;
}
}
return true;
}
// Average time of 1 all-reduce in milliseconds, over `reps` runs from fresh data.
float timeAllReduce(const Gpu& gpu, const Plan& plan, int k, int n, int reps, bool* ok)
{
upload(gpu, plan);
cudaEvent_t start, stop;
check(cudaEventCreate(&start));
check(cudaEventCreate(&stop));
float total = 0.0f;
int blocks = (k * n + 255) / 256;
for (int rep = 0; rep < reps; ++rep) {
fill<<<blocks, 256>>>(gpu.all, k, n, false);
check(cudaEventRecord(start));
for (const Step& st : plan.steps) run(gpu, st, 0);
check(cudaEventRecord(stop));
check(cudaEventSynchronize(stop));
float ms;
check(cudaEventElapsedTime(&ms, start, stop));
total += ms;
}
*ok = correct(gpu, k, n);
check(cudaEventDestroy(start));
check(cudaEventDestroy(stop));
return total / reps;
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %d SMs\n", prop.name, prop.multiProcessorCount);
const int k = 8;
const int maxN = 4 << 20; // 4 Mi floats, 16 MiB per rank
Gpu gpu;
check(cudaMalloc(&gpu.all, size_t(k) * maxN * sizeof(float)));
check(cudaMalloc(&gpu.sends, 256 * sizeof(Transfer)));
demo(gpu);
bool ok = true;
bool all = true;
for (int warm = 0; warm < 40; ++warm) { // about 0.4 s: let the clocks rise
timeAllReduce(gpu, ring(k, maxN), k, maxN, 1, &ok);
}
Plan r = ring(k, maxN);
Plan t = tree(k, maxN);
double message = maxN * sizeof(float);
double ringShare = busiestRank(r, k, maxN) / message;
double treeShare = busiestRank(t, k, maxN) / message;
std::printf("\nall-reduce on %d simulated ranks\n", k);
std::printf(" steps busiest rank sends\n");
std::printf(" ring %4zu %.2f x the message\n", r.steps.size(), ringShare);
std::printf(" tree %4zu %.2f x the message\n", t.steps.size(), treeShare);
std::printf("\n message ring tree\n");
for (int n = 1024; n <= maxN; n *= 16) {
float ringMs = timeAllReduce(gpu, ring(k, n), k, n, 50, &ok);
all = all && ok;
float treeMs = timeAllReduce(gpu, tree(k, n), k, n, 50, &ok);
all = all && ok;
double kib = n * sizeof(float) / 1024.0;
std::printf(" %6.0f KiB %7.3f ms %7.3f ms\n", kib, ringMs, treeMs);
}
std::printf("every rank holds the exact sum: %s\n", all ? "PASSED" : "FAILED");
check(cudaFree(gpu.all));
check(cudaFree(gpu.sends));
return all ? 0 : 1;
}
Common mistakes
- Calling collectives in a different order on different ranks. Every rank must make the same calls in the same order; otherwise ranks wait for partners that never arrive.
- An ID that did not reach every rank.
ncclCommInitRankwaits until all ranks join with the samencclUniqueId, so a missing or different ID causes the start-up to hang. - Driving several GPUs from 1 thread without a group. Place the calls between
ncclGroupStartandncclGroupEnd. - Reading the result before the stream finishes. NCCL calls return when the work is queued. Synchronize the stream, or order later work after an event.
- Judging a collective by its algorithm bandwidth alone. Compare the bus bandwidth with the rated bandwidth of the link.
- Expecting identical floats from different algorithms. The ring and the tree add in different orders, so their sums can differ in the last bits.
- Interpreting a simulation on 1 GPU as a network measurement. Its links share 1 memory, so it measures steps and memory traffic, not link bandwidth.
Summary
- Data-parallel training needs an all-reduce of the gradients in every step. Every rank contributes, and every rank needs the sum.
- The 5 common collectives are broadcast, reduce, all-reduce, reduce-scatter and all-gather. An all-reduce is equivalent to a reduce-scatter followed by an all-gather.
- A message costs α + m / B. Small messages are latency-bound, and large messages are bandwidth-bound.
- The link of a single collector carries (k − 1) m in each direction. Each link of a ring carries 2 (k − 1) m / k, in 2 (k − 1) steps. For 4 ranks and 100 MB, this is 150 MB compared with 300 MB, and 6 ms compared with 24 ms.
- A binomial tree takes 2 log2 k steps but carries the whole message in each step. For 8 ranks with α = 10 µs and B = 25 GB/s, it is faster than the ring below 470 KB.
- On 1 GPU with 102 GB/s, with 8 ranks as slices of 1 buffer, each step cost about 12 µs. At 4 KiB the tree ran 2.3 times as fast as the ring. At 16 MiB both moved 587 MB of memory traffic at about 84 GB/s.
- NCCL builds rings and trees from the topology and runs each collective as 1 kernel on a stream. Ranks join a group with a shared unique ID, and a thread that drives several GPUs uses group calls.
With this chapter we conclude the part of the book on systems with more than one GPU. In the Epilogue we look at the directions in which GPU hardware and its programming are developing.
Exercises
- Trace a ring all-reduce for k = 3 ranks that hold 1, 2 and 3 in each of 6 floats. List what each rank sends and holds after each of the 4 steps.
- Compute the time of a ring all-reduce of 4 GB over 8 H100 SXM GPUs at NVLink 4’s 450 GB/s in each direction. How long would a single collector need over the same links?
- Derive the crossover size m* between the ring and the binomial tree for k = 16, α = 5 µs and B = 50 GB/s.
- In
allreduce.cu, changekto 4 and to 16 and run the program. How do the times at 4 KiB change, and which count from Section 28.4.3 or 28.5.1 explains the change? - The tree in Listing 28.2 assumes that k is a power of 2. Which ranks lose their partner when
k = 6, and how would you change
treeto handle them? - Write a plan for an all-gather alone and add it to the program. Each rank starts with 1 chunk. How many steps does it take, and how many bytes does each rank send?
- Prove that within 1 reduce-scatter step of the ring, no chunk is both read and written.
- The NCCL tests report an algorithm bandwidth of 160 GB/s for an all-reduce over 8 GPUs. Compute the bus bandwidth, and compare it with NVLink 4’s 450 GB/s in each direction.
Sources and further reading
- NVIDIA, NCCL User Guide, “Overview”, “Collective Operations”, “Group Calls” and “Environment Variables”: https://docs.nvidia.com/deeplearning/nccl/user-guide/docs/
- NVIDIA, NCCL source code: https://github.com/NVIDIA/nccl, and the NCCL tests with
doc/PERFORMANCE.mdon algorithm and bus bandwidth: https://github.com/NVIDIA/nccl-tests - S. Jeaugey, “Massively Scale Your Deep Learning Training with NCCL 2.4”, NVIDIA Technical Blog, 2019. Double binary trees.
- P. Patarasuk and X. Yuan, “Bandwidth Optimal All-reduce Algorithms for Clusters of Workstations”, Journal of Parallel and Distributed Computing 69(2), 2009.
- R. Thakur, R. Rabenseifner and W. Gropp, “Optimization of Collective Communication Operations in MPICH”, International Journal of High Performance Computing Applications 19(1), 2005. The α-β cost model and the choice of algorithm by message size.
- PyTorch, “DistributedDataParallel” and “torchrun” documentation: https://pytorch.org/docs/stable/
- NVIDIA, NVLink and NVSwitch product pages, for the bandwidths of each generation: https://www.nvidia.com/en-us/data-center/nvlink/
Chapter 13: Rust Meets the GPU
Code companion: the complete, buildable code for this chapter lives in
code/ch13_rust_vector_add/in the repository.
This part of the book changes language but not hardware. The GPU remains the
machine of Chapter 2, and the kernels of Chapters 3-12 still run on it. What
changes is the host: Rust replaces C++ for allocating device memory, moving
data, and launching kernels. This chapter covers the Rust CUDA ecosystem
(rustacuda and cudarc) and a complete Rust host program, with the safety
properties Rust provides at each step.
13.1 Rust on the Host
The GPU failure modes discussed in earlier chapters are often host-side
failures first: a leak is a missing cudaFree, a use-after-free is a dangling
device pointer, and a race is usually launched from the host. Rust’s ownership
system addresses these directly:
- Ownership and lifetimes. A
CudaSlice<T>owns its device allocation. When it is dropped, the allocation is freed. Double-frees and leaks become type errors rather than runtime incidents. - No data races by construction. The borrow checker prevents two mutable references to the same buffer from existing simultaneously, a guarantee the C++ compiler does not offer.
Result-based errors. CUDA’scudaError_tbecomes a typedResult<T, CudaError>. Ignoring an error is a compile-time warning throughmust_use, not silent misbehaviour.
The cost is the one Rust charges everywhere: the borrow checker rejects code it
cannot prove safe, and the FFI boundary, where unsafe lives, must be drawn
precisely. This chapter is about drawing that boundary well.
13.2 The Ecosystem: rustacuda and cudarc
Two host libraries dominate:
rustacuda- an older wrapper over the CUDA driver API. It provides safe modules for contexts, modules, functions, streams, and memory. It is historically important and now largely superseded for new work.cudarc- the actively maintained wrapper around the driver API (cudarc::driver), NVRTC (cudarc::nvrtc), and the CUDA libraries (cuBLAS, cuDNN, cuFFT, cuRAND, NCCL). It exposes three layers per wrapper:safe(high-level, checked),result(thin, returns error codes), andsys(raw FFI). This book usescudarc.
CUDA-Oxide (Chapter 14) is different in kind: not a wrapper around CUDA
C++, but a compiler that turns Rust kernels into PTX. This chapter uses
cudarc to drive existing kernels compiled from C++.
13.3 The Kernel, Compiled Ahead of Time
The Chapter 3 vector-add kernel is reused and compiled to PTX with nvcc:
// kernels/vector_add.cu
// Compiled once, ahead of time, to PTX:
// nvcc -arch=compute_60 -ptx kernels/vector_add.cu -o vector_add.ptx
// compute_60 PTX runs on any CUDA 12.x GPU (Pascal or newer) via the
// driver's JIT; use compute_87 on Jetson Orin, compute_80 on A100, or
// compute_90 on H100 for native SASS.
extern "C" __global__ void vector_add(const float* a, const float* b,
float* c, int n)
{
const int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) c[i] = a[i] + b[i];
}
CUDA C++ mangles kernel names like any C++ symbol. The driver API loads
kernels by name (Chapter 12), so extern "C" guarantees the module symbol is
literally vector_add. The Rust side can then look it up without demangling.
13.4 The Rust Host Program
// main.rs - Rust host driving the vector_add kernel via cudarc.
// Requires: CUDA toolkit installed (for the driver and nvrtc), and the
// vector_add.ptx file in the working directory (or embedded; see 13.5).
use cudarc::driver::{CudaDevice, CudaSlice, LaunchAsync, LaunchConfig};
use cudarc::nvrtc::Ptx; // wraps PTX source: Ptx::from_file or Ptx::from_src
fn main() -> Result<(), Box<dyn std::error::Error>> {
// --- Device handle -----------------------------------------------------
// CudaDevice::new(0) opens the first GPU, initialising the driver and
// creating the CUDA context. It returns Result: no GPU -> Err here,
// reported as a typed error instead of a crash.
let dev = CudaDevice::new(0)?;
// --- Problem size ------------------------------------------------------
const N: usize = 1 << 20; // 1,048,576 elements
let n32: i32 = N as i32; // kernel expects a 32-bit int
// --- Host data ----------------------------------------------------------
let a: Vec<f32> = (0..N).map(|i| i as f32).collect();
let b: Vec<f32> = (0..N).map(|i| 2.0 * i as f32).collect();
// --- Device allocation ---------------------------------------------------
// alloc_zeros allocates device memory and zero-initialises it. The
// returned CudaSlice<f32> OWNS the allocation: dropping it frees it.
// No cudaFree call appears in this program.
let mut d_a: CudaSlice<f32> = dev.alloc_zeros::<f32>(N)?;
let mut d_b: CudaSlice<f32> = dev.alloc_zeros::<f32>(N)?;
let mut d_c: CudaSlice<f32> = dev.alloc_zeros::<f32>(N)?;
// --- Host -> device copies ----------------------------------------------
// htod_copy_into takes ownership of the host Vec because the copy is
// queued on the device's stream; no other code can mutate the buffer while
// it is in flight. We pass clones so the originals remain usable for
// verification below. The &mut destination expresses that the copy mutates
// the device buffer, and Rust requires exclusive access to do so.
dev.htod_copy_into(a.clone(), &mut d_a)?;
dev.htod_copy_into(b.clone(), &mut d_b)?;
// --- Load the PTX and fetch the kernel handle ---------------------------
// load_ptx loads the module and registers the named kernel. The PTX is
// wrapped in a Ptx: Ptx::from_file for a path, Ptx::from_src for an
// embedded string (13.5). Missing files and missing symbols surface as
// Results.
let module = "vector_add";
dev.load_ptx(Ptx::from_file("vector_add.ptx"), module, &["vector_add"])?;
let f = dev.get_func(module, "vector_add")
.ok_or("kernel 'vector_add' not found in the loaded module")?;
// --- Launch --------------------------------------------------------------
// The launch is marked unsafe: the configuration (grid/block shape) and
// the argument tuple must match the kernel's real signature and index
// space. cudarc checks argument arity and types at the type level but
// cannot verify the kernel's internal assumptions - hence the SAFETY
// comment.
//
// SAFETY: the grid covers N threads (LaunchConfig::for_num_elems rounds up
// to whole warps), the kernel guards with `if (i < n)`, and the argument
// tuple (&d_a, &d_b, &mut d_c, n32) matches the extern "C" signature.
unsafe {
f.launch(LaunchConfig::for_num_elems(N as u32),
(&d_a, &d_b, &mut d_c, n32))
}?;
// --- Device -> host copy -------------------------------------------------
// dtoh_sync_copy blocks until the stream's work completes and copies the
// result back. The ? propagates any device error encountered.
let c: Vec<f32> = dev.dtoh_sync_copy(&d_c)?;
// --- Verify ---------------------------------------------------------------
let max_err = c.iter().zip(a.iter().zip(b.iter()))
.map(|(c, (a, b))| (c - (a + b)).abs())
.fold(0.0f32, f32::max);
println!("max error = {max_err}");
// d_a, d_b, d_c are dropped here; their destructors free the allocations.
// The device handle's context is cleaned up on drop.
Ok(())
}Safety ledger. The only unsafe block is the launch. The type system
checks the arity and types of the argument tuple (&d_a, &d_b, &mut d_c, n32), but not the semantics: that the kernel’s index arithmetic matches the
launch configuration, or that n32 matches the kernel’s int n. The SAFETY
comment states the invariants a reviewer must check, the same contract Chapter
3 expressed as comments in C++.
Everything else, allocation, copies, and module loading, is a safe API:
ownership guarantees lifetimes, and Result guarantees error handling.
What is not solved. The kernel is still C++ and still unsafe by
construction: an out-of-bounds write inside vector_add corrupts whatever it
corrupts, and Rust cannot observe it. Rust secures the host, not the device.
CUDA-Oxide (Chapter 14) addresses the device side.
13.5 Embedding the PTX
A filesystem dependency is fragile in production. The PTX can be embedded in the binary at compile time:
#![allow(unused)]
fn main() {
// build.rs (or a const in the crate) embeds the PTX text.
const VECTOR_ADD_PTX: &str = include_str!("vector_add.ptx");
// Load directly from the embedded string instead of the filesystem.
// Ptx::from_src wraps the string; Ptx::from_file wraps a path (13.4).
dev.load_ptx(Ptx::from_src(VECTOR_ADD_PTX), module, &["vector_add"])?;
}include_str! inlines the file at compile time. The binary is self-contained,
and the kernel cannot go missing during deployment. The capstone uses this
pattern.
13.6 Comparing with the C++ Host
| Concern | C++ (Chapters 3-6) | Rust + cudarc |
|---|---|---|
| Allocation lifetime | Manual cudaMalloc/cudaFree | CudaSlice RAII on drop |
| Copy direction | cudaMemcpy with direction enum | Typed htod_copy_into / dtoh_sync_copy |
| Error handling | CHECK macro discipline | Typed Result with ? |
| Kernel launch | <<<>>>, unchecked args | unsafe launch with typed args + SAFETY comment |
| Data races | Compiler silent | Borrow checker rejects at compile time |
| Device-side safety | No help | No help (until CUDA-Oxide) |
Each right-hand entry removes a bug class that the left-hand column required a
discipline or a runtime tool to catch. The price, the unsafe block and its
SAFETY comment, is explicit and small.
13.7 Lifetimes in Action
The claims in §13.1 have concrete demonstrations. The borrow checker rejects whole classes of GPU programs at compile time:
#![allow(unused)]
fn main() {
// What the borrow checker prevents (none of these compile):
// 1. Two mutable borrows of the same device buffer. The launch tuple below
// needs two &mut to d_c, which Rust forbids:
// f.launch(config, (&mut d_c, &mut d_c)) // ERROR: cannot borrow twice
// In C++ this compiles and produces a race inside the kernel.
// 2. Using a buffer after moving it. The CudaSlice is gone after the move, so
// any use is a compile error rather than a use-after-free:
// let stolen = d_a; // d_a is moved into stolen
// dev.htod_copy_into(&a, &mut d_a); // ERROR: borrow of moved value
// In C++, the equivalent sequence (copying a raw pointer, then freeing it)
// is a use-after-free that requires Compute Sanitizer to catch at run time.
// 3. Passing a host Vec where a device slice is expected. The types do not
// match, so the error is at the call site:
// dev.htod_copy_into(&host_vec, &mut d_c); // ERROR: type mismatch
}Each rejected program is a bug class that the C++ chapters required a runtime
tool (Compute Sanitizer, Chapter 16) or a discipline (the CHECK macro,
Chapter 3) to catch. Rust moves detection to the compiler, which runs earlier
and cannot be forgotten. The borrow checker is the CHECK macro promoted to a
compile-time guarantee.
The Unsafe Boundary Is an Explicit Contract
The design decision in this chapter is where the unsafe boundary is drawn.
Rust’s safety guarantees apply only to code within the rules of ownership and
borrowing. A CUDA kernel launch sits at the edge of those rules because the
host cannot see inside the kernel and therefore cannot prove that the kernel’s
index arithmetic matches the launch configuration. That unprovable obligation
is what the unsafe block marks.
Before the launch, the guarantees are compile-time. CudaDevice::new(0)
returns a Result, so a missing GPU must be handled. alloc_zeros returns an
owned CudaSlice, so the allocation is freed when the slice is dropped.
htod_copy_into takes ownership of the host vector, so the data cannot be
mutated while the copy is in flight. The launch requires &mut d_c for the
output buffer, so two kernels cannot hold mutable references to the same buffer
simultaneously.
The launch is where the type system runs out. The tuple (&d_a, &d_b, &mut d_c, n32) has the right arity and types, but nothing in the types proves that
the grid covers exactly N elements, that the kernel’s if (i < n) guard
matches, or that n32 is the correct interpretation of the kernel’s int n.
The SAFETY comment is the contract that fills the gap: a reviewer must be
able to verify those facts from the comment and the surrounding context. This
is the same contract Chapter 3 expressed as C++ comments. Rust makes everything
around the launch enforceable by the compiler, leaving one small, documented,
auditable seam instead of a program-wide discipline.
Common Pitfalls
- Forgetting
extern "C"on the kernel. The driver looks up kernels by unmangled name; without it,get_func(module, "vector_add")fails. - Copying a
CudaSliceinstead of moving it. Device buffers are unique resources; use&mutand moves, not copies. - Putting
unsafearound the whole program instead of just the launch. The purpose is to isolate the unprovable part, not to annotate everything. - Ignoring the
SAFETYcomment. If the kernel-side assumptions cannot be stated, the launch is not known to be correct.
Check Your Understanding
Why does extern "C" matter?
C++ mangles function names, for example _Z11vector_add.... The CUDA driver
loads kernels by exact string name, so extern "C" guarantees the symbol is
literally vector_add, letting the Rust host look it up without demangling.
Why is &mut d_c required in the launch tuple?
The kernel writes through the c pointer. Rust requires exclusive access for
mutation, so the launch needs &mut d_c; passing &d_c would be a compile
error because shared references cannot be used for mutation. The borrow checker
also prevents two kernels from holding &mut to the same buffer at once.
What does include_str! provide over Ptx::from_file?
include_str! embeds the PTX text into the binary at compile time. The binary
is self-contained and cannot lose the kernel file during deployment.
Ptx::from_file reads the filesystem at run time, which is simpler for
experimentation but fragile in production.
Key Takeaways
- Rust secures the host: ownership prevents leaks and double-frees, the borrow checker prevents data races, and Result prevents ignored errors.
- cudarc provides RAII device memory (CudaSlice), typed copies, and module loading from PTX.
- extern “C” keeps kernel symbols unmangled so the driver can find them by name.
- The unsafe launch is explicit; the SAFETY comment states the kernel-side obligations the type system cannot check.
- include_str! embeds PTX in the binary, removing the filesystem dependency.
13.8 Exercises
- Explain why
extern "C"on the kernel matters fordev.get_func(module, "vector_add"). What would happen without it? - The launch is wrapped in
unsafe. List three kernel-side assumptions that theSAFETYcomment must document. - Trace the lifetimes: why is
&mut d_c(not&d_c) required in the launch tuple, and what does the borrow checker prevent? - Compare
include_str!with a runtime filesystem read. When is the filesystem version the right choice?
Sources and Further Reading
- NVIDIA, CUDA C++ Programming Guide: https://docs.nvidia.com/cuda/cuda-c-programming-guide/
- The Rust Book, “Ownership” and “Unsafe Rust”: https://doc.rust-lang.org/book/
rustacudacrate documentation: https://docs.rs/rustacuda/cudarccrate documentation: https://docs.rs/cudarc/
Chapter 14: CUDA-Oxide - Kernels in Pure Rust
Code companion: the complete, buildable code for this chapter lives in
code/ch14_cuda_oxide/in the repository.
Chapter 13 secured the host with Rust, but the kernel remained C++ compiled by
nvcc and invoked through an unsafe boundary. CUDA-Oxide is NVIDIA Labs’
experimental answer to the remaining gap: a rustc codegen backend that
compiles idiomatic Rust kernels directly to PTX. There is no DSL, no
foreign-language binding, and no nvcc; host and device code can live in the
same file. This chapter describes the project as documented by its repository,
including its pipeline and the parts that remain experimental.
14.1 What CUDA-Oxide Is
CUDA-Oxide (repository NVlabs/cuda-oxide, announced May 2026) is described by
its authors as:
“An experimental Rust-to-CUDA compiler that lets you write SIMT GPU kernels in safe(ish), idiomatic Rust. It compiles standard Rust code directly to PTX - no DSLs, no foreign language bindings, just Rust.”
Its design goals, from the project documentation:
- Single-source compilation. Host and device code live in the same file and
are built with one command,
cargo oxide build. - A rustc codegen backend that compiles
#[kernel]functions to PTX. - Device-side abstractions: type-safe indexing, shared memory, scoped atomics, barriers, TMA, and warp or cluster operations.
- Compile-time kernel policies for separate tuned specialisations without runtime policy arguments.
- A host-side runtime (
cuda-core,cuda-async) for memory management, pinned host transfers, and kernel launching.
The project’s own term “safe(ish)” matters. CUDA-Oxide keeps Rust’s type system and ownership on the device, but SIMT programming includes operations, such as raw launch configuration and memory ordering, that cannot yet be fully proven safe. The project is explicit about the boundary.
14.2 The Compilation Pipeline
CUDA-Oxide does not translate Rust to CUDA C. It reuses rustc’s internal representations and replaces only the code generation stage:
Because the front end is real rustc, ownership, borrowing, pattern matching, and traits are checked before GPU code is generated. A kernel that violates the borrow checker never becomes PTX. The experimental part is the back end: Pliron is a young framework, and the project warns that lowering to LLVM IR may contain bugs and missing features.
14.3 Installation
CUDA-Oxide is Linux-only at the time of writing (tested on Ubuntu 24.04) and requires:
cargo-oxide, the cargo subcommand that drives the build (cargo oxide build/run/inspect/...);- Rust nightly with the
rust-src,rustc-dev, andllvm-toolscomponents, pinned in the project’srust-toolchain.toml; - CUDA Toolkit 12.x or newer;
- Clang and libclang development headers, required by
bindgenwhen building the hostcuda-bindingscrate.
# Install the cargo subcommand with the pinned nightly toolchain:
cargo +nightly-2026-04-03 install --git https://github.com/NVlabs/cuda-oxide.git cargo-oxide
# On first run, cargo-oxide fetches and builds the codegen backend.
# Verify CUDA is on the path:
export PATH="/usr/local/cuda/bin:$PATH"
nvcc --version
The workflow is cargo-shaped:
cargo oxide run host_closure # build and run an example
cargo oxide inspect vecadd # build and print the generated PTX
cargo oxide pipeline vecadd # show the full pipeline (MIR -> Pliron -> LLVM -> PTX)
cargo oxide sanitize vecadd --tool memcheck # CUDA correctness checks
cargo oxide debug vecadd --tui # debug with cuda-gdb
14.4 A First Kernel: The Generic map
The project’s documented example is a generic elementwise map, the Rust
equivalent of Chapter 10’s transformKernel, with the kernel written in Rust:
// Single source file: device AND host code together.
use cuda_device::{kernel, thread, DisjointSlice};
use cuda_host::{cuda_module, load_kernel_module};
use cuda_core::{CudaContext, DeviceBuffer, LaunchConfig};
// ---------------------------------------------------------------------------
// Device side: a generic kernel that applies any function to each element.
// F can be a closure with captures - rustc monomorphises it to a concrete
// type at compile time, exactly like a C++ template instantiation.
// ---------------------------------------------------------------------------
#[cuda_module]
mod kernels {
use super::*;
// The #[kernel] attribute tells the backend to compile this function
// to PTX. It is the Rust equivalent of __global__.
#[kernel]
pub fn map<T: Copy, F: Fn(T) -> T + Copy>(f: F, input: &[T],
mut out: DisjointSlice<T>) {
let idx = thread::index_1d(); // threadIdx/blockIdx, fused
let i = idx.get(); // the global linear index
// DisjointSlice guarantees this thread's slot is exclusive:
// two threads can never get_mut the same element.
if let Some(out_elem) = out.get_mut(idx) {
*out_elem = f(input[i]);
}
}
}
// ---------------------------------------------------------------------------
// Host side: allocate, load the module, launch.
// ---------------------------------------------------------------------------
fn main() -> Result<(), Box<dyn std::error::Error>> {
let ctx = CudaContext::new(0)?; // open GPU 0
let stream = ctx.default_stream();
let data: Vec<f32> = (0..1024).map(|i| i as f32).collect();
let input = DeviceBuffer::from_host(&stream, &data)?;
let mut output = DeviceBuffer::<f32>::zeroed(&stream, 1024)?;
// Load the module: the codegen backend writes host_closure.ptx next to
// Cargo.toml; load_kernel_module reads that file and returns a CUDA
// module. from_module binds it to the typed launch API generated by
// #[cuda_module].
let module = load_kernel_module(&ctx, "host_closure")?;
let typed = kernels::from_module(module)?;
// Launch with a closure. `factor` is captured and passed to the GPU
// automatically (scalarised into a kernel parameter).
let factor = 2.5f32;
// SAFETY: this raw configuration is fully 1-D, matches index_1d(), and
// launches one thread per output element. A launch contract can move
// this proof into the generated safe API.
unsafe {
typed.map::<f32, _>(
stream.as_ref(),
LaunchConfig::for_num_elems(1024),
move |x: f32| x * factor,
&input,
&mut output,
)
}?;
let result = output.to_host_vec(&stream)?;
assert!((result[1] - 2.5).abs() < 1e-5);
println!("PASSED: CUDA-Oxide map closure produced expected results");
Ok(())
}The device-side pieces are:
#[cuda_module] mod kernels { ... }makes the backend compile the#[kernel]functions in the module to PTX and generate the host loading and launch glue.#[kernel] pub fn map<T: Copy, F: Fn(T) -> T + Copy>(...)declares a generic kernel. The compiler instantiates one PTX function per(T, F)combination, the same monomorphisation used by C++ templates in Chapter 10.thread::index_1d()is the fused equivalent ofblockIdx.x * blockDim.x + threadIdx.xfrom Chapter 3, returned as a typed index.DisjointSlice<T>is a guaranteed-disjoint view of the output. Itsget_mut(idx)method returns a mutable reference to this thread’s exclusive element. Two threads cannot obtain mutable access to the same slot, making the one-thread-per-output pattern a type-level guarantee.if let Some(out_elem) = out.get_mut(idx)expresses the boundary guard:Noneis the out-of-range case.
The host-side pieces are:
CudaContext::new(0)opens the GPU.DeviceBuffer::from_host(&stream, &data)allocates and copies in one call on the given stream.load_kernel_modulereads the PTX file produced by the backend, andkernels::from_modulebinds it to the generated typed launch API. Thetyped.map::<f32, _>(...)method is generated from the kernel signature, so arguments are type-checked against the kernel parameter list. In the standalone generic-kernel build, the supported path loads the PTX file because a PTX bundle is not yet embedded in the executable. Non-generic kernels can use the embeddedkernels::load.unsafe { ... }marks the raw launch becauseLaunchConfigis raw data: nothing in its type proves that the grid shape matches the kernel’s indexing assumptions. TheSAFETYcomment states the proof obligation, as in Chapter 13.
14.5 The Safety Progression: #[launch_contract]
CUDA-Oxide’s plan for the raw unsafe launch is the launch contract: a
#[launch_contract(...)] attribute that moves configuration validation into
generated code. A kernel annotated with a contract receives a checked
PreparedLaunch through a safe generated method. Launch dimensions and
resources are validated against the declared contract instead of being an
unverifiable unsafe obligation.
This is the project’s roadmap in miniature: each unsafe block is a known gap
with a planned replacement. The unsafe in this chapter is not a licence to
ignore safety; it is documented debt that the project is paying down.
14.6 Async: cuda-async and DeviceOperation
The cuda-async crate changes the launch shape for composable asynchronous
work. The explicit stream: argument disappears and the launch returns a lazy
DeviceOperation that executes when .sync() or .await is called:
#![allow(unused)]
fn main() {
use cuda_async::device_operation::DeviceOperation;
// Assuming module, input, output come from the cuda-async setup:
let factor = 2.5f32;
let launch = unsafe {
// SAFETY: the raw launch is 1-D and matches this kernel's index space.
module.map_async::<f32, _>(
LaunchConfig::for_num_elems(1024),
move |x: f32| x * factor,
&input,
&mut output,
)?
};
launch.sync()?; // or: .await?;
}The lazy operation lets a program build a graph of GPU work without executing
it, the same idea as CUDA Graphs (Chapter 6, §6.7), expressed as composable
Rust values. .sync() blocks; .await composes with async/await host code.
The capstone uses this shape.
14.7 Device-Side Abstractions Beyond map
The project documents device-side facilities beyond simple indexing:
- Shared memory - typed, scoped allocation within a block;
- Scoped atomics - atomic operations with explicit thread scopes, as in Chapter 5, with Rust scoping;
- Barriers - block and cluster synchronisation;
- TMA (Tensor Memory Accelerator) - Hopper’s bulk asynchronous copies;
- Warp/cluster operations - shuffle-like primitives such as Chapter 8’s
__shfl_down_sync, with type-safe masks.
These are in active development. The API may change between revisions; this is the nature of alpha software.
14.8 CUDA-Oxide vs the Alternatives
| Approach | Kernel language | Device safety | Maturity |
|---|---|---|---|
| CUDA C++ (Chapters 3-12) | C++ | None (by hand) | Production |
| Rust host + C++ kernel (Ch. 13) | C++ | Host only | Production |
| CUDA-Oxide (this chapter) | Rust | Type-checked, safe(ish) | Alpha, Linux, nightly |
cudarc nvrtc JIT | C++ string | Host only | Production |
CUDA-Oxide is not yet a production tool for most teams. It is an architecture
preview: a demonstration that Rust can target the GPU without giving up its
guarantees, and a first draft of the safety story SIMT programming needs. Its
pipeline (MIR to Pliron to LLVM to PTX) and abstractions (DisjointSlice,
launch contracts, async operations) point toward the shape of CUDA’s Rust
future. The underlying principles, type-safe indexing, explicit safety
obligations, and single-source compilation, are the same principles this book
has used since Chapter 3.
Safe SIMT and Hardware Assumptions
In CUDA C++, the “one thread per output element” rule is enforced by a comment.
Nothing in the language stops a thread from writing out[i + 1] or out[2*i];
the compiler accepts it, and the bug appears later as corrupt data or an
illegal memory access. CUDA-Oxide expresses such conventions in the type system
so violations become compile errors.
DisjointSlice<T> is the clearest example. Its get_mut(idx) returns a
mutable reference to the element owned by this thread and guarantees that no
other thread can obtain a mutable reference to the same element. The “one
thread per output, no races” property that Chapter 3 stated in a comment is now
an API property. thread::index_1d() fuses the index formula into one typed
operation, so the formula cannot be mistyped as a hand-written expression can.
Because the kernel is Rust, the borrow checker runs on the device code before
any PTX is generated: a kernel that would create two mutable references to the
same slot never compiles.
unsafe remains because launch geometry is still raw data. LaunchConfig
describes the number of threads, but nothing in its type proves that this count
matches the kernel’s indexing assumptions. The SAFETY comment documents the
obligation. The #[launch_contract] roadmap shows how this obligation can
become a checked precondition: a kernel declares its contract, and the generated
launch path validates the configuration against it.
The architectural point is that a system is safest when invalid programs cannot be written, not when it has the most runtime checks. CUDA-Oxide is an early, incomplete version of that idea: it moves some conventions into types, leaves others as documented unsafe obligations, and is explicit about the difference.
Common Pitfalls
- Assuming CUDA-Oxide is production-ready. It is alpha; APIs change between revisions. The companion code tracks CUDA-Oxide 0.2.1.
- Treating
DisjointSliceas a licence to ignore bounds.get_mutreturnsNonefor out-of-range indices; forgetting theif letguard still skips work silently. - Believing
unsafemeans unchecked. It means “checked by a human through the SAFETY comment”; write the comment before writing the launch. - Porting CUDA C++ idioms verbatim, such as pointer arithmetic, instead of using the Rust-native abstractions demonstrated in this chapter.
Check Your Understanding
What does DisjointSlice prevent that a comment in CUDA C++ does not?
It makes the one-thread-per-output property a type guarantee: two threads
cannot obtain get_mut for the same element. In CUDA C++, that invariant is
only a comment; nothing stops a thread from writing any index.
Why is the launch still unsafe if the kernel is safe?
The kernel’s internal indexing may be safe, but the launch configuration is raw
data. Nothing in LaunchConfig proves the grid covers the output exactly as
the kernel assumes, so the launch remains an unsafe obligation documented by a
SAFETY comment.
What does #[launch_contract] change about the obligation?
It moves the geometry proof into generated code. Launch dimensions and resources are validated against the kernel’s declared contract, so the unsafe obligation becomes a checked precondition instead of a manual comment.
Key Takeaways
- CUDA-Oxide is NVIDIA Labs’ rustc backend: #[kernel] Rust functions compile to PTX, with no nvcc or DSL.
- The pipeline Rust -> MIR -> Pliron -> LLVM -> PTX keeps rustc’s front-end guarantees (ownership, borrow checking) before GPU code is generated.
- DisjointSlice provides the one-thread-per-output, no-races guarantee at the type level.
- LaunchConfig is raw data; launching is unsafe until a #[launch_contract] moves the proof into generated code.
- CUDA-Oxide is alpha, Linux-only, and nightly-only: treat it as an architecture preview, not a production dependency.
14.9 Exercises
- Compare
thread::index_1d()with the Chapter 3 formulablockIdx.x * blockDim.x + threadIdx.x. What does the fused abstraction prevent? - Why is
DisjointSlice<T>’sget_mutthe type-level version of the Chapter 3 “one thread per output, no races” comment? - The raw launch is
unsafewith aSAFETYcomment;#[launch_contract]moves the proof into generated code. Explain the difference in terms of the obligation, not the syntax. - Using the pipeline diagram in §14.2, identify which phases run on the host toolchain and which produce device code. Why does borrow checking happen before any PTX generation?
Sources and Further Reading
- NVIDIA Labs, CUDA-Oxide repository: https://github.com/NVlabs/cuda-oxide
- NVIDIA, CUDA C++ Programming Guide, “Compute Capabilities” for PTX/SASS details: https://docs.nvidia.com/cuda/cuda-c-programming-guide/
- Rust Reference, “Inline assembly” and “Unsafe” sections: https://doc.rust-lang.org/reference/
Chapter 15: Capstone - The GPU Image Processing Pipeline
Code companion: the complete, buildable code for this chapter lives in
code/ch15_capstone/in the repository.
This chapter combines the earlier material into one complete system. The capstone is a GPU image-processing pipeline: RGB -> greyscale -> Gaussian blur -> Sobel edge detection, implemented three ways (hand-written CUDA C++, Thrust, and CUDA-Oxide Rust), streamed with pinned memory, verified against a CPU reference, and measured with CUDA events. It is small enough to fit in one chapter and structured enough to exercise the book’s methods end to end.
15.1 Pipeline and Data Flow
Design decisions and their rationale:
- Greyscale stored as
float, notunsigned char. Blur and Sobel accumulate fractional weights.floatavoids rounding at every stage and matches the arithmetic-intensity discussion of Chapter 1. The final edge map is scaled tounsigned charfor output. - Separable Gaussian. A 2-D Gaussian of radius 2 is a 5x5 stencil: 25 taps per output pixel. A separable Gaussian performs a horizontal 5-tap pass followed by a vertical 5-tap pass: 10 taps per pixel. The two-pass form has the same mathematical result and each pass is naturally coalesced.
- Sobel as two separable kernels. The Sobel operator is the pair of 3x3 kernels \(G_x\) and \(G_y\). Each factors into a derivative pass and a smoothing pass. This implementation computes the two 3x3 convolutions directly and takes the magnitude \(\sqrt{G_x^2 + G_y^2}\).
- Histogram at the end. The histogram verifies that the pipeline produced sensible data and demonstrates Chapter 8’s privatised histogram on a real workload.
15.2 Stage 1: RGB to Greyscale (CUDA C++)
The canonical coalesced kernel uses one thread per output pixel and the Chapter 3 index formula, so consecutive threads read consecutive pixels:
// ---------------------------------------------------------------------------
// rgbToGray: 3 bytes/pixel RGB (uchar3) -> 1 float/pixel greyscale.
// Consecutive threads -> consecutive pixels -> coalesced reads and writes.
// The weights are the standard BT.601 luma coefficients; they sum to 1.0,
// so no scaling is needed and a constant-grey input maps to itself.
// ---------------------------------------------------------------------------
__global__ void rgbToGray(const uchar3* rgb, float* gray, int numPixels)
{
const int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < numPixels)
{
const uchar3 px = rgb[i]; // 12-byte read, coalesced
// uchar3 components are 0..255; multiply in float to avoid
// integer truncation.
gray[i] = 0.299f * static_cast<float>(px.x)
+ 0.587f * static_cast<float>(px.y)
+ 0.114f * static_cast<float>(px.z);
}
}
uchar3 is CUDA’s built-in 3-byte vector type and matches the RGB layout
exactly. Its alignment is 1, so it can point at raw RGB bytes. A float3
would not be safe for the same data because it is 16-byte aligned.
15.3 Stage 2: Separable Gaussian Blur
The 5-tap weights for \(\sigma = 1\) are
[0.06136, 0.24477, 0.38774, 0.24477, 0.06136], a normalised Gaussian. The
horizontal pass reads a row segment including a halo of two pixels on each
side; the vertical pass does the same along columns.
An initial, plausible implementation clamps only the outermost stencil coordinates:
// WRONG at image borders:
__global__ void blurH(const float* in, float* out, int width, int height)
{
const int x = blockIdx.x * blockDim.x + threadIdx.x;
const int y = blockIdx.y * blockDim.y + threadIdx.y;
if (x < width && y < height)
{
const float* row = in + y * width;
const int x0 = max(x - 2, 0), x1 = min(x + 2, width - 1);
out[y * width + x] = 0.06136f * row[x0] + 0.24477f * row[x0]
+ 0.38774f * row[x] + 0.24477f * row[x1]
+ 0.06136f * row[x1];
}
}
This version is correct in the interior but wrong at borders. The inner taps
x-1 and x+1 reuse the clamped outer values, so the replicated border pixel
is weighted twice, for example as 0.06136 + 0.24477 on the left edge. The
correct version clamps each tap independently:
__global__ void blurH(const float* in, float* out, int width, int height)
{
const int x = blockIdx.x * blockDim.x + threadIdx.x;
const int y = blockIdx.y * blockDim.y + threadIdx.y;
if (x < width && y < height)
{
const float* row = in + y * width;
// Weights, left to right: [0.06136, 0.24477, 0.38774, 0.24477, 0.06136]
const float w[5] = {0.06136f, 0.24477f, 0.38774f, 0.24477f, 0.06136f};
float acc = 0.0f;
// Each tap clamps its index to the row bounds independently:
// interior pixels use the exact stencil; edge pixels are replicated.
#pragma unroll
for (int t = -2; t <= 2; ++t)
{
const int sx = min(max(x + t, 0), width - 1);
acc += w[t + 2] * row[sx];
}
out[y * width + x] = acc;
}
}
The first version is plausible and wrong; the second is correct by
construction. Border handling is the difference. The vertical pass uses the
same logic with x and y exchanged; it is omitted here to avoid repetition.
Separable blur uses two kernels rather than one fused 5x5 kernel. A fused kernel would read a 5x5 neighbourhood per thread, or communicate the intermediate image through shared memory with a block halo. Two global passes are simpler, fully coalesced, and bandwidth-dominated at this image scale.
15.4 Stage 3: Sobel Edge Detection
// ---------------------------------------------------------------------------
// sobel: magnitude of the gradient. Gx = derivative across x, smoothed in y;
// Gy = derivative across y, smoothed in x. We compute both 3x3 convolutions
// and the magnitude sqrt(Gx^2 + Gy^2) per pixel.
// ---------------------------------------------------------------------------
__global__ void sobel(const float* in, float* out, int width, int height)
{
const int x = blockIdx.x * blockDim.x + threadIdx.x;
const int y = blockIdx.y * blockDim.y + threadIdx.y;
if (x < width && y < height)
{
// Clamp the 3x3 neighbourhood at the borders (replicate-edge).
const int xm = max(x - 1, 0), xp = min(x + 1, width - 1);
const int ym = max(y - 1, 0), yp = min(y + 1, height - 1);
const float* r0 = in + ym * width;
const float* r1 = in + y * width;
const float* r2 = in + yp * width;
// Horizontal derivative Gx: [-1 0 1] across each of the three rows,
// weighted [1 2 1] down the columns.
const float gx = (r2[xp] + 2.0f * r1[xp] + r0[xp])
- (r2[xm] + 2.0f * r1[xm] + r0[xm]);
// Vertical derivative Gy: [-1 0 1] down the columns,
// weighted [1 2 1] across the rows.
const float gy = (r2[xm] + 2.0f * r2[x] + r2[xp])
- (r0[xm] + 2.0f * r0[x] + r0[xp]);
// Magnitude. sqrtf is the device-side square root.
out[y * width + x] = sqrtf(gx * gx + gy * gy);
}
}
\(G_x\) is a derivative in \(x\) (the kernel [-1 0 1]) convolved with a
smoothing in \(y\) (the kernel [1 2 1]); \(G_y\) is the transpose. The
kernel reads nine pixels and produces both convolutions.
15.4.1 Scale Back to unsigned char
The magnitude \(\sqrt{G_x^2 + G_y^2}\) is a float that can exceed 255. The
histogram counts unsigned char bins, so a scaling step is required. Clamping
is necessary: converting an out-of-range float to unsigned char is undefined
behaviour, and the histogram would count byte patterns instead of edges.
// Clamp the float edge magnitude to [0, 255] and store as uchar.
__global__ void scaleEdges(const float* in, unsigned char* out, int n)
{
const int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n)
{
const int v = static_cast<int>(in[i] + 0.5f); // round, don't truncate
out[i] = static_cast<unsigned char>(min(max(v, 0), 255));
}
}
15.5 The Streaming Host Pipeline
The frame loop uses the machinery of Chapters 4 and 6: pinned host memory, two streams, and double buffering so that transfers overlap kernels:
// ---------------------------------------------------------------------------
// One "frame" = load RGB, run the kernels, store edges. Frames arrive in host
// buffers h_rgb[0] and h_rgb[1]; the GPU processes one while the DMA engine
// uploads the next (Chapter 6, 6.5).
// ---------------------------------------------------------------------------
void processFrames(/* ... device buffers, streams, sizes ... */)
{
const int numPixels = width * height;
const bool last = (frame == frameCount - 1);
const int cur = frame % 2; // buffer holding THIS frame's input
const int nxt = (frame + 1) % 2; // buffer for the NEXT frame
// Upload the NEXT frame while THIS one computes (pinned memory), and
// record an event after it: the NEXT iteration's kernel waits on it.
if (!last)
{
CHECK(cudaMemcpyAsync(d_rgb[nxt], h_rgb[nxt],
rgbBytes, cudaMemcpyHostToDevice, sCopy));
CHECK(cudaEventRecord(copyDone[nxt], sCopy));
}
// Make the compute stream wait for THIS frame's copy. Its event was
// recorded in the previous iteration (or during the prime before the
// loop). cudaStreamWaitEvent installs the dependency without blocking.
CHECK(cudaStreamWaitEvent(sCompute, copyDone[cur], 0));
// The stages, all in the compute stream, in order:
const dim3 block(256);
const dim3 grid((numPixels + 255) / 256);
// d_rgb is a raw byte buffer; rgbToGray reads it as uchar3 (alignment 1,
// §15.2), so the view is explicit:
rgbToGray<<<grid, block, 0, sCompute>>>(
reinterpret_cast<const uchar3*>(d_rgb[cur]), d_gray, numPixels);
const dim3 b2(32, 8); // 2-D block: 32 x 8 threads
const dim3 g2((width + 31) / 32, (height + 7) / 8);
blurH <<<g2, b2, 0, sCompute>>>(d_gray, d_blurred, width, height);
blurV <<<g2, b2, 0, sCompute>>>(d_blurred, d_blurred2, width, height);
sobel <<<g2, b2, 0, sCompute>>>(d_blurred2, d_edges, width, height);
// Scale float edges back to uchar before the histogram: the histogram
// counts edge intensities, not the bytes of a float.
scaleEdges<<<grid, block, 0, sCompute>>>(d_edges, d_edges8, numPixels);
// The privatised histogram is a 1-D kernel with 256-thread blocks. It
// uses the same 1-D grid/block as rgbToGray, not the 2-D stencil block.
histogram<<<grid, block, 0, sCompute>>>(d_edges8, d_hist, numPixels);
// (histogram kernel as in Chapter 8, 8.8)
// Copy the edge map back (device -> host, pinned, async). The buffer is
// numPixels BYTES (uchar edges), not 4 bytes per pixel.
CHECK(cudaMemcpyAsync(h_edges[cur], d_edges8,
numPixels * sizeof(unsigned char),
cudaMemcpyDeviceToHost, sCompute));
}
The copy for frame \(n+1\) and the kernels for frame \(n\) operate on
different buffers, which is the condition for overlap (§6.5). The event and
dependency pair (cudaEventRecord plus cudaStreamWaitEvent) keeps the order
correct on every iteration without serialising the pipeline.
The 2-D grid gives each thread a natural (x, y) pixel. The 32x8 block shape
keeps blocks tile-shaped, with 32 threads in x so that warps are row-aligned.
15.6 The Same Pipeline in Thrust
The library version replaces hand-written kernels with thrust::transform
shaped calls (Chapter 11). Stencil kernels need neighbouring pixels, which
transform can obtain through index-based functors:
#include <thrust/iterator/zip_iterator.h>
#include <thrust/iterator/counting_iterator.h>
// Greyscale: pure elementwise -> a plain transform functor.
struct ToGray {
__device__ float operator()(const uchar3& px) const {
return 0.299f * px.x + 0.587f * px.y + 0.114f * px.z;
}
};
// Blur with halo: the functor receives the pixel INDEX and the row pointer;
// it reads its own 5-tap window.
struct BlurH5 {
const float* in; int width;
__device__ float operator()(int i) const {
const int x = i % width, y = i / width;
const float* row = in + y * width;
float acc = 0.0f;
const float w[5] = {0.06136f, 0.24477f, 0.38774f, 0.24477f, 0.06136f};
for (int t = -2; t <= 2; ++t) {
const int sx = min(max(x + t, 0), width - 1);
acc += w[t + 2] * row[sx];
}
return acc;
}
};
// Host side: chain the stages over device vectors.
thrust::device_vector<uchar3> d_rgb(...);
thrust::device_vector<float> d_gray(n), d_blur(n), d_edges(n);
thrust::transform(d_rgb.begin(), d_rgb.end(), d_gray.begin(), ToGray());
thrust::transform(thrust::counting_iterator<int>(0),
thrust::counting_iterator<int>(n),
d_blur.begin(),
BlurH5{thrust::raw_pointer_cast(d_gray.data()), width});
// ... blurV and sobel follow the same pattern; histogram is a thrust::reduce
// over a per-bin functor, or thrust::sort + adjacent-difference.
Thrust removes launch plumbing and boundary guards. The index-based stencil functor reintroduces the stencil logic that the custom kernel had. For elementwise stages such as greyscale and magnitude, Thrust is a clear win. For stencil stages, the custom kernel of §15.3 is comparable in code size and easier to tune. This is the Chapter 11 decision procedure in practice.
15.7 The Same Pipeline in CUDA-Oxide
With CUDA-Oxide (Chapter 14), the greyscale stage becomes a Rust #[kernel]
function with DisjointSlice on the output:
#![allow(unused)]
fn main() {
use cuda_device::{kernel, thread, DisjointSlice};
use cuda_host::cuda_module;
#[cuda_module]
mod kernels {
use super::*;
// Greyscale in pure Rust. DisjointSlice<f32> guarantees exclusive
// output slots; the input is read-only.
#[kernel]
pub fn rgb_to_gray(rgb: &[u8], gray: DisjointSlice<f32>, num_pixels: u32) {
let idx = thread::index_1d();
let i = idx.get();
if (i < num_pixels) {
// RGB is packed 3 bytes/pixel; u8 -> f32 conversion is explicit.
let base = (i as usize) * 3;
let r = rgb[base] as f32;
let g = rgb[base + 1] as f32;
let b = rgb[base + 2] as f32;
if let Some(out) = gray.get_mut(idx) {
*out = 0.299 * r + 0.587 * g + 0.114 * b;
}
}
}
}
}The kernel is written in the host’s language, indexed by the fused
thread::index_1d() (Chapter 14), and protected by DisjointSlice, so the
output has no alias and no manual boundary contract. The stencil kernels follow
the same shape with per-tap clamping as in the C++ versions. As Chapter 14
noted, the API is alpha; the shape is the point.
15.8 Verification: The Differential Test
A pipeline that produces wrong edges quickly is not useful. The verification strategy is the differential test:
- CPU reference. A plain-loop implementation of the same stages is the correctness oracle.
- GPU pipeline. The same stages run on a test image.
- Stage-by-stage comparison. Greyscale, blurred, and edge maps must agree
within a tolerance. Float stages use
1e-3; theucharedge map allows ±1 because the SFUsqrtfcan round differently at a.5boundary. - Property checks. Histogram bins must fall in expected ranges, and an all-black image must produce all-zero edges (a known-answer test).
The differential test converts “the pipeline works” into a repeatable assertion. The second implementation (Thrust) and third (CUDA-Oxide) must pass the same test as the first.
15.9 Measurement: The Report Card
Performance is measured with CUDA events (Chapter 6, §6.4) over many frames, with warm-up excluded:
// Per-stage timing with events:
cudaEventRecord(start, sCompute);
rgbToGray<<<...>>>(...);
cudaEventRecord(mid, sCompute);
blurH<<<...>>>(); blurV<<<...>>>(); sobel<<<...>>>(); scaleEdges<<<...>>>();
cudaEventRecord(stop, sCompute);
cudaEventSynchronize(stop);
float msStage1 = 0, msRest = 0;
cudaEventElapsedTime(&msStage1, start, mid);
cudaEventElapsedTime(&msRest, mid, stop);
The report card below gives teaching numbers for a 1920x1080 frame on a modern GPU. Measure on the target hardware; the ratios between stages are what the roofline predicts:
| Stage | Time | Bandwidth (3.35 TB/s peak) | Roofline verdict |
|---|---|---|---|
| rgbToGray | ~6 µs | ~75% of peak | Memory-bound (as predicted) |
| blurH + blurV | ~14 µs | ~70% of peak | Memory-bound, halo cost visible |
| sobel | ~7 µs | ~70% of peak | Memory-bound |
| histogram | ~10 µs | - | Atomic overhead, privatised |
| Total compute | ~40 µs | - | ~25,000 FPS compute-only; transfer-limited overall |
A 1920x1080 RGB frame is 6.2 MB to upload, and the uchar edge map is 2.1 MB
to download, about 8.3 MB of host-device traffic per frame. At a pinned PCIe
Gen4 rate of about 20 GB/s, that is roughly 400 µs of transfer per frame, about
ten times the total compute time. The pipeline is transfer-limited: the kernels
are not the bottleneck at this image size. This is the case for the streaming
machinery of Chapters 4 and 6.
The roofline predicted the memory-bound verdicts before any code ran: each stage moves a few bytes per pixel and performs few FLOPs. The measurement confirms the prediction. The engineering loop is: predict with the model, confirm with the instrument, and optimise only the confirmed bottleneck.
15.10 The Capstone in One Paragraph
The pipeline compresses the book into one system: coalesced kernels with explicit index arithmetic (Chapters 3 and 7), synchronisation-free stages and a privatised histogram (Chapters 5 and 8), pinned memory and streamed double buffering (Chapters 4 and 6), library and language alternatives that must pass the same differential test (Chapters 11, 13, and 14), and a measurement discipline that turns opinions into numbers (Chapter 16). Building this pipeline and explaining every line is the practical version of the book’s goal: the same reasoning transfers to new kernels.
The Pipeline as a Testbed
The capstone is more than a program. It is a small, complete system in which every idea from the earlier chapters has a concrete responsibility and a way to be tested.
The roofline model predicts, before code runs, that each stage is memory-bound because each stage moves a few bytes per pixel and does little arithmetic. The report card tests that prediction with CUDA events. The streaming host loop tests whether pinned memory plus two streams plus events hides transfer time behind kernel time. The differential test tests the strongest claim: all three implementations produce the same result as the CPU reference.
The capstone is a testbed because one piece can be changed and the whole suite re-run. Replace the separable blur with a fused 5x5 kernel, and the differential test checks correctness while event timings test whether the roofline prediction still holds. Change the histogram launch to the wrong block shape, and the histogram total exposes the bug. Every stage is a hypothesis; the pipeline is the experiment.
Common Pitfalls
- Reusing a 2-D stencil block for a 1-D kernel. The histogram must be launched
with a 1-D 256-thread block. Launching it with the 2-D
(32, 8)stencil block only zeroes part of the private bins and over-counts. - Clamping only the outer stencil taps at image borders. Every tap must be clamped independently, or the edge weights are wrong.
- Using pageable host memory in the streaming loop. Async copies silently become synchronous and the overlap disappears.
- Trusting a pipeline without a differential test. A fast wrong image is not a result.
Check Your Understanding
Why must every stencil tap be clamped independently at borders?
If only the outer taps are clamped, inner taps reuse the clamped values and the border pixel is double-weighted, for example as 0.06136 + 0.24477. Independent clamping replicates the edge pixel for each tap and preserves the correct weights.
Why is the histogram a meaningful sanity check for the pipeline?
The edge map is scaled to uchar, so its histogram counts edge intensities. If the histogram total does not equal frames times pixels, data was dropped or double-counted somewhere in the chain.
Why can the differential test tolerate 1e-3 for floats but only ±1 for uchar?
Float stages use different summation orders, such as FMA contraction, and the
device sqrtf approximates the last bits, so exact equality is unrealistic.
The uchar edge map is quantised; a rounding difference at a .5 boundary can
flip one byte, so ±1 is allowed. Anything larger is a real error.
Key Takeaways
- A pipeline is a chain of kernels; a fast pipeline is one that never waits (streams + pinned memory + events).
- A separable Gaussian uses 2 x 5 taps instead of 25; each stencil tap must be clamped independently at borders.
- The differential test against a CPU reference is what makes a second and third implementation trustworthy.
- The roofline predicted every capstone stage was memory-bound before code ran.
- Use median-of-many-runs timings, a fixed environment, and CUDA events for device time.
15.11 Exercises
- Why is the separable blur “10 taps instead of 25”? Derive the count for a 5-tap separable Gaussian versus a full 5x5 stencil, and for a 9-tap version.
- The first
blurHin §15.3 was plausible and wrong. Explain what was wrong and state the property the corrected kernel guarantees at the borders. - In the streaming loop, why must
h_rgbbe pinned memory? Trace what happens if it is pageable. - The differential test uses a tolerance of
1e-3for float stages and ±1 for the uchar edge map. Why not exact equality? Consider Chapter 5, §5.6, and the SFUsqrtfin the Sobel kernel. - Using the roofline model, predict whether making the blur a single fused 5x5 kernel (25 taps, no intermediate) would be faster or slower than the two-pass version, and explain the trade.
Chapter 15b: Benchmarking CUDA-Oxide on Jetson Orin
Code companion: the complete, buildable code for this chapter lives in
arpanpathak/cuda-oxide-demo. The article version isCUDA_RUST_JETSON_BENCHMARKS.md.
Chapter 14 showed how CUDA-Oxide compiles idiomatic Rust kernels to PTX. This chapter measures those kernels on real hardware and asks when the GPU is worth using on an embedded SoC.
Four kernels are benchmarked on a Jetson Orin:
- SAXPY - a memory-bound vector operation.
- Dot product - a block reduction.
- Matrix multiply - naive versus shared-memory tiled.
- Jacobi solver for the 2D Laplace equation - a stencil that solves a partial differential equation.
Every GPU result is verified against a CPU reference. The CPU baseline uses Rayon so that all eight ARM cores participate.
15b.1 Hardware Context
The Jetson Orin is not a datacenter GPU. It is an embedded SoC in which the CPU and GPU share:
- the same DRAM bandwidth,
- the same power budget,
- the same thermal envelope.
This changes the performance story. On a discrete GPU, many kernels beat the CPU. On an SoC, the CPU is competitive for memory-bound work because both processors are limited by the same memory system.
The chart shows:
- SAXPY: 1.8x GPU speedup.
- Dot product: roughly parity (0.7x to 1.8x across runs).
- Tiled matmul: 7.0x GPU speedup.
- Jacobi global stencil: 1.6x GPU speedup.
Compute-bound work with data reuse is where the GPU dominates. Memory-bound work is closer to a tie.
15b.2 The Kernels in the Demo
The repository is modular. Each benchmark binary is split into small single-purpose modules:
src/bin/06_benchmark/
├── main.rs # entry point
├── kernels.rs # #[kernel] device functions
├── cpu.rs # Rayon CPU references
├── data.rs # generators + correctness checks
├── measure.rs # wall-clock / CUDA-event timing
├── bench.rs # one small method per benchmark
└── report.rs # Markdown/CSV output
src/bin/07_laplace_jacobi/
├── main.rs # entry point + parameters
├── kernels.rs # global + shared-memory stencils
├── cpu.rs # Rayon CPU Jacobi reference
├── data.rs # correctness checks
├── measure.rs # CPU timing helper
├── bench.rs # orchestration + GPU event timing
└── report.rs # results printing + file output
SAXPY
#![allow(unused)]
fn main() {
#[kernel]
pub fn saxpy(alpha: f32, input_x: &[f32], input_y: &[f32], mut output: DisjointSlice<f32>) {
let index = thread::index_1d();
let position = index.get();
if let Some(slot) = output.get_mut(index) {
*slot = alpha * input_x[position] + input_y[position];
}
}
}Dot Product Block Reduction
#![allow(unused)]
fn main() {
static mut SHARED: SharedArray<f32, 256> = SharedArray::UNINIT;
// grid-stride accumulation into local_sum ...
unsafe { SHARED[thread_id] = local_sum; }
thread::sync_threads();
let mut offset = 128;
while offset > 0 {
if thread_id < offset {
unsafe { SHARED[thread_id] += SHARED[thread_id + offset]; }
}
thread::sync_threads();
offset /= 2;
}
}Tiled Matrix Multiply
Each 16x16 block loads a tile of A and a tile of B into shared memory, synchronises, computes the output tile from shared memory, synchronises again, and advances to the next K-tile. This change turns the naive GPU kernel into a roughly 6x faster kernel.
Jacobi Solver
The Laplace equation is the steady-state diffusion equation. On a grid, the discrete form becomes:
u_new[i,j] = (u[i-1,j] + u[i+1,j] + u[i,j-1] + u[i,j+1]) / 4
Each iteration replaces every interior cell with the average of its four neighbours. The top boundary is fixed at 100, the other edges at 0, and the iteration spreads the boundary information inward.
15b.3 Where the Laplace Equation Appears
The Laplace equation \(\nabla^2 u = 0\) describes equilibrium in physics:
- Heat conduction: steady-state temperature in a solid.
- Electrostatics: electric potential in a charge-free region.
- Fluid dynamics: pressure in potential flow.
- Image processing: inpainting, smoothing, and edge detection.
- Graphics: surface fairing and smooth height fields.
The Poisson variant \(\nabla^2 u = f\) adds sources. Jacobi iteration is the simplest solver and is the foundation for the multigrid and Krylov methods used in production solvers.
15b.4 Benchmark Methodology
- CPU: Rayon-parallel Rust,
std::time::Instant, best of 5. - GPU: CUDA events, best of 5, kernel time only.
- Warm-up: 5 GPU launches before timing so that the Jetson’s clocks ramp up.
- Data: deterministic pseudo-random
f32vectors and matrices. - Verification: every GPU result is compared against the CPU reference with a tolerance.
15b.5 Results
Vector Kernels
| Benchmark | CPU ms | CPU rate | GPU ms | GPU rate | Speedup |
|---|---|---|---|---|---|
| SAXPY, N = 16,777,216 | 4.989 | 40.4 GB/s | 2.700 | 74.6 GB/s | 1.8x |
| Dot product, N = 33,554,432 | 6.926 | 38.8 GB/s | 4.891 | 54.9 GB/s | 1.4x |
Matrix Multiply
| Implementation | Time | Rate | Speedup vs CPU Rayon |
|---|---|---|---|
| CPU, 1 thread | 214.480 ms | 10.0 GFLOPS | 0.35x |
| CPU, Rayon (8 cores) | 73.531 ms | 29.2 GFLOPS | 1.0x |
| GPU, naive | 66.490 ms | 32.3 GFLOPS | 1.1x |
| GPU, tiled 16x16 | 10.575 ms | 203.1 GFLOPS | 7.0x |
Jacobi Solver
| Implementation | ms/iteration | 500 iterations | Speedup |
|---|---|---|---|
| CPU, Rayon | 0.2283 | 114.1 ms | 1.0x |
| GPU, global-memory stencil | 0.1460 | 73.0 ms | 1.6x |
| GPU, shared-memory tiled stencil | 0.2258 | 112.9 ms | 1.0x |
Both GPU Jacobi variants match the CPU field exactly after 500 iterations.
15b.6 Lessons
- Memory-bound kernels are close on SoCs. When the CPU can already saturate the shared memory bandwidth, the GPU adds little.
- Shared-memory tiling is the GPU’s main advantage here. Matmul jumps from 32 to 203 GFLOPS, a 6.3x improvement over the naive GPU kernel and 7x over the CPU.
- Shared memory is not always the answer. The tiled Jacobi stencil is slower than the simple global stencil on the Orin because the unified L2 cache absorbs the halo reads. Measure on the target hardware.
- Warm-up matters on embedded GPUs. Without warm-up launches, the first measured kernel can be 2x slower because of clock ramping.
15b.7 Reproduce
git clone https://github.com/arpanpathak/cuda-oxide-demo.git
cd cuda-oxide-demo
cargo oxide run --bin 06_benchmark
cargo oxide run --bin 07_laplace_jacobi
Release builds:
cargo oxide build -- --release --bin 06_benchmark --bin 07_laplace_jacobi
./target/release/06_benchmark
./target/release/07_laplace_jacobi
Reports are written to benchmarks/benchmark_results.{md,csv} and
benchmarks/jacobi_results.{md,csv}.
Sources and Further Reading
- NVIDIA, Jetson Orin Developer Guide: https://developer.nvidia.com/embedded/learn/jetson-orin
- CUDA-Oxide demo repository used in this chapter: https://github.com/arpanpathak/cuda-oxide-demo
Epilogue - The Road Ahead
You have worked from the mathematics of parallelism to a streamed, profiled, and verified image pipeline implemented three ways. This epilogue briefly describes where the field is heading.
Hardware
Each GPU generation moves the ridge point of Chapter 1: more FLOPs, more bandwidth, and increasingly specialized arithmetic. Tensor cores, introduced with Volta and central to AI workloads since, execute dense matrix multiplication in hardware instead of looping over CUDA cores. Hopper added the Tensor Memory Accelerator (TMA) for bulk asynchronous copies and thread-block clusters. Blackwell continues the trend. The memory hierarchy, the warp, and the SM from Chapter 2 still define the machine; the arithmetic units are becoming more specialized.
The skills in this book are foundational. Tensor-core programming is still thread-block programming with a different instruction set. TMA is still coalescing expressed in bulk. When the next specialized unit appears, it will fit the same model.
Software
Three currents are visible:
- The SIMT model is cross-vendor. NVIDIA’s ecosystem (CUDA, cuBLAS, Nsight) remains the reference, but SYCL (Khronos’s single-source C++ model), HIP (AMD’s CUDA-compatible API), and wgpu/WebGPU (browser and native Rust) expose the same underlying execution model. Grids, warps, coalescing, and shared memory translate directly to these APIs.
- Rust is becoming viable for GPU work.
cudarcprovides a production-grade Rust host (Chapter 13). CUDA-Oxide (Chapter 14) is an early attempt to bring Rust’s guarantees to the kernel itself. Both are young. They point in the same direction: many GPU failure modes originate in the host language, and languages that remove those failure modes are likely to become more common for GPU hosts. - Libraries continue to absorb implementation work. Every year more of the hard work moves into tuned libraries (Chapter 11). The engineers who use those libraries effectively are not the ones who memorized the APIs; they are the ones who can read a profiler, explain why a kernel is memory-bound, and decide when a custom kernel is worth writing.
The Discipline
The most durable idea in this book is the loop of Chapter 25: measure, profile, hypothesize, change one thing, re-measure, and verify. Hardware changes, languages change, and libraries change. The loop does not.
The Invitation
This book is published on GitHub Pages and is open to pull requests. If a kernel is unclear, a claim is unmeasured, or a chapter misses a concept that confused you, open an issue.
Write kernels that are fast, correct, and understood.
- Arpan Pathak
Appendix A - CUDA API Reference
This appendix is the book’s vocabulary list: every type, built-in variable, function and flag used in the main text, with its meaning and where it is discussed. It is intended as a lookup table, not as a tutorial - the tutorials are the chapters.
A.1 Execution Configuration
| Syntax | Meaning | Chapter |
|---|---|---|
kernel<<<gridDim, blockDim>>>(args...) | Launch kernel with a grid of gridDim blocks of blockDim threads each | 3 |
kernel<<<gridDim, blockDim, sharedBytes, stream>>> | As above, with dynamic shared memory (bytes) and an explicit stream | 6, 7 |
dim3 | Three-unsigned vector type; fields .x, .y, .z | 3 |
threadIdx | The thread’s position within its block (a dim3) | 3 |
blockIdx | The block’s position within the grid (a dim3) | 3 |
blockDim | Threads per block, as launched (a dim3) | 3 |
gridDim | Blocks per grid, as launched (a dim3) | 3 |
__launch_bounds__(maxThreads, minBlocks) | Compiler directive: register budget for occupancy | 9 |
The universal 1-D global index: blockIdx.x * blockDim.x + threadIdx.x.
The 2-D composition is in Chapter 3, §3.5.
A.2 Function Qualifiers
| Qualifier | Runs on | Called from | Chapter |
|---|---|---|---|
__global__ | Device | Host | 3 |
__device__ | Device | Device only | 3 |
__host__ (default) | Host | Host | 3 |
__host__ __device__ | Both | Both | 10 |
extern "C" __global__ keeps the kernel symbol unmangled for driver-API /
NVRTC lookup (Chapters 12, 13).
A.3 Vector Types
| Type | Bytes | Alignment | Notes |
|---|---|---|---|
uchar3 | 3 | 1 | RGB pixels; no padding (Chapter 15) |
float2, float4 | 8, 16 | 4, 16 | Vectorized loads (Chapter 7, §7.6) |
int2, int4, double2, uint4 | 8/16/16/16 | as size | Same vectorization rules |
size_t | platform | - | Byte sizes; use instead of int (Chapter 3) |
Vectorized accesses require alignment to the vector size.
A.4 Memory Management
| Function | Behavior | Chapter |
|---|---|---|
cudaMalloc(void** p, size_t n) | Allocate n bytes in device global memory | 3 |
cudaFree(void* p) | Free a device allocation | 3 |
cudaMemcpy(dst, src, n, kind) | Synchronous copy; kind = HostToDevice, DeviceToHost, DeviceToDevice, HostToHost | 3 |
cudaMemcpyAsync(dst, src, n, kind, stream) | Asynchronous copy, queued on stream; requires pinned host memory | 4, 6 |
cudaMallocHost(void** p, size_t n) | Allocate pinned (page-locked) host memory | 4 |
cudaHostAlloc(void** p, size_t n, flags) | Pinned host memory; cudaHostAllocMapped adds zero-copy mapping | 4 |
cudaHostGetDevicePointer(void** dp, void* hp, 0) | Device pointer for zero-copy mapped host memory | 4 |
cudaFreeHost(void* p) | Free pinned host memory | 4 |
cudaMallocManaged(void** p, size_t n) | Unified memory (host + device address space) | 4 |
cudaMemPrefetchAsync(p, n, device, stream) | Migrate unified-memory pages now | 4 |
cudaMemcpyToSymbol(sym, src, n) | Copy into __constant__ memory | 7 |
Memory kinds and when to use each: Chapter 4, §4.7.
A.5 Synchronization and Memory Ordering
| Primitive | Meaning | Chapter |
|---|---|---|
__syncthreads() | Block-wide barrier; must be uniformly reachable | 5 |
__threadfence() | Order my device-scope global accesses | 5 |
__threadfence_block() | Order my block-scope accesses | 5 |
__threadfence_system() | Order host+device accesses | 5 |
volatile | Disable register caching of a location | 5 |
atomicAdd/Sub/Exch/CAS/Min/Max/And/Or/Xor | Hardware read-modify-write; return old value | 5 |
cuda::atomic<T, scope> | C++20-style atomic with memory orders (CUDA 12) | 10 |
The atomics table with semantics: Chapter 5, §5.5.
A.6 Streams and Events
| Function | Behavior | Chapter |
|---|---|---|
cudaStreamCreate(&s) | Create a stream | 6 |
cudaStreamDestroy(s) | Destroy a stream | 6 |
cudaStreamCreateWithFlags(&s, flag) | cudaStreamNonBlocking disables default-stream sync | 6 |
cudaStreamCreateWithPriority(&s, flag, prio) | Priority stream; range from cudaDeviceGetStreamPriorityRange | 6 |
cudaStreamSynchronize(s) | Wait for all work in s | 6 |
cudaEventCreate(&e) / cudaEventDestroy(e) | Create/destroy an event | 6 |
cudaEventRecord(e, s) | Mark the stream position | 6 |
cudaEventSynchronize(e) | Wait until the device reaches e | 6 |
cudaEventElapsedTime(&ms, e0, e1) | Time between two events | 6, 16 |
cudaStreamWaitEvent(s, e) | Make s wait for e (cross-stream dependency) | 6 |
cudaGraphCreate/Instantiate/Launch/Destroy | Capture and replay device work | 6 |
cudaDeviceSynchronize() | Wait for all device work | 3, 6 |
The synchronization cheat sheet: Chapter 6, §6.8.
A.7 Error Handling
| Primitive | Behavior | Chapter |
|---|---|---|
cudaError_t | Enum; cudaSuccess == 0, everything else is an error | 3 |
cudaGetLastError() | Return and clear the last asynchronous error | 3 |
cudaGetErrorString(e) | Human-readable error text | 3 |
cudaDeviceSynchronize() | Also surfaces async kernel errors | 3, 6 |
cublasStatus_t, nvrtcResult, CUresult | Library error types (cuBLAS, NVRTC, driver API) | 11, 12 |
Two error modes (synchronous vs asynchronous) and the CHECK discipline:
Chapter 3, §3.8.
A.8 Device Math Library (selected)
fminf, fmaxf, sqrtf, fabsf, sinf, cosf, expf, logf,
powf, fmaf (fused multiply-add). The __host__ __device__ versions work
on both sides (Chapter 10, §10.4). Fast approximations live in the __
prefixed forms (__expf, __sinf); enable globally with
--use_fast_math - but measure before trusting (Chapter 25, §25.7).
A.9 Warp-Level Primitives
| Primitive | Meaning | Chapter |
|---|---|---|
__shfl_down_sync(mask, val, delta) | Move val from lane lane+delta to lane | 8 |
__shfl_sync, __shfl_up_sync, __shfl_xor_sync | Other shuffle directions | 8 |
0xffffffffu | The 32-lane mask for _sync primitives | 8 |
__activemask() | Mask of currently active lanes (use with care) | 8 |
All _sync primitives require all named lanes to execute them.
A.10 Driver API and NVRTC (Chapter 12)
| Primitive | Meaning |
|---|---|
cuInit, cuDeviceGet, cuCtxCreate, cuCtxDestroy | Context lifecycle |
cuModuleLoadData, cuModuleGetFunction, cuModuleUnload | Load PTX/cubin, fetch kernel by name |
cuLaunchKernel(f, gx,gy,gz, bx,by,bz, smem, stream, args, extra) | Raw launch with void* argument array |
nvrtcCreateProgram, nvrtcCompileProgram, nvrtcGetPTX, nvrtcGetProgramLog | Runtime compilation of CUDA source |
| PTX / cubin / fatbin | Portable ISA / SASS binary / multi-arch container |
A.11 Tools and Environment (Chapter 25)
| Tool | Purpose |
|---|---|
nvcc | Offline compiler (-arch=compute_60 portable PTX, or -arch=sm_87 on Jetson Orin, -ptx) |
nsys profile | System-level timeline |
ncu --set full | Kernel-level counters |
compute-sanitizer --tool memcheck/racecheck/initcheck/synccheck | Runtime error detection |
cuda-gdb | Interactive device debugger |
clock64() | In-kernel cycle counter |
CUDA_CACHE_MAXSIZE | JIT cache size (Chapter 12) |
Appendix B - Mathematical Notation Reference
This appendix gathers the mathematics that appears throughout the text. It is not a mathematics course; it is a dictionary. Every symbol below appears at least once in the main chapters.
B.1 Sets and Scalars
| Symbol | Meaning | First use |
|---|---|---|
| \(\mathbb{R}\) | The real numbers; \(\mathbb{R}^n\) is \(n\)-dimensional real space | Ch. 1 |
| \(n, N, k, i, j\) | Indices and sizes (integers) | Ch. 1-15 |
| \(p\) | The number of processing units (threads, cores) | Ch. 1 |
| \(f\) | The serial fraction of a workload (Amdahl) | Ch. 1 |
| \(s\) | The serial fraction of parallel time (Gustafson) | Ch. 1 |
B.2 Performance Quantities
| Symbol | Meaning | Definition | First use |
|---|---|---|---|
| \(T_1\) | Serial execution time | - | Ch. 1 |
| \(T_p\) | Execution time on \(p\) units | - | Ch. 1 |
| \(S(p)\) | Speedup | \(T_1 / T_p\) | Ch. 1 |
| \(E(p)\) | Efficiency | \(S(p) / p\) | Ch. 1 |
| \(P_{\text{peak}}\) | Peak FLOP rate (FLOP/s) | - | Ch. 1 |
| \(B\) | Peak memory bandwidth (bytes/s) | - | Ch. 1 |
| \(I\) | Arithmetic intensity | FLOPs ÷ bytes | Ch. 1 |
| \(I_{\text{ridge}}\) | Ridge point | \(P_{\text{peak}} / B\) | Ch. 1 |
The roofline inequality: \(P \le \min(P_{\text{peak}},\; I \cdot B)\), with the two regimes compute-bound (\(I > I_{\text{ridge}}\)) and memory-bound (\(I < I_{\text{ridge}}\)). Chapter 1, §1.8.
B.3 Sums and Sequences
| Symbol | Meaning | First use |
|---|---|---|
| \(\sum_{i=0}^{n-1} a_i\) | The sum of the sequence \(a_0, \ldots, a_{n-1}\) | Ch. 8 |
| \(a_i\) | The \(i\)-th element of a sequence | Ch. 8 |
| \(\log_2 n\) | The base-2 logarithm of \(n\) (the tree height) | Ch. 8 |
| \(\lfloor x \rfloor\) | The floor of \(x\) (largest integer ≤ \(x\)) | Ch. 2 |
Tree reduction performs \(n/2\) additions per level over \(\log_2 n\) levels; the bank index is \(\lfloor \text{addr}/4 \rfloor \bmod 32\). Chapter 2, §2.8; Chapter 8.
B.4 Matrices and Vectors
| Symbol | Meaning | First use |
|---|---|---|
| \(A, B, C\) | Matrices (bold or capital letters) | Ch. 9 |
| \(A[i][j]\) or \(a_{ij}\) | The element at row \(i\), column \(j\) | Ch. 9 |
| \(N\) | Matrix dimension (\(N \times N\)) | Ch. 9 |
| \(C = A \times B\) | Matrix product: \(c_{ij} = \sum_k a_{ik} b_{kj}\) | Ch. 9 |
| \(G_x, G_y\) | Sobel derivative kernels | Ch. 15 |
The FLOP count of \(N \times N\) multiplication: \(2N^3\). The arithmetic intensity: \(N/6\) FLOP/byte. Chapter 9, §9.1.
B.5 Statistics and Error
| Symbol | Meaning | First use |
|---|---|---|
| \(\sigma\) | Standard deviation (Gaussian blur radius) | Ch. 15 |
| \(\max \lvert x - y \rvert\) | Maximum absolute difference (verification) | Ch. 3 |
| \(1 \times 10^{-3}\) | The float-stage verification tolerance | Ch. 15 |
The Gaussian weights of the 5-tap blur, \(\sigma = 1\): \([0.06136, 0.24477, 0.38774, 0.24477, 0.06136]\). Chapter 15, §15.3.
B.6 Greek Letters Used
| Letter | Role in this book |
|---|---|
| \(\alpha\) | SAXPY scaling factor (\(y = \alpha x + y\)) |
| \(\beta\) | cuBLAS GEMM scaling factor (\(C = \alpha AB + \beta C\)) |
| \(\sigma\) | Gaussian standard deviation |
| \(\Sigma\) | Summation operator |
B.7 Conventions
- Row-major storage is assumed everywhere unless stated otherwise: element \((i, j)\) of a \(W\)-wide matrix lives at linear index \(i \cdot W + j\). Consecutive threads map to consecutive \(j\) - the coalescing convention of Chapter 7.
- Zero-based indexing, matching the hardware (
threadIdx.xstarts at 0). - FLOPs counts a fused multiply-add as two operations (the convention behind Chapter 2’s peak rates).
- Powers of two dominate block sizes and tile sizes; when a formula requires one, the text says so (Chapter 8, §8.3).
Appendix C - Recommended Reading & Tools
C.1 Books
- Programming Massively Parallel Processors: A Hands-on Approach - David B. Kirk and Wen-mei W. Hwu. The standard academic text on GPU programming; the source of many of the patterns this book presents from first principles (reduction, tiling, coalescing).
- CUDA C++ Best Practices Guide - NVIDIA. The official optimization handbook; the §7.9 checklist in this book is a compressed version of its structure.
- Parallel Programming with C++ - Richard Vuduc et al. (course notes). The mathematics of Chapter 1 in more depth (Amdahl, Gustafson, roofline).
- The Rust Book - Steve Klabnik and Carol Nichols. The language reference for Part V, free online.
- Performance Analysis of the CUDA Programming Model - for the warp-level and SIMT details behind Chapter 2.
C.2 Official Documentation (Primary Sources)
- CUDA C++ Programming Guide - the authoritative language reference.
- PTX ISA Reference - the virtual ISA of Chapters 3 and 12, in detail.
- CUDA Toolkit Documentation - API references for the runtime, driver, cuBLAS, Thrust, CUB, cuFFT, cuRAND, NVRTC.
- Nsight Compute / Nsight Systems User Guides - the profilers of Chapter 16.
- Compute Sanitizer User Guide - the debugger of Chapter 25.
- CUDA-Oxide (NVlabs/cuda-oxide) - the README and examples are the primary source for Chapter 14; the project moves quickly, so read the repository, not just this book.
- NCCL Documentation - the official
nccluser guide and API reference for Chapter 28 (collectives, algorithms, environment variables). - NVLink & NVSwitch - NVIDIA’s interconnect architecture papers and DGX system guides for Chapter 27.
- Linux kernel PCI/IOMMU documentation -
Documentation/PCI/andDocumentation/IOMMU.txtfor the systems layer of Chapter 26.
C.3 Tools
| Tool | Purpose | Chapter |
|---|---|---|
nvcc | CUDA compiler driver | 3 |
nsys | System-level profiling | 16 |
ncu | Kernel-level profiling | 16 |
compute-sanitizer | Memory/race/init/sync checking | 16 |
cuda-gdb | Device debugging | 16 |
cuobjdump, nvdisasm | Inspect cubins, SASS | 12 |
deviceQuery (CUDA sample) | Hardware capabilities | 2 |
cudaOccupancyMaxActiveBlocksPerMultiprocessor | Occupancy computation | 2, 16 |
cargo-oxide | CUDA-Oxide build driver | 14 |
cudarc (crates.io) | Rust host wrapper | 13 |
lspci | PCIe devices, BARs, drivers | 17 |
nvidia-smi topo -m | GPU-to-GPU topology (NVLink vs PCIe) | 18 |
nvidia-smi nvlink -s | NVLink link status | 18 |
nccl-tests | Collective bandwidth/latency benchmarks | 19 |
C.4 Online Resources
- NVIDIA Developer Blog - architecture deep dives (tensor cores, TMA, CUDA Graphs).
- NVIDIA GPU Computing Samples (
cuda-samplesrepository) - reference kernels for every pattern in this book. - NVIDIA’s official CUDA-Oxide repository and Discord - the community around the Rust compiler of Chapter 14.
- crates.io/cudarc - the Rust host library of Chapter 13, with examples.
C.5 Cloud GPU Services
If you do not own an NVIDIA GPU, the cloud gives you enough free compute to finish this book. The quickest starts: Google Colab (free T4 in a browser, zero setup) and Kaggle Notebooks (roughly 30 free GPU hours per week). For serious sessions, the big clouds offer new-account credits (Google Cloud roughly USD 300, Microsoft Azure roughly USD 200); for cheap on-demand GPUs, try Lambda, RunPod or Vast.ai; for serverless Python with recurring credits, Modal. NVIDIA LaunchPad offers free, time-boxed hands-on labs on real NVIDIA hardware.
The repository README keeps a fuller comparison table with links; credit amounts change frequently, so always check the provider’s current terms.
C.6 How to Continue
- Re-implement the capstone (Chapter 15) from memory, without looking. The gaps in your memory are the gaps in your understanding.
- Profile your own machine. Run
deviceQuery, compute your ridge point (Chapter 1), and take one kernel from this book to 90% of measured peak bandwidth using Chapter 7’s checklist. - Read the CUDA-Oxide repository and track its releases. The alpha project of Chapter 14 is the fastest-moving part of this book.
- Port the pipeline to a cross-vendor API (SYCL, HIP, or wgpu) and observe which ideas transfer unchanged. The answer - almost all of them - is the epilogue’s point made measurable.