Chapter 6: Streams, Events & Asynchronous Execution
A GPU contains more than one kind of execution unit. The streaming multiprocessors (SMs), described in Chapter 2, execute kernels. The copy engines, described in Chapter 4, transfer data between host memory and device memory without using the SMs. In the programs of the previous chapters, these units were used one at a time. The program copied its input to the device, launched a kernel, and copied the result back, and each operation started only after the previous one had finished. While a copy was in progress the SMs were idle, and while the kernel was running the copy engines were idle.
In this chapter, we study how a program can keep these units busy at the same time. The mechanism is asynchronous execution: a kernel launch or a copy is placed in a queue, called a stream, and the call returns before the work is done. When the data is divided into chunks and the chunks are distributed over 2 streams, a copy engine can transfer 1 chunk while the SMs process another and the second copy engine returns a third. We also use events to time work on the GPU’s own clock, and CUDA graphs to reduce the cost of launching many short kernels.
This chapter covers
- asynchronous launches and copies, and the work the host can do while the GPU runs
- streams: ordered queues of GPU work, and the overlap of work in different streams
- the default stream and the synchronization it adds between streams
- events, which time work on the GPU’s own clock
- a pipeline of chunks on 2 streams, 43% faster on a Jetson Orin NX
- why overlap gains less when the kernel dominates or the memory is shared
- CUDA graphs, which submit 1,000 launches with 1 call
The code of the chapter is in
code/ch06_streams/
for C++ and in
code/oxide/ch06_streams/
for Rust.
6.1 Serial execution of copies and kernels
The programs of this chapter process 128 MiB of floats in 3 stages. The first stage copies the input to the device, the second runs a kernel that performs some arithmetic on every element, and the third copies the result back to the host. Listing 6.1 shows the kernel. Its loop of 256 iterations has no purpose other than to make the kernel take about as long as its copies; with a much shorter kernel, overlapping the stages would make little difference.
Listing 6.1 The kernel of the chapter. code/oxide/ch06_streams/src/main.rs code/ch06_streams/streams.cu
mod kernels {
    // ...
    /// Some arithmetic per element, so that a kernel takes about as long as its copies.
    #[kernel]
    #[launch_contract(domain = 1, block = (256, 1, 1))]
    pub fn work(mut x: DisjointSlice<f32>, steps: u32) {
        if let Some(v) = x.get_mut(thread::index_1d()) {
            let mut a = *v;
            for _ in 0..steps {
                a = a * 0.999 + 0.5;
            }
            *v = a;
        }
    }
    // ...
}
// Some arithmetic per element, so that a kernel takes about as long as its copies.
__global__ void work(float* x, int n, int steps)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i >= n) return;
float v = x[i];
for (int k = 0; k < steps; ++k) {
v = fmaf(v, 0.999f, 0.5f);
}
x[i] = v;
}
When the 3 stages are timed separately on a Jetson Orin NX, they take the following times:
copy in, kernel, copy out over 128 MiB
copy in 4.29 ms
kernel 10.39 ms
copy out 4.30 ms
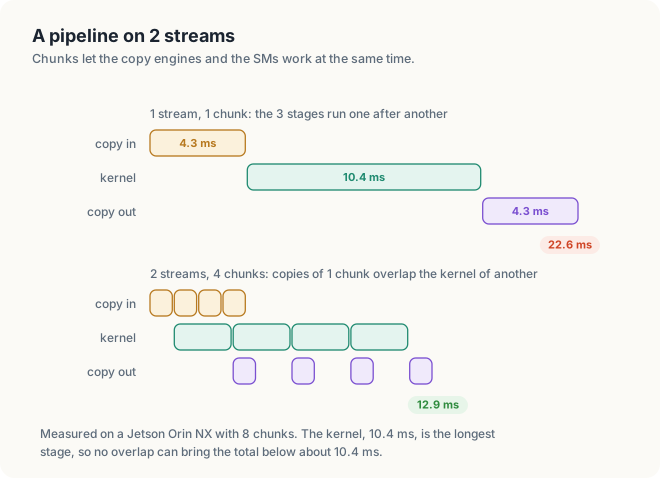
If the stages run one after another, the computation takes about 4.3 + 10.4 + 4.3 = 19 ms. Each unit of the GPU is busy for only part of that time: the copy engine that moves data to the device works for 4.3 ms of the 19 ms, and the SMs work for 10.4 ms. If the 3 stages could operate at the same time on different parts of the data, the total time would approach the time of the longest stage, 10.4 ms. For that, the program must be able to give the GPU new work without waiting for earlier work to finish. Asynchronous launches and streams, the subject of section 6.2, provide this ability.
6.2 Asynchronous launches and streams
6.2.1 Asynchronous kernel launches
A call is said to be synchronous if it returns only after its work is done, and asynchronous if it returns as soon as the work has been queued. Kernel launches have been asynchronous in every program since Chapter 3. The program of this chapter measures the effect directly, with a method that section 6.4 explains:
a launch of a kernel over 128 MiB
launch call returned after 0.075 ms
kernel finished after 12.451 ms
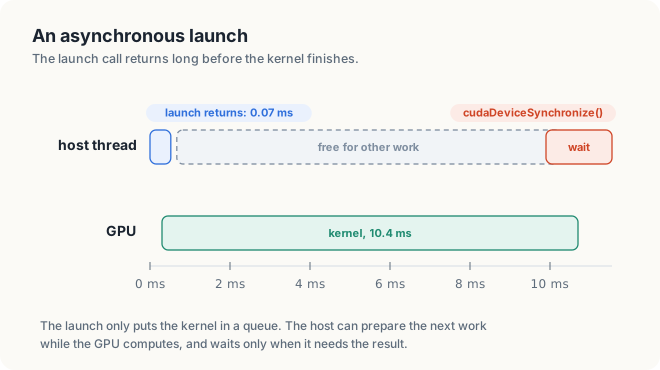
The launch call returned after 0.075 ms, whereas the kernel finished 12 ms later. Between these 2 moments the host thread was free, as figure 6.1 shows. It could prepare the next input or launch more work, and it needs to wait only when it requires a result from the GPU.
6.2.2 Streams
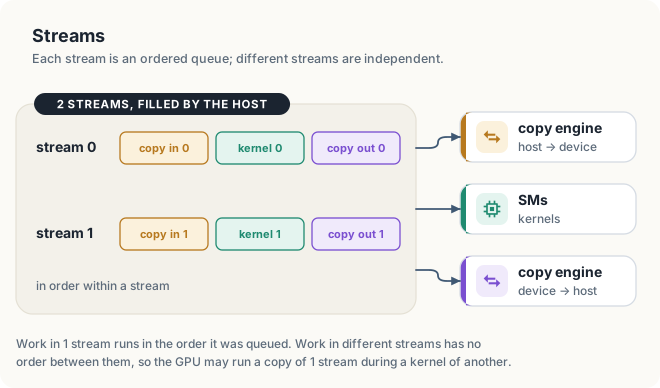
Work that has been queued must be held somewhere until the GPU executes it. A stream is an ordered queue of GPU operations, such as kernel launches and memory copies. The GPU executes the operations of a stream in the order in which they were queued, so operations in the same stream never overlap: a copy queued after a kernel starts only when the kernel has finished. Operations in different streams, on the other hand, have no ordering constraint between them, and the GPU may execute them at the same time (figure 6.2). Animation 1 shows a host thread placing work in a stream and the GPU executing it in order.
In C++, cudaStreamCreate(&s) creates a stream. A kernel is launched into a stream by passing
the stream as the 4th launch parameter between the angle brackets,
kernel<<<grid, block, 0, s>>>(...), and cudaMemcpyAsync(dst, src, bytes, kind, s) places a
copy in it. In Rust, ctx.new_stream()? creates a stream, and every launch and copy takes the
stream as its first argument. Note that an asynchronous copy requires pinned host memory, which
Chapter 4 introduced. The copy engine reads the host memory after the call has returned, so the
operating system must not move the pages of that memory while the copy is in progress.
6.3 The default stream and implicit synchronization
A launch or a copy that does not name a stream is placed in the default stream. In its
original form, which is still the default behavior in C++, the default stream synchronizes with
every other stream of the device. An operation in the default stream waits for all earlier work in
all streams, and work queued later in other streams waits for it. Therefore, a single launch or
cudaMemcpy without a stream can serialize a program that was designed to overlap its operations.
There are two ways to avoid this behavior:
- Name a stream in every launch and copy. The dependencies between operations are then visible in the code, at the place where the work is queued.
- Compile with
--default-stream per-thread. Each host thread then has its own default stream, which does not synchronize with the streams of other threads.
Streams created with cudaStreamCreateWithFlags(&s, cudaStreamNonBlocking) do not synchronize
with the default stream at all.
6.4 CUDA events
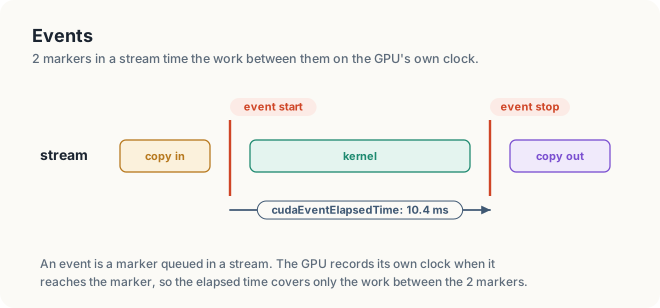
An event is a marker placed in a stream. When the GPU reaches the marker, it records the time on its own clock. By recording 1 event before a kernel and another after it, we can measure the execution time of the kernel on the GPU. The measurement excludes the time the host takes to launch the kernel and the time it takes to notice that the kernel has finished (figure 6.3).
Listing 6.2 An asynchronous launch, timed with events.
fn main() -> Result<(), Box<dyn std::error::Error>> {
// ...
// 1. A launch returns at once; events time the kernel on the GPU.
let stream = &streams[0];
let launch = module.prepare_work(LaunchConfig1D::new((N / 256) as u32, 256, 0))?;
let device = &mut whole[0].device;
let t0 = Instant::now();
let start = stream.record_event(Some(TIMING))?;
module.work(stream, &launch, device, STEPS)?;
let stop = stream.record_event(Some(TIMING))?;
let launched = t0.elapsed().as_secs_f64() * 1e3;
stop.synchronize()?;
let finished = t0.elapsed().as_secs_f64() * 1e3;
println!("a launch of a kernel over 128 MiB");
println!(" launch call returned after {launched:8.3} ms");
println!(" kernel finished after {finished:8.3} ms");
println!(" kernel time by events {:8.3} ms", start.elapsed_ms(&stop)?);
// ...
}// 1. A launch returns before the kernel finishes; events time the kernel on the GPU.
void asyncLaunch(float* d, int n, int steps)
{
cudaEvent_t start, stop;
check(cudaEventCreate(&start));
check(cudaEventCreate(&stop));
work<<<(n + 255) / 256, 256>>>(d, n, steps); // warm up
check(cudaDeviceSynchronize());
double t0 = nowMs();
check(cudaEventRecord(start));
work<<<(n + 255) / 256, 256>>>(d, n, steps);
check(cudaEventRecord(stop));
double launched = nowMs() - t0;
check(cudaEventSynchronize(stop));
double finished = nowMs() - t0;
float gpuMs;
check(cudaEventElapsedTime(&gpuMs, start, stop));
std::printf("a launch of a kernel over %d MiB\n", int(n * sizeof(float) >> 20));
std::printf(" launch call returned after %8.3f ms\n", launched);
std::printf(" kernel finished after %8.3f ms\n", finished);
std::printf(" kernel time by events %8.3f ms\n", gpuMs);
check(cudaEventDestroy(start));
check(cudaEventDestroy(stop));
}
The call cudaEventRecord(e) places the marker in the stream, cudaEventSynchronize(e) makes
the host wait until the GPU has passed it, and cudaEventElapsedTime(&ms, start, stop) returns
the time between 2 markers in milliseconds. The Rust version follows the same steps.
stream.record_event(Some(TIMING))? creates an event that can record time and places it in the
stream, stop.synchronize()? waits for it, and start.elapsed_ms(&stop)? returns the time
between the 2 events.
a launch of a kernel over 128 MiB
launch call returned after 0.075 ms
kernel finished after 12.451 ms
kernel time by events 11.151 ms
The host observed the kernel finish after 12.45 ms, whereas the events measured 11.15 ms. The difference of about 1.3 ms is time spent outside the kernel: the GPU starting the kernel and signaling its completion, and the host thread noticing that signal. For timing work on the GPU, events therefore give the more accurate measurement.
6.5 A double-buffered pipeline
6.5.1 Dividing the data into chunks
To allow the units of the GPU to overlap, we divide the data into chunks and give each chunk its own 3 stages. Chunk \(c\) is placed in stream \(c \bmod 2\), so consecutive chunks alternate between 2 streams. Within a stream, the stages of a chunk remain in order. Between the streams, however, the copy of 1 chunk can proceed while the kernel of the previous chunk runs (figure 6.4). Keeping 2 chunks in flight in this way is commonly called double buffering.
Listing 6.3 The pipeline.
/// 1 chunk of the data: its pinned host buffer and its device buffer.
struct Chunk {
host: PinnedHostBuffer<f32>,
device: DeviceBuffer<f32>,
}
/// Copy in, compute and copy out every chunk, chunk c on stream c % streams.len().
/// Returns the average of 5 runs, in milliseconds.
fn pipeline(
module: &kernels::LoadedModule,
streams: &[Arc<CudaStream>],
parts: &mut [Chunk],
) -> Result<f64, Box<dyn std::error::Error>> {
let len = parts[0].host.len();
let blocks = len.div_ceil(256) as u32;
let launch = module.prepare_work(LaunchConfig1D::new(blocks, 256, 0))?;
let start = Instant::now();
for _ in 0..5 {
for (c, part) in parts.iter_mut().enumerate() {
let stream = &streams[c % streams.len()];
// SAFETY: `part.host` is neither read, written nor dropped until every
// stream is synchronized below, after both copies have completed.
unsafe { part.device.copy_from_pinned_host_async(stream, &part.host)? };
module.work(stream, &launch, &mut part.device, STEPS)?;
unsafe { part.device.copy_to_pinned_host_async(stream, &mut part.host)? };
}
}
for stream in streams {
stream.synchronize()?;
}
Ok(start.elapsed().as_secs_f64() * 1e3 / 5.0)
}// 2. Copy in, compute, copy out: all at once on 1 stream, or in chunks on 2 streams.
void enqueue(float* host, float* d, int n, int steps, int chunks, cudaStream_t* streams)
{
int part = n / chunks;
size_t bytes = part * sizeof(float);
for (int c = 0; c < chunks; ++c) {
cudaStream_t s = streams[c % 2];
float* h = host + c * part;
float* g = d + c * part;
check(cudaMemcpyAsync(g, h, bytes, cudaMemcpyHostToDevice, s));
work<<<(part + 255) / 256, 256, 0, s>>>(g, part, steps);
check(cudaMemcpyAsync(h, g, bytes, cudaMemcpyDeviceToHost, s));
}
}
// Average time of 5 pipelines, in milliseconds.
double pipeline(float* host, float* d, int n, int steps, int chunks, cudaStream_t* streams)
{
check(cudaDeviceSynchronize());
double t0 = nowMs();
for (int r = 0; r < 5; ++r) {
enqueue(host, d, n, steps, chunks, streams);
}
check(cudaDeviceSynchronize());
return (nowMs() - t0) / 5;
}
The function enqueue only queues work. Each of the 3 calls in its loop returns immediately, so
the host queues every chunk of every stream before the first copy has finished. The function
pipeline runs the complete pipeline 5 times and divides the total time by 5. Animation 2 shows
the chunks passing through the 3 units of the GPU.
6.5.2 The pipeline in Rust
In the Rust version of Listing 6.3, each chunk owns its pinned host buffer and its device buffer. With this arrangement, the borrow checker can see which data each stream uses.
The asynchronous copies are unsafe for a reason that the borrow checker cannot see. A copy
continues after copy_from_pinned_host_async has returned, so the host buffer must remain alive
and unchanged until the GPU has finished with it. The borrow of part.host ends when the call
returns, but the GPU’s use of the buffer ends only at stream.synchronize(). The SAFETY comment
states why the program meets this requirement. No code touches the host buffers until every
stream has been synchronized.
6.5.3 Measured pipeline times
$ ./streams # on a Jetson Orin NX
copy in, kernel, copy out over 128 MiB
1 stream, 1 chunk 22.60 ms
2 streams, 8 chunks 12.93 ms
2 streams, 32 chunks 13.27 ms
$ ./streams # on a Jetson AGX Thor
copy in, kernel, copy out over 128 MiB
copy in 1.12 ms
kernel 3.05 ms
copy out 1.08 ms
1 stream, 1 chunk 5.21 ms
2 streams, 8 chunks 4.88 ms
2 streams, 32 chunks 4.51 ms
$ cargo oxide run # on a Jetson Orin NX
copy in, kernel, copy out over 128 MiB
1 stream, 1 chunk 20.07 ms
2 streams, 8 chunks 12.55 ms
On the Orin NX, 2 streams reduced the time from 22.6 ms to 12.9 ms, a reduction of 43% (figure 6.5). To judge how close this result is to the best possible, we can derive a simple bound. With \(k\) chunks, the longest stage runs from the start of the pipeline to its end. Each of the other stages contributes only the time it spends on 1 chunk: the copy of the first chunk before the first kernel can start, and the copy of the last chunk after the last kernel has finished. The total time is therefore approximately
\[ T_{\text{pipeline}} \approx T_{\text{longest}} + \frac{T_{\text{others}}}{k} \]
For 8 chunks, the bound is 10.4 + (4.3 + 4.3) / 8 ≈ 11.5 ms, which is close to the measured 12.9 ms. 32 chunks performed no better than 8. The bound for 8 chunks is already within 1 ms of the kernel’s time, and each additional chunk adds 3 more calls that the host must queue.
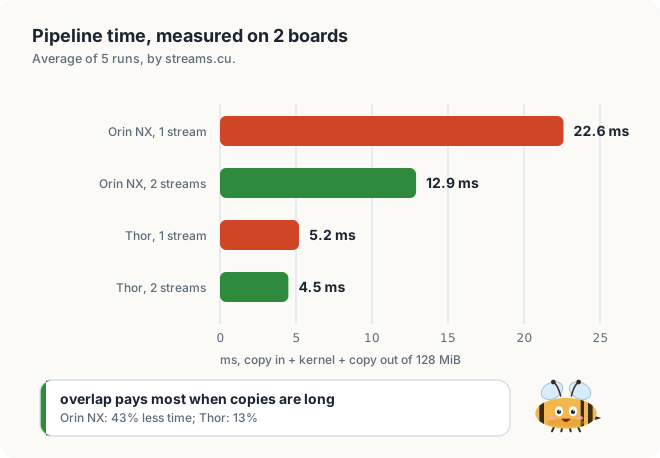
On the Thor, the gain was 13%, for two reasons. First, its kernel dominates: the kernel takes 3.05 ms, against 1.1 ms for each copy, so even perfect overlap could hide only the copies, about 2.2 ms of the 5.2 ms. Second, on an integrated GPU the copies and the kernel use the same memory, so a copy that runs during a kernel slows the kernel down. In Chapter 4, we saw a larger saving that is available on such a GPU: avoiding the copies altogether with zero-copy or unified memory.
Overlap hides the shorter stages behind the longest one; it cannot make the longest one shorter.
A pipeline has copy in 6 ms, kernel 4 ms and copy out 6 ms, on a GPU with 2 copy engines. What is the best time with 8 chunks?
The longest stage is a copy, which takes 6 ms. The bound gives 6 + (4 + 6) / 8 ≈ 7.3 ms, against 16 ms in 1 stream. When the copies dominate, they set the time, and the kernel is hidden behind them.
6.6 Stream priorities and concurrency limits
Not every pair of operations can overlap. A GPU has a fixed number of copy engines, which the
device property asyncEngineCount reports. With 2 copy engines, as on both boards used here, 1
copy to the device and 1 copy to the host can run at the same time, but 2 copies in the same
direction must take turns. Kernels in different streams can run at the same time only if the
first kernel leaves some SMs free. A kernel that fills the GPU, like the one in this chapter, runs
alone until its last blocks finish.
When operations compete for the SMs, stream priorities tell the scheduler which stream to serve first:
/// A stream for urgent work and a stream for bulk work, at the 2 ends of the range.
fn priorities(ctx: &Arc<CudaContext>) -> Result<(), DriverError> {
let range = ctx.stream_priority_range()?;
let urgent = ctx.new_stream_with_priority(range.greatest())?;
let bulk = ctx.new_stream_with_priority(range.least())?;
println!("stream priorities: urgent {}, bulk {}", urgent.priority()?, bulk.priority()?);
Ok(())
}int least, greatest;
cudaStream_t urgent, bulk;
cudaDeviceGetStreamPriorityRange(&least, &greatest);
cudaStreamCreateWithPriority(&urgent, cudaStreamNonBlocking, greatest);
cudaStreamCreateWithPriority(&bulk, cudaStreamNonBlocking, least);
The scheduler starts blocks from a high-priority stream before waiting blocks from a low-priority
stream. Latency-critical work, such as a small kernel whose result the host is waiting for, belongs
in the high-priority stream, and bulk work in the low-priority one. In Rust,
ctx.new_stream_with_priority(p)? creates such a stream, and ctx.stream_priority_range()?
returns the range of priorities.
6.7 CUDA graphs
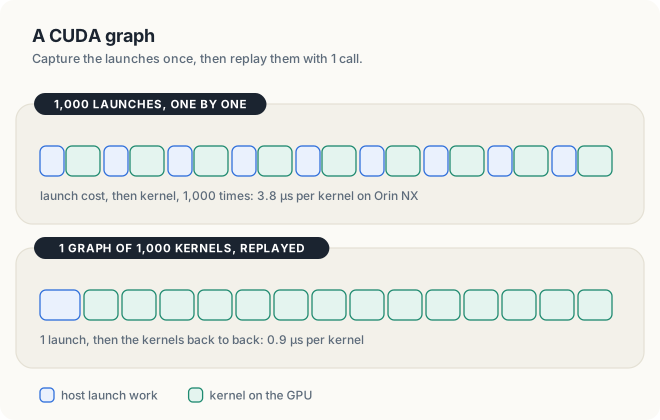
Every kernel launch costs the host a few microseconds: the driver checks the arguments, writes a command, and submits it to the GPU. For a kernel that runs for 10 ms, this cost is negligible. For a program that launches thousands of short kernels, however, the launch cost can exceed the execution time of the kernels themselves.
A CUDA graph is a recorded set of GPU operations, such as kernels and copies, together with the
ordering between them. The program records the graph once and then launches the whole graph with a
single call, so the launch work is performed once for all of its operations. The simplest way to
record a graph is stream capture: between the calls cudaStreamBeginCapture and
cudaStreamEndCapture, operations queued in the stream are recorded instead of executed.
Listing 6.4 1,000 launches, one by one and as a graph.
/// 1,000 launches of an empty kernel: one by one, and replayed from a graph.
fn graphs(
module: &kernels::LoadedModule,
stream: &CudaStream,
) -> Result<(), Box<dyn std::error::Error>> {
let launches = 1000;
let launch = module.prepare_empty(LaunchConfig1D::new(1, 32, 0))?;
module.empty(stream, &launch)?;
stream.synchronize()?;
let t0 = Instant::now();
for _ in 0..launches {
module.empty(stream, &launch)?;
}
stream.synchronize()?;
let direct = t0.elapsed().as_secs_f64() * 1e3 / launches as f64;
let s = stream.cu_stream();
let mut graph = std::ptr::null_mut();
let mut exec = std::ptr::null_mut();
// SAFETY: `s` is a live stream, and no other thread queues work while it is captured.
unsafe { sys::cuStreamBeginCapture_v2(s, GLOBAL).result()? };
for _ in 0..launches {
module.empty(stream, &launch)?;
}
// SAFETY: `graph` and `exec` receive new handles, used only in this function.
unsafe {
sys::cuStreamEndCapture(s, &mut graph).result()?;
sys::cuGraphInstantiateWithFlags(&mut exec, graph, 0).result()?;
}
// SAFETY: `exec` is the graph instantiated above, and `s` is still live.
unsafe { sys::cuGraphLaunch(exec, s).result()? }; // warm up
stream.synchronize()?;
let t0 = Instant::now();
// SAFETY: `exec` is the graph instantiated above, and `s` is still live.
unsafe { sys::cuGraphLaunch(exec, s).result()? };
stream.synchronize()?;
let replay = t0.elapsed().as_secs_f64() * 1e3 / launches as f64;
let direct_us = direct * 1e3;
let replay_us = replay * 1e3;
println!("1,000 launches of an empty kernel, time per kernel");
println!(" launched one by one {direct_us:6.2} us");
println!(" replayed from a graph {replay_us:6.2} us");
// SAFETY: the stream is synchronized, so the GPU no longer uses either handle.
unsafe {
sys::cuGraphExecDestroy(exec).result()?;
sys::cuGraphDestroy(graph).result()?;
}
Ok(())
}// 3. 1,000 launches of an empty kernel: one by one, and replayed from a graph.
void graphs(cudaStream_t s)
{
const int launches = 1000;
empty<<<1, 32, 0, s>>>();
check(cudaStreamSynchronize(s));
double t0 = nowMs();
for (int k = 0; k < launches; ++k) {
empty<<<1, 32, 0, s>>>();
}
check(cudaStreamSynchronize(s));
double direct = (nowMs() - t0) / launches;
cudaGraph_t graph;
cudaGraphExec_t exec;
check(cudaStreamBeginCapture(s, cudaStreamCaptureModeGlobal));
for (int k = 0; k < launches; ++k) {
empty<<<1, 32, 0, s>>>();
}
check(cudaStreamEndCapture(s, &graph));
check(cudaGraphInstantiate(&exec, graph, 0));
check(cudaGraphLaunch(exec, s)); // warm up
check(cudaStreamSynchronize(s));
t0 = nowMs();
check(cudaGraphLaunch(exec, s));
check(cudaStreamSynchronize(s));
double replay = (nowMs() - t0) / launches;
std::printf("1,000 launches of an empty kernel, time per kernel\n");
std::printf(" launched one by one %6.2f us\n", direct * 1e3);
std::printf(" replayed from a graph %6.2f us\n", replay * 1e3);
check(cudaGraphExecDestroy(exec));
check(cudaGraphDestroy(graph));
}
1,000 launches of an empty kernel, time per kernel
launched one by one 3.77 us
replayed from a graph 0.93 us
An empty kernel does no work, so its time consists entirely of launch overhead. Launched 1 at a time, each empty kernel cost 3.77 µs on the Orin NX and 2.65 µs on the Thor. Replayed from a graph, it cost 0.93 µs and 0.85 µs, respectively (figure 6.6). Graphs are therefore useful in programs that run the same short sequence of operations many times, such as each step of an inference loop or each frame of a video pipeline.
NOTE: The version of cuda-oxide used in this book has no safe API for CUDA graphs. The Rust
version therefore calls the driver functions cuStreamBeginCapture_v2, cuStreamEndCapture,
cuGraphInstantiateWithFlags and cuGraphLaunch through cuda_core::sys, in unsafe blocks.
6.8 Synchronization calls
| C++ | Rust (cuda-oxide) | The host waits for |
|---|---|---|
cudaDeviceSynchronize() | ctx.synchronize()? | all work on the device |
cudaStreamSynchronize(s) | stream.synchronize()? | all work queued in stream s |
cudaEventSynchronize(e) | event.synchronize()? | the GPU to pass event e |
cudaStreamWaitEvent(s, e) | stream.wait(&event)? | nothing: stream s waits on the GPU for event e |
cudaMemcpy(...) | buffer.copy_from_host(&stream, ...)? | the copy itself |
cudaMemcpyAsync(..., s) | unsafe { buffer.copy_from_pinned_host_async(&stream, ...)? } | nothing: the copy is queued |
The call cudaStreamWaitEvent needs a further explanation. It makes 1 stream wait for work in
another stream without stopping the host. For example, if a kernel in 1 stream must not start
until a copy in another stream has completed, the program records an event after the copy in the
first stream and makes the second stream wait for that event.
6.9 The complete programs
Listing 6.5 The complete programs. code/oxide/ch06_streams/src/main.rs code/ch06_streams/streams.cu
//! Chapter 6 in Rust: a launch timed with events, a pipeline on 2 streams, streams with
//! priorities, and a CUDA graph of 1,000 launches.
//!
//! cargo oxide run
use std::sync::Arc;
use std::time::Instant;
use cuda_core::sys::CUevent_flags_enum_CU_EVENT_DEFAULT as TIMING;
use cuda_core::sys::CUstreamCaptureMode_enum_CU_STREAM_CAPTURE_MODE_GLOBAL as GLOBAL;
use cuda_core::{
CudaContext, CudaStream, DeviceBuffer, DriverError, IntoResult, LaunchConfig1D,
PinnedHostBuffer, sys,
};
use cuda_device::{DisjointSlice, cuda_module, kernel, launch_contract, thread};
const N: usize = 32 << 20; // 33,554,432 floats, 128 MiB
const STEPS: u32 = 256;
#[cuda_module]
mod kernels {
use super::*;
/// Some arithmetic per element, so that a kernel takes about as long as its copies.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn work(mut x: DisjointSlice<f32>, steps: u32) {
if let Some(v) = x.get_mut(thread::index_1d()) {
let mut a = *v;
for _ in 0..steps {
a = a * 0.999 + 0.5;
}
*v = a;
}
}
/// A kernel that does nothing, so that its time is the cost of its launch.
#[kernel]
#[launch_contract(domain = 1, block = (32, 1, 1))]
pub fn empty() {}
}
/// 1 chunk of the data: its pinned host buffer and its device buffer.
struct Chunk {
host: PinnedHostBuffer<f32>,
device: DeviceBuffer<f32>,
}
/// The data split into `count` chunks of 1.0s.
fn chunks(
ctx: &Arc<CudaContext>,
stream: &CudaStream,
count: usize,
) -> Result<Vec<Chunk>, DriverError> {
let len = N / count;
(0..count)
.map(|_| {
let host = PinnedHostBuffer::from_slice(ctx, &vec![1.0f32; len])?;
let device = DeviceBuffer::<f32>::zeroed(stream, len)?;
Ok(Chunk { host, device })
})
.collect()
}
/// Copy in, compute and copy out every chunk, chunk c on stream c % streams.len().
/// Returns the average of 5 runs, in milliseconds.
fn pipeline(
module: &kernels::LoadedModule,
streams: &[Arc<CudaStream>],
parts: &mut [Chunk],
) -> Result<f64, Box<dyn std::error::Error>> {
let len = parts[0].host.len();
let blocks = len.div_ceil(256) as u32;
let launch = module.prepare_work(LaunchConfig1D::new(blocks, 256, 0))?;
let start = Instant::now();
for _ in 0..5 {
for (c, part) in parts.iter_mut().enumerate() {
let stream = &streams[c % streams.len()];
// SAFETY: `part.host` is neither read, written nor dropped until every
// stream is synchronized below, after both copies have completed.
unsafe { part.device.copy_from_pinned_host_async(stream, &part.host)? };
module.work(stream, &launch, &mut part.device, STEPS)?;
unsafe { part.device.copy_to_pinned_host_async(stream, &mut part.host)? };
}
}
for stream in streams {
stream.synchronize()?;
}
Ok(start.elapsed().as_secs_f64() * 1e3 / 5.0)
}
/// A stream for urgent work and a stream for bulk work, at the 2 ends of the range.
fn priorities(ctx: &Arc<CudaContext>) -> Result<(), DriverError> {
let range = ctx.stream_priority_range()?;
let urgent = ctx.new_stream_with_priority(range.greatest())?;
let bulk = ctx.new_stream_with_priority(range.least())?;
println!("stream priorities: urgent {}, bulk {}", urgent.priority()?, bulk.priority()?);
Ok(())
}
/// 1,000 launches of an empty kernel: one by one, and replayed from a graph.
fn graphs(
module: &kernels::LoadedModule,
stream: &CudaStream,
) -> Result<(), Box<dyn std::error::Error>> {
let launches = 1000;
let launch = module.prepare_empty(LaunchConfig1D::new(1, 32, 0))?;
module.empty(stream, &launch)?;
stream.synchronize()?;
let t0 = Instant::now();
for _ in 0..launches {
module.empty(stream, &launch)?;
}
stream.synchronize()?;
let direct = t0.elapsed().as_secs_f64() * 1e3 / launches as f64;
let s = stream.cu_stream();
let mut graph = std::ptr::null_mut();
let mut exec = std::ptr::null_mut();
// SAFETY: `s` is a live stream, and no other thread queues work while it is captured.
unsafe { sys::cuStreamBeginCapture_v2(s, GLOBAL).result()? };
for _ in 0..launches {
module.empty(stream, &launch)?;
}
// SAFETY: `graph` and `exec` receive new handles, used only in this function.
unsafe {
sys::cuStreamEndCapture(s, &mut graph).result()?;
sys::cuGraphInstantiateWithFlags(&mut exec, graph, 0).result()?;
}
// SAFETY: `exec` is the graph instantiated above, and `s` is still live.
unsafe { sys::cuGraphLaunch(exec, s).result()? }; // warm up
stream.synchronize()?;
let t0 = Instant::now();
// SAFETY: `exec` is the graph instantiated above, and `s` is still live.
unsafe { sys::cuGraphLaunch(exec, s).result()? };
stream.synchronize()?;
let replay = t0.elapsed().as_secs_f64() * 1e3 / launches as f64;
let direct_us = direct * 1e3;
let replay_us = replay * 1e3;
println!("1,000 launches of an empty kernel, time per kernel");
println!(" launched one by one {direct_us:6.2} us");
println!(" replayed from a graph {replay_us:6.2} us");
// SAFETY: the stream is synchronized, so the GPU no longer uses either handle.
unsafe {
sys::cuGraphExecDestroy(exec).result()?;
sys::cuGraphDestroy(graph).result()?;
}
Ok(())
}
fn main() -> Result<(), Box<dyn std::error::Error>> {
let ctx = CudaContext::new(0)?;
let streams = [ctx.new_stream()?, ctx.new_stream()?];
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let mut whole = chunks(&ctx, &streams[0], 1)?;
let mut eighths = chunks(&ctx, &streams[0], 8)?;
pipeline(&module, &streams, &mut eighths)?; // warm up: the clocks rise under load
// 1. A launch returns at once; events time the kernel on the GPU.
let stream = &streams[0];
let launch = module.prepare_work(LaunchConfig1D::new((N / 256) as u32, 256, 0))?;
let device = &mut whole[0].device;
let t0 = Instant::now();
let start = stream.record_event(Some(TIMING))?;
module.work(stream, &launch, device, STEPS)?;
let stop = stream.record_event(Some(TIMING))?;
let launched = t0.elapsed().as_secs_f64() * 1e3;
stop.synchronize()?;
let finished = t0.elapsed().as_secs_f64() * 1e3;
println!("a launch of a kernel over 128 MiB");
println!(" launch call returned after {launched:8.3} ms");
println!(" kernel finished after {finished:8.3} ms");
println!(" kernel time by events {:8.3} ms", start.elapsed_ms(&stop)?);
// 2. The same work in 1 chunk on 1 stream, and in 8 chunks on 2 streams.
println!("copy in, kernel, copy out over 128 MiB");
let one = pipeline(&module, &streams[..1], &mut whole)?;
let eight = pipeline(&module, &streams, &mut eighths)?;
println!(" 1 stream, 1 chunk {one:7.2} ms");
println!(" 2 streams, 8 chunks {eight:7.2} ms");
// 3. Streams with priorities, and a graph.
priorities(&ctx)?;
graphs(&module, stream)?;
Ok(())
}// Chapter 6: asynchronous launches, events, a pipeline on 2 streams, and a CUDA graph.
// Build: nvcc -arch=native streams.cu -o streams
#include <chrono>
#include <cstdio>
#include <cstdlib>
#include <cuda_runtime.h>
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// Some arithmetic per element, so that a kernel takes about as long as its copies.
__global__ void work(float* x, int n, int steps)
{
    int i = blockIdx.x * blockDim.x + threadIdx.x;
    if (i >= n) return;

    float v = x[i];
    for (int k = 0; k < steps; ++k) {
        v = fmaf(v, 0.999f, 0.5f);
    }
    x[i] = v;
}
__global__ void empty() {}
// 1. A launch returns before the kernel finishes; events time the kernel on the GPU.
void asyncLaunch(float* d, int n, int steps)
{
    cudaEvent_t start, stop;
    check(cudaEventCreate(&start));
    check(cudaEventCreate(&stop));

    work<<<(n + 255) / 256, 256>>>(d, n, steps);       // warm up
    check(cudaDeviceSynchronize());

    double t0 = nowMs();
    check(cudaEventRecord(start));
    work<<<(n + 255) / 256, 256>>>(d, n, steps);
    check(cudaEventRecord(stop));
    double launched = nowMs() - t0;

    check(cudaEventSynchronize(stop));
    double finished = nowMs() - t0;

    float gpuMs;
    check(cudaEventElapsedTime(&gpuMs, start, stop));

    std::printf("a launch of a kernel over %d MiB\n", int(n * sizeof(float) >> 20));
    std::printf("  launch call returned after   %8.3f ms\n", launched);
    std::printf("  kernel finished after        %8.3f ms\n", finished);
    std::printf("  kernel time by events        %8.3f ms\n", gpuMs);

    check(cudaEventDestroy(start));
    check(cudaEventDestroy(stop));
}
// 2. Copy in, compute, copy out: all at once on 1 stream, or in chunks on 2 streams.
void enqueue(float* host, float* d, int n, int steps, int chunks, cudaStream_t* streams)
{
    int part = n / chunks;
    size_t bytes = part * sizeof(float);

    for (int c = 0; c < chunks; ++c) {
        cudaStream_t s = streams[c % 2];
        float* h = host + c * part;
        float* g = d + c * part;

        check(cudaMemcpyAsync(g, h, bytes, cudaMemcpyHostToDevice, s));
        work<<<(part + 255) / 256, 256, 0, s>>>(g, part, steps);
        check(cudaMemcpyAsync(h, g, bytes, cudaMemcpyDeviceToHost, s));
    }
}

// Average time of 5 pipelines, in milliseconds.
double pipeline(float* host, float* d, int n, int steps, int chunks, cudaStream_t* streams)
{
    check(cudaDeviceSynchronize());
    double t0 = nowMs();

    for (int r = 0; r < 5; ++r) {
        enqueue(host, d, n, steps, chunks, streams);
    }

    check(cudaDeviceSynchronize());
    return (nowMs() - t0) / 5;
}
// The 3 stages of the 1-stream run, timed separately with events.
void stages(float* host, float* d, int n, int steps, cudaStream_t s)
{
cudaEvent_t e[4];
for (auto& ev : e) check(cudaEventCreate(&ev));
size_t bytes = n * sizeof(float);
check(cudaEventRecord(e[0], s));
check(cudaMemcpyAsync(d, host, bytes, cudaMemcpyHostToDevice, s));
check(cudaEventRecord(e[1], s));
work<<<(n + 255) / 256, 256, 0, s>>>(d, n, steps);
check(cudaEventRecord(e[2], s));
check(cudaMemcpyAsync(host, d, bytes, cudaMemcpyDeviceToHost, s));
check(cudaEventRecord(e[3], s));
check(cudaEventSynchronize(e[3]));
const char* names[] = {"copy in", "kernel", "copy out"};
for (int k = 0; k < 3; ++k) {
float ms;
check(cudaEventElapsedTime(&ms, e[k], e[k + 1]));
std::printf(" %-9s %7.2f ms\n", names[k], ms);
}
for (auto& ev : e) check(cudaEventDestroy(ev));
}
// 3. 1,000 launches of an empty kernel: one by one, and replayed from a graph.
void graphs(cudaStream_t s)
{
    const int launches = 1000;
    empty<<<1, 32, 0, s>>>();
    check(cudaStreamSynchronize(s));

    double t0 = nowMs();
    for (int k = 0; k < launches; ++k) {
        empty<<<1, 32, 0, s>>>();
    }
    check(cudaStreamSynchronize(s));
    double direct = (nowMs() - t0) / launches;

    cudaGraph_t graph;
    cudaGraphExec_t exec;
    check(cudaStreamBeginCapture(s, cudaStreamCaptureModeGlobal));
    for (int k = 0; k < launches; ++k) {
        empty<<<1, 32, 0, s>>>();
    }
    check(cudaStreamEndCapture(s, &graph));
    check(cudaGraphInstantiate(&exec, graph, 0));

    check(cudaGraphLaunch(exec, s));                    // warm up
    check(cudaStreamSynchronize(s));

    t0 = nowMs();
    check(cudaGraphLaunch(exec, s));
    check(cudaStreamSynchronize(s));
    double replay = (nowMs() - t0) / launches;

    std::printf("1,000 launches of an empty kernel, time per kernel\n");
    std::printf("  launched one by one   %6.2f us\n", direct * 1e3);
    std::printf("  replayed from a graph %6.2f us\n", replay * 1e3);

    check(cudaGraphExecDestroy(exec));
    check(cudaGraphDestroy(graph));
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %d copy engine(s)\n", prop.name, prop.asyncEngineCount);
const int n = 32 << 20; // 33,554,432 floats, 128 MiB
const int steps = 256;
float* host;
float* d;
check(cudaMallocHost(&host, n * sizeof(float)));
check(cudaMalloc(&d, n * sizeof(float)));
for (int i = 0; i < n; ++i) {
host[i] = 1.0f;
}
cudaStream_t streams[2];
check(cudaStreamCreate(&streams[0]));
check(cudaStreamCreate(&streams[1]));
pipeline(host, d, n, steps, 8, streams); // warm up: clocks rise under load
asyncLaunch(d, n, steps);
std::printf("copy in, kernel, copy out over 128 MiB\n");
stages(host, d, n, steps, streams[0]);
double one = pipeline(host, d, n, steps, 1, streams);
double eight = pipeline(host, d, n, steps, 8, streams);
double many = pipeline(host, d, n, steps, 32, streams);
std::printf(" 1 stream, 1 chunk %7.2f ms\n", one);
std::printf(" 2 streams, 8 chunks %7.2f ms\n", eight);
std::printf(" 2 streams, 32 chunks %7.2f ms\n", many);
graphs(streams[0]);
check(cudaStreamDestroy(streams[0]));
check(cudaStreamDestroy(streams[1]));
check(cudaFreeHost(host));
check(cudaFree(d));
}
Common mistakes
- Queuing a copy with
cudaMemcpyAsyncfrom pageable memory. The copy runs synchronously, and the overlap is lost. Use pinned memory (Chapter 4). - Launching or copying without a stream in a program that overlaps work. The default stream waits for every other stream. Name a stream in every call.
- Timing GPU work with the host clock alone. The measurement includes launch time and the time the host takes to notice completion. Use events.
- Modifying a host buffer while an asynchronous copy still reads it. Synchronize the stream, or wait for an event, first.
- Dividing the data into more and more chunks. Once the longest stage dominates, additional chunks only add launch work.
- Expecting overlap to shorten the longest stage. Overlap hides the other stages behind it.
Summary
- A launch or an asynchronous copy only queues work and returns: 0.075 ms for a kernel that ran for 12 ms.
- A stream is an ordered queue. Work in 1 stream runs in order; work in different streams may run at the same time, on the copy engines and the SMs together.
- The default stream synchronizes with every other stream, so programs that overlap work name their streams explicitly.
- Events time work on the GPU’s own clock.
- A pipeline of chunks on 2 streams reduced 22.6 ms to 12.9 ms on an Orin NX, close to the bound \(T_{\text{longest}} + T_{\text{others}} / k\). On a Thor, where the kernel dominates and the memory is shared, it saved 13%.
- In Rust, asynchronous copies are
unsafe, because the GPU uses the buffer after the borrow has ended. - A CUDA graph launches many operations with 1 call: 0.93 µs per empty kernel instead of 3.77 µs.
In Chapter 7, we return to a single kernel and study its memory accesses: coalescing, shared-memory tiling and bank conflicts, each measured.
Exercises
- A program queues copy in, kernel and copy out for 4 chunks, all in stream 0. Why does it gain nothing over 1 chunk?
- Copy in takes 8 ms, the kernel 3 ms and copy out 2 ms. What is the bound for 4 chunks on 2 streams, and which stage sets it?
- Change
streams.cuto use 1 stream with 8 chunks. Predict the time, then measure it. - Why does the gain from overlap fall on an integrated GPU such as the Thor? Name two reasons.
- Record an event after the copy in stream 0 and make stream 1 wait for it with
cudaStreamWaitEvent. What does stream 1 now wait for, and what does the host wait for? - A loop launches 5 kernels of 20 µs each, 10,000 times. Estimate the launch overhead at 4 µs per launch, and the time saved by a graph at 1 µs per kernel.
- In the Rust pipeline, move
stream.synchronize()out ofpipelineand readparts[0].hostright after the loop. Which promise in theSAFETYcomment does that break?
Sources and further reading
- NVIDIA, CUDA C++ Programming Guide, “Asynchronous Concurrent Execution”, “Streams”, “Events” and “CUDA Graphs”: https://docs.nvidia.com/cuda/cuda-c-programming-guide/
- NVIDIA, CUDA C++ Best Practices Guide, “Asynchronous and Overlapping Transfers with Computation”: https://docs.nvidia.com/cuda/cuda-c-best-practices-guide/
- M. Harris, “How to Overlap Data Transfers in CUDA C/C++”, NVIDIA Technical Blog, 2012.
- NVlabs, cuda-oxide,
cuda_core::CudaStreamandcuda_core::CudaEvent: https://github.com/NVlabs/cuda-oxide