Chapter 7: Memory Optimization Deep Dive
Most kernels perform only a few arithmetic operations for each byte they read from global memory. As we saw in Chapter 1, the speed of such a kernel is limited by the memory bandwidth of the GPU, not by its arithmetic units. For a memory-bound kernel, the number of operations it performs matters less than the number of bytes it moves and the fraction of those bytes it uses. Two kernels that compute the same result can differ 5 times in speed because one of them moves 5 times as many bytes.
In this chapter, we study the rules that determine how many bytes a kernel moves. Global memory transfers data in fixed-size pieces, so the pattern in which the threads of a warp access memory matters as much as the amount of data they access. Shared memory allows a block to rearrange data on the chip before writing it to global memory, and it has a layout rule of its own. Wider load instructions move more bytes per instruction. We measure the effect of each rule and conclude with a checklist for memory-bound kernels that later chapters use.
This chapter covers
- effective bandwidth as the measure of a memory-bound kernel
- 32-byte sectors, and the effect of the stride between neighboring threads on the bytes moved
- the grid-stride loop
- shared memory as a program-managed cache, applied to a matrix transpose
- bank conflicts, and the padding column that removes them
- vector loads with
float4 - constant and texture memory
- a checklist for memory-bound kernels
The code of the chapter is in
code/ch07_memory/
for C++ and in
code/oxide/ch07_memory/
for Rust.
7.1 Effective bandwidth
The effective bandwidth of a kernel is the number of bytes it must read and write to perform its task, divided by its running time. For example, a kernel that copies 64 MiB reads 64 MiB and writes 64 MiB, so its effective bandwidth is 128 MiB divided by its running time. Effective bandwidth counts only the bytes that the task requires, not the bytes that the hardware actually transfers. Therefore, a kernel that causes unnecessary memory traffic has a low effective bandwidth, and the measure exposes the waste.
A plain copy kernel provides the reference point. On a Jetson Orin NX, whose memory has a peak bandwidth of 102 GB/s, a copy kernel reached about 74 GB/s; on a Jetson AGX Thor, with a peak of 273 GB/s, it reached about 225 GB/s. No kernel moves its bytes faster than a copy. A memory-bound kernel whose effective bandwidth is close to that of a copy has little left to gain, whereas a kernel far below it either transfers bytes that it does not use or accesses memory in an unfavorable pattern.
There are two ways to improve a memory-bound kernel:
- Waste fewer bytes. Arrange the accesses so that every byte delivered by the memory is used.
- Fetch fewer bytes. When the same data is needed more than once, keep it on the chip, in shared memory or in registers, instead of reading it from global memory again.
Each technique in the rest of this chapter belongs to one of these 2 categories.
7.2 Memory coalescing
7.2.1 Sectors
Global memory does not deliver individual bytes. The memory system transfers data in sectors of 32 bytes, aligned to multiples of 32, and the L2 cache groups 4 sectors into a 128-byte line. When a warp executes a load instruction, the hardware collects the 32 addresses of its threads and fetches every sector that contains at least one of them. A warp’s access is said to be coalesced when its addresses fall into as few sectors as possible.
Consider a warp whose 32 threads read 32 neighboring floats. These occupy 32 × 4 = 128 bytes,
exactly 4 sectors, so the warp moves 128 bytes and uses all 128 of them. If the threads instead read
every other float, the 32 floats are spread over 256 bytes, or 8 sectors, and half of each sector is
wasted. At a distance of 8 floats, which is 32 bytes, each float lies in a sector of its own. The
warp then moves 32 sectors, 1,024 bytes, to use 128 bytes (figure 7.1).
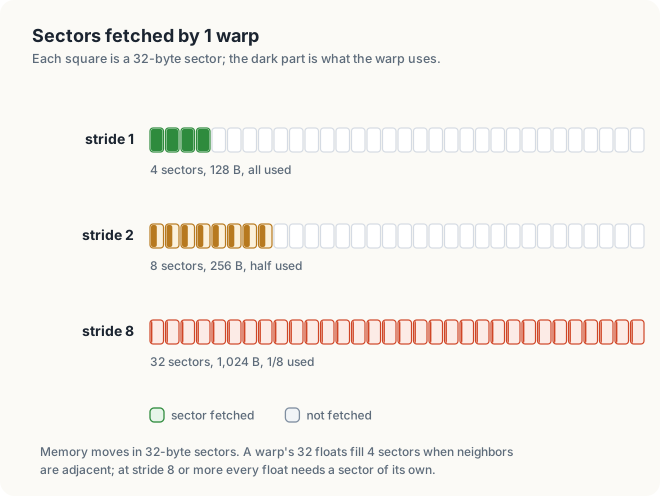
Animation 1 shows the sectors moved for each stride, with the bytes moved and the bytes used.
7.2.2 Measuring the effect of stride
The kernel in Listing 7.1 takes the stride as a parameter. Thread \(i\) reads element \(i
\times\) stride of the input and writes element \(i\) of the output. The writes therefore
remain coalesced for every stride, and only the reads change from one run to the next.
Listing 7.1 A strided read. code/oxide/ch07_memory/src/main.rs code/ch07_memory/memory.cu
mod kernels {
    // ...
    /// Thread i reads element i * stride.
    #[kernel]
    #[launch_contract(domain = 1, block = (256, 1, 1))]
    pub fn strided(input: &[f32], mut out: DisjointSlice<f32>, stride: u32) {
        let idx = thread::index_1d();
        let i = idx.get();

        if let Some(o) = out.get_mut(idx) {
            *o = input[i * stride as usize];
        }
    }
    // ...
}
// 1. Thread i reads element i * stride, so neighboring threads read `stride` floats apart.
__global__ void strided(const float* in, float* out, int n, int stride)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
out[i] = in[(size_t)i * stride];
}
}
The program launches 16,777,216 threads, so every run reads the 64 MiB that the task requires. The input array is 32 times as large, 2 GiB, so that stride 32 stays within it. The array is also far larger than the L2 cache, which is 2 MiB on the Orin NX and 32 MiB on the Thor, so no stride can be served from the cache.
$ ./memory # on a Jetson Orin NX
GPU: Orin, 8 SMs, L2 cache 2 MiB
each thread reads 1 float, neighbours `stride` floats apart
stride 1 1.973 ms 68.0 GB/s useful
stride 2 2.199 ms 61.0 GB/s useful
stride 4 3.824 ms 35.1 GB/s useful
stride 8 6.432 ms 20.9 GB/s useful
stride 16 9.333 ms 14.4 GB/s useful
stride 32 7.616 ms 17.6 GB/s useful
$ ./memory # on a Jetson AGX Thor
GPU: NVIDIA Thor, 20 SMs, L2 cache 32 MiB
each thread reads 1 float, neighbours `stride` floats apart
stride 1 0.587 ms 228.6 GB/s useful
stride 2 0.776 ms 172.9 GB/s useful
stride 4 1.283 ms 104.6 GB/s useful
stride 8 2.315 ms 58.0 GB/s useful
stride 16 4.468 ms 30.0 GB/s useful
stride 32 2.636 ms 50.9 GB/s useful
The sector model of section 7.2.1 predicts how far the useful bandwidth falls. At stride 1, each thread moves 4 bytes of read and 4 bytes of write, 8 bytes in all. From stride 8 onwards, each read costs a whole sector, so a thread moves 32 + 4 = 36 bytes for the same 8 useful bytes. That is 36 / 8 = 4.5 times the traffic, and the useful bandwidth should therefore fall to about 1/4.5 of its stride-1 value: 68 / 4.5 ≈ 15 GB/s on the Orin NX and 229 / 4.5 ≈ 51 GB/s on the Thor. These predictions are close to the measured values at strides 8 and 16 (figure 7.2).
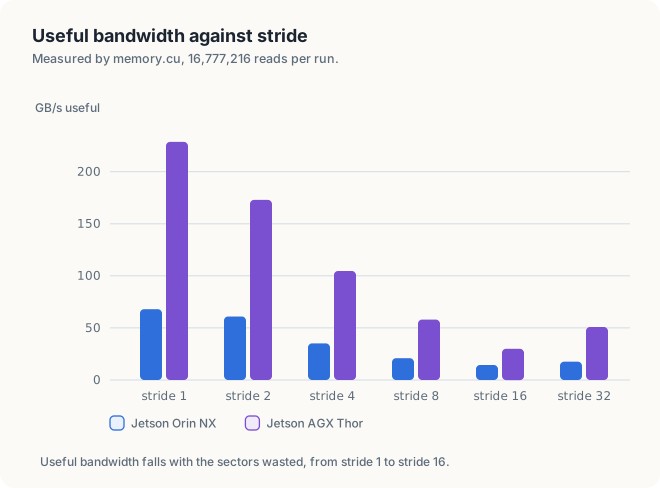
Note that stride 32 ran faster than stride 16 on both GPUs. The DRAM chips are organized in rows and banks, and some address patterns are distributed over them better than others. This effect lies below the level of the sector model, and we do not analyze it here. The stride-1 bandwidth on the Orin NX also varied between about 68 and 78 GB/s from run to run, as the GPU’s clocks changed. Neither effect changes the conclusion:
Neighboring threads should read neighboring addresses.
The global index of Chapter 3, blockIdx.x * blockDim.x + threadIdx.x, satisfies this rule by
construction, since consecutive threads receive consecutive indices. Row-major 2-D data satisfies
it when threadIdx.x moves along a row: thread \(x\) reads in[y * width + x]. If the same data
is read down a column, as in in[x * width + y], neighboring threads are width floats apart,
which is the worst case in the measurements above.
7.3 The grid-stride loop
A kernel that assigns 1 thread to each element ties the size of its launch to the size of the
data. A grid-stride loop, which we used for the histogram in Chapter 5, removes that
dependence. The program launches a grid of fixed size, and each thread processes element \(i\),
then element \(i + s\), then \(i + 2s\), and so on, where \(s\) = gridDim.x * blockDim.x is
the number of threads in the grid.
mod kernels {
// ...
/// A copy by a grid-stride loop: thread i copies elements i, i + s, i + 2s, ...
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn copy_grid_stride(input: &[f32], mut out: DisjointSlice<f32>) {
let stride = (thread::gridDim_x() * thread::blockDim_x()) as usize;
let mut i = thread::index_1d().get();
while i < out.len() {
// SAFETY: thread t writes only the elements i with i % stride == t, and no 2
// threads of the grid have the same t.
unsafe { *out.get_unchecked_mut(i) = input[i] };
i += stride;
}
}
// ...
}int stride = gridDim.x * blockDim.x;
for (int i = blockIdx.x * blockDim.x + threadIdx.x; i < n; i += stride) {
out[i] = in[i];
}
In every iteration of the loop, neighboring threads access neighboring elements, so the loop keeps the coalescing of the kernel with one thread per element. It allows a kernel to process data of any size with a grid sized to the GPU, typically a few blocks per SM. It also allows each thread to accumulate a private result over many elements before it updates shared state, as the histogram kernel of Chapter 5 did.
7.4 Shared memory tiling
7.4.1 Matrix transpose
A transpose exchanges the rows and columns of a matrix: out[x][y] = in[y][x]. When the
matrix is stored in row-major order, 1 of the 2 accesses must cross rows. If each warp reads a row
of the input, the read is coalesced, but the write goes down a column of the output, 1 float in each
of 32 rows (figure 7.3).
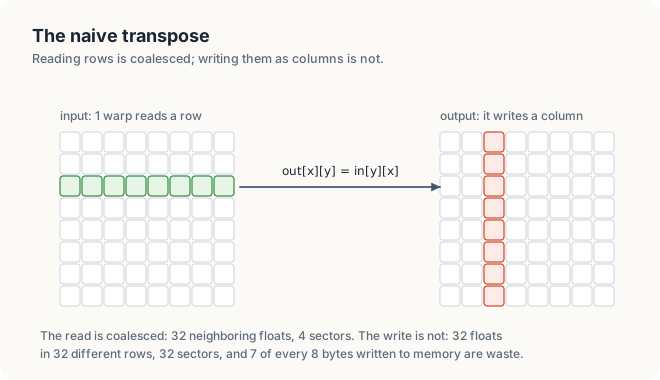
Listing 7.2 The naive transpose.
mod kernels {
// ...
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (32, 32, 1))]
pub fn transpose_naive(input: &[f32], mut out: DisjointSlice<f32, Index2D<WIDTH>>) {
let x = (thread::blockIdx_x() * 32 + thread::threadIdx_x()) as usize;
let y = (thread::blockIdx_y() * 32 + thread::threadIdx_y()) as usize;
// SAFETY: (x, y) -> x * WIDTH + y is a permutation of the matrix, so no 2 threads
// write the same element, and every index is below WIDTH * WIDTH.
unsafe { *out.get_unchecked_mut(x * WIDTH + y) = input[y * WIDTH + x] };
}
// ...
}// 3. Transposes of a width x width matrix, 1 thread per element, blocks of 32 x 32.
__global__ void transposeNaive(const float* in, float* out, int width)
{
int x = blockIdx.x * TILE + threadIdx.x;
int y = blockIdx.y * TILE + threadIdx.y;
out[x * width + y] = in[y * width + x];
}
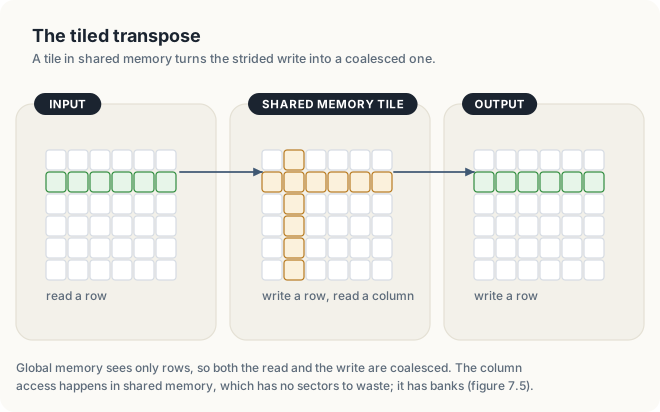
Exchanging the 2 accesses does not help, because the read then goes down a column instead. The solution is to perform the column access in a memory that does not transfer data in sectors, and to access global memory only along rows.
7.4.2 A tiled transpose
Recall from Chapter 2 that shared memory is located on the chip and belongs to 1 block. It does not transfer data in sectors: a thread can read or write any word of it at the same cost. A block can therefore use shared memory as a cache whose contents the program chooses explicitly. For the transpose, each block of 32 × 32 threads performs 3 steps:
- It reads a 32 × 32 tile of the input row by row, with coalesced accesses, and stores the tile in shared memory in the same layout.
- It waits at a barrier, so that the whole tile is in shared memory before any thread reads it.
- It reads the tile column by column and writes each column as a row of the output tile, which is located at the mirrored position of the output matrix. These writes are also coalesced.
Global memory is accessed only along rows; the column access takes place in shared memory (figure 7.4).
Listing 7.3 The tiled transpose.
mod kernels {
// ...
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (32, 32, 1))]
pub fn transpose_tiled(input: &[f32], mut out: DisjointSlice<f32, Index2D<WIDTH>>) {
static mut TILE: SharedArray<f32, { 32 * 33 }> = SharedArray::UNINIT;
let (tx, ty) = (thread::threadIdx_x() as usize, thread::threadIdx_y() as usize);
let bx = thread::blockIdx_x() as usize * 32;
let by = thread::blockIdx_y() as usize * 32;
// SAFETY: each thread writes only its own slot of the tile, before the barrier.
unsafe { TILE[ty * 33 + tx] = input[(by + ty) * WIDTH + bx + tx] };
thread::sync_threads();
// SAFETY: the tile is only read after the barrier. The map
// (tx, ty) -> (bx + ty) * WIDTH + by + tx is a permutation of the matrix,
// so no 2 threads write the same element.
unsafe { *out.get_unchecked_mut((bx + ty) * WIDTH + by + tx) = TILE[tx * 33 + ty] };
}
// ...
}template <int PAD>
__global__ void transposeTiled(const float* in, float* out, int width)
{
__shared__ float tile[TILE][TILE + PAD];
int x = blockIdx.x * TILE + threadIdx.x;
int y = blockIdx.y * TILE + threadIdx.y;
tile[threadIdx.y][threadIdx.x] = in[y * width + x];
__syncthreads();
x = blockIdx.y * TILE + threadIdx.x;
y = blockIdx.x * TILE + threadIdx.y;
out[y * width + x] = tile[threadIdx.x][threadIdx.y];
}
After the barrier, the kernel recomputes x and y for the output. The block’s x and y block
numbers are exchanged, because tile (bx, by) of the input becomes tile (by, bx) of the output.
PAD is a template parameter whose value is 0 or 1; section 7.5 explains the purpose of the
additional column. Animation 2 follows a 4 × 4 tile through shared memory.
7.4.3 The transposes in Rust
In Rust, both transpose kernels, Listings 7.2 and 7.3, require unsafe, for a reason that the
compiler cannot check. A DisjointSlice allows a thread to write only the element named by its own
index, which guarantees that no 2 threads write the same element. A transpose, however, writes
element x * WIDTH + y, which is the index of a different thread. The writes are still disjoint,
because the mapping from \((x, y)\) to x * WIDTH + y is a permutation, but the compiler cannot
prove this. The kernel therefore states the argument in a SAFETY comment and writes through
get_unchecked_mut.
Index2D<WIDTH> declares the output to be a 2-D grid of width WIDTH, which a launch with a 2-D
contract requires. The tile is a SharedArray<f32, { 32 * 33 }>, indexed as row * 33 + column.
This is the padded layout described in section 7.5.
7.5 Bank conflicts and column padding
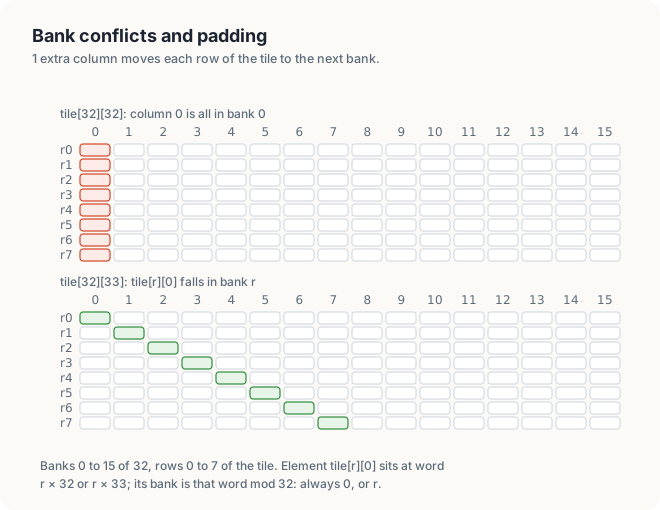
Shared memory is divided into 32 banks, each of which can serve 1 32-bit word per cycle. Consecutive words are assigned to consecutive banks, so word \(w\) is located in bank \(w \bmod 32\) (Chapter 2). A warp’s 32 accesses complete in 1 cycle when they fall into 32 different banks. When several accesses fall into the same bank at different addresses, the result is a bank conflict, and that bank serves the accesses one after another.
In a tile declared as float tile[32][32], element tile[r][c] is word \(32r + c\), which is in
bank \((32r + c) \bmod 32 = c\). Reading column 0 means reading tile[0][0] to tile[31][0],
all of which are in bank 0. This is a 32-way conflict, and 1 warp’s access takes 32 cycles. If the
tile is declared with 1 additional column, as float tile[32][33], then tile[r][c] is word
\(33r + c\), in bank \((33r + c) \bmod 32 = (r + c) \bmod 32\). Column 0 now falls into banks
0, 1, 2, … 31, which are all different, and the access takes 1 cycle (figure 7.5). The additional
column is never used; its only effect is to shift each row by 1 bank.
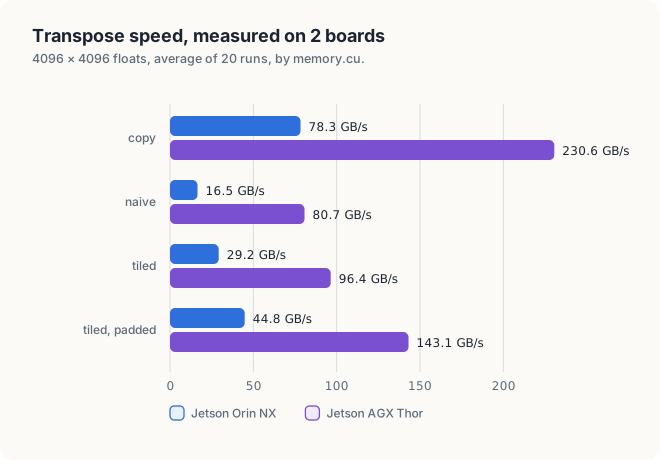
transpose of a 4096 x 4096 matrix # on a Jetson Orin NX
copy, for reference 1.71 ms 78.3 GB/s
naive 8.13 ms 16.5 GB/s
tiled 4.60 ms 29.2 GB/s
tiled and padded 3.00 ms 44.8 GB/s
tiled transpose correct: yes
transpose of a 4096 x 4096 matrix # on a Jetson AGX Thor
copy, for reference 0.58 ms 230.6 GB/s
naive 1.66 ms 80.7 GB/s
tiled 1.39 ms 96.4 GB/s
tiled and padded 0.94 ms 143.1 GB/s
tiled transpose correct: yes
$ cargo oxide run # on a Jetson Orin NX
transpose of a 4096 x 4096 matrix
naive 7.98 ms 16.8 GB/s
tiled and padded 3.26 ms 41.1 GB/s
tiled transpose correct: yes
On the Orin NX, tiling alone raised the transpose from 16.5 to 29.2 GB/s, and padding raised it to 44.8 GB/s, 2.7 times the bandwidth of the naive kernel. On the Thor, the transpose rose from 80.7 to 143.1 GB/s, 1.8 times (figure 7.6). Both results are still below the copy. A block of the tiled transpose must wait at its barrier between reading and writing, so it overlaps memory traffic less than a copy does. Chapter 9 returns to the problem of keeping more work in flight per thread.
A tile is declared float tile[32][16]. Which banks does a column of it fall in, and how many cycles does reading a column take?
tile[r][c] is word \(16r + c\), in bank \((16r + c) \bmod 32\). For column 0, rows 0, 2, 4, …
fall in bank 0 and rows 1, 3, 5, … in bank 16. With 32 rows, each of the 2 banks serves 16 words: a
16-way conflict, 16 cycles. Padding to 17 columns spreads the column over all 32 banks.
7.6 Vectorized loads: float4 and alignment
A load instruction can move 4, 8 or 16 bytes per thread. float4 is a built-in type that holds 4
floats. With a float4 load, 1 instruction moves 16 bytes per thread and 512 bytes per warp, 4
times as much as a float load. The kernel therefore issues a quarter as many load and store
instructions for the same number of bytes.
Listing 7.4 A copy with 1 and with 4 floats per thread.
/// 4 floats aligned to 16 bytes, so that 1 instruction loads or stores all 4: `float4`.
#[repr(C, align(16))]
#[derive(Clone, Copy, PartialEq)]
pub struct Float4([f32; 4]);
// SAFETY: 4 plain floats, with no pointers, can be copied to and from the device.
unsafe impl DeviceCopy for Float4 {}
mod kernels {
// ...
/// A copy, 1 float per thread.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn copy1(input: &[f32], mut out: DisjointSlice<f32>) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(o) = out.get_mut(idx) {
*o = input[i];
}
}
/// A copy, 4 floats per thread.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn copy4(input: &[Float4], mut out: DisjointSlice<Float4>) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(o) = out.get_mut(idx) {
*o = input[i];
}
}
// ...
}// 2. A copy, 1 float or 4 floats per thread.
__global__ void copy1(const float* in, float* out, int n)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
out[i] = in[i];
}
}
__global__ void copy4(const float4* in, float4* out, int n4)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n4) {
out[i] = in[i];
}
}
copy of 64 MiB # Orin NX, then Thor
1 float per thread 1.83 ms 73.5 GB/s
4 floats per thread 1.53 ms 87.7 GB/s
1 float per thread 0.60 ms 225.2 GB/s
4 floats per thread 0.53 ms 251.5 GB/s
The wider loads made the copy 19% faster on the Orin NX and 12% faster on the Thor, where the copy
reached 92% of the peak of 273 GB/s. A float4 access must be aligned to 16 bytes. Memory returned
by cudaMalloc is aligned to a much larger boundary, so it is safe to cast the start of an
allocation to float4*. A pointer offset by 1, 2 or 3 floats, however, is not aligned, and the last
\(n \bmod 4\) elements of an array must be handled with a plain float loop. In Rust, the
type Float4, 4 floats with the attribute #[repr(C, align(16))], takes the place of float4.
7.7 Constant memory
Constant memory is a read-only space of 64 KB with a small cache of its own on each SM. The constant cache serves all 32 threads of a warp in 1 access when they read the same address; this is called a broadcast. When the threads read different addresses, the accesses are served 1 after another. This behavior is the opposite of global and shared memory, which perform best when the threads access different addresses.
mod kernels {
// ...
#[constant]
static COEFFS: ConstantMemory<[f32; 16]> = ConstantMemory::UNINIT; // in constant memory
/// Every thread multiplies by the same coefficient, coeffs[k].
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scale(input: &[f32], mut out: DisjointSlice<f32>, k: u32) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(o) = out.get_mut(idx) {
*o = input[i] * COEFFS.get_ref()[k as usize]; // every thread reads coeffs[k]
}
}
}
fn main() -> Result<(), Error> {
// ...
let coeffs: [f32; 16] = std::array::from_fn(|k| k as f32 * 0.5);
module.set_coeffs(&stream, &coeffs)?; // fill it by name
// ...
}__constant__ float coeffs[16]; // device side, at file scope
cudaMemcpyToSymbol(coeffs, host, 16 * sizeof(float)); // host side: fill it by name
out[i] = in[i] * coeffs[k]; // in a kernel: every thread reads coeffs[k]
Constant memory is therefore suited to parameters, coefficients and small tables that every thread of a warp reads at the same index. When each thread needs a different entry, ordinary global memory, served through the caches, is faster.
7.8 Texture and surface memory
Texture memory is a read-only path to global memory with 2 additional capabilities. Its cache is organized for 2-D neighborhoods, which suits images read in small squares, and its hardware can interpolate, returning a weighted average of neighboring pixels in 1 load. On current GPUs, the ordinary L1 and L2 caches serve most access patterns as well as the texture cache does, so the main reason to use textures today is the interpolation hardware. Surfaces are the writable counterpart of textures. For data read in rows, as in every kernel of this chapter, coalesced accesses to global memory are as fast and simpler to program.
7.9 Optimization checklist
For a memory-bound kernel, check the following items in order, and measure after each change:
- Effective bandwidth. Compute it and compare it with a copy on the same GPU. A kernel close to the copy has little left to gain.
- Coalescing. Do neighboring threads access neighboring addresses in every load and every store (section 7.2)?
- Launch shape. Does a grid-stride loop give each thread enough work (section 7.3)?
- Reuse. Is data read more than once, or read in a pattern that cannot be coalesced? Stage it in shared memory (section 7.4).
- Bank conflicts. Do the shared-memory accesses of a warp fall into different banks? If not, pad the rows of the tile (section 7.5).
- Vector loads. Can the kernel use
float4loads with correct alignment (section 7.6)? - Uniform values. Do all threads of a warp read the same small values? Use constant memory (section 7.7).
- Transfers. Do the copies that feed the kernel take longer than the kernel itself? Use pinned memory and streams first (Chapters 4 and 6).
7.10 The complete programs
Listing 7.5 The complete programs. code/oxide/ch07_memory/src/main.rs code/ch07_memory/memory.cu
//! Chapter 7 in Rust: coalescing, a grid-stride loop, a matrix transpose through shared
//! memory, copies of 1 and 4 floats per thread, and constant memory.
//!
//! cargo oxide run
use std::sync::Arc;
use std::time::Instant;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, DeviceCopy};
use cuda_core::{LaunchConfig1D, LaunchConfig2D};
use cuda_device::thread::Index2D;
use cuda_device::{ConstantMemory, DisjointSlice, SharedArray, constant, cuda_module};
use cuda_device::{kernel, launch_contract, thread};
const WIDTH: usize = 4096;
const N: usize = WIDTH * WIDTH; // 16,777,216 floats, 64 MiB
type Error = Box<dyn std::error::Error>;
/// 4 floats aligned to 16 bytes, so that 1 instruction loads or stores all 4: `float4`.
#[repr(C, align(16))]
#[derive(Clone, Copy, PartialEq)]
pub struct Float4([f32; 4]);
// SAFETY: 4 plain floats, with no pointers, can be copied to and from the device.
unsafe impl DeviceCopy for Float4 {}
#[cuda_module]
mod kernels {
use super::*;
/// Thread i reads element i * stride.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn strided(input: &[f32], mut out: DisjointSlice<f32>, stride: u32) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(o) = out.get_mut(idx) {
*o = input[i * stride as usize];
}
}
/// A copy by a grid-stride loop: thread i copies elements i, i + s, i + 2s, ...
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn copy_grid_stride(input: &[f32], mut out: DisjointSlice<f32>) {
let stride = (thread::gridDim_x() * thread::blockDim_x()) as usize;
let mut i = thread::index_1d().get();
while i < out.len() {
// SAFETY: thread t writes only the elements i with i % stride == t, and no 2
// threads of the grid have the same t.
unsafe { *out.get_unchecked_mut(i) = input[i] };
i += stride;
}
}
/// A copy, 1 float per thread.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn copy1(input: &[f32], mut out: DisjointSlice<f32>) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(o) = out.get_mut(idx) {
*o = input[i];
}
}
/// A copy, 4 floats per thread.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn copy4(input: &[Float4], mut out: DisjointSlice<Float4>) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(o) = out.get_mut(idx) {
*o = input[i];
}
}
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (32, 32, 1))]
pub fn transpose_naive(input: &[f32], mut out: DisjointSlice<f32, Index2D<WIDTH>>) {
let x = (thread::blockIdx_x() * 32 + thread::threadIdx_x()) as usize;
let y = (thread::blockIdx_y() * 32 + thread::threadIdx_y()) as usize;
// SAFETY: (x, y) -> x * WIDTH + y is a permutation of the matrix, so no 2 threads
// write the same element, and every index is below WIDTH * WIDTH.
unsafe { *out.get_unchecked_mut(x * WIDTH + y) = input[y * WIDTH + x] };
}
#[kernel]
#[launch_contract(domain = 2, coordinates = u32, block = (32, 32, 1))]
pub fn transpose_tiled(input: &[f32], mut out: DisjointSlice<f32, Index2D<WIDTH>>) {
static mut TILE: SharedArray<f32, { 32 * 33 }> = SharedArray::UNINIT;
let (tx, ty) = (thread::threadIdx_x() as usize, thread::threadIdx_y() as usize);
let bx = thread::blockIdx_x() as usize * 32;
let by = thread::blockIdx_y() as usize * 32;
// SAFETY: each thread writes only its own slot of the tile, before the barrier.
unsafe { TILE[ty * 33 + tx] = input[(by + ty) * WIDTH + bx + tx] };
thread::sync_threads();
// SAFETY: the tile is only read after the barrier. The map
// (tx, ty) -> (bx + ty) * WIDTH + by + tx is a permutation of the matrix,
// so no 2 threads write the same element.
unsafe { *out.get_unchecked_mut((bx + ty) * WIDTH + by + tx) = TILE[tx * 33 + ty] };
}
#[constant]
static COEFFS: ConstantMemory<[f32; 16]> = ConstantMemory::UNINIT; // in constant memory
/// Every thread multiplies by the same coefficient, coeffs[k].
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scale(input: &[f32], mut out: DisjointSlice<f32>, k: u32) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(o) = out.get_mut(idx) {
*o = input[i] * COEFFS.get_ref()[k as usize]; // every thread reads coeffs[k]
}
}
}
/// Average time of 20 runs of `launch`, in milliseconds, after 1 warm-up run.
fn time_ms(
stream: &Arc<CudaStream>,
mut launch: impl FnMut() -> Result<(), Error>,
) -> Result<f64, Error> {
launch()?;
stream.synchronize()?;
let start = Instant::now();
for _ in 0..20 {
launch()?;
}
stream.synchronize()?;
Ok(start.elapsed().as_secs_f64() * 1e3 / 20.0)
}
fn gb_per_s(bytes: usize, ms: f64) -> f64 {
bytes as f64 / 1e9 / (ms / 1e3)
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
// 1. Strided reads, from 2 GiB: room for stride 32, too big for any L2.
let big = DeviceBuffer::<f32>::zeroed(&stream, 32 * N)?;
let mut out = DeviceBuffer::<f32>::zeroed(&stream, N)?;
let launch = module.prepare_strided(LaunchConfig1D::new((N / 256) as u32, 256, 0))?;
let mut read = |stride| -> Result<(), Error> {
Ok(module.strided(&stream, &launch, &big, &mut out, stride)?)
};
time_ms(&stream, || read(1))?; // warm up the clocks
println!("each thread reads 1 float, neighbours `stride` floats apart");
for stride in [1u32, 2, 4, 8, 16, 32] {
let ms = time_ms(&stream, || read(stride))?;
let useful = gb_per_s(2 * N * 4, ms);
println!(" stride {stride:2} {ms:7.3} ms {useful:6.1} GB/s useful");
}
// 2. Transposes of a 4096 x 4096 matrix.
let values: Vec<f32> = (0..N).map(|i| (i % 1000) as f32).collect();
let input = DeviceBuffer::from_host(&stream, &values)?;
let blocks = (WIDTH / 32) as u32;
let grid = LaunchConfig2D::new((blocks, blocks), (32, 32), 0);
let naive = module.prepare_transpose_naive(grid)?;
let tiled = module.prepare_transpose_tiled(grid)?;
let ms_naive = time_ms(&stream, || {
Ok(module.transpose_naive(&stream, &naive, &input, &mut out)?)
})?;
let ms_tiled = time_ms(&stream, || {
Ok(module.transpose_tiled(&stream, &tiled, &input, &mut out)?)
})?;
let gb_naive = gb_per_s(2 * N * 4, ms_naive);
let gb_tiled = gb_per_s(2 * N * 4, ms_tiled);
println!("transpose of a {WIDTH} x {WIDTH} matrix");
println!(" naive {ms_naive:6.2} ms {gb_naive:6.1} GB/s");
println!(" tiled and padded {ms_tiled:6.2} ms {gb_tiled:6.1} GB/s");
let result = out.to_host_vec(&stream)?;
let correct = (0..WIDTH)
.all(|y| (0..WIDTH).all(|x| result[x * WIDTH + y] == values[y * WIDTH + x]));
println!("tiled transpose correct: {}", if correct { "yes" } else { "no" });
// 3. A copy of 64 MiB, 1 float and 4 floats per thread, and by a grid-stride loop.
let quads: Vec<Float4> = values
.chunks_exact(4)
.map(|c| Float4([c[0], c[1], c[2], c[3]]))
.collect();
let input4 = DeviceBuffer::from_host(&stream, &quads)?;
let mut out4 = DeviceBuffer::from_host(&stream, &vec![Float4([0.0; 4]); N / 4])?;
let one = module.prepare_copy1(LaunchConfig1D::new((N / 256) as u32, 256, 0))?;
let four = module.prepare_copy4(LaunchConfig1D::new((N / 1024) as u32, 256, 0))?;
let ms1 = time_ms(&stream, || Ok(module.copy1(&stream, &one, &input, &mut out)?))?;
let ms4 = time_ms(&stream, || Ok(module.copy4(&stream, &four, &input4, &mut out4)?))?;
let copied = out4.to_host_vec(&stream)? == quads;
let gb1 = gb_per_s(2 * N * 4, ms1);
let gb4 = gb_per_s(2 * N * 4, ms4);
println!("copy of 64 MiB");
println!(" 1 float per thread {ms1:6.2} ms {gb1:6.1} GB/s");
println!(" 4 floats per thread {ms4:6.2} ms {gb4:6.1} GB/s");
let grid = module.prepare_copy_grid_stride(LaunchConfig1D::new(64, 256, 0))?;
module.copy_grid_stride(&stream, &grid, &input, &mut out)?;
let strided = out.to_host_vec(&stream)? == values;
let copies = if copied && strided { "yes" } else { "no" };
println!("copies correct: {copies}");
// 4. A coefficient from constant memory, read by every thread.
let coeffs: [f32; 16] = std::array::from_fn(|k| k as f32 * 0.5);
module.set_coeffs(&stream, &coeffs)?; // fill it by name
let scale = module.prepare_scale(LaunchConfig1D::new((N / 256) as u32, 256, 0))?;
module.scale(&stream, &scale, &input, &mut out, 3)?;
let result = out.to_host_vec(&stream)?;
let correct = result.iter().zip(&values).all(|(r, v)| *r == v * 1.5);
let verdict = if correct { "yes" } else { "no" };
println!("constant memory correct: {verdict}");
Ok(())
}// Chapter 7: coalescing, vector loads, and a matrix transpose in shared memory, measured.
// Build: nvcc -arch=native memory.cu -o memory
#include <chrono>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cuda_runtime.h>
const int TILE = 32;
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// 1. Thread i reads element i * stride, so neighboring threads read `stride` floats apart.
__global__ void strided(const float* in, float* out, int n, int stride)
{
    int i = blockIdx.x * blockDim.x + threadIdx.x;
    if (i < n) {
        out[i] = in[(size_t)i * stride];
    }
}
__global__ void fill(float* x, size_t n)
{
size_t i = (size_t)blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
x[i] = float(i % 1000);
}
}
// 2. A copy, 1 float or 4 floats per thread.
__global__ void copy1(const float* in, float* out, int n)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
out[i] = in[i];
}
}
__global__ void copy4(const float4* in, float4* out, int n4)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n4) {
out[i] = in[i];
}
}
// 3. Transposes of a width x width matrix, 1 thread per element, blocks of 32 x 32.
__global__ void transposeNaive(const float* in, float* out, int width)
{
    int x = blockIdx.x * TILE + threadIdx.x;
    int y = blockIdx.y * TILE + threadIdx.y;
    out[x * width + y] = in[y * width + x];
}
template <int PAD>
__global__ void transposeTiled(const float* in, float* out, int width)
{
    __shared__ float tile[TILE][TILE + PAD];

    int x = blockIdx.x * TILE + threadIdx.x;
    int y = blockIdx.y * TILE + threadIdx.y;
    tile[threadIdx.y][threadIdx.x] = in[y * width + x];
    __syncthreads();

    x = blockIdx.y * TILE + threadIdx.x;
    y = blockIdx.x * TILE + threadIdx.y;
    out[y * width + x] = tile[threadIdx.x][threadIdx.y];
}
// Average time of 20 runs of `launch`, in milliseconds, after 1 warm-up run.
template <typename F>
double timeKernel(F launch)
{
launch();
check(cudaDeviceSynchronize());
double t0 = nowMs();
for (int r = 0; r < 20; ++r) {
launch();
}
check(cudaGetLastError());
check(cudaDeviceSynchronize());
return (nowMs() - t0) / 20;
}
double gbps(double bytes, double ms)
{
return bytes / 1e9 / (ms / 1e3);
}
void coalescing(const float* in, float* out)
{
const int n = 16 << 20; // 16,777,216 threads, 64 MiB each way
std::printf("each thread reads 1 float, neighbours `stride` floats apart\n");
for (int stride = 1; stride <= 32; stride *= 2) {
double ms = timeKernel([&] { strided<<<n / 256, 256>>>(in, out, n, stride); });
double useful = 2.0 * n * sizeof(float);
std::printf(" stride %2d %7.3f ms %6.1f GB/s useful\n", stride, ms,
gbps(useful, ms));
}
}
void vectors(const float* in, float* out, int n)
{
double ms1 = timeKernel([&] { copy1<<<n / 256, 256>>>(in, out, n); });
double ms4 = timeKernel([&] {
copy4<<<n / 4 / 256, 256>>>((const float4*)in, (float4*)out, n / 4);
});
std::printf("copy of %d MiB\n", int(n * sizeof(float) >> 20));
double bytes = 2.0 * n * sizeof(float);
std::printf(" 1 float per thread %6.2f ms %6.1f GB/s\n", ms1, gbps(bytes, ms1));
std::printf(" 4 floats per thread %6.2f ms %6.1f GB/s\n", ms4, gbps(bytes, ms4));
}
void transposes(const float* in, float* out, int width)
{
dim3 grid(width / TILE, width / TILE), block(TILE, TILE);
double bytes = 2.0 * width * width * sizeof(float);
int n = width * width;
double copy = timeKernel([&] { copy1<<<n / 256, 256>>>(in, out, n); });
double naive = timeKernel([&] { transposeNaive<<<grid, block>>>(in, out, width); });
double tiled = timeKernel([&] { transposeTiled<0><<<grid, block>>>(in, out, width); });
double padded = timeKernel([&] { transposeTiled<1><<<grid, block>>>(in, out, width); });
std::printf("transpose of a %d x %d matrix\n", width, width);
std::printf(" copy, for reference %6.2f ms %6.1f GB/s\n", copy, gbps(bytes, copy));
const char* names[] = {"naive", "tiled", "tiled and padded"};
double times[] = {naive, tiled, padded};
for (int k = 0; k < 3; ++k) {
double gb = gbps(bytes, times[k]);
std::printf(" %-20s %6.2f ms %6.1f GB/s\n", names[k], times[k], gb);
}
}
bool isTranspose(const float* in, float* out, int width)
{
dim3 grid(width / TILE, width / TILE), block(TILE, TILE);
transposeTiled<1><<<grid, block>>>(in, out, width);
std::vector<float> a(width * width), b(width * width);
check(cudaMemcpy(a.data(), in, a.size() * sizeof(float), cudaMemcpyDeviceToHost));
check(cudaMemcpy(b.data(), out, b.size() * sizeof(float), cudaMemcpyDeviceToHost));
for (int y = 0; y < width; ++y) {
for (int x = 0; x < width; ++x) {
if (b[x * width + y] != a[y * width + x]) return false;
}
}
return true;
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %d SMs, L2 cache %d MiB\n",
prop.name, prop.multiProcessorCount, prop.l2CacheSize >> 20);
const int width = 4096;
const int n = width * width; // 16,777,216 floats, 64 MiB
const size_t inLen = (size_t)32 * n; // 2 GiB: room for stride 32, beyond any L2
float *in, *out;
check(cudaMalloc(&in, inLen * sizeof(float)));
check(cudaMalloc(&out, n * sizeof(float)));
fill<<<(inLen + 255) / 256, 256>>>(in, inLen);
for (int k = 0; k < 10; ++k) { // warm up: clocks rise under sustained load
timeKernel([&] { copy1<<<n / 256, 256>>>(in, out, n); });
}
coalescing(in, out);
vectors(in, out, n);
transposes(in, out, width);
bool correct = isTranspose(in, out, width);
std::printf("tiled transpose correct: %s\n", correct ? "yes" : "no");
check(cudaFree(in));
check(cudaFree(out));
}
Common mistakes
- Indexing 2-D data with
threadIdx.xdown a column. Neighboring threads are thenwidthfloats apart. LetthreadIdx.xmove along rows. - Measuring a small array. When the data fits in the L2 cache, the measurement reflects the cache, not the memory: the Thor reported 432 GB/s, above the 273 GB/s peak of its memory, for a 16 MiB test.
- Timing before the clocks have risen. Run the kernel for a fraction of a second before timing it.
- A 32 × 32 shared tile read by columns. Pad it to 32 × 33.
- A missing barrier between filling a tile and reading it. We measured the consequences in Chapter 5.
- Casting an unaligned pointer to
float4*. Only offsets that are multiples of 4 floats are safe. - Constant memory indexed differently by each thread. The accesses are serialized.
Summary
- Effective bandwidth, the bytes a task requires divided by its running time, compared with a plain copy, shows how much a memory-bound kernel has left to gain.
- Global memory transfers 32-byte sectors. When neighboring threads access neighboring addresses, every byte is used; at a stride of 8 floats or more, a warp moves 8 times the bytes it needs, and the measured useful bandwidth fell 3 to 5 times.
- A tile in shared memory allows a transpose to read and write global memory only along rows; a barrier separates filling the tile from reading it.
- Shared memory has 32 banks. One additional column in a 32 × 32 tile removes the 32-way conflict of a column read. Tiling and padding made the transpose 2.7 times as fast on the Orin NX.
float4loads moved the same bytes with a quarter of the instructions and were 12 to 19% faster.- In Rust, a write to another thread’s index requires
unsafeand a stated permutation argument.
Chapter 8 combines these techniques in reductions, scans and histograms that run close to the speed of a copy.
Exercises
- A warp reads
floats at stride 3. How many 32-byte sectors does it fetch, and what fraction of the bytes is used? - A kernel reads 1 GB and writes 1 GB in 25 ms on a GPU whose copy reaches 90 GB/s. What is its effective bandwidth, and how far is it from the copy?
- Run
memoryon your GPU. Use the sector model to predict the useful bandwidth at stride 8 from your stride-1 result, and compare. - Rewrite
transposeNaiveso that it reads down columns and writes rows. Is it faster or slower than the original, and why? - A tile is
double tile[32][32]. Adoubletakes 2 banks. Which padding removes the conflict of a column read? - Change
copy4to handle anyn, including the last \(n \bmod 4\) elements. - In the Rust
transpose_tiled, whichSAFETYclaim would break if the tile were filled after the barrier instead of before?
Sources and further reading
- NVIDIA, CUDA C++ Best Practices Guide, “Coalesced Access to Global Memory”, “Shared Memory” and “Effective Bandwidth Calculation”: https://docs.nvidia.com/cuda/cuda-c-best-practices-guide/
- NVIDIA, CUDA C++ Programming Guide, “Device Memory Accesses”: https://docs.nvidia.com/cuda/cuda-c-programming-guide/
- M. Harris, “An Efficient Matrix Transpose in CUDA C/C++”, NVIDIA Technical Blog, 2013.
- D. Kirk and W. Hwu, Programming Massively Parallel Processors, 4th ed., Morgan Kaufmann, 2022, chapters on memory and tiling.