Chapter 8: Reduction, Scan & Histogram
Many computations end by combining a large number of values into a small result: the total of an array, its largest element, the running total at every position, or the number of elements that fall into each of several bins. These are the reduction, scan and histogram patterns. In Chapter 5 we wrote a tree sum in shared memory and a histogram with atomic counters, and we used them to study barriers and atomic operations. Both kernels produced correct results, but both ran far below the bandwidth of the memory that supplied their data.
In this chapter, we develop a sum, a scan and a histogram that run close to the memory bandwidth of the GPU. We use the tools of Chapter 7: effective bandwidth as the measure of a kernel, the grid-stride loop, and wide loads. The sum is developed in 4 stages, and each stage removes one source of overhead. The scan reuses the same building blocks in a different arrangement. The histogram returns to the kernel of Chapter 5, and its measurements show that its speed was limited by its loads rather than by contention between atomic operations. Every kernel is given in CUDA C++ and in Rust.
This chapter covers
- reductions, and the difference between the work of a computation and its number of steps
- the accuracy of a float sum computed sequentially and computed as a tree
- a tree sum in shared memory, thread coarsening, and warp shuffles, each measured
- inclusive and exclusive scans within a warp, within a block, and across many blocks
- a histogram that reads 16 bytes per load
- results that are identical from run to run
The code of the chapter is in
code/ch08_reduction/
for C++ and in
code/oxide/ch08_reduce/
for Rust. The measurements in this chapter come from 2 integrated GPUs: a Jetson Orin NX (8 SMs,
102 GB/s) and a Jetson AGX Thor (20 SMs, 273 GB/s).
8.1 Background
8.1.1 Reduction operators
A reduction derives a single value from \(n\) values by repeatedly applying a binary operator. A sum uses \(+\), a maximum uses \(\max\), and a count of the elements that satisfy a condition uses \(+\) over values of 0 and 1. A sequential program computes a reduction by walking the array from one end to the other and combining each element with the result so far.
A parallel program must combine the values in a different order. It adds them in pairs, then adds the pairs, and so on. The result is unchanged only if the operator is associative, that is, if \((a + b) + c = a + (b + c)\) for any 3 values. Integer addition, maximum and minimum are associative. Floating-point addition is associative only approximately, because every addition rounds its result and a different grouping rounds at different places (Chapter 5, section 5.6). A float sum computed in pairs is therefore a slightly different sum from the sequential one. As we will see in section 8.2, it is usually the more accurate of the 2.
8.1.2 Work and steps
Two quantities describe the cost of a parallel computation. The work of a computation is the number of operations it performs. Its steps, also called its depth, is the length of the longest chain of operations in which each operation needs the result of the one before. Given enough threads, the work determines the energy that the computation consumes, and the number of steps determines its time.
Consider the 8 values 3, 1, 4, 1, 5, 9, 2, 6. Added sequentially, they produce the running sums 3, 4, 8, 9, 14, 23, 25, 31. Each addition needs the previous running sum, so the computation performs 7 additions in 7 steps. Added in pairs, the values become 4, 5, 14, 8; these become 9 and 22; and these become 31. The 4 additions of the first level are independent of each other, and so are the 2 additions of the second level. The tree therefore performs the same 7 additions in 3 steps (figure 8.1).
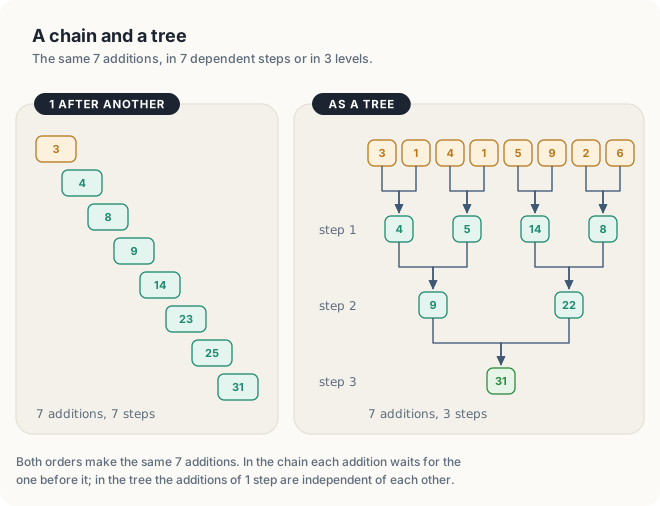
In general, both orders perform \(n - 1\) additions. Each level of the tree halves the number of values, so a tree over \(n\) values has \(\log_2 n\) levels, while the sequential chain has \(n - 1\) steps. For the \(n\) = 67,108,864 values summed in this chapter, the chain is 67,108,863 steps long and the tree 26 steps, because \(2^{26}\) = 67,108,864.
8.1.3 The bandwidth limit of a sum
A sum performs 1 addition for every 4-byte float that it reads, so its arithmetic intensity is 0.25 FLOP per byte. The ridge points of Chapter 2 lie between 10 and 114 FLOP per byte. A sum is therefore memory-bound on every GPU of that table, by a factor of 40 or more, and the shortest time in which it can run is the time the memory needs to deliver the array once: the size of the array divided by the memory bandwidth.
| GPU | Bandwidth | 256 MiB read once |
|---|---|---|
| Jetson Orin NX 16 GB | 102 GB/s | 2.63 ms |
| Jetson AGX Thor | 273 GB/s | 0.98 ms |
| DGX Spark (GB10) | 273 GB/s | 0.98 ms |
| GeForce RTX 4090 | 1,008 GB/s | 0.27 ms |
| GeForce RTX 5090 | 1,792 GB/s | 0.15 ms |
| A100 SXM 80 GB | 2,039 GB/s | 0.13 ms |
| H100 SXM | 3,350 GB/s | 0.08 ms |
For example, 256 MiB is 268,435,456 bytes, and at 102 GB/s the array takes 268,435,456 / (102 × 109) s = 2.63 ms to read. As in Chapter 7, we judge each kernel of this chapter by the bytes it must read and write, divided by its time, and compare the result with the bandwidth in the table.
8.2 Accuracy of a sequential float sum
The test data of the chapter is 67,108,864 floats spread evenly between 0 and 1, generated on the
host. Their exact sum, computed in double precision, is 33,557,630.3. When the same values are
added sequentially into a float on the CPU, the result is 16,777,216.0, half of the correct
answer.
The reason lies in the precision of a float, which holds 24 significant bits. Below 224 = 16,777,216, consecutive floats are at most 1 apart. Between 224 and 225, they are 2 apart, so a float in that range can hold only even numbers. When a value below 1 is added to 16,777,216, the exact result is closer to 16,777,216 than to 16,777,218, and rounding returns 16,777,216. Once the running sum reaches 224, which happens about halfway through the array, no further addition changes it (figure 8.2).
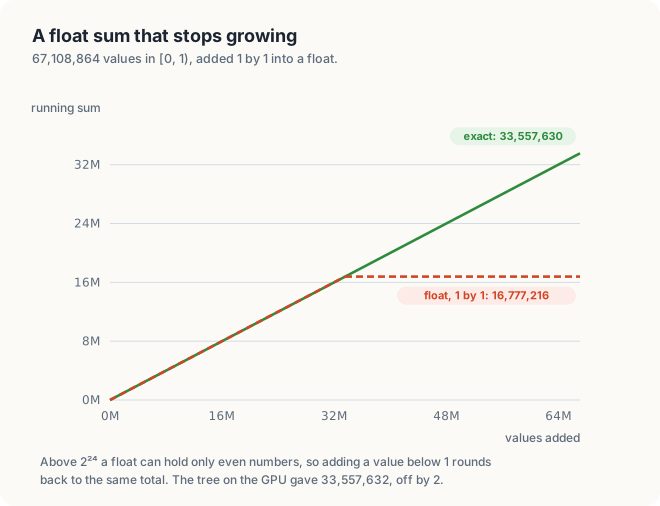
A reduction tree does not have this problem. In the GPU sums of this chapter, each thread first adds 256 values into a register, which produces a total near 128. From then on, totals of similar size are added to each other, so no addition combines a very large number with a very small one. The GPU sums of section 8.6 produced 33,557,632.0. Near 33.5 million, consecutive floats are 4 apart, and 33,557,632 is the float nearest to the exact 33,557,630.3. It is the most accurate result that a float can hold.
A long float sum computed sequentially loses the small values. A tree adds values of similar size and keeps them.
8.3 A tree in shared memory
The first GPU sum is the tree of Chapter 5, section 5.3. Each block of 256 threads loads 256 values into shared memory. At strides 128, 64, …, 1, the lower half of the active threads adds the values of the upper half into its own slots. The halving requires a block size that is a power of 2, so that every level splits evenly; 128, 256 and 512 are the usual choices. A barrier separates the levels, because each level reads values that other threads wrote in the level before.
Listing 8.1 A tree sum per block, 1 element per thread. code/oxide/ch08_reduce/src/main.rs code/ch08_reduction/reduce.cu
mod kernels {
    // ...
    /// 1. A tree in shared memory, 1 element per thread.
    #[kernel]
    #[launch_contract(domain = 1, block = (256, 1, 1))]
    pub fn sum_tree(input: &[f32], mut partial: DisjointSlice<f32>) {
        static mut S: SharedArray<f32, 256> = SharedArray::UNINIT;
        let t = thread::threadIdx_x() as usize;
        let i = thread::index_1d().get();

        let value = if i < input.len() { input[i] } else { 0.0 };
        // SAFETY: each thread writes only its own slot, before the first barrier.
        unsafe { S[t] = value };

        let mut step: usize = 0;
        #[unroll]
        while step < 8 {
            let stride = (BLOCK as usize / 2) >> step; // 128, 64, ... 1
            thread::sync_threads();
            if t < stride {
                // SAFETY: between 2 barriers thread t alone writes slot t, and it reads
                // slot t + stride, which no thread writes at this stride.
                unsafe { S[t] += S[t + stride] };
            }
            step += 1;
        }

        if t == 0 {
            // SAFETY: only thread 0 of each block writes, at its own block number.
            unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = S[0] };
        }
    }
    // ...
}
// 1. A tree in shared memory, 1 element per thread.
__global__ void sumTree(const float* in, float* partial, int n)
{
__shared__ float s[BLOCK];
int i = blockIdx.x * BLOCK + threadIdx.x;
s[threadIdx.x] = i < n ? in[i] : 0.0f;
for (int stride = BLOCK / 2; stride > 0; stride /= 2) {
__syncthreads();
if (threadIdx.x < stride) {
s[threadIdx.x] += s[threadIdx.x + stride];
}
}
if (threadIdx.x == 0) {
partial[blockIdx.x] = s[0];
}
}
Each block writes 1 partial sum, the total of its own values, to partial[blockIdx.x].
Because blocks cannot wait for each other inside a kernel (Chapter 5, section 5.4), the partial
sums are added by a second launch of 1 block of 256 threads. For 67,108,864 values, the first
launch writes 262,144 partial sums.
sum of 67108864 floats (256 MiB), average of 20 runs # on a Jetson Orin NX
tree, 1 per thread 10.36 ms 25.9 GB/s sum 33557628.0
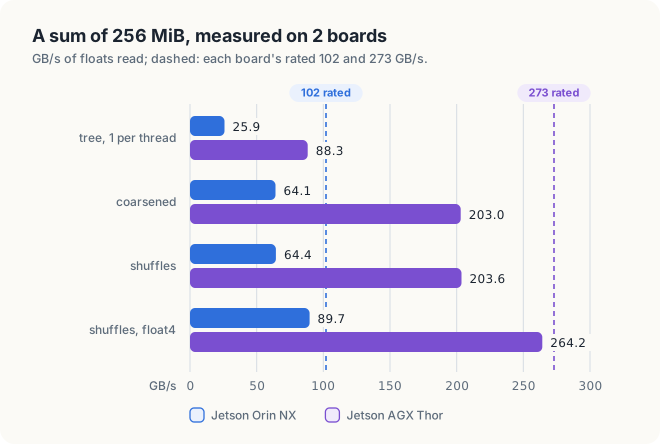
The kernel reached 25.9 GB/s, a quarter of the first GPU’s 102 GB/s; on the second GPU it reached 88.3 GB/s, a third of 273 GB/s. The cause is the ratio of loads to barriers. We let each thread load 1 float and then takes part in 8 levels separated by 8 barriers. In the last levels, almost all of the threads of a block wait for a few others: at stride 1, 1 thread adds and 255 threads wait. While its threads are busy with the tree, a block issues no loads, so the memory is idle for much of the time.
8.4 Thread coarsening
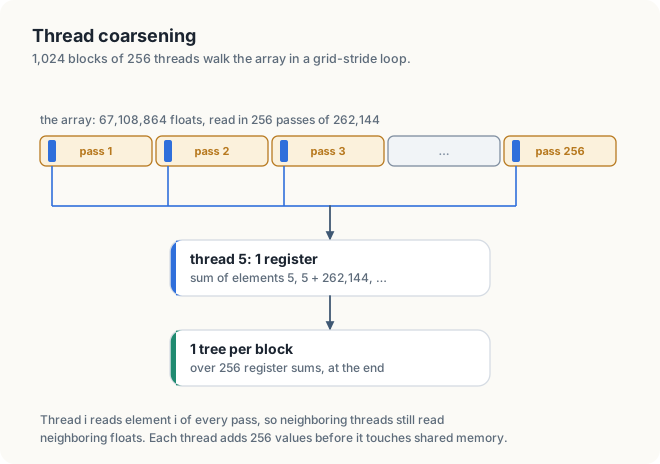
Thread coarsening assigns many elements to each thread instead of 1. Each thread first sums its elements in a register, and the block’s tree then combines the 256 register sums once, at the end. The elements are assigned by the grid-stride loop of Chapter 7, section 7.3: thread \(i\) of a grid of \(s\) threads reads elements \(i\), \(i + s\), \(i + 2s\), and so on.
The program launches 1,024 blocks of 256 threads, so \(s\) = 262,144 threads, and each thread adds 67,108,864 / 262,144 = 256 elements (figure 8.3). 1,024 blocks are several times as many as either GPU can hold at once, so no SM runs out of work. They are also few enough that the second launch adds only 1,024 partial sums.
Listing 8.2 The coarsened sum.
mod kernels {
// ...
/// 2. Each thread first sums many elements in a register, then 1 tree per block.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_coarse(input: &[f32], mut partial: DisjointSlice<f32>) {
static mut S: SharedArray<f32, 256> = SharedArray::UNINIT;
let t = thread::threadIdx_x() as usize;
let grid = (thread::gridDim_x() * BLOCK) as usize;
let mut sum = 0.0;
let mut i = thread::index_1d().get();
while i < input.len() {
sum += input[i];
i += grid;
}
// SAFETY: each thread writes only its own slot, before the first barrier.
unsafe { S[t] = sum };
let mut step: usize = 0;
#[unroll]
while step < 8 {
let stride = (BLOCK as usize / 2) >> step; // 128, 64, ... 1
thread::sync_threads();
if t < stride {
// SAFETY: between 2 barriers thread t alone writes slot t, and it reads
// slot t + stride, which no thread writes at this stride.
unsafe { S[t] += S[t + stride] };
}
step += 1;
}
if t == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = S[0] };
}
}
// ...
}// 2. Each thread first sums many elements in a register, then 1 tree per block.
__global__ void sumCoarse(const float* in, float* partial, int n)
{
__shared__ float s[BLOCK];
float sum = 0.0f;
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n; i += gridDim.x * BLOCK) {
sum += in[i];
}
s[threadIdx.x] = sum;
for (int stride = BLOCK / 2; stride > 0; stride /= 2) {
__syncthreads();
if (threadIdx.x < stride) {
s[threadIdx.x] += s[threadIdx.x + stride];
}
}
if (threadIdx.x == 0) {
partial[blockIdx.x] = s[0];
}
}
In every pass of the loop, neighboring threads read neighboring floats, so the loads of each warp are coalesced. The loads of different passes do not depend on each other, so a thread can have several of them in flight while the memory serves them.
coarsened 4.19 ms 64.1 GB/s sum 33557632.0 # Orin NX
coarsened 1.32 ms 203.0 GB/s sum 33557632.0 # Thor
With 256 loads per tree instead of 1, the same kernel structure ran 2.5 times as fast on the first GPU and 2.3 times as fast on the second. The tree still costs 8 barriers per block, but a block now pays that cost once for 65,536 values instead of once for 256 values.
8.5 Warp shuffles
8.5.1 Shuffle instructions
A lane is the position of a thread within its warp, from 0 to 31; for a 1-D block it is
threadIdx.x % 32. A warp shuffle is an instruction with which the lanes of a warp read each
other’s registers, without shared memory and without a barrier. In
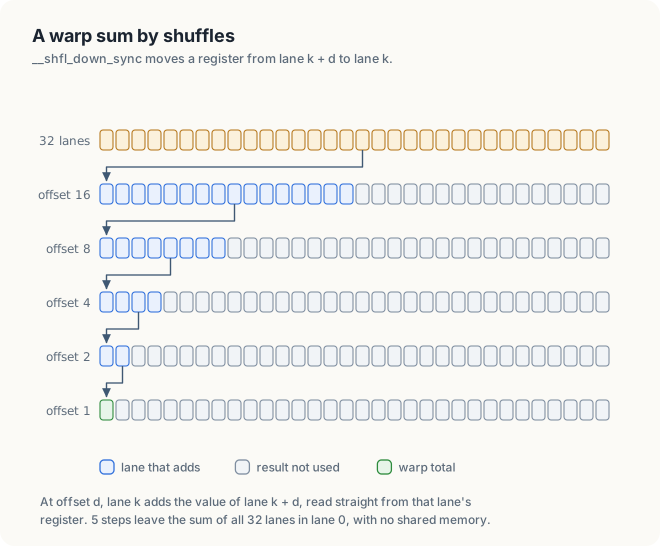
__shfl_down_sync(mask, v, d), every lane supplies its value v, and lane \(k\) receives the
value of lane \(k + d\). A lane for which \(k + d\) is above 31 receives its own value. The
mask names the lanes that take part, 0xffffffff for all 32, and each of these lanes must
execute the call. In Rust the same instruction is warp::shuffle_down_f32(v, d).
A warp is reduced with 5 shuffles. At offset 16, lanes 0 to 15 add the values of lanes 16 to 31. At offset 8, lanes 0 to 7 add the values of lanes 8 to 15, and so on down to offset 1, after which lane 0 holds the sum of all 32 values (figure 8.4). The other lanes hold partial sums that the program does not use. The number 5 is \(\log_2 32\), the depth of a tree over 32 values.
8.5.2 A block reduction with warp shuffles
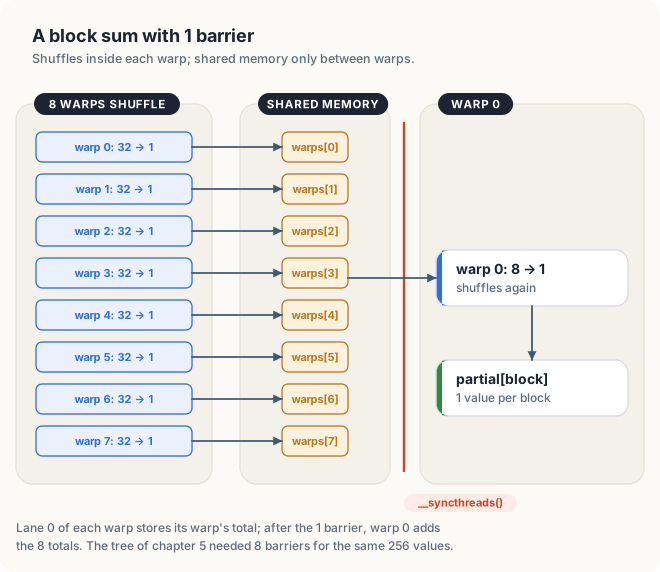
A block of 256 threads consists of 8 warps. Each warp reduces its 32 values by shuffles, and lane 0 of each warp writes the warp’s total into 1 of 8 slots in shared memory. A single barrier makes the 8 totals visible to all threads, and warp 0 then reduces them by shuffles (figure 8.5). The tree of section 8.3 needed 8 barriers for the same 256 values; this version needs 1.
Listing 8.3 Warp sum, block sum, and the shuffle kernel.
mod kernels {
// ...
#[device]
fn warp_sum(mut v: f32) -> f32 {
for offset in [16, 8, 4, 2, 1] {
v += warp::shuffle_down_f32(v, offset);
}
v
}
// ...
}
mod kernels {
// ...
/// Each thread sums many elements, each warp shuffles, 1 barrier per block.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_shuffle(input: &[f32], mut partial: DisjointSlice<f32>) {
static mut WARPS: SharedArray<f32, 8> = SharedArray::UNINIT;
let stride = (thread::gridDim_x() * BLOCK) as usize;
let lane = warp::lane_id() as usize;
let warp = thread::threadIdx_x() as usize / 32;
let mut sum = 0.0;
let mut i = thread::index_1d().get();
while i < input.len() {
sum += input[i];
i += stride;
}
sum = warp_sum(sum);
if lane == 0 {
// SAFETY: lane 0 of each warp writes its own slot, before the barrier.
unsafe { WARPS[warp] = sum };
}
thread::sync_threads();
if warp == 0 {
// SAFETY: after the barrier the slots are only read.
sum = warp_sum(if lane < 8 { unsafe { WARPS[lane] } } else { 0.0 });
if lane == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = sum };
}
}
}
// ...
}// 3. Shuffles within each warp, and 1 barrier per block.
__device__ float warpSum(float v)
{
for (int offset = 16; offset > 0; offset /= 2) {
v += __shfl_down_sync(0xffffffff, v, offset);
}
return v; // the warp's total, in lane 0
}
__device__ float blockSum(float v)
{
__shared__ float warps[BLOCK / 32];
int lane = threadIdx.x % 32;
int warp = threadIdx.x / 32;
v = warpSum(v);
if (lane == 0) {
warps[warp] = v;
}
__syncthreads();
if (warp == 0) {
v = warpSum(lane < BLOCK / 32 ? warps[lane] : 0.0f);
}
return v; // the block's total, in thread 0
}
__global__ void sumShuffle(const float* in, float* partial, int n)
{
float sum = 0.0f;
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n; i += gridDim.x * BLOCK) {
sum += in[i];
}
sum = blockSum(sum);
if (threadIdx.x == 0) {
partial[blockIdx.x] = sum;
}
}
In blockSum, lanes 8 to 31 of warp 0 contribute 0, the identity value of addition, so the second
call of warpSum adds exactly the 8 warp totals. Only warp 0 makes this second call, and all 32 of
its lanes make it, as the mask requires.
The Rust kernel has the same structure. The attribute #[device] marks warp_sum as a function
that runs on the GPU and is called from kernels. Thread 0 of each block writes the block’s partial
sum at an index that is not the thread’s own. The write therefore uses get_unchecked_mut, with a
SAFETY comment, as the transpose of Chapter 7 did.
shuffles 4.17 ms 64.4 GB/s sum 33557632.0 # Orin NX
shuffles 1.31 ms 203.6 GB/s sum 33557632.0 # Thor
The shuffles made almost no difference: 64.4 GB/s against 64.1 GB/s on the first GPU, and 203.6 GB/s against 203.0 GB/s on the second. After coarsening, a block runs its tree once per 65,536 values, so the 8 barriers had become a small part of its time, and removing 7 of them saved little. Shuffles are worthwhile where the combining step is frequent: in many short reductions, such as 1 per row of a matrix, and in the scans of section 8.7, which perform a shuffle-based scan in every block.
8.6 Vector loads and reproducible results
8.6.1 Vector loads with float4
The last stage replaces each float load with a float4 load, the 16-byte load of Chapter 7,
section 7.6. Each thread now adds 4 floats per load instruction, and the loop runs a quarter as
many iterations.
Listing 8.4 The shuffle sum with 16-byte loads.
mod kernels {
// ...
/// The sum of `v` over the 256 threads of a block, returned to thread 0.
#[device]
fn block_sum(v: f32) -> f32 {
static mut WARPS: SharedArray<f32, 8> = SharedArray::UNINIT;
let lane = warp::lane_id() as usize;
let warp = thread::threadIdx_x() as usize / 32;
let v = warp_sum(v);
if lane == 0 {
// SAFETY: lane 0 of each warp writes its own slot, before the barrier.
unsafe { WARPS[warp] = v };
}
thread::sync_threads();
// SAFETY: after the barrier the slots are only read.
let w = if lane < 8 { unsafe { WARPS[lane] } } else { 0.0 };
if warp == 0 { warp_sum(w) } else { 0.0 }
}
// ...
}
mod kernels {
// ...
/// 4. The shuffle sum, loading 4 floats per instruction.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_shuffle4(input: &[f32], mut partial: DisjointSlice<f32>) {
let quads = vector::as_vectors::<F32x4>(input).unwrap_or(&[]);
let grid = (thread::gridDim_x() * BLOCK) as usize;
let mut sum = 0.0;
let mut i = thread::index_1d().get();
while i < quads.len() {
let [x, y, z, w] = quads[i].to_array();
sum += x + y + z + w;
i += grid;
}
let sum = block_sum(sum);
if thread::threadIdx_x() == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = sum };
}
}
// ...
}// 4. The same, loading 4 floats per instruction; n4 is the number of float4s.
__global__ void sumShuffle4(const float4* in, float* partial, int n4)
{
float sum = 0.0f;
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n4; i += gridDim.x * BLOCK) {
float4 v = in[i];
sum += v.x + v.y + v.z + v.w;
}
sum = blockSum(sum);
if (threadIdx.x == 0) {
partial[blockIdx.x] = sum;
}
}
Listing 8.5 times the 4 stages. Each run consists of 2 launches: the stage itself, and 1 block of
sumShuffle over its partial sums.
Listing 8.5 Timing the 4 stages.
/// Prints a stage's time and bandwidth over `n` floats, and the sum it left in `total`.
fn report(
stream: &Arc<CudaStream>,
name: &str,
ms: f64,
n: usize,
total: &DeviceBuffer<f32>,
) -> Result<(), Error> {
let sum = total.to_host_vec(stream)?[0];
let gb = (n * 4) as f64 / 1e9 / (ms / 1e3);
println!(" {name:22} {ms:6.2} ms {gb:6.1} GB/s sum {sum:.1}");
Ok(())
}
/// Times the 4 stages of the sum. A run is the stage, then 1 block over its partial sums.
fn sums(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
input: &DeviceBuffer<f32>,
) -> Result<(), Error> {
let n = input.len();
let mut leaves = DeviceBuffer::<f32>::zeroed(stream, n / BLOCK as usize)?;
let mut partial = DeviceBuffer::<f32>::zeroed(stream, GRID as usize)?;
let mut total = DeviceBuffer::<f32>::zeroed(stream, 1)?;
let full = LaunchConfig1D::new(GRID, BLOCK, 0);
let tree = module.prepare_sum_tree(LaunchConfig1D::new(n as u32 / BLOCK, BLOCK, 0))?;
let coarse = module.prepare_sum_coarse(full)?;
let shuffle = module.prepare_sum_shuffle(full)?;
let shuffle4 = module.prepare_sum_shuffle4(full)?;
let last = module.prepare_sum_shuffle(LaunchConfig1D::new(1, BLOCK, 0))?;
println!("sum of {n} floats, the 4 stages, average of 20 runs");
let ms = time_ms(stream, || {
module.sum_tree(stream, &tree, input, &mut leaves)?;
Ok(module.sum_shuffle(stream, &last, &leaves, &mut total)?)
})?;
report(stream, "tree, 1 per thread", ms, n, &total)?;
let ms = time_ms(stream, || {
module.sum_coarse(stream, &coarse, input, &mut partial)?;
Ok(module.sum_shuffle(stream, &last, &partial, &mut total)?)
})?;
report(stream, "coarsened", ms, n, &total)?;
let ms = time_ms(stream, || {
module.sum_shuffle(stream, &shuffle, input, &mut partial)?;
Ok(module.sum_shuffle(stream, &last, &partial, &mut total)?)
})?;
report(stream, "shuffles", ms, n, &total)?;
let ms = time_ms(stream, || {
module.sum_shuffle4(stream, &shuffle4, input, &mut partial)?;
Ok(module.sum_shuffle(stream, &last, &partial, &mut total)?)
})?;
report(stream, "shuffles, F32x4", ms, n, &total)
}void sums(const float* in, float* partial, float* total, int n)
{
double bytes = n * sizeof(float);
std::printf("sum of %d floats (%d MiB), average of 20 runs\n", n, int(bytes) >> 20);
auto finish = [&](int blocks) { sumShuffle<<<1, BLOCK>>>(partial, total, blocks); };
auto report = [&](const char* name, double ms) {
float t;
check(cudaMemcpy(&t, total, sizeof(float), cudaMemcpyDeviceToHost));
double gb = bytes / ms / 1e6;
std::printf(" %-22s %6.2f ms %6.1f GB/s sum %.1f\n", name, ms, gb, t);
};
report("tree, 1 per thread", timeKernel([&] {
sumTree<<<n / BLOCK, BLOCK>>>(in, partial, n);
finish(n / BLOCK);
}));
report("coarsened", timeKernel([&] {
sumCoarse<<<GRID, BLOCK>>>(in, partial, n);
finish(GRID);
}));
report("shuffles", timeKernel([&] {
sumShuffle<<<GRID, BLOCK>>>(in, partial, n);
finish(GRID);
}));
report("shuffles, float4", timeKernel([&] {
sumShuffle4<<<GRID, BLOCK>>>((const float4*)in, partial, n / 4);
finish(GRID);
}));
}
$ ./reduce # on a Jetson Orin NX
GPU: Orin, 8 SMs, L2 cache 2 MiB
sum of 67108864 floats (256 MiB), average of 20 runs
tree, 1 per thread 10.36 ms 25.9 GB/s sum 33557628.0
coarsened 4.19 ms 64.1 GB/s sum 33557632.0
shuffles 4.17 ms 64.4 GB/s sum 33557632.0
shuffles, float4 2.99 ms 89.7 GB/s sum 33557628.0
exact sum (double) 33557630.3
CPU, float, 1 by 1 16777216.0
GPU, shuffles, 5 runs 33557632.0 33557632.0 33557632.0 33557632.0 33557632.0
$ ./reduce # on a Jetson AGX Thor
GPU: NVIDIA Thor, 20 SMs, L2 cache 32 MiB
sum of 67108864 floats (256 MiB), average of 20 runs
tree, 1 per thread 3.04 ms 88.3 GB/s sum 33557628.0
coarsened 1.32 ms 203.0 GB/s sum 33557632.0
shuffles 1.32 ms 203.6 GB/s sum 33557632.0
shuffles, float4 1.02 ms 264.2 GB/s sum 33557628.0
$ cargo oxide run # on a Jetson Orin NX, then a Thor
sum of 67108864 floats, average of 20 runs
shuffles 4.13 ms 65.0 GB/s sum 33557632.0
shuffles 1.33 ms 201.2 GB/s sum 33557632.0
With float4 loads, the sum read its 256 MiB at 89.7 GB/s on the first GPU, 88% of its rated
102 GB/s, and at 264.2 GB/s on the second, 97% of its rated 273 GB/s (figure 8.6). Together, the 4
stages made the sum 3.5 times as fast on the first GPU and 3.0 times as fast on the second.
Section 8.1.3 predicted 2.63 ms and 0.98 ms at the full rated bandwidth, and the measured 2.99 ms
and 1.02 ms are close to both predictions. The Rust shuffle kernel matched the C++ shuffle
stage.
8.6.2 Reproducibility of the sum
The 5 runs of the shuffle sum printed the same value, 33,557,632.0, and the Rust kernel printed it
as well. The float sum by atomicAdd in Chapter 5 gave a different answer on each run, because
the threads added their values in whatever order they arrived. In a tree, the code determines the
order. Thread \(i\) always adds the same elements in the same order, each warp always shuffles
the same pairs, and the second launch always adds the 1,024 partial sums in the same way. The same
order of additions produces the same roundings and therefore the same bits.
Note, however, that the order depends on the shape of the launch. The tree with one element per
thread and the float4 version group the values differently from the coarsened versions, and
both printed 33,557,628.0, 1 float step lower. A program that must reproduce its results across
machines must therefore fix its block size and grid size, not only its algorithm.
A sum runs with 512 blocks instead of 1,024. Will its answer match the 1,024-block answer bit for bit?
Not necessarily. With 512 blocks, thread \(i\) reads elements \(i\), \(i + 131{,}072\), …, a different set from the 1,024-block grid, so the partial sums round differently. The answer is still the same on every run with 512 blocks.
8.7 Scan
8.7.1 Inclusive and exclusive scan
An inclusive scan of an array \(a\) computes, at every position \(i\), the sum of elements 0 to \(i\): \(y_i = a_0 + a_1 + \cdots + a_i\). An exclusive scan leaves out element \(i\) itself: \(y_i = a_0 + \cdots + a_{i-1}\), with \(y_0 = 0\). Scans are also called prefix sums, because \(y_i\) is the sum of the prefix of the array that ends at \(i\).
| \(i\) | 0 | 1 | 2 | 3 | 4 | 5 | 6 | 7 |
|---|---|---|---|---|---|---|---|---|
| \(a_i\) | 3 | 1 | 4 | 1 | 5 | 9 | 2 | 6 |
| inclusive | 3 | 4 | 8 | 9 | 14 | 23 | 25 | 31 |
| exclusive | 0 | 3 | 4 | 8 | 9 | 14 | 23 | 25 |
A scan gives each element the position at which it is stored when selected elements are packed together. For this reason, it is the core of stream compaction, which keeps the elements that pass a test and stores them contiguously in a shorter array. For example, to keep the values above 3 from 3, 1, 4, 1, 5, 9, 2, 6, we first set a flag of 1 for each value above 3, which gives 0, 0, 1, 0, 1, 1, 0, 1. The exclusive scan of the flags is 0, 0, 0, 1, 1, 2, 3, 3. Each kept value is then written to the position given by its scan value: 4 to position 0, 5 to position 1, 9 to position 2 and 6 to position 3. The output is 4, 5, 9, 6, and its length, 4, is the last scan value plus the last flag.
Because every thread computes its output position independently, all threads can write at the same time. Radix sort, the allocation of outputs of varying size, and sparse matrix formats use scans in the same way.
8.7.2 Warp-level scan
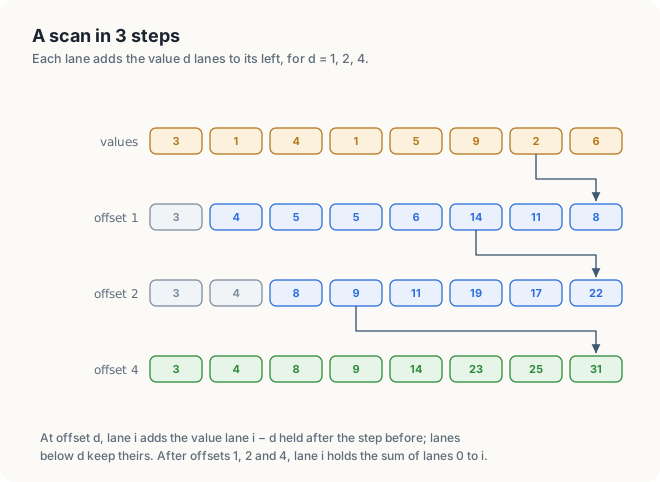
A scan within a warp uses the opposite shuffle, __shfl_up_sync, in which lane \(k\) receives
the value of lane \(k - d\). At offset 1, every lane from lane 1 upwards adds the value of the
lane to its left. Each lane then holds the sum of 2 values, and at offset 2 it adds the sum of the
2 values before those; at offset 4, it adds the sum of the 4 values before those. After offsets
1, 2 and 4, each of 8 lanes holds the sum of all lanes up to and including its own (figure 8.7).
A warp of 32 lanes needs 5 offsets, 1 to 16.
Animation 1 shows the values moving at each of the 3 offsets.
Listing 8.6 A warp scan.
mod kernels {
// ...
#[device]
fn warp_scan(mut v: u32) -> u32 {
let lane = warp::lane_id();
for offset in [1, 2, 4, 8, 16] {
let left = warp::shuffle_up_sync(u32::MAX, v, offset);
if lane >= offset {
v += left;
}
}
v
}
// ...
}// 5. An inclusive scan, 4 elements per thread, 1,024 per block.
__device__ unsigned warpScan(unsigned v)
{
int lane = threadIdx.x % 32;
for (int offset = 1; offset < 32; offset *= 2) {
unsigned left = __shfl_up_sync(0xffffffff, v, offset);
if (lane >= offset) {
v += left;
}
}
return v; // the sum of lanes 0 to `lane`
}
This form of scan performs more work than a sequential scan. At offset \(d\), \(32 - d\) lanes perform an addition, so a warp performs 31 + 30 + 28 + 24 + 16 = 129 additions where a sequential chain needs 31. Within a warp, the extra additions add no time: the 32 lanes execute every step together whether or not a lane adds, and 5 steps take less time than 31. For large scans in shared memory, the work-efficient algorithm due to Blelloch performs \(2(n - 1)\) additions in \(2 \log_2 n\) steps instead; Exercise 6 traces it.
8.7.3 Block-level scan
The kernel scanBlocks scans 1,024 values per block of 256 threads, 4 values per thread, in 4
phases:
- We let each thread load its 4 consecutive values with a single 16-byte
uint4load and scan them in its registers. - The threads scan their 4-value totals with
warpScan. Lane 31 of each warp then holds the total of its warp and writes it to shared memory. - After a barrier, warp 0 scans the 8 warp totals.
- After a second barrier, each thread adds 2 offsets to its 4 values: the total of the warps before its own, and the total of the lanes before it in its own warp.
Listing 8.7 A scan of 1,024 values per block.
mod kernels {
// ...
/// An inclusive scan of 1,024 values per block, 4 per thread.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scan_blocks(
input: &[u32],
mut out: DisjointSlice<u32>,
mut sums: DisjointSlice<u32>,
) {
static mut WARPS: SharedArray<u32, 8> = SharedArray::UNINIT;
let first = thread::index_1d().get() * 4;
let lane = warp::lane_id() as usize;
let warp = thread::threadIdx_x() as usize / 32;
let mut a = [0u32; 4];
let mut own = 0;
for k in 0..4 {
if first + k < input.len() {
own += input[first + k];
}
a[k] = own;
}
let v = warp_scan(own);
if lane == 31 {
// SAFETY: lane 31 of each warp writes its own slot, before the barrier.
unsafe { WARPS[warp] = v };
}
thread::sync_threads();
if warp == 0 {
// SAFETY: only warp 0 touches the slots between the 2 barriers.
let w = warp_scan(if lane < 8 { unsafe { WARPS[lane] } } else { 0 });
if lane < 8 {
unsafe { WARPS[lane] = w };
}
}
thread::sync_threads();
// SAFETY: after the second barrier the slots are only read.
let before = v - own + if warp > 0 { unsafe { WARPS[warp - 1] } } else { 0 };
for k in 0..4 {
if first + k < out.len() {
// SAFETY: thread t alone writes elements 4t to 4t + 3.
unsafe { *out.get_unchecked_mut(first + k) = before + a[k] };
}
}
if thread::threadIdx_x() == BLOCK - 1 {
let block = thread::blockIdx_x() as usize;
// SAFETY: only the last thread of each block writes, at its own block number.
unsafe { *sums.get_unchecked_mut(block) = before + a[3] };
}
}
// ...
}__global__ void scanBlocks(const uint4* in, uint4* out, unsigned* sums, int n4)
{
__shared__ unsigned warps[BLOCK / 32];
int i = blockIdx.x * BLOCK + threadIdx.x;
int lane = threadIdx.x % 32;
int warp = threadIdx.x / 32;
uint4 a = i < n4 ? in[i] : make_uint4(0, 0, 0, 0);
a.y += a.x; // the thread's own 4 values, scanned
a.z += a.y;
a.w += a.z;
unsigned v = warpScan(a.w);
if (lane == 31) {
warps[warp] = v;
}
__syncthreads();
if (warp == 0) {
unsigned w = warpScan(lane < BLOCK / 32 ? warps[lane] : 0);
if (lane < BLOCK / 32) {
warps[lane] = w;
}
}
__syncthreads();
unsigned before = v - a.w + (warp > 0 ? warps[warp - 1] : 0);
a = make_uint4(before + a.x, before + a.y, before + a.z, before + a.w);
if (i < n4) {
out[i] = a;
}
if (threadIdx.x == BLOCK - 1) {
sums[blockIdx.x] = a.w;
}
}
The expression v - a.w computes the second offset. The variable v holds the inclusive warp
scan at this lane, and subtracting the lane’s own total a.w leaves the sum of the lanes before
it. The last thread of the block writes the block’s total to sums.
8.7.4 Hierarchical scan across blocks
Blocks cannot read each other’s results while a kernel runs, so an array larger than 1 block is scanned in 3 steps (figure 8.8):
- every block scans its 1,024 values and writes its total;
- the block totals are scanned, by the same function;
- every value of block \(b\) has the scanned total of blocks 0 to \(b - 1\) added to it.
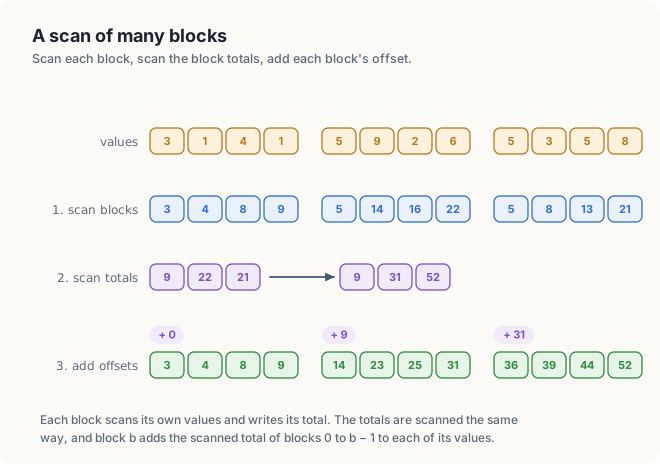
For 67,108,864 values, step 1 runs 65,536 blocks and writes 65,536 totals. Scanning these totals is
the same problem, 1,024 times smaller: 64 blocks, whose 64 totals fit in 1 block. The C++ function
scan therefore calls itself for step 2 until a single block remains. Animation 2 shows the 3
steps on the 12 values of the figure.
Listing 8.8 Adding the offsets, and the whole scan.
mod kernels {
// ...
/// Adds to every value of block b the total of blocks 0 to b - 1.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn add_offsets(mut out: DisjointSlice<u32>, scanned: &[u32]) {
let block = thread::blockIdx_x() as usize;
let first = thread::index_1d().get() * 4;
if block > 0 {
for k in 0..4 {
if first + k < out.len() {
// SAFETY: thread t alone writes elements 4t to 4t + 3.
unsafe { *out.get_unchecked_mut(first + k) += scanned[block - 1] };
}
}
}
}
// ...
}
/// Buffers for the block totals and their scan, per level: n / 1,024, / 1,024 again, ... 1.
fn levels(stream: &Arc<CudaStream>, mut n: usize) -> Result<Levels, Error> {
let mut levels = Vec::new();
while n > 1 {
n = n.div_ceil(1024);
let totals = DeviceBuffer::<u32>::zeroed(stream, n)?;
let scanned = DeviceBuffer::<u32>::zeroed(stream, n)?;
levels.push((totals, scanned));
}
Ok(levels)
}
/// Scans each block, then the block totals (by the same function), then adds them.
fn scan(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
input: &DeviceBuffer<u32>,
out: &mut DeviceBuffer<u32>,
levels: &mut [(DeviceBuffer<u32>, DeviceBuffer<u32>)],
) -> Result<(), Error> {
let blocks = input.len().div_ceil(1024) as u32;
let config = LaunchConfig1D::new(blocks, BLOCK, 0);
let ((totals, scanned), rest) = levels.split_first_mut().ok_or("no level left")?;
module.scan_blocks(stream, &module.prepare_scan_blocks(config)?, input, out, totals)?;
if blocks > 1 {
scan(module, stream, totals, scanned, rest)?;
module.add_offsets(stream, &module.prepare_add_offsets(config)?, out, scanned)?;
}
Ok(())
}__global__ void addOffsets(uint4* out, const unsigned* sums, int n4)
{
int i = blockIdx.x * BLOCK + threadIdx.x;
if (blockIdx.x > 0 && i < n4) {
unsigned s = sums[blockIdx.x - 1];
uint4 a = out[i];
out[i] = make_uint4(a.x + s, a.y + s, a.z + s, a.w + s);
}
}
// Scans each block, then the block totals (by the same function), then adds them.
// n is a multiple of 4. The totals are padded to a multiple of 4 as well: the padding
// comes after the last real total, so it changes none of the sums that are used.
void scan(const unsigned* in, unsigned* out, int n, unsigned* scratch)
{
int blocks = (n / 4 + BLOCK - 1) / BLOCK;
scanBlocks<<<blocks, BLOCK>>>((const uint4*)in, (uint4*)out, scratch, n / 4);
if (blocks > 1) {
int padded = (blocks + 3) / 4 * 4;
scan(scratch, scratch, padded, scratch + padded);
addOffsets<<<blocks, BLOCK>>>((uint4*)out, scratch, n / 4);
}
}
The totals of each level are scanned in place, in scratch, which holds all levels one after
another. The number of totals is rounded up to a multiple of 4, so that the next level can load
them as uint4. The rounding adds unused values after the last real total. Because an inclusive
scan never carries a value backwards, these values change none of the sums that are used.
The Rust version loads its 4 values with 4 ordinary loads and writes them through
get_unchecked_mut, because thread \(t\) writes elements \(4t\) to \(4t + 3\) rather than
element \(t\). A Rust function cannot borrow 1 buffer as both input and output, so each level
has its own pair of buffers, totals and scanned, which are allocated before the timing starts.
8.7.5 Performance of the scan
The test scans 67,108,864 random values from 0 to 3 and checks every result against a scan computed on the CPU. The reported bandwidth counts the bytes that the job requires: the input read once and the output written once, 2 × 256 MiB.
inclusive scan of 67108864 values # Orin NX
13.19 ms 40.7 GB/s last 100652862 correct: yes
inclusive scan of 67108864 values # Thor
5.88 ms 91.4 GB/s last 100652862 correct: yes
$ cargo oxide run # Orin NX, then Thor
inclusive scan of 67108864 values
19.38 ms 27.7 GB/s last 100652862 correct: yes
inclusive scan of 67108864 values
5.48 ms 98.0 GB/s last 100652862 correct: yes
Every value matched the CPU scan. The 3 steps, however, move more bytes than the job requires. Step 1 reads the input and writes the output, and step 3 reads the output and writes it again, so 4 × 256 MiB cross the memory in all. The memory therefore moved about 2 × 40.7 = 81 GB/s on the first GPU and 2 × 91.4 = 183 GB/s on the second, 80% and 67% of their rated bandwidth. A single-pass scan passes each block’s total directly to the next block while the kernel runs, so that each value is read once and written once. The CUB library of Chapter 11 provides one. The Rust scan, which uses 4 ordinary loads per thread, ran slower than the C++ scan on the first GPU and faster on the second in this run; over several runs, its bandwidth on the second GPU varied between 96 and 128 GB/s.
8.8 Histogram with wide loads
In Chapter 5, section 5.5.2, we privatized a histogram of bytes. Each block counts into 256 bins
in shared memory and adds them to the global bins once. This made the kernel 6 to 28 times as fast
as the version with global atomics. Measured as a bandwidth, however, its speed was still low.
Listing 5.7, run here as histBytes, read 64 MiB at 13.7 GB/s on the first GPU, 13% of the
memory’s rated bandwidth.
An input in which every byte is 7 shows where the time goes. In that case, every atomic operation of a warp targets the same bin, which is the worst possible contention. Yet these bytes were counted no more slowly than random bytes: 16.8 GB/s against 13.7 GB/s. Contention was therefore not the limit. Each byte cost 1 load instruction, and the 1-byte loads of a warp fetch only 32 bytes, 1 sector, per instruction. The kernel was limited by its loads.
The kernel histWords reads 16 bytes per thread with a single uint4 load, 512 bytes per warp.
It extracts the 4 bytes of each 32-bit word by shifting and masking: (w >> 8 * k) & 255 is byte
\(k\) of the word w.
Listing 8.9 A histogram reading 16 bytes per load.
mod kernels {
// ...
/// Adds the 4 bytes of the word `w` to the 256 shared bins that start at `local`.
#[device]
fn count_word(local: *mut u32, w: u32) {
let mut k = 0;
#[unroll]
while k < 4 {
let byte = (w >> (8 * k)) & 255;
// SAFETY: `local` points to 256 bins and byte < 256. Every access to the bins
// between the 2 barriers of the kernel is atomic.
let bin = unsafe { BlockAtomicU32::from_ptr(local.add(byte as usize)) };
bin.fetch_add(1, AtomicOrdering::Relaxed);
k += 1;
}
}
// ...
}
mod kernels {
// ...
/// A histogram of bytes in shared bins, reading 16 bytes per load.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn hist_quads(words: &[u32], bins: &[DeviceAtomicU32]) {
static mut LOCAL: SharedArray<u32, 256> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
let quads = vector::as_vectors::<U32x4>(words).unwrap_or(&[]);
// SAFETY: each thread zeroes only its own bin, before the barrier.
unsafe { LOCAL[tid] = 0 };
thread::sync_threads();
// SAFETY: the pointer is only used through atomics, between the 2 barriers.
let local = unsafe { (*&raw mut LOCAL).as_mut_ptr() };
let grid = (thread::gridDim_x() * BLOCK) as usize;
let mut i = thread::index_1d().get();
while i < quads.len() {
let [x, y, z, w] = quads[i].to_array();
count_word(local, x);
count_word(local, y);
count_word(local, z);
count_word(local, w);
i += grid;
}
thread::sync_threads();
// SAFETY: after the barrier no thread writes LOCAL again.
let local = unsafe { LOCAL[tid] };
bins[tid].fetch_add(local, AtomicOrdering::Relaxed);
}
}__device__ void countWord(unsigned* local, unsigned w)
{
for (int k = 0; k < 4; ++k) {
atomicAdd(&local[(w >> 8 * k) & 255], 1u);
}
}
__global__ void histWords(const uint4* data, unsigned* bins, int n16)
{
__shared__ unsigned local[256];
local[threadIdx.x] = 0;
__syncthreads();
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n16; i += gridDim.x * BLOCK) {
uint4 q = data[i];
countWord(local, q.x);
countWord(local, q.y);
countWord(local, q.z);
countWord(local, q.w);
}
__syncthreads();
atomicAdd(&bins[threadIdx.x], local[threadIdx.x]);
}
histogram of 64 MiB, average of 20 runs # Orin NX
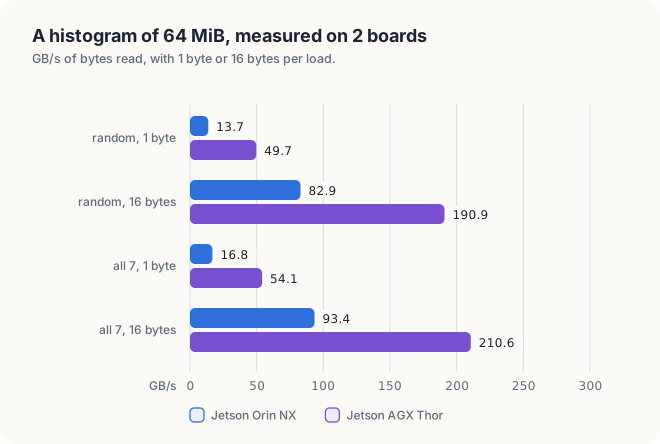
random bytes 1 byte per load 4.92 ms 13.7 GB/s
random bytes 16 bytes per load 0.81 ms 82.9 GB/s total 67108864
all 7 1 byte per load 3.99 ms 16.8 GB/s
all 7 16 bytes per load 0.72 ms 93.4 GB/s total 67108864
histogram of 64 MiB, average of 20 runs # Thor
random bytes 1 byte per load 1.35 ms 49.7 GB/s
random bytes 16 bytes per load 0.35 ms 190.9 GB/s total 67108864
all 7 1 byte per load 1.24 ms 54.1 GB/s
all 7 16 bytes per load 0.32 ms 210.6 GB/s total 67108864
With 16-byte loads, the same atomic operations ran 6.1 times as fast for random bytes on the first GPU and 3.8 times as fast on the second, which is 81% and 70% of rated bandwidth (figure 8.9). Every total is 67,108,864, 1 count per byte. A version with 1 set of 256 bins per warp, intended to reduce contention further, was also measured. It ran no faster on either GPU, so the listing leaves it out.
Listing 8.10 reads 4-byte words, 4 bytes per load:
Listing 8.10 A histogram reading 4 bytes per load.
mod kernels {
// ...
/// A histogram of bytes in shared bins, reading 4 bytes per load.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn hist_words(words: &[u32], bins: &[DeviceAtomicU32]) {
static mut LOCAL: SharedArray<u32, 256> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
// SAFETY: each thread zeroes only its own bin, before the barrier.
unsafe { LOCAL[tid] = 0 };
thread::sync_threads();
let stride = (thread::gridDim_x() * BLOCK) as usize;
let mut i = thread::index_1d().get();
while i < words.len() {
for k in 0..4 {
let byte = (words[i] >> (8 * k)) & 255;
// SAFETY: between the 2 barriers every access to LOCAL is atomic.
let bin = unsafe {
let base = (*&raw mut LOCAL).as_mut_ptr();
BlockAtomicU32::from_ptr(base.add(byte as usize))
};
bin.fetch_add(1, AtomicOrdering::Relaxed);
}
i += stride;
}
thread::sync_threads();
// SAFETY: after the barrier no thread writes LOCAL again.
let local = unsafe { LOCAL[tid] };
bins[tid].fetch_add(local, AtomicOrdering::Relaxed);
}
// ...
}__global__ void histUint(const unsigned* data, unsigned* bins, int n4)
{
__shared__ unsigned local[256];
local[threadIdx.x] = 0;
__syncthreads();
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n4; i += gridDim.x * BLOCK) {
countWord(local, data[i]);
}
__syncthreads();
atomicAdd(&bins[threadIdx.x], local[threadIdx.x]);
}
$ cargo oxide run # Orin NX, then Thor
histogram of 64 MiB, 4 bytes per load
1.27 ms 52.8 GB/s total 67108864
histogram of 64 MiB, 4 bytes per load
0.38 ms 176.4 GB/s total 67108864
Loads of 4 bytes already gave 3.9 and 3.5 times the speed of 1-byte loads, and 16-byte loads provided the rest of the gain.
Measure before optimizing. The histogram was limited by its loads, not by the contention that privatization was designed to avoid.
8.9 Comparison of the 3 patterns
| Pattern | Computes | Combining step | Shared state | Measured, best stage |
|---|---|---|---|---|
| Reduction | 1 value from \(n\) | tree: registers, shuffles, 1 barrier per block, 2 launches | none | 88% and 97% of rated |
| Scan | \(n\) running sums | warp scan by shuffles, block scan, 3 steps across blocks | none | 80% and 67% of rated, counting the bytes moved |
| Histogram | counts per bin | atomics on private bins in shared memory, 1 fold per block | 256 bins | 81% and 70% of rated |
The three kernels follow the same method. Each does as much of the work as possible in registers, combines values within a warp by shuffles, and then combines the warps of a block through shared memory. It combines results across blocks only once, through global memory or a second launch. Each optimization was kept only when a measurement showed that it removed a cost.
8.10 The complete programs
Listing 8.11 The complete programs. code/oxide/ch08_reduce/src/main.rs code/ch08_reduction/reduce.cu
//! Chapter 8 in Rust: a sum in 4 stages (tree, coarsened, shuffles, 16-byte loads), a scan,
//! and histograms reading 4 and 16 bytes per load.
//!
//! cargo oxide run
use std::sync::Arc;
use std::time::Instant;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, LaunchConfig1D};
use cuda_device::atomic::{AtomicOrdering, BlockAtomicU32, DeviceAtomicU32};
use cuda_device::{DisjointSlice, SharedArray, cuda_module, device, kernel, launch_contract};
use cuda_device::vector::{self, F32x4, U32x4};
use cuda_device::{thread, warp};
const BLOCK: u32 = 256;
const GRID: u32 = 1024;
type Error = Box<dyn std::error::Error>;
type Levels = Vec<(DeviceBuffer<u32>, DeviceBuffer<u32>)>;
#[cuda_module]
mod kernels {
use super::*;
/// 1. A tree in shared memory, 1 element per thread.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_tree(input: &[f32], mut partial: DisjointSlice<f32>) {
static mut S: SharedArray<f32, 256> = SharedArray::UNINIT;
let t = thread::threadIdx_x() as usize;
let i = thread::index_1d().get();
let value = if i < input.len() { input[i] } else { 0.0 };
// SAFETY: each thread writes only its own slot, before the first barrier.
unsafe { S[t] = value };
let mut step: usize = 0;
#[unroll]
while step < 8 {
let stride = (BLOCK as usize / 2) >> step; // 128, 64, ... 1
thread::sync_threads();
if t < stride {
// SAFETY: between 2 barriers thread t alone writes slot t, and it reads
// slot t + stride, which no thread writes at this stride.
unsafe { S[t] += S[t + stride] };
}
step += 1;
}
if t == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = S[0] };
}
}
/// 2. Each thread first sums many elements in a register, then 1 tree per block.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_coarse(input: &[f32], mut partial: DisjointSlice<f32>) {
static mut S: SharedArray<f32, 256> = SharedArray::UNINIT;
let t = thread::threadIdx_x() as usize;
let grid = (thread::gridDim_x() * BLOCK) as usize;
let mut sum = 0.0;
let mut i = thread::index_1d().get();
while i < input.len() {
sum += input[i];
i += grid;
}
// SAFETY: each thread writes only its own slot, before the first barrier.
unsafe { S[t] = sum };
let mut step: usize = 0;
#[unroll]
while step < 8 {
let stride = (BLOCK as usize / 2) >> step; // 128, 64, ... 1
thread::sync_threads();
if t < stride {
// SAFETY: between 2 barriers thread t alone writes slot t, and it reads
// slot t + stride, which no thread writes at this stride.
unsafe { S[t] += S[t + stride] };
}
step += 1;
}
if t == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = S[0] };
}
}
#[device]
fn warp_sum(mut v: f32) -> f32 {
for offset in [16, 8, 4, 2, 1] {
v += warp::shuffle_down_f32(v, offset);
}
v
}
#[device]
fn warp_scan(mut v: u32) -> u32 {
let lane = warp::lane_id();
for offset in [1, 2, 4, 8, 16] {
let left = warp::shuffle_up_sync(u32::MAX, v, offset);
if lane >= offset {
v += left;
}
}
v
}
/// Each thread sums many elements, each warp shuffles, 1 barrier per block.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_shuffle(input: &[f32], mut partial: DisjointSlice<f32>) {
static mut WARPS: SharedArray<f32, 8> = SharedArray::UNINIT;
let stride = (thread::gridDim_x() * BLOCK) as usize;
let lane = warp::lane_id() as usize;
let warp = thread::threadIdx_x() as usize / 32;
let mut sum = 0.0;
let mut i = thread::index_1d().get();
while i < input.len() {
sum += input[i];
i += stride;
}
sum = warp_sum(sum);
if lane == 0 {
// SAFETY: lane 0 of each warp writes its own slot, before the barrier.
unsafe { WARPS[warp] = sum };
}
thread::sync_threads();
if warp == 0 {
// SAFETY: after the barrier the slots are only read.
sum = warp_sum(if lane < 8 { unsafe { WARPS[lane] } } else { 0.0 });
if lane == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = sum };
}
}
}
/// The sum of `v` over the 256 threads of a block, returned to thread 0.
#[device]
fn block_sum(v: f32) -> f32 {
static mut WARPS: SharedArray<f32, 8> = SharedArray::UNINIT;
let lane = warp::lane_id() as usize;
let warp = thread::threadIdx_x() as usize / 32;
let v = warp_sum(v);
if lane == 0 {
// SAFETY: lane 0 of each warp writes its own slot, before the barrier.
unsafe { WARPS[warp] = v };
}
thread::sync_threads();
// SAFETY: after the barrier the slots are only read.
let w = if lane < 8 { unsafe { WARPS[lane] } } else { 0.0 };
if warp == 0 { warp_sum(w) } else { 0.0 }
}
/// 4. The shuffle sum, loading 4 floats per instruction.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_shuffle4(input: &[f32], mut partial: DisjointSlice<f32>) {
let quads = vector::as_vectors::<F32x4>(input).unwrap_or(&[]);
let grid = (thread::gridDim_x() * BLOCK) as usize;
let mut sum = 0.0;
let mut i = thread::index_1d().get();
while i < quads.len() {
let [x, y, z, w] = quads[i].to_array();
sum += x + y + z + w;
i += grid;
}
let sum = block_sum(sum);
if thread::threadIdx_x() == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = sum };
}
}
/// An inclusive scan of 1,024 values per block, 4 per thread.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scan_blocks(
input: &[u32],
mut out: DisjointSlice<u32>,
mut sums: DisjointSlice<u32>,
) {
static mut WARPS: SharedArray<u32, 8> = SharedArray::UNINIT;
let first = thread::index_1d().get() * 4;
let lane = warp::lane_id() as usize;
let warp = thread::threadIdx_x() as usize / 32;
let mut a = [0u32; 4];
let mut own = 0;
for k in 0..4 {
if first + k < input.len() {
own += input[first + k];
}
a[k] = own;
}
let v = warp_scan(own);
if lane == 31 {
// SAFETY: lane 31 of each warp writes its own slot, before the barrier.
unsafe { WARPS[warp] = v };
}
thread::sync_threads();
if warp == 0 {
// SAFETY: only warp 0 touches the slots between the 2 barriers.
let w = warp_scan(if lane < 8 { unsafe { WARPS[lane] } } else { 0 });
if lane < 8 {
unsafe { WARPS[lane] = w };
}
}
thread::sync_threads();
// SAFETY: after the second barrier the slots are only read.
let before = v - own + if warp > 0 { unsafe { WARPS[warp - 1] } } else { 0 };
for k in 0..4 {
if first + k < out.len() {
// SAFETY: thread t alone writes elements 4t to 4t + 3.
unsafe { *out.get_unchecked_mut(first + k) = before + a[k] };
}
}
if thread::threadIdx_x() == BLOCK - 1 {
let block = thread::blockIdx_x() as usize;
// SAFETY: only the last thread of each block writes, at its own block number.
unsafe { *sums.get_unchecked_mut(block) = before + a[3] };
}
}
/// Adds to every value of block b the total of blocks 0 to b - 1.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn add_offsets(mut out: DisjointSlice<u32>, scanned: &[u32]) {
let block = thread::blockIdx_x() as usize;
let first = thread::index_1d().get() * 4;
if block > 0 {
for k in 0..4 {
if first + k < out.len() {
// SAFETY: thread t alone writes elements 4t to 4t + 3.
unsafe { *out.get_unchecked_mut(first + k) += scanned[block - 1] };
}
}
}
}
/// A histogram of bytes in shared bins, reading 4 bytes per load.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn hist_words(words: &[u32], bins: &[DeviceAtomicU32]) {
static mut LOCAL: SharedArray<u32, 256> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
// SAFETY: each thread zeroes only its own bin, before the barrier.
unsafe { LOCAL[tid] = 0 };
thread::sync_threads();
let stride = (thread::gridDim_x() * BLOCK) as usize;
let mut i = thread::index_1d().get();
while i < words.len() {
for k in 0..4 {
let byte = (words[i] >> (8 * k)) & 255;
// SAFETY: between the 2 barriers every access to LOCAL is atomic.
let bin = unsafe {
let base = (*&raw mut LOCAL).as_mut_ptr();
BlockAtomicU32::from_ptr(base.add(byte as usize))
};
bin.fetch_add(1, AtomicOrdering::Relaxed);
}
i += stride;
}
thread::sync_threads();
// SAFETY: after the barrier no thread writes LOCAL again.
let local = unsafe { LOCAL[tid] };
bins[tid].fetch_add(local, AtomicOrdering::Relaxed);
}
/// Adds the 4 bytes of the word `w` to the 256 shared bins that start at `local`.
#[device]
fn count_word(local: *mut u32, w: u32) {
let mut k = 0;
#[unroll]
while k < 4 {
let byte = (w >> (8 * k)) & 255;
// SAFETY: `local` points to 256 bins and byte < 256. Every access to the bins
// between the 2 barriers of the kernel is atomic.
let bin = unsafe { BlockAtomicU32::from_ptr(local.add(byte as usize)) };
bin.fetch_add(1, AtomicOrdering::Relaxed);
k += 1;
}
}
/// A histogram of bytes in shared bins, reading 16 bytes per load.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn hist_quads(words: &[u32], bins: &[DeviceAtomicU32]) {
static mut LOCAL: SharedArray<u32, 256> = SharedArray::UNINIT;
let tid = thread::threadIdx_x() as usize;
let quads = vector::as_vectors::<U32x4>(words).unwrap_or(&[]);
// SAFETY: each thread zeroes only its own bin, before the barrier.
unsafe { LOCAL[tid] = 0 };
thread::sync_threads();
// SAFETY: the pointer is only used through atomics, between the 2 barriers.
let local = unsafe { (*&raw mut LOCAL).as_mut_ptr() };
let grid = (thread::gridDim_x() * BLOCK) as usize;
let mut i = thread::index_1d().get();
while i < quads.len() {
let [x, y, z, w] = quads[i].to_array();
count_word(local, x);
count_word(local, y);
count_word(local, z);
count_word(local, w);
i += grid;
}
thread::sync_threads();
// SAFETY: after the barrier no thread writes LOCAL again.
let local = unsafe { LOCAL[tid] };
bins[tid].fetch_add(local, AtomicOrdering::Relaxed);
}
}
/// Average time of 20 runs of `launch`, in milliseconds, after 1 warm-up run.
fn time_ms(
stream: &Arc<CudaStream>,
mut launch: impl FnMut() -> Result<(), Error>,
) -> Result<f64, Error> {
launch()?;
stream.synchronize()?;
let start = Instant::now();
for _ in 0..20 {
launch()?;
}
stream.synchronize()?;
Ok(start.elapsed().as_secs_f64() * 1e3 / 20.0)
}
/// Prints a stage's time and bandwidth over `n` floats, and the sum it left in `total`.
fn report(
stream: &Arc<CudaStream>,
name: &str,
ms: f64,
n: usize,
total: &DeviceBuffer<f32>,
) -> Result<(), Error> {
let sum = total.to_host_vec(stream)?[0];
let gb = (n * 4) as f64 / 1e9 / (ms / 1e3);
println!(" {name:22} {ms:6.2} ms {gb:6.1} GB/s sum {sum:.1}");
Ok(())
}
/// Times the 4 stages of the sum. A run is the stage, then 1 block over its partial sums.
fn sums(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
input: &DeviceBuffer<f32>,
) -> Result<(), Error> {
let n = input.len();
let mut leaves = DeviceBuffer::<f32>::zeroed(stream, n / BLOCK as usize)?;
let mut partial = DeviceBuffer::<f32>::zeroed(stream, GRID as usize)?;
let mut total = DeviceBuffer::<f32>::zeroed(stream, 1)?;
let full = LaunchConfig1D::new(GRID, BLOCK, 0);
let tree = module.prepare_sum_tree(LaunchConfig1D::new(n as u32 / BLOCK, BLOCK, 0))?;
let coarse = module.prepare_sum_coarse(full)?;
let shuffle = module.prepare_sum_shuffle(full)?;
let shuffle4 = module.prepare_sum_shuffle4(full)?;
let last = module.prepare_sum_shuffle(LaunchConfig1D::new(1, BLOCK, 0))?;
println!("sum of {n} floats, the 4 stages, average of 20 runs");
let ms = time_ms(stream, || {
module.sum_tree(stream, &tree, input, &mut leaves)?;
Ok(module.sum_shuffle(stream, &last, &leaves, &mut total)?)
})?;
report(stream, "tree, 1 per thread", ms, n, &total)?;
let ms = time_ms(stream, || {
module.sum_coarse(stream, &coarse, input, &mut partial)?;
Ok(module.sum_shuffle(stream, &last, &partial, &mut total)?)
})?;
report(stream, "coarsened", ms, n, &total)?;
let ms = time_ms(stream, || {
module.sum_shuffle(stream, &shuffle, input, &mut partial)?;
Ok(module.sum_shuffle(stream, &last, &partial, &mut total)?)
})?;
report(stream, "shuffles", ms, n, &total)?;
let ms = time_ms(stream, || {
module.sum_shuffle4(stream, &shuffle4, input, &mut partial)?;
Ok(module.sum_shuffle(stream, &last, &partial, &mut total)?)
})?;
report(stream, "shuffles, F32x4", ms, n, &total)
}
/// Numbers from a small linear congruential generator, so the run needs no extra crate.
fn random(n: usize, seed: u32) -> Vec<u32> {
let mut state = seed;
(0..n)
.map(|_| {
state = state.wrapping_mul(1_664_525).wrapping_add(1_013_904_223);
state
})
.collect()
}
/// Buffers for the block totals and their scan, per level: n / 1,024, / 1,024 again, ... 1.
fn levels(stream: &Arc<CudaStream>, mut n: usize) -> Result<Levels, Error> {
let mut levels = Vec::new();
while n > 1 {
n = n.div_ceil(1024);
let totals = DeviceBuffer::<u32>::zeroed(stream, n)?;
let scanned = DeviceBuffer::<u32>::zeroed(stream, n)?;
levels.push((totals, scanned));
}
Ok(levels)
}
/// Scans each block, then the block totals (by the same function), then adds them.
fn scan(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
input: &DeviceBuffer<u32>,
out: &mut DeviceBuffer<u32>,
levels: &mut [(DeviceBuffer<u32>, DeviceBuffer<u32>)],
) -> Result<(), Error> {
let blocks = input.len().div_ceil(1024) as u32;
let config = LaunchConfig1D::new(blocks, BLOCK, 0);
let ((totals, scanned), rest) = levels.split_first_mut().ok_or("no level left")?;
module.scan_blocks(stream, &module.prepare_scan_blocks(config)?, input, out, totals)?;
if blocks > 1 {
scan(module, stream, totals, scanned, rest)?;
module.add_offsets(stream, &module.prepare_add_offsets(config)?, out, scanned)?;
}
Ok(())
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let n = 64 << 20;
// 1. A sum of 67,108,864 floats in [0, 1).
let values: Vec<f32> = random(n, 1)
.iter()
.map(|&r| (r >> 8) as f32 / 16_777_216.0)
.collect();
let floats = DeviceBuffer::from_host(&stream, &values)?;
let mut partial = DeviceBuffer::<f32>::zeroed(&stream, GRID as usize)?;
let mut total = DeviceBuffer::<f32>::zeroed(&stream, 1)?;
let blocks = module.prepare_sum_shuffle(LaunchConfig1D::new(GRID, BLOCK, 0))?;
let last = module.prepare_sum_shuffle(LaunchConfig1D::new(1, BLOCK, 0))?;
let mut sum = || -> Result<(), Error> {
module.sum_shuffle(&stream, &blocks, &floats, &mut partial)?;
Ok(module.sum_shuffle(&stream, &last, &partial, &mut total)?)
};
for _ in 0..10 {
time_ms(&stream, &mut sum)?; // warm up the clocks
}
let ms = time_ms(&stream, &mut sum)?;
let gpu = total.to_host_vec(&stream)?[0];
let exact: f64 = values.iter().map(|&v| v as f64).sum();
let gb = (n * 4) as f64 / 1e9 / (ms / 1e3);
println!("sum of {n} floats, average of 20 runs");
println!(" shuffles {ms:6.2} ms {gb:6.1} GB/s sum {gpu:.1}");
println!(" exact (f64) sum {exact:.1}");
// 2. An inclusive scan of values 0 to 3.
let counts: Vec<u32> = random(n, 2).iter().map(|&r| r >> 30).collect();
let input = DeviceBuffer::from_host(&stream, &counts)?;
let mut out = DeviceBuffer::<u32>::zeroed(&stream, n)?;
let mut levels = levels(&stream, n)?;
let ms = time_ms(&stream, || scan(&module, &stream, &input, &mut out, &mut levels))?;
let result = out.to_host_vec(&stream)?;
let mut running = 0u32;
let correct = counts.iter().zip(&result).all(|(&c, &r)| {
running += c;
r == running
});
let gb = (2 * n * 4) as f64 / 1e9 / (ms / 1e3);
let verdict = if correct { "yes" } else { "no" };
println!("inclusive scan of {n} values");
println!(" {ms:6.2} ms {gb:6.1} GB/s last {} correct: {verdict}", result[n - 1]);
// 3. A histogram of 64 MiB of random bytes, read as 4-byte words.
let words = DeviceBuffer::from_host(&stream, &random(n / 4, 3))?;
let hist = module.prepare_hist_words(LaunchConfig1D::new(GRID, BLOCK, 0))?;
let scratch = DeviceBuffer::<u32>::zeroed(&stream, 256)?.cast_elem::<DeviceAtomicU32>();
let ms = time_ms(&stream, || Ok(module.hist_words(&stream, &hist, &words, &scratch)?))?;
let bins = DeviceBuffer::<u32>::zeroed(&stream, 256)?.cast_elem::<DeviceAtomicU32>();
module.hist_words(&stream, &hist, &words, &bins)?;
let counts = bins.cast_elem::<u32>().to_host_vec(&stream)?;
let total: u64 = counts.iter().map(|&c| c as u64).sum();
let gb = n as f64 / 1e9 / (ms / 1e3);
println!("histogram of 64 MiB, 4 bytes per load");
println!(" {ms:6.2} ms {gb:6.1} GB/s total {total}");
// 4. The histogram reading 16 bytes per load, and the 4 stages of the sum.
let wide = module.prepare_hist_quads(LaunchConfig1D::new(GRID, BLOCK, 0))?;
let ms = time_ms(&stream, || Ok(module.hist_quads(&stream, &wide, &words, &scratch)?))?;
let bins = DeviceBuffer::<u32>::zeroed(&stream, 256)?.cast_elem::<DeviceAtomicU32>();
module.hist_quads(&stream, &wide, &words, &bins)?;
let counts = bins.cast_elem::<u32>().to_host_vec(&stream)?;
let total: u64 = counts.iter().map(|&c| c as u64).sum();
let gb = n as f64 / 1e9 / (ms / 1e3);
println!("histogram of 64 MiB, 16 bytes per load");
println!(" {ms:6.2} ms {gb:6.1} GB/s total {total}");
sums(&module, &stream, &floats)?;
Ok(())
}// Chapter 8: a sum, a scan and a histogram at memory speed, measured.
// Build: nvcc -arch=native reduce.cu -o reduce
#include <chrono>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cuda_runtime.h>
const int BLOCK = 256; // threads per block, a power of 2
const int GRID = 1024; // blocks of the grid-stride kernels
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// Average time of 20 runs of `launch`, in milliseconds, after 1 warm-up run.
template <typename F>
double timeKernel(F launch)
{
launch();
check(cudaDeviceSynchronize());
double t0 = nowMs();
for (int r = 0; r < 20; ++r) {
launch();
}
check(cudaGetLastError());
check(cudaDeviceSynchronize());
return (nowMs() - t0) / 20;
}
// 1. A tree in shared memory, 1 element per thread.
__global__ void sumTree(const float* in, float* partial, int n)
{
    __shared__ float s[BLOCK];
    int i = blockIdx.x * BLOCK + threadIdx.x;
    s[threadIdx.x] = i < n ? in[i] : 0.0f;

    for (int stride = BLOCK / 2; stride > 0; stride /= 2) {
        __syncthreads();
        if (threadIdx.x < stride) {
            s[threadIdx.x] += s[threadIdx.x + stride];
        }
    }
    if (threadIdx.x == 0) {
        partial[blockIdx.x] = s[0];
    }
}
// 2. Each thread first sums many elements in a register, then 1 tree per block.
__global__ void sumCoarse(const float* in, float* partial, int n)
{
    __shared__ float s[BLOCK];
    float sum = 0.0f;
    for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n; i += gridDim.x * BLOCK) {
        sum += in[i];
    }
    s[threadIdx.x] = sum;

    for (int stride = BLOCK / 2; stride > 0; stride /= 2) {
        __syncthreads();
        if (threadIdx.x < stride) {
            s[threadIdx.x] += s[threadIdx.x + stride];
        }
    }
    if (threadIdx.x == 0) {
        partial[blockIdx.x] = s[0];
    }
}
// 3. Shuffles within each warp, and 1 barrier per block.
__device__ float warpSum(float v)
{
    for (int offset = 16; offset > 0; offset /= 2) {
        v += __shfl_down_sync(0xffffffff, v, offset);
    }
    return v;                                 // the warp's total, in lane 0
}

__device__ float blockSum(float v)
{
    __shared__ float warps[BLOCK / 32];
    int lane = threadIdx.x % 32;
    int warp = threadIdx.x / 32;

    v = warpSum(v);
    if (lane == 0) {
        warps[warp] = v;
    }
    __syncthreads();

    if (warp == 0) {
        v = warpSum(lane < BLOCK / 32 ? warps[lane] : 0.0f);
    }
    return v;                                 // the block's total, in thread 0
}

__global__ void sumShuffle(const float* in, float* partial, int n)
{
    float sum = 0.0f;
    for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n; i += gridDim.x * BLOCK) {
        sum += in[i];
    }

    sum = blockSum(sum);
    if (threadIdx.x == 0) {
        partial[blockIdx.x] = sum;
    }
}
// 4. The same, loading 4 floats per instruction; n4 is the number of float4s.
__global__ void sumShuffle4(const float4* in, float* partial, int n4)
{
    float sum = 0.0f;
    for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n4; i += gridDim.x * BLOCK) {
        float4 v = in[i];
        sum += v.x + v.y + v.z + v.w;
    }

    sum = blockSum(sum);
    if (threadIdx.x == 0) {
        partial[blockIdx.x] = sum;
    }
}
// 5. An inclusive scan, 4 elements per thread, 1,024 per block.
__device__ unsigned warpScan(unsigned v)
{
int lane = threadIdx.x % 32;
for (int offset = 1; offset < 32; offset *= 2) {
unsigned left = __shfl_up_sync(0xffffffff, v, offset);
if (lane >= offset) {
v += left;
}
}
return v; // the sum of lanes 0 to `lane`
}
__global__ void scanBlocks(const uint4* in, uint4* out, unsigned* sums, int n4)
{
__shared__ unsigned warps[BLOCK / 32];
int i = blockIdx.x * BLOCK + threadIdx.x;
int lane = threadIdx.x % 32;
int warp = threadIdx.x / 32;
uint4 a = i < n4 ? in[i] : make_uint4(0, 0, 0, 0);
a.y += a.x; // the thread's own 4 values, scanned
a.z += a.y;
a.w += a.z;
unsigned v = warpScan(a.w);
if (lane == 31) {
warps[warp] = v;
}
__syncthreads();
if (warp == 0) {
unsigned w = warpScan(lane < BLOCK / 32 ? warps[lane] : 0);
if (lane < BLOCK / 32) {
warps[lane] = w;
}
}
__syncthreads();
unsigned before = v - a.w + (warp > 0 ? warps[warp - 1] : 0);
a = make_uint4(before + a.x, before + a.y, before + a.z, before + a.w);
if (i < n4) {
out[i] = a;
}
if (threadIdx.x == BLOCK - 1) {
sums[blockIdx.x] = a.w;
}
}
__global__ void addOffsets(uint4* out, const unsigned* sums, int n4)
{
int i = blockIdx.x * BLOCK + threadIdx.x;
if (blockIdx.x > 0 && i < n4) {
unsigned s = sums[blockIdx.x - 1];
uint4 a = out[i];
out[i] = make_uint4(a.x + s, a.y + s, a.z + s, a.w + s);
}
}
// Scans each block, then the block totals (by the same function), then adds them.
// n is a multiple of 4. The totals are padded to a multiple of 4 as well: the padding
// comes after the last real total, so it changes none of the sums that are used.
void scan(const unsigned* in, unsigned* out, int n, unsigned* scratch)
{
int blocks = (n / 4 + BLOCK - 1) / BLOCK;
scanBlocks<<<blocks, BLOCK>>>((const uint4*)in, (uint4*)out, scratch, n / 4);
if (blocks > 1) {
int padded = (blocks + 3) / 4 * 4;
scan(scratch, scratch, padded, scratch + padded);
addOffsets<<<blocks, BLOCK>>>((uint4*)out, scratch, n / 4);
}
}
// 6. Histograms of bytes in shared bins (Chapter 5): 1 byte, 16 bytes or 4 bytes per load.
__global__ void histBytes(const unsigned char* data, unsigned* bins, int n)
{
__shared__ unsigned local[256];
local[threadIdx.x] = 0;
__syncthreads();
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n; i += gridDim.x * BLOCK) {
atomicAdd(&local[data[i]], 1u);
}
__syncthreads();
atomicAdd(&bins[threadIdx.x], local[threadIdx.x]);
}
__device__ void countWord(unsigned* local, unsigned w)
{
for (int k = 0; k < 4; ++k) {
atomicAdd(&local[(w >> 8 * k) & 255], 1u);
}
}
__global__ void histWords(const uint4* data, unsigned* bins, int n16)
{
__shared__ unsigned local[256];
local[threadIdx.x] = 0;
__syncthreads();
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n16; i += gridDim.x * BLOCK) {
uint4 q = data[i];
countWord(local, q.x);
countWord(local, q.y);
countWord(local, q.z);
countWord(local, q.w);
}
__syncthreads();
atomicAdd(&bins[threadIdx.x], local[threadIdx.x]);
}
__global__ void histUint(const unsigned* data, unsigned* bins, int n4)
{
__shared__ unsigned local[256];
local[threadIdx.x] = 0;
__syncthreads();
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n4; i += gridDim.x * BLOCK) {
countWord(local, data[i]);
}
__syncthreads();
atomicAdd(&bins[threadIdx.x], local[threadIdx.x]);
}
unsigned nextRandom(unsigned& state)
{
state = state * 1664525u + 1013904223u;
return state;
}
void sums(const float* in, float* partial, float* total, int n)
{
    double bytes = n * sizeof(float);
    std::printf("sum of %d floats (%d MiB), average of 20 runs\n", n, int(bytes) >> 20);

    auto finish = [&](int blocks) { sumShuffle<<<1, BLOCK>>>(partial, total, blocks); };
    auto report = [&](const char* name, double ms) {
        float t;
        check(cudaMemcpy(&t, total, sizeof(float), cudaMemcpyDeviceToHost));
        double gb = bytes / ms / 1e6;
        std::printf("  %-22s %6.2f ms  %6.1f GB/s  sum %.1f\n", name, ms, gb, t);
    };

    report("tree, 1 per thread", timeKernel([&] {
        sumTree<<<n / BLOCK, BLOCK>>>(in, partial, n);
        finish(n / BLOCK);
    }));
    report("coarsened", timeKernel([&] {
        sumCoarse<<<GRID, BLOCK>>>(in, partial, n);
        finish(GRID);
    }));
    report("shuffles", timeKernel([&] {
        sumShuffle<<<GRID, BLOCK>>>(in, partial, n);
        finish(GRID);
    }));
    report("shuffles, float4", timeKernel([&] {
        sumShuffle4<<<GRID, BLOCK>>>((const float4*)in, partial, n / 4);
        finish(GRID);
    }));
}
void scans(int n)
{
std::vector<unsigned> values(n), expected(n), result(n);
unsigned state = 2;
unsigned running = 0;
for (int i = 0; i < n; ++i) {
values[i] = nextRandom(state) >> 30; // 0, 1, 2 or 3
running += values[i];
expected[i] = running;
}
unsigned *in, *out, *scratch;
check(cudaMalloc(&in, n * sizeof(unsigned)));
check(cudaMalloc(&out, n * sizeof(unsigned)));
check(cudaMalloc(&scratch, (n / 512 + 64) * sizeof(unsigned)));
check(cudaMemcpy(in, values.data(), n * sizeof(unsigned), cudaMemcpyHostToDevice));
double ms = timeKernel([&] { scan(in, out, n, scratch); });
check(cudaMemcpy(result.data(), out, n * sizeof(unsigned), cudaMemcpyDeviceToHost));
double gb = 2.0 * n * sizeof(unsigned) / ms / 1e6;
std::printf("inclusive scan of %d values\n", n);
std::printf(" %6.2f ms %6.1f GB/s last %u correct: %s\n", ms, gb, result[n - 1],
result == expected ? "yes" : "no");
check(cudaFree(in));
check(cudaFree(out));
check(cudaFree(scratch));
}
void histograms(int n)
{
std::vector<unsigned char> random(n), sevens(n, 7);
unsigned state = 3;
for (int i = 0; i < n; ++i) {
random[i] = nextRandom(state) >> 24;
}
unsigned char* data;
unsigned* bins;
check(cudaMalloc(&data, n));
check(cudaMalloc(&bins, 256 * sizeof(unsigned)));
std::printf("histogram of %d MiB, average of 20 runs\n", n >> 20);
for (auto* bytes : {&random, &sevens}) {
check(cudaMemcpy(data, bytes->data(), n, cudaMemcpyHostToDevice));
const char* name = bytes == &random ? "random bytes" : "all 7 ";
double ms1 = timeKernel([&] {
check(cudaMemsetAsync(bins, 0, 256 * sizeof(unsigned)));
histBytes<<<GRID, BLOCK>>>(data, bins, n);
});
double ms16 = timeKernel([&] {
check(cudaMemsetAsync(bins, 0, 256 * sizeof(unsigned)));
histWords<<<GRID, BLOCK>>>((const uint4*)data, bins, n / 16);
});
std::vector<unsigned> counts(256);
check(cudaMemcpy(counts.data(), bins, 1024, cudaMemcpyDeviceToHost));
long long total = 0;
for (unsigned c : counts) {
total += c;
}
std::printf(" %s 1 byte per load %6.2f ms %6.1f GB/s\n", name, ms1,
n / ms1 / 1e6);
std::printf(" %s 16 bytes per load %6.2f ms %6.1f GB/s total %lld\n", name,
ms16, n / ms16 / 1e6, total);
}
check(cudaMemcpy(data, random.data(), n, cudaMemcpyHostToDevice));
double ms4 = timeKernel([&] {
check(cudaMemsetAsync(bins, 0, 256 * sizeof(unsigned)));
histUint<<<GRID, BLOCK>>>((const unsigned*)data, bins, n / 4);
});
std::vector<unsigned> counts(256);
check(cudaMemcpy(counts.data(), bins, 1024, cudaMemcpyDeviceToHost));
long long total = 0;
for (unsigned c : counts) {
total += c;
}
double gbPerS = n / ms4 / 1e6;
std::printf(" random bytes 4 bytes per load %6.2f ms", ms4);
std::printf(" %6.1f GB/s total %lld\n", gbPerS, total);
check(cudaFree(data));
check(cudaFree(bins));
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %d SMs, L2 cache %d MiB\n",
prop.name, prop.multiProcessorCount, prop.l2CacheSize >> 20);
const int n = 64 << 20; // 67,108,864 values, 256 MiB of floats
std::vector<float> values(n);
unsigned state = 1;
for (int i = 0; i < n; ++i) {
values[i] = (nextRandom(state) >> 8) / 16777216.0f; // in [0, 1)
}
float *in, *partial, *total;
check(cudaMalloc(&in, n * sizeof(float)));
check(cudaMalloc(&partial, n / BLOCK * sizeof(float)));
check(cudaMalloc(&total, sizeof(float)));
check(cudaMemcpy(in, values.data(), n * sizeof(float), cudaMemcpyHostToDevice));
for (int k = 0; k < 10; ++k) { // warm up: clocks rise under sustained load
timeKernel([&] { sumShuffle<<<GRID, BLOCK>>>(in, partial, n); });
}
sums(in, partial, total, n);
double exact = 0.0;
float serial = 0.0f;
for (float v : values) {
exact += v;
serial += v;
}
std::printf("exact sum (double) %.1f\n", exact);
std::printf("CPU, float, 1 by 1 %.1f\n", serial);
std::printf("GPU, shuffles, 5 runs ");
for (int r = 0; r < 5; ++r) {
sumShuffle<<<GRID, BLOCK>>>(in, partial, n);
sumShuffle<<<1, BLOCK>>>(partial, total, GRID);
float t;
check(cudaMemcpy(&t, total, sizeof(float), cudaMemcpyDeviceToHost));
std::printf(" %.1f", t);
}
std::printf("\n");
check(cudaFree(in));
check(cudaFree(partial));
check(cudaFree(total));
scans(n);
histograms(n);
}
Common mistakes
- A block size that is not a power of 2 in a halving tree. The levels no longer split evenly, and some values are skipped.
- A shuffle that only some lanes execute. Every lane named in the mask must call
__shfl_down_sync; calling it insideif (lane < 8)is undefined. - Reading the partial result of a lane other than lane 0 after a shuffle sum. Only lane 0 holds the total.
- A missing barrier between writing the warp totals and reading them. We measured the effect in Chapter 5.
- Summing many floats sequentially into a float. Above 224, small values are lost.
- Comparing results bit for bit across launch shapes. A different grid groups the additions differently.
- Timing a scan with allocations inside the timed loop. Allocate the buffers of every level first.
Summary
- A reduction combines \(n\) values with an associative operator. A tree performs the same \(n - 1\) operations as a sequential chain, in \(\log_2 n\) steps.
- A float sum of values below 1, computed sequentially, stopped at 224 = 16,777,216. The tree on the GPU produced the float nearest to the exact sum.
- A tree with one element per thread reached a quarter to a third of rated bandwidth. Coarsening to 256 elements per thread made it 2.3 to 2.5 times as fast.
- Warp shuffles combine the registers of a warp without shared memory or barriers. After coarsening they changed little, because the tree had become a small cost.
- With
float4loads, the sum reached 88% and 97% of rated bandwidth on the 2 GPUs, with the same bits on every run. - A scan within a warp takes 5 shuffle steps. A scan of many blocks scans the blocks, scans their totals, and adds the offsets, and it moves the output twice.
- The privatized histogram of Chapter 5 was limited by its 1-byte loads; 16-byte loads made it 3.8 to 6.1 times as fast.
Chapter 9 applies the same approach to matrix multiplication, a computation that reuses every value it loads many times and can therefore run faster than the memory bandwidth alone would allow.
Exercises
- A tree sums 512 values per block, 1 per thread. How many levels and how many barriers does it need? How many does the shuffle version of section 8.5 need?
- In
blockSum, why does lane 0 of each warp writewarps[warp], and not every lane? What would go wrong if every lane wrote its ownv? - Compute the largest number of floats with values in [0, 1) that can be summed sequentially into a float before the sum stops growing, and check it with a small CPU program.
- Change
GRIDto 256 and to 4,096 and runreduce. Explain the change in speed, and check whether the bits of the sum change. - Write
warpMaxwith__shfl_down_syncand use it to find the largest value of the array. Does the result depend on the launch shape, as the float sum does? - Trace the Blelloch scan on 3, 1, 4, 1: an up-sweep that stores the partial sums of a tree, then a down-sweep that gives each left child its parent’s prefix and each right child the parent’s prefix plus the left child’s sum. Check that it yields the exclusive scan 0, 3, 4, 8.
- Use
scanto write stream compaction: keep the values above 1 from 67,108,864 values from 0 to 3, and verify the output length against a count on the CPU. - Rewrite the Rust
hist_wordsto read 16 bytes per thread, as 4 consecutiveu32words, and compare its speed with listing 8.13 on your GPU.
Sources and further reading
- M. Harris, “Optimizing Parallel Reduction in CUDA”, NVIDIA, 2007.
- J. Luitjens, “Faster Parallel Reductions on Kepler”, NVIDIA Technical Blog, 2014.
- G. Blelloch, “Prefix Sums and Their Applications”, Carnegie Mellon University, 1990.
- D. Merrill and M. Garland, “Single-pass Parallel Prefix Scan with Decoupled Look-back”, NVIDIA, 2016.
- N. Higham, “The Accuracy of Floating Point Summation”, SIAM Journal on Scientific Computing, 1993.
- NVIDIA, CUDA C++ Programming Guide, “Warp Shuffle Functions”: https://docs.nvidia.com/cuda/cuda-c-programming-guide/
- D. Kirk and W. Hwu, Programming Massively Parallel Processors, 4th ed., Morgan Kaufmann, 2022, chapters on reduction, prefix sum and histogram.