Chapter 10: Modern C++ for CUDA
The host code of Chapters 3 to 9 was written in the style of the CUDA C API. Device memory is
allocated with cudaMalloc and released with cudaFree, every API call returns an error code
of type cudaError_t, and every size passed to a copy is a number of bytes. This style keeps
each step of a program visible, which is why we used it for the first programs. It also leaves
3 responsibilities to the programmer at every call site. Every allocation must be freed on
every path out of a function, every error code must be examined, and every size must be given
in the unit that the called function expects. The compiler checks none of them.
In this chapter, we use the features of modern C++, the language as standardized in 2011 and
later, to make the compiler enforce these rules. We first run 3 short programs in which each
rule is broken, and measure the consequences. We then rewrite them with a class that frees its
memory in its destructor, an error-checking function, template kernels, functions compiled for
both host and device, compile-time checks, the cuda:: library and C++20 concepts. We measure
each technique to confirm that it adds no run-time cost. Each one also has a Rust counterpart,
which we show alongside, since Rust makes most of these rules part of the language.
This chapter covers
- Three errors that the CUDA C API does not detect, run and measured
- RAII: allocation in a constructor and release in a destructor
- ownership: why copying is forbidden and moving is allowed
- error reporting with exceptions and
std::source_location, without a macro - template kernels and their instantiations
__host__ __device__functions, and rounding differences between host and deviceconstexprandstatic_assertcuda::std::span,cuda::atomic_refand thread scopes- C++20 concepts
- the corresponding features of Rust:
Drop, moves,?, generic kernels and trait bounds
The code of the chapter is in
code/ch10_modern/
for C++ and in
code/oxide/ch10_modern/
for Rust. The outputs in this chapter come from 2 integrated GPUs: a Jetson Orin NX (8 SMs,
102 GB/s, CUDA 12.6), whose runs the listings show, and a Jetson AGX Thor (20 SMs, 273 GB/s,
CUDA 13.2), which gives the same counts.
10.1 Problems with raw CUDA C
A resource is anything a program acquires from the system and must later return, such as
device memory, a stream, an event or an open file. The CUDA C API manages resources with pairs
of calls, such as cudaMalloc and cudaFree, and it reports failures through return values of
type cudaError_t. Both conventions work correctly as long as the caller remembers to make the
second call and to examine the return value. In this section, we look at what happens when the
caller does not. The program raw.cu contains 3 such errors, each in a few lines of code that
look reasonable.
10.1.1 Measuring the device memory in use
To detect a leak, we need an exact count of the device memory that a program holds. The programs
of this chapter allocate with cudaMallocAsync(&pointer, bytes, stream), the stream-ordered
allocator introduced in CUDA 11.2. It behaves like cudaMalloc, with two differences. First,
the allocation and the matching cudaFreeAsync are ordered in a stream, the queue of GPU work
introduced in Chapter 6, in the same way as kernel launches. Second, the memory comes from a
pool, a reserve of device memory that the driver keeps for each GPU and reuses between
allocations. The pool records the number of bytes that have been allocated and not yet freed in
the attribute cudaMemPoolAttrUsedMemCurrent, which Listing 10.1 reads and converts to MiB.
Listing 10.1 The bytes in use from the pool, in MiB. code/ch10_modern/raw.cu
/// Bytes in use from the pool that stream-ordered allocations draw on, in MiB.
fn pool_mib(ctx: &CudaContext) -> Result<f64, DriverError> {
    ctx.synchronize()?;

    let mut pool = std::ptr::null_mut();
    let mut used: u64 = 0;
    let used_ptr = (&mut used as *mut u64).cast::<c_void>();

    // SAFETY: both out-pointers are valid for the length of each call.
    unsafe {
        sys::cuDeviceGetDefaultMemPool(&mut pool, ctx.cu_device()).result()?;
        sys::cuMemPoolGetAttribute(pool, USED_MEM, used_ptr).result()?;
    }
    Ok(used as f64 / 1_048_576.0)
}
// Bytes in use from the pool that cudaMallocAsync draws on, in MiB.
double poolMiB()
{
cudaMemPool_t pool;
cudaDeviceGetDefaultMemPool(&pool, 0);
unsigned long long used = 0;
cudaMemPoolGetAttribute(pool, cudaMemPoolAttrUsedMemCurrent, &used);
return used / 1048576.0;
}
The older function cudaMemGetInfo is not suitable for this purpose. It reports the free memory
of the whole device, which other programs also change. On an integrated GPU, which shares its
memory with the operating system, an allocation of 128 MiB changed the free memory reported by
cudaMemGetInfo by only 0.5 MiB on the first GPU and by 129 MiB on the second. The pool’s
count, in contrast, depends only on the allocations of our own program.
10.1.2 Memory leaks on early returns
A memory leak occurs when a program has allocated memory and no longer holds its address, so that the memory can no longer be freed. Listing 10.2 shows a function that scales a vector on the GPU and contains such a leak.
Listing 10.2 An early return before the frees.
/// Mistake 1 of raw.cu: ManuallyDrop turns the drops off, so the frees are written by
/// hand, and the early return skips them.
fn scale_by_hand(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
factor: f32,
) -> Result<Option<Vec<f32>>, Error> {
let mut input = ManuallyDrop::new(pool_copy(stream, host)?);
let mut out = ManuallyDrop::new(pool_copy(stream, host)?);
if factor == 0.0 {
return Ok(None); // nothing to scale
}
let config = LaunchConfig1D::new(blocks_for(host.len()), BLOCK, 0);
let prepared = module.prepare_scale::<f32>(config)?;
module.scale(stream, &prepared, factor, &input, &mut out)?;
let result = out.to_host_vec(stream)?;
// SAFETY: neither buffer is used after its drop.
unsafe {
ManuallyDrop::drop(&mut input);
ManuallyDrop::drop(&mut out);
}
Ok(Some(result))
}// Mistake 1: the early return skips both frees.
bool scaleOnGpu(const std::vector<float>& host, std::vector<float>& result, float factor)
{
int n = static_cast<int>(host.size());
size_t bytes = n * sizeof(float);
float* in = nullptr;
float* out = nullptr;
cudaMallocAsync(&in, bytes, 0);
cudaMallocAsync(&out, bytes, 0);
if (factor == 0.0f) {
return false; // nothing to scale
}
cudaMemcpy(in, host.data(), bytes, cudaMemcpyHostToDevice);
scale<<<(n + 255) / 256, 256>>>(in, out, n, factor);
cudaMemcpy(result.data(), out, bytes, cudaMemcpyDeviceToHost);
cudaFreeAsync(in, 0);
cudaFreeAsync(out, 0);
return true;
}
The function allocates 2 device buffers, in and out, with the 2 calls to cudaMallocAsync.
It then copies the input to the device, launches the kernel scale, copies the result back, and
frees both buffers at the end. However, when the factor is 0, there is nothing to compute, and
the function returns false before it reaches the 2 calls to cudaFreeAsync. The early return
is correct by itself. The error is that it skips the frees. The pointers in and out are
local variables, so the return destroys them, and with them the only record of where the 2
buffers are. The memory remains allocated until the program exits.
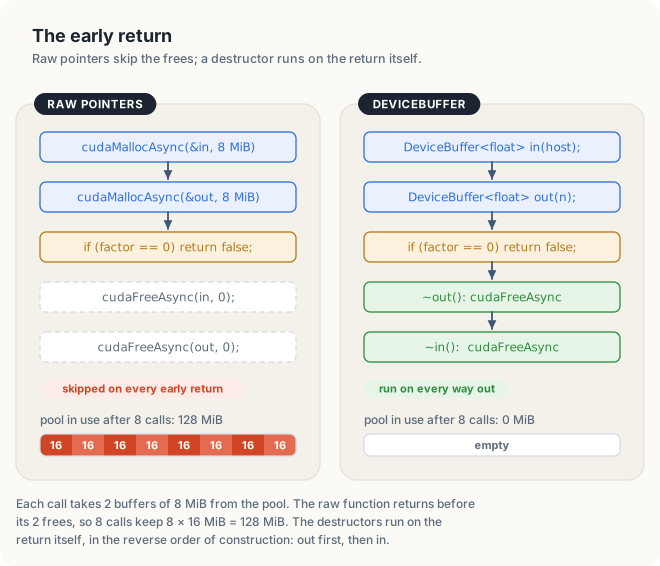
Each buffer holds N = 2,097,152 floats of 4 bytes, which is 8 MiB, so each early return leaks 16 MiB. The test program calls the function 8 times with a factor of 0, which should leave 8 × 16 MiB = 128 MiB allocated, and then reads the pool’s count:
$ nvcc -arch=native raw.cu -o raw && ./raw
1. 8 calls that return early: 128.0 MiB lost
The measured 128.0 MiB agrees with the calculation. No error was reported, and none will be, because as far as CUDA is concerned the program still owns the memory. A long-running program, such as a server or a training job that calls this function millions of times, will eventually run out of device memory, long after the leak occurred and in code that has nothing to do with it.
In Rust, frees are written by hand only after ManuallyDrop has turned the automatic ones off,
and the Rust function of Listing 10.2 then loses the same 128.0 MiB.
10.1.3 Unchecked launch errors
Recall from Chapter 3 that a GPU contains several streaming multiprocessors (SMs), the
processors that execute the threads of a kernel; the Jetson Orin NX has 8 of them. A block
is a group of threads that are launched together, run on the same SM, and can share memory and
synchronize with each other. The compute capability is a version number, such as 8.7 for
the Orin NX, that NVIDIA assigns to each GPU generation and that determines which features the
generation has. Since compute capability 2.0, every CUDA GPU limits a block to at most 1,024
threads. The second error in raw.cu launches blocks of 2,048 threads, twice the limit.
Listing 10.3 A launch that exceeds the block size limit.
/// The launch of 2,048 threads per block. The `?` returns before any kernel runs.
fn launch_too_wide(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
) -> Result<(), Error> {
let input = pool_copy(stream, host)?;
let mut out = pool_copy(stream, host)?;
let blocks = (host.len() as u32) / 2048;
let prepared = module.prepare_scale::<f32>(LaunchConfig1D::new(blocks, 2048, 0))?;
module.scale(stream, &prepared, 2.0, &input, &mut out)?;
Ok(())
}
fn main() -> Result<(), Error> {
// ...
match launch_too_wide(&module, &stream, &host) {
Ok(()) => passed = false,
Err(error) => println!(" 2048 threads per block returned: {error}"),
}
println!(" after the error: {:.1} MiB in use", pool_mib(&ctx)?);
// ...
}int main()
{
// ...
// Mistake 2: 2,048 threads per block is over the limit of 1,024. Nothing reports it.
scale<<<N / 2048, 2048>>>(in, out, N, 2.0f);
cudaMemcpy(result.data(), out, bytes, cudaMemcpyDeviceToHost);
std::printf("2. 2048 threads per block: out[0] = %.1f, expected 2.0\n", result[0]);
cudaError_t err = cudaGetLastError();
std::printf(" the error, found only by asking: %s\n", cudaGetErrorString(err));
// ...
}
2. 2048 threads per block: out[0] = 0.0, expected 2.0
the error, found only by asking: invalid configuration argument
The launch syntax <<<...>>> has no return value, so a launch that fails cannot return an error
code to its caller. Instead, CUDA records the error, and the next call to cudaGetLastError
returns it. In the meantime, the program continues. Let us follow the first element of out
through the program. Before the launch, cudaMemset, which fills device memory with a given
byte, writes 0 into every byte of out, so out[0] is 0.0. The launch is rejected, and no
thread runs. The copy that follows the launch succeeds, but it copies an array that no kernel
has written, so out[0] still holds the 0.0 written by cudaMemset, where the kernel would
have written 1.0 × 2 = 2.0. A program that does not call cudaGetLastError continues with wrong
data and reports nothing. On the second GPU, CUDA 13.2 describes the same failure as invalid argument. The wording of the message differs between CUDA versions, but in both cases the error
is visible only to a program that asks for it.
The Rust launch of Listing 10.3 never reaches the driver: prepare_scale returns an Err, and
the ? passes it to the caller (section 10.2.6).
10.1.4 Size errors in copies
The function cudaMemcpy(dst, src, count, kind) copies count bytes. Its pointer
parameters have type void*, a pointer to memory of no particular type, so the function cannot
know that they point to floats and cannot check a count of floats against them. The third error
in raw.cu passes N, the number of floats, where the number of bytes, N * sizeof(float),
was intended.
Listing 10.4 A count of floats passed as a count of bytes.
/// Mistake 3 of raw.cu: the driver's copy counts bytes, but `host.len()` counts floats.
fn copy_count_as_bytes(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
) -> Result<usize, Error> {
let input = DeviceBuffer::<f32>::zeroed(stream, host.len())?;
let mut out = DeviceBuffer::<f32>::zeroed(stream, host.len())?;
let src = host.as_ptr().cast::<c_void>();
// SAFETY: both sides hold 4 bytes per float, so host.len() bytes fit in each.
check(unsafe { sys::cuMemcpyHtoD_v2(input.cu_deviceptr(), src, host.len()) })?;
let config = LaunchConfig1D::new(blocks_for(host.len()), BLOCK, 0);
let prepared = module.prepare_scale::<f32>(config)?;
module.scale(stream, &prepared, 2.0, &input, &mut out)?;
let result = out.to_host_vec(stream)?;
Ok(result.iter().filter(|&&x| x == 2.0).count())
}int main()
{
// ...
// Mistake 3: N counts floats, but cudaMemcpy counts bytes.
cudaMemset(in, 0, bytes);
cudaMemcpy(in, host.data(), N, cudaMemcpyHostToDevice);
scale<<<N / 256, 256>>>(in, out, N, 2.0f);
cudaMemcpy(result.data(), out, bytes, cudaMemcpyDeviceToHost);
int correct = 0;
for (float x : result) {
correct += (x == 2.0f);
}
std::printf("3. a copy of N bytes, not N floats: %d of %d correct\n", correct, N);
// ...
}
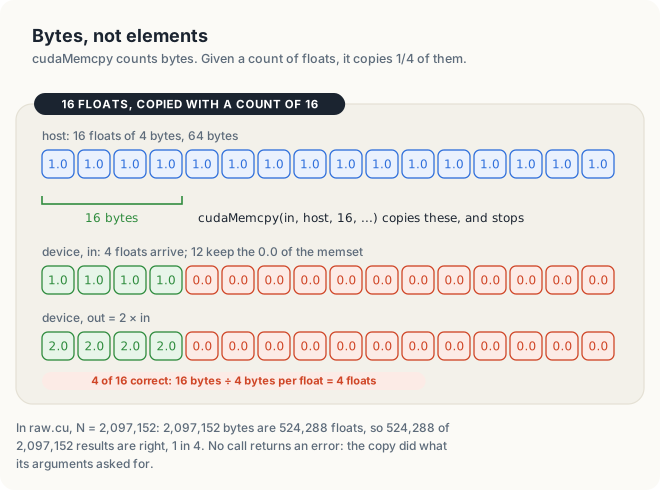
Consider a small example with N = 16. The host array holds 16 floats of 4 bytes, or 64 bytes.
The call cudaMemcpy(in, host, 16, ...) copies 16 bytes, which are the first 16 ÷ 4 = 4 floats.
The other 12 floats of in keep the value 0.0 written by cudaMemset. The kernel doubles every
element, so 4 results are 2.0 and 12 are 0.0: only 1 result in 4 is correct, as Figure 10.2
shows.
3. a copy of N bytes, not N floats: 524288 of 2097152 correct
With N = 2,097,152, the copy moved 2,097,152 bytes, which are 524,288 floats, so again exactly 1
result in 4 is correct. Every call returned cudaSuccess, because the API did exactly what its
arguments asked for.
The Rust function calls the driver’s copy inside unsafe and also finds 524,288 of 2,097,152
correct: unsafe states that the copy stays inside both arrays, which it does, not that the count
is the one intended.
In 3 short programs, the CUDA C API lost 128 MiB of memory, skipped a kernel and copied 1/4 of an array, and none of these errors produced a message.
10.2 RAII: The Device Buffer
The three errors of section 10.1 have a common cause. Each rule, such as “every allocation is freed”, must be applied by hand at every place in the program where it is relevant, and a single omission is enough to break it. C++ allows us to state such a rule once, inside a type, and have the compiler apply it wherever the type is used. We begin with the rule that every allocation is freed.
10.2.1 Constructors, destructors and scope
A scope is a region of a program, delimited by braces { }, in which a name is visible. The
body of a function is a scope, and so is the body of a loop. An object of a class type is
created by a constructor, a member function of the class that runs when the object is
defined. The object is destroyed by its destructor, ~ClassName(), a member function that
the compiler calls when the object’s lifetime ends. The lifetime of an object is the period
during which the object exists, from its construction to its destruction. For a local variable,
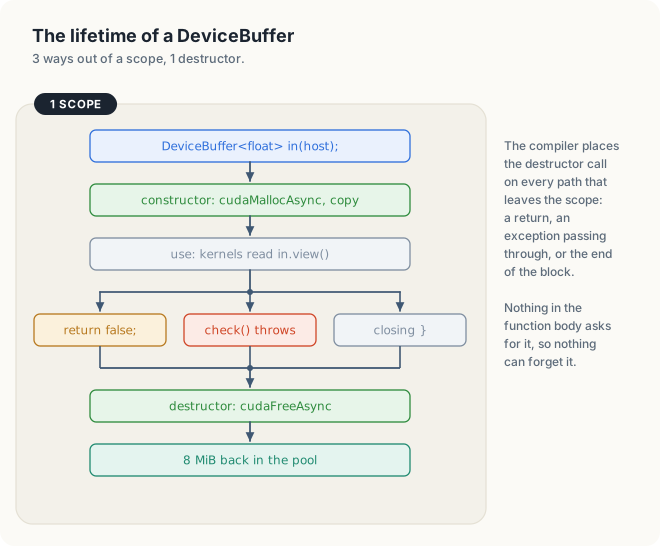
the lifetime ends when control leaves its scope, whichever way it leaves: through the closing
brace, a return, a break, or an exception that passes through the scope.
Before we name the technique, let us follow 1 call of the function of Listing 10.2 with a factor
of 0, first as written and then with the 2 pointers replaced by objects whose destructor frees
the memory. As written, the function performs 4 steps. It allocates in, and the pool holds
8 MiB; it allocates out, and the pool holds 16 MiB; it tests the factor; and it returns. The
return removes the local variables in and out, which are plain addresses, and 16 MiB remain
allocated with no variable that records where they are. With objects, the first 3 steps are the
same. At the return, however, the compiler destroys the 2 local objects, in the reverse order of
their construction. The destructor of out frees 8 MiB, the destructor of in frees the other
8 MiB, and the pool holds 0 MiB. Neither version contains a call to cudaFreeAsync on the path
of the early return. The second version obtains its 2 frees from the type of its variables.
Key observation A release written in a destructor runs on every path out of the scope, because the compiler, not the programmer, writes the call at each exit.
Definition 10.1 RAII. Resource acquisition is initialization (RAII) is the practice of acquiring a resource in the constructor of an object and releasing it in the destructor of the same object. The resource then lives exactly as long as the object.
Example. An object of the class DeviceBuffer<float> of section 10.2.2, created with a count
of 2,097,152, allocates 8 MiB in its constructor and frees the 8 MiB in its destructor when its
scope ends, whether by the closing brace, by a return or by an exception.
Because the compiler, and not the programmer, inserts the call to the destructor, the release happens on every path out of the scope. The pseudocode below marks where the compiler inserts these calls.
{ # a scope opens
buffer ← DeviceBuffer(n) # constructor: allocate n elements
... # use buffer
if done early: return # compiler inserts: destroy buffer, then return
...
} # compiler inserts: destroy buffer
# destroy = destructor: free the allocation
The C++ standard library already uses RAII. A std::vector frees its array in its destructor,
and a std::unique_ptr deletes the object it points to. Device memory needs a class of its own
only because new and delete manage host memory, while device memory is allocated and freed
through CUDA calls.
10.2.2 The class
DeviceBuffer<T> holds count values of type T in device memory. Listing 10.5 shows its
constructors and destructor.
Listing 10.5 DeviceBuffer and PoolBuffer: construction and destruction. code/ch10_modern/device_buffer.hpp
/// `count` values of T in device memory from the pool, owned by exactly 1 variable.
struct PoolBuffer<T> {
ptr: sys::CUdeviceptr,
count: usize,
stream: Arc<CudaStream>,
elements: PhantomData<T>,
}
impl<T: DeviceCopy> PoolBuffer<T> {
#[track_caller]
fn new(stream: &Arc<CudaStream>, count: usize) -> Result<Self, Error> {
let mut ptr = 0;
let bytes = count * size_of::<T>();
// SAFETY: `ptr` is a valid out-pointer, and the stream belongs to this context.
check(unsafe { sys::cuMemAllocAsync(&mut ptr, bytes, stream.cu_stream()) })?;
let elements = PhantomData;
Ok(Self { ptr, count, stream: stream.clone(), elements })
}
#[track_caller]
fn from_host(stream: &Arc<CudaStream>, host: &[T]) -> Result<Self, Error> {
let buffer = Self::new(stream, host.len())?;
let src = host.as_ptr().cast::<c_void>();
// SAFETY: the buffer and `host` both hold buffer.bytes() bytes.
check(unsafe { sys::cuMemcpyHtoD_v2(buffer.ptr, src, buffer.bytes()) })?;
Ok(buffer)
}
}
impl<T> Drop for PoolBuffer<T> {
fn drop(&mut self) {
// A drop cannot report an error, so the result is ignored.
// SAFETY: `ptr` came from cuMemAllocAsync, and only this drop frees it.
let _ = unsafe { sys::cuMemFreeAsync(self.ptr, self.stream.cu_stream()) };
}
}// `count` values of T in device memory, owned by exactly 1 object.
template <typename T>
class DeviceBuffer {
static_assert(std::is_trivially_copyable_v<T>, "device memory holds plain bytes");
public:
explicit DeviceBuffer(std::size_t count) : count_(count)
{
check(cudaMallocAsync(&data_, bytes(), 0));
}
explicit DeviceBuffer(const std::vector<T>& host) : DeviceBuffer(host.size())
{
check(cudaMemcpy(data_, host.data(), bytes(), cudaMemcpyHostToDevice));
}
~DeviceBuffer()
{
release();
}
// ...
};
The Rust type PoolBuffer<T> frees its memory in the method drop of the trait Drop, which
section 10.2.6 describes.
The first constructor allocates count elements. The second constructor allocates enough
elements for a host vector and copies the vector into them. The destructor frees the
allocation. We explain three details of this code.
First, the size in bytes is always computed from the type: bytes() returns
count_ * sizeof(T). Since no caller ever writes a byte count, the error of section 10.1.4
cannot occur.
Second, the second constructor delegates the allocation to the first, with
: DeviceBuffer(host.size()), before its body copies the data. A constructor that begins by
calling another constructor of the same class in this way is called a delegating
constructor. If the copy throws an exception
(section 10.2.4), the object has already been constructed, so its destructor runs and the
allocation is freed.
Third, the static_assert rejects types that cannot be stored in device memory. A type is
trivially copyable when copying its bytes produces a valid copy of the object. float,
int and a struct of floats are trivially copyable. A std::string is not, because it holds a
pointer to host memory, and a copy of its bytes on the device would contain an address that the
GPU cannot use. DeviceBuffer<std::string> is therefore a compile error. We describe
static_assert in more detail in Section 10.5.
Note also that the first constructor is declared explicit. Without this keyword, the compiler
would convert a number into a buffer implicitly, and a function that takes a
DeviceBuffer<float> would accept the argument 5 and allocate 5 floats.
10.2.3 Ownership and move semantics
A class that frees memory in its destructor must define what it means to copy one of its
objects. C++ performs a copy with 2 member functions. The copy constructor creates a new
object from an existing one, as in DeviceBuffer<float> b = a;. The copy assignment
operator overwrites an existing object with the contents of another, as in b = a; when b
already exists. If a class does not define them, the compiler generates both, and the generated
versions copy every member, field by field.
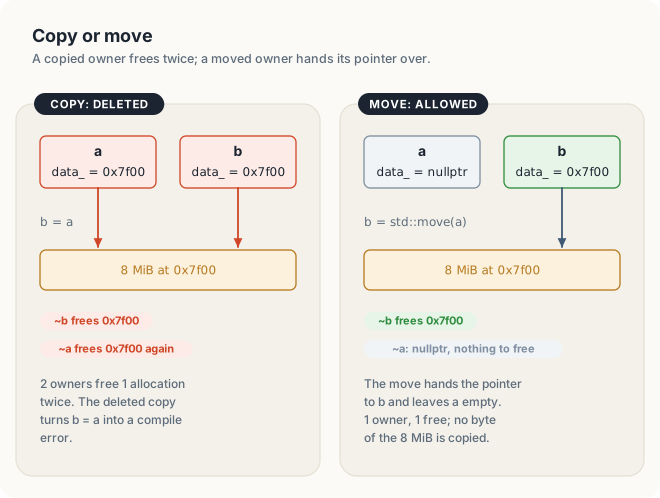
Let us follow 1 allocation through such a field-by-field copy. Suppose that a holds
data_ = 0x7f00 and count_ = 2,097,152, the 8 MiB of a buffer of floats. The statement
b = a copies both fields, so b also holds 0x7f00 and 2,097,152. At the end of the scope,
the destructor of b frees 0x7f00, and then the destructor of a frees 0x7f00 a second time.
Freeing the same allocation twice is called a double free. It corrupts the records of the
allocator, which may later hand out memory that another buffer is still using.
The same allocation can instead pass from a to b in 2 steps: copy the 2 fields to b, then
write nullptr and 0 into the fields of a. Afterward b holds 0x7f00 and a holds
nullptr. At the end of the scope, the destructor of b frees 0x7f00, and the destructor of
a finds nullptr and frees nothing. The allocation is freed exactly once. In both cases, only
the 16 bytes of the 2 fields are copied, never the 8 MiB of data they describe.
Key observation 2 objects that hold the same address free it
twice. If the object that gives up the address is left holding nullptr, exactly 1 object frees
it.
Definition 10.2 Owner and move. The owner of an allocation is the object whose destructor frees it. A move transfers an allocation from 1 owner to another: the new object takes the address, and the old object is left empty, so that its destructor frees nothing.
Example. After b = std::move(a), b owns the 8 MiB at 0x7f00 and a holds nullptr.
For this reason, each allocation has exactly 1 owner. Copying is forbidden: the 2 declarations
marked = delete in Listing 10.6 remove the copy constructor and the copy assignment operator,
so b = a does not compile. Moving, however, is allowed. The function std::move(a) moves
nothing by itself. It marks a as an object whose contents may be taken, and the compiler then
calls the move constructor or the move assignment operator, the 2 member functions that
perform the transfer, instead of the copy operations. Figure 10.4 shows both cases.
Listing 10.6 Copies deleted, moves allowed.
/// A move: `b` takes the allocation, and the name `a` can no longer be used.
fn move_once(stream: &Arc<CudaStream>, host: &[f32]) -> Result<usize, Error> {
let a = PoolBuffer::from_host(stream, host)?;
let b = a;
Ok(b.len())
}// `count` values of T in device memory, owned by exactly 1 object.
template <typename T>
class DeviceBuffer {
// ...
DeviceBuffer(const DeviceBuffer&) = delete;
DeviceBuffer& operator=(const DeviceBuffer&) = delete;
DeviceBuffer(DeviceBuffer&& other) noexcept
: data_(std::exchange(other.data_, nullptr)), count_(std::exchange(other.count_, 0))
{
}
DeviceBuffer& operator=(DeviceBuffer&& other) noexcept
{
if (this != &other) {
release();
data_ = std::exchange(other.data_, nullptr);
count_ = std::exchange(other.count_, 0);
}
return *this;
}
// ...
};
The move constructor uses std::exchange(other.data_, nullptr), which returns the old value of
other.data_ and stores nullptr in its place in a single step. The move assignment operator
first frees the memory that *this held, then takes the pointer of other. The test this != &other prevents a self-assignment such as a = std::move(a) from freeing the buffer that it is
about to keep. Both move operations are declared noexcept, a promise that they never throw.
The promise is easy to keep, because they only exchange 2 values.
C++ programmers refer to this set of member functions as the rule of 5. A class that defines
any of the destructor, copy constructor, copy assignment, move constructor and move assignment
usually needs to define or delete all 5. The table lists the choices that DeviceBuffer makes.
| Member | DeviceBuffer | Reason |
|---|---|---|
| destructor | frees data_ | the object owns the allocation |
| copy constructor | deleted | 2 owners would free twice |
| copy assignment | deleted | same |
| move constructor | takes the pointer, leaves nullptr | 1 owner after the move |
| move assignment | frees its own, then takes the pointer | same, without leaking the old buffer |
With the copy operations deleted, an accidental copy becomes a compile error. We added the line
DeviceBuffer<float> copy = in; to the program and compiled it:
copy.cu(113): error: function "DeviceBuffer<T>::DeviceBuffer(const DeviceBuffer<T> &) [with T=float]" (declared at line 59 of device_buffer.hpp) cannot be referenced -- it is a deleted function
DeviceBuffer<float> copy = in;
^
In Rust, let b = a; moves the buffer, as move_once in Listing 10.6 does, and a later use of
a is the compile error:
error[E0382]: borrow of moved value: `a`
--> src/main.rs:224:17
|
222 | let a = PoolBuffer::from_host(stream, host)?;
| - move occurs because `a` has type `PoolBuffer<f32>`, which does not implement the `Copy` trait
223 | let b = a;
| - value moved here
224 | let first = a.len();
| ^ value borrowed here after move
Listing 10.7 shows the rest of the class: the functions that give access to the memory, and the single function that frees it.
Listing 10.7 Access, and the 1 place that frees.
impl<T> PoolBuffer<T> {
fn len(&self) -> usize {
self.count
}
fn bytes(&self) -> usize {
self.count * size_of::<T>()
}
}
impl<T> Drop for PoolBuffer<T> {
fn drop(&mut self) {
// A drop cannot report an error, so the result is ignored.
// SAFETY: `ptr` came from cuMemAllocAsync, and only this drop frees it.
let _ = unsafe { sys::cuMemFreeAsync(self.ptr, self.stream.cu_stream()) };
}
}// `count` values of T in device memory, owned by exactly 1 object.
template <typename T>
class DeviceBuffer {
// ...
T* data() const { return data_; }
std::size_t size() const { return count_; }
std::size_t bytes() const { return count_ * sizeof(T); }
cuda::std::span<const T> view() const { return {data_, count_}; }
cuda::std::span<T> span() { return {data_, count_}; }
std::vector<T> toHost() const
{
std::vector<T> host(count_);
check(cudaMemcpy(host.data(), data_, bytes(), cudaMemcpyDeviceToHost));
return host;
}
private:
void release()
{
if (data_ != nullptr) { // a moved-from buffer owns nothing
cudaFreeAsync(data_, 0);
}
}
T* data_ = nullptr;
std::size_t count_ = 0;
};
view() returns a read-only view of the buffer and span() a writable one; we introduce
the type of these views in section 10.6.1. release() tests for nullptr because a buffer that has
been moved from no longer owns any memory. A Rust value that has been moved from is never
dropped, so drop needs no such test.
10.2.4 Error reporting without a macro
In Chapters 3 to 9, we checked each CUDA call with a small function that printed the error and
ended the program. Many CUDA programs use a macro instead, CHECK(call). A macro is a name that
the preprocessor, a text-substitution step that runs before the compiler proper, replaces
with other text wherever the name appears. Programs use a macro here for one reason: the
preprocessor replaces __FILE__ and __LINE__ with the file name and line number of the place
where the macro is written, so the message names the call that failed. For example, CHECK
written on line 40 of app.cu produces a message that contains app.cu and 40. Before C++20, a
function had no way to find out where it was called from. C++20 added std::source_location for
this purpose.
A default argument is a value that a function parameter takes when the caller omits it. When
std::source_location::current() is used as a default argument, it is evaluated at the call
site, so it records the file and line of the caller rather than a line inside check. Listing
10.8 shows the function.
Listing 10.8 check, with the caller's file and line.
/// Turn a driver result into an error that names the caller's file and line.
#[track_caller]
fn check(result: sys::CUresult) -> Result<(), Error> {
let place = Location::caller();
match result.result() {
Ok(()) => Ok(()),
Err(error) => Err(format!("{}:{}: {error}", place.file(), place.line()).into()),
}
}using Where = std::source_location;
// Throw if a CUDA call failed. The default argument records the caller's file and line.
inline void check(cudaError_t err, Where where = Where::current())
{
if (err == cudaSuccess) {
return;
}
std::string place = std::string(where.file_name()) + ":" + std::to_string(where.line());
throw std::runtime_error(place + ": " + cudaGetErrorString(err));
}
In Rust, the attribute #[track_caller] makes Location::caller() return the file and line of
the call, so the Rust check needs no macro either.
check reports a failure by throwing an exception, an object that travels up the chain of
function calls until a catch clause handles it. On its way, the exception leaves every scope
it passes through, and every local object in those scopes is destroyed. The destruction of local
objects while an exception travels up the chain of calls is called stack unwinding. It is
the path labeled “check() throws” in Figure 10.3. For example, if main calls a function f
that holds 2 buffers, and check throws inside f, the 2 destructors of f run first, and
only then does the exception reach the catch in main. As a result, the buffers of a function
that fails are freed before the error reaches the code that handles it.
Note that the destructor itself does not call check. A destructor may run while an exception
is already traveling, and if a second exception is thrown at that moment, the program ends with
std::terminate, a standard function that stops the program immediately. The destructor
therefore frees the memory and ignores the result. A program that needs to know whether a free
succeeded can call cudaDeviceSynchronize through check before the buffer goes out of scope.
10.2.5 The errors of section 10.1, revisited
We can now rewrite the functions of section 10.1 with DeviceBuffer and check. Listing 10.9
shows the function with the early return and the launch with 2,048 threads per block.
Listing 10.9 The early return and the launch over the limit, with DeviceBuffer and check. code/ch10_modern/modern.cu
/// The function of raw.cu. Every return, early or not, drops both buffers.
fn scale_on_gpu(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
factor: f32,
) -> Result<Option<Vec<f32>>, Error> {
let input = pool_copy(stream, host)?;
let mut out = pool_copy(stream, host)?;
if factor == 0.0 {
return Ok(None);
}
let blocks = blocks_for(host.len());
let prepared = module.prepare_scale::<f32>(LaunchConfig1D::new(blocks, BLOCK, 0))?;
module.scale(stream, &prepared, factor, &input, &mut out)?;
Ok(Some(out.to_host_vec(stream)?))
}
/// The launch of 2,048 threads per block. The `?` returns before any kernel runs.
fn launch_too_wide(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
) -> Result<(), Error> {
let input = pool_copy(stream, host)?;
let mut out = pool_copy(stream, host)?;
let blocks = (host.len() as u32) / 2048;
let prepared = module.prepare_scale::<f32>(LaunchConfig1D::new(blocks, 2048, 0))?;
module.scale(stream, &prepared, 2.0, &input, &mut out)?;
Ok(())
}// The function of raw.cu: the early return frees both buffers.
bool scaleOnGpu(const std::vector<float>& host, std::vector<float>& result, float factor)
{
DeviceBuffer<float> in(host);
DeviceBuffer<float> out(host.size());
if (factor == 0.0f) {
return false;
}
transform<<<blocksFor(in.size()), BLOCK>>>(in.view(), out.span(), Scale{factor});
check(cudaGetLastError());
result = out.toHost();
return true;
}
void launchTooWide(const std::vector<float>& host)
{
DeviceBuffer<float> in(host);
DeviceBuffer<float> out(host.size());
transform<<<N / 2048, 2048>>>(in.view(), out.span(), Scale{2.0f});
check(cudaGetLastError());
}
The function main in Listing 10.10 makes the same 8 calls as raw.cu, launches the 2,048
threads inside a try block, and copies 2,097,152 floats through the constructor that takes a
host vector.
Listing 10.10 The measurements of section 10.1, repeated.
fn main() -> Result<(), Error> {
// ...
println!("ownership");
let before = pool_mib(&ctx)?;
for _ in 0..8 {
scale_on_gpu(&module, &stream, &host, 0.0)?;
}
let lost = pool_mib(&ctx)? - before;
println!(" 8 calls that return early: {lost:.1} MiB lost");
passed &= lost == 0.0;
match launch_too_wide(&module, &stream, &host) {
Ok(()) => passed = false,
Err(error) => println!(" 2048 threads per block returned: {error}"),
}
println!(" after the error: {:.1} MiB in use", pool_mib(&ctx)?);
let result = scale_on_gpu(&module, &stream, &host, 2.0)?.unwrap_or_default();
let correct = result.iter().filter(|&&x| x == 2.0).count();
println!(" copies sized by the type: {correct} of {N} correct");
passed &= correct == N;
// ...
}int main()
{
// ...
std::printf("ownership\n");
double before = poolMiB();
for (int call = 0; call < 8; ++call) {
scaleOnGpu(host, result, 0.0f);
}
double lost = poolMiB() - before;
std::printf(" 8 calls that return early: %.1f MiB lost\n", lost);
passed = passed && lost == 0.0;
try {
launchTooWide(host);
passed = false;
} catch (const std::runtime_error& e) {
std::printf(" 2048 threads per block threw: %s\n", e.what());
}
std::printf(" after the exception: %.1f MiB in use\n", poolMiB());
scaleOnGpu(host, result, 2.0f);
int correct = 0;
for (float x : result) {
correct += (x == 2.0f);
}
std::printf(" copies sized by the type: %d of %d correct\n", correct, N);
passed = passed && correct == N;
// ...
}
$ nvcc -std=c++20 --extended-lambda -arch=native modern.cu -o modern && ./modern
GPU: Orin, 8 SMs
ownership
8 calls that return early: 0.0 MiB lost
2048 threads per block threw: modern.cu:134: invalid configuration argument
after the exception: 0.0 MiB in use
copies sized by the type: 2097152 of 2097152 correct
All three errors are gone. The early returns leaked 0.0 MiB. The launch error became an exception
that names line 134, the check(cudaGetLastError()) after the launch, and the 2 buffers of
launchTooWide, 16 MiB in total, were freed while the exception traveled to main. Every
element was copied correctly, because no caller states a byte count.
10.2.6 RAII in Rust
Rust builds RAII into the language. A trait in Rust is a named set of methods that a type
can implement; a function can then require that its argument type implements the trait. The
destructor of a type is the method drop of the trait Drop, and the compiler calls it when
the owner of a value goes out of scope. cuda-core, the host-side crate (Rust package) of
cuda-oxide, provides a DeviceBuffer<T> that implements Drop by freeing its allocation, so a
Rust program has no free to forget. Ownership is also the default. The statement let b = a;
moves the buffer, and any later use of a is a compile error. A copy must be requested
explicitly, and DeviceBuffer does not provide one.
Rust reports errors as values of type Result<T, E>, which is either Ok(value) or
Err(error). The ? operator after a call returns the Err from the enclosing function
immediately. Like any other return, this return drops every local buffer.
Listing 10.11 shows the Rust version of the function with the early return. The helper
pool_copy allocates from the same pool as the C++ program, so that the 2 counts can be
compared. The safe cuda-core functions, such as DeviceBuffer::from_host, allocate with the
synchronous cuMemAlloc, a function of the CUDA driver API (Chapter 12) that the pool does not
count. uninitialized_async takes the memory from the pool. A Rust function marked unsafe
performs operations whose correctness the compiler cannot check, and a caller must write the
call inside an unsafe block, which states that the programmer has checked it.
uninitialized_async is unsafe only because the contents of the buffer are undefined until
they are written, and the copy on the next line writes every element.
Listing 10.11 The early return, with buffers that free themselves. code/oxide/ch10_modern/src/main.rs
/// A copy of `host` in device memory from the pool, freed when the buffer is dropped.
fn pool_copy<T: DeviceCopy>(
stream: &Arc<CudaStream>,
host: &[T],
) -> Result<DeviceBuffer<T>, DriverError> {
// SAFETY: the copy below writes every element before anything reads one.
let mut buffer = unsafe { DeviceBuffer::uninitialized_async(stream, host.len())? };
buffer.copy_from_host(stream, host)?;
Ok(buffer)
}
/// The function of raw.cu. Every return, early or not, drops both buffers.
fn scale_on_gpu(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
factor: f32,
) -> Result<Option<Vec<f32>>, Error> {
let input = pool_copy(stream, host)?;
let mut out = pool_copy(stream, host)?;
if factor == 0.0 {
return Ok(None);
}
let blocks = blocks_for(host.len());
let prepared = module.prepare_scale::<f32>(LaunchConfig1D::new(blocks, BLOCK, 0))?;
module.scale(stream, &prepared, factor, &input, &mut out)?;
Ok(Some(out.to_host_vec(stream)?))
}// `count` values of T in device memory, owned by exactly 1 object.
template <typename T>
class DeviceBuffer {
// ...
explicit DeviceBuffer(std::size_t count) : count_(count)
{
check(cudaMallocAsync(&data_, bytes(), 0));
}
explicit DeviceBuffer(const std::vector<T>& host) : DeviceBuffer(host.size())
{
check(cudaMemcpy(data_, host.data(), bytes(), cudaMemcpyHostToDevice));
}
// ...
};
// The function of raw.cu: the early return frees both buffers.
bool scaleOnGpu(const std::vector<float>& host, std::vector<float>& result, float factor)
{
DeviceBuffer<float> in(host);
DeviceBuffer<float> out(host.size());
if (factor == 0.0f) {
return false;
}
transform<<<blocksFor(in.size()), BLOCK>>>(in.view(), out.span(), Scale{factor});
check(cudaGetLastError());
result = out.toHost();
return true;
}
The Rust launch in Listing 10.12 carries a launch contract (Chapter 13): the kernel declares
that it runs in blocks of 256 threads, and prepare_scale checks the requested configuration
against this declaration on the host, before any call to the driver. The listing also shows the
only way to leak a buffer in safe Rust. std::mem::forget takes ownership of a value and never
drops it. It is part of safe Rust, because a leak cannot cause a program to read or write the
wrong memory, but it must be written explicitly.
Listing 10.12 The launch over the limit, and the only way to leak.
/// The launch of 2,048 threads per block. The `?` returns before any kernel runs.
fn launch_too_wide(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
) -> Result<(), Error> {
let input = pool_copy(stream, host)?;
let mut out = pool_copy(stream, host)?;
let blocks = (host.len() as u32) / 2048;
let prepared = module.prepare_scale::<f32>(LaunchConfig1D::new(blocks, 2048, 0))?;
module.scale(stream, &prepared, 2.0, &input, &mut out)?;
Ok(())
}
/// The same function with `std::mem::forget`: the only way to skip a drop.
fn forget_on_gpu(stream: &Arc<CudaStream>, host: &[f32]) -> Result<(), DriverError> {
let input = pool_copy(stream, host)?;
std::mem::forget(input);
Ok(())
}void launchTooWide(const std::vector<float>& host)
{
DeviceBuffer<float> in(host);
DeviceBuffer<float> out(host.size());
transform<<<N / 2048, 2048>>>(in.view(), out.span(), Scale{2.0f});
check(cudaGetLastError());
}
// The only way to skip a destructor: a buffer created with new and never deleted.
void leakOnGpu(const std::vector<float>& host)
{
new DeviceBuffer<float>(host);
}
$ cargo oxide run
ownership
8 calls that return early: 0.0 MiB lost
2048 threads per block returned: scale: block (2048, 1, 1) does not match required block (256, 1, 1)
after the error: 0.0 MiB in use
copies sized by the type: 2097152 of 2097152 correct
8 calls with mem::forget: 64.0 MiB lost
Each of the 8 calls of forget_on_gpu forgot 1 buffer of 8 MiB, for the 64.0 MiB shown. The
other results match those of the C++ program, with 1 difference: the wrong block size was
rejected before it reached the driver. In C++, the counterpart of forget is a buffer created
with new and never deleted, and 8 calls of leakOnGpu lost the same 64.0 MiB.
A function creates a DeviceBuffer, then calls a function that throws. Who frees the buffer, and when?
The destructor of the buffer frees it, while the exception passes through the function’s scope
on its way to a catch. The code of the function after the throwing call never runs, but the
compiler destroys every local object in every scope that the exception leaves.
10.3 Templates: One Kernel, Many Types
10.3.1 Templates and instantiation
The kernel scale of raw.cu multiplies floats. A program that also needs to multiply doubles
and ints would need 3 copies of this kernel. Let us compare the float copy with the double copy
line by line. The parameter in changes from const float* to const double*, the parameter
out from float* to double*, and the factor from float to double. The index
computation, the bounds test and the multiplication are the same text in both. The 3 copies
therefore differ in 1 word, the element type, written in 3 places. C++ templates remove this
duplication by turning that word into a parameter.
Definition 10.3 Template and instantiation. A template is
a function or class written in terms of a template parameter, a placeholder for a type, such
as T. When the program uses the template with a particular type, the compiler substitutes the
type for the parameter and compiles the result, which is called an instantiation of the
template.
Example. From 1 template transform<T, F>, the uses transform<float, Scale<float>> and
transform<double, Scale<double>> produce 2 instantiations, 2 different kernels in the binary.
A template is not yet code. Only its instantiations are compiled into machine code, each exactly as if it had been written by hand, so a program contains 1 kernel for each type with which it uses the template.
Our kernel is generic in two ways: in the element type T, and in the operation F applied to
each element. Its pseudocode is that of scale, with the multiplication replaced by a call to
f.
KERNEL transform<T, F>(in, out, f): # T: element type, F: operation from T to T
i ← blockIdx.x × blockDim.x + threadIdx.x # this thread's index (Chapter 3)
if i < length of in:
out[i] ← f(in[i])
Listing 10.13 A template kernel and an operation to pass to it.
mod kernels {
// ...
/// out[i] = f(input[i]), for any T and any operation f from T to T, such as a closure.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn transform<T, F>(f: F, input: &[T], mut out: DisjointSlice<T>)
where
T: Copy,
F: Fn(T) -> T + Copy,
{
let idx = thread::index_1d();
let i = idx.get();
if let Some(slot) = out.get_mut(idx) {
*slot = f(input[i]);
}
}
// ...
}// out[i] = f(in[i]), for any number type T and any operation f from T to T.
template <Number T, UnaryOp<T> F>
__global__ void transform(cuda::std::span<const T> in, cuda::std::span<T> out, F f)
{
std::size_t i = blockIdx.x * std::size_t(blockDim.x) + threadIdx.x;
if (i < in.size()) {
out[i] = f(in[i]);
}
}
template <Number T>
struct Scale {
T factor;
__host__ __device__ T operator()(T x) const { return factor * x; }
};
The line template <Number T, UnaryOp<T> F> states that T must be a numeric type and F an
operation that maps a T to a T; we define both conditions in section 10.7. The arguments in
and out are spans, which carry their length together with the pointer, so the bounds check
compares i with in.size() rather than with a separate n that might belong to another array
(section 10.6.1). The index i is a std::size_t of 64 bits, so the kernel also works on
arrays of more than 231 elements.
Scale<T> is a function object, a struct with an operator(). The member function
operator() is the function that C++ runs when an object is followed by parentheses, so an
object triple of type Scale<float> with factor = 3 can be called as triple(x), and
triple(2.0f) returns 6.0. It stores its state, the factor, as a member, and it is passed to
the GPU as a kernel argument of sizeof(T) bytes. Its operator() is marked __host__ __device__ so that the kernel can call it; we explain these qualifiers in section 10.4. The Rust kernel transform takes a closure, the
Rust form of a lambda, as its operation f.
Let us run transform<float, Scale<float>> by hand on 4 values, in = 1, 2, 3, 4, with f =
triple. With blocks of 256 threads, 1 block is launched, and threads 0 to 3 pass the test i < in.size(), since the span in has size 4. Thread 2 reads in[2] = 3, calls f(3), and writes
9 into out[2]. The 4 threads write 3, 6, 9, 12. Threads 4 to 255 fail the test and write
nothing.
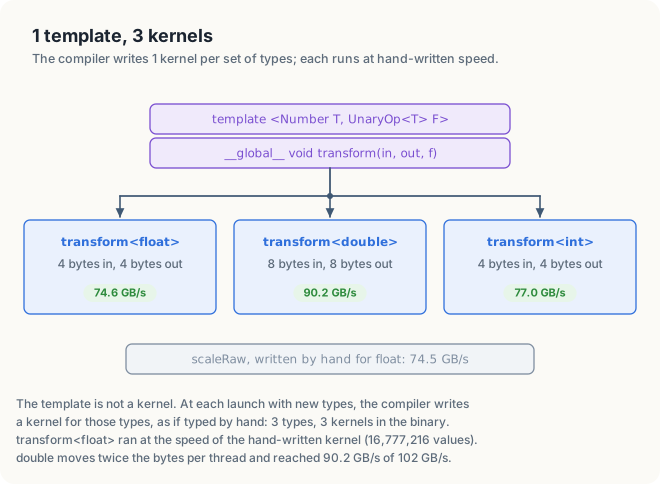
The timing function in Listing 10.14 is itself a template. The single call timeType<double>
creates a Scale<double> and launches transform<double, Scale<double>>, so the compiler
instantiates the whole chain from that 1 line.
Listing 10.14 1 timing function, instantiated for 3 types.
/// Time scale::<T> on `data`, print the rate, and check every result.
fn time_scale<T>(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
name: &str,
data: &[T],
factor: T,
) -> Result<bool, Error>
where
T: DeviceCopy + Mul<Output = T> + PartialEq,
{
let input = DeviceBuffer::from_host(stream, data)?;
let mut out = DeviceBuffer::<T>::zeroed(stream, data.len())?;
let blocks = blocks_for(data.len());
let prepared = module.prepare_scale::<T>(LaunchConfig1D::new(blocks, BLOCK, 0))?;
let mut launch = || Ok(module.scale(stream, &prepared, factor, &input, &mut out)?);
let ms = time_ms(stream, 20, &mut launch)?;
let bytes = 2 * data.len() * size_of::<T>();
println!(" {name:<14} {ms:7.2} ms {:6.1} GB/s", bytes as f64 / ms / 1e6);
let result = out.to_host_vec(stream)?;
Ok(result.iter().zip(data).all(|(&y, &x)| y == factor * x))
}// Time transform<T> on BIG values; return true if every result is right.
template <Number T>
bool timeType(const char* name, int runs)
{
std::vector<T> host(BIG);
for (int i = 0; i < BIG; ++i) {
host[i] = static_cast<T>(i % 1000);
}
DeviceBuffer<T> in(host);
DeviceBuffer<T> out(host.size());
Scale<T> triple{3};
auto launch = [&] {
transform<<<blocksFor(BIG), BLOCK>>>(in.view(), out.span(), triple);
};
double ms = timeKernel(launch, runs);
double gbs = 2.0 * BIG * sizeof(T) / ms / 1e6;
std::printf(" %-22s %7.2f ms %6.1f GB/s\n", name, ms, gbs);
std::vector<T> result = out.toHost();
for (int i = 0; i < BIG; ++i) {
if (result[i] != triple(host[i])) {
return false;
}
}
return true;
}
10.3.2 Lambdas as operations
A lambda is a function object written in place. The expression
[](float v) { return 2.0f * v; } defines an unnamed struct with that operator() and creates
an object of it. The unnamed struct is called the closure type of the lambda. The square
brackets at the start of the lambda are its capture list, which names the variables of the
surrounding code that the lambda may use; here the list is empty. Passing such a lambda to a
kernel looks natural, but it does not compile:
hostlambda.cu(227): error: The closure type for a lambda ("lambda [](float)->float", defined at hostlambda.cu:224) cannot be used in the template argument type of a __global__ function template instantiation, unless the lambda is defined within a __device__ or __global__ function, or the flag '-extended-lambda' is specified and the lambda is an extended lambda (a __device__ or __host__ __device__ lambda defined within a __host__ or __host__ __device__ function)
A lambda written in host code is a host function, and the GPU cannot execute host code. The
error message names the solution. An extended lambda carries __device__ or __host__ __device__ after its capture list, and the compiler then generates a device version of it. The
program must be compiled with --extended-lambda. We use 2 extended lambdas in Section 10.4.2.
A lambda can also capture variables, which copies them into the lambda object, as in
[factor](float v) {...}. For example, if the host variable factor holds 3.0 when the lambda
is created, the lambda object contains its own float with the value 3.0, and the lambda
multiplies by 3.0 even if factor changes later. The copies are passed to the GPU with the
kernel’s arguments, so they must be trivially copyable. A capture by reference, [&factor],
would pass the address of a host variable, which the GPU cannot use, and nvcc rejects it with
the error An extended __device__ lambda cannot capture variables by reference.
10.3.3 The run-time cost of templates
A template, a function object and a span are abstractions. They give names to things that the
hand-written kernel did directly. To measure their cost, we compare transform<float> with
scaleRaw, the C-style kernel of raw.cu, on the same 16,777,216 floats, and run the other 2
instantiations alongside. Each measurement follows 500 ms of warm-up, because a GPU raises the
clock rates of its cores and of its memory only under sustained load.
1 template, 3 types, 16777216 values
raw pointers, float 1.80 ms 74.5 GB/s
transform<float> 1.80 ms 74.6 GB/s
transform<double> 2.98 ms 90.2 GB/s
transform<int> 1.74 ms 77.0 GB/s
The rate counts each element read once and written once. For float, that is
2 × 16,777,216 × 4 bytes = 134.2 MB, divided by the time. transform<float> and scaleRaw both
took 1.80 ms, so the abstractions have no measurable cost. Repeated runs vary by 10 to 20% in
both directions, and the 2 kernels varied together. transform<double> moved twice as many
bytes, 268.4 MB, in 1.66 times the time. With 8 bytes per element, each load and store of a
thread carries twice as much data, and the kernel came closer to the GPU’s memory bandwidth of
102 GB/s: 90.2 GB/s is 88% of it.
A kernel is said to be memory-bound if its time is set by the number of bytes it moves
rather than by its arithmetic. Each thread of transform<float> performs 1 multiplication for
every 8 bytes it reads and writes, so each of these kernels is memory-bound. The shortest
possible time on any GPU then follows from the number of bytes moved and the memory
bandwidth, the maximum number of bytes that the memory can transfer per second. For example,
134.2 MB at 102 GB/s take 134.2 / 102 = 1.32 ms.
| GPU | Memory bandwidth | Least time for transform<float>, 134.2 MB |
|---|---|---|
| Jetson Orin NX 16 GB | 102 GB/s | 1.32 ms |
| Jetson AGX Thor | 273 GB/s | 0.49 ms |
| DGX Spark (GB10) | 273 GB/s | 0.49 ms |
| GeForce RTX 4090 | 1,008 GB/s | 0.133 ms |
| GeForce RTX 5090 | 1,792 GB/s | 0.075 ms |
| A100 SXM 80 GB | 2,039 GB/s | 0.066 ms |
| H100 SXM | 3,350 GB/s | 0.040 ms |
The measured 1.80 ms corresponds to 74.6 GB/s, 73% of the GPU’s 102 GB/s. A template does not change this limit; only moving fewer bytes would.
10.3.4 Generic kernels in Rust
Rust’s equivalent of templates is generics: a function with a type parameter T and a list
of conditions on that type. The compiler instantiates a generic function for each type it is
used with, a process that Rust calls monomorphization. cuda-oxide applies it to kernels, so
scale::<f32> and scale::<f64> become 2 separate kernels.
Listing 10.15 A generic kernel.
mod kernels {
// ...
/// out[i] = factor * input[i], for any T that can be multiplied.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scale<T>(factor: T, input: &[T], mut out: DisjointSlice<T>)
where
T: Copy + Mul<Output = T>,
{
let idx = thread::index_1d();
let i = idx.get();
if let Some(slot) = out.get_mut(idx) {
*slot = factor * input[i];
}
}
// ...
}// out[i] = f(in[i]), for any number type T and any operation f from T to T.
template <Number T, UnaryOp<T> F>
__global__ void transform(cuda::std::span<const T> in, cuda::std::span<T> out, F f)
{
std::size_t i = blockIdx.x * std::size_t(blockDim.x) + threadIdx.x;
if (i < in.size()) {
out[i] = f(in[i]);
}
}
template <Number T>
struct Scale {
T factor;
__host__ __device__ T operator()(T x) const { return factor * x; }
};
A trait bound is a condition, written after a type parameter, that the type must implement
the named traits. The bound T: Copy + Mul<Output = T> lists the operations that the body
needs: values of T can be copied (the trait Copy), and 2 of them can be multiplied to give a
T (the trait Mul with result type T). f32, f64 and i32 satisfy both; a String
satisfies neither. The host side names the type when it prepares the launch,
prepare_scale::<T>, and a generic host function, such as the timing function in Listing 10.16,
can do so for its own T.
Listing 10.16 1 generic timing function for 3 types.
/// Time scale::<T> on `data`, print the rate, and check every result.
fn time_scale<T>(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
name: &str,
data: &[T],
factor: T,
) -> Result<bool, Error>
where
T: DeviceCopy + Mul<Output = T> + PartialEq,
{
let input = DeviceBuffer::from_host(stream, data)?;
let mut out = DeviceBuffer::<T>::zeroed(stream, data.len())?;
let blocks = blocks_for(data.len());
let prepared = module.prepare_scale::<T>(LaunchConfig1D::new(blocks, BLOCK, 0))?;
let mut launch = || Ok(module.scale(stream, &prepared, factor, &input, &mut out)?);
let ms = time_ms(stream, 20, &mut launch)?;
let bytes = 2 * data.len() * size_of::<T>();
println!(" {name:<14} {ms:7.2} ms {:6.1} GB/s", bytes as f64 / ms / 1e6);
let result = out.to_host_vec(stream)?;
Ok(result.iter().zip(data).all(|(&y, &x)| y == factor * x))
}// Time transform<T> on BIG values; return true if every result is right.
template <Number T>
bool timeType(const char* name, int runs)
{
std::vector<T> host(BIG);
for (int i = 0; i < BIG; ++i) {
host[i] = static_cast<T>(i % 1000);
}
DeviceBuffer<T> in(host);
DeviceBuffer<T> out(host.size());
Scale<T> triple{3};
auto launch = [&] {
transform<<<blocksFor(BIG), BLOCK>>>(in.view(), out.span(), triple);
};
double ms = timeKernel(launch, runs);
double gbs = 2.0 * BIG * sizeof(T) / ms / 1e6;
std::printf(" %-22s %7.2f ms %6.1f GB/s\n", name, ms, gbs);
std::vector<T> result = out.toHost();
for (int i = 0; i < BIG; ++i) {
if (result[i] != triple(host[i])) {
return false;
}
}
return true;
}
1 generic kernel, 3 types, 16777216 values
scale::<f32> 1.92 ms 69.9 GB/s
scale::<f64> 2.88 ms 93.3 GB/s
scale::<i32> 1.77 ms 75.7 GB/s
The Rust instantiations ran within 7% of the C++ ones, which is inside the variation between runs, and in the same order: double reaches the highest rate in bytes per second.
10.4 __host__ __device__ Functions
10.4.1 Compiling a function for both processors
CUDA marks every function with the processor it is compiled for. A __global__ function is a
kernel. It is launched from the host and runs on the device. A __device__ function runs on the
device and is called from device code. A function with no qualifier, or with __host__, runs on
the host. A function marked __host__ __device__ is compiled twice from 1 definition, once for
each processor, and can be called from either side.
This makes a simple test possible: run the function on the CPU, run it in a kernel, and check that the 2 results agree. Testing a GPU result against a CPU result computed by the same source code is called differential testing.
for each x in the test values:
cpu[x] ← f(x) # host compilation
gpu ← run f on every x in a kernel # device compilation
count the x where the bits of cpu[x] and gpu[x] differ
A function compiled for both processors may use only what exists on both: arithmetic, the CUDA
math functions such as fmaf, sqrtf and expf, and plain C++. A part that must differ
between the 2 compilations is guarded by the macro __CUDA_ARCH__, which the compiler defines
only while it compiles device code:
__host__ __device__ float logOf(float x)
{
#ifdef __CUDA_ARCH__
return __logf(x); // device: the fast hardware approximation
#else
return std::log(x); // host: the standard library
#endif
}
The Rust programs of this book have no counterpart of this guard: a Rust function called from a kernel is compiled for both processors from the same text (section 10.4.3).
10.4.2 Floating-point differences between host and device
As an example, we use the polynomial 1 + x + x²/2 + x³/6, the first 4 terms of the series of ex. Horner’s rule evaluates a polynomial from its highest coefficient down by nesting the multiplications. It writes the polynomial as 1 + x(1 + x(1/2 + x/6)), which takes 3 multiplications, each followed by an addition. At x = 1, for example, the 3 steps give 1/2 + 1/6 = 0.6667, then 1 + 0.6667 = 1.6667, then 1 + 1.6667 = 2.6667. Listing 10.17 writes it in two ways.
Listing 10.17 1 polynomial, written 2 ways, for both processors.
/// 1 + x + x^2/2 + x^3/6, the first 4 terms of e^x, by Horner's rule.
fn exp_poly(x: f32) -> f32 {
1.0 + x * (1.0 + x * (0.5 + x * (1.0 / 6.0)))
}
/// The same polynomial, with every multiply-add rounded once.
fn exp_poly_fma(x: f32) -> f32 {
let p = x.mul_add(1.0 / 6.0, 0.5);
let p = x.mul_add(p, 1.0);
x.mul_add(p, 1.0)
}// 1 + x + x^2/2 + x^3/6, the first 4 terms of e^x, by Horner's rule.
__host__ __device__ float expPoly(float x)
{
return 1.0f + x * (1.0f + x * (0.5f + x * (1.0f / 6.0f)));
}
// The same polynomial, with every multiply-add rounded once, on both sides.
__host__ __device__ float expPolyFma(float x)
{
float p = fmaf(x, 1.0f / 6.0f, 0.5f);
p = fmaf(x, p, 1.0f);
return fmaf(x, p, 1.0f);
}
The test in Listing 10.18 wraps each function in an extended __host__ __device__ lambda, runs
it in transform on 2,097,152 values from −1 to 1, calls the same lambda on the CPU, and
compares the bits of the results with memcmp.
Listing 10.18 The differential test.
fn main() -> Result<(), Error> {
// ...
let prepared = module.prepare_poly(config)?;
module.poly(&stream, &prepared, &x, &mut y)?;
let gpu = y.to_host_vec(&stream)?;
let plain_differ = xs.iter().zip(&gpu).filter(|&(&x, &y)| exp_poly(x) != y).count();
println!(" x * y + z: {plain_differ} of {N} differ from the CPU");
let prepared = module.prepare_poly_fma(config)?;
module.poly_fma(&stream, &prepared, &x, &mut y)?;
let gpu = y.to_host_vec(&stream)?;
let fused_differ = xs.iter().zip(&gpu).filter(|&(&x, &y)| exp_poly_fma(x) != y).count();
println!(" mul_add: {fused_differ} of {N} differ from the CPU");
passed &= fused_differ == 0;
// ...
}int main()
{
// ...
auto plain = [] __host__ __device__ (float v) { return expPoly(v); };
auto fused = [] __host__ __device__ (float v) { return expPolyFma(v); };
transform<<<blocksFor(N), BLOCK>>>(x.view(), y.span(), plain);
check(cudaGetLastError());
std::vector<float> gpuPlain = y.toHost();
transform<<<blocksFor(N), BLOCK>>>(x.view(), y.span(), fused);
check(cudaGetLastError());
std::vector<float> gpuFused = y.toHost();
int plainDiffer = 0;
int fusedDiffer = 0;
for (int i = 0; i < N; ++i) {
float cpuPlain = plain(xs[i]);
float cpuFused = fused(xs[i]);
plainDiffer += std::memcmp(&cpuPlain, &gpuPlain[i], sizeof(float)) != 0;
fusedDiffer += std::memcmp(&cpuFused, &gpuFused[i], sizeof(float)) != 0;
}
std::printf(" x * y + z: %d of %d differ from the CPU\n", plainDiffer, N);
std::printf(" fmaf: %d of %d differ from the CPU\n", fusedDiffer, N);
passed = passed && fusedDiffer == 0;
// ...
}
1 function on both sides, 2097152 values in [-1, 1)
x * y + z: 585903 of 2097152 differ from the CPU
fmaf: 0 of 2097152 differ from the CPU
The version written as x * y + z differs in 585,903 values, 28% of them, although both
processors executed the same source code. To see how 1 expression can produce 2 results, let us
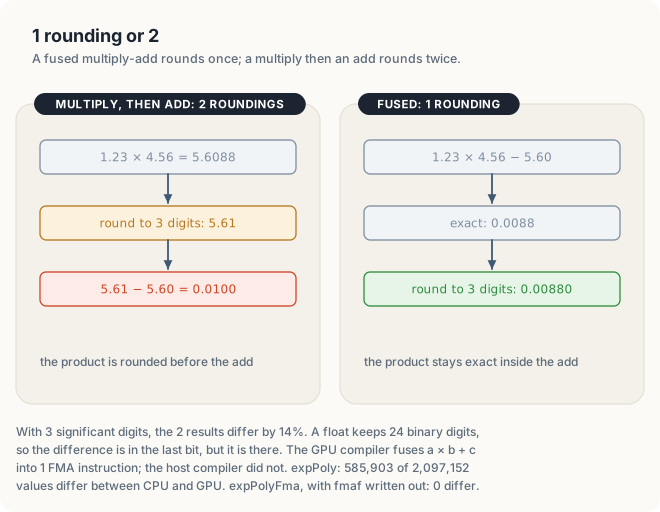
compute a × b + c by hand with a = 1.23, b = 4.56 and c = −5.60. A float keeps a fixed number of
binary digits, and we imitate it with decimal arithmetic that keeps 3 significant digits.
Suppose first that the multiplication and the addition are 2 separate operations, each rounded to 3 digits. The exact product 1.23 × 4.56 = 5.6088 is rounded to 5.61, and 5.61 − 5.60 gives 0.0100. Suppose instead that the 2 operations are performed as 1, and only the final result is rounded. The exact value 1.23 × 4.56 − 5.60 = 0.0088 is rounded to 0.00880. The 2 results differ by 14%, because the first rounding discarded 0.0012 of the product, and the subtraction of a nearly equal number then made that small part the largest part of the result. Figure 10.6 shows both computations.
Key observation a × b + c computed as 2 operations is rounded twice, and computed as 1 operation it is rounded once. The 2 results can differ in their last digits, and neither of them is wrong.
Definition 10.4 Fused multiply-add. A fused multiply-add (FMA) computes a × b + c as a single operation with a single rounding at the end, so the product is kept exact inside the addition.
Example. With 3 significant digits, the FMA of 1.23, 4.56 and −5.60 gives 0.00880, while a multiplication followed by an addition gives 0.0100.
The GPU has an FMA instruction, and by default the device compiler fuses each x * (...) + ...
in expPoly into it. The host compiler used here does not fuse, so the CPU rounds twice at each
of the 3 steps where the GPU rounds once.
A float keeps 24 binary digits, so in expPoly the 2 results differ only in their last binary
digits, by about 1 part in 107. Neither result is wrong. Each follows the rounding
rules for its own sequence of operations, and the fused version rounds fewer times. However, a
differential test that expects identical bits fails on 28% of its inputs. expPolyFma writes
each step as fmaf(a, b, c), which rounds once on both processors, because the host’s fmaf
follows the same rule of IEEE 754, the standard that defines the floating-point formats and
how each operation rounds. Its 0 differences confirm that the device compilation is correct.
The compiler option nvcc --fmad=false would disable fusion for the whole file, but it would
also make every kernel in the file slower, because each fused operation becomes 2 instructions.
Writing fmaf where the bits must agree states the intent in the code, at the place where it
applies.
The same source code can produce different bits on the CPU and the GPU, because the GPU fuses a
multiplication and an addition into an operation with 1 rounding. Use fmaf (or mul_add in
Rust) where the two sides must agree bit for bit.
10.4.3 Host and device functions in Rust
In cuda-oxide, an ordinary Rust function that is called from a kernel is compiled for the device as well as for the host, so it needs no qualifier.
Listing 10.19 The polynomial, called by a kernel and by the CPU.
/// 1 + x + x^2/2 + x^3/6, the first 4 terms of e^x, by Horner's rule.
fn exp_poly(x: f32) -> f32 {
1.0 + x * (1.0 + x * (0.5 + x * (1.0 / 6.0)))
}
/// The same polynomial, with every multiply-add rounded once.
fn exp_poly_fma(x: f32) -> f32 {
let p = x.mul_add(1.0 / 6.0, 0.5);
let p = x.mul_add(p, 1.0);
x.mul_add(p, 1.0)
}// 1 + x + x^2/2 + x^3/6, the first 4 terms of e^x, by Horner's rule.
__host__ __device__ float expPoly(float x)
{
return 1.0f + x * (1.0f + x * (0.5f + x * (1.0f / 6.0f)));
}
// The same polynomial, with every multiply-add rounded once, on both sides.
__host__ __device__ float expPolyFma(float x)
{
float p = fmaf(x, 1.0f / 6.0f, 0.5f);
p = fmaf(x, p, 1.0f);
return fmaf(x, p, 1.0f);
}
x.mul_add(a, b) is Rust’s FMA. The kernels poly and poly_fma call the 2 functions, and
main compares their results with those of the same functions run on the CPU.
1 function on both sides, 2097152 values in [-1, 1)
x * y + z: 585903 of 2097152 differ from the CPU
mul_add: 0 of 2097152 differ from the CPU
The counts are identical to those of the C++ program. The device compiler fuses, the host
compiler does not (Rust never fuses on its own), and mul_add rounds once on both processors.
10.5 constexpr and static_assert
A constant expression is an expression whose value the compiler can compute while it
compiles the program. A variable declared constexpr must be initialized with a constant
expression, and a function declared constexpr can be evaluated by the compiler when its
arguments are constant expressions. A static_assert(condition, message) evaluates its
condition during compilation and stops the compilation with the message when the condition is
false. Together, these features move checks from run time to compile time.
A useful application is checking the block size. A warp is a group of 32 threads of a block that the hardware executes together, 1 instruction for all 32. A block size that is not a multiple of 32 leaves the last warp of every block partly idle, and a size above 1,024 threads cannot be launched at all (section 10.1.3). Listing 10.20 checks both conditions while compiling.
Listing 10.20 The block size, checked while compiling.
const BLOCK: u32 = 256;
const _: () = assert!(BLOCK % 32 == 0, "a block is a whole number of warps");
const _: () = assert!(BLOCK <= 1024, "a block holds at most 1,024 threads");
const fn blocks_for(n: usize) -> u32 {
n.div_ceil(BLOCK as usize) as u32
}
const _: () = assert!(blocks_for(1000) == 4);constexpr int BLOCK = 256;
static_assert(BLOCK % 32 == 0, "a block is a whole number of warps");
static_assert(BLOCK <= 1024, "a block holds at most 1,024 threads");
constexpr int blocksFor(std::size_t n)
{
return static_cast<int>((n + BLOCK - 1) / BLOCK);
}
static_assert(blocksFor(1000) == 4);
The function blocksFor computes the number of blocks needed for a given number of elements,
rounding up. For 1,000 elements and blocks of 256 threads, it computes
(1,000 + 256 − 1) / 256 = 1,255 / 256 = 4 in integer division. Four blocks hold 1,024 threads,
enough for 1,000 elements, whereas 3 blocks, with 768 threads, would not be. Because blocksFor
is constexpr, the compiler performs this division itself, and the assertion
static_assert(blocksFor(1000) == 4) holds.
If we change the first line to constexpr int BLOCK = 100;, the file no longer compiles:
block100.cu(15): error: static assertion failed with "a block is a whole number of warps"
static_assert(BLOCK % 32 == 0, "a block is a whole number of warps");
^
block100.cu(23): error: static assertion failed
static_assert(blocksFor(1000) == 4);
^
With blocks of 100 threads, 1,000 elements need 10 blocks, so the second assertion fails as
well. A constexpr constant is preferable to #define BLOCK 256 because it has a type and a
scope and can be used in a static_assert, whereas a macro is text that the preprocessor pastes
wherever its name appears.
Rust writes the same checks as constant assertions. An assert! inside a const item is
evaluated by the compiler, and a false condition is a compile error.
Listing 10.21 The checks of Listing 10.20.
const BLOCK: u32 = 256;
const _: () = assert!(BLOCK % 32 == 0, "a block is a whole number of warps");
const _: () = assert!(BLOCK <= 1024, "a block holds at most 1,024 threads");
const fn blocks_for(n: usize) -> u32 {
n.div_ceil(BLOCK as usize) as u32
}
const _: () = assert!(blocks_for(1000) == 4);constexpr int BLOCK = 256;
static_assert(BLOCK % 32 == 0, "a block is a whole number of warps");
static_assert(BLOCK <= 1024, "a block holds at most 1,024 threads");
constexpr int blocksFor(std::size_t n)
{
return static_cast<int>((n + BLOCK - 1) / BLOCK);
}
static_assert(blocksFor(1000) == 4);
With const BLOCK: u32 = 100;, both Rust assertions fail while compiling:
error[E0080]: evaluation panicked: a block is a whole number of warps
--> src/main.rs:21:15
|
21 | const _: () = assert!(BLOCK % 32 == 0, "a block is a whole number of warps");
| ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^ evaluation of `_` failed here
error[E0080]: evaluation panicked: assertion failed: blocks_for(1000) == 4
--> src/main.rs:28:15
|
28 | const _: () = assert!(blocks_for(1000) == 4);
| ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^ evaluation of `_` failed here
10.6 CUDA 12 and the cuda:: Namespace
CUDA includes a C++ library for device code called libcu++. A namespace is a named group
of declarations, which keeps names of different libraries apart; the full name std::vector
means the name vector in the namespace std of the standard library. The names of libcu++ are
in 2 namespaces: cuda::std:: holds versions of standard library types that work in device
code, and cuda:: holds extensions specific to the GPU. Both headers used in this section,
<cuda/std/span> and <cuda/atomic>, are available in CUDA 12.6 and in CUDA 13.2.
10.6.1 cuda::std::span
The C-style kernel scale received a pointer and a separate count n. Consider a program with
2 device arrays: a, at address 0x7f00, with 1,000 floats, and b, with 2,000 floats. A call
scale<<<8, 256>>>(a, out, 2000, 2.0f) passes the count of b together with the pointer of
a. The kernel cannot tell, because it receives 2 unrelated numbers, 0x7f00 and 2,000. Threads
0 to 999 read a correctly. Threads 1,000 to 1,999 pass the test i < n and read the 1,000
floats that follow a in memory, which belong to another allocation or to none. No error is
reported. The mistake becomes impossible if the length travels together with the pointer from
the place where both are known, the buffer.
Definition 10.5 Span. A span is a pointer and a length kept together: a view of a contiguous array that the span does not own. Destroying a span frees nothing.
Example. A span of the array a above holds the 2 values 0x7f00 and 1,000. A kernel that
receives it tests i < in.size(), that is i < 1000.
cuda::std::span<const T> allows reading, and cuda::std::span<T> allows writing as well.
DeviceBuffer::view() and span() return one of each, and transform receives them:
fn scale_on_gpu(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
factor: f32,
) -> Result<Option<Vec<f32>>, Error> {
// ...
module.scale(stream, &prepared, factor, &input, &mut out)?;
// ...
}transform<<<blocksFor(in.size()), BLOCK>>>(in.view(), out.span(), Scale{factor});
The length of a span comes from the buffer it views, so the bounds check i < in.size() always
uses the correct length. A span occupies 16 bytes, a pointer
and a length, and it is passed to the kernel by value like any other argument. A Rust slice,
&[T], has always consisted of a pointer and a length, which is why the Rust kernels of this
book never take a separate count.
10.6.2 cuda::atomic_ref and thread scopes
Recall from Chapter 5 why a shared counter needs special care. An ordinary increment count += 1 is 3 steps: read the value, add 1, write the result. Suppose the counter holds 5 and 2
threads increment it at the same time. Both read 5, both compute 6, and both write 6. 2
increments were made, but the counter rose by 1, and 1 count is lost. An atomic operation on
a memory location completes as a single indivisible step, so that no other thread can observe or
modify the location partway through it. With an atomic increment, the second thread reads 6, not
5, and the counter ends at 7. cuda::atomic_ref<int, scope> applies atomic operations to an
ordinary int that already exists, in this example a counter in a DeviceBuffer<int>. The
int itself remains a plain int.
The memory order of an atomic operation specifies what other memory accesses it orders, that
is, whether writes made before the operation become visible to a thread that observes its
result. cuda::memory_order_relaxed orders nothing except the counter itself. This is
sufficient for a count, and it is the least expensive order.
The thread scope specifies the set of threads that must agree on the value. For example, a counter in shared memory, the on-chip memory that only the threads of 1 block can access, is never seen by the threads of other blocks, so only the threads of its block need to agree on it. A counter in global memory, the main memory of the GPU, can be reached by every thread of the kernel. The narrower the set, the less work the hardware must do to keep those threads in agreement. The table lists the 3 scopes.
| Scope | The threads that must agree | Example |
|---|---|---|
cuda::thread_scope_block | the threads of 1 block | a counter in shared memory (Chapter 5) |
cuda::thread_scope_device | every thread of 1 GPU | a counter in global memory |
cuda::thread_scope_system | the CPU and every GPU | a flag in memory both processors write |
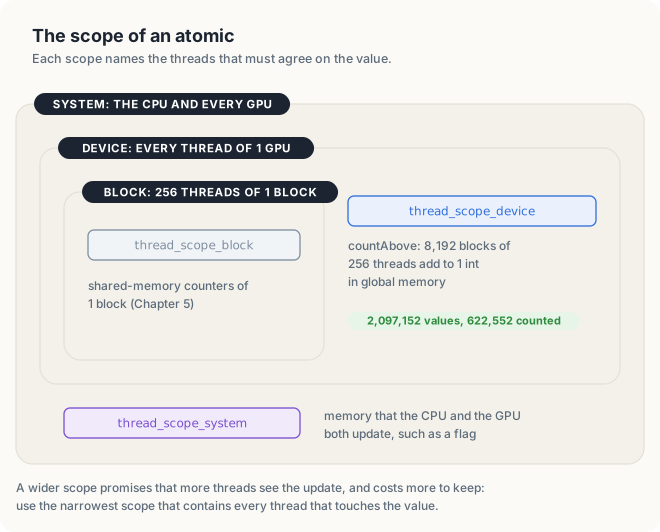
Listing 10.22 A count with cuda::atomic_ref.
mod kernels {
// ...
/// Count the values above a threshold. DeviceAtomicU32 adds atomically, device-wide.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn count_above(input: &[f32], threshold: f32, count: &[DeviceAtomicU32]) {
let i = thread::index_1d().get();
if i < input.len() && input[i] > threshold {
count[0].fetch_add(1, AtomicOrdering::Relaxed);
}
}
}// Count the values above a threshold. atomic_ref makes an ordinary int atomic.
template <Number T>
__global__ void countAbove(cuda::std::span<const T> in, T threshold, int* count)
{
std::size_t i = blockIdx.x * std::size_t(blockDim.x) + threadIdx.x;
if (i < in.size() && in[i] > threshold) {
cuda::atomic_ref<int, cuda::thread_scope_device> total(*count);
total.fetch_add(1, cuda::memory_order_relaxed);
}
}
The kernel in Listing 10.22 counts the results of expPolyFma that are greater than 1.5. Its
2,097,152 threads, in 8,192 blocks of 256, all add to a single int in global memory, so the
scope must be the whole device.
span and atomic_ref: 622552 values above 1.5, CPU 622552
PASSED
We can verify this count by hand. The polynomial reaches 1.5 at x = 0.40629, slightly to the right of ln 1.5 = 0.40547, because the polynomial is smaller than ex for x > 0. The inputs are evenly spaced from −1 to 1, so the fraction above 0.40629 is (1 − 0.40629) ÷ 2 = 0.29686, and 0.29686 × 2,097,152 = 622,552 values, the number that both processors counted.
The Rust programs of Chapter 5 use DeviceAtomicU32 from cuda-device, which serves the same
purpose. The Rust kernel count_above of Listing 10.22 uses it and counted the same 622,552
values.
10.7 C++20 Concepts
A template accepts any type for which its body compiles. The body of transform contains only
out[i] = f(in[i]), and C++ converts between number types implicitly. An operation f that
takes a float and returns a bool therefore passes: the bool is converted to a float and
stored. The template compiles, and every result is 0.0 or 1.0. The mistake is in the call, but
the body of the template has no way to see it, because the body never states what type f must
return. A condition written next to the template parameters can state it.
Definition 10.6 Concept. A concept is a named condition on template parameters that the compiler checks when the template is used. A use whose types do not satisfy the condition is a compile error at the call.
Example. The concept Number<T> of Listing 10.23 holds for float and int and fails for
std::string, so transform<std::string, ...> is rejected at the call.
Listing 10.23 defines the 2 concepts that transform requires.
Listing 10.23 2 concepts.
mod kernels {
// ...
/// out[i] = f(input[i]), for any T and any operation f from T to T, such as a closure.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn transform<T, F>(f: F, input: &[T], mut out: DisjointSlice<T>)
where
T: Copy,
F: Fn(T) -> T + Copy,
// ...
}template <typename T>
concept Number = std::integral<T> || std::floating_point<T>;
template <typename F, typename T>
concept UnaryOp = std::invocable<F, T> && std::same_as<std::invoke_result_t<F, T>, T>;
Number<T> holds when T is an integer or floating-point type. UnaryOp<F, T> holds when an
F can be called with a T and returns exactly a T. Writing UnaryOp<T> F in the template’s
parameter list applies the concept to F, with T as its second argument. We can evaluate both
conditions by hand for 2 calls. For transform with T = float and F = Scale<float>,
Number<float> holds, and Scale<float> called with a float returns a float, so
UnaryOp<Scale<float>, float> holds as well. For F = a lambda of type (float)->bool, the
lambda can be called with a float, but it returns a bool, which is not exactly a float, so
UnaryOp fails.
To see what these conditions prevent, we replaced Scale{factor} in scaleOnGpu with an
operation that returns a bool, [] __device__ (float v) { return v > 0.0f; }, and compiled it
first against a version of transform without the concepts. It compiled without a warning,
because C++ converts a bool to a float implicitly, and it ran:
copies sized by the type: 0 of 2097152 correct
Every result was 1.0, the float value of true, and none was the expected 2.0. With the
concepts, the same call does not compile:
concept.cu(118): error: no instance of function template "transform" matches the argument list
argument types are: (cuda::std::__4::span<const float, 18446744073709551615UL>, cuda::std::__4::span<float, 18446744073709551615UL>, lambda [](float)->bool)
concept.cu(36): note #3327-D: candidate function template "transform" failed deduction
The message points to the call and shows the type of the lambda, (float)->bool, which is the
error. Template argument deduction is the step in which the compiler works out the template
parameters, here T and F, from the types of the arguments of a call. When a deduced type
fails a concept, the compiler discards the template, and the message reports that deduction
failed. A Rust generic states its conditions in the same way, as trait bounds. Rust checks
them when the function is used, and also when it is defined: the body of scale<T> may perform
only the operations that Copy + Mul<Output = T> allows. The closure |v: f32| v > 0.0, passed
to the Rust kernel transform, fails its bound F: Fn(T) -> T at the call:
error[E0271]: expected `{closure@main.rs:455:20}` to return `f32`, but it returns `bool`
--> src/main.rs:455:29
|
455 | let positive = |v: f32| v > 0.0;
| -------- ^^^^^^^ expected `f32`, found `bool`
| |
| this closure
456 | let prepared = module.prepare_transform_for(&0.0f32, &positive, config)?;
| --------------------- --------- closure used here
10.8 Style Summary
Figure 10.8 collects the errors examined in this chapter and shows where each is detected in the C API, in modern C++ and in Rust.
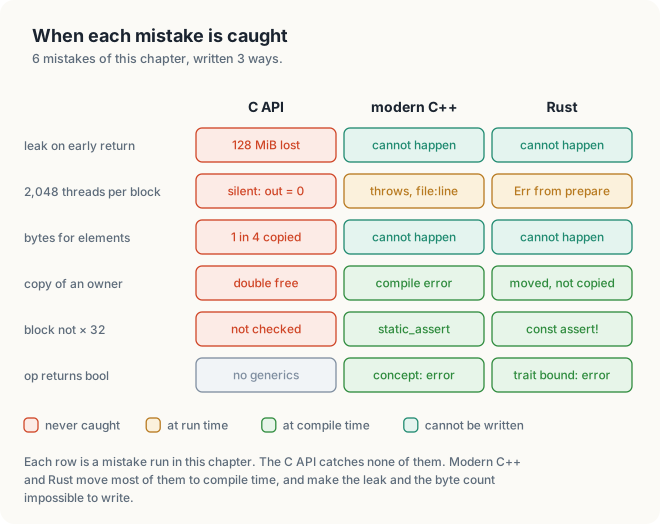
The common principle is to turn a rule that the programmer must remember into a rule that the
program cannot break. Some rules can no longer be broken because no call site performs the step
any more: a destructor frees the memory, and a type computes the byte count. Some violations
become compile errors: deleted copies, static_assert and concepts. The remaining ones become
run-time errors that cannot be ignored, such as an exception or an Err passed up by ?. What
C++ cannot check, such as index arithmetic, Rust kernels confine to DisjointSlice, the
cuda-oxide output type through which each thread can write only the element at its own index,
and to unsafe blocks with a written justification (Chapter 13). The table summarizes the
replacements.
| C-style habit | Modern replacement | What the compiler now does |
|---|---|---|
cudaMalloc and cudaFree by hand | DeviceBuffer<T> | frees on every path, forbids 2 owners |
| byte counts at each call | sizes from sizeof(T) inside the class | no call site writes a byte count |
CHECK macro | check() with std::source_location, exceptions | names the failed line; frees while unwinding |
| 1 kernel per type | template kernels and function objects | writes 1 kernel per type |
#define TILE 16 | constexpr int TILE = 16 and static_assert | checks configuration while compiling |
pointer and separate n | cuda::std::span | keeps the length with the pointer |
atomicAdd on a raw pointer | cuda::atomic_ref with a scope | states which threads must agree |
| unconstrained templates | concepts | rejects a wrong operation at the call |
None of these techniques has a run-time cost: transform<float> ran at 74.6 GB/s, and the
hand-written kernel at 74.5 GB/s.
10.9 The complete programs
Listing 10.24 The complete programs. code/oxide/ch10_modern/src/main.rs, code/ch10_modern/device_buffer.hpp, code/ch10_modern/raw.cu, code/ch10_modern/modern.cu
//! Chapter 10 in Rust: ownership frees device memory, generic kernels, 1 function, 2 sides.
//!
//! cargo oxide run
use std::ffi::c_void;
use std::marker::PhantomData;
use std::mem::ManuallyDrop;
use std::ops::Mul;
use std::panic::Location;
use std::sync::Arc;
use std::time::Instant;
use cuda_core::sys;
use cuda_core::sys::CUmemPool_attribute_enum_CU_MEMPOOL_ATTR_USED_MEM_CURRENT as USED_MEM;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, DeviceCopy, DriverError, IntoResult};
use cuda_core::LaunchConfig1D;
use cuda_device::atomic::{AtomicOrdering, DeviceAtomicU32};
use cuda_device::{DisjointSlice, cuda_module, kernel, launch_contract, thread};
const BLOCK: u32 = 256;
const _: () = assert!(BLOCK % 32 == 0, "a block is a whole number of warps");
const _: () = assert!(BLOCK <= 1024, "a block holds at most 1,024 threads");
const fn blocks_for(n: usize) -> u32 {
n.div_ceil(BLOCK as usize) as u32
}
const _: () = assert!(blocks_for(1000) == 4);
const N: usize = 1 << 21;
const BIG: usize = 1 << 24;
type Error = Box<dyn std::error::Error>;
/// 1 + x + x^2/2 + x^3/6, the first 4 terms of e^x, by Horner's rule.
fn exp_poly(x: f32) -> f32 {
1.0 + x * (1.0 + x * (0.5 + x * (1.0 / 6.0)))
}
/// The same polynomial, with every multiply-add rounded once.
fn exp_poly_fma(x: f32) -> f32 {
let p = x.mul_add(1.0 / 6.0, 0.5);
let p = x.mul_add(p, 1.0);
x.mul_add(p, 1.0)
}
#[cuda_module]
mod kernels {
use super::*;
/// out[i] = factor * input[i], for any T that can be multiplied.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scale<T>(factor: T, input: &[T], mut out: DisjointSlice<T>)
where
T: Copy + Mul<Output = T>,
{
let idx = thread::index_1d();
let i = idx.get();
if let Some(slot) = out.get_mut(idx) {
*slot = factor * input[i];
}
}
/// out[i] = f(input[i]), for any T and any operation f from T to T, such as a closure.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn transform<T, F>(f: F, input: &[T], mut out: DisjointSlice<T>)
where
T: Copy,
F: Fn(T) -> T + Copy,
{
let idx = thread::index_1d();
let i = idx.get();
if let Some(slot) = out.get_mut(idx) {
*slot = f(input[i]);
}
}
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn poly(x: &[f32], mut y: DisjointSlice<f32>) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(slot) = y.get_mut(idx) {
*slot = exp_poly(x[i]);
}
}
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn poly_fma(x: &[f32], mut y: DisjointSlice<f32>) {
let idx = thread::index_1d();
let i = idx.get();
if let Some(slot) = y.get_mut(idx) {
*slot = exp_poly_fma(x[i]);
}
}
/// Count the values above a threshold. DeviceAtomicU32 adds atomically, device-wide.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn count_above(input: &[f32], threshold: f32, count: &[DeviceAtomicU32]) {
let i = thread::index_1d().get();
if i < input.len() && input[i] > threshold {
count[0].fetch_add(1, AtomicOrdering::Relaxed);
}
}
}
/// Bytes in use from the pool that stream-ordered allocations draw on, in MiB.
fn pool_mib(ctx: &CudaContext) -> Result<f64, DriverError> {
ctx.synchronize()?;
let mut pool = std::ptr::null_mut();
let mut used: u64 = 0;
let used_ptr = (&mut used as *mut u64).cast::<c_void>();
// SAFETY: both out-pointers are valid for the length of each call.
unsafe {
sys::cuDeviceGetDefaultMemPool(&mut pool, ctx.cu_device()).result()?;
sys::cuMemPoolGetAttribute(pool, USED_MEM, used_ptr).result()?;
}
Ok(used as f64 / 1_048_576.0)
}
/// Mistake 1 of raw.cu: ManuallyDrop turns the drops off, so the frees are written by
/// hand, and the early return skips them.
fn scale_by_hand(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
factor: f32,
) -> Result<Option<Vec<f32>>, Error> {
let mut input = ManuallyDrop::new(pool_copy(stream, host)?);
let mut out = ManuallyDrop::new(pool_copy(stream, host)?);
if factor == 0.0 {
return Ok(None); // nothing to scale
}
let config = LaunchConfig1D::new(blocks_for(host.len()), BLOCK, 0);
let prepared = module.prepare_scale::<f32>(config)?;
module.scale(stream, &prepared, factor, &input, &mut out)?;
let result = out.to_host_vec(stream)?;
// SAFETY: neither buffer is used after its drop.
unsafe {
ManuallyDrop::drop(&mut input);
ManuallyDrop::drop(&mut out);
}
Ok(Some(result))
}
/// Mistake 3 of raw.cu: the driver's copy counts bytes, but `host.len()` counts floats.
fn copy_count_as_bytes(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
) -> Result<usize, Error> {
let input = DeviceBuffer::<f32>::zeroed(stream, host.len())?;
let mut out = DeviceBuffer::<f32>::zeroed(stream, host.len())?;
let src = host.as_ptr().cast::<c_void>();
// SAFETY: both sides hold 4 bytes per float, so host.len() bytes fit in each.
check(unsafe { sys::cuMemcpyHtoD_v2(input.cu_deviceptr(), src, host.len()) })?;
let config = LaunchConfig1D::new(blocks_for(host.len()), BLOCK, 0);
let prepared = module.prepare_scale::<f32>(config)?;
module.scale(stream, &prepared, 2.0, &input, &mut out)?;
let result = out.to_host_vec(stream)?;
Ok(result.iter().filter(|&&x| x == 2.0).count())
}
/// Turn a driver result into an error that names the caller's file and line.
#[track_caller]
fn check(result: sys::CUresult) -> Result<(), Error> {
let place = Location::caller();
match result.result() {
Ok(()) => Ok(()),
Err(error) => Err(format!("{}:{}: {error}", place.file(), place.line()).into()),
}
}
/// `count` values of T in device memory from the pool, owned by exactly 1 variable.
struct PoolBuffer<T> {
ptr: sys::CUdeviceptr,
count: usize,
stream: Arc<CudaStream>,
elements: PhantomData<T>,
}
impl<T: DeviceCopy> PoolBuffer<T> {
#[track_caller]
fn new(stream: &Arc<CudaStream>, count: usize) -> Result<Self, Error> {
let mut ptr = 0;
let bytes = count * size_of::<T>();
// SAFETY: `ptr` is a valid out-pointer, and the stream belongs to this context.
check(unsafe { sys::cuMemAllocAsync(&mut ptr, bytes, stream.cu_stream()) })?;
let elements = PhantomData;
Ok(Self { ptr, count, stream: stream.clone(), elements })
}
#[track_caller]
fn from_host(stream: &Arc<CudaStream>, host: &[T]) -> Result<Self, Error> {
let buffer = Self::new(stream, host.len())?;
let src = host.as_ptr().cast::<c_void>();
// SAFETY: the buffer and `host` both hold buffer.bytes() bytes.
check(unsafe { sys::cuMemcpyHtoD_v2(buffer.ptr, src, buffer.bytes()) })?;
Ok(buffer)
}
}
/// A move: `b` takes the allocation, and the name `a` can no longer be used.
fn move_once(stream: &Arc<CudaStream>, host: &[f32]) -> Result<usize, Error> {
let a = PoolBuffer::from_host(stream, host)?;
let b = a;
Ok(b.len())
}
impl<T> PoolBuffer<T> {
fn len(&self) -> usize {
self.count
}
fn bytes(&self) -> usize {
self.count * size_of::<T>()
}
}
impl<T> Drop for PoolBuffer<T> {
fn drop(&mut self) {
// A drop cannot report an error, so the result is ignored.
// SAFETY: `ptr` came from cuMemAllocAsync, and only this drop frees it.
let _ = unsafe { sys::cuMemFreeAsync(self.ptr, self.stream.cu_stream()) };
}
}
/// The early return of raw.cu with PoolBuffer: both drops run on the return.
fn early_return_pool(
stream: &Arc<CudaStream>,
host: &[f32],
factor: f32,
) -> Result<bool, Error> {
let input = PoolBuffer::from_host(stream, host)?;
let out = PoolBuffer::<f32>::new(stream, input.len())?;
if factor == 0.0 {
return Ok(false);
}
Ok(out.len() == input.len())
}
/// A copy of `host` in device memory from the pool, freed when the buffer is dropped.
fn pool_copy<T: DeviceCopy>(
stream: &Arc<CudaStream>,
host: &[T],
) -> Result<DeviceBuffer<T>, DriverError> {
// SAFETY: the copy below writes every element before anything reads one.
let mut buffer = unsafe { DeviceBuffer::uninitialized_async(stream, host.len())? };
buffer.copy_from_host(stream, host)?;
Ok(buffer)
}
/// The function of raw.cu. Every return, early or not, drops both buffers.
fn scale_on_gpu(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
factor: f32,
) -> Result<Option<Vec<f32>>, Error> {
let input = pool_copy(stream, host)?;
let mut out = pool_copy(stream, host)?;
if factor == 0.0 {
return Ok(None);
}
let blocks = blocks_for(host.len());
let prepared = module.prepare_scale::<f32>(LaunchConfig1D::new(blocks, BLOCK, 0))?;
module.scale(stream, &prepared, factor, &input, &mut out)?;
Ok(Some(out.to_host_vec(stream)?))
}
/// The launch of 2,048 threads per block. The `?` returns before any kernel runs.
fn launch_too_wide(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
host: &[f32],
) -> Result<(), Error> {
let input = pool_copy(stream, host)?;
let mut out = pool_copy(stream, host)?;
let blocks = (host.len() as u32) / 2048;
let prepared = module.prepare_scale::<f32>(LaunchConfig1D::new(blocks, 2048, 0))?;
module.scale(stream, &prepared, 2.0, &input, &mut out)?;
Ok(())
}
/// The same function with `std::mem::forget`: the only way to skip a drop.
fn forget_on_gpu(stream: &Arc<CudaStream>, host: &[f32]) -> Result<(), DriverError> {
let input = pool_copy(stream, host)?;
std::mem::forget(input);
Ok(())
}
/// Average time of `runs` runs of `launch`, in milliseconds, after 500 ms of warm-up:
/// the clocks of the GPU and of its memory rise under sustained load.
fn time_ms<F>(stream: &CudaStream, runs: u32, mut launch: F) -> Result<f64, Error>
where
F: FnMut() -> Result<(), Error>,
{
let start = Instant::now();
while start.elapsed().as_millis() < 500 {
launch()?;
stream.synchronize()?;
}
let start = Instant::now();
for _ in 0..runs {
launch()?;
}
stream.synchronize()?;
Ok(start.elapsed().as_secs_f64() * 1e3 / runs as f64)
}
/// Time scale::<T> on `data`, print the rate, and check every result.
fn time_scale<T>(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
name: &str,
data: &[T],
factor: T,
) -> Result<bool, Error>
where
T: DeviceCopy + Mul<Output = T> + PartialEq,
{
let input = DeviceBuffer::from_host(stream, data)?;
let mut out = DeviceBuffer::<T>::zeroed(stream, data.len())?;
let blocks = blocks_for(data.len());
let prepared = module.prepare_scale::<T>(LaunchConfig1D::new(blocks, BLOCK, 0))?;
let mut launch = || Ok(module.scale(stream, &prepared, factor, &input, &mut out)?);
let ms = time_ms(stream, 20, &mut launch)?;
let bytes = 2 * data.len() * size_of::<T>();
println!(" {name:<14} {ms:7.2} ms {:6.1} GB/s", bytes as f64 / ms / 1e6);
let result = out.to_host_vec(stream)?;
Ok(result.iter().zip(data).all(|(&y, &x)| y == factor * x))
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let host = vec![1.0f32; N];
let mut passed = true;
println!("ownership");
let before = pool_mib(&ctx)?;
for _ in 0..8 {
scale_on_gpu(&module, &stream, &host, 0.0)?;
}
let lost = pool_mib(&ctx)? - before;
println!(" 8 calls that return early: {lost:.1} MiB lost");
passed &= lost == 0.0;
match launch_too_wide(&module, &stream, &host) {
Ok(()) => passed = false,
Err(error) => println!(" 2048 threads per block returned: {error}"),
}
println!(" after the error: {:.1} MiB in use", pool_mib(&ctx)?);
let result = scale_on_gpu(&module, &stream, &host, 2.0)?.unwrap_or_default();
let correct = result.iter().filter(|&&x| x == 2.0).count();
println!(" copies sized by the type: {correct} of {N} correct");
passed &= correct == N;
for _ in 0..8 {
forget_on_gpu(&stream, &host)?;
}
println!(" 8 calls with mem::forget: {:.1} MiB lost", pool_mib(&ctx)? - before);
println!("1 generic kernel, 3 types, {BIG} values");
let floats: Vec<f32> = (0..BIG).map(|i| (i % 1000) as f32).collect();
let doubles: Vec<f64> = (0..BIG).map(|i| (i % 1000) as f64).collect();
let ints: Vec<i32> = (0..BIG).map(|i| (i % 1000) as i32).collect();
passed &= time_scale(&module, &stream, "scale::<f32>", &floats, 3.0)?;
passed &= time_scale(&module, &stream, "scale::<f64>", &doubles, 3.0)?;
passed &= time_scale(&module, &stream, "scale::<i32>", &ints, 3)?;
println!("1 function on both sides, {N} values in [-1, 1)");
let xs: Vec<f32> = (0..N).map(|i| -1.0 + 2.0 * i as f32 / N as f32).collect();
let x = DeviceBuffer::from_host(&stream, &xs)?;
let mut y = DeviceBuffer::<f32>::zeroed(&stream, N)?;
let config = LaunchConfig1D::new(blocks_for(N), BLOCK, 0);
let prepared = module.prepare_poly(config)?;
module.poly(&stream, &prepared, &x, &mut y)?;
let gpu = y.to_host_vec(&stream)?;
let plain_differ = xs.iter().zip(&gpu).filter(|&(&x, &y)| exp_poly(x) != y).count();
println!(" x * y + z: {plain_differ} of {N} differ from the CPU");
let prepared = module.prepare_poly_fma(config)?;
module.poly_fma(&stream, &prepared, &x, &mut y)?;
let gpu = y.to_host_vec(&stream)?;
let fused_differ = xs.iter().zip(&gpu).filter(|&(&x, &y)| exp_poly_fma(x) != y).count();
println!(" mul_add: {fused_differ} of {N} differ from the CPU");
passed &= fused_differ == 0;
println!("the mistakes of raw.cu, in Rust");
let before = pool_mib(&ctx)?;
for _ in 0..8 {
scale_by_hand(&module, &stream, &host, 0.0)?;
}
let lost = pool_mib(&ctx)? - before;
println!(" 1. 8 calls with ManuallyDrop that return early: {lost:.1} MiB lost");
let correct = copy_count_as_bytes(&module, &stream, &host)?;
println!(" 3. a copy of N bytes, not N floats: {correct} of {N} correct");
println!("PoolBuffer, check and closures");
let before = pool_mib(&ctx)?;
for _ in 0..8 {
early_return_pool(&stream, &host, 0.0)?;
}
let lost = pool_mib(&ctx)? - before;
println!(" 8 calls that return early: {lost:.1} MiB lost");
passed &= lost == 0.0;
let moved = move_once(&stream, &host)?;
let in_use = pool_mib(&ctx)? - before;
println!(" after a move: {moved} values, {in_use:.1} MiB in use");
passed &= moved == N;
if let Err(error) = PoolBuffer::<f32>::new(&stream, 1 << 45) {
println!(" 128 TiB returned: {error}");
}
let factor = 3.0f32;
let triple = move |v: f32| factor * v;
let input = DeviceBuffer::from_host(&stream, &floats)?;
let mut out = DeviceBuffer::<f32>::zeroed(&stream, BIG)?;
let config = LaunchConfig1D::new(blocks_for(BIG), BLOCK, 0);
let prepared = module.prepare_transform_for(&factor, &triple, config)?;
module.transform(&stream, &prepared, triple, &input, &mut out)?;
let result = out.to_host_vec(&stream)?;
let correct = result.iter().zip(&floats).filter(|&(&y, &x)| y == triple(x)).count();
println!(" transform with a closure: {correct} of {BIG} correct");
passed &= correct == BIG;
let count = DeviceBuffer::<u32>::zeroed(&stream, 1)?.cast_elem::<DeviceAtomicU32>();
let config = LaunchConfig1D::new(blocks_for(N), BLOCK, 0);
let prepared = module.prepare_count_above(config)?;
module.count_above(&stream, &prepared, &y, 1.5, &count)?;
let gpu_count = count.cast_elem::<u32>().to_host_vec(&stream)?[0] as usize;
let cpu_count = gpu.iter().filter(|&&v| v > 1.5).count();
println!("slice and DeviceAtomicU32: {gpu_count} values above 1.5, CPU {cpu_count}");
passed &= gpu_count == cpu_count;
if passed {
println!("PASSED");
Ok(())
} else {
Err("FAILED".into())
}
}device_buffer.hpp
// Chapter 10: a check without a macro, and a device allocation that frees itself.
#pragma once
#include <cstddef>
#include <source_location>
#include <stdexcept>
#include <string>
#include <type_traits>
#include <utility>
#include <vector>
#include <cuda/std/span>
#include <cuda_runtime.h>
using Where = std::source_location;
// Throw if a CUDA call failed. The default argument records the caller's file and line.
inline void check(cudaError_t err, Where where = Where::current())
{
if (err == cudaSuccess) {
return;
}
std::string place = std::string(where.file_name()) + ":" + std::to_string(where.line());
throw std::runtime_error(place + ": " + cudaGetErrorString(err));
}
// Bytes in use from the pool that cudaMallocAsync draws on, in MiB.
inline double poolMiB()
{
cudaMemPool_t pool;
check(cudaDeviceGetDefaultMemPool(&pool, 0));
unsigned long long used = 0;
check(cudaMemPoolGetAttribute(pool, cudaMemPoolAttrUsedMemCurrent, &used));
return used / 1048576.0;
}
// `count` values of T in device memory, owned by exactly 1 object.
template <typename T>
class DeviceBuffer {
static_assert(std::is_trivially_copyable_v<T>, "device memory holds plain bytes");
public:
explicit DeviceBuffer(std::size_t count) : count_(count)
{
check(cudaMallocAsync(&data_, bytes(), 0));
}
explicit DeviceBuffer(const std::vector<T>& host) : DeviceBuffer(host.size())
{
check(cudaMemcpy(data_, host.data(), bytes(), cudaMemcpyHostToDevice));
}
~DeviceBuffer()
{
release();
}
DeviceBuffer(const DeviceBuffer&) = delete;
DeviceBuffer& operator=(const DeviceBuffer&) = delete;
DeviceBuffer(DeviceBuffer&& other) noexcept
: data_(std::exchange(other.data_, nullptr)), count_(std::exchange(other.count_, 0))
{
}
DeviceBuffer& operator=(DeviceBuffer&& other) noexcept
{
if (this != &other) {
release();
data_ = std::exchange(other.data_, nullptr);
count_ = std::exchange(other.count_, 0);
}
return *this;
}
T* data() const { return data_; }
std::size_t size() const { return count_; }
std::size_t bytes() const { return count_ * sizeof(T); }
cuda::std::span<const T> view() const { return {data_, count_}; }
cuda::std::span<T> span() { return {data_, count_}; }
std::vector<T> toHost() const
{
std::vector<T> host(count_);
check(cudaMemcpy(host.data(), data_, bytes(), cudaMemcpyDeviceToHost));
return host;
}
private:
void release()
{
if (data_ != nullptr) { // a moved-from buffer owns nothing
cudaFreeAsync(data_, 0);
}
}
T* data_ = nullptr;
std::size_t count_ = 0;
};
raw.cu
// Chapter 10: 3 mistakes that the CUDA C API lets through. Each one runs and does damage.
// Build: nvcc -arch=native raw.cu -o raw
#include <cstdio>
#include <vector>
#include <cuda_runtime.h>
const int N = 1 << 21; // 2,097,152 floats, 8 MiB per buffer
const int CALLS = 8;
__global__ void scale(const float* in, float* out, int n, float factor)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
out[i] = factor * in[i];
}
}
// Bytes in use from the pool that cudaMallocAsync draws on, in MiB.
double poolMiB()
{
    cudaMemPool_t pool;
    cudaDeviceGetDefaultMemPool(&pool, 0);

    unsigned long long used = 0;
    cudaMemPoolGetAttribute(pool, cudaMemPoolAttrUsedMemCurrent, &used);
    return used / 1048576.0;
}
// Mistake 1: the early return skips both frees.
bool scaleOnGpu(const std::vector<float>& host, std::vector<float>& result, float factor)
{
    int n = static_cast<int>(host.size());
    size_t bytes = n * sizeof(float);

    float* in = nullptr;
    float* out = nullptr;
    cudaMallocAsync(&in, bytes, 0);
    cudaMallocAsync(&out, bytes, 0);

    if (factor == 0.0f) {
        return false;                         // nothing to scale
    }

    cudaMemcpy(in, host.data(), bytes, cudaMemcpyHostToDevice);
    scale<<<(n + 255) / 256, 256>>>(in, out, n, factor);
    cudaMemcpy(result.data(), out, bytes, cudaMemcpyDeviceToHost);

    cudaFreeAsync(in, 0);
    cudaFreeAsync(out, 0);
    return true;
}
int main()
{
std::vector<float> host(N, 1.0f);
std::vector<float> result(N, 0.0f);
size_t bytes = N * sizeof(float);
double before = poolMiB();
for (int call = 0; call < CALLS; ++call) {
scaleOnGpu(host, result, 0.0f);
}
double lost = poolMiB() - before;
std::printf("1. %d calls that return early: %.1f MiB lost\n", CALLS, lost);
float* in = nullptr;
float* out = nullptr;
cudaMallocAsync(&in, bytes, 0);
cudaMallocAsync(&out, bytes, 0);
cudaMemcpy(in, host.data(), bytes, cudaMemcpyHostToDevice);
cudaMemset(out, 0, bytes);
// Mistake 2: 2,048 threads per block is over the limit of 1,024. Nothing reports it.
scale<<<N / 2048, 2048>>>(in, out, N, 2.0f);
cudaMemcpy(result.data(), out, bytes, cudaMemcpyDeviceToHost);
std::printf("2. 2048 threads per block: out[0] = %.1f, expected 2.0\n", result[0]);
cudaError_t err = cudaGetLastError();
std::printf(" the error, found only by asking: %s\n", cudaGetErrorString(err));
// Mistake 3: N counts floats, but cudaMemcpy counts bytes.
cudaMemset(in, 0, bytes);
cudaMemcpy(in, host.data(), N, cudaMemcpyHostToDevice);
scale<<<N / 256, 256>>>(in, out, N, 2.0f);
cudaMemcpy(result.data(), out, bytes, cudaMemcpyDeviceToHost);
int correct = 0;
for (float x : result) {
correct += (x == 2.0f);
}
std::printf("3. a copy of N bytes, not N floats: %d of %d correct\n", correct, N);
cudaFreeAsync(in, 0);
cudaFreeAsync(out, 0);
}
modern.cu
// Chapter 10: the work of raw.cu with RAII, templates, span, atomic_ref and concepts.
// Build: nvcc -std=c++20 --extended-lambda -arch=native modern.cu -o modern
#include <chrono>
#include <cmath>
#include <concepts>
#include <cstdio>
#include <cstring>
#include <stdexcept>
#include <vector>
#include <cuda/atomic>
#include "device_buffer.hpp"
constexpr int BLOCK = 256;
static_assert(BLOCK % 32 == 0, "a block is a whole number of warps");
static_assert(BLOCK <= 1024, "a block holds at most 1,024 threads");
constexpr int blocksFor(std::size_t n)
{
return static_cast<int>((n + BLOCK - 1) / BLOCK);
}
static_assert(blocksFor(1000) == 4);
const int N = 1 << 21; // 2,097,152 values, as in raw.cu
const int BIG = 1 << 24; // 16,777,216 values for timing
template <typename T>
concept Number = std::integral<T> || std::floating_point<T>;
template <typename F, typename T>
concept UnaryOp = std::invocable<F, T> && std::same_as<std::invoke_result_t<F, T>, T>;
// out[i] = f(in[i]), for any number type T and any operation f from T to T.
template <Number T, UnaryOp<T> F>
__global__ void transform(cuda::std::span<const T> in, cuda::std::span<T> out, F f)
{
std::size_t i = blockIdx.x * std::size_t(blockDim.x) + threadIdx.x;
if (i < in.size()) {
out[i] = f(in[i]);
}
}
template <Number T>
struct Scale {
T factor;
__host__ __device__ T operator()(T x) const { return factor * x; }
};
// The C-style kernel of raw.cu, kept to compare its speed.
__global__ void scaleRaw(const float* in, float* out, int n, float factor)
{
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
out[i] = factor * in[i];
}
}
// 1 + x + x^2/2 + x^3/6, the first 4 terms of e^x, by Horner's rule.
__host__ __device__ float expPoly(float x)
{
return 1.0f + x * (1.0f + x * (0.5f + x * (1.0f / 6.0f)));
}
// The same polynomial, with every multiply-add rounded once, on both sides.
__host__ __device__ float expPolyFma(float x)
{
float p = fmaf(x, 1.0f / 6.0f, 0.5f);
p = fmaf(x, p, 1.0f);
return fmaf(x, p, 1.0f);
}
// Count the values above a threshold. atomic_ref makes an ordinary int atomic.
template <Number T>
__global__ void countAbove(cuda::std::span<const T> in, T threshold, int* count)
{
std::size_t i = blockIdx.x * std::size_t(blockDim.x) + threadIdx.x;
if (i < in.size() && in[i] > threshold) {
cuda::atomic_ref<int, cuda::thread_scope_device> total(*count);
total.fetch_add(1, cuda::memory_order_relaxed);
}
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// Average time of `runs` runs of `launch`, in milliseconds, after 500 ms of warm-up:
// the clocks of the GPU and of its memory rise under sustained load.
template <typename F>
double timeKernel(F launch, int runs)
{
double start = nowMs();
while (nowMs() - start < 500.0) {
launch();
check(cudaDeviceSynchronize());
}
double t0 = nowMs();
for (int r = 0; r < runs; ++r) {
launch();
}
check(cudaGetLastError());
check(cudaDeviceSynchronize());
return (nowMs() - t0) / runs;
}
// The function of raw.cu: the early return frees both buffers.
bool scaleOnGpu(const std::vector<float>& host, std::vector<float>& result, float factor)
{
    DeviceBuffer<float> in(host);
    DeviceBuffer<float> out(host.size());

    if (factor == 0.0f) {
        return false;
    }

    transform<<<blocksFor(in.size()), BLOCK>>>(in.view(), out.span(), Scale{factor});
    check(cudaGetLastError());
    result = out.toHost();
    return true;
}

void launchTooWide(const std::vector<float>& host)
{
    DeviceBuffer<float> in(host);
    DeviceBuffer<float> out(host.size());

    transform<<<N / 2048, 2048>>>(in.view(), out.span(), Scale{2.0f});
    check(cudaGetLastError());
}
// The only way to skip a destructor: a buffer created with new and never deleted.
void leakOnGpu(const std::vector<float>& host)
{
new DeviceBuffer<float>(host);
}
// Time transform<T> on BIG values; return true if every result is right.
template <Number T>
bool timeType(const char* name, int runs)
{
    std::vector<T> host(BIG);
    for (int i = 0; i < BIG; ++i) {
        host[i] = static_cast<T>(i % 1000);
    }

    DeviceBuffer<T> in(host);
    DeviceBuffer<T> out(host.size());
    Scale<T> triple{3};

    auto launch = [&] {
        transform<<<blocksFor(BIG), BLOCK>>>(in.view(), out.span(), triple);
    };
    double ms = timeKernel(launch, runs);
    double gbs = 2.0 * BIG * sizeof(T) / ms / 1e6;
    std::printf("  %-22s %7.2f ms  %6.1f GB/s\n", name, ms, gbs);

    std::vector<T> result = out.toHost();
    for (int i = 0; i < BIG; ++i) {
        if (result[i] != triple(host[i])) {
            return false;
        }
    }
    return true;
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %d SMs\n", prop.name, prop.multiProcessorCount);
std::vector<float> host(N, 1.0f);
std::vector<float> result(N, 0.0f);
bool passed = true;
std::printf("ownership\n");
double before = poolMiB();
for (int call = 0; call < 8; ++call) {
scaleOnGpu(host, result, 0.0f);
}
double lost = poolMiB() - before;
std::printf(" 8 calls that return early: %.1f MiB lost\n", lost);
passed = passed && lost == 0.0;
try {
launchTooWide(host);
passed = false;
} catch (const std::runtime_error& e) {
std::printf(" 2048 threads per block threw: %s\n", e.what());
}
std::printf(" after the exception: %.1f MiB in use\n", poolMiB());
scaleOnGpu(host, result, 2.0f);
int correct = 0;
for (float x : result) {
correct += (x == 2.0f);
}
std::printf(" copies sized by the type: %d of %d correct\n", correct, N);
passed = passed && correct == N;
for (int call = 0; call < 8; ++call) {
leakOnGpu(host);
}
double leaked = poolMiB() - before;
std::printf(" 8 calls with new and no delete: %.1f MiB lost\n", leaked);
std::printf("1 template, 3 types, %d values\n", BIG);
{
DeviceBuffer<float> in(std::vector<float>(BIG, 1.0f));
DeviceBuffer<float> out(BIG);
auto launch = [&] {
scaleRaw<<<blocksFor(BIG), BLOCK>>>(in.data(), out.data(), BIG, 3.0f);
};
double ms = timeKernel(launch, 20);
double gbs = 2.0 * BIG * sizeof(float) / ms / 1e6;
std::printf(" %-22s %7.2f ms %6.1f GB/s\n", "raw pointers, float", ms, gbs);
}
passed = timeType<float>("transform<float>", 20) && passed;
passed = timeType<double>("transform<double>", 20) && passed;
passed = timeType<int>("transform<int>", 20) && passed;
std::printf("1 function on both sides, %d values in [-1, 1)\n", N);
std::vector<float> xs(N);
for (int i = 0; i < N; ++i) {
xs[i] = -1.0f + 2.0f * i / N;
}
DeviceBuffer<float> x(xs);
DeviceBuffer<float> y(N);
auto plain = [] __host__ __device__ (float v) { return expPoly(v); };
auto fused = [] __host__ __device__ (float v) { return expPolyFma(v); };
transform<<<blocksFor(N), BLOCK>>>(x.view(), y.span(), plain);
check(cudaGetLastError());
std::vector<float> gpuPlain = y.toHost();
transform<<<blocksFor(N), BLOCK>>>(x.view(), y.span(), fused);
check(cudaGetLastError());
std::vector<float> gpuFused = y.toHost();
int plainDiffer = 0;
int fusedDiffer = 0;
for (int i = 0; i < N; ++i) {
float cpuPlain = plain(xs[i]);
float cpuFused = fused(xs[i]);
plainDiffer += std::memcmp(&cpuPlain, &gpuPlain[i], sizeof(float)) != 0;
fusedDiffer += std::memcmp(&cpuFused, &gpuFused[i], sizeof(float)) != 0;
}
std::printf(" x * y + z: %d of %d differ from the CPU\n", plainDiffer, N);
std::printf(" fmaf: %d of %d differ from the CPU\n", fusedDiffer, N);
passed = passed && fusedDiffer == 0;
DeviceBuffer<int> count(1);
check(cudaMemset(count.data(), 0, sizeof(int)));
countAbove<<<blocksFor(N), BLOCK>>>(y.view(), 1.5f, count.data());
check(cudaGetLastError());
int gpuCount = count.toHost()[0];
int cpuCount = 0;
for (float v : gpuFused) {
cpuCount += (v > 1.5f);
}
std::printf("span and atomic_ref: %d values above 1.5, CPU %d\n", gpuCount, cpuCount);
passed = passed && gpuCount == cpuCount;
std::printf(passed ? "PASSED\n" : "FAILED\n");
return passed ? 0 : 1;
}
Common mistakes
- Copying an owner. A struct that holds a raw device pointer and is copied leads to 2 frees
of the same memory. Delete the copy operations and move with
std::move. - Throwing from a destructor. A destructor can run while an exception is traveling, and a second exception ends the program. Free the memory and ignore the result there.
- Passing a host lambda to a kernel. Mark the lambda
__device__or__host__ __device__and compile with--extended-lambda. - Capturing by reference in a device lambda. The capture passes a host address to the GPU. Capture by value, and only trivially copyable values.
- Comparing CPU and GPU results bit for bit with plain
a * b + c. The GPU fuses the expression into an FMA. Writefmafwhere the bits must agree, or compare with a tolerance. - Using a wider thread scope than necessary.
thread_scope_systemcosts more thanthread_scope_device. Use the narrowest scope that contains every thread that accesses the value. - Measuring without a warm-up. With 0.3 s of warm-up, the kernels of this chapter ran at 33 to 48 GB/s; with 500 ms before each measurement, at 70 to 90 GB/s. The clock rates of a GPU and of its memory rise only under sustained load.
Summary
- The CUDA C API leaves 3 responsibilities at every call site. When they were neglected, 8 early returns leaked 128 MiB, a kernel was skipped without a message, and only 1 float in 4 was copied.
- RAII acquires a resource in a constructor and releases it in the destructor, which the compiler
runs on every path out of a scope. With
DeviceBuffer<T>, the early returns leaked 0.0 MiB. - Each allocation has 1 owner: copies are deleted, and a move transfers the pointer and leaves
nullptrbehind. check()withstd::source_locationnames the failed line without a macro, and its exception frees every buffer in the scopes it leaves.- Template kernels produce 1 kernel per type at the speed of a hand-written kernel: 74.6 GB/s against 74.5 GB/s.
__host__ __device__functions are compiled for both processors. The GPU’s FMA made 585,903 of 2,097,152 results differ in the last bits untilfmafmade both sides round once.constexpr,static_assert, spans,cuda::atomic_refwith a scope, and concepts each turn a rule into something that the compiler checks.- Rust provides each of these as part of the language:
Drop, moves,Resultand?, generics with trait bounds, and constant assertions. Leaking memory requires an explicitmem::forget.
In Chapter 11, we find these techniques in NVIDIA’s libraries. Thrust’s device_vector is a
DeviceBuffer with algorithms, CUB is a library of template building blocks, and cuBLAS
provides the matrix product of Chapter 9.
Exercises
- Remove the
= deletefrom the copy constructor ofDeviceBuffer, writeb = a, and run the program. What happens at the end of the scope, and why? - Add a
release()that frees early and leaves the object empty, and use it in a loop that allocates a large buffer in each iteration. Show withpoolMiB()that the peak stays at 1 buffer. - Write
DeviceBuffer<std::string> s(4);and read the error. Which property ofstd::stringdoes it reject? - Write a
__host__ __device__functionlerp(a, b, t) = a + t × (b − a), test it differentially on 1,048,576 values, and count the differences. Rewrite it withfmafso that none remain. - Instantiate
transformforunsigned charand measure it. Explain the rate from the number of bytes each thread moves. - Change
countAbovetothread_scope_blockand run it. Is the count still correct on your GPU? Is it guaranteed to be? - Write a concept
Floatingthat accepts onlyfloatanddouble, and use it on a kernel that callssqrt. What error doestransform<int>give now? - In Rust, replace
pool_copywithDeviceBuffer::from_hostinscale_on_gpu. Does the pool still count the buffers? Why?
Sources and further reading
- NVIDIA, CUDA C++ Programming Guide, “Function Execution Space Specifiers”, “Extended Lambdas” and “Stream Ordered Memory Allocator”: https://docs.nvidia.com/cuda/cuda-c-programming-guide/
- NVIDIA, libcu++ documentation,
cuda::std::span,cuda::atomic_refand thread scopes: https://nvidia.github.io/cccl/libcudacxx/ - NVIDIA, CUDA Floating Point and IEEE 754, on fused multiply-add and differences between CPU and GPU results: https://docs.nvidia.com/cuda/floating-point/
- B. Stroustrup, The C++ Programming Language, 4th ed., Addison-Wesley, 2013, chapters on resource management, copy and move, and templates.
- cppreference, “RAII”, “The rule of three/five/zero”, “std::source_location”, “Constraints and concepts”: https://en.cppreference.com/
- S. Klabnik and C. Nichols, The Rust Programming Language, chapters “Understanding Ownership” and “Generic Types, Traits, and Lifetimes”: https://doc.rust-lang.org/book/