Chapter 11: The Library Ecosystem - Thrust, CUB & cuBLAS
In Chapters 8 and 9, we wrote a sum, a scan, a histogram and a matrix product as our own kernels and measured each version. The CUDA toolkit already contains tuned implementations of all of these operations. A library is a collection of routines written, tested and tuned by other programmers, which a program calls instead of implementing the operation itself. NVIDIA ships several libraries with every toolkit and tunes them for each new GPU generation.
In this chapter, we place each library next to the kernel it replaces and measure both on the
same GPU. The measurements come from a Jetson Orin NX, an integrated GPU with 8 SMs (streaming
multiprocessors), 102 GB/s of memory bandwidth and 2.4 TFLOP/s of FP32 throughput, with all runs
made on the same day. FP32 is the 32-bit floating-point format of the C++ type float, and
1 TFLOP/s is 1012 floating-point operations per second. We will use them to answer 2
practical questions: when a library is as fast as a hand-written kernel, and what a library call
costs beyond the kernels it launches. We will find that on large inputs the libraries match or
exceed our kernels, while on small inputs most of the time of a convenient library call goes to
memory allocation and synchronization rather than to computation. Synchronization here means
that the host stops and waits until the GPU has finished the work submitted so far.
This chapter covers
- the libraries Thrust, CUB, cuBLAS, cuFFT and cuRAND, and the kernels of earlier chapters that each one replaces
- reductions with Thrust, and fusing 2 passes into 1 with
transform_reduce - the single-pass scan, which moves half the bytes of the scan in Chapter 8
- radix sort, built from a histogram and a scan
- the temporary storage that a library call needs, and the cost of allocating it on every call
- CUB’s block-level primitives inside a custom kernel, and their counterparts in cuda-oxide
- calling cuBLAS with row-major matrices
- TF32 tensor cores: speed and accuracy
- choosing between a library and a custom kernel
The code of the chapter is in
code/ch11_libraries/
for C++ and in
code/oxide/ch11_blocks/
for Rust.
11.1 Libraries in the CUDA toolkit
11.1.1 The libraries and what they replace
The 5 libraries of this chapter cover most of the algorithms of Part III, as well as a few
that we do not implement by hand. All of them are installed with the CUDA toolkit.
Before we look at the table below, we need 4 terms. A reduction combines all the elements
of an array into 1 value with an operation such as addition; the sum of Chapter 8 is a
reduction. GEMM (general matrix multiply) is the matrix product \(C = AB\) of Chapter 9,
and SGEMM is its single-precision version, on floats. Temporary storage, also called
scratch memory, is device memory that an algorithm needs only while it runs. For example, a
sum of 1,024 blocks writes 1 partial sum per block, 1,024 floats or 4 KiB, which the final step
adds and which are not needed afterward. A header is a source file that a program includes
with #include, and a link flag such as -lcublas tells the linker to add a compiled
library file to the executable.
| Library | What it provides | Replaces | Header, link flag |
|---|---|---|---|
| Thrust | whole-array algorithms called from the host: reduce, transform, scan, sort | Chapter 8’s sum and scan | <thrust/...>, none |
| CUB | the same algorithms with temporary storage managed by the caller, and primitives for use inside a kernel | Chapter 8’s block sum and block scan | <cub/cub.cuh>, none |
| cuBLAS | dense linear algebra: SGEMM, matrix-vector products, dot products | Chapter 9’s SGEMM | <cublas_v2.h>, -lcublas |
| cuFFT | fast Fourier transforms | not implemented in this book | <cufft.h>, -lcufft |
| cuRAND | random numbers on the GPU | not implemented in this book | <curand.h>, -lcurand |
Thrust and CUB consist entirely of C++ templates (Chapter 10) in header files. They are compiled
into the program together with the rest of its code and therefore need no link flag. Both belong
to the CUDA C++ Core Libraries (CCCL), together with libcu++, which provides the
cuda::std:: versions of the C++ standard library that we use below. The CCCL version is tied
to the toolkit: CUDA 12.6 ships CCCL 2.5, and CUDA 13.2 ships CCCL 3.2. cuBLAS, cuFFT and
cuRAND, on the other hand, are compiled libraries and must be linked with a flag.
We describe each library briefly before we arrange them. Thrust is a library of
algorithms on whole arrays, such as sum, sort and scan, that a host program calls in 1 line,
in the manner of the C++ standard library; Thrust launches the kernels itself. CUB (CUDA
UnBound) provides the same algorithms with more control left to the caller, and also provides
building blocks, such as the sum of the values of 1 block, that a programmer calls from inside
a kernel of their own. cuBLAS is NVIDIA’s implementation of the standard routines of linear
algebra, among them GEMM. For example, a sum of 1,000,000 floats is 1 call of thrust::reduce,
2 calls of cub::DeviceReduce::Sum, or 1 kernel of our own in which each block calls
cub::BlockReduce and writes 1 partial sum.
Fig. 11.1 arranges the libraries by where they are called from and by who manages the memory they use.
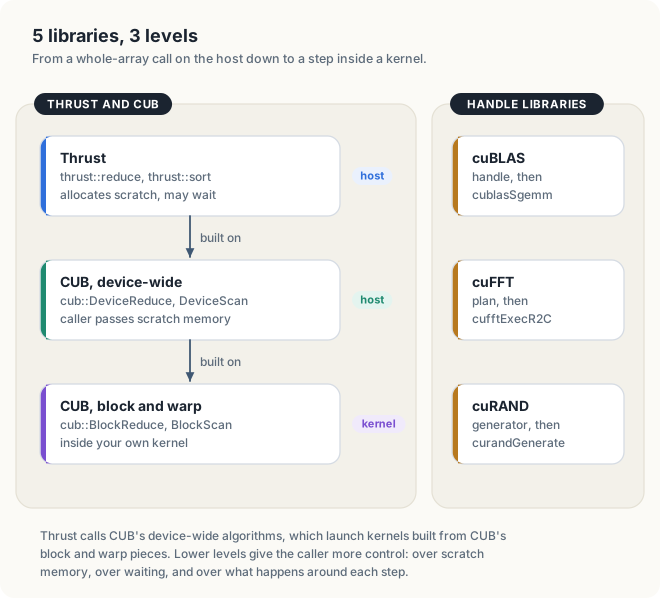
The 3 levels trade convenience for control. A Thrust call does everything for the programmer. It allocates its temporary storage, launches its kernels and, in the case of a reduction, returns the result to the host. A CUB device-wide call performs the same work but leaves 2 decisions to the caller: where the temporary storage comes from, and when the host waits for the result. A CUB block-level call performs only 1 step of an algorithm, inside a kernel that the programmer writes. Since Thrust is built on CUB, the kernels launched at the top 2 levels are the same. In Sections 11.2 and 11.3, we measure what the difference in convenience costs.
11.1.2 Advantages and limits of a library
A library has 3 advantages over a kernel written for a single program. First, its authors select a different kernel for each GPU generation, the family of GPUs that share 1 design, such as the GPUs of compute capability 8.x, with block sizes, load widths and algorithms tuned on that hardware. Second, it can use algorithms whose implementation effort a single program could not justify. The scan of Section 11.2.3, for example, relies on a protocol between thread blocks that we did not attempt in Chapter 8. Third, it is tested on every release against reference results and on a wide range of input shapes.
A library also has a limitation, which we measure in this chapter. It does not know the context in which it is called. It cannot know that the same temporary storage could serve 1,000 consecutive calls, or that the result will be used by another kernel on the GPU rather than by the host. The programmer knows these facts and can pass them to the library by calling it at one of the lower levels of Fig. 11.1.
NOTE: cuda-oxide, the Rust compiler used in this book, has no bindings to Thrust, CUB,
cuBLAS, cuFFT or cuRAND at revision b7fe543. A Rust program can call these C libraries
through Rust’s foreign function interface (FFI), the mechanism by which Rust code declares
and calls functions written in C. We use it for NVRTC in Chapter 12; its use for these
libraries is beyond the scope of this chapter.
cuda-oxide does provide its own block-level primitives for use inside a kernel, the
counterparts of CUB’s lowest level, and we measure them in Section 11.3.2.
11.2 Thrust: whole-array algorithms
11.2.1 Reduction with thrust::reduce
Thrust’s algorithms have the names and parameters of the algorithms in the C++ standard library.
A range of elements is given by 2 positions, first and last. Such a position is called an
iterator: an object that marks 1 element of a sequence and can be advanced to the next. A
raw pointer is the simplest iterator. The range is half-open: it contains first and every
element up to, but not including, last. For example, with in pointing to an array of 8
floats, the range in to in + 8 covers elements 0 to 7, and in + 8 itself marks the
position just past the end. The first argument of the call is an execution policy, which
specifies where the algorithm runs. The policy thrust::device runs the algorithm on the GPU,
on data in device memory.
thrust::reduce(policy, first, last, initial value)
    → initial value + every element in [first, last), combined in any order
The phrase “in any order” matters, and a small example shows why. Take the 8 values 3, 1, 2, 0, 1, 2, 0, 1. A sequential loop adds them from left to right: 3, 4, 6, 6, 7, 9, 9, 10. A tree reduction, as in the kernels of Chapter 8, adds neighboring pairs in rounds. Round 1 gives 3 + 1 = 4, 2 + 0 = 2, 1 + 2 = 3 and 0 + 1 = 1; round 2 gives 4 + 2 = 6 and 3 + 1 = 4; round 3 gives 6 + 4 = 10. Both orders reach 10, but the tree takes 3 rounds instead of 7 steps, and the 4 additions of round 1 can run at the same time on 4 threads. With integers the order makes no difference. With floats, every addition rounds, and different orders round at different places.
Key observation A parallel reduction adds the same elements in a different order from a sequential loop. With floats, the 2 results can differ in their last digits, although neither is less accurate.
Like the kernels of Chapter 8, thrust::reduce adds the elements in a tree. The order of the
additions therefore differs from that of a sequential loop, and the result is rounded
differently, though not less accurately. Listing 11.1 times thrust::reduce on the
67,108,864 floats (256 MiB) of Chapter 8, next to the fastest kernel of that chapter.
Listing 11.1 A sum with thrust::reduce, timed. code/ch11_libraries/reduce_scan.cu
fn main() -> Result<(), Error> {
    // ...
    let ms = time_ms(&stream, || {
        module.sum_blocks(&stream, &blocks.0, &input, &mut partial)?;
        Ok(module.sum_blocks(&stream, &blocks.1, &partial, &mut total)?)
    })?;
    let rate = gb / ms * 1e3;
    let sum_blocks = total.to_host_vec(&stream)?[0];
    println!("  block_reduce        {ms:6.2} ms  {rate:6.1} GB/s  sum {sum_blocks:.1}");
    // ...
}
bool sums(const float* in, float* partial, float* total, int n, double exact)
{
// ...
float t = 0.0f;
auto thrustSum = [&] { t = thrust::reduce(thrust::device, in, in + n, 0.0f); };
ms = timeMs(thrustSum);
ok &= report("thrust::reduce", ms, bytes, t, exact);
// ...
}
cuda-oxide has no call that sums a whole array, so the Rust tab times the 2 launches of
block_reduce from Section 11.3.2.
Note that thrust::reduce returns the sum to the host as a float. The call therefore also
waits for the GPU to finish and copies 4 bytes back to the host. The program compares every
sum with a sum computed in double precision and prints PASSED when all of them agree to 1 part
in 100,000.
$ ./reduce_scan
GPU: Orin, 8 SMs, L2 cache 2 MiB
sum of 67108864 floats (256 MiB), average of 20 runs
  Chapter 8, float4 + shuffles    2.87 ms    93.4 GB/s  sum 33557628.0
  same, cub::BlockReduce          2.90 ms    92.5 GB/s  sum 33557624.0
  cub::DeviceReduce::Sum          2.92 ms    91.8 GB/s  sum 33557628.0
    (CUB asked for 1279 bytes of temporary storage)
  thrust::reduce                  2.89 ms    93.0 GB/s  sum 33557628.0
The 4 implementations ran within 2% of each other, at 91.8 to 93.4 GB/s, which is 90% to 92% of the GPU’s 102 GB/s. Recall from Chapter 8 that this is the limit for a sum: the kernel reads each byte once and performs 1 addition for every 4 bytes, so its speed is set by the memory. A kernel is said to be memory-bound if its performance is limited by the memory bandwidth of the hardware, and no library can read data faster than the memory delivers it. The sums differ in their last digits because each implementation adds the elements in a different order. All of them are within 7 of the exact value 33,557,630.3, a relative error of 2 × 10⁻⁷. The times varied by up to 20% across 3 runs, so a difference of a few percent between the 4 lines is not significant.
11.2.2 Fusing transform and reduce
The sum of squares \(\sum_i x_i^2\) can be written with 2 Thrust calls.
thrust::transform squares every element and writes the squares to a second array, and
thrust::reduce then adds the elements of the second array. Let us count the memory traffic
for the 4 floats 1, 2, 3, 4, which occupy 16 bytes. The first call reads the 16 bytes and
writes the squares 1, 4, 9, 16 into a second array of 16 bytes. The second call reads those 16
bytes again and adds them to 30. In all, 48 bytes cross the memory bus. A single loop could
instead read 1, square it, add it to a running total, and go on to 2, so that each square exists
only in a register, the storage of 1 thread inside the SM, and never reaches memory. The
same total 30 then costs 16 bytes of traffic.
Definition 11.1 Pass and fusion. A pass is 1 traversal of an array in memory. Fusion combines several passes into 1, so that each intermediate value is passed on in a register instead of being written to memory and read back.
Example. thrust::transform followed by thrust::reduce makes 2 passes over the sum of
squares; thrust::transform_reduce makes 1, squaring each element as it reads it and adding the
square immediately.
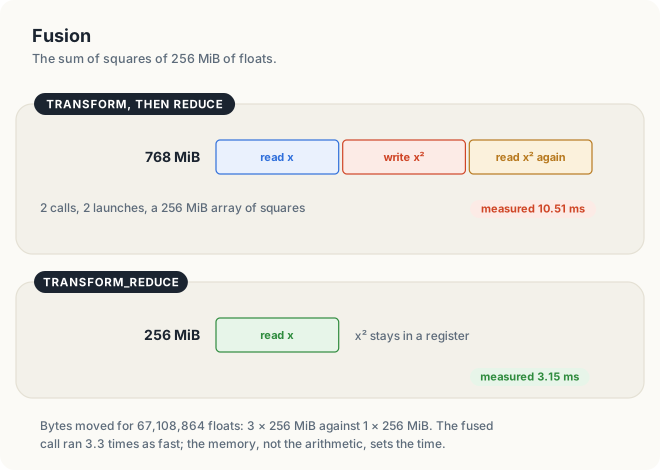
The benefit of fusion follows from the number of bytes each version moves. For 256 MiB of
floats, transform reads 256 MiB and writes 256 MiB of squares, and reduce reads the 256
MiB of squares again, for a total of 768 MiB, 3 times the input. transform_reduce reads the
input once, 256 MiB. At the 92 GB/s measured in Section 11.2.1, 768 MiB (805 MB) take about
8.8 ms and 256 MiB (268 MB) take about 2.9 ms.
Thrust takes the operation to apply to each element as a functor, an object that can be
called like a function, as the function objects of Chapter 10 are. An object sq of a struct
whose operator() returns x * x gives sq(3.0f) = 9.0. In Listing 11.2, the functor Square
is declared __host__ __device__ so that it is compiled for the GPU, and
cuda::std::plus<float> is the addition of the standard library, in the cuda::std version
that can be called on both the host and the device.
Listing 11.2 The sum of squares in 2 passes and in 1.
mod kernels {
    // ...
    /// out[i] = f(input[i]), 1 element per thread: the work of thrust::transform.
    #[kernel]
    #[launch_contract(domain = 1, block = (256, 1, 1))]
    pub fn map<F>(f: F, input: &[f32], mut out: DisjointSlice<f32>)
    where
        F: Fn(f32) -> f32 + Copy,
    {
        let idx = thread::index_1d();
        let i = idx.get();

        if let Some(slot) = out.get_mut(idx) {
            *slot = f(input[i]);
        }
    }

    /// 1 partial sum of f(input[i]) per block, each f(x) kept in a register: the work
    /// of thrust::transform_reduce.
    #[kernel]
    #[launch_contract(domain = 1, block = (256, 1, 1))]
    pub fn map_sum<F>(f: F, input: &[f32], mut partial: DisjointSlice<f32>)
    where
        F: Fn(f32) -> f32 + Copy,
    {
        static mut WARPS: SharedArray<f32, 8> = SharedArray::UNINIT;
        let stride = (thread::gridDim_x() * BLOCK) as usize;
        let block = this_thread_block();

        let mut sum = 0.0;
        let mut i = thread::index_1d().get();
        while i < input.len() {
            sum += f(input[i]);
            i += stride;
        }

        sum = block_reduce::<f32, Sum, 8>(&block, sum, &raw mut WARPS);

        if thread::threadIdx_x() == 0 {
            let b = thread::blockIdx_x() as usize;
            // SAFETY: only thread 0 of each block writes, at its own block number.
            unsafe { *partial.get_unchecked_mut(b) = sum };
        }
    }
}

/// The sum of squares of 64 Mi floats in 2 passes and in 1.
fn sums_of_squares(
    module: &kernels::LoadedModule,
    stream: &Arc<CudaStream>,
    values: &[f32],
) -> Result<bool, Error> {
    let n = values.len();
    let exact: f64 = values.iter().map(|&v| v as f64 * v as f64).sum();

    let input = DeviceBuffer::from_host(stream, values)?;
    let mut squares = DeviceBuffer::<f32>::zeroed(stream, n)?;
    let mut partial = DeviceBuffer::<f32>::zeroed(stream, GRID as usize)?;
    let mut total = DeviceBuffer::<f32>::zeroed(stream, 1)?;

    let each = module.prepare_map(LaunchConfig1D::new(n as u32 / BLOCK, BLOCK, 0))?;
    let grid = module.prepare_map_sum(LaunchConfig1D::new(GRID, BLOCK, 0))?;
    let fused = module.prepare_map_sum(LaunchConfig1D::new(GRID, BLOCK, 0))?;
    let one = module.prepare_map_sum(LaunchConfig1D::new(1, BLOCK, 0))?;

    let square = |v: f32| v * v;
    let same = |v: f32| v;

    let gb = (n * 4) as f64 / 1e9;
    println!("sum of squares, GB/s of input read");

    let ms = time_ms(stream, || {
        module.map(stream, &each, square, &input, &mut squares)?;
        module.map_sum(stream, &grid, same, &squares, &mut partial)?;
        Ok(module.map_sum(stream, &one, same, &partial, &mut total)?)
    })?;
    let two_passes = total.to_host_vec(stream)?[0];
    let rate = gb / ms * 1e3;
    println!("  map, then map_sum    {ms:6.2} ms  {rate:6.1} GB/s  sum {two_passes:.1}");

    let ms = time_ms(stream, || {
        module.map_sum(stream, &fused, square, &input, &mut partial)?;
        Ok(module.map_sum(stream, &one, same, &partial, &mut total)?)
    })?;
    let one_pass = total.to_host_vec(stream)?[0];
    let rate = gb / ms * 1e3;
    println!("  map_sum, fused       {ms:6.2} ms  {rate:6.1} GB/s  sum {one_pass:.1}");
    println!("  exact (f64)                               sum {exact:.1}");

    let close = |s: f32| (s as f64 - exact).abs() < 1e-5 * exact;
    Ok(close(two_passes) && close(one_pass))
}
struct Square {
__host__ __device__ float operator()(float v) const { return v * v; }
};
bool sumsOfSquares(const float* in, float* squares, int n, double exact)
{
double bytes = n * 4.0;
Square square;
cuda::std::plus<float> plus;
std::printf("sum of squares, GB/s of input read\n");
float t = 0.0f;
auto twoPasses = [&] {
thrust::transform(thrust::device, in, in + n, squares, square);
t = thrust::reduce(thrust::device, squares, squares + n, 0.0f);
};
double ms = timeMs(twoPasses);
bool ok = report("transform, then reduce", ms, bytes, t, exact);
auto fused = [&] {
t = thrust::transform_reduce(thrust::device, in, in + n, square, 0.0f, plus);
};
ms = timeMs(fused);
ok &= report("transform_reduce", ms, bytes, t, exact);
return ok;
}
In the Rust tab, the generic kernels map and map_sum take the closure square in the role
of the functor Square.
sum of squares, GB/s of input read
  transform, then reduce         10.51 ms    25.5 GB/s  sum 22372548.0
  transform_reduce                3.15 ms    85.3 GB/s  sum 22372548.0
The fused version ran 3.3 times as fast, close to the factor of 3 predicted from the bytes moved. The remainder is accounted for by the second kernel launch and the allocation of the intermediate array in the 2-pass version. Note that the GB/s column counts only the 256 MiB of input. The 2-pass version therefore shows a third of the memory bandwidth, although the memory was as busy as in the fused version.
A chain of library calls writes every intermediate result to memory and reads it back. For memory-bound work, fusing the chain into a single call divides the time by the number of passes saved.
11.2.3 Single-pass scan
A scan, or prefix sum, replaces each element of an array by the running total up to that element. An inclusive scan includes the element itself in its total, whereas an exclusive scan stops immediately before it and therefore starts at 0. For the values 3, 1, 2, 0, the 2 scans are:
| i | 0 | 1 | 2 | 3 |
|---|---|---|---|---|
| value | 3 | 1 | 2 | 0 |
| inclusive scan | 3 | 4 | 6 | 6 |
| exclusive scan | 0 | 3 | 4 | 6 |
The exclusive scan is the inclusive scan shifted right by 1 position. Element \(i\) of the exclusive scan is the number of items that come before position \(i\), and we use exactly this property in Section 11.2.4.
Definition 11.2 Scan. The inclusive scan of \(x_0, x_1, \dots, x_{n-1}\) is the array \(y\) with \(y_i = x_0 + x_1 + \dots + x_i\). The exclusive scan is the array \(z\) with \(z_0 = 0\) and \(z_i = x_0 + \dots + x_{i-1}\).
Example. For 3, 1, 2, 0, element 2 of the inclusive scan is 3 + 1 + 2 = 6, and element 2 of the exclusive scan is 3 + 1 = 4.
The scan of Chapter 8 made 3 passes. Each block scanned its 1,024 values and wrote them out, a second kernel scanned the block totals, and a third kernel read every value again to add the offset of its block. CUB, which Thrust calls internally, performs the scan in a single pass with a method called decoupled look-back.
To see how 1 pass can suffice, consider 4 blocks whose values add up to the block totals 6, 10, 4 and 8. Block 2 needs to know the sum of everything before it, 6 + 10 = 16, before it can write its first output. In the method of Chapter 8, a separate kernel computed 16 after every block had finished. In decoupled look-back, each block keeps a small record in global memory, a flag with 2 fields: a status and a number. The status is aggregate when the number is the block’s own total, and prefix when the number is the running total up to and including that block.
Let us follow block 2. It scans its own values in registers, finds its total 4, and publishes aggregate 4. It then looks at the flag of block 1, the block to its left. Suppose block 1 has so far published only aggregate 10. Block 2 adds 10 and looks one block further left, at block 0, which has published prefix 6. Block 2 adds 6, and the sum before it is 10 + 6 = 16. It publishes prefix 16 + 4 = 20 for the blocks to its right, adds 16 to each of its scanned values, and writes them out once, in their final form. The search to the left stops at the first prefix it finds, so it is usually short.
Key observation A block needs only the total of the elements before it, not the elements themselves. Blocks therefore wait for each other only on a few bytes of flags, never on the data, and every value is read once and written once.
The saving can again be counted in bytes. For 64 Mi values of 4 bytes (256 MiB), the first kernel of Chapter 8 reads 256 MiB and writes 256 MiB, and the third kernel reads and writes them again; the block totals are 1,024 times smaller and add little. The total is 1,024 MiB. Decoupled look-back reads 256 MiB and writes 256 MiB, a total of 512 MiB. Measured on the same day, the scan of Chapter 8 took 12.49 ms, which corresponds to 1,074 MB / 12.49 ms = 86 GB/s of actual memory traffic, although its program reports 43.0 GB/s because it counts only the 512 MiB that a scan must move.
Listing 11.3 An inclusive scan with Thrust, an exclusive scan with CUB.
fn main() -> Result<(), Error> {
    // ...
    // 2. Each block of 256 values 0 to 3, scanned with block_scan.
    let counts: Vec<u32> = random(n, 2).iter().map(|&r| r >> 30).collect();
    let input = DeviceBuffer::from_host(&stream, &counts)?;
    let mut out = DeviceBuffer::<u32>::zeroed(&stream, n)?;
    let config = LaunchConfig1D::new((n as u32).div_ceil(BLOCK), BLOCK, 0);
    let scan = module.prepare_scan_blocks(config)?;
    module.scan_blocks(&stream, &scan, &input, &mut out)?;
    // ...
}
bool scans(int n)
{
// ...
auto thrustScan = [&] { thrust::inclusive_scan(thrust::device, in, in + n, out); };
double ms = timeMs(thrustScan);
check(cudaMemcpy(result.data(), out, n * sizeof(unsigned), cudaMemcpyDeviceToHost));
bool ok = result == inclusive;
std::printf(" thrust::inclusive_scan %6.2f ms", ms);
std::printf(" %6.1f GB/s", bytes / ms / 1e6);
std::printf(" last %u correct: %s\n", result[n - 1], ok ? "yes" : "no");
size_t tempBytes = 0;
cub::DeviceScan::ExclusiveSum(nullptr, tempBytes, in, out, n);
void* temp;
check(cudaMalloc(&temp, tempBytes));
auto cubScan = [&] { cub::DeviceScan::ExclusiveSum(temp, tempBytes, in, out, n); };
ms = timeMs(cubScan);
// ...
}
cuda-oxide has no scan of a whole array; the Rust tab scans each block of 256 values with
block_scan, the kernel of Listing 11.8.
scan of 67108864 values 0 to 3, average of 20 runs
  thrust::inclusive_scan           7.88 ms    68.2 GB/s  last 100652862  correct: yes
  cub::DeviceScan::ExclusiveSum    7.23 ms    74.3 GB/s  last 100652860  correct: yes
Both lines count 512 MiB, the bytes a scan must move. The library scans ran at 68.2 and 74.3 GB/s, against 43.0 GB/s for the scan of Chapter 8: 1.6 to 1.7 times as fast, almost entirely because they move half the bytes. The 2 last values differ by 2, the value of the last element, which the exclusive scan does not include.
11.2.4 Radix sort
Sorting is the clearest case for a library, because the fastest GPU sorting algorithm is long
and difficult to write. The algorithm is radix sort. Most sorting algorithms, such as the
std::sort of the C++ library, are comparison sorts: they learn the order only by asking
which of 2 keys comes first. Radix sort never compares 2 keys. It sorts them 1 digit at a time,
starting with the lowest digit.
Definition 11.3 Radix sort and stability. A radix sort sorts keys in 1 pass per digit, from the lowest digit to the highest, and in each pass orders the keys by that digit alone. A pass is stable if keys with the same digit keep the relative order they had before the pass.
Example. The keys 21 and 28 have the same tens digit, 2. After the pass on the ones digit, 21 comes before 28; a stable pass on the tens digit keeps 21 before 28.
Stability is what preserves the order established by the lower digits. Each pass is built from two algorithms of Chapter 8. A histogram counts how many keys have each digit. An exclusive scan of the counts then gives the first output position of each digit’s group. Finally, every key is written to the next free position of its group. Writing each element to a position computed for it, rather than to the next position in order, is called a scatter:
radix sort, digits of b bits, keys of B bits:
    for shift ← 0, b, 2b, … , B − b:
        digit(k) ← (k >> shift) mod 2^b
        count[d] ← number of keys with digit d          # a histogram
        start[d] ← count[0] + … + count[d − 1]          # an exclusive scan
        for each key k, in order:                       # a stable scatter
            out[start[digit(k)]] ← k
            start[digit(k)] ← start[digit(k)] + 1
        keys ← out
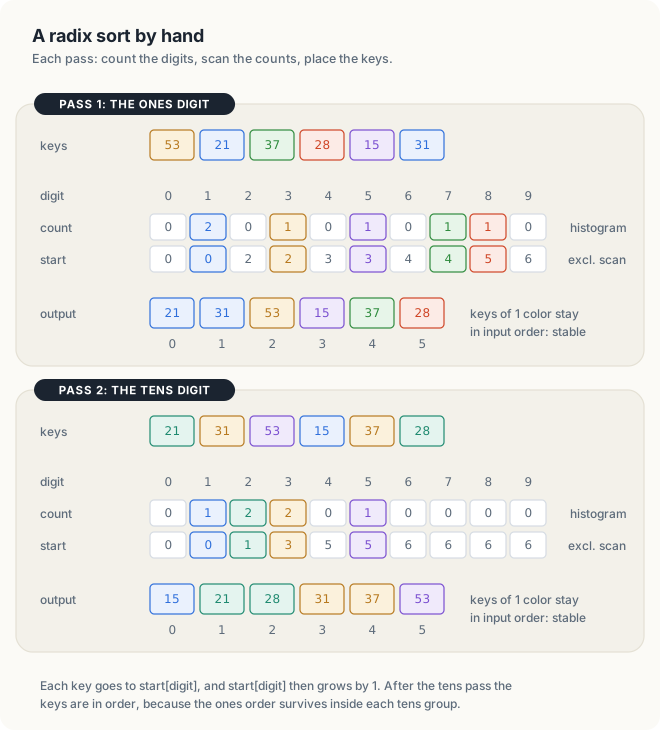
Fig. 11.3 sorts 6 keys of 2 decimal digits, so that the digits can be read directly.
Worked example: 53, 21, 37, 28, 15, 31
- Pass 1, the ones digit: 3, 1, 7, 8, 5, 1. Counts: digit 1 twice, digits 3, 5, 7 and 8 once each.
- Exclusive scan of the counts: digit 1 starts at 0, digit 3 at 2, digit 5 at 3, digit 7 at 4, digit 8 at 5.
- Scatter, in input order: 21 → 0, 31 → 1, 53 → 2, 15 → 3, 37 → 4, 28 → 5. Result: 21, 31, 53, 15, 37, 28.
- Pass 2, the tens digit: 2, 3, 5, 1, 3, 2. Starts: digit 1 at 0, digit 2 at 1, digit 3 at 3, digit 5 at 5.
- Scatter: 15, 21, 28, 31, 37, 53. The keys are sorted after 2 passes, 1 for each digit.
On a GPU the digits are binary. CUB sorts 8 bits per pass, which gives 256 possible digits, so a 32-bit key takes 4 passes, and each pass reads and writes every key. The work of a radix sort therefore grows with the number of keys times the number of passes, not with \(n \log n\) as the work of a comparison sort does. For \(n\) = 16,777,216 = 224 keys, a comparison sort needs on the order of \(n \log_2 n\) = 24\(n\) comparisons, while a radix sort on 32-bit keys makes 4 passes over the \(n\) keys.
Radix sort has 1 requirement. It must know what the bits of a key mean. Thrust uses it only
when the keys are numbers and the order is a standard one, less or greater. If the
program supplies any other comparison, such as the functor Ascending in Listing 11.4,
Thrust cannot look inside it and falls back to a merge sort, a comparison sort that
repeatedly merges 2 sorted runs of keys into 1 longer sorted run and only asks the comparison
which of 2 keys comes first. Ascending produces the same order as less, so the
2 results are identical; only the algorithm differs.
Thrust also needs temporary storage to sort: a second array of keys, plus space for the counts.
By default it allocates this memory with cudaMalloc at the start of each call and frees it
with cudaFree at the end. An allocator is an object that provides memory on request.
Thrust accepts an allocator as part of its execution policy, thrust::cuda::par(allocator), and
then takes its temporary storage from the allocator. The allocator Arena in Listing 11.4 keeps
1 large buffer and hands out pieces of it. During 1 sort, Thrust asks for several pieces, and
Arena hands them out one after another from the start of the buffer. Before the sort returns,
Thrust gives every piece back, and Arena then starts again from the beginning. The next sort
therefore receives the same memory, with no call to cudaMalloc or cudaFree in between.
Listing 11.4 A comparison Thrust cannot see inside, and an allocator that reuses 1 buffer. code/ch11_libraries/sort.cu
// The same order as thrust::less, but Thrust cannot see inside it, so it cannot use a
// radix sort and falls back to a merge sort, which only compares keys.
struct Ascending {
    __host__ __device__ bool operator()(unsigned a, unsigned b) const { return a < b; }
};

// Scratch memory for Thrust, allocated once. During a call Thrust asks for temporary
// buffers and gives them all back before it returns. The arena hands out pieces of 1
// large buffer, and starts again from its beginning when every piece is back.
struct Arena {
    using value_type = char;

    char* base = nullptr;
    size_t size = 0;
    size_t used = 0;
    int live = 0;

    char* allocate(std::ptrdiff_t bytes)
    {
        size_t start = (used + 255) / 256 * 256;          // 256-byte aligned
        if (start + bytes > size) {
            std::fprintf(stderr, "arena too small for %td bytes\n", bytes);
            std::exit(1);
        }

        used = start + bytes;
        ++live;
        return base + start;
    }

    void deallocate(char*, size_t)
    {
        --live;
        if (live == 0) {
            used = 0;
        }
    }
};
Listing 11.5 4 ways to sort with Thrust.
int main()
{
    // ...
    auto plain = [&] { thrust::sort(thrust::device, keys, keys + n); };
    double ms = timeSort(plain, keys, original, n);
    bool ok = report("thrust::sort", ms, n, keys, ascending);

    Arena arena;
    arena.size = 2 * size_t(n) * 4;
    check(cudaMalloc(&arena.base, arena.size));
    auto policy = thrust::cuda::par(arena);

    auto radix = [&] { thrust::sort(policy, keys, keys + n); };
    ms = timeSort(radix, keys, original, n);
    ok &= report("thrust::sort, scratch reused", ms, n, keys, ascending);

    cuda::std::greater<unsigned> greater;
    auto down = [&] { thrust::sort(policy, keys, keys + n, greater); };
    ms = timeSort(down, keys, original, n);
    ok &= report("  ... with cuda::std::greater", ms, n, keys, descending);

    auto merge = [&] { thrust::sort(policy, keys, keys + n, Ascending()); };
    ms = timeSort(merge, keys, original, n);
    ok &= report("  ... with own comparison", ms, n, keys, ascending);
    // ...
}
cuda-oxide provides no sort, so Listings 11.4 and 11.5 have no Rust form; in Chapter 22 we write a radix sort in Rust from its histogram, scan and scatter.
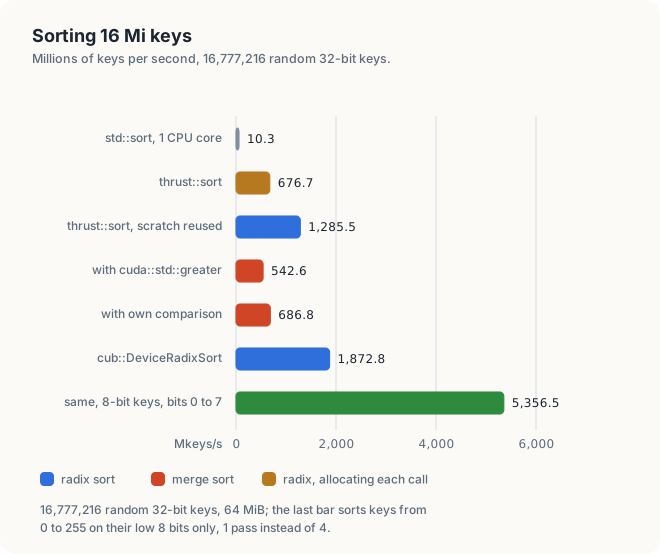
The program sorts 16,777,216 random 32-bit keys (64 MiB) and checks each result against
std::sort on the CPU. It also runs CUB’s own radix sort, cub::DeviceRadixSort, with its
temporary storage allocated once, as described in Section 11.3.3.
$ ./sort
GPU: Orin, 8 SMs
sort of 16777216 random 32-bit keys, average of 5 runs
  std::sort, 1 CPU core              1626.26 ms     10.3 Mkeys/s
  thrust::sort                         24.79 ms    676.7 Mkeys/s  correct: yes
  thrust::sort, scratch reused         13.05 ms   1285.5 Mkeys/s  correct: yes
    ... with cuda::std::greater        30.92 ms    542.6 Mkeys/s  correct: yes
    ... with own comparison            24.43 ms    686.8 Mkeys/s  correct: yes
  cub::DeviceRadixSort                  8.96 ms   1872.8 Mkeys/s  correct: yes
sort of 16777216 keys from 0 to 255
  cub::DeviceRadixSort, bits 0 to 31    8.12 ms   2067.2 Mkeys/s  correct: yes
  cub::DeviceRadixSort, bits 0 to 7     3.13 ms   5356.5 Mkeys/s  correct: yes
PASSED
Mkeys/s is millions of keys sorted per second. The output supports 5 observations.
- The GPU sorts 66 to 180 times as fast as 1 CPU core: 24.79 ms or less, against 1,626 ms.
- Allocation accounts for almost half the time of the plain
thrust::sort. With the temporary storage reused, the sort took 13.05 ms instead of 24.79 ms, so about 12 ms of each call went tocudaMallocandcudaFree. A separate test on the same GPU timed 1cudaMallocandcudaFreeof 64 MiB at 10 ms, and of 128 MiB at 20 ms. The cost depends on the state of the system: across 9 runs the difference ranged from 1 ms to 18 ms. On an integrated GPU the device memory is the system memory, which other programs on the CPU use as well. - Merge sort is slower than radix sort. With the comparison hidden in a functor, the same order took 24.43 ms instead of 13.05 ms, 1.9 times as long.
- The fast path depends on what the library recognizes. In CCCL 2.5, Thrust selects radix
sort only if the type of the comparison is exactly
thrust::less<Key>orthrust::greater<Key>.cuda::std::greateris a different type in that version, so the descending sort fell back to merge sort and took 30.92 ms. CCCL 3.2 makesthrust::greateranother name forcuda::std::greater, and the same source code then takes the radix path and runs as fast as the ascending sort. Only a measurement shows which path a call took. - Fewer key bits mean fewer passes. For keys from 0 to 255, only bits 0 to 7 differ.
When told so with
begin_bit= 0 andend_bit= 8, CUB made 1 pass instead of 4 and finished 2.6 times as fast, in 3.13 ms instead of 8.12 ms. The range of the keys is known to the program, not to the library.
The 2 merge sorts differ by 26%, more than their code differs. Sorts that take 20 to 30 ms varied by 20% to 30% between runs, so this difference is within the noise of the measurement.
Why does a radix sort need every pass to be stable?
After pass 1 the keys are in order of their lowest digit. Pass 2 groups them by the next digit; within a group, the keys must stay in the order pass 1 left them, or the order of the lower digit is lost. In Fig. 11.3, 21 and 28 share the tens digit 2, and 21 stays ahead of 28 only because pass 2 keeps the order of pass 1.
11.3 CUB: block-level and device-wide primitives
11.3.1 Block-wide reduction with cub::BlockReduce
The lowest level of CUB is used inside a kernel that the programmer writes. Recall that a
block is a group of threads of a kernel that run on the same SM and share its shared
memory, and that a warp is a group of 32 threads of a block that execute each
instruction together. cub::BlockReduce combines 1 value from each thread of a block into a
single value, the task performed by the function blockSum in Chapter 8. That function
first reduced the values within each warp with shuffles, instructions that pass a value
from 1 thread of a warp to another. It then stored 1 partial sum per warp in shared memory
and reduced those partial sums with a final round of shuffles in warp 0.
Let us count the steps for a block of 256 threads, which form 256 / 32 = 8 warps. In the first
step, each warp halves its 32 values 5 times with shuffles, 32 → 16 → 8 → 4 → 2 → 1, and the
thread at lane 0, the position 0 within the warp, holds the warp’s total. In the second
step, the 8 lane-0 threads write 8 totals to shared memory. In the third step, warp 0 reads the
8 totals and reduces them with 3 more shuffles, 8 → 4 → 2 → 1. Thread 0 of the block then holds
the total of all 256 values. Listing 11.6 is the fastest kernel of Chapter 8 with blockSum
replaced by CUB.
Listing 11.6 Chapter 8's sum with cub::BlockReduce.
mod kernels {
    // ...
    /// The same sum, with cuda-oxide's block_reduce in place of warp_sum and the slots.
    #[kernel]
    #[launch_contract(domain = 1, block = (256, 1, 1))]
    pub fn sum_blocks(input: &[f32], mut partial: DisjointSlice<f32>) {
        static mut WARPS: SharedArray<f32, 8> = SharedArray::UNINIT;
        let stride = (thread::gridDim_x() * BLOCK) as usize;
        let block = this_thread_block();

        let mut sum = 0.0;
        let mut i = thread::index_1d().get();
        while i < input.len() {
            sum += input[i];
            i += stride;
        }

        sum = block_reduce::<f32, Sum, 8>(&block, sum, &raw mut WARPS);
        if thread::threadIdx_x() == 0 {
            // SAFETY: only thread 0 of each block writes, at its own block number.
            unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = sum };
        }
    }
    // ...
}
// The same kernel, with CUB's block reduction in place of warpSum and blockSum.
__global__ void sumCub(const float4* in, float* partial, int n4)
{
using BlockReduce = cub::BlockReduce<float, BLOCK>;
__shared__ BlockReduce::TempStorage temp;
float sum = 0.0f;
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n4; i += gridDim.x * BLOCK) {
float4 v = in[i];
sum += v.x + v.y + v.z + v.w;
}
sum = BlockReduce(temp).Sum(sum);
if (threadIdx.x == 0) {
partial[blockIdx.x] = sum;
}
}
cub::BlockReduce<float, BLOCK> is a class template, a class written in terms of template
parameters (Chapter 10), here the element type and the number of threads. Both are fixed when
the program is compiled, and CUB selects its algorithm from them.
TempStorage is a type defined inside the class: a region of shared memory sized for the
selected algorithm. The reason for making it a type is that shared memory must be declared
with a size known at compile time, and only CUB knows how many bytes its algorithm needs for
256 floats. Declaring a __shared__ variable of type TempStorage passes that size to the
compiler. The expression BlockReduce(temp) constructs the object on that storage, and
.Sum(sum) returns the total of the block in thread 0.
In the measurements of Section 11.2.1 this kernel ran at 92.5 GB/s, against 93.4 GB/s for the
kernel of Chapter 8, which is within the noise. CUB does not make the kernel faster. It
replaces 25 lines that had to be written and verified by hand, and it handles cases that the
code of Chapter 8 did not, such as block sizes that are not a multiple of 32 and element types
other than float. The same header provides cub::BlockScan, cub::BlockHistogram,
cub::BlockRadixSort, cub::WarpReduce and cub::WarpScan, which are used in the same way.
11.3.2 Block-wide primitives in cuda-oxide
The cooperative_groups module of cuda-oxide provides the Rust counterparts: warp_reduce,
warp_scan, block_reduce and block_scan, for the types u32, i32 and f32 and the
operations Sum, Min and Max. They work in the same 3 steps as cub::BlockReduce. Each
warp reduces its 32 values with shuffles, lane 0 of each warp writes the warp’s total to a
slot in shared memory, and warp 0 reduces the slots. The slots are a SharedArray,
cuda-oxide’s type for an array in shared memory, with one element per warp, which is 256 / 32 = 8
elements for a block of 256 threads. The kernel declares the array as a static mut, a variable
that exists once for the whole block rather than once per thread, and that may be modified. A
Rust reference is a pointer that the compiler checks: while a mutable reference exists, the
compiler assumes that nothing else modifies the value. The threads of a block access the array
at the same time, so the compiler cannot guarantee that assumption, and Rust 2024 does not allow
a reference to a static mut. The kernel therefore passes &raw mut WARPS, the Rust 2024
way to obtain a raw pointer to a static mut without creating a reference.
Listing 11.7 Chapter 8's sum with block_reduce. code/oxide/ch11_blocks/src/main.rs
mod kernels {
// ...
/// The same sum, with cuda-oxide's block_reduce in place of warp_sum and the slots.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_blocks(input: &[f32], mut partial: DisjointSlice<f32>) {
static mut WARPS: SharedArray<f32, 8> = SharedArray::UNINIT;
let stride = (thread::gridDim_x() * BLOCK) as usize;
let block = this_thread_block();
let mut sum = 0.0;
let mut i = thread::index_1d().get();
while i < input.len() {
sum += input[i];
i += stride;
}
sum = block_reduce::<f32, Sum, 8>(&block, sum, &raw mut WARPS);
if thread::threadIdx_x() == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = sum };
}
}
// ...
}// The same kernel, with CUB's block reduction in place of warpSum and blockSum.
__global__ void sumCub(const float4* in, float* partial, int n4)
{
using BlockReduce = cub::BlockReduce<float, BLOCK>;
__shared__ BlockReduce::TempStorage temp;
float sum = 0.0f;
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n4; i += gridDim.x * BLOCK) {
float4 v = in[i];
sum += v.x + v.y + v.z + v.w;
}
sum = BlockReduce(temp).Sum(sum);
if (threadIdx.x == 0) {
partial[blockIdx.x] = sum;
}
}
The 8 in block_reduce::<f32, Sum, 8> is the number of warps, and the call checks it at
compile time: a block of more than 32 warps fails to build. block_scan has the same form.
Listing 11.8 scans each block of 256 values, 1 value per thread. The call out.get_mut(i)
returns an Option, a Rust value that is either Some(slot) or None. It is Some for a
thread whose index lies inside the array and None for the threads beyond its end, so the
kernel writes its results without unsafe.
Listing 11.8 A scan of each block with block_scan.
mod kernels {
// ...
/// An inclusive scan of each block of 256 values, 1 value per thread.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scan_blocks(input: &[u32], mut out: DisjointSlice<u32>) {
static mut WARPS: SharedArray<u32, 8> = SharedArray::UNINIT;
let block = this_thread_block();
let i = thread::index_1d();
let v = if i.get() < input.len() { input[i.get()] } else { 0 };
let scanned = block_scan::<u32, Sum, 8>(&block, v, &raw mut WARPS);
if let Some(slot) = out.get_mut(i) {
*slot = scanned;
}
}
// ...
}// An inclusive scan of each block of 256 values, 1 value per thread, with CUB.
__global__ void scanBlocks(const unsigned* in, unsigned* out, int n)
{
using BlockScan = cub::BlockScan<unsigned, BLOCK>;
__shared__ BlockScan::TempStorage temp;
int i = blockIdx.x * BLOCK + threadIdx.x;
unsigned v = i < n ? in[i] : 0;
BlockScan(temp).InclusiveSum(v, v);
if (i < n) {
out[i] = v;
}
}
$ cargo oxide run
sum of 67108864 floats, average of 20 runs
Chapter 8, by hand 3.95 ms 68.0 GB/s sum 33557632.0
block_reduce 4.10 ms 65.5 GB/s sum 33557632.0
exact (f64) sum 33557630.3
block_scan of 67108864 values, 256 per block
first block: [0, 1, 1, 3, 5, 5, 5, 6] ... 403
sum of squares, GB/s of input read
map, then map_sum 14.67 ms 18.3 GB/s sum 22372548.0
map_sum, fused 4.17 ms 64.4 GB/s sum 22372548.0
exact (f64) sum 22372547.9
sum of 4096 floats, microseconds per sum
allocated each time, result copied 40.7 us
allocated once, result copied 24.1 us
allocated once, result kept 8.4 us
PASSED
The 2 Rust sums ran within 4% of each other and produced the same total. Both kernels read 1
float per load, so they reach 68 GB/s rather than the 93 GB/s of the C++ kernels, which use
float4 loads, each of which reads 4 floats, 16 bytes, in 1 instruction; we measured
the same difference in Chapter 8. The first 8 scanned values increase by
0 to 3 at each step, as the inputs 0, 1, 0, 2, 2, 0, 0, 1 require, and the program checked all
67,108,864 results. The last 8 lines are the Rust counterparts of Listings 11.2 and
11.10: the fused sum of squares ran 3.5 times as fast as the 2 passes, and the small sum took
8.4 µs instead of 40.7 µs once the allocation and the copy were removed.
11.3.3 Device-wide calls and temporary storage
The middle level of CUB runs a complete algorithm on a complete array, as Thrust does, but takes its temporary storage from the caller. The caller, however, does not know how many bytes CUB needs: the number depends on the algorithm that CUB selects for the GPU and for the size of the array. CUB therefore answers that question in a first call, and does the work in a second call. A CUB device-wide call is made twice:
1. call with no temporary storage (nullptr) → CUB writes the number of bytes it needs
2. allocate that many bytes, once
3. call with the temporary storage → CUB launches its kernels and returns at once
(repeat step 3 as often as needed, with the same storage)
Listing 11.9 cub::DeviceReduce::Sum, called twice.
fn small_sums(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
values: &[f32],
) -> Result<(), Error> {
// ...
let mut partial = DeviceBuffer::<f32>::zeroed(stream, blocks as usize)?;
let mut total = DeviceBuffer::<f32>::zeroed(stream, 1)?;
let ms = time_ms(stream, || {
module.map_sum(stream, &grid, same, &input, &mut partial)?;
module.map_sum(stream, &one, same, &partial, &mut total)?;
total.to_host_vec(stream)?;
Ok(())
})?;
println!(" allocated once, result copied {:6.1} us", ms * 1e3);
let ms = time_ms(stream, || {
module.map_sum(stream, &grid, same, &input, &mut partial)?;
Ok(module.map_sum(stream, &one, same, &partial, &mut total)?)
})?;
println!(" allocated once, result kept {:6.1} us", ms * 1e3);
// ...
}bool sums(const float* in, float* partial, float* total, int n, double exact)
{
// ...
size_t tempBytes = 0;
cub::DeviceReduce::Sum(nullptr, tempBytes, in, total, n); // asks for the size only
void* temp;
check(cudaMalloc(&temp, tempBytes));
auto cubDevice = [&] { cub::DeviceReduce::Sum(temp, tempBytes, in, total, n); };
ms = timeMs(cubDevice);
ok &= report("cub::DeviceReduce::Sum", ms, bytes, readBack(total), exact);
std::printf(" (CUB asked for %zu bytes of temporary storage)\n", tempBytes);
// ...
}
The Rust kernels need no temporary storage beyond the partial sums, whose number the program knows, so the Rust tab allocates them once and reuses them.
For the sum of 64 Mi floats, CUB asked for 1,279 bytes, enough for the partial sums of its
blocks. The result total remains in device memory, and the call returns without waiting for
the GPU. A call that returns before the GPU has finished the work it requested is called
asynchronous; the host can go on to queue the next kernel while the sum runs. On 256 MiB of
data, where the work itself takes 2.9 ms, neither difference from thrust::reduce matters. On a
small array, however, they determine the time.
Consider a sum of 4,096 floats, 16 KiB. At 92 GB/s, reading 16 KiB takes 16,384 B / 92 GB/s
= 0.18 µs. Listing 11.10 measures three ways of computing this sum. thrust::reduce took 68.1 µs
per sum, CUB with the result copied to the host took 29.9 µs, and CUB with the result left on
the GPU took 8.8 µs. The differences identify where the time goes. Allocating and freeing the
temporary storage costs 68.1 − 29.9 = 38.2 µs, and copying 4 bytes back and waiting for the
GPU costs 29.9 − 8.8 = 21.1 µs. The remaining 8.8 µs are the launch and execution of CUB’s
kernel, which is still 49 times the time the memory needs.
Listing 11.10 3 ways to sum 4,096 floats.
/// A sum of 4,096 floats in 3 ways: storage allocated for each sum and the result
/// copied to the host, as thrust::reduce does; storage allocated once and the result
/// copied; storage allocated once and the result kept on the GPU.
fn small_sums(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
values: &[f32],
) -> Result<(), Error> {
let n = 4096;
let blocks = 16;
let input = DeviceBuffer::from_host(stream, &values[..n])?;
let grid = module.prepare_map_sum(LaunchConfig1D::new(blocks, BLOCK, 0))?;
let one = module.prepare_map_sum(LaunchConfig1D::new(1, BLOCK, 0))?;
let same = |v: f32| v;
println!("sum of {n} floats, microseconds per sum");
let ms = time_ms(stream, || {
let mut partial = DeviceBuffer::<f32>::zeroed(stream, blocks as usize)?;
let mut total = DeviceBuffer::<f32>::zeroed(stream, 1)?;
module.map_sum(stream, &grid, same, &input, &mut partial)?;
module.map_sum(stream, &one, same, &partial, &mut total)?;
total.to_host_vec(stream)?;
Ok(())
})?;
println!(" allocated each time, result copied {:6.1} us", ms * 1e3);
let mut partial = DeviceBuffer::<f32>::zeroed(stream, blocks as usize)?;
let mut total = DeviceBuffer::<f32>::zeroed(stream, 1)?;
let ms = time_ms(stream, || {
module.map_sum(stream, &grid, same, &input, &mut partial)?;
module.map_sum(stream, &one, same, &partial, &mut total)?;
total.to_host_vec(stream)?;
Ok(())
})?;
println!(" allocated once, result copied {:6.1} us", ms * 1e3);
let ms = time_ms(stream, || {
module.map_sum(stream, &grid, same, &input, &mut partial)?;
Ok(module.map_sum(stream, &one, same, &partial, &mut total)?)
})?;
println!(" allocated once, result kept {:6.1} us", ms * 1e3);
Ok(())
}void smallSums(const float* in, float* total)
{
const int n = 4096;
float t = 0.0f;
std::printf("sum of %d floats, microseconds per sum\n", n);
auto thrustSum = [&] { t = thrust::reduce(thrust::device, in, in + n, 0.0f); };
std::printf(" thrust::reduce %6.1f us\n", timeMs(thrustSum) * 1e3);
size_t tempBytes = 0;
cub::DeviceReduce::Sum(nullptr, tempBytes, in, total, n);
void* temp;
check(cudaMalloc(&temp, tempBytes));
auto cubAndCopy = [&] {
cub::DeviceReduce::Sum(temp, tempBytes, in, total, n);
check(cudaMemcpy(&t, total, sizeof(float), cudaMemcpyDeviceToHost));
};
double usCopy = timeMs(cubAndCopy) * 1e3;
std::printf(" cub::DeviceReduce, result copied %6.1f us\n", usCopy);
auto cubOnly = [&] { cub::DeviceReduce::Sum(temp, tempBytes, in, total, n); };
double usOnly = timeMs(cubOnly) * 1e3;
std::printf(" cub::DeviceReduce, result kept %6.1f us\n", usOnly);
check(cudaFree(temp));
}
sum of 4096 floats, microseconds per sum
thrust::reduce 68.1 us
cub::DeviceReduce, result copied 29.9 us
cub::DeviceReduce, result kept 8.8 us
Across 6 runs, thrust::reduce took 44 to 68 µs and CUB with the result kept on the GPU 4.7
to 8.8 µs. In 5 of the 6 runs the 3 lines appeared in the order shown. In the remaining run
the copy back was slow, and CUB with the result copied took 78.6 µs. Operations that wait for
the host vary the most.
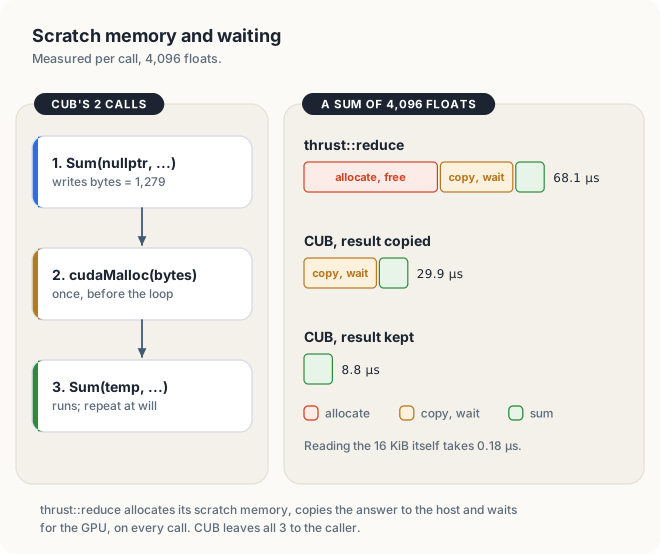
A program that sums 1,000 small arrays per second therefore spends 68 ms of each second in
thrust::reduce, and less than 9 ms with CUB when the result stays on the GPU for the next
kernel. The algorithm is the same in both cases. The difference lies in the information the
program gave the library.
On small inputs, the cost of a library call is allocation and synchronization, not arithmetic. Allocate temporary storage once, and keep results on the GPU when the next step runs there.
11.4 cuBLAS: dense linear algebra
11.4.1 The cuBLAS handle
cuBLAS implements the BLAS (Basic Linear Algebra Subprograms), a standard set of routines first published for Fortran in 1979. The routines are organized in 3 levels: dot products and vector updates (level 1), matrix-vector products (level 2) and matrix-matrix products (level 3), among them SGEMM.
A cuBLAS call needs more information than its arguments carry. It must know which stream to submit its kernels to, where its temporary storage is, and whether it may trade accuracy for speed. A stream (Chapter 6) is a queue of GPU work that runs in order. cuBLAS could keep these settings in global variables, but then 2 host threads that use cuBLAS at the same time, 1 with stream 1 and 1 with stream 2, would overwrite each other’s setting. cuBLAS instead keeps them in an object that the program creates and passes to every call.
Definition 11.4 Handle. A handle is an object, created once by the program, that holds the state of a library: its temporary storage, its stream and its settings. The program passes the handle as the first argument of every call.
Example. cublasCreate(&handle) creates a cuBLAS handle; cublasSetStream(handle, s) makes
every later call with handle submit its kernels to stream s; a second host thread uses its
own handle with its own stream.
The settings in a handle include the math mode of Section 11.4.3. Keeping this state in a handle rather than in global variables allows 2 threads of a program to use cuBLAS at the same time, each with its own handle.
Creating a handle is slow. The program of this section measures it:
cublasCreate took 13.2 ms
13.2 ms is 3,500 times the 3.77 µs per launch of an empty kernel measured in Section 6.7. A program should therefore create 1 handle at startup and pass it to every call.
11.4.2 Row-major and column-major storage
A matrix is stored in memory as a 1-dimensional sequence of numbers, so a program must decide in which order the entries are laid out. We work with 1 small matrix throughout this section, \(A = [1\ 2\ 3;\ 4\ 5\ 6]\), which has 2 rows and 3 columns; the semicolon separates the rows. We number the entries by (row, column) from 0, so the entry 6 is at (1, 2). In every chapter of this book we have stored a matrix row by row, as C and C++ arrays do: row 0 occupies locations 0 to 2 and row 1 locations 3 to 5, so memory holds 1, 2, 3, 4, 5, 6. To find entry (r, c), we skip r complete rows of 3 entries and then c entries, which gives location \(3r + c\). The entry 6 at (1, 2) is at location 3 + 2 = 5.
Fortran, and the original BLAS written in it, store a matrix column by column instead: column 0 occupies locations 0 and 1, column 1 locations 2 and 3, and column 2 locations 4 and 5, so memory holds 1, 4, 2, 5, 3, 6. To find entry (r, c), we skip c complete columns of 2 entries and then r entries, which gives location \(2c + r\). The entry 6 at (1, 2) is now at location 2 × 2 + 1 = 5, and location 1, which held 2 in the first layout, now holds 4.
Definition 11.5 Row-major and column-major order. In row-major order, the rows of a matrix are stored one after another; in a matrix with \(n\) columns, entry (r, c) is at location \(r n + c\). In column-major order, the columns are stored one after another; in a matrix with \(m\) rows, entry (r, c) is at location \(c m + r\).
Example. For the 2 × 3 matrix \(A\) above, entry (0, 1) = 2 is at location 1 in row-major order and at location 2 in column-major order.
cuBLAS keeps the column-major convention of the original BLAS. Let us therefore ask what cuBLAS sees when it receives our row-major memory 1, 2, 3, 4, 5, 6 and is told that the matrix has 3 rows and 2 columns. It reads column 0 from locations 0 to 2, which hold 1, 2, 3, and column 1 from locations 3 to 5, which hold 4, 5, 6. The matrix it sees is \([1\ 4;\ 2\ 5;\ 3\ 6]\). It is the transpose of \(A\), written \(A^T\), the matrix in which rows and columns are exchanged, so that entry (r, c) of \(A^T\) is entry (c, r) of \(A\).
Key observation Entry (r, c) of a row-major \(m \times n\) matrix is at location \(r n + c\), and entry (c, r) of a column-major \(n \times m\) matrix is at location \(r n + c\) as well. A row-major matrix and its column-major transpose occupy memory identically, so a row-major array passed to a column-major library is seen as its transpose.
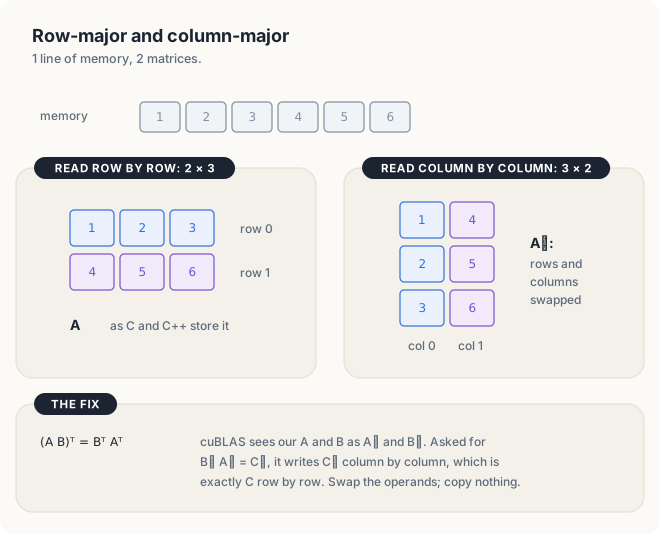
The transpose of a product reverses the order of its factors: \((AB)^T = B^T A^T\). This identity gives the solution. cuBLAS sees our arrays for \(A\) and \(B\) as \(A^T\) and \(B^T\). If we ask cuBLAS for the product of \(B^T\) as its first operand and \(A^T\) as its second, it computes \(B^T A^T = (AB)^T = C^T\) and stores it column by column. A column-major \(C^T\) occupies memory exactly as a row-major \(C\) does. For example, with the matrix \(B\) of the worked example below, \(C = AB = [58\ 64;\ 139\ 154]\), so \(C^T = [58\ 139;\ 64\ 154]\). Stored column by column, \(C^T\) is 58, 64, 139, 154, which is \(C\) stored row by row. Swapping the 2 operands, together with the 2 outer dimensions, is therefore sufficient; no data is copied or transposed.
The location formula \(c m + r\) of column-major order needs 1 more number from the program: how far apart 2 consecutive columns start. For our 2 × 3 matrix, column 1 starts 2 locations after column 0. Now suppose a program stores a 4 × 4 matrix in column-major order and wants cuBLAS to work on its top-left 2 × 2 corner. The corner has 2 rows, but its column 0 starts at location 0 and its column 1 at location 4, because the 4 entries of the first column of the large matrix lie in between. cuBLAS must therefore be told 4, not 2.
Definition 11.6 Leading dimension. The leading dimension of a column-major matrix is the distance in elements between the starts of 2 consecutive columns. Entry (r, c) is at location \(c \cdot ld + r\), where \(ld\) is the leading dimension.
Example. For a complete matrix it equals the number of rows that cuBLAS sees: 2 for the 2 × 3 matrix \(A\). For the 2 × 2 corner of a 4 × 4 matrix it is 4.
Worked example: \(A\) is 2 × 3, \(B = [7\ 8;\ 9\ 10;\ 11\ 12]\) is 3 × 2
- The correct result: row 0 of \(C\) is 1 × 7 + 2 × 9 + 3 × 11 = 58 and 1 × 8 + 2 × 10 + 3 × 12 = 64; row 1 is 139 and 154.
- The incorrect call passes \(A\) and \(B\) as given. cuBLAS reads the memory of \(A\) as 2 rows with leading dimension 2, so its columns are (1, 2), (3, 4), (5, 6): the matrix \([1\ 3\ 5;\ 2\ 4\ 6]\). It reads \(B\) as \([7\ 10;\ 8\ 11;\ 9\ 12]\).
- Their product is \([76\ 103;\ 100\ 136]\), since 1 × 7 + 3 × 8 + 5 × 9 = 76. cuBLAS stores it column by column: 76, 100, 103, 136. The program reads that memory row by row, as \([76\ 100;\ 103\ 136]\). No error is reported, and every element is wrong.
- The correct call passes \(B\) first, with leading dimension 2, and \(A\) second, with leading dimension 3.
Listing 11.11 The incorrect call and the correct one. code/ch11_libraries/gemm.cu
fn small_product(handle: Handle, stream: &Arc<CudaStream>) -> Result<bool, Error> {
// ...
let (one, zero) = (1.0f32, 0.0f32);
let op = CUBLAS_OP_N;
println!("C = A B with A 2 x 3 and B 3 x 2, stored row by row");
print("A", &a, 2, 3);
print("B", &b, 3, 2);
// Wrong: cuBLAS reads each array column by column.
// SAFETY: the 3 pointers address live buffers of 6, 6 and 4 floats, enough for the
// sizes and leading dimensions given.
let result = unsafe {
cublasSgemm_v2(handle, op, op, 2, 2, 3, &one, pa, 2, pb, 3, &zero, pc, 2)
};
ok(result, "cublasSgemm")?;
let c = c_dev.to_host_vec(stream)?;
print("C, operands as given ", &c, 2, 2);
// Right: in column-major terms our arrays hold A^T and B^T. Ask for B^T A^T = C^T,
// whose column-major storage is C row by row.
// SAFETY: as above.
let result = unsafe {
cublasSgemm_v2(handle, op, op, 2, 2, 3, &one, pb, 2, pa, 3, &zero, pc, 2)
};
ok(result, "cublasSgemm")?;
let c = c_dev.to_host_vec(stream)?;
print("C, operands swapped ", &c, 2, 2);
// ...
}// C = A B for a 2 x 3 matrix A and a 3 x 2 matrix B, all stored row by row.
bool smallProduct(cublasHandle_t handle)
{
// ...
float one = 1.0f, zero = 0.0f;
auto op = CUBLAS_OP_N;
std::printf("C = A B with A 2 x 3 and B 3 x 2, stored row by row\n");
print("A", a, 2, 3);
print("B", b, 3, 2);
// Wrong: cuBLAS reads each array column by column.
check(cublasSgemm(handle, op, op, 2, 2, 3, &one, A, 2, B, 3, &zero, C, 2));
check(cudaMemcpy(c.data(), C, 4 * sizeof(float), cudaMemcpyDeviceToHost));
print("C, operands as given ", c, 2, 2);
// Right: in column-major terms our arrays hold A^T and B^T. Ask for B^T A^T = C^T,
// whose column-major storage is C row by row.
check(cublasSgemm(handle, op, op, 2, 2, 3, &one, B, 2, A, 3, &zero, C, 2));
check(cudaMemcpy(c.data(), C, 4 * sizeof(float), cudaMemcpyDeviceToHost));
print("C, operands swapped ", c, 2, 2);
// ...
}
The Rust program declares cublasSgemm_v2, the C function behind cublasSgemm, with
#[link(name = "cublas")], and passes the same arguments.
The 2 calls differ only in the order of their operands and leading dimensions. cuBLAS computes \(C \leftarrow \alpha \cdot \mathrm{op}(A)\,\mathrm{op}(B) + \beta C\), where \(\alpha\) and \(\beta\) are scalars and \(\mathrm{op}\) either leaves an operand as it is or transposes it. With \(\alpha = 1\) and \(\beta = 0\), the formula reduces to \(C \leftarrow AB\); with \(\beta = 1\), it adds the product to the previous contents of \(C\). The arguments after the handle follow that formula:
| Arguments | Meaning | In the correct call |
|---|---|---|
op, op | an operation on each operand; CUBLAS_OP_N means none | none, none |
2, 2, 3 | \(m\), \(n\), \(k\): an \(m \times k\) operand times a \(k \times n\) operand | 2, 2, 3 |
&one | the factor \(\alpha\) | 1 |
B, 2 | the first operand and its leading dimension | \(B^T\), 2 rows |
A, 3 | the second operand and its leading dimension | \(A^T\), 3 rows |
&zero | the factor \(\beta\); 0 ignores the previous contents of \(C\) | 0 |
C, 2 | the result and its leading dimension | \(C^T\), 2 rows |
C = A B with A 2 x 3 and B 3 x 2, stored row by row
A = [1 2 3; 4 5 6]
B = [7 8; 9 10; 11 12]
C, operands as given = [76 100; 103 136]
C, operands swapped = [58 64; 139 154]
Both lines agree with the values computed by hand. In Chapter 9, we called cuBLAS in the same way for square matrices. There the 2 outer dimensions are equal, so only the order of the operands differs, and a test with square matrices alone would not have exposed a wrong leading dimension.
11.4.3 SGEMM performance and TF32 tensor cores
Listing 11.12 runs the product of Chapter 9 with \(N\) = 4,096 twice. The first call uses
cuBLAS’s default math mode, the setting in the handle that states which number formats and
arithmetic units cuBLAS may use; the default is FP32 on the ordinary arithmetic units. Before
the second call, cublasSetMathMode allows the library to use TF32, a number format
described below, on the tensor cores, units that multiply small matrices in a single
instruction.
Listing 11.12 SGEMM in FP32, then with TF32 tensor cores allowed.
fn main() -> Result<(), Error> {
// ...
let (one, zero) = (1.0f32, 0.0f32);
let op = CUBLAS_OP_N;
let n = N as c_int;
let mut gemm = || -> Result<(), Error> {
// SAFETY: the 3 pointers address live buffers of N x N floats.
let result = unsafe {
cublasSgemm_v2(handle, op, op, n, n, n, &one, pb, n, pa, n, &zero, pc, n)
};
ok(result, "cublasSgemm")
};
let report = |name: &str, ms: f64| -> Result<f64, Error> {
let c = c_dev.to_host_vec(&stream)?;
let gflops = 2.0 * (N * N * N) as f64 / ms / 1e6;
let error = max_error(&a, &b, &c);
println!(" {name:<22} {ms:8.2} ms {gflops:7.1} GFLOP/s max error {error:.1e}");
Ok(error)
};
for _ in 0..10 {
time_ms(&stream, 5, &mut gemm)?; // warm up: clocks rise under sustained load
}
println!("C = A B, {N} x {N} floats, average of 10 runs");
let ms = time_ms(&stream, 10, &mut gemm)?;
let fp32 = report("cuBLAS, FP32", ms)?;
// SAFETY: the handle is live.
let result = unsafe { cublasSetMathMode(handle, CUBLAS_TF32_TENSOR_OP_MATH) };
ok(result, "cublasSetMathMode")?;
let ms = time_ms(&stream, 10, &mut gemm)?;
let tf32 = report("cuBLAS, TF32 tensor", ms)?;
// ...
}int main()
{
// ...
float one = 1.0f, zero = 0.0f;
auto op = CUBLAS_OP_N;
auto gemm = [&] {
check(cublasSgemm(handle, op, op, N, N, N, &one, B, N, A, N, &zero, C, N));
};
auto report = [&](const char* name, double ms) {
check(cudaMemcpy(c.data(), C, bytes, cudaMemcpyDeviceToHost));
double gflops = 2.0 * N * N * N / ms / 1e6;
double error = maxError(a, b, c);
std::printf(" %-22s %8.2f ms %7.1f GFLOP/s", name, ms, gflops);
std::printf(" max error %.1e\n", error);
return error;
};
for (int k = 0; k < 10; ++k) { // warm up: clocks rise under sustained load
timeMs(gemm, 5);
}
std::printf("C = A B, %d x %d floats, average of 10 runs\n", N, N);
double fp32 = report("cuBLAS, FP32", timeMs(gemm, 10));
check(cublasSetMathMode(handle, CUBLAS_TF32_TENSOR_OP_MATH));
double tf32 = report("cuBLAS, TF32 tensor", timeMs(gemm, 10));
// ...
}
$ ./gemm
C = A B, 4096 x 4096 floats, average of 10 runs
cuBLAS, FP32 91.34 ms 1504.6 GFLOP/s max error 1.9e-05
cuBLAS, TF32 tensor 21.05 ms 6530.4 GFLOP/s max error 4.0e-03
PASSED
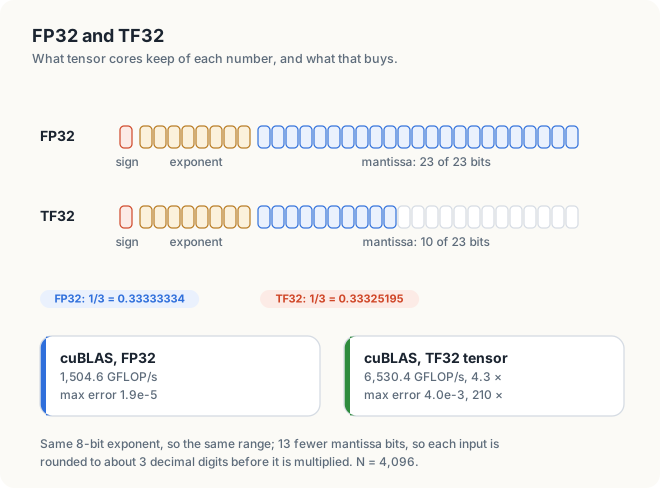
In FP32, cuBLAS reached 1,504.6 GFLOP/s, 63% of the GPU’s FP32 peak of 2.4 TFLOP/s. The
best kernel of Chapter 9 reached 931.9 GFLOP/s, which is 62% of cuBLAS. The column max error compares 64 elements with a product computed in double precision, as in Chapter 9.
With tensor cores allowed, the same call ran 4.3 times as fast, at 6,530.4 GFLOP/s, which is 2.7 times the FP32 peak of the ordinary units. Its error, however, grew 210 times, from 1.9 × 10⁻⁵ to 4.0 × 10⁻³. The reason is the number format. A floating-point number is stored in 3 fields: a sign, an exponent and a mantissa, and its value is ±1.mantissa × 2exponent in binary. For example, 6 = 1.1 (binary) × 22, with exponent 2 and mantissa bits 1000…. The exponent sets the range of magnitudes that the format can hold, and the number of mantissa bits sets how many significant digits it keeps. TF32 (TensorFloat-32) keeps the 8-bit exponent of FP32 and therefore covers the same range of magnitudes, but it keeps only 10 of the 23 bits of the mantissa. Each input is rounded to 10 mantissa bits before it is multiplied, and the products are added in FP32.
The effect of the rounding can be seen on the number 1/3. In binary, 1/3 = 1.010101… × 2−2, with the pattern 01 repeating in the mantissa. FP32 keeps 23 bits of it and stores 0.33333334. TF32 keeps 10 bits, 1.0101010101 in binary, which is 1 + 341/1,024 = 1.3330078, and multiplied by 2−2 gives 0.33325195. The error of 8.1 × 10⁻⁵ is 2.4 × 10⁻⁴ of the value, against 3 × 10⁻⁸ of the value in FP32. A sum of 4,096 such products carries this error into each element of the result.
The gain from tensor cores varies widely between GPUs, because data-center GPUs devote a much larger share of the chip to them than consumer GPUs do:
| GPU | FP32 peak | TF32 tensor peak, dense | Ratio |
|---|---|---|---|
| A100 SXM | 19.5 TFLOP/s | 156 TFLOP/s | 8.0 |
| H100 SXM | 67 TFLOP/s | 495 TFLOP/s | 7.4 |
| GeForce RTX 4090 | 82.6 TFLOP/s | 82.6 TFLOP/s | 1.0 |
| The measured GPU | 1.50 TFLOP/s (cuBLAS) | 6.53 TFLOP/s (cuBLAS) | 4.3 |
The peak rates are taken from NVIDIA’s A100, H100 and Ada architecture documents; “dense” excludes the doubled rates quoted for sparse matrices, matrices in which a fixed fraction of the entries is 0 and is skipped by the hardware. TF32 is the default for training neural networks, whose results tolerate errors far larger than 10−3. A simulation that needs 7 correct digits must not use it, and cuBLAS does not use it unless the program asks for it.
11.5 cuFFT and cuRAND
11.5.1 Random number generation with cuRAND
cuRAND generates random numbers on the GPU, either into an array from a call on the host or
inside a kernel, 1 number per thread. A pseudo-random generator computes a sequence that
appears random from a starting value called the seed. The same seed always produces the
same sequence, which makes a run repeatable. CURAND_RNG_PSEUDO_PHILOX4_32_10 selects the
Philox generator, which is counter-based: number \(i\) of the sequence is computed by a
scrambling function from \(i\) and the seed alone. A classical generator instead computes
each number from the previous one, so number 1,000 can be obtained only after numbers 0 to 999.
With a counter-based generator, thread 1,000 applies the function to the counter 1,000 and the
seed directly. Every thread can therefore compute its own numbers without waiting for the
numbers that precede them.
Listing 11.13 16 Mi normal numbers with cuRAND. code/ch11_libraries/fft_rand.cu
fn normal_numbers(stream: &Arc<CudaStream>) -> Result<bool, Error> {
// ...
let mut generator: Generator = std::ptr::null_mut();
let kind = CURAND_RNG_PSEUDO_PHILOX4_32_10;
let out = ptr(&x);
// SAFETY: `generator` is a valid place for cuRAND to store its generator; `out`
// addresses n floats; the stream outlives the generator.
let ms = unsafe {
let result = curandCreateGenerator(&mut generator, kind);
ok(result, "curandCreateGenerator")?;
let result = curandSetPseudoRandomGeneratorSeed(generator, 2024);
ok(result, "curandSetPseudoRandomGeneratorSeed")?;
let result = curandSetStream(generator, stream.cu_stream().cast());
ok(result, "curandSetStream")?;
let result = curandGenerateNormal(generator, out, n, 0.0, 1.0); // warm-up
ok(result, "curandGenerateNormal")?;
stream.synchronize()?;
let start = Instant::now();
let result = curandGenerateNormal(generator, out, n, 0.0, 1.0);
ok(result, "curandGenerateNormal")?;
stream.synchronize()?;
start.elapsed().as_secs_f64() * 1e3
};
// ...
}// 16 Mi numbers from the normal distribution; their mean should be near 0 and their
// standard deviation near 1.
bool normalNumbers()
{
// ...
curandGenerator_t gen;
check(curandCreateGenerator(&gen, CURAND_RNG_PSEUDO_PHILOX4_32_10));
check(curandSetPseudoRandomGeneratorSeed(gen, 2024));
cudaEvent_t start, stop;
check(cudaEventCreate(&start));
check(cudaEventCreate(&stop));
check(curandGenerateNormal(gen, x, n, 0.0f, 1.0f)); // warm-up
check(cudaEventRecord(start));
check(curandGenerateNormal(gen, x, n, 0.0f, 1.0f));
check(cudaEventRecord(stop));
check(cudaEventSynchronize(stop));
float ms;
check(cudaEventElapsedTime(&ms, start, stop));
// ...
}
The program draws 16,777,216 numbers from the normal distribution with mean 0 and standard deviation 1, the bell-shaped distribution in which about 68% of the values lie between −1 and 1. The mean is the average of the values, and the standard deviation measures their typical distance from the mean; it is the square root of the mean of the squared distances. The program checks both parameters with 2 Thrust reductions, one over the numbers and one over their squares.
$ ./fft_rand
cuRAND, 16777216 normal numbers in 1.01 ms (16688 million per second)
mean -0.00042, standard deviation 0.99994
Writing 64 MiB of numbers in 1.01 ms corresponds to 66 GB/s, so the generator runs close to the speed of the memory. The mean of a finite sample is itself random. Its typical deviation from the true mean, called the standard error, is the standard deviation divided by the square root of the number of samples. For 16.8 million samples, the mean of a correct generator is therefore expected to deviate from 0 by about 1 / √16,777,216 = 0.00024. The measured −0.00042 is within 2 of these standard errors.
11.5.2 Fast Fourier transforms with cuFFT
A Fourier transform represents a signal as a sum of waves and gives, for each frequency, the strength of the corresponding wave. For \(N\) samples, the discrete Fourier transform produces \(N\) complex numbers. Computed directly, each of them takes \(N\) multiplications, \(N^2\) in total. The fast Fourier transform (FFT), published by Cooley and Tukey in 1965, divides the problem in halves recursively and needs about \(N \log_2 N\) operations: for \(N\) = 1,024, about 10,240 instead of 1,048,576.
cuFFT works with a plan, which is created once for a given size and kind of transform and can then be executed on any number of arrays of that shape. A plan plays the role of the cuBLAS handle. It holds the choices that cuFFT makes once for a size, such as how to split 1,024 into halves, so that later transforms of that size can skip them. The list of magnitudes, 1 per frequency, is called the spectrum of the signal. For real input, cuFFT returns \(N/2 + 1\) frequencies; the remaining half of the spectrum is a mirror image and carries no additional information. For \(N\) = 1,024, that is 513 frequencies, numbered 0 to 512.
As a test, the program transforms 1,024 samples of \(\sin(50t) + 0.5 \sin(120t)\). The signal consists of 2 waves: 50 cycles over the 1,024 samples with height 1, and 120 cycles with height 0.5. A wave of height \(h\) that completes a whole number of cycles appears as a single frequency of magnitude \(hN/2\). We therefore expect 1 × 1,024 / 2 = 512 at frequency 50, 0.5 × 512 = 256 at frequency 120, and 0, up to rounding, at every other frequency.
Listing 11.14 A plan, then the transform.
fn spectrum(stream: &Arc<CudaStream>) -> Result<bool, Error> {
// ...
let mut plan: c_int = 0;
// SAFETY: `plan` is a valid place for the plan; `x` holds n floats and `spectrum`
// holds `bins` complex numbers, the sizes of a real-to-complex transform of n.
unsafe {
let result = cufftPlan1d(&mut plan, n as c_int, CUFFT_R2C, 1);
ok(result, "cufftPlan1d")?;
let result = cufftSetStream(plan, stream.cu_stream().cast());
ok(result, "cufftSetStream")?;
let result = cufftExecR2C(plan, ptr(&x), ptr(&spectrum));
ok(result, "cufftExecR2C")?;
}
let result = spectrum.to_host_vec(stream)?;
// ...
}// 1,024 samples of sin(50 t) + 0.5 sin(120 t), with t running once around the circle.
// The transform should show 2 peaks, at frequencies 50 and 120, and nothing else.
bool spectrum()
{
// ...
cufftHandle plan;
check(cufftPlan1d(&plan, n, CUFFT_R2C, 1));
check(cufftExecR2C(plan, x, spectrum));
std::vector<cufftComplex> result(bins);
check(cudaMemcpy(result.data(), spectrum, spectrumBytes, cudaMemcpyDeviceToHost));
// ...
}
cuFFT, 1024 samples of sin(50 t) + 0.5 sin(120 t)
frequency 50: magnitude 512.0
frequency 120: magnitude 256.0
PASSED
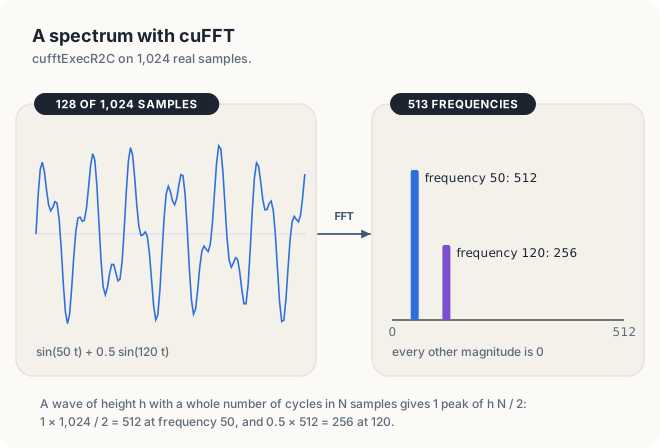
The program prints every frequency whose magnitude exceeds 1. Only the 2 expected frequencies appear, with the expected magnitudes.
11.6 Choosing between a library and a custom kernel
Fig. 11.9 collects the measurements of this chapter for the three algorithms that we also implemented by hand.
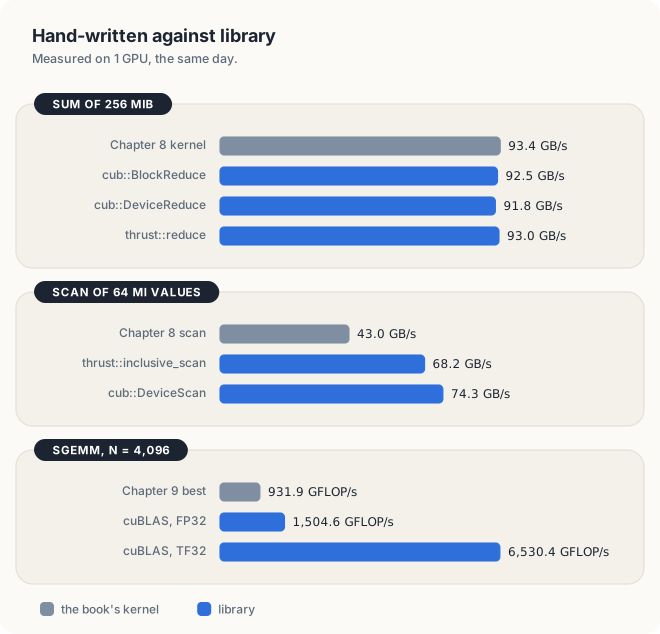
| Problem | Library | Book’s kernel | Measured | Choice |
|---|---|---|---|---|
| sum of a large array | thrust::reduce or CUB | Chapter 8 | 93.0 vs 93.4 GB/s | library: same speed, no code |
| sum of a small array, often | CUB, storage reused, result kept | Chapter 8 | 8.8 µs vs 68.1 µs for thrust::reduce | CUB device-wide call |
| scan | CUB or Thrust | Chapter 8 | 74.3 vs 43.0 GB/s | library: half the bytes |
| sort | CUB radix sort | none | 1,873 Mkeys/s, 180 times 1 CPU core | library |
| SGEMM | cuBLAS | Chapter 9 | 1,505 vs 932 GFLOP/s | library; TF32 if 10 bits suffice |
| a step inside a custom kernel | CUB block level | Chapter 8 | 92.5 vs 93.4 GB/s | CUB inside the kernel |
| a stencil with a halo | none | custom | custom kernel |
The table suggests a sequence of questions to ask when an operation is needed.
- Is the algorithm available in a library? If so, call the library and measure the call. On large inputs, the libraries matched or exceeded every kernel of Part III.
- Is the call slow because of its convenience? On small or repeated inputs, move down a level in Fig. 11.1: use CUB’s device-wide call with temporary storage allocated once and results kept on the GPU, or give Thrust an allocator.
- Does the problem need custom logic for each element? Then write a kernel, but use the block-level primitives of CUB or cuda-oxide inside it. A custom kernel does not have to be written from scratch.
- Is a chain of library calls memory-bound? Each call is a pass over memory. Fuse the
calls, with
transform_reduce, with Thrust’s transform iterators, or with a single custom kernel. A transform iterator is an iterator that applies a functor to each element as it is read, so thatthrust::reduceover a transform iterator that squares its elements computes the sum of squares in 1 pass.
The following 2 examples apply these questions.
Normalizing 100,000,000 floats to the range 0 to 1 requires the smallest and largest
values, followed by 1 multiply-add per element. thrust::minmax_element finds both values
in a single pass that reads 400 MB, and thrust::transform reads the 400 MB again and writes
400 MB of results. The total of 1.2 GB takes about 13 ms at 92 GB/s. A custom kernel cannot
avoid the second pass, because no element can be scaled before the largest value is known,
so it would save nothing.
A 7-point blur of each frame of a video reads 3 neighbors on each side of every pixel. A computation in which each output is computed from a fixed pattern of neighboring inputs is called a stencil, and the inputs that a tile of outputs needs from beyond its own edges are its halo. For a row of 256 pixels, the blur needs 3 more pixels on each side, 262 in all. No library call fits a stencil with a halo of neighbors, so the blur requires a custom kernel. It should read along rows, so that neighboring threads read neighboring pixels (Chapter 7). Tiling in shared memory should be added only if the profiler of Chapter 25 shows the blur to be the slowest stage of the pipeline.
11.7 The complete programs
Listing 11.15 The complete programs for the sums and scans.
//! Chapter 11 in Rust: block_reduce and block_scan, and closures in place of Thrust calls.
//!
//! cargo oxide run
use std::sync::Arc;
use std::time::Instant;
use cuda_core::{CudaContext, CudaStream, DeviceBuffer, LaunchConfig1D};
use cuda_device::cooperative_groups::ops::Sum;
use cuda_device::cooperative_groups::{block_reduce, block_scan, this_thread_block};
use cuda_device::{DisjointSlice, SharedArray, cuda_module, device, kernel, launch_contract};
use cuda_device::{thread, warp};
const BLOCK: u32 = 256;
const GRID: u32 = 1024;
type Error = Box<dyn std::error::Error>;
#[cuda_module]
mod kernels {
use super::*;
#[device]
fn warp_sum(mut v: f32) -> f32 {
for offset in [16, 8, 4, 2, 1] {
v += warp::shuffle_down_f32(v, offset);
}
v
}
/// Chapter 8's sum: each warp shuffles, 1 barrier per block, written by hand.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_hand(input: &[f32], mut partial: DisjointSlice<f32>) {
static mut WARPS: SharedArray<f32, 8> = SharedArray::UNINIT;
let stride = (thread::gridDim_x() * BLOCK) as usize;
let lane = warp::lane_id() as usize;
let warp = thread::threadIdx_x() as usize / 32;
let mut sum = 0.0;
let mut i = thread::index_1d().get();
while i < input.len() {
sum += input[i];
i += stride;
}
sum = warp_sum(sum);
if lane == 0 {
// SAFETY: lane 0 of each warp writes its own slot, before the barrier.
unsafe { WARPS[warp] = sum };
}
thread::sync_threads();
if warp == 0 {
// SAFETY: after the barrier the slots are only read.
sum = warp_sum(if lane < 8 { unsafe { WARPS[lane] } } else { 0.0 });
if lane == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = sum };
}
}
}
/// The same sum, with cuda-oxide's block_reduce in place of warp_sum and the slots.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn sum_blocks(input: &[f32], mut partial: DisjointSlice<f32>) {
static mut WARPS: SharedArray<f32, 8> = SharedArray::UNINIT;
let stride = (thread::gridDim_x() * BLOCK) as usize;
let block = this_thread_block();
let mut sum = 0.0;
let mut i = thread::index_1d().get();
while i < input.len() {
sum += input[i];
i += stride;
}
sum = block_reduce::<f32, Sum, 8>(&block, sum, &raw mut WARPS);
if thread::threadIdx_x() == 0 {
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(thread::blockIdx_x() as usize) = sum };
}
}
/// An inclusive scan of each block of 256 values, 1 value per thread.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn scan_blocks(input: &[u32], mut out: DisjointSlice<u32>) {
static mut WARPS: SharedArray<u32, 8> = SharedArray::UNINIT;
let block = this_thread_block();
let i = thread::index_1d();
let v = if i.get() < input.len() { input[i.get()] } else { 0 };
let scanned = block_scan::<u32, Sum, 8>(&block, v, &raw mut WARPS);
if let Some(slot) = out.get_mut(i) {
*slot = scanned;
}
}
/// out[i] = f(input[i]), 1 element per thread: the work of thrust::transform.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn map<F>(f: F, input: &[f32], mut out: DisjointSlice<f32>)
where
F: Fn(f32) -> f32 + Copy,
{
let idx = thread::index_1d();
let i = idx.get();
if let Some(slot) = out.get_mut(idx) {
*slot = f(input[i]);
}
}
/// 1 partial sum of f(input[i]) per block, each f(x) kept in a register: the work
/// of thrust::transform_reduce.
#[kernel]
#[launch_contract(domain = 1, block = (256, 1, 1))]
pub fn map_sum<F>(f: F, input: &[f32], mut partial: DisjointSlice<f32>)
where
F: Fn(f32) -> f32 + Copy,
{
static mut WARPS: SharedArray<f32, 8> = SharedArray::UNINIT;
let stride = (thread::gridDim_x() * BLOCK) as usize;
let block = this_thread_block();
let mut sum = 0.0;
let mut i = thread::index_1d().get();
while i < input.len() {
sum += f(input[i]);
i += stride;
}
sum = block_reduce::<f32, Sum, 8>(&block, sum, &raw mut WARPS);
if thread::threadIdx_x() == 0 {
let b = thread::blockIdx_x() as usize;
// SAFETY: only thread 0 of each block writes, at its own block number.
unsafe { *partial.get_unchecked_mut(b) = sum };
}
}
}
/// Average time of 20 runs of `launch`, in milliseconds, after 1 warm-up run.
fn time_ms(
stream: &Arc<CudaStream>,
mut launch: impl FnMut() -> Result<(), Error>,
) -> Result<f64, Error> {
launch()?;
stream.synchronize()?;
let start = Instant::now();
for _ in 0..20 {
launch()?;
}
stream.synchronize()?;
Ok(start.elapsed().as_secs_f64() * 1e3 / 20.0)
}
/// Numbers from a small linear congruential generator, as in Chapter 8.
fn random(n: usize, seed: u32) -> Vec<u32> {
let mut state = seed;
(0..n)
.map(|_| {
state = state.wrapping_mul(1_664_525).wrapping_add(1_013_904_223);
state
})
.collect()
}
/// The sum of squares of 64 Mi floats in 2 passes and in 1.
fn sums_of_squares(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
values: &[f32],
) -> Result<bool, Error> {
let n = values.len();
let exact: f64 = values.iter().map(|&v| v as f64 * v as f64).sum();
let input = DeviceBuffer::from_host(stream, values)?;
let mut squares = DeviceBuffer::<f32>::zeroed(stream, n)?;
let mut partial = DeviceBuffer::<f32>::zeroed(stream, GRID as usize)?;
let mut total = DeviceBuffer::<f32>::zeroed(stream, 1)?;
let each = module.prepare_map(LaunchConfig1D::new(n as u32 / BLOCK, BLOCK, 0))?;
let grid = module.prepare_map_sum(LaunchConfig1D::new(GRID, BLOCK, 0))?;
let fused = module.prepare_map_sum(LaunchConfig1D::new(GRID, BLOCK, 0))?;
let one = module.prepare_map_sum(LaunchConfig1D::new(1, BLOCK, 0))?;
let square = |v: f32| v * v;
let same = |v: f32| v;
let gb = (n * 4) as f64 / 1e9;
println!("sum of squares, GB/s of input read");
let ms = time_ms(stream, || {
module.map(stream, &each, square, &input, &mut squares)?;
module.map_sum(stream, &grid, same, &squares, &mut partial)?;
Ok(module.map_sum(stream, &one, same, &partial, &mut total)?)
})?;
let two_passes = total.to_host_vec(stream)?[0];
let rate = gb / ms * 1e3;
println!(" map, then map_sum {ms:6.2} ms {rate:6.1} GB/s sum {two_passes:.1}");
let ms = time_ms(stream, || {
module.map_sum(stream, &fused, square, &input, &mut partial)?;
Ok(module.map_sum(stream, &one, same, &partial, &mut total)?)
})?;
let one_pass = total.to_host_vec(stream)?[0];
let rate = gb / ms * 1e3;
println!(" map_sum, fused {ms:6.2} ms {rate:6.1} GB/s sum {one_pass:.1}");
println!(" exact (f64) sum {exact:.1}");
let close = |s: f32| (s as f64 - exact).abs() < 1e-5 * exact;
Ok(close(two_passes) && close(one_pass))
}
/// A sum of 4,096 floats in 3 ways: storage allocated for each sum and the result
/// copied to the host, as thrust::reduce does; storage allocated once and the result
/// copied; storage allocated once and the result kept on the GPU.
fn small_sums(
module: &kernels::LoadedModule,
stream: &Arc<CudaStream>,
values: &[f32],
) -> Result<(), Error> {
let n = 4096;
let blocks = 16;
let input = DeviceBuffer::from_host(stream, &values[..n])?;
let grid = module.prepare_map_sum(LaunchConfig1D::new(blocks, BLOCK, 0))?;
let one = module.prepare_map_sum(LaunchConfig1D::new(1, BLOCK, 0))?;
let same = |v: f32| v;
println!("sum of {n} floats, microseconds per sum");
let ms = time_ms(stream, || {
let mut partial = DeviceBuffer::<f32>::zeroed(stream, blocks as usize)?;
let mut total = DeviceBuffer::<f32>::zeroed(stream, 1)?;
module.map_sum(stream, &grid, same, &input, &mut partial)?;
module.map_sum(stream, &one, same, &partial, &mut total)?;
total.to_host_vec(stream)?;
Ok(())
})?;
println!(" allocated each time, result copied {:6.1} us", ms * 1e3);
let mut partial = DeviceBuffer::<f32>::zeroed(stream, blocks as usize)?;
let mut total = DeviceBuffer::<f32>::zeroed(stream, 1)?;
let ms = time_ms(stream, || {
module.map_sum(stream, &grid, same, &input, &mut partial)?;
module.map_sum(stream, &one, same, &partial, &mut total)?;
total.to_host_vec(stream)?;
Ok(())
})?;
println!(" allocated once, result copied {:6.1} us", ms * 1e3);
let ms = time_ms(stream, || {
module.map_sum(stream, &grid, same, &input, &mut partial)?;
Ok(module.map_sum(stream, &one, same, &partial, &mut total)?)
})?;
println!(" allocated once, result kept {:6.1} us", ms * 1e3);
Ok(())
}
fn main() -> Result<(), Error> {
let ctx = CudaContext::new(0)?;
let stream = ctx.default_stream();
// SAFETY: the loaded code was compiled from the `kernels` module above.
let module = unsafe { kernels::load(&ctx)? };
let n = 64 << 20;
// 1. A sum of 67,108,864 floats in [0, 1), by hand and with block_reduce.
let values: Vec<f32> = random(n, 1)
.iter()
.map(|&r| (r >> 8) as f32 / 16_777_216.0)
.collect();
let exact: f64 = values.iter().map(|&v| v as f64).sum();
let input = DeviceBuffer::from_host(&stream, &values)?;
let mut partial = DeviceBuffer::<f32>::zeroed(&stream, GRID as usize)?;
let mut total = DeviceBuffer::<f32>::zeroed(&stream, 1)?;
let grid = LaunchConfig1D::new(GRID, BLOCK, 0);
let one = LaunchConfig1D::new(1, BLOCK, 0);
let hand = (module.prepare_sum_hand(grid)?, module.prepare_sum_hand(one)?);
let blocks = (module.prepare_sum_blocks(grid)?, module.prepare_sum_blocks(one)?);
let mut by_hand = || -> Result<(), Error> {
module.sum_hand(&stream, &hand.0, &input, &mut partial)?;
Ok(module.sum_hand(&stream, &hand.1, &partial, &mut total)?)
};
for _ in 0..10 {
time_ms(&stream, &mut by_hand)?; // warm up the clocks
}
let gb = (n * 4) as f64 / 1e9;
println!("sum of {n} floats, average of 20 runs");
let ms = time_ms(&stream, &mut by_hand)?;
let rate = gb / ms * 1e3;
let sum_hand = total.to_host_vec(&stream)?[0];
println!(" Chapter 8, by hand {ms:6.2} ms {rate:6.1} GB/s sum {sum_hand:.1}");
let ms = time_ms(&stream, || {
module.sum_blocks(&stream, &blocks.0, &input, &mut partial)?;
Ok(module.sum_blocks(&stream, &blocks.1, &partial, &mut total)?)
})?;
let rate = gb / ms * 1e3;
let sum_blocks = total.to_host_vec(&stream)?[0];
println!(" block_reduce {ms:6.2} ms {rate:6.1} GB/s sum {sum_blocks:.1}");
println!(" exact (f64) sum {exact:.1}");
// 2. Each block of 256 values 0 to 3, scanned with block_scan.
let counts: Vec<u32> = random(n, 2).iter().map(|&r| r >> 30).collect();
let input = DeviceBuffer::from_host(&stream, &counts)?;
let mut out = DeviceBuffer::<u32>::zeroed(&stream, n)?;
let config = LaunchConfig1D::new((n as u32).div_ceil(BLOCK), BLOCK, 0);
let scan = module.prepare_scan_blocks(config)?;
module.scan_blocks(&stream, &scan, &input, &mut out)?;
let result = out.to_host_vec(&stream)?;
let mut running = 0;
let mut scan_ok = true;
for (i, (&c, &r)) in counts.iter().zip(&result).enumerate() {
if i % BLOCK as usize == 0 {
running = 0;
}
running += c;
scan_ok &= r == running;
}
println!("block_scan of {n} values, 256 per block");
println!(" first block: {:?} ... {}", &result[..8], result[255]);
// 3. The sum of squares in 2 passes and in 1, and 3 ways to sum 4,096 floats.
let squares_ok = sums_of_squares(&module, &stream, &values)?;
small_sums(&module, &stream, &values)?;
let close = |s: f32| (s as f64 - exact).abs() < 1e-5 * exact;
let ok = close(sum_hand) && close(sum_blocks) && scan_ok && squares_ok;
println!("{}", if ok { "PASSED" } else { "FAILED" });
Ok(())
}// Chapter 11: Thrust and CUB against the hand-written sum and scan of Chapter 8.
// Build: nvcc -arch=native -O2 -std=c++17 reduce_scan.cu -o reduce_scan
#include <chrono>
#include <cmath>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cub/cub.cuh>
#include <cuda/std/functional>
#include <cuda_runtime.h>
#include <thrust/execution_policy.h>
#include <thrust/reduce.h>
#include <thrust/scan.h>
#include <thrust/transform.h>
#include <thrust/transform_reduce.h>
const int BLOCK = 256; // threads per block
const int GRID = 1024; // blocks of the hand-written sums
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// Average time of `runs` runs of `run`, in milliseconds, after 1 warm-up run.
template <typename F>
double timeMs(F run, int runs = 20)
{
run();
check(cudaDeviceSynchronize());
double t0 = nowMs();
for (int r = 0; r < runs; ++r) {
run();
}
check(cudaGetLastError());
check(cudaDeviceSynchronize());
return (nowMs() - t0) / runs;
}
unsigned nextRandom(unsigned& state)
{
state = state * 1664525u + 1013904223u;
return state;
}
// Chapter 8's fastest sum: float4 loads, warp shuffles, 1 barrier per block.
__device__ float warpSum(float v)
{
for (int offset = 16; offset > 0; offset /= 2) {
v += __shfl_down_sync(0xffffffff, v, offset);
}
return v;
}
__device__ float blockSum(float v)
{
__shared__ float warps[BLOCK / 32];
int lane = threadIdx.x % 32;
int warp = threadIdx.x / 32;
v = warpSum(v);
if (lane == 0) {
warps[warp] = v;
}
__syncthreads();
if (warp == 0) {
v = warpSum(lane < BLOCK / 32 ? warps[lane] : 0.0f);
}
return v; // the block's total, in thread 0
}
__global__ void sumHand(const float4* in, float* partial, int n4)
{
float sum = 0.0f;
for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n4; i += gridDim.x * BLOCK) {
float4 v = in[i];
sum += v.x + v.y + v.z + v.w;
}
sum = blockSum(sum);
if (threadIdx.x == 0) {
partial[blockIdx.x] = sum;
}
}
// The same kernel, with CUB's block reduction in place of warpSum and blockSum.
__global__ void sumCub(const float4* in, float* partial, int n4)
{
    using BlockReduce = cub::BlockReduce<float, BLOCK>;
    __shared__ BlockReduce::TempStorage temp;

    float sum = 0.0f;
    for (int i = blockIdx.x * BLOCK + threadIdx.x; i < n4; i += gridDim.x * BLOCK) {
        float4 v = in[i];
        sum += v.x + v.y + v.z + v.w;
    }

    sum = BlockReduce(temp).Sum(sum);
    if (threadIdx.x == 0) {
        partial[blockIdx.x] = sum;
    }
}
struct Square {
__host__ __device__ float operator()(float v) const { return v * v; }
};
// Prints 1 line of results; true if `sum` is within 1 part in 100,000 of `exact`.
bool report(const char* name, double ms, double bytes, float sum, double exact)
{
double gb = bytes / ms / 1e6;
std::printf(" %-28s %7.2f ms %6.1f GB/s sum %.1f\n", name, ms, gb, sum);
return std::abs(sum - exact) < 1e-5 * exact;
}
float readBack(const float* total)
{
float t;
check(cudaMemcpy(&t, total, sizeof(float), cudaMemcpyDeviceToHost));
return t;
}
bool sums(const float* in, float* partial, float* total, int n, double exact)
{
double bytes = n * 4.0;
const float4* in4 = (const float4*)in;
const float4* partial4 = (const float4*)partial;
std::printf("sum of %d floats (%d MiB), average of 20 runs\n", n, n >> 18);
auto hand = [&] {
sumHand<<<GRID, BLOCK>>>(in4, partial, n / 4);
sumHand<<<1, BLOCK>>>(partial4, total, GRID / 4);
};
double ms = timeMs(hand);
bool ok = report("Chapter 8, float4 + shuffles", ms, bytes, readBack(total), exact);
auto cubBlock = [&] {
sumCub<<<GRID, BLOCK>>>(in4, partial, n / 4);
sumCub<<<1, BLOCK>>>(partial4, total, GRID / 4);
};
ms = timeMs(cubBlock);
ok &= report("same, cub::BlockReduce", ms, bytes, readBack(total), exact);
size_t tempBytes = 0;
cub::DeviceReduce::Sum(nullptr, tempBytes, in, total, n); // asks for the size only
void* temp;
check(cudaMalloc(&temp, tempBytes));
auto cubDevice = [&] { cub::DeviceReduce::Sum(temp, tempBytes, in, total, n); };
ms = timeMs(cubDevice);
ok &= report("cub::DeviceReduce::Sum", ms, bytes, readBack(total), exact);
std::printf(" (CUB asked for %zu bytes of temporary storage)\n", tempBytes);
float t = 0.0f;
auto thrustSum = [&] { t = thrust::reduce(thrust::device, in, in + n, 0.0f); };
ms = timeMs(thrustSum);
ok &= report("thrust::reduce", ms, bytes, t, exact);
check(cudaFree(temp));
return ok;
}
bool sumsOfSquares(const float* in, float* squares, int n, double exact)
{
double bytes = n * 4.0;
Square square;
cuda::std::plus<float> plus;
std::printf("sum of squares, GB/s of input read\n");
float t = 0.0f;
auto twoPasses = [&] {
thrust::transform(thrust::device, in, in + n, squares, square);
t = thrust::reduce(thrust::device, squares, squares + n, 0.0f);
};
double ms = timeMs(twoPasses);
bool ok = report("transform, then reduce", ms, bytes, t, exact);
auto fused = [&] {
t = thrust::transform_reduce(thrust::device, in, in + n, square, 0.0f, plus);
};
ms = timeMs(fused);
ok &= report("transform_reduce", ms, bytes, t, exact);
return ok;
}
void smallSums(const float* in, float* total)
{
const int n = 4096;
float t = 0.0f;
std::printf("sum of %d floats, microseconds per sum\n", n);
auto thrustSum = [&] { t = thrust::reduce(thrust::device, in, in + n, 0.0f); };
std::printf(" thrust::reduce %6.1f us\n", timeMs(thrustSum) * 1e3);
size_t tempBytes = 0;
cub::DeviceReduce::Sum(nullptr, tempBytes, in, total, n);
void* temp;
check(cudaMalloc(&temp, tempBytes));
auto cubAndCopy = [&] {
cub::DeviceReduce::Sum(temp, tempBytes, in, total, n);
check(cudaMemcpy(&t, total, sizeof(float), cudaMemcpyDeviceToHost));
};
double usCopy = timeMs(cubAndCopy) * 1e3;
std::printf(" cub::DeviceReduce, result copied %6.1f us\n", usCopy);
auto cubOnly = [&] { cub::DeviceReduce::Sum(temp, tempBytes, in, total, n); };
double usOnly = timeMs(cubOnly) * 1e3;
std::printf(" cub::DeviceReduce, result kept %6.1f us\n", usOnly);
check(cudaFree(temp));
}
bool scans(int n)
{
std::vector<unsigned> values(n), inclusive(n), result(n);
unsigned state = 2;
unsigned running = 0;
for (int i = 0; i < n; ++i) {
values[i] = nextRandom(state) >> 30; // 0, 1, 2 or 3
running += values[i];
inclusive[i] = running;
}
unsigned *in, *out;
check(cudaMalloc(&in, n * sizeof(unsigned)));
check(cudaMalloc(&out, n * sizeof(unsigned)));
check(cudaMemcpy(in, values.data(), n * sizeof(unsigned), cudaMemcpyHostToDevice));
double bytes = 2.0 * n * sizeof(unsigned); // each value read once, written once
std::printf("scan of %d values 0 to 3, average of 20 runs\n", n);
auto thrustScan = [&] { thrust::inclusive_scan(thrust::device, in, in + n, out); };
double ms = timeMs(thrustScan);
check(cudaMemcpy(result.data(), out, n * sizeof(unsigned), cudaMemcpyDeviceToHost));
bool ok = result == inclusive;
std::printf(" thrust::inclusive_scan %6.2f ms", ms);
std::printf(" %6.1f GB/s", bytes / ms / 1e6);
std::printf(" last %u correct: %s\n", result[n - 1], ok ? "yes" : "no");
size_t tempBytes = 0;
cub::DeviceScan::ExclusiveSum(nullptr, tempBytes, in, out, n);
void* temp;
check(cudaMalloc(&temp, tempBytes));
auto cubScan = [&] { cub::DeviceScan::ExclusiveSum(temp, tempBytes, in, out, n); };
ms = timeMs(cubScan);
check(cudaMemcpy(result.data(), out, n * sizeof(unsigned), cudaMemcpyDeviceToHost));
bool okEx = true;
for (int i = 0; i < n; ++i) {
okEx = okEx && result[i] == inclusive[i] - values[i];
}
std::printf(" cub::DeviceScan::ExclusiveSum %6.2f ms", ms);
std::printf(" %6.1f GB/s", bytes / ms / 1e6);
std::printf(" last %u correct: %s\n", result[n - 1], okEx ? "yes" : "no");
check(cudaFree(temp));
check(cudaFree(in));
check(cudaFree(out));
return ok && okEx;
}
// An inclusive scan of each block of 256 values, 1 value per thread, with CUB.
__global__ void scanBlocks(const unsigned* in, unsigned* out, int n)
{
    using BlockScan = cub::BlockScan<unsigned, BLOCK>;
    __shared__ BlockScan::TempStorage temp;
    int i = blockIdx.x * BLOCK + threadIdx.x;

    unsigned v = i < n ? in[i] : 0;
    BlockScan(temp).InclusiveSum(v, v);
    if (i < n) {
        out[i] = v;
    }
}
bool blockScans(int n)
{
std::vector<unsigned> values(n), result(n);
unsigned state = 2;
for (int i = 0; i < n; ++i) {
values[i] = nextRandom(state) >> 30; // 0, 1, 2 or 3, as in scans()
}
unsigned *in, *out;
check(cudaMalloc(&in, n * sizeof(unsigned)));
check(cudaMalloc(&out, n * sizeof(unsigned)));
check(cudaMemcpy(in, values.data(), n * sizeof(unsigned), cudaMemcpyHostToDevice));
int blocks = (n + BLOCK - 1) / BLOCK;
scanBlocks<<<blocks, BLOCK>>>(in, out, n);
check(cudaMemcpy(result.data(), out, n * sizeof(unsigned), cudaMemcpyDeviceToHost));
bool ok = true;
unsigned running = 0;
for (int i = 0; i < n; ++i) {
if (i % BLOCK == 0) {
running = 0; // each block starts a scan of its own
}
running += values[i];
ok = ok && result[i] == running;
}
const char* verdict = ok ? "yes" : "no";
std::printf("cub::BlockScan of %d values, 256 per block\n", n);
std::printf(" first block:");
for (int i = 0; i < 8; ++i) {
std::printf(" %u", result[i]);
}
std::printf(" ... %u correct: %s\n", result[BLOCK - 1], verdict);
check(cudaFree(in));
check(cudaFree(out));
return ok;
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %d SMs", prop.name, prop.multiProcessorCount);
std::printf(", L2 cache %d MiB\n", prop.l2CacheSize >> 20);
const int n = 64 << 20; // 67,108,864 floats, 256 MiB
std::vector<float> values(n);
unsigned state = 1;
double exact = 0.0;
double exactSquares = 0.0;
for (int i = 0; i < n; ++i) {
values[i] = (nextRandom(state) >> 8) / 16777216.0f; // in [0, 1), as in Chapter 8
exact += values[i];
exactSquares += double(values[i]) * values[i];
}
float *in, *partial, *total, *squares;
check(cudaMalloc(&in, n * sizeof(float)));
check(cudaMalloc(&partial, GRID * sizeof(float)));
check(cudaMalloc(&total, sizeof(float)));
check(cudaMalloc(&squares, n * sizeof(float)));
check(cudaMemcpy(in, values.data(), n * sizeof(float), cudaMemcpyHostToDevice));
for (int k = 0; k < 10; ++k) { // warm up: clocks rise under sustained load
timeMs([&] { sumHand<<<GRID, BLOCK>>>((const float4*)in, partial, n / 4); });
}
bool ok = sums(in, partial, total, n, exact);
ok &= sumsOfSquares(in, squares, n, exactSquares);
std::printf(" exact (double): sum %.1f, sum of squares %.1f\n", exact, exactSquares);
smallSums(in, total);
check(cudaFree(in));
check(cudaFree(partial));
check(cudaFree(total));
check(cudaFree(squares));
ok &= scans(n);
ok &= blockScans(n);
std::printf("%s\n", ok ? "PASSED" : "FAILED");
}
Listing 11.16 The complete sort.cu. code/ch11_libraries/sort.cu
// Chapter 11: sorting 16 Mi keys with Thrust and CUB, against std::sort on the CPU.
// Build: nvcc -arch=native -O2 -std=c++17 sort.cu -o sort

#include <algorithm>
#include <chrono>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cub/cub.cuh>
#include <cuda/std/functional>
#include <cuda_runtime.h>
#include <thrust/execution_policy.h>
#include <thrust/sort.h>

using Keys = std::vector<unsigned>;

void check(cudaError_t err)
{
    if (err != cudaSuccess) {
        std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
        std::exit(1);
    }
}

double nowMs()
{
    using namespace std::chrono;
    return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}

unsigned nextRandom(unsigned& state)
{
    state = state * 1664525u + 1013904223u;
    return state;
}

// The same order as thrust::less, but Thrust cannot see inside it, so it cannot use a
// radix sort and falls back to a merge sort, which only compares keys.
struct Ascending {
    __host__ __device__ bool operator()(unsigned a, unsigned b) const { return a < b; }
};

// Scratch memory for Thrust, allocated once. During a call Thrust asks for temporary
// buffers and gives them all back before it returns. The arena hands out pieces of 1
// large buffer, and starts again from its beginning when every piece is back.
struct Arena {
    using value_type = char;

    char* base = nullptr;
    size_t size = 0;
    size_t used = 0;
    int live = 0;

    char* allocate(std::ptrdiff_t bytes)
    {
        size_t start = (used + 255) / 256 * 256;          // 256-byte aligned
        if (start + bytes > size) {
            std::fprintf(stderr, "arena too small for %td bytes\n", bytes);
            std::exit(1);
        }

        used = start + bytes;
        ++live;
        return base + start;
    }

    void deallocate(char*, size_t)
    {
        --live;
        if (live == 0) {
            used = 0;
        }
    }
};

// Average time of 5 sorts, in milliseconds. Each sort starts from a fresh copy of
// `original`; only the sort itself is timed.
template <typename F>
double timeSort(F sort, unsigned* keys, const unsigned* original, int n)
{
    double total = 0.0;
    for (int r = 0; r < 6; ++r) {
        check(cudaMemcpy(keys, original, n * 4, cudaMemcpyDeviceToDevice));
        check(cudaDeviceSynchronize());

        double t0 = nowMs();
        sort();
        check(cudaDeviceSynchronize());
        if (r > 0) {                          // run 0 warms up
            total += nowMs() - t0;
        }
    }
    return total / 5;
}

bool report(const char* name, double ms, int n, const unsigned* keys, const Keys& expected)
{
    Keys got(n);
    check(cudaMemcpy(got.data(), keys, n * 4, cudaMemcpyDeviceToHost));
    bool ok = got == expected;

    double rate = n / ms / 1e3;               // millions of keys per second
    std::printf("  %-34s %7.2f ms  %7.1f Mkeys/s", name, ms, rate);
    std::printf("  correct: %s\n", ok ? "yes" : "no");
    return ok;
}

int main()
{
    cudaDeviceProp prop;
    check(cudaGetDeviceProperties(&prop, 0));
    std::printf("GPU: %s, %d SMs\n", prop.name, prop.multiProcessorCount);

    const int n = 16 << 20;                   // 16,777,216 keys of 32 bits, 64 MiB
    Keys random(n), small(n);
    unsigned state = 5;
    for (int i = 0; i < n; ++i) {
        random[i] = nextRandom(state);
        small[i] = random[i] >> 24;           // keys 0 to 255: only 8 bits differ
    }

    Keys ascending = random;
    double t0 = nowMs();
    std::sort(ascending.begin(), ascending.end());
    double cpuMs = nowMs() - t0;
    Keys descending(ascending.rbegin(), ascending.rend());
    Keys smallSorted = small;
    std::sort(smallSorted.begin(), smallSorted.end());

    unsigned *original, *keys, *sorted;
    check(cudaMalloc(&original, n * 4));
    check(cudaMalloc(&keys, n * 4));
    check(cudaMalloc(&sorted, n * 4));
    check(cudaMemcpy(original, random.data(), n * 4, cudaMemcpyHostToDevice));

    std::printf("sort of %d random 32-bit keys, average of 5 runs\n", n);
    double cpuRate = n / cpuMs / 1e3;
    std::printf("  %-34s %7.2f ms", "std::sort, 1 CPU core", cpuMs);
    std::printf("  %7.1f Mkeys/s\n", cpuRate);

    auto plain = [&] { thrust::sort(thrust::device, keys, keys + n); };
    double ms = timeSort(plain, keys, original, n);
    bool ok = report("thrust::sort", ms, n, keys, ascending);

    Arena arena;
    arena.size = 2 * size_t(n) * 4;
    check(cudaMalloc(&arena.base, arena.size));
    auto policy = thrust::cuda::par(arena);

    auto radix = [&] { thrust::sort(policy, keys, keys + n); };
    ms = timeSort(radix, keys, original, n);
    ok &= report("thrust::sort, scratch reused", ms, n, keys, ascending);

    cuda::std::greater<unsigned> greater;
    auto down = [&] { thrust::sort(policy, keys, keys + n, greater); };
    ms = timeSort(down, keys, original, n);
    ok &= report("  ... with cuda::std::greater", ms, n, keys, descending);

    auto merge = [&] { thrust::sort(policy, keys, keys + n, Ascending()); };
    ms = timeSort(merge, keys, original, n);
    ok &= report("  ... with own comparison", ms, n, keys, ascending);

    size_t tempBytes = 0;
    cub::DeviceRadixSort::SortKeys(nullptr, tempBytes, keys, sorted, n);
    void* temp;
    check(cudaMalloc(&temp, tempBytes));

    auto all32 = [&] { cub::DeviceRadixSort::SortKeys(temp, tempBytes, keys, sorted, n); };
    ms = timeSort(all32, keys, original, n);
    ok &= report("cub::DeviceRadixSort", ms, n, sorted, ascending);

    check(cudaMemcpy(original, small.data(), n * 4, cudaMemcpyHostToDevice));
    std::printf("sort of %d keys from 0 to 255\n", n);

    ms = timeSort(all32, keys, original, n);
    ok &= report("cub::DeviceRadixSort, bits 0 to 31", ms, n, sorted, smallSorted);

    auto low8 = [&] {
        cub::DeviceRadixSort::SortKeys(temp, tempBytes, keys, sorted, n, 0, 8);
    };
    ms = timeSort(low8, keys, original, n);
    ok &= report("cub::DeviceRadixSort, bits 0 to 7", ms, n, sorted, smallSorted);

    check(cudaFree(temp));
    check(cudaFree(arena.base));
    check(cudaFree(original));
    check(cudaFree(keys));
    check(cudaFree(sorted));

    std::printf("%s\n", ok ? "PASSED" : "FAILED");
}
The sort has no Rust program, because cuda-oxide provides no sort (Section 11.2.4).
Listing 11.17 The complete cuBLAS programs.
//! Chapter 11 in Rust: cuBLAS called through its C interface, with row-major matrices,
//! then SGEMM in FP32 and on tensor cores.
//!
//!     cargo oxide run --bin gemm

use std::ffi::{c_int, c_void};
use std::sync::Arc;
use std::time::Instant;

use cuda_core::{CudaContext, CudaStream, DeviceBuffer};

const N: usize = 4096; // the matrix size of Chapter 9

type Error = Box<dyn std::error::Error>;

/// A cuBLAS handle: a pointer to state that only cuBLAS reads.
type Handle = *mut c_void;

const CUBLAS_OP_N: c_int = 0;
const CUBLAS_TF32_TENSOR_OP_MATH: c_int = 3;

#[link(name = "cublas")]
unsafe extern "C" {
    fn cublasCreate_v2(handle: *mut Handle) -> c_int;
    fn cublasSetStream_v2(handle: Handle, stream: *mut c_void) -> c_int;
    fn cublasSetMathMode(handle: Handle, mode: c_int) -> c_int;
    fn cublasDestroy_v2(handle: Handle) -> c_int;
    fn cublasSgemm_v2(
        handle: Handle,
        op_a: c_int,
        op_b: c_int,
        m: c_int,
        n: c_int,
        k: c_int,
        alpha: *const f32,
        a: *const f32,
        lda: c_int,
        b: *const f32,
        ldb: c_int,
        beta: *const f32,
        c: *mut f32,
        ldc: c_int,
    ) -> c_int;
}

/// cuBLAS returns 0 for success and an error number otherwise.
fn ok(result: c_int, call: &str) -> Result<(), Error> {
    if result == 0 {
        return Ok(());
    }

    Err(format!("{call} failed with cuBLAS error {result}").into())
}

/// The device address of a buffer, as the pointer type cuBLAS takes.
fn ptr(buffer: &DeviceBuffer<f32>) -> *mut f32 {
    buffer.cu_deviceptr() as *mut f32
}

/// Average time of `runs` runs of `launch`, in milliseconds, after 1 warm-up run.
fn time_ms<F>(stream: &CudaStream, runs: u32, mut launch: F) -> Result<f64, Error>
where
    F: FnMut() -> Result<(), Error>,
{
    launch()?;
    stream.synchronize()?;

    let start = Instant::now();
    for _ in 0..runs {
        launch()?;
    }
    stream.synchronize()?;

    Ok(start.elapsed().as_secs_f64() * 1e3 / runs as f64)
}

/// 1 row of a matrix as text, its values separated by spaces.
fn row_text(row: &[f32]) -> String {
    let values: Vec<String> = row.iter().map(|v| v.to_string()).collect();
    values.join(" ")
}

fn print(name: &str, m: &[f32], rows: usize, cols: usize) {
    let lines: Vec<String> = m.chunks(cols).take(rows).map(row_text).collect();
    println!("  {name} = [{}]", lines.join("; "));
}

/// C = A B for a 2 x 3 matrix A and a 3 x 2 matrix B, all stored row by row.
fn small_product(handle: Handle, stream: &Arc<CudaStream>) -> Result<bool, Error> {
    let a = [1.0, 2.0, 3.0, 4.0, 5.0, 6.0];
    let b = [7.0, 8.0, 9.0, 10.0, 11.0, 12.0];
    let expected = [58.0, 64.0, 139.0, 154.0];

    let a_dev = DeviceBuffer::from_host(stream, &a)?;
    let b_dev = DeviceBuffer::from_host(stream, &b)?;
    let c_dev = DeviceBuffer::<f32>::zeroed(stream, 4)?;
    let (pa, pb, pc) = (ptr(&a_dev), ptr(&b_dev), ptr(&c_dev));

    let (one, zero) = (1.0f32, 0.0f32);
    let op = CUBLAS_OP_N;

    println!("C = A B with A 2 x 3 and B 3 x 2, stored row by row");
    print("A", &a, 2, 3);
    print("B", &b, 3, 2);

    // Wrong: cuBLAS reads each array column by column.
    // SAFETY: the 3 pointers address live buffers of 6, 6 and 4 floats, enough for the
    // sizes and leading dimensions given.
    let result = unsafe {
        cublasSgemm_v2(handle, op, op, 2, 2, 3, &one, pa, 2, pb, 3, &zero, pc, 2)
    };
    ok(result, "cublasSgemm")?;

    let c = c_dev.to_host_vec(stream)?;
    print("C, operands as given  ", &c, 2, 2);

    // Right: in column-major terms our arrays hold A^T and B^T. Ask for B^T A^T = C^T,
    // whose column-major storage is C row by row.
    // SAFETY: as above.
    let result = unsafe {
        cublasSgemm_v2(handle, op, op, 2, 2, 3, &one, pb, 2, pa, 3, &zero, pc, 2)
    };
    ok(result, "cublasSgemm")?;

    let c = c_dev.to_host_vec(stream)?;
    print("C, operands swapped   ", &c, 2, 2);

    Ok(c == expected)
}

/// Values in [-0.5, 0.5) from a small linear congruential generator, as in Chapter 9.
fn random_matrix(state: &mut u32) -> Vec<f32> {
    let mut m = Vec::with_capacity(N * N);

    for _ in 0..N * N {
        *state = state.wrapping_mul(1_664_525).wrapping_add(1_013_904_223);
        m.push((*state >> 8) as f32 / 16_777_216.0 - 0.5);
    }
    m
}

/// Element (i, j) of A B, computed in double precision.
fn exact_element(a: &[f32], b: &[f32], i: usize, j: usize) -> f64 {
    let mut sum = 0.0;

    for k in 0..N {
        sum += a[i * N + k] as f64 * b[k * N + j] as f64;
    }
    sum
}

/// The largest difference from a double-precision product, over 64 elements of C.
fn max_error(a: &[f32], b: &[f32], c: &[f32]) -> f64 {
    let mut worst: f64 = 0.0;

    for s in 0..64 {
        let i = s * 977 % N;
        let j = (s * 1231 + 7) % N;

        let exact = exact_element(a, b, i, j);
        let error = (exact - c[i * N + j] as f64).abs();
        worst = worst.max(error);
    }
    worst
}

fn main() -> Result<(), Error> {
    let ctx = CudaContext::new(0)?;
    let stream = ctx.default_stream();
    println!("GPU: {}", ctx.device_name()?);

    let start = Instant::now();
    let mut handle: Handle = std::ptr::null_mut();
    // SAFETY: `handle` is a valid place for cuBLAS to store its handle.
    let result = unsafe { cublasCreate_v2(&mut handle) };
    ok(result, "cublasCreate")?;
    println!("cublasCreate took {:.1} ms", start.elapsed().as_secs_f64() * 1e3);

    // SAFETY: the handle is live, and the stream lives until the program ends.
    let result = unsafe { cublasSetStream_v2(handle, stream.cu_stream().cast()) };
    ok(result, "cublasSetStream")?;

    let mut passed = small_product(handle, &stream)?;

    let mut state = 1;
    let a = random_matrix(&mut state);
    let b = random_matrix(&mut state);

    let a_dev = DeviceBuffer::from_host(&stream, &a)?;
    let b_dev = DeviceBuffer::from_host(&stream, &b)?;
    let c_dev = DeviceBuffer::<f32>::zeroed(&stream, N * N)?;
    let (pa, pb, pc) = (ptr(&a_dev), ptr(&b_dev), ptr(&c_dev));

    let (one, zero) = (1.0f32, 0.0f32);
    let op = CUBLAS_OP_N;
    let n = N as c_int;

    let mut gemm = || -> Result<(), Error> {
        // SAFETY: the 3 pointers address live buffers of N x N floats.
        let result = unsafe {
            cublasSgemm_v2(handle, op, op, n, n, n, &one, pb, n, pa, n, &zero, pc, n)
        };
        ok(result, "cublasSgemm")
    };

    let report = |name: &str, ms: f64| -> Result<f64, Error> {
        let c = c_dev.to_host_vec(&stream)?;
        let gflops = 2.0 * (N * N * N) as f64 / ms / 1e6;
        let error = max_error(&a, &b, &c);
        println!("  {name:<22} {ms:8.2} ms  {gflops:7.1} GFLOP/s  max error {error:.1e}");
        Ok(error)
    };

    for _ in 0..10 {
        time_ms(&stream, 5, &mut gemm)?; // warm up: clocks rise under sustained load
    }

    println!("C = A B, {N} x {N} floats, average of 10 runs");
    let ms = time_ms(&stream, 10, &mut gemm)?;
    let fp32 = report("cuBLAS, FP32", ms)?;

    // SAFETY: the handle is live.
    let result = unsafe { cublasSetMathMode(handle, CUBLAS_TF32_TENSOR_OP_MATH) };
    ok(result, "cublasSetMathMode")?;
    let ms = time_ms(&stream, 10, &mut gemm)?;
    let tf32 = report("cuBLAS, TF32 tensor", ms)?;

    passed &= fp32 < 1e-3 && tf32 < 1e-2;
    let verdict = if passed { "PASSED" } else { "FAILED" };
    println!("{verdict}");

    // SAFETY: the handle is live and is not used after this call.
    let result = unsafe { cublasDestroy_v2(handle) };
    ok(result, "cublasDestroy")?;
    Ok(())
}
// Chapter 11: cuBLAS with row-major matrices, then SGEMM in FP32 and on tensor cores.
// Build: nvcc -arch=native -O2 gemm.cu -o gemm -lcublas
#include <chrono>
#include <cmath>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cublas_v2.h>
#include <cuda_runtime.h>
using Matrix = std::vector<float>;
const int N = 4096; // the size of Chapter 9
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
void check(cublasStatus_t status)
{
if (status != CUBLAS_STATUS_SUCCESS) {
std::fprintf(stderr, "cuBLAS error: %s\n", cublasGetStatusString(status));
std::exit(1);
}
}
double nowMs()
{
using namespace std::chrono;
return duration<double, std::milli>(steady_clock::now().time_since_epoch()).count();
}
// Average time of `runs` runs of `launch`, in milliseconds, after 1 warm-up run.
template <typename F>
double timeMs(F launch, int runs)
{
launch();
check(cudaDeviceSynchronize());
double t0 = nowMs();
for (int r = 0; r < runs; ++r) {
launch();
}
check(cudaDeviceSynchronize());
return (nowMs() - t0) / runs;
}
void print(const char* name, const Matrix& m, int rows, int cols)
{
std::printf(" %s =", name);
for (int i = 0; i < rows; ++i) {
std::printf(i == 0 ? " [" : "; ");
for (int j = 0; j < cols; ++j) {
std::printf(j == 0 ? "%g" : " %g", m[i * cols + j]);
}
}
std::printf("]\n");
}
// C = A B for a 2 x 3 matrix A and a 3 x 2 matrix B, all stored row by row.
bool smallProduct(cublasHandle_t handle)
{
Matrix a = {1, 2, 3,
4, 5, 6};
Matrix b = {7, 8,
9, 10,
11, 12};
Matrix expected = {58, 64,
139, 154};
Matrix c(4);
float *A, *B, *C;
check(cudaMalloc(&A, 6 * sizeof(float)));
check(cudaMalloc(&B, 6 * sizeof(float)));
check(cudaMalloc(&C, 4 * sizeof(float)));
check(cudaMemcpy(A, a.data(), 6 * sizeof(float), cudaMemcpyHostToDevice));
check(cudaMemcpy(B, b.data(), 6 * sizeof(float), cudaMemcpyHostToDevice));
float one = 1.0f, zero = 0.0f;
auto op = CUBLAS_OP_N;
std::printf("C = A B with A 2 x 3 and B 3 x 2, stored row by row\n");
print("A", a, 2, 3);
print("B", b, 3, 2);
// Wrong: cuBLAS reads each array column by column.
check(cublasSgemm(handle, op, op, 2, 2, 3, &one, A, 2, B, 3, &zero, C, 2));
check(cudaMemcpy(c.data(), C, 4 * sizeof(float), cudaMemcpyDeviceToHost));
print("C, operands as given ", c, 2, 2);
// Right: in column-major terms our arrays hold A^T and B^T. Ask for B^T A^T = C^T,
// whose column-major storage is C row by row.
check(cublasSgemm(handle, op, op, 2, 2, 3, &one, B, 2, A, 3, &zero, C, 2));
check(cudaMemcpy(c.data(), C, 4 * sizeof(float), cudaMemcpyDeviceToHost));
print("C, operands swapped ", c, 2, 2);
check(cudaFree(A));
check(cudaFree(B));
check(cudaFree(C));
return c == expected;
}
// Values in [-0.5, 0.5) from a small linear congruential generator, as in Chapter 9.
void fillRandom(Matrix& m, unsigned& state)
{
for (float& v : m) {
state = state * 1664525u + 1013904223u;
v = (state >> 8) / 16777216.0f - 0.5f;
}
}
// The largest difference from a double-precision product, over 64 elements of C.
double maxError(const Matrix& a, const Matrix& b, const Matrix& c)
{
double worst = 0.0;
for (int s = 0; s < 64; ++s) {
int i = s * 977 % N;
int j = (s * 1231 + 7) % N;
double exact = 0.0;
for (int k = 0; k < N; ++k) {
exact += double(a[i * N + k]) * b[k * N + j];
}
worst = std::fmax(worst, std::fabs(exact - c[i * N + j]));
}
return worst;
}
int main()
{
cudaDeviceProp prop;
check(cudaGetDeviceProperties(&prop, 0));
std::printf("GPU: %s, %d SMs\n", prop.name, prop.multiProcessorCount);
check(cudaFree(nullptr)); // create the CUDA context before timing
double t0 = nowMs();
cublasHandle_t handle;
check(cublasCreate(&handle));
std::printf("cublasCreate took %.1f ms\n", nowMs() - t0);
bool ok = smallProduct(handle);
Matrix a(N * N), b(N * N), c(N * N);
unsigned state = 1;
fillRandom(a, state);
fillRandom(b, state);
size_t bytes = size_t(N) * N * sizeof(float);
float *A, *B, *C;
check(cudaMalloc(&A, bytes));
check(cudaMalloc(&B, bytes));
check(cudaMalloc(&C, bytes));
check(cudaMemcpy(A, a.data(), bytes, cudaMemcpyHostToDevice));
check(cudaMemcpy(B, b.data(), bytes, cudaMemcpyHostToDevice));
float one = 1.0f, zero = 0.0f;
auto op = CUBLAS_OP_N;
auto gemm = [&] {
check(cublasSgemm(handle, op, op, N, N, N, &one, B, N, A, N, &zero, C, N));
};
auto report = [&](const char* name, double ms) {
check(cudaMemcpy(c.data(), C, bytes, cudaMemcpyDeviceToHost));
double gflops = 2.0 * N * N * N / ms / 1e6;
double error = maxError(a, b, c);
std::printf(" %-22s %8.2f ms %7.1f GFLOP/s", name, ms, gflops);
std::printf(" max error %.1e\n", error);
return error;
};
for (int k = 0; k < 10; ++k) { // warm up: clocks rise under sustained load
timeMs(gemm, 5);
}
std::printf("C = A B, %d x %d floats, average of 10 runs\n", N, N);
double fp32 = report("cuBLAS, FP32", timeMs(gemm, 10));
check(cublasSetMathMode(handle, CUBLAS_TF32_TENSOR_OP_MATH));
double tf32 = report("cuBLAS, TF32 tensor", timeMs(gemm, 10));
ok = ok && fp32 < 1e-3 && tf32 < 1e-2;
std::printf("%s\n", ok ? "PASSED" : "FAILED");
check(cublasDestroy(handle));
check(cudaFree(A));
check(cudaFree(B));
check(cudaFree(C));
}
Listing 11.18 The complete cuRAND and cuFFT programs.
//! Chapter 11 in Rust: random numbers with cuRAND, and the frequencies in a signal with
//! cuFFT, both called through their C interfaces.
//!
//!     cargo oxide run --bin fft_rand

use std::ffi::{c_int, c_void};
use std::sync::Arc;
use std::time::Instant;

use cuda_core::{CudaContext, CudaStream, DeviceBuffer};

type Error = Box<dyn std::error::Error>;

/// A cuRAND generator: a pointer to state that only cuRAND reads.
type Generator = *mut c_void;

const CURAND_RNG_PSEUDO_PHILOX4_32_10: c_int = 161;
const CUFFT_R2C: c_int = 0x2a;

#[link(name = "curand")]
unsafe extern "C" {
    fn curandCreateGenerator(generator: *mut Generator, kind: c_int) -> c_int;
    fn curandSetPseudoRandomGeneratorSeed(generator: Generator, seed: u64) -> c_int;
    fn curandSetStream(generator: Generator, stream: *mut c_void) -> c_int;
    fn curandGenerateNormal(
        generator: Generator,
        out: *mut f32,
        n: usize,
        mean: f32,
        sd: f32,
    ) -> c_int;
    fn curandDestroyGenerator(generator: Generator) -> c_int;
}

#[link(name = "cufft")]
unsafe extern "C" {
    fn cufftPlan1d(plan: *mut c_int, n: c_int, kind: c_int, batch: c_int) -> c_int;
    fn cufftSetStream(plan: c_int, stream: *mut c_void) -> c_int;
    fn cufftExecR2C(plan: c_int, input: *mut f32, output: *mut f32) -> c_int;
    fn cufftDestroy(plan: c_int) -> c_int;
}

/// cuRAND and cuFFT return 0 for success and an error number otherwise.
fn ok(result: c_int, call: &str) -> Result<(), Error> {
    if result == 0 {
        return Ok(());
    }

    Err(format!("{call} failed with error {result}").into())
}

/// The device address of a buffer, as the pointer type the C libraries take.
fn ptr(buffer: &DeviceBuffer<f32>) -> *mut f32 {
    buffer.cu_deviceptr() as *mut f32
}

/// 16 Mi numbers from the normal distribution; their mean should be near 0 and their
/// standard deviation near 1.
fn normal_numbers(stream: &Arc<CudaStream>) -> Result<bool, Error> {
    let n: usize = 16 << 20;
    let x = DeviceBuffer::<f32>::zeroed(stream, n)?;

    let mut generator: Generator = std::ptr::null_mut();
    let kind = CURAND_RNG_PSEUDO_PHILOX4_32_10;
    let out = ptr(&x);

    // SAFETY: `generator` is a valid place for cuRAND to store its generator; `out`
    // addresses n floats; the stream outlives the generator.
    let ms = unsafe {
        let result = curandCreateGenerator(&mut generator, kind);
        ok(result, "curandCreateGenerator")?;
        let result = curandSetPseudoRandomGeneratorSeed(generator, 2024);
        ok(result, "curandSetPseudoRandomGeneratorSeed")?;
        let result = curandSetStream(generator, stream.cu_stream().cast());
        ok(result, "curandSetStream")?;

        let result = curandGenerateNormal(generator, out, n, 0.0, 1.0); // warm-up
        ok(result, "curandGenerateNormal")?;
        stream.synchronize()?;

        let start = Instant::now();
        let result = curandGenerateNormal(generator, out, n, 0.0, 1.0);
        ok(result, "curandGenerateNormal")?;
        stream.synchronize()?;

        start.elapsed().as_secs_f64() * 1e3
    };

    // The 2 sums that the C++ program computes with Thrust, here on the host.
    let numbers = x.to_host_vec(stream)?;
    let sum: f64 = numbers.iter().map(|&v| v as f64).sum();
    let sum_of_squares: f64 = numbers.iter().map(|&v| v as f64 * v as f64).sum();

    let mean = sum / n as f64;
    let sd = (sum_of_squares / n as f64 - mean * mean).sqrt();
    let rate = n as f64 / ms / 1e3;

    println!("cuRAND, {n} normal numbers in {ms:.2} ms ({rate:.0} million per second)");
    println!("  mean {mean:.5}, standard deviation {sd:.5}");

    // SAFETY: the generator is live and is not used after this call.
    let result = unsafe { curandDestroyGenerator(generator) };
    ok(result, "curandDestroyGenerator")?;

    let mean_ok = mean.abs() < 1e-3;
    let sd_ok = (sd - 1.0).abs() < 1e-3;
    Ok(mean_ok && sd_ok)
}

/// 1 sample of sin(50 t) + 0.5 sin(120 t), at step t of n around the circle.
fn sample(t: usize, n: usize) -> f32 {
    let angle = 2.0 * std::f64::consts::PI * t as f64 / n as f64;
    let wave = (50.0 * angle).sin() + 0.5 * (120.0 * angle).sin();
    wave as f32
}

/// 1,024 samples of sin(50 t) + 0.5 sin(120 t), with t running once around the circle.
/// The transform should show 2 peaks, at frequencies 50 and 120, and nothing else.
fn spectrum(stream: &Arc<CudaStream>) -> Result<bool, Error> {
    let n = 1024;
    let bins = n / 2 + 1; // a real signal needs only half the spectrum
    let signal: Vec<f32> = (0..n).map(|t| sample(t, n)).collect();

    let x = DeviceBuffer::from_host(stream, &signal)?;
    let spectrum = DeviceBuffer::<f32>::zeroed(stream, 2 * bins)?; // (re, im) pairs

    let mut plan: c_int = 0;
    // SAFETY: `plan` is a valid place for the plan; `x` holds n floats and `spectrum`
    // holds `bins` complex numbers, the sizes of a real-to-complex transform of n.
    unsafe {
        let result = cufftPlan1d(&mut plan, n as c_int, CUFFT_R2C, 1);
        ok(result, "cufftPlan1d")?;
        let result = cufftSetStream(plan, stream.cu_stream().cast());
        ok(result, "cufftSetStream")?;
        let result = cufftExecR2C(plan, ptr(&x), ptr(&spectrum));
        ok(result, "cufftExecR2C")?;
    }
    let result = spectrum.to_host_vec(stream)?;

    println!("cuFFT, {n} samples of sin(50 t) + 0.5 sin(120 t)");
    let mut peaks = 0;
    let mut passed = true;

    for (f, pair) in result.chunks(2).enumerate() {
        let size = (pair[0] as f64).hypot(pair[1] as f64);
        if size <= 1.0 {
            continue;
        }

        println!("  frequency {f:3}: magnitude {size:.1}");
        peaks += 1;
        passed &= f == 50 || f == 120;
    }

    // SAFETY: the plan is live and is not used after this call.
    let result = unsafe { cufftDestroy(plan) };
    ok(result, "cufftDestroy")?;
    Ok(passed && peaks == 2)
}

fn main() -> Result<(), Error> {
    let ctx = CudaContext::new(0)?;
    let stream = ctx.default_stream();

    let mut passed = normal_numbers(&stream)?;
    passed &= spectrum(&stream)?;

    let verdict = if passed { "PASSED" } else { "FAILED" };
    println!("{verdict}");
    Ok(())
}
// Chapter 11: random numbers with cuRAND, and the frequencies in a signal with cuFFT.
// Build: nvcc -arch=native -O2 fft_rand.cu -o fft_rand -lcurand -lcufft
#include <cmath>
#include <cstdio>
#include <cstdlib>
#include <vector>
#include <cuda/std/functional>
#include <cuda_runtime.h>
#include <cufft.h>
#include <curand.h>
#include <thrust/execution_policy.h>
#include <thrust/reduce.h>
#include <thrust/transform_reduce.h>
void check(cudaError_t err)
{
if (err != cudaSuccess) {
std::fprintf(stderr, "CUDA error: %s\n", cudaGetErrorString(err));
std::exit(1);
}
}
void check(curandStatus_t status)
{
if (status != CURAND_STATUS_SUCCESS) {
std::fprintf(stderr, "cuRAND error %d\n", int(status));
std::exit(1);
}
}
void check(cufftResult status)
{
if (status != CUFFT_SUCCESS) {
std::fprintf(stderr, "cuFFT error %d\n", int(status));
std::exit(1);
}
}
struct Square {
__host__ __device__ float operator()(float v) const { return v * v; }
};
// 16 Mi numbers from the normal distribution; their mean should be near 0 and their
// standard deviation near 1.
bool normalNumbers()
{
const int n = 16 << 20;
float* x;
check(cudaMalloc(&x, n * sizeof(float)));
curandGenerator_t gen;
check(curandCreateGenerator(&gen, CURAND_RNG_PSEUDO_PHILOX4_32_10));
check(curandSetPseudoRandomGeneratorSeed(gen, 2024));
cudaEvent_t start, stop;
check(cudaEventCreate(&start));
check(cudaEventCreate(&stop));
check(curandGenerateNormal(gen, x, n, 0.0f, 1.0f)); // warm-up
check(cudaEventRecord(start));
check(curandGenerateNormal(gen, x, n, 0.0f, 1.0f));
check(cudaEventRecord(stop));
check(cudaEventSynchronize(stop));
float ms;
check(cudaEventElapsedTime(&ms, start, stop));
Square square;
cuda::std::plus<float> plus;
float sum = thrust::reduce(thrust::device, x, x + n, 0.0f);
float squares = thrust::transform_reduce(thrust::device, x, x + n, square, 0.0f, plus);
double mean = sum / n;
double sd = std::sqrt(squares / n - mean * mean);
std::printf("cuRAND, %d normal numbers in %.2f ms", n, ms);
std::printf(" (%.0f million per second)\n", n / ms / 1e3);
std::printf(" mean %.5f, standard deviation %.5f\n", mean, sd);
check(curandDestroyGenerator(gen));
check(cudaEventDestroy(start));
check(cudaEventDestroy(stop));
check(cudaFree(x));
return std::fabs(mean) < 1e-3 && std::fabs(sd - 1.0) < 1e-3;
}
// 1,024 samples of sin(50 t) + 0.5 sin(120 t), with t running once around the circle.
// The transform should show 2 peaks, at frequencies 50 and 120, and nothing else.
bool spectrum()
{
const int n = 1024;
const int bins = n / 2 + 1; // a real signal needs only half the spectrum
const double pi = 3.14159265358979323846;
std::vector<float> signal(n);
for (int t = 0; t < n; ++t) {
double angle = 2.0 * pi * t / n;
signal[t] = std::sin(50 * angle) + 0.5 * std::sin(120 * angle);
}
size_t spectrumBytes = bins * sizeof(cufftComplex);
float* x;
cufftComplex* spectrum;
check(cudaMalloc(&x, n * sizeof(float)));
check(cudaMalloc(&spectrum, spectrumBytes));
check(cudaMemcpy(x, signal.data(), n * sizeof(float), cudaMemcpyHostToDevice));
cufftHandle plan;
check(cufftPlan1d(&plan, n, CUFFT_R2C, 1));
check(cufftExecR2C(plan, x, spectrum));
std::vector<cufftComplex> result(bins);
check(cudaMemcpy(result.data(), spectrum, spectrumBytes, cudaMemcpyDeviceToHost));
std::printf("cuFFT, %d samples of sin(50 t) + 0.5 sin(120 t)\n", n);
int peaks = 0;
bool ok = true;
for (int f = 0; f < bins; ++f) {
double size = std::hypot(result[f].x, result[f].y);
if (size > 1.0) {
std::printf(" frequency %3d: magnitude %.1f\n", f, size);
++peaks;
ok = ok && (f == 50 || f == 120);
}
}
check(cufftDestroy(plan));
check(cudaFree(x));
check(cudaFree(spectrum));
return ok && peaks == 2;
}
int main()
{
bool ok = normalNumbers();
ok &= spectrum();
std::printf("%s\n", ok ? "PASSED" : "FAILED");
}
The 3 Rust programs run with cargo oxide run, cargo oxide run --bin gemm and
cargo oxide run --bin fft_rand in code/oxide/ch11_blocks.
Common mistakes
- Passing row-major data to cuBLAS unchanged. The result is the product of 2 different matrices, and no error is reported. Swap the operands, and check a non-square case by hand.
- Testing only with square matrices. With \(m = n = k\), a wrong leading dimension can go unnoticed; the 2 × 3 example of Section 11.4.2 exposes it.
- Calling a library in a loop over small inputs. Each
thrust::reducecall allocated, waited and copied: 68.1 µs for 0.18 µs of reading. Reuse temporary storage and keep results on the GPU. - Creating a cuBLAS handle for every call.
cublasCreatetook 13 to 22 ms. - Chaining Thrust calls on memory-bound data. Every call is a pass over memory; fuse them.
- Assuming the fast path. A custom comparison, or a standard one that the library version does not recognize, turned a radix sort into a merge sort at half the speed.
- Leaving TF32 enabled where 7 digits are needed. TF32 multiplies with 10-bit mantissas; the SGEMM error grew from 1.9 × 10⁻⁵ to 4.0 × 10⁻³.
- Sorting all 32 bits of keys that use 8.
begin_bitandend_bitreduce the number of passes from 4 to 1.
Summary
- Thrust provides whole-array algorithms called from the host. CUB provides the same algorithms with temporary storage managed by the caller, as well as primitives for use inside a kernel. cuBLAS, cuFFT and cuRAND work through a handle or a plan created once.
- On 256 MiB,
thrust::reduce, CUB and the best kernel of Chapter 8 all ran at 92 to 93 GB/s. Memory-bound work runs at the speed of the memory, regardless of who wrote the kernel. transform_reducefused 2 passes into 1 and ran 3.3 times as fast astransformfollowed byreduce.- CUB’s single-pass scan moves 512 MiB where the scan of Chapter 8 moves 1,024 MiB, and it ran 1.7 times as fast.
- A radix sort performs a histogram, an exclusive scan and a stable scatter for each digit.
On 16 Mi keys the GPU sorted up to 180 times as fast as 1 CPU core. Reusing temporary
storage nearly halved the time of
thrust::sort, and a comparison hidden in a functor nearly doubled it. - On a sum of 4,096 floats,
thrust::reducetook 68.1 µs, of which 38.2 µs went to allocation and 21.1 µs to copying and waiting. CUB with its temporary storage reused and the result kept on the GPU took 8.8 µs. cub::BlockReduceand cuda-oxide’sblock_reducereplace the hand-written block sum of Chapter 8 at the same speed.TempStorageis a type so that its size is known at compile time.- A row-major array is seen by cuBLAS as its transpose; requesting \(B^T A^T\) writes \(C\) in row-major order. cuBLAS ran SGEMM at 1,505 GFLOP/s in FP32, 1.6 times the best kernel of Chapter 9, and at 6,530 GFLOP/s with TF32 tensor cores, with 210 times the error.
In Chapter 12, we go below the libraries. We compile CUDA source code while the program runs, with NVRTC, and load and launch the result through the driver API.
Exercises
- Change the sum of 4,096 floats in
reduce_scan.cuto 65,536 and to 1,048,576 floats. At what size doesthrust::reducecome within 10% of CUB with the result kept on the GPU? Explain the size from the 38.2 µs and 21.1 µs of Section 11.3.3. - Write the sum of squares as
thrust::transforminto athrust::device_vectorfollowed bythrust::reduce, and as a single custom kernel. Predict both times from the bytes moved, then measure them. - Sort the 6 keys 47, 12, 40, 18, 42, 11 by hand with a radix sort on 2 decimal digits. Write the counts, the starting positions and the output of both passes.
- Use
cub::BlockScanin place ofwarpScanin thescanBlockskernel of Chapter 8. Count the lines saved and measure the speed. - In
gemm.cu, compute \(C = AB\) for a 3 × 2 matrix \(A\) and a 2 × 4 matrix \(B\), both stored row by row. Work out all 6 arguments that change, then check the result by hand. - Instead of swapping the operands, call
cublasSgemmwithCUBLAS_OP_Tfor both operands. What does cuBLAS then compute, and in which order is the result stored? - Rerun
sort.cuwiththrust::greater<unsigned>in place ofcuda::std::greater<unsigned>. With which toolkit does the time change, and why? - The measured GPU ran TF32 SGEMM 4.3 times as fast as FP32. The peak rates of the A100
differ by a factor of 8, and those of the RTX 4090 not at all. Look up the FP32 and TF32
peaks of your GPU, predict the ratio, and measure it with
gemm.cu. - Generate 16 Mi uniform numbers with
curandGenerateUniformand estimate π by counting the pairs \((x, y)\) with \(x^2 + y^2 < 1\), usingthrust::count_ifon a zipped pair of arrays. How many correct digits do 8 Mi pairs give?
Sources and further reading
- NVIDIA, CUDA C++ Core Libraries (CCCL): Thrust, CUB and libcu++: https://nvidia.github.io/cccl/
- NVIDIA, cuBLAS Library,
cublasSgemm, leading dimensions andcublasSetMathMode: https://docs.nvidia.com/cuda/cublas/ - NVIDIA, cuFFT Library User’s Guide: https://docs.nvidia.com/cuda/cufft/
- NVIDIA, cuRAND Library: https://docs.nvidia.com/cuda/curand/
- NVIDIA, A100 Tensor Core GPU Architecture (2020), TF32; H100 Tensor Core GPU Architecture (2022); Ada GPU Architecture (2022), the peak rates of Section 11.4.3.
- D. Merrill and M. Garland, “Single-pass Parallel Prefix Scan with Decoupled Look-back”, NVIDIA Technical Report NVR-2016-002, 2016.
- A. Adinets and D. Merrill, “Onesweep: A Faster Least Significant Digit Radix Sort for GPUs”, 2022.
- C. Lawson, R. Hanson, D. Kincaid and F. Krogh, “Basic Linear Algebra Subprograms for Fortran Usage”, ACM Transactions on Mathematical Software 5(3), 1979.
- J. Salmon, M. Moraes, R. Dror and D. Shaw, “Parallel Random Numbers: As Easy as 1, 2, 3”, SC11, 2011 (the Philox generator).
- J. Cooley and J. Tukey, “An Algorithm for the Machine Calculation of Complex Fourier Series”, Mathematics of Computation 19, 1965.
- cuda-oxide,
cuda_device::cooperative_groups(block_reduce,block_scan), revisionb7fe543: https://github.com/NVlabs/cuda-oxide